Stay Ahead, Stay ONMINE

The second wave of AI coding is here

Ask people building generative AI what generative AI is good for right now—what they’re really fired up about—and many will tell you: coding.  “That’s something that’s been very exciting for developers,” Jared Kaplan, chief scientist at Anthropic, told MIT Technology Review this month: “It’s really understanding what’s wrong with code, debugging it.” Copilot, a tool built on top of OpenAI’s large language models and launched by Microsoft-backed GitHub in 2022, is now used by millions of developers around the world. Millions more turn to general-purpose chatbots like Anthropic’s Claude, OpenAI’s ChatGPT, and Google DeepMind’s Gemini for everyday help. “Today, more than a quarter of all new code at Google is generated by AI, then reviewed and accepted by engineers,” Alphabet CEO Sundar Pichai claimed on an earnings call in October: “This helps our engineers do more and move faster.” Expect other tech companies to catch up, if they haven’t already. It’s not just the big beasts rolling out AI coding tools. A bunch of new startups have entered this buzzy market too. Newcomers such as Zencoder, Merly, Cosine, Tessl (valued at $750 million within months of being set up), and Poolside (valued at $3 billion before it even released a product) are all jostling for their slice of the pie. “It actually looks like developers are willing to pay for copilots,” says Nathan Benaich, an analyst at investment firm Air Street Capital: “And so code is one of the easiest ways to monetize AI.” Such companies promise to take generative coding assistants to the next level. Instead of providing developers with a kind of supercharged autocomplete, like most existing tools, this next generation can prototype, test, and debug code for you. The upshot is that developers could essentially turn into managers, who may spend more time reviewing and correcting code written by a model than writing it from scratch themselves.  But there’s more. Many of the people building generative coding assistants think that they could be a fast track to artificial general intelligence (AGI), the hypothetical superhuman technology that a number of top firms claim to have in their sights. “The first time we will see a massively economically valuable activity to have reached human-level capabilities will be in software development,” says Eiso Kant, CEO and cofounder of Poolside. (OpenAI has already boasted that its latest o3 model beat the company’s own chief scientist in a competitive coding challenge.) Welcome to the second wave of AI coding.  Correct code  Software engineers talk about two types of correctness. There’s the sense in which a program’s syntax (its grammar) is correct—meaning all the words, numbers, and mathematical operators are in the right place. This matters a lot more than grammatical correctness in natural language. Get one tiny thing wrong in thousands of lines of code and none of it will run. The first generation of coding assistants are now pretty good at producing code that’s correct in this sense. Trained on billions of pieces of code, they have assimilated the surface-level structures of many types of programs.   But there’s also the sense in which a program’s function is correct: Sure, it runs, but does it actually do what you wanted it to? It’s that second level of correctness that the new wave of generative coding assistants are aiming for—and this is what will really change the way software is made. “Large language models can write code that compiles, but they may not always write the program that you wanted,” says Alistair Pullen, a cofounder of Cosine. “To do that, you need to re-create the thought processes that a human coder would have gone through to get that end result.” The problem is that the data most coding assistants have been trained on—the billions of pieces of code taken from online repositories—doesn’t capture those thought processes. It represents a finished product, not what went into making it. “There’s a lot of code out there,” says Kant. “But that data doesn’t represent software development.” What Pullen, Kant, and others are finding is that to build a model that does a lot more than autocomplete—one that can come up with useful programs, test them, and fix bugs—you need to show it a lot more than just code. You need to show it how that code was put together.   In short, companies like Cosine and Poolside are building models that don’t just mimic what good code looks like—whether it works well or not—but mimic the process that produces such code in the first place. Get it right and the models will come up with far better code and far better bug fixes.  Breadcrumbs But you first need a data set that captures that process—the steps that a human developer might take when writing code. Think of these steps as a breadcrumb trail that a machine could follow to produce a similar piece of code itself. Part of that is working out what materials to draw from: Which sections of the existing codebase are needed for a given programming task? “Context is critical,” says Zencoder founder Andrew Filev. “The first generation of tools did a very poor job on the context, they would basically just look at your open tabs. But your repo [code repository] might have 5000 files and they’d miss most of it.” Zencoder has hired a bunch of search engine veterans to help it build a tool that can analyze large codebases and figure out what is and isn’t relevant. This detailed context reduces hallucinations and improves the quality of code that large language models can produce, says Filev: “We call it repo grokking.” Cosine also thinks context is key. But it draws on that context to create a new kind of data set. The company has asked dozens of coders to record what they were doing as they worked through hundreds of different programming tasks. “We asked them to write down everything,” says Pullen: “Why did you open that file? Why did you scroll halfway through? Why did you close it?” They also asked coders to annotate finished pieces of code, marking up sections that would have required knowledge of other pieces of code or specific documentation to write. Cosine then takes all that information and generates a large synthetic data set that maps the typical steps coders take, and the sources of information they draw on, to finished pieces of code. They use this data set to train a model to figure out what breadcrumb trail it might need to follow to produce a particular program, and then how to follow it.   Poolside, based in San Francisco, is also creating a synthetic data set that captures the process of coding, but it leans more on a technique called RLCE—reinforcement learning from code execution. (Cosine uses this too, but to a lesser degree.) RLCE is analogous to the technique used to make chatbots like ChatGPT slick conversationalists, known as RLHF—reinforcement learning from human feedback. With RLHF, a model is trained to produce text that’s more like the kind human testers say they favor. With RLCE, a model is trained to produce code that’s more like the kind that does what it is supposed to do when it is run (or executed).   Gaming the system Cosine and Poolside both say they are inspired by the approach DeepMind took with its game-playing model AlphaZero. AlphaZero was given the steps it could take—the moves in a game—and then left to play against itself over and over again, figuring out via trial and error what sequence of moves were winning moves and which were not.   “They let it explore moves at every possible turn, simulate as many games as you can throw compute at—that led all the way to beating Lee Sedol,” says Pengming Wang, a founding scientist at Poolside, referring to the Korean Go grandmaster that AlphaZero beat in 2016. Before Poolside, Wang worked at Google DeepMind on applications of AlphaZero beyond board games, including FunSearch, a version trained to solve advanced math problems. When that AlphaZero approach is applied to coding, the steps involved in producing a piece of code—the breadcrumbs—become the available moves in a game, and a correct program becomes winning that game. Left to play by itself, a model can improve far faster than a human could. “A human coder tries and fails one failure at a time,” says Kant. “Models can try things 100 times at once.” A key difference between Cosine and Poolside is that Cosine is using a custom version of GPT-4o provided by OpenAI, which makes it possible to train on a larger data set than the base model can cope with, but Poolside is building its own large language model from scratch. Poolside’s Kant thinks that training a model on code from the start will give better results than adapting an existing model that has sucked up not only billions of pieces of code but most of the internet. “I’m perfectly fine with our model forgetting about butterfly anatomy,” he says.   Cosine claims that its generative coding assistant, called Genie, tops the leaderboard on SWE-Bench, a standard set of tests for coding models. Poolside is still building its model but claims that what it has so far already matches the performance of GitHub’s Copilot. “I personally have a very strong belief that large language models will get us all the way to being as capable as a software developer,” says Kant. Not everyone takes that view, however. Illogical LLMs To Justin Gottschlich, the CEO and founder of Merly, large language models are the wrong tool for the job—period. He invokes his dog: “No amount of training for my dog will ever get him to be able to code, it just won’t happen,” he says. “He can do all kinds of other things, but he’s just incapable of that deep level of cognition.”   Having worked on code generation for more than a decade, Gottschlich has a similar sticking point with large language models. Programming requires the ability to work through logical puzzles with unwavering precision. No matter how well large language models may learn to mimic what human programmers do, at their core they are still essentially statistical slot machines, he says: “I can’t train an illogical system to become logical.” Instead of training a large language model to generate code by feeding it lots of examples, Merly does not show its system human-written code at all. That’s because to really build a model that can generate code, Gottschlich argues, you need to work at the level of the underlying logic that code represents, not the code itself. Merly’s system is therefore trained on an intermediate representation—something like the machine-readable notation that most programming languages get translated into before they are run. Gottschlich won’t say exactly what this looks like or how the process works. But he throws out an analogy: There’s this idea in mathematics that the only numbers that have to exist are prime numbers, because you can calculate all other numbers using just the primes. “Take that concept and apply it to code,” he says. Not only does this approach get straight to the logic of programming; it’s also fast, because millions of lines of code are reduced to a few thousand lines of intermediate language before the system analyzes them. Shifting mindsets What you think of these rival approaches may depend on what you want generative coding assistants to be.   In November, Cosine banned its engineers from using tools other than its own products. It is now seeing the impact of Genie on its own engineers, who often find themselves watching the tool as it comes up with code for them. “You now give the model the outcome you would like, and it goes ahead and worries about the implementation for you,” says Yang Li, another Cosine cofounder. Pullen admits that it can be baffling, requiring a switch of mindset. “We have engineers doing multiple tasks at once, flitting between windows,” he says. “While Genie is running code in one, they might be prompting it to do something else in another.” These tools also make it possible to protype multiple versions of a system at once. Say you’re developing software that needs a payment system built in. You can get a coding assistant to simultaneously try out several different options—Stripe, Mango, Checkout—instead of having to code them by hand one at a time. Genie can be left to fix bugs around the clock. Most software teams use bug-reporting tools that let people upload descriptions of errors they have encountered. Genie can read these descriptions and come up with fixes. Then a human just needs to review them before updating the code base. No single human understands the trillions of lines of code in today’s biggest software systems, says Li, “and as more and more software gets written by other software, the amount of code will only get bigger.” This will make coding assistants that maintain that code for us essential. “The bottleneck will become how fast humans can review the machine-generated code,” says Li. How do Cosine’s engineers feel about all this? According to Pullen, at least, just fine. “If I give you a hard problem, you’re still going to think about how you want to describe that problem to the model,” he says. “Instead of writing the code, you have to write it in natural language. But there’s still a lot of thinking that goes into that, so you’re not really taking the joy of engineering away. The itch is still scratched.” Some may adapt faster than others. Cosine likes to invite potential hires to spend a few days coding with its team. A couple of months ago it asked one such candidate to build a widget that would let employees share cool bits of software they were working on to social media.  The task wasn’t straightforward, requiring working knowledge of multiple sections of Cosine’s millions of lines of code. But the candidate got it done in a matter of hours. “This person who had never seen our code base turned up on Monday and by Tuesday afternoon he’d shipped something,” says Li. “We thought it would take him all week.” (They hired him.) But there’s another angle too. Many companies will use this technology to cut down on the number of programmers they hire. Li thinks we will soon see tiers of software engineers. At one end there will be elite developers with million-dollar salaries who can diagnose problems when the AI goes wrong. At the other end, smaller teams of 10 to 20 people will do a job that once required hundreds of coders. “It will be like how ATMs transformed banking,” says Li. “Anything you want to do will be determined by compute and not head count,” he says. “I think it’s generally accepted that the era of adding another few thousand engineers to your organization is over.” Warp drives Indeed, for Gottschlich, machines that can code better than humans are going to be essential. For him, that’s the only way we will build the vast, complex software systems that he thinks we will eventually need. Like many in Silicon Valley, he anticipates a future in which humans move to other planets. That’s only going to be possible if we get AI to build the software required, he says: “Merly’s real goal is to get us to Mars.” Gottschlich prefers to talk about “machine programming” rather than “coding assistants,” because he thinks that term frames the problem the wrong way. “I don’t think that these systems should be assisting humans—I think humans should be assisting them,” he says. “They can move at the speed of AI. Why restrict their potential?” “There’s this cartoon called The Flintstones where they have these cars, but they only move when the drivers use their feet,” says Gottschlich. “This is sort of how I feel most people are doing AI for software systems.” “But what Merly’s building is, essentially, spaceships,” he adds. He’s not joking. “And I don’t think spaceships should be powered by humans on a bicycle. Spaceships should be powered by a warp engine.” If that sounds wild—it is. But there’s a serious point to be made about what the people building this technology think the end goal really is. Gottschlich is not an outlier with his galaxy-brained take. Despite their focus on products that developers will want to use today, most of these companies have their sights on a far bigger payoff. Visit Cosine’s website and the company introduces itself as a “Human Reasoning Lab.” It sees coding as just the first step toward a more general-purpose model that can mimic human problem-solving in a number of domains. Poolside has similar goals: The company states upfront that it is building AGI. “Code is a way of formalizing reasoning,” says Kant. Wang invokes agents. Imagine a system that can spin up its own software to do any task on the fly, he says. “If you get to a point where your agent can really solve any computational task that you want through the means of software—that is a display of AGI, essentially.” Down here on Earth, such systems may remain a pipe dream. And yet software engineering is changing faster than many at the cutting edge expected.  “We’re not at a point where everything’s just done by machines, but we’re definitely stepping away from the usual role of a software engineer,” says Cosine’s Pullen. “We’re seeing the sparks of that new workflow—what it means to be a software engineer going into the future.”
Ask people building generative AI what generative AI is good for right now—what they’re really fired up about—and many will tell you: coding. 

“That’s something that’s been very exciting for developers,” Jared Kaplan, chief scientist at Anthropic, told MIT Technology Review this month: “It’s really understanding what’s wrong with code, debugging it.”

Copilot, a tool built on top of OpenAI’s large language models and launched by Microsoft-backed GitHub in 2022, is now used by millions of developers around the world. Millions more turn to general-purpose chatbots like Anthropic’s Claude, OpenAI’s ChatGPT, and Google DeepMind’s Gemini for everyday help.

“Today, more than a quarter of all new code at Google is generated by AI, then reviewed and accepted by engineers,” Alphabet CEO Sundar Pichai claimed on an earnings call in October: “This helps our engineers do more and move faster.” Expect other tech companies to catch up, if they haven’t already.

It’s not just the big beasts rolling out AI coding tools. A bunch of new startups have entered this buzzy market too. Newcomers such as Zencoder, Merly, Cosine, Tessl (valued at $750 million within months of being set up), and Poolside (valued at $3 billion before it even released a product) are all jostling for their slice of the pie. “It actually looks like developers are willing to pay for copilots,” says Nathan Benaich, an analyst at investment firm Air Street Capital: “And so code is one of the easiest ways to monetize AI.”

Such companies promise to take generative coding assistants to the next level. Instead of providing developers with a kind of supercharged autocomplete, like most existing tools, this next generation can prototype, test, and debug code for you. The upshot is that developers could essentially turn into managers, who may spend more time reviewing and correcting code written by a model than writing it from scratch themselves. 

But there’s more. Many of the people building generative coding assistants think that they could be a fast track to artificial general intelligence (AGI), the hypothetical superhuman technology that a number of top firms claim to have in their sights.

“The first time we will see a massively economically valuable activity to have reached human-level capabilities will be in software development,” says Eiso Kant, CEO and cofounder of Poolside. (OpenAI has already boasted that its latest o3 model beat the company’s own chief scientist in a competitive coding challenge.)

Welcome to the second wave of AI coding. 

Correct code 

Software engineers talk about two types of correctness. There’s the sense in which a program’s syntax (its grammar) is correct—meaning all the words, numbers, and mathematical operators are in the right place. This matters a lot more than grammatical correctness in natural language. Get one tiny thing wrong in thousands of lines of code and none of it will run.

The first generation of coding assistants are now pretty good at producing code that’s correct in this sense. Trained on billions of pieces of code, they have assimilated the surface-level structures of many types of programs.  

But there’s also the sense in which a program’s function is correct: Sure, it runs, but does it actually do what you wanted it to? It’s that second level of correctness that the new wave of generative coding assistants are aiming for—and this is what will really change the way software is made.

“Large language models can write code that compiles, but they may not always write the program that you wanted,” says Alistair Pullen, a cofounder of Cosine. “To do that, you need to re-create the thought processes that a human coder would have gone through to get that end result.”

The problem is that the data most coding assistants have been trained on—the billions of pieces of code taken from online repositories—doesn’t capture those thought processes. It represents a finished product, not what went into making it. “There’s a lot of code out there,” says Kant. “But that data doesn’t represent software development.”

What Pullen, Kant, and others are finding is that to build a model that does a lot more than autocomplete—one that can come up with useful programs, test them, and fix bugs—you need to show it a lot more than just code. You need to show it how that code was put together.  

In short, companies like Cosine and Poolside are building models that don’t just mimic what good code looks like—whether it works well or not—but mimic the process that produces such code in the first place. Get it right and the models will come up with far better code and far better bug fixes. 

Breadcrumbs

But you first need a data set that captures that process—the steps that a human developer might take when writing code. Think of these steps as a breadcrumb trail that a machine could follow to produce a similar piece of code itself.

Part of that is working out what materials to draw from: Which sections of the existing codebase are needed for a given programming task? “Context is critical,” says Zencoder founder Andrew Filev. “The first generation of tools did a very poor job on the context, they would basically just look at your open tabs. But your repo [code repository] might have 5000 files and they’d miss most of it.”

Zencoder has hired a bunch of search engine veterans to help it build a tool that can analyze large codebases and figure out what is and isn’t relevant. This detailed context reduces hallucinations and improves the quality of code that large language models can produce, says Filev: “We call it repo grokking.”

Cosine also thinks context is key. But it draws on that context to create a new kind of data set. The company has asked dozens of coders to record what they were doing as they worked through hundreds of different programming tasks. “We asked them to write down everything,” says Pullen: “Why did you open that file? Why did you scroll halfway through? Why did you close it?” They also asked coders to annotate finished pieces of code, marking up sections that would have required knowledge of other pieces of code or specific documentation to write.

Cosine then takes all that information and generates a large synthetic data set that maps the typical steps coders take, and the sources of information they draw on, to finished pieces of code. They use this data set to train a model to figure out what breadcrumb trail it might need to follow to produce a particular program, and then how to follow it.  

Poolside, based in San Francisco, is also creating a synthetic data set that captures the process of coding, but it leans more on a technique called RLCE—reinforcement learning from code execution. (Cosine uses this too, but to a lesser degree.)

RLCE is analogous to the technique used to make chatbots like ChatGPT slick conversationalists, known as RLHF—reinforcement learning from human feedback. With RLHF, a model is trained to produce text that’s more like the kind human testers say they favor. With RLCE, a model is trained to produce code that’s more like the kind that does what it is supposed to do when it is run (or executed).  

Gaming the system

Cosine and Poolside both say they are inspired by the approach DeepMind took with its game-playing model AlphaZero. AlphaZero was given the steps it could take—the moves in a game—and then left to play against itself over and over again, figuring out via trial and error what sequence of moves were winning moves and which were not.  

“They let it explore moves at every possible turn, simulate as many games as you can throw compute at—that led all the way to beating Lee Sedol,” says Pengming Wang, a founding scientist at Poolside, referring to the Korean Go grandmaster that AlphaZero beat in 2016. Before Poolside, Wang worked at Google DeepMind on applications of AlphaZero beyond board games, including FunSearch, a version trained to solve advanced math problems.

When that AlphaZero approach is applied to coding, the steps involved in producing a piece of code—the breadcrumbs—become the available moves in a game, and a correct program becomes winning that game. Left to play by itself, a model can improve far faster than a human could. “A human coder tries and fails one failure at a time,” says Kant. “Models can try things 100 times at once.”

A key difference between Cosine and Poolside is that Cosine is using a custom version of GPT-4o provided by OpenAI, which makes it possible to train on a larger data set than the base model can cope with, but Poolside is building its own large language model from scratch.

Poolside’s Kant thinks that training a model on code from the start will give better results than adapting an existing model that has sucked up not only billions of pieces of code but most of the internet. “I’m perfectly fine with our model forgetting about butterfly anatomy,” he says.  

Cosine claims that its generative coding assistant, called Genie, tops the leaderboard on SWE-Bench, a standard set of tests for coding models. Poolside is still building its model but claims that what it has so far already matches the performance of GitHub’s Copilot.

“I personally have a very strong belief that large language models will get us all the way to being as capable as a software developer,” says Kant.

Not everyone takes that view, however.

Illogical LLMs

To Justin Gottschlich, the CEO and founder of Merly, large language models are the wrong tool for the job—period. He invokes his dog: “No amount of training for my dog will ever get him to be able to code, it just won’t happen,” he says. “He can do all kinds of other things, but he’s just incapable of that deep level of cognition.”  

Having worked on code generation for more than a decade, Gottschlich has a similar sticking point with large language models. Programming requires the ability to work through logical puzzles with unwavering precision. No matter how well large language models may learn to mimic what human programmers do, at their core they are still essentially statistical slot machines, he says: “I can’t train an illogical system to become logical.”

Instead of training a large language model to generate code by feeding it lots of examples, Merly does not show its system human-written code at all. That’s because to really build a model that can generate code, Gottschlich argues, you need to work at the level of the underlying logic that code represents, not the code itself. Merly’s system is therefore trained on an intermediate representation—something like the machine-readable notation that most programming languages get translated into before they are run.

Gottschlich won’t say exactly what this looks like or how the process works. But he throws out an analogy: There’s this idea in mathematics that the only numbers that have to exist are prime numbers, because you can calculate all other numbers using just the primes. “Take that concept and apply it to code,” he says.

Not only does this approach get straight to the logic of programming; it’s also fast, because millions of lines of code are reduced to a few thousand lines of intermediate language before the system analyzes them.

Shifting mindsets

What you think of these rival approaches may depend on what you want generative coding assistants to be.  

In November, Cosine banned its engineers from using tools other than its own products. It is now seeing the impact of Genie on its own engineers, who often find themselves watching the tool as it comes up with code for them. “You now give the model the outcome you would like, and it goes ahead and worries about the implementation for you,” says Yang Li, another Cosine cofounder.

Pullen admits that it can be baffling, requiring a switch of mindset. “We have engineers doing multiple tasks at once, flitting between windows,” he says. “While Genie is running code in one, they might be prompting it to do something else in another.”

These tools also make it possible to protype multiple versions of a system at once. Say you’re developing software that needs a payment system built in. You can get a coding assistant to simultaneously try out several different options—Stripe, Mango, Checkout—instead of having to code them by hand one at a time.

Genie can be left to fix bugs around the clock. Most software teams use bug-reporting tools that let people upload descriptions of errors they have encountered. Genie can read these descriptions and come up with fixes. Then a human just needs to review them before updating the code base.

No single human understands the trillions of lines of code in today’s biggest software systems, says Li, “and as more and more software gets written by other software, the amount of code will only get bigger.”

This will make coding assistants that maintain that code for us essential. “The bottleneck will become how fast humans can review the machine-generated code,” says Li.

How do Cosine’s engineers feel about all this? According to Pullen, at least, just fine. “If I give you a hard problem, you’re still going to think about how you want to describe that problem to the model,” he says. “Instead of writing the code, you have to write it in natural language. But there’s still a lot of thinking that goes into that, so you’re not really taking the joy of engineering away. The itch is still scratched.”

Some may adapt faster than others. Cosine likes to invite potential hires to spend a few days coding with its team. A couple of months ago it asked one such candidate to build a widget that would let employees share cool bits of software they were working on to social media. 

The task wasn’t straightforward, requiring working knowledge of multiple sections of Cosine’s millions of lines of code. But the candidate got it done in a matter of hours. “This person who had never seen our code base turned up on Monday and by Tuesday afternoon he’d shipped something,” says Li. “We thought it would take him all week.” (They hired him.)

But there’s another angle too. Many companies will use this technology to cut down on the number of programmers they hire. Li thinks we will soon see tiers of software engineers. At one end there will be elite developers with million-dollar salaries who can diagnose problems when the AI goes wrong. At the other end, smaller teams of 10 to 20 people will do a job that once required hundreds of coders. “It will be like how ATMs transformed banking,” says Li.

“Anything you want to do will be determined by compute and not head count,” he says. “I think it’s generally accepted that the era of adding another few thousand engineers to your organization is over.”

Warp drives

Indeed, for Gottschlich, machines that can code better than humans are going to be essential. For him, that’s the only way we will build the vast, complex software systems that he thinks we will eventually need. Like many in Silicon Valley, he anticipates a future in which humans move to other planets. That’s only going to be possible if we get AI to build the software required, he says: “Merly’s real goal is to get us to Mars.”

Gottschlich prefers to talk about “machine programming” rather than “coding assistants,” because he thinks that term frames the problem the wrong way. “I don’t think that these systems should be assisting humans—I think humans should be assisting them,” he says. “They can move at the speed of AI. Why restrict their potential?”

“There’s this cartoon called The Flintstones where they have these cars, but they only move when the drivers use their feet,” says Gottschlich. “This is sort of how I feel most people are doing AI for software systems.”

“But what Merly’s building is, essentially, spaceships,” he adds. He’s not joking. “And I don’t think spaceships should be powered by humans on a bicycle. Spaceships should be powered by a warp engine.”

If that sounds wild—it is. But there’s a serious point to be made about what the people building this technology think the end goal really is.

Gottschlich is not an outlier with his galaxy-brained take. Despite their focus on products that developers will want to use today, most of these companies have their sights on a far bigger payoff. Visit Cosine’s website and the company introduces itself as a “Human Reasoning Lab.” It sees coding as just the first step toward a more general-purpose model that can mimic human problem-solving in a number of domains.

Poolside has similar goals: The company states upfront that it is building AGI. “Code is a way of formalizing reasoning,” says Kant.

Wang invokes agents. Imagine a system that can spin up its own software to do any task on the fly, he says. “If you get to a point where your agent can really solve any computational task that you want through the means of software—that is a display of AGI, essentially.”

Down here on Earth, such systems may remain a pipe dream. And yet software engineering is changing faster than many at the cutting edge expected. 

“We’re not at a point where everything’s just done by machines, but we’re definitely stepping away from the usual role of a software engineer,” says Cosine’s Pullen. “We’re seeing the sparks of that new workflow—what it means to be a software engineer going into the future.”
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Lenovo expands virtualization portfolio for AI

On the services front, Lenovo is restructuring its infrastructure deployment offerings around three defined service levels: Standard Deploy, Premier Deploy, and Premier Deploy Plus. The options are designed to allow customers to select a deployment model based on multiple factors, including project complexity, business criticality, internal IT capabilities and the

Read More »

Practical quantum computers are over a decade away, says NEC

A practical, commercial quantum computer is over a decade away, executives at Japanese IT services company NEC are reported as saying. That’s why, according to Japanese news publication The Mainichi, company has pulled the plug on its plans to develop a quantum computer — although it will still continue research

Read More »

Huawei aims to deliver faster AI chips, faster

Huawei is accelerating its AI chips development, bringing forward the release of the next two models in the family powering its AI computing clusters by three to nine months. Its Ascend 960 chip family is a major component of supercomputing portfolio. It now plans to release the Ascend 960DT in

Read More »

QatarEnergy NFE LNG Train 1 to start 1H 2027; Ras Laffan repairs to take 3 years

QatarEnergy expects the 8-million tonne/year (tpy) first train of its 32-million tpy North Field East (NFE) LNG expansion project to begin operations in first-half 2027, Reuters reported, noting that the timing of additional trains would depend on ​the Strait of Hormuz crisis. Speaking at the Qatar Economic Forum Special Edition in New York, QatarEnergy chief executive officer (CEO) and Qatari minister of energy affairs, Saad al-Kaabi, attributed the uncertainty to delays in delivering equipment needed for the expansion caused by the Strait of Hormuz disruption. Regarding damage to Qatar’s natural gas infrastructure sustained during the Iran war and its possible return, al-Kaabi said that repairs to the two LNG trains damaged at Ras Laffan (17% of its production capacity) would take 3 years. A damaged gas-to-liquids (GTL) train is expected to return to service first-quarter 2027. Al-Kaabi expects “a few” NFE trains to start production as 2027 progresses, and output from the 16-million tpy North Field South (NFS) expansion to begin in 2028, according to Reuters. The NFE and NFS projects are part of the overall North Field expansion program that also includes the North Field West project, which together will raise Qatar’s LNG production capacity to 142 million tpy from the current 77 million tpy. Al-Kaabi also thanked Qatar’s neighbors for being willing to allow construction of a gas pipeline across their territories to bypass Hormuz, while noting that doing so would be “redundant” and made “no economic sense” in light of the already underway North Field expansion project. “As for resuming operations,” he added, “Qatar is ready to resume normal operations within a few weeks of the reopening of the Strait of Hormuz.” More generally, al-Kaabi rejected the notion that the Strait of Hormuz was obsolete, saying that it “carries trade in all products, not only oil and

Read More »

ESENTIA to acquire Guadalajara-Manzanillo natural gas pipeline system

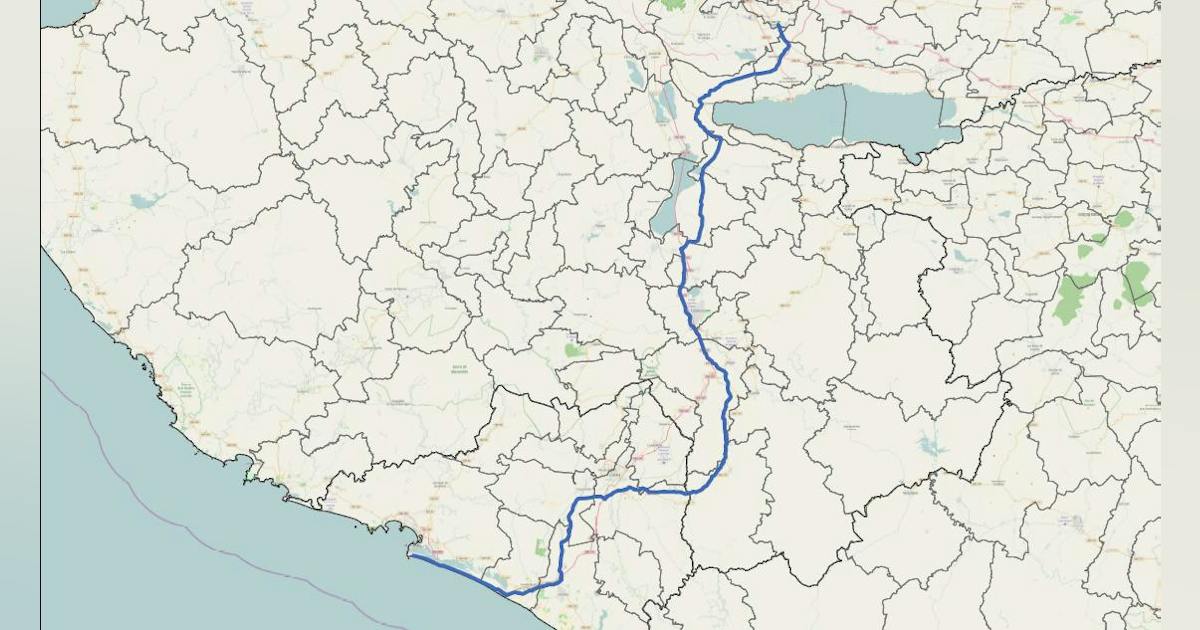
ESENTIA Energy Development SAB de CV, Mexico City, has agreed to acquire 100% of the equity interests of Energía Occidente de México S de RL de CV (EOM) from TC Energy Corp., Calgary, for a gross purchase price of $400 million. EOM owns and operates the 313-km Guadalajara-Manzanillo natural gas pipeline system, which runs from the Guadalajara area in Jalisco to Manzanillo, Colima, and is directly interconnected with ESENTIA’s Villa de Reyes-Aguascalientes-Guadalajara (VAG) pipeline system operated by Esentia Pipeline de Occidente S de RL de CV, an indirect subsidiary of ESENTIA. The pipeline transports up to 500 MMcfd of natural gas, connecting imported LNG supply near Manzanillo and continental gas supply near Guadalajara to power plants and industrial customers in Colima and Jalisco. Upon closing, the acquisition will extend ESENTIA’s pipeline network to the Port of Manzanillo on Mexico’s Pacific coast, making the company the only private operator with an integrated natural gas pipeline system connecting the Permian basin in Texas to Mexico’s Pacific coast, the company said in a release Sept. 21. The deal is part of ESENTIA’s strategy to build a cross-border transportation system and would “expand ESENTIA’s ability to serve existing and prospective customers within the combined system’s area of influence, including demand from power generation, industrial customers and potential LNG-related projects,” said Daniel Bustos, chief executive officer. ESENTIA also highlighted construction of its Aguascalientes Compression Station, which is expected to increase capacity on the VAG pipeline system beginning in early 2027. The project is part of the company’s three-phase expansion plan, which includes a total estimated investment of $680 million and an increase of 660 MMcfd in natural gas transportation capacity. For TC Energy, the transaction creates “optionality to redeploy proceeds from a mature asset towards high-value growth opportunities across our North American footprint,” said François

Read More »

Energy Department Announces $99 Million for 21 Projects to Advance U.S. Geothermal Energy Development

WASHINGTON—The U.S. Department of Energy (DOE) today announced more than $99 million for 21 projects selected to advance geothermal energy development across the United States. The projects will conduct field-scale tests of next-generation geothermal technologies and exploration drilling to characterize and potentially confirm promising geothermal resources.  Thanks to President Trump’s leadership, the Energy Department is advancing American geothermal innovation to unlock the nation’s abundant domestic energy resources. Geothermal can provide reliable, around-the-clock power to help meet growing demand while strengthening U.S. energy security. “These projects will empower American innovators to unlock the tremendous geothermal resources beneath our feet,” said DOE Under Secretary of Energy Kyle Haustveit. “Under President Trump’s leadership, we’re advancing next-generation geothermal technologies that can lower costs, strengthen American energy dominance, and turn more of our vast domestic geothermal resources into reliable and affordable power.” The 21 projects will advance geothermal development in two key areas. Five projects will conduct field-scale enhanced geothermal systems (EGS) tests to validate technologies under real-world conditions, while 16 additional projects will conduct exploration drilling to identify and characterize promising next-generation geothermal resources. Together, these efforts will help reduce technical and development risk and provide the information needed to support future commercial projects and investment.   Data generated by these projects will be publicly available through DOE’s Geothermal Data Repository (GDR), giving industry, researchers, and other stakeholders access to information from the field tests and geothermal exploration activities. Making these data available can extend the value of the projects beyond individual sites by helping inform future technology development and geothermal exploration across the industry.  Learn more about the selected projects here.  Selection for award negotiations is not a commitment by DOE to issue an award or provide funding. Before funding is issued, DOE and the applicants will undergo a negotiation process, and DOE may cancel negotiations and rescind the

Read More »

INA commissions new delayed coker at Rijeka refinery

Croatia’s INA Industrija Nafte DD has started up a new delayed coking unit (DCU) at its 90,000-b/d Rijeka refinery along the northern part of the Adriatic Sea, marking a major milestone in the refinery’s upgrading project. Following mechanical completion and commissioning, INA introduced feedstock into the DCU on Sept. 1, beginning production, majority owner MOL Group said in a release Sept. 21. The unit has operated continuously since startup and has reached about 70% of design capacity, the company said. The DCU—which  converts heavy refinery residues into higher-value products—has produced all key products at required quality and is anticipated to increase diesel production by as much as 30% from the same crude volume. MOL Group said the new DCU unit—once fully operable—also will eliminate Croatia’s need to import vacuum gas oil (VGO). The Rijeka refinery upgrade represents an investment of nearly €700 million, which is included in a combined €1.3-billion joint investment by INA and MOL Group in refining and logistics modernization during the past 12 years. “The start-up of the new unit went really well,” said Zsuzsanna Ortutay, president of INA’s management board, adding that the DCU would improve the sustainability and profitability of INA’s refining business while supporting energy supply in Croatia and the surrounding region. INA  plans to increase throughput and optimize process performance at the new unit gradually, with stable operation anticipated by yearend, followed by final plant performance testing and project closeout activities. Rijeka DCU project background INA awarded a lump-sum, turnkey engineering, procurement, and construction contract for the project to Maire Tecnimont SPA subsidiary KT-Kinetics Technology SPA in December 2019. The contract covered a new delayed coking complex with coke handling and ship-loading facilities, a sour-water stripper, and amine recovery units. It also included modifications to the existing hydrocracker, sulfur recovery unit, utilities, and

Read More »

Oil prices retreat as Middle East supply concerns ease amid diplomatic talks

Oil prices fell on Monday, Sept.21, with Brent extending its retreat from recent highs, as recovering Saudi crude exports and hopes for renewed US-Iran diplomacy eased fears of an immediate Middle East supply crunch. Brent crude futures and US West Texas Intermediate (WTI) crude dipped below $100/bbl to their lowest since Sept. 9. The move extends a four-session retreat from the recent surge in crude prices as traders reassess how severely regional conflict is constraining physical oil flows. Despite the continued uncertainty in the Middle East, news of a major rebound in Saudi crude oil exports in September weighed on prices. Saudi Arabia has increased shipments through the Strait of Hormuz to compensate for disruptions to its East-West pipeline following Houthi attacks on Saudi energy infrastructure. Saudi crude flows through the strait have averaged roughly 2.9 million b/d over the past 6 days, compared with about 700,000 b/d in August, according to satellite data cited by JPMorgan analysts. US Central Command Commander Admiral Brad Cooper confirmed on Sept.19 that, thanks to US naval escorts and mine-clearance efforts, oil and LNG shipments through the Strait of Hormuz in the past 2 weeks reached the highest level in 6 months. The recovery in Gulf exports has helped ease fears that attacks on Saudi infrastructure would translate into a prolonged loss of barrels from the global market. Meanwhile, investors are closely monitoring signs of potential diplomatic progress between Washington and Tehran during this week’s UN General Assembly. US President Donald Trump has expressed a willingness to meet with Iranian President Masoud Pezeshkian, while Iran has reportedly conveyed the conditions for resuming negotiations. Expectations that talks could eventually reduce regional tensions have removed some of the geopolitical risk premium that pushed crude prices higher earlier this month. Still, physical oil markets remain strained. Middle Eastern producers

Read More »

Trump Administration Moves to Keep Indiana Coal Plants Operating to Support Grid Reliability

WASHINGTON—U.S. Secretary of Energy Chris Wright issued emergency orders to keep two Indiana coal plants operational to ensure Americans in the Midwest region of the United States have continued access to affordable, reliable, and secure electricity. The orders direct the Northern Indiana Public Service Company (NIPSCO), CenterPoint Energy, and the Midcontinent Independent System Operator, Inc. (MISO) to take all measures necessary to ensure specified generation units at both the R.M. Schahfer and F.B. Culley generating stations in Indiana are available to operate. Certain generation units at these coal plants were scheduled to shut down at the end of 2025.  The orders will minimize the risk of unnecessary blackouts for the American people. Since the U.S. Department of Energy’s (DOE) original orders were issued on December 23, 2025, the Schahfer and Culley coal plants have proven critical to MISO’s operations, operating during periods of high energy demand and low levels of intermittent energy production, including during Winter Storm Fern.   “Forcing reliable, dispatchable coal generation off the grid would compromise energy reliability and needlessly raises energy costs for Americans,” said Energy Secretary Wright. “Midwestern families should not be forced to pay the price for the misguided energy subtraction policies of the past. They deserve affordable, reliable, and secure energy, regardless of the wind blowing or the sun shining.” Thanks to President Trump’s leadership, coal generating plants across the country are being saved from premature retirement. For example, in 2025, more than 17 gigawatts of coal power electricity generation were saved from going offline.  The availability of R.M. Schahfer and F.B. Culley generating stations to operate will continue to be an asset to maintain reliability in the MISO region and is necessary to address elevated reliability risks in that region during extreme weather and reduce the risk of power outages that could threaten public health and safety. As

Read More »

How Communities Can Plan for AI Data Centers Before the Projects Arrive

The collision between AI infrastructure development and community opposition has become one of the defining data center stories of 2026. Developers are pursuing larger campuses, more power and compressed delivery schedules as AI accelerates demand for computing capacity. Meanwhile, local planning boards, elected officials and residents are increasingly being asked to make decisions about facilities whose scale, energy requirements and technological purpose may be unlike anything previously contemplated in their comprehensive plans. That gap is where Ilissa Miller believes much of the conflict begins. Miller, founder and CEO of iMiller Public Relations and a board member of the Open Infrastructure Exchange (OIX), joined the Data Center Frontier Show to discuss the OIX Digital Infrastructure Framework, an effort designed to give municipalities a more systematic way to think about data centers and other digital infrastructure before an individual development application lands in front of them. The idea is straightforward: communities routinely create long-range plans defining where homes, commercial development, industry and other land uses should go. Digital infrastructure should be part of that process as well. “Our vision for the framework was to help solve the problem by empowering communities to think about digital infrastructure,” Miller said, so municipalities can incorporate it into their comprehensive master plans and maintain control over how land is ultimately used. That distinction is key. The framework is not intended to convince communities to approve data centers. Nor does it prescribe what a town or county should decide. Instead, Miller said, it is meant to help public officials ask the right questions early enough to make those decisions deliberately. The Data Center May Not Be in the Plan One of the industry’s recurring problems is deceptively basic: many municipalities never anticipated data centers when writing their zoning codes and comprehensive plans. A parcel might already be

Read More »

Executive Roundtable: AI Infrastructure Under Pressure

Matt Vincent is Editor in Chief of Data Center Frontier, where he leads editorial strategy and coverage focused on the infrastructure powering cloud computing, artificial intelligence, and the digital economy. A veteran B2B technology journalist with more than two decades of experience, Vincent specializes in the intersection of data centers, power, cooling, and emerging AI-era infrastructure. Since assuming the EIC role in 2023, he has helped guide Data Center Frontier’s coverage of the industry’s transition into the gigawatt-scale AI era, with a focus on hyperscale development, behind-the-meter power strategies, liquid cooling architectures, and the evolving energy demands of high-density compute, while working closely with the Digital Infrastructure Group at Endeavor Business Media to expand the brand’s analytical and multimedia footprint. Vincent also hosts The Data Center Frontier Show podcast, where he interviews industry leaders across hyperscale, colocation, utilities, and the data center supply chain to examine the technologies and business models reshaping digital infrastructure. Since its inception he serves as Head of Content for the Data Center Frontier Trends Summit. Before becoming Editor in Chief, he served in multiple senior editorial roles across Endeavor Business Media’s digital infrastructure portfolio, with coverage spanning data centers and hyperscale infrastructure, structured cabling and networking, telecom and datacom, IP physical security, and wireless and Pro AV markets. He began his career in 2005 within PennWell’s Advanced Technology Division and later held senior editorial positions supporting brands such as Cabling Installation & Maintenance, Lightwave Online, Broadband Technology Report, and Smart Buildings Technology. Vincent is a frequent moderator, interviewer, and keynote speaker at industry events including the HPC Forum, where he delivers forward-looking analysis on how AI and high-performance computing are reshaping digital infrastructure. He graduated with honors from Indiana University Bloomington with a B.A. in English Literature and Creative Writing and lives in southern New Hampshire with

Read More »

California joins US states clamping down on data center gold rush

“Dismissing fears around water consumption, for example, by showing a spreadsheet at a local planning committee meeting, doesn’t resolve concerns for a community that is already suspicious,” he said. Community opposition “is real, and it’s everywhere,” and the new strategic pillar for data center builders and operators is social outreach, Kimball noted. Those proposing data centers must be able to provide credible answers about usage and community impacts, listen to concerns, and commit to transparency. Most enterprises aren’t building gigawatt campuses, he pointed out, but they are paying the price downstream in colocation availability, lead times, pricing, and other factors. Predictability is the big question, supply is already tight, and every delayed project removes capacity factored into forecasts.

Read More »

Communities are blocking data centers before they’re even proposed

“Dismissing fears around water consumption, for example, by showing a spreadsheet at a local planning committee meeting, doesn’t resolve concerns for a community that is already suspicious,” he said. Community opposition “is real, and it’s everywhere,” and the new strategic pillar for data center builders and operators is social outreach, Kimball noted. Those proposing data centers must be able to provide credible answers about usage and community impacts, listen to concerns, and commit to transparency. Most enterprises aren’t building gigawatt campuses, he pointed out, but they are paying the price downstream in colocation availability, lead times, pricing, and other factors. Predictability is the big question, supply is already tight, and every delayed project removes capacity factored into forecasts.

Read More »

Data Centre West 2026: Alberta Moves From Data Center Ambition to Execution

Firm Power Is an Architecture That brought the morning back to its recurring problem: What counts as available power? During the “Solving for Power” panel, moderator Lillian Kasa of Metlen Energy & Metals argued that data centers cannot operate on announcements. They need reliable electricity delivered on a schedule and backed by a commercial structure that can be financed. Margarita Patria of Charles River Associates made the distinction even sharper. Firm power is not merely generation. It is generation, transmission and fuel availability working together. Todd Detling of FortisAlberta added an important Alberta-specific qualification. Despite perceptions that the province had substantial transmission capacity available for new development, FortisAlberta is encountering constraints, particularly around the Edmonton and Calgary fringes. At the distribution level, the demand is already material. Detling said FortisAlberta has connected nearly 80 MW of data center load over the past several years, has approximately another 80 MW in the build queue, and has received roughly 300 MW in additional requests. Those smaller increments matter in a market dominated rhetorically by gigawatt announcements. They are another indication that developers are searching for power pathways they can execute now. AI Is Not Just a Bigger Load Tesla’s Sean Jones added another technical wrinkle: AI training loads can change extremely quickly. Data center power planning traditionally focuses heavily on annual consumption, peak demand and hourly load. GPU clusters can create significant changes at the second or even sub-second level. Jones described AI training demand falling from full load to around 30% in less than a second. That kind of movement can be difficult for onsite turbines and reciprocating generators to follow and potentially disruptive to the grid. Battery energy storage is therefore taking on a different role. The familiar data center battery story is backup power. The emerging AI story is

Read More »

Local AI is getting small enough to make every app multilingual

On-device translation used to mean a separate model for every language you wanted to support. English to French, English to German, and so on. However, that becomes unsustainable at a global scale when you’re talking about thousands of possible language pairs. Add to that the fact that most developers have to either send translation requests to the cloud to get fast, accurate results, or keep it local with restricted language support. Tether’s AI Research team has developed a family of multilingual translation models, TranslatePsy-EuroNano, that each support nine European languages, with deployment built around a pair of multilingual models rather than separate bilingual models for every language pair. What makes this possible Supporting a full European market on-device has previously meant bundling dozens of separate model files, but this is impractical for mobile apps and those building them. Tether AI’s multilingual open‑source edge translation models set the standard for efficiency, quality, and speed. For developers, the possibilities are endless. Using English as a pivot, the models remain comparable to Mozilla Firefox’s Bergamot-based translation system while dramatically reducing the size of on-device translation. At its smallest tier, Tether’s deployment is 17.6 times smaller while maintaining comparable translation quality. Tether’s deployment takes up 36MB to 89MB, depending on the tier you use. By comparison, the equivalent Firefox setup requires 18 separate bilingual models totaling 633MB to provide the same language coverage. The models are small enough to run efficiently on edge devices while supporting nine European languages from a single multilingual deployment, making multilingual experiences practical for a much wider range of software. Potential applications include travel and navigation apps, educational platforms that present lessons and resources on-device. The models are also designed for academics and researchers. Because the weights are openly available, researchers can fine-tune them for specialized domains, like customer

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »