Stay Ahead, Stay ONMINE

Training Large Language Models: From TRPO to GRPO

Deepseek has recently made quite a buzz in the AI community, thanks to its impressive performance at relatively low costs. I think this is a perfect opportunity to dive deeper into how Large Language Models (LLMs) are trained. In this article, we will focus on the Reinforcement Learning (RL) side of things: we will cover […]

Deepseek has recently made quite a buzz in the AI community, thanks to its impressive performance at relatively low costs. I think this is a perfect opportunity to dive deeper into how Large Language Models (LLMs) are trained. In this article, we will focus on the Reinforcement Learning (RL) side of things: we will cover TRPO, PPO, and, more recently, GRPO (don’t worry, I will explain all these terms soon!) 

I have aimed to keep this article relatively easy to read and accessible, by minimizing the math, so you won’t need a deep Reinforcement Learning background to follow along. However, I will assume that you have some familiarity with Machine Learning, Deep Learning, and a basic understanding of how LLMs work.

I hope you enjoy the article!

The 3 steps of LLM training
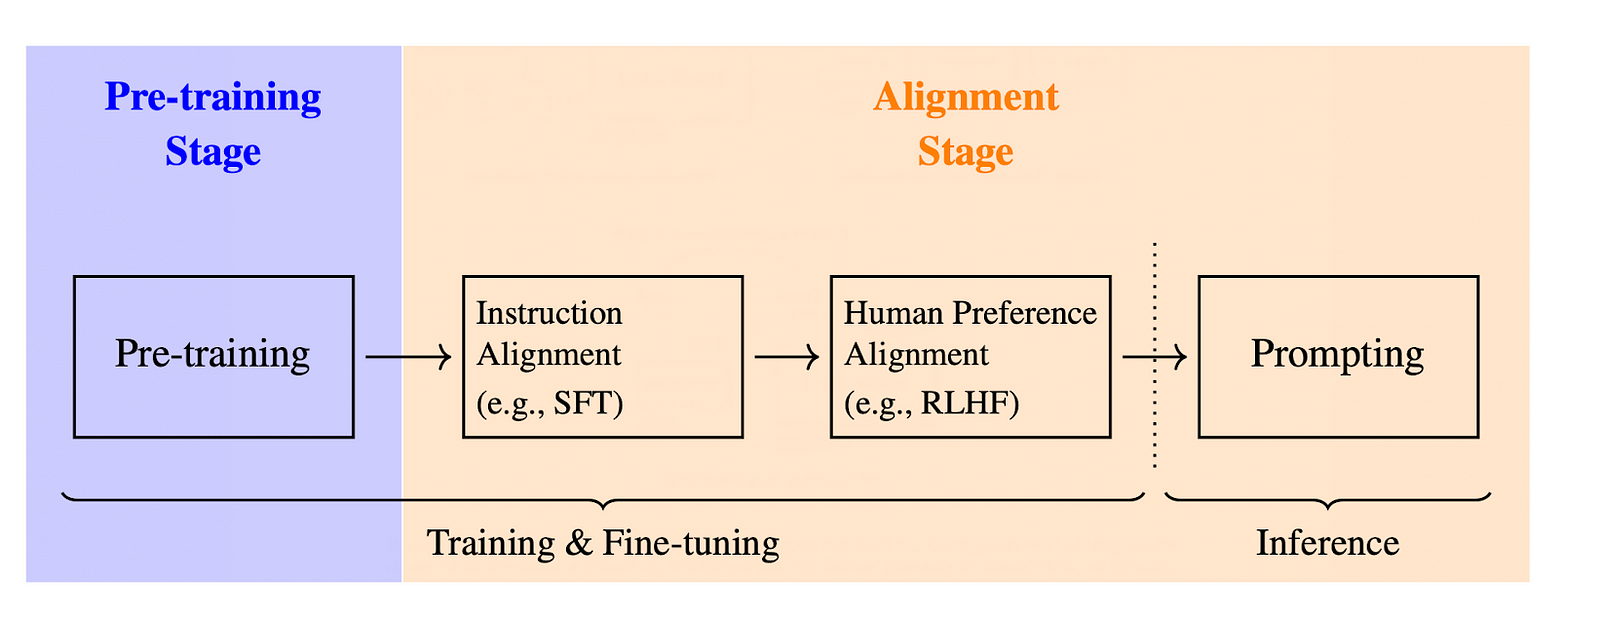
The 3 steps of LLM training [1]

Before diving into RL specifics, let’s briefly recap the three main stages of training a Large Language Model:

  • Pre-training: the model is trained on a massive dataset to predict the next token in a sequence based on preceding tokens.
  • Supervised Fine-Tuning (SFT): the model is then fine-tuned on more targeted data and aligned with specific instructions.
  • Reinforcement Learning (often called RLHF for Reinforcement Learning with Human Feedback): this is the focus of this article. The main goal is to further refine responses’ alignments with human preferences, by allowing the model to learn directly from feedback.

Reinforcement Learning Basics
A robot trying to exit a maze! [2]

Before diving deeper, let’s briefly revisit the core ideas behind Reinforcement Learning.

RL is quite straightforward to understand at a high level: an agent interacts with an environment. The agent resides in a specific state within the environment and can take actions to transition to other states. Each action yields a reward from the environment: this is how the environment provides feedback that guides the agent’s future actions. 

Consider the following example: a robot (the agent) navigates (and tries to exit) a maze (the environment).

  • The state is the current situation of the environment (the robot’s position in the maze).
  • The robot can take different actions: for example, it can move forward, turn left, or turn right.
  • Successfully navigating towards the exit yields a positive reward, while hitting a wall or getting stuck in the maze results in negative rewards.

Easy! Now, let’s now make an analogy to how RL is used in the context of LLMs.

RL in the context of LLMs
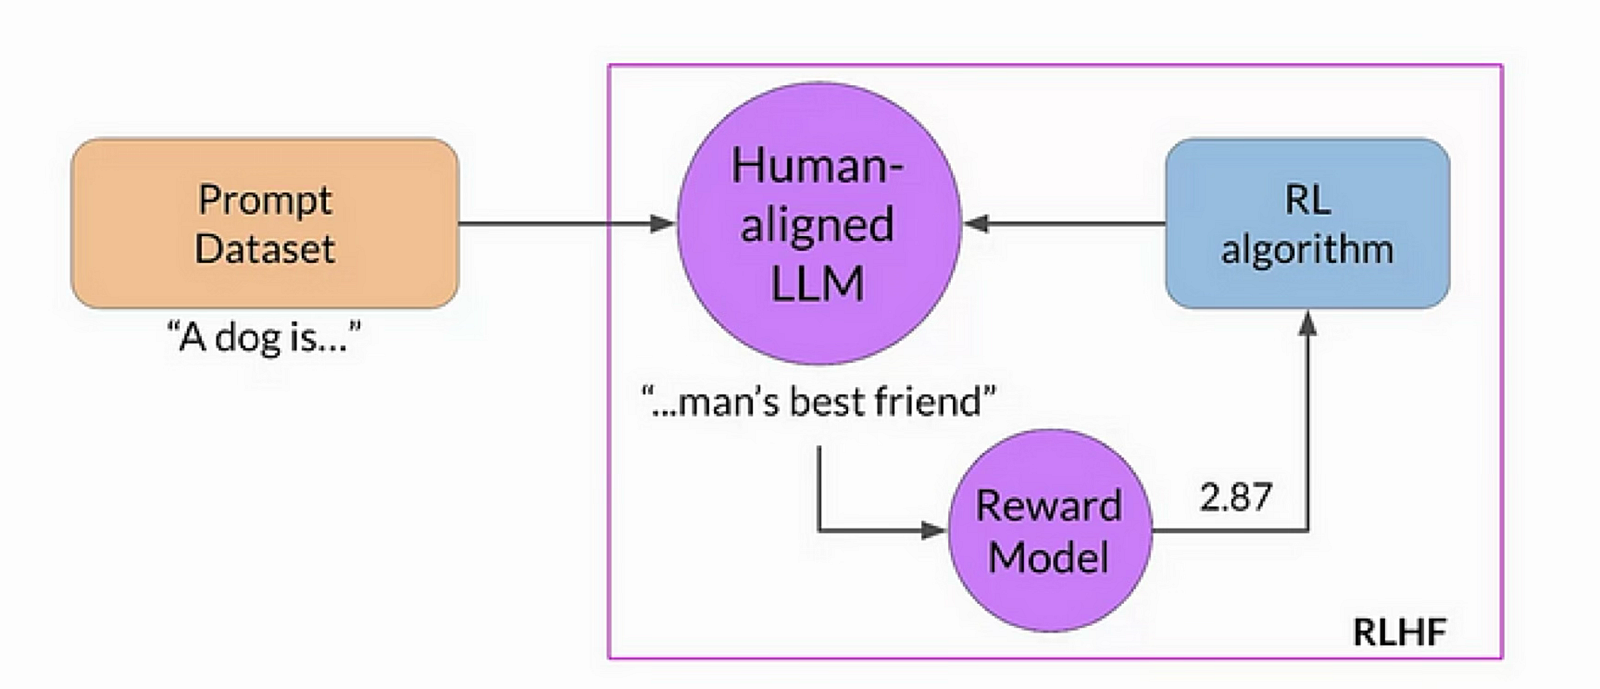
Simplified RLHF Process [3]

When used during LLM training, RL is defined by the following components:

  • The LLM itself is the agent
  • Environment: everything external to the LLM, including user prompts, feedback systems, and other contextual information. This is basically the framework the LLM is interacting with during training.
  • Actions: these are responses to a query from the model. More specifically: these are the tokens that the LLM decides to generate in response to a query.
  • State: the current query being answered along with tokens the LLM has generated so far (i.e., the partial responses).
  • Rewards: this is a bit more tricky here: unlike the maze example above, there is usually no binary reward. In the context of LLMs, rewards usually come from a separate reward model, which outputs a score for each (query, response) pair. This model is trained from human-annotated data (hence “RLHF”) where annotators rank different responses. The goal is for higher-quality responses to receive higher rewards.

Note: in some cases, rewards can actually get simpler. For example, in DeepSeekMath, rule-based approaches can be used because math responses tend to be more deterministic (correct or wrong answer)

Policy is the final concept we need for now. In RL terms, a policy is simply the strategy for deciding which action to take. In the case of an LLM, the policy outputs a probability distribution over possible tokens at each step: in short, this is what the model uses to sample the next token to generate. Concretely, the policy is determined by the model’s parameters (weights). During RL training, we adjust these parameters so the LLM becomes more likely to produce “better” tokens— that is, tokens that produce higher reward scores.

We often write the policy as:
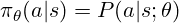
where a is the action (a token to generate), s the state (the query and tokens generated so far), and θ (model’s parameters).

This idea of finding the best policy is the whole point of RL! Since we don’t have labeled data (like we do in supervised learning) we use rewards to adjust our policy to take better actions. (In LLM terms: we adjust the parameters of our LLM to generate better tokens.)

TRPO (Trust Region Policy Optimization)

An analogy with supervised learning

Let’s take a quick step back to how supervised learning typically works. you have labeled data and use a loss function (like cross-entropy) to measure how close your model’s predictions are to the true labels.
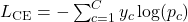
We can then use algorithms like backpropagation and gradient descent to minimize our loss function and update the weights θ of our model.

Recall that our policy also outputs probabilities! In that sense, it is analogous to the model’s predictions in supervised learning… We are tempted to write something like:
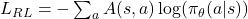
where s is the current state and a is a possible action.

A(s, a) is called the advantage function and measures how good is the chosen action in the current state, compared to a baseline. This is very much like the notion of labels in supervised learning but derived from rewards instead of explicit labeling. To simplify, we can write the advantage as:
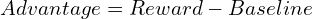
In practice, the baseline is calculated using a value function. This is a common term in RL that I will explain later. What you need to know for now is that it measures the expected reward we would receive if we continue following the current policy from the state s.

What is TRPO?

TRPO (Trust Region Policy Optimization) builds on this idea of using the advantage function but adds a critical ingredient for stability: it constrains how far the new policy can deviate from the old policy at each update step (similar to what we do with batch gradient descent for example).

  • It introduces a KL divergence term (see it as a measure of similarity) between the current and the old policy:
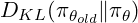
  • It also divides the policy by the old policy. This ratio, multiplied by the advantage function, gives us a sense of how beneficial each update is relative to the old policy.

Putting it all together, TRPO tries to maximize a surrogate objective (which involves the advantage and the policy ratio) subject to a KL divergence constraint.
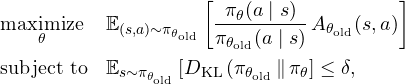
PPO (Proximal Policy Optimization)

While TRPO was a significant advancement, it’s no longer used widely in practice, especially for training LLMs, due to its computationally intensive gradient calculations.

Instead, PPO is now the preferred approach in most LLMs architecture, including ChatGPT, Gemini, and more.

It is actually quite similar to TRPO, but instead of enforcing a hard constraint on the KL divergence, PPO introduces a “clipped surrogate objective” that implicitly restricts policy updates, and greatly simplifies the optimization process.

Here is a breakdown of the PPO objective function we maximize to tweak our model’s parameters.
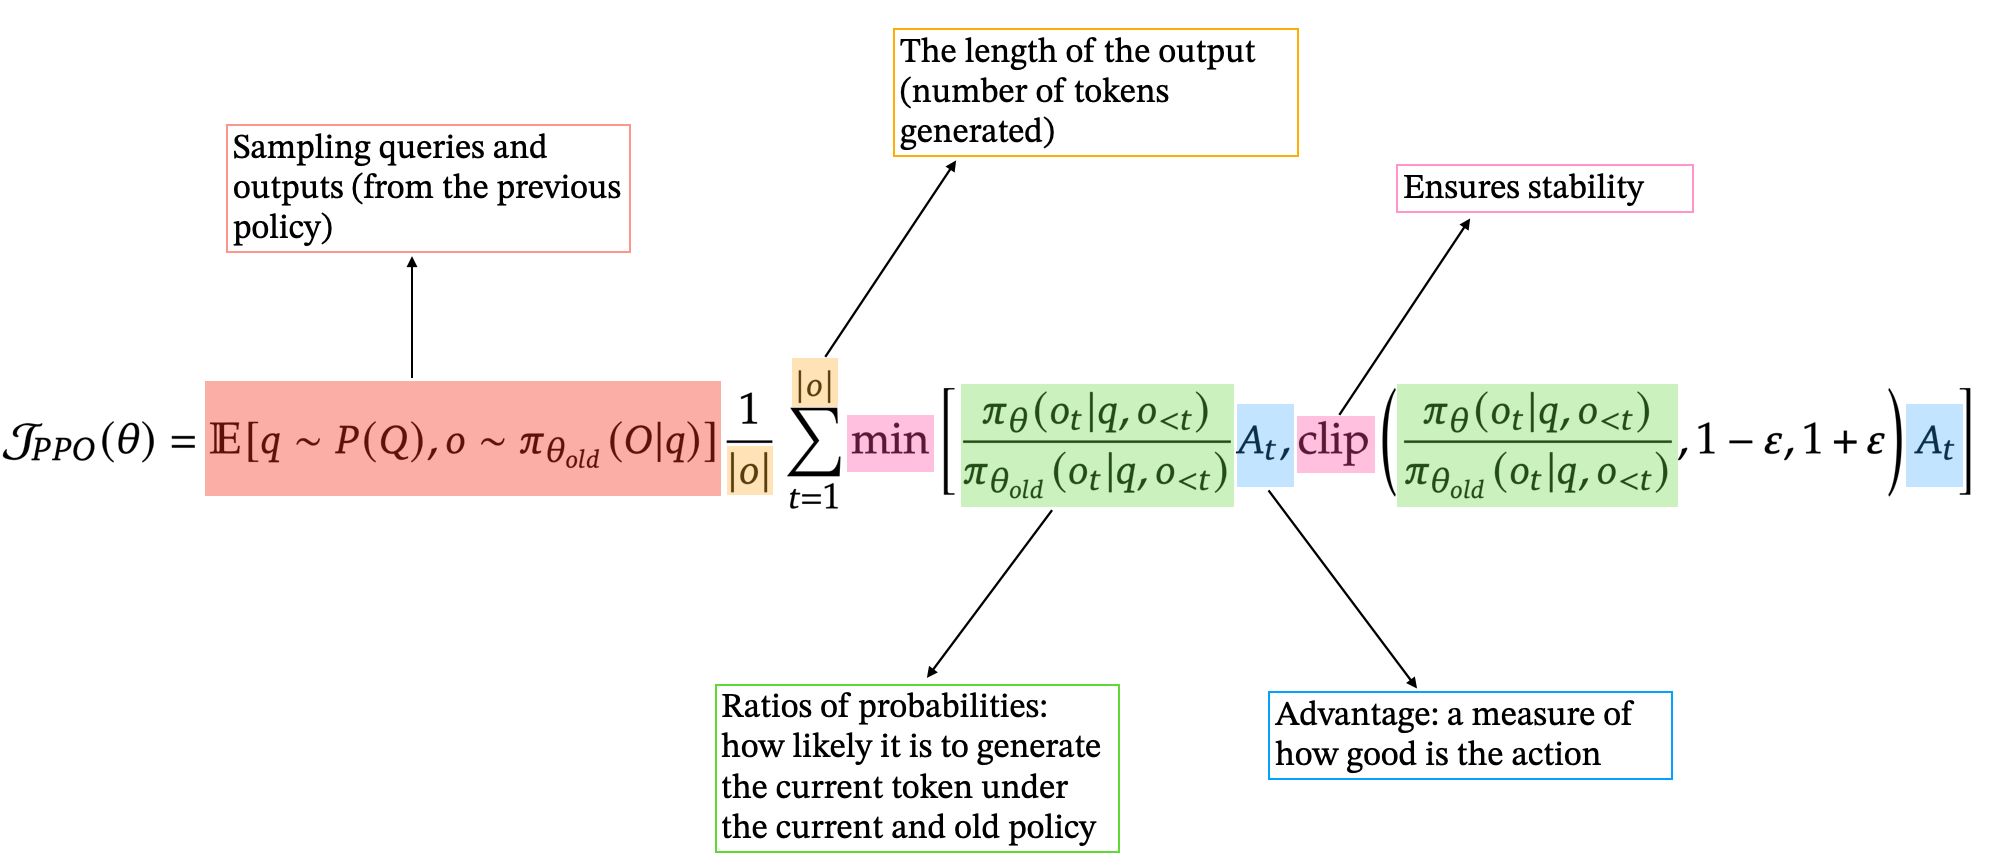
Image by the Author

GRPO (Group Relative Policy Optimization)

How is the value function usually obtained?

Let’s first talk more about the advantage and the value functions I introduced earlier.

In typical setups (like PPO), a value model is trained alongside the policy. Its goal is to predict the value of each action we take (each token generated by the model), using the rewards we obtain (remember that the value should represent the expected cumulative reward).

Here is how it works in practice. Take the query “What is 2+2?” as an example. Our model outputs “2+2 is 4” and receives a reward of 0.8 for that response. We then go backward and attribute discounted rewards to each prefix:

  • “2+2 is 4” gets a value of 0.8
  • “2+2 is” (1 token backward) gets a value of 0.8γ
  • “2+2” (2 tokens backward) gets a value of 0.8γ²
  • etc.

where γ is the discount factor (0.9 for example). We then use these prefixes and associated values to train the value model.

Important note: the value model and the reward model are two different things. The reward model is trained before the RL process and uses pairs of (query, response) and human ranking. The value model is trained concurrently to the policy, and aims at predicting the future expected reward at each step of the generation process.

What’s new in GRPO

Even if in practice, the reward model is often derived from the policy (training only the “head”), we still end up maintaining many models and handling multiple training procedures (policy, reward, value model). GRPO streamlines this by introducing a more efficient method.

Remember what I said earlier?

In PPO, we decided to use our value function as the baseline. GRPO chooses something else: Here is what GRPO does: concretely, for each query, GRPO generates a group of responses (group of size G) and uses their rewards to calculate each response’s advantage as a z-score:

where rᵢ is the reward of the i-th response and μ and σ are the mean and standard deviation of rewards in that group.

This naturally eliminates the need for a separate value model. This idea makes a lot of sense when you think about it! It aligns with the value function we introduced before and also measures, in a sense, an “expected” reward we can obtain. Also, this new method is well adapted to our problem because LLMs can easily generate multiple non-deterministic outputs by using a low temperature (controls the randomness of tokens generation).

This is the main idea behind GRPO: getting rid of the value model.

Finally, GRPO adds a KL divergence term (to be exact, GRPO uses a simple approximation of the KL divergence to improve the algorithm further) directly into its objective, comparing the current policy to a reference policy (often the post-SFT model).

See the final formulation below:
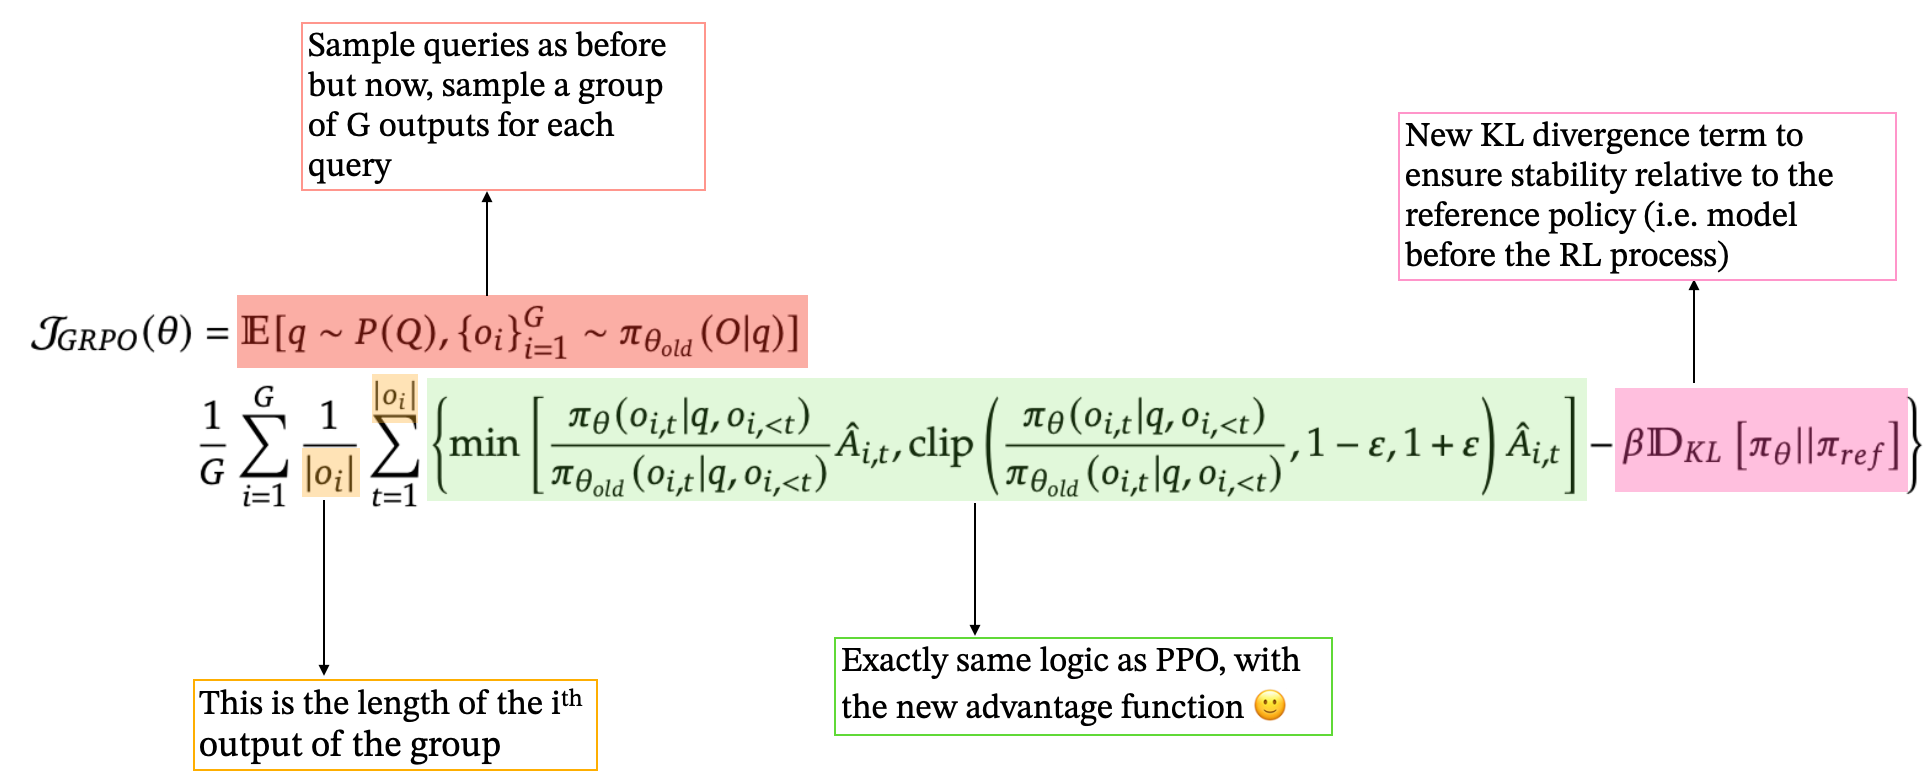
Image by the Author

And… that’s mostly it for GRPO! I hope this gives you a clear overview of the process: it still relies on the same foundational ideas as TRPO and PPO but introduces additional improvements to make training more efficient, faster, and cheaper — key factors behind DeepSeek’s success.

Conclusion

Reinforcement Learning has become a cornerstone for training today’s Large Language Models, particularly through PPO, and more recently GRPO. Each method rests on the same RL fundamentals — states, actions, rewards, and policies — but adds its own twist to balance stability, efficiency, and human alignment:

TRPO introduced strict policy constraints via KL divergence

PPO eased those constraints with a clipped objective

GRPO took an extra step by removing the value model requirement and using group-based reward normalization. Of course, DeepSeek also benefits from other innovations, like high-quality data and other training strategies, but that is for another time!

I hope this article gave you a clearer picture of how these methods connect and evolve. I believe that Reinforcement Learning will become the main focus in training LLMs to improve their performance, surpassing pre-training and SFT in driving future innovations. 

If you’re interested in diving deeper, feel free to check out the references below or explore my previous posts.

Thanks for reading, and feel free to leave a clap and a comment!


Want to learn more about Transformers or dive into the math behind the Curse of Dimensionality? Check out my previous articles:

Transformers: How Do They Transform Your Data?
Diving into the Transformers architecture and what makes them unbeatable at language taskstowardsdatascience.com

The Math Behind “The Curse of Dimensionality”
Dive into the “Curse of Dimensionality” concept and understand the math behind all the surprising phenomena that arise…towardsdatascience.com


References:

Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Practical quantum computers are over a decade away, says NEC

A practical, commercial quantum computer is over a decade away, executives at Japanese IT services company NEC are reported as saying. That’s why, according to Japanese news publication The Mainichi, company has pulled the plug on its plans to develop a quantum computer — although it will still continue research

Read More »

Huawei aims to deliver faster AI chips, faster

Huawei is accelerating its AI chips development, bringing forward the release of the next two models in the family powering its AI computing clusters by three to nine months. Its Ascend 960 chip family is a major component of supercomputing portfolio. It now plans to release the Ascend 960DT in

Read More »

Trump Administration Moves to Keep Indiana Coal Plants Operating to Support Grid Reliability

WASHINGTON—U.S. Secretary of Energy Chris Wright issued emergency orders to keep two Indiana coal plants operational to ensure Americans in the Midwest region of the United States have continued access to affordable, reliable, and secure electricity. The orders direct the Northern Indiana Public Service Company (NIPSCO), CenterPoint Energy, and the Midcontinent Independent System Operator, Inc. (MISO) to take all measures necessary to ensure specified generation units at both the R.M. Schahfer and F.B. Culley generating stations in Indiana are available to operate. Certain generation units at these coal plants were scheduled to shut down at the end of 2025.  The orders will minimize the risk of unnecessary blackouts for the American people. Since the U.S. Department of Energy’s (DOE) original orders were issued on December 23, 2025, the Schahfer and Culley coal plants have proven critical to MISO’s operations, operating during periods of high energy demand and low levels of intermittent energy production, including during Winter Storm Fern.   “Forcing reliable, dispatchable coal generation off the grid would compromise energy reliability and needlessly raises energy costs for Americans,” said Energy Secretary Wright. “Midwestern families should not be forced to pay the price for the misguided energy subtraction policies of the past. They deserve affordable, reliable, and secure energy, regardless of the wind blowing or the sun shining.” Thanks to President Trump’s leadership, coal generating plants across the country are being saved from premature retirement. For example, in 2025, more than 17 gigawatts of coal power electricity generation were saved from going offline.  The availability of R.M. Schahfer and F.B. Culley generating stations to operate will continue to be an asset to maintain reliability in the MISO region and is necessary to address elevated reliability risks in that region during extreme weather and reduce the risk of power outages that could threaten public health and safety. As

Read More »

Energy Secretary Secures Carolinas’ Grid Amidst Hot Weather Conditions

WASHINGTON—The U.S. Department of Energy (DOE) issued an emergency order to mitigate the risk of blackouts in the Carolinas amid hot weather conditions. Issued pursuant to Section 202(c) of the Federal Power Act, the order authorizes Duke Energy Carolinas, LLC (Duke) to dispatch specified resources and to order their operation as needed to maintain reliability. The order also authorizes Duke, in collaboration with its Transmission Owners, to direct backup generation resources to operate as a last resort before declaring an Energy Emergency Alert (EEA) 3 or during an EEA 3. This order was issued pursuant to an application from Duke submitted on September 18, 2026. “Today’s order will help secure reliable electricity access for millions of American families and businesses across North and South Carolina by making additional power generation, including backup power, available to use as needed,” said U.S. Secretary of Energy Chris Wright. “It should come as no surprise that during the end of summer and early fall, there are fewer hours of daylight—and therefore, less power generation from solar power. The North American Electric Reliability Corporation and others have warned of the potential dangers late summer temperature spikes can pose to the grid when leaders prematurely retire reliable power sources. While past leaders’ energy subtraction policies have made the grid more vulnerable to blackouts when the sun doesn’t shine or the wind doesn’t blow, this administration remains committed to using every available tool to prevent blackouts.”  DOE estimates more than 35 GW of unused backup generation remains available nationwide.  The order is in effect upon issuance on September 18, 2026, through September 21, 2026. 

Read More »

Enbridge launches open season for West Texas Express natural gas pipeline

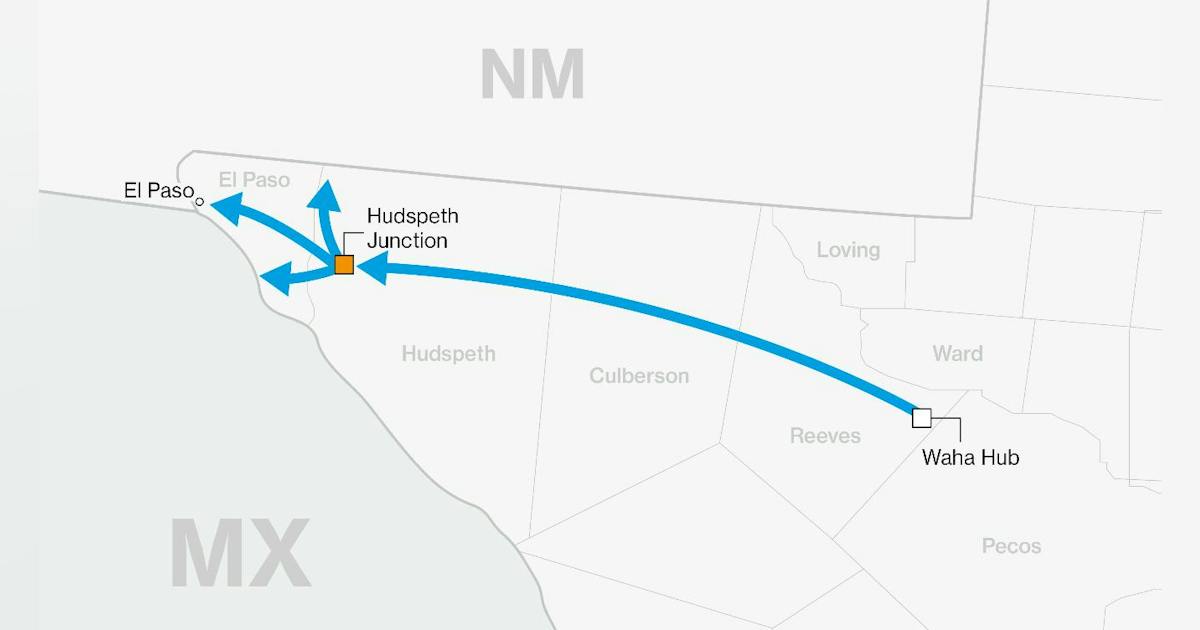
Enbridge has launched a non-binding open season for its proposed 2-bcfd West Texas Express (WTX) natural gas pipeline project, designed to transport Permian basin supply west from the Waha area to markets in and around El Paso, Tex. The proposed project responds to growing demand for reliable natural gas supplies from proposed power generation, utilities, generators, and industrial customers such as data centers across west Texas and downstream markets in Mexico, New Mexico, and Arizona, Enbridge said. WTX is currently expected to include more than 150 miles of new 42-in. OD pipeline. The project could also include laterals serving Hudspeth County, Tex., and delivery points at the US-Mexico border. Enbridge said WTX can be designed to connect with existing pipeline infrastructure based on customer requirements identified through the open season. Final capacity, routing, receipt and delivery points, and system design will be informed by market interest. Subject to securing sufficient commercial support and obtaining required approvals, Enbridge is targeting a fourth-quarter 2029 in-service date. The open season will close at 5 p.m. CDT, Sept. 25, 2026. Enbridge last week agreed to acquire Tallgrass Energy LP’s crude oil business for $2.55 billion in cash.

Read More »

Editorial: Let’s make a deal

The Trump administration announced Aug. 28, 2026, that the US and Venezuela had agreed to give the US majority control over development of more than 65 billion bbl of Venezuelan proven oil reserves. The agreement presents an extraordinary opportunity to the US oil industry, but also a great deal of risk, at least some of which should seem familiar. Before private capital follows Washington into Venezuela, the industry needs answers to some fundamental questions about the deal’s legal durability, political risk, commercial structure, and ultimate purpose. The agreement covers 17 fields and roughly 20% of Venezuela’s proved reserves. Development would be led by Barbados-based North American Blue Energy Partners (NABEP)—controlled by Venezuelan businessman Alejandro Betancourt López—under what the White House described as a 100-year concession. It’s a huge deal. But its timeline alone stretches credulity. A typical international concession agreement would last for 20-30 years, a term consistent with both in-country media reports and outside analysis. As noted by the Center for Strategic & International Studies, Venezuela’s Organic Hydrocarbon Law, passed in January 2026 after Nicolás Maduro’s ouster, only allows “production participation contracts” to private companies, not concessions of any duration.1 Venezuela’s constitution also creates questions about the agreement. Article 150 requires National Assembly approval of “public interest” contracts to entities based outside Venezuela while Article 302 reserves the petroleum industry to the State. Beyond the deal itself Looking beyond legal and structural technicalities, large questions remain regarding both stable governance in Venezuela and the viability of any agreements struck in its absence. There has been no meaningful progress toward establishing a functional democracy in Venezuela since the US captured Maduro. Both Acting President (and former VP) Delcy Rodríguez and Betancourt owe much of their political and personal fortunes to Maduro and his predecessor, Hugo Chávez. Rodríguez has done a

Read More »

US sanctions bill targets Russian energy but gives Trump broad discretion

US President Donald Trump is poised to sign legislation aimed at increasing economic pressure on Russia over its war in Ukraine by targeting Russian oil and gas revenues and countries that continue to buy Russian energy. While the measure mandates broad sanctions, it gives Trump wide discretion over implementation, including which countries face tariffs, the tariff rates imposed, and whether sanctions provisions are waived. The Lindsey O. Graham Sanctioning Russia and Iran Act of 2026, named for the late South Carolina senator who championed the legislation, passed the House Sept. 16 by a vote of 262-159 after clearing the Senate 86-11 in August. The measure now awaits Trump’s signature. The White House has said the administration supports the legislation and would recommend that Trump sign it into law. The legislation directs the president to impose broad sanctions and tariff measures targeting Russian energy exports and countries that facilitate sanctions evasion. However, Trump “may waive the application” of sanctions provisions, restrictions, or duties if he certifies to Congress that doing so is “in the national interest of the United States” and explains the basis for the decision. While the law mandates sanctions, it leaves key implementation decisions to the administration. Tariff provisions Within 30 days of enactment, the act requires the president to impose duties of up to 100% on goods imported from countries that fall within specified categories involving Russian oil and gas purchases or sanctions evasion. The covered countries include those among the five largest importers of Russian-origin crude oil or natural gas by total volume during the 12 months preceding enactment, as well as countries that meet separate criteria for facilitating Russian sanctions evasion. The administration must reassess those countries every 180 days. A country is exempt from the gas-related duties if its Russian gas imports accounted for

Read More »

California Resources unloads Uinta assets

The leaders of California Resources Corp., Long Beach, have sold the company’s Uinta basin assets for about $90 million to an undisclosed buyer. The deal has an effective date of July 1 and is expected to close by yearend. “Today’s transaction strengthens our business,” said Francisco Leon, CRC president and chief executive officer. “This transaction enhances our capital allocation flexibility, allowing us to invest in higher-return opportunities within the Golden State, and supports our shareholder return strategy.” CRC had come to own the Uinta assets, which span about 100,000 net acres, after it acquired Berry Corp. in December of last year for $709 million. But the operation accounts for a small part of CRC’s business–2.5% of oil production and 8% of natural gas production in the second quarter–and Leon last month told analysts “it’s hard to see allocating a lot of dollars back into the Uinta” as his team focuses on building out its California network of assets. “It requires a pretty significant amount of capital to develop the scale that we need for a second asset,” Leon said Aug. 10 after CRC reported its second-quarter results. “So as we do a side-by-side and we compare the Uinta assets with California, Uinta has higher capital intensity, higher break-evens, lower crude quality [and] higher transportation and operating costs and steeper declines.” In the deal announcement, Leon said the Uinta sale also offsets the price CRC will pay for a set of midstream assets in California it plans to buy from CorEnergy Infrastructure Trust. The purchase of those pipelines and other operations is expected to close later this month. Shares of CRC (Ticker: CRC) were down slightly to $54.24 in late-morning trading Sept. 17. They have lost about 15% of their value over the past 6 months, trimming the company’s market capitalization

Read More »

Local AI is getting small enough to make every app multilingual

On-device translation used to mean a separate model for every language you wanted to support. English to French, English to German, and so on. However, that becomes unsustainable at a global scale when you’re talking about thousands of possible language pairs. Add to that the fact that most developers have to either send translation requests to the cloud to get fast, accurate results, or keep it local with restricted language support. Tether’s AI Research team has developed a family of multilingual translation models, TranslatePsy-EuroNano, that each support nine European languages, with deployment built around a pair of multilingual models rather than separate bilingual models for every language pair. What makes this possible Supporting a full European market on-device has previously meant bundling dozens of separate model files, but this is impractical for mobile apps and those building them. Tether AI’s multilingual open‑source edge translation models set the standard for efficiency, quality, and speed. For developers, the possibilities are endless. Using English as a pivot, the models remain comparable to Mozilla Firefox’s Bergamot-based translation system while dramatically reducing the size of on-device translation. At its smallest tier, Tether’s deployment is 17.6 times smaller while maintaining comparable translation quality. Tether’s deployment takes up 36MB to 89MB, depending on the tier you use. By comparison, the equivalent Firefox setup requires 18 separate bilingual models totaling 633MB to provide the same language coverage. The models are small enough to run efficiently on edge devices while supporting nine European languages from a single multilingual deployment, making multilingual experiences practical for a much wider range of software. Potential applications include travel and navigation apps, educational platforms that present lessons and resources on-device. The models are also designed for academics and researchers. Because the weights are openly available, researchers can fine-tune them for specialized domains, like customer

Read More »

AI Infrastructure Is Redrawing the Data Center Services Landscape

For gigawatt-scale AI developments, the developer may be involved with substations, transmission interconnections, generation plants, batteries or other behind-the-meter infrastructure long before servers arrive. Solaris now describes its overall portfolio as including generation, distribution, installation and commissioning, aftermarket support, and operations and maintenance. The arrival of companies with roots in energy and heavy industrial services suggests that the data center supplier base itself is changing as projects begin to resemble large industrial infrastructure developments. The Pattern Extends Across the Services Stack The transactions involving T5, Limbach, JK Technology Services and Solaris are hardly isolated. A wider wave of acquisitions and partnerships is pushing equipment manufacturers, contractors, engineering firms and specialist service providers toward broader roles across the data center lifecycle. Vertiv provided perhaps the clearest parallel in September, announcing an agreement to acquire UtilityInnovation Group for approximately $1.45 billion in cash, with additional consideration tied to performance. UIG brings microgrid controls, onsite-generation orchestration, specialized switchgear and behind-the-meter power architecture. The deal also extends a broader 2026 acquisition push by Vertiv that has added liquid-cooling specialist Strategic Thermal Labs, chiller manufacturer ThermoKey and prefabricated infrastructure provider Bmarko as the company builds out more of the AI data center infrastructure stack. Vertiv described the move as extending its portfolio upstream from the critical power and cooling systems inside the facility toward the grid interconnection and onsite generation itself — effectively creating a path from power source to chip. Days later, Flex announced a $4.4 billion agreement to acquire EPC Power, adding grid-forming and power-conversion technology designed for data centers, utility-scale energy storage and microgrids. EPC Power’s platform includes rectifiers and DC-DC conversion for emerging 800-volt data center architectures, with solid-state transformer development also planned. The company says it has more than 15 GW deployed across 62 countries and expects its annual U.S.

Read More »

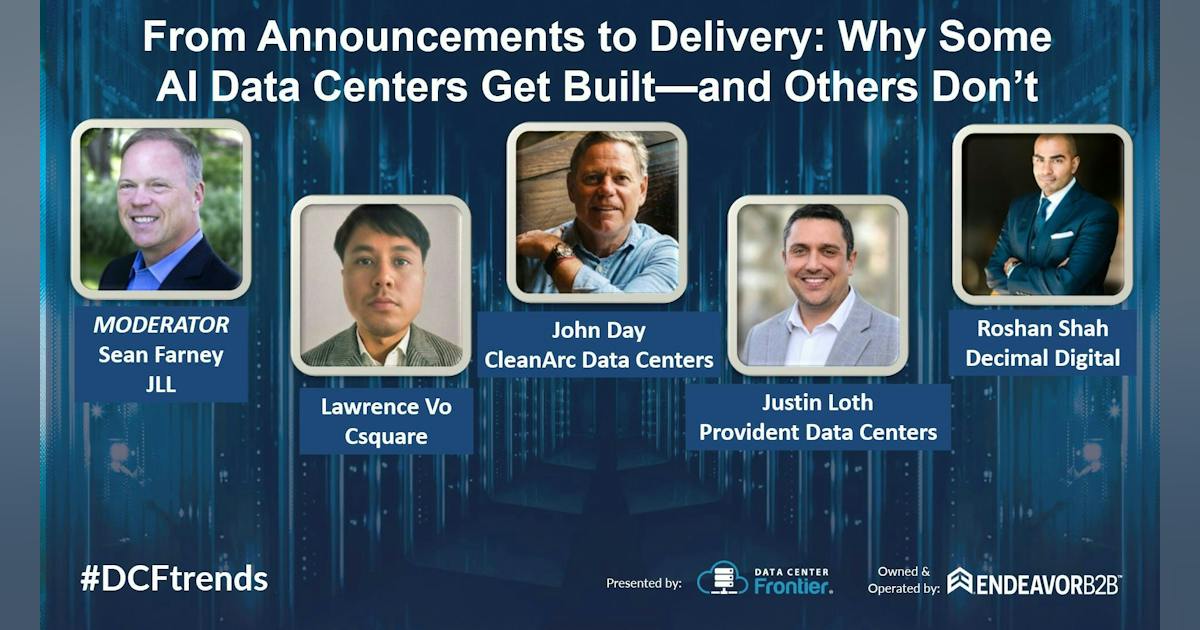
From Announcements to Delivery: What Separates Real AI Data Center Projects From the Rest

The AI infrastructure market has become very good at announcing gigawatts. Delivering them is another matter. That distinction framed one of the closing sessions of Day 1 at the Data Center Frontier Trends Summit 2026 (Aug. 4-6), where Sean Farney, vice president of data center strategy at JLL and a member of the Data Center Frontier Editorial Advisory Board, moderated a discussion on why some AI data center projects advance from concept to construction while others remain little more than ambitious site plans. Farney was joined by Lawrence Vo, vice president of M&A and capex at Csquare; John Day, chief commercial officer at CleanArc Data Centers; Justin Loth, executive director of power development at Provident Data Centers; and Roshan Shah, co-founder and CEO of Decimal Digital. The question Farney put before the group was straightforward: amid a market moving at what he called “the speed of light,” what separates the developers that actually get projects done from those that do not? The answers repeatedly came back to the same point. In the current market, land, capital and an announcement are no longer enough. Developers have to prove that power is deliverable, infrastructure is ready, regulatory processes are moving, communities are receptive, talent is available and the commercial model can withstand changing conditions. A Gigawatt on Paper Is Not a Gigawatt of Capacity For Loth, who spent roughly 15 years on the utility side before joining Provident, the scale of current data center proposals alone should force the industry to think differently about what constitutes a credible project. Before the hyperscale and AI expansion, he noted, gigawatts were a measure more commonly associated with cities than individual loads. “A 3.5 gigawatt campus,” Loth said, is roughly equivalent to the native load of Austin or San Antonio. That scale makes the distinction

Read More »

The Future of Data Centers: Biomimicry and Community-Centric Design

As a result, Microsoft has said six additional data centers planned in the region are being designed around biomimicry principles rather than treating landscaping as something added after the engineering work is finished. The change, from landscaping as decoration to ecology as a design input, is now being applied elsewhere. There is already a significant US example, set in Mecklenburg County, Virginia, where Microsoft originally announced the Chase City Conservancy in 2022, as part of a data center development south of Chase City. The completed project, which opened in April 2025, protects more than 230 acres from development. It includes more than eight acres of wetlands, over 16,300 linear feet of restored streams, 185 acres of native pollinator habitat, more than 25,000 planted trees and over three miles of publicly accessible walking trails. Local environmental organizations helped shift the design away from what the company describes as a more conventional recreational area toward biodiversity and habitat conservation illustrating the community-engagement side of Microsoft’s model, which, given the current temperature of such relationships, can’t be understated. For data center developers, that may be as important as the ecological results. Community impact is no longer being evaluated on just tax revenue and jobs. Turning portions of a site into protected wetlands, forests, trails or habitat potentially creates a visible local benefit in ways that renewable-energy contracts hundreds of miles away cannot. Microsoft’s commitment to the local community has been led by their Community First AI Infrastructure Plan announced in January 2026. Wetlands in Wisconsin, Screening in Georgia At Microsoft’s massive Mount Pleasant, Wisconsin, AI data center development, the company is working with the Root-Pike Watershed Initiative Network on restoration projects involving wetlands, native prairie and forested riparian buffers. One element involves returning previously straightened streams to more natural, winding channels, improving aquatic

Read More »

Axelera Europa targets enterprise data centers with far more efficient AI

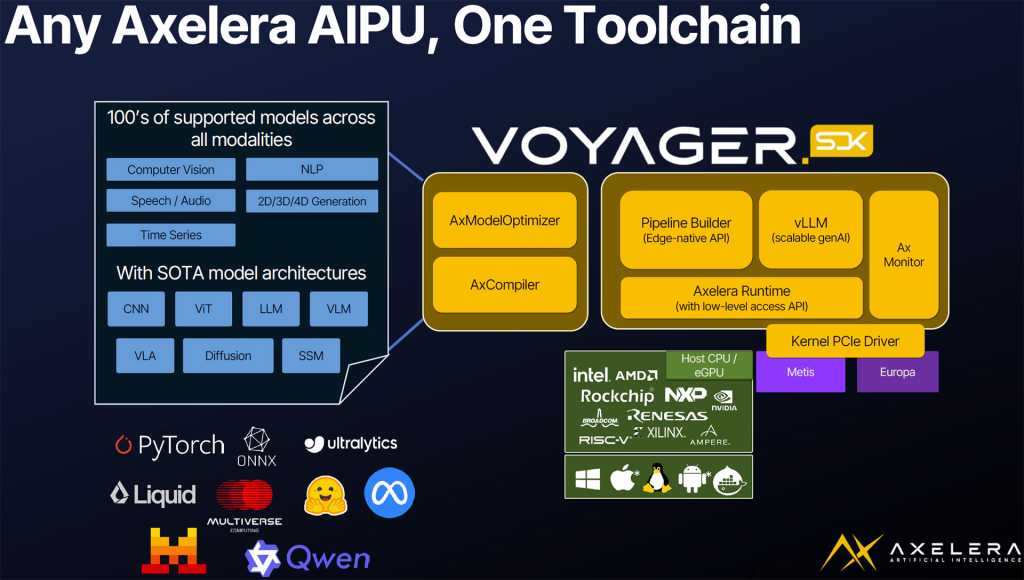
Software is still the gatekeeper Axelera In terms of software enablement, Axelera’s Voyager SDK spans its existing Metis products and the new Europa architecture, providing a common environment across embedded, edge and server deployments, with support for a multitude of computer vision models, LLMs, VLMs, diffusion models, speech and other AI workloads. To automate setup, Axelera’s Voyager Wingman uses natural-language prompts to help developers create or port inference pipelines, while AxeleraScript, or AxScript, provides a Python-enabled domain-specific language with lower-level AIPU control for custom operators and transformer models. This could prove every bit as important as Europa’s performance and efficiency. Enterprises already have models, development environments and application stacks. Extensive rewriting or specialized expertise adds development and operational costs that can quickly undermine savings on hardware and power.

Read More »

Scott Bergs, CEO of Kirkwood IG: Fiber and the AI Data Center Buildout

For years, fiber was one of the more forgiving elements of data center site selection. Developers could secure land, line up power, begin planning the facility and then work with carriers to establish the connectivity required by tenants. In a traditional multi-tenant data center, that model generally worked. At AI scale, Scott Bergs says it increasingly does not. “The architecture of those original communications service provider networks just don’t meet the latency and/or capacity needs” of today’s high-density compute environments, said Bergs, CEO of Kirkwood Infrastructure Group, during a recent episode of the Data Center Frontier Show. The result is a significant change in the data center development stack: network infrastructure can no longer be treated as something that gets solved after the site is chosen. For hyperscalers and neo-cloud providers, fiber route diversity, latency, physical security and future capacity increasingly need to enter the conversation alongside power and land. And as data center campuses follow available power farther from established digital infrastructure hubs, the scale of the network challenge is expanding with them. A connection between data center campuses that might once have extended two or 30 miles can now stretch 250 miles or more, Bergs said. What would traditionally have been considered a long-haul fiber route is increasingly becoming another piece of inter-campus infrastructure. That change is helping drive Kirkwood’s own expansion. From DF&I to Kirkwood Bergs previously led DF&I, a dark-fiber infrastructure platform concentrated in Northern Virginia and Maryland. Kirkwood Infrastructure Group is not simply DF&I under a new name, he said. Rather, it represents what Bergs described as a second phase in a broader infrastructure investment strategy developed originally through IPI Partners. IPI, an investment platform focused on digital infrastructure, backed DF&I after identifying communications infrastructure serving dense compute environments as an area requiring greater direct

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »