Stay Ahead, Stay ONMINE

When Optimal is the Enemy of Good: High-Budget Differential Privacy for Medical AI

Imagine you’re building your dream home. Just about everything is ready. All that’s left to do is pick out a front door. Since the neighborhood has a low crime rate, you decide you want a door with a standard lock — nothing too fancy, but probably enough to deter 99.9% of would-be burglars. Unfortunately, the local homeowners’ association (HOA) has a rule stating that all front doors in the neighborhood must be bank vault doors. Their reasoning? Bank vault doors are the only doors that have been mathematically proven to be absolutely secure. As far as they’re concerned, any front door below that standard may as well not be there at all. You’re left with three options, none of which seems particularly appealing: Concede defeat and have a bank vault door installed. Not only is this expensive and cumbersome, but you’ll be left with a front door that bogs you down every single time you want to open or close it. At least burglars won’t be a problem! Leave your house doorless. The HOA rule imposes requirements on any front door in the neighborhood, but it doesn’t technically forbid you from not installing a door at all. That would save you a lot of time and money. The downside, of course, is that it would allow anyone to come and go as they please. On top of that, the HOA could always close the loophole, taking you back to square one. Opt out entirely. Faced with such a stark dilemma (all-in on either security or practicality), you choose not to play the game at all, selling your nearly-complete house and looking for someplace else to live. This scenario is obviously completely unrealistic. In real life, everybody strives to strike an appropriate balance between security and practicality. This balance is informed by everyone’s own circumstances and risk analysis, but it universally lands somewhere between the two extremes of bank vault door and no door at all. But what if instead of your dream home, you imagined a medical AI model that has the power to help doctors improve patient outcomes? Highly-sensitive training data points from patients are your valuables. The privacy protection measures you take are the front door you choose to install. Healthcare providers and the scientific community are the HOA.  Suddenly, the scenario is much closer to reality. In this article, we’ll explore why that is. After understanding the problem, we’ll consider a simple but empirically effective solution proposed in the paper Reconciling privacy and accuracy in AI for medical imaging [1]. The authors propose a balanced alternative to the three bad choices laid out above, much like the real-life approach of a typical front door. The State of Patient Privacy in Medical AI Over the past few years, artificial intelligence has become an ever more ubiquitous part of our day-to-day lives, proving its utility across a wide range of domains. The rising use of AI models has, however, raised questions and concerns about protecting the privacy of the data used to train them. You may remember the well-known case of ChatGPT, just months after its initial release, exposing proprietary code from Samsung [2]. Some of the privacy risks associated with AI models are obvious. For example, if the training data used for a model isn’t stored securely enough, bad actors could find ways to access it directly. Others are more insidious, such as the risk of reconstruction. As the name implies, in a reconstruction attack, a bad actor attempts to reconstruct a model’s training data without needing to gain direct access to the dataset. Medical records are one of the most sensitive kinds of personal information there are. Although specific regulation varies by jurisdiction, patient data is generally subject to stringent safeguards, with hefty fines for inadequate protection. Beyond the letter of the law, unintentionally exposing such data could irreparably damage our ability to use specialized AI to empower medical professionals.  As Ziller, Mueller, Stieger, et al. point out [1], fully taking advantage of medical AI requires rich datasets comprising information from actual patients. This information must be obtained with the full consent of the patient. Ethically acquiring medical data for research was challenging enough as it was before the unique challenges posed by AI came into play. But if proprietary code being exposed caused Samsung to ban the use of ChatGPT [2], what would happen if attackers managed to reconstruct MRI scans and identify the patients they belonged to? Even isolated instances of negligent protection against data reconstruction could end up being a monumental setback for medical AI as a whole. Tying this back into our front door metaphor, the HOA statute calling for bank vault doors starts to make a little bit more sense. When the cost of a single break-in could be so catastrophic for the entire neighborhood, it’s only natural to want to go to any lengths to prevent them.  Differential Privacy (DP) as a Theoretical Bank Vault Door Before we discuss what an appropriate balance between privacy and practicality might look like in the context of medical AI, we have to turn our attention to the inherent tradeoff between protecting an AI model’s training data and optimizing for quality of performance. This will set the stage for us to develop a basic understanding of Differential Privacy (DP), the theoretical gold standard of privacy protection. Although academic interest in training data privacy has increased significantly over the past four years, principles on which much of the conversation is based were pointed out by researchers well before the recent LLM boom, and even before OpenAI was founded in 2015. Though it doesn’t deal with reconstruction per se, the 2013 paper Hacking smart machines with smarter ones [3] demonstrates a generalizable attack methodology capable of accurately inferring statistical properties of machine learning classifiers, noting: “Although ML algorithms are known and publicly released, training sets may not be reasonably ascertainable and, indeed, may be guarded as trade secrets. While much research has been performed about the privacy of the elements of training sets, […] we focus our attention on ML classifiers and on the statistical information that can be unconsciously or maliciously revealed from them. We show that it is possible to infer unexpected but useful information from ML classifiers.” [3] Theoretical data reconstruction attacks were described even earlier, in a context not directly pertaining to machine learning. The landmark 2003 paper Revealing information while preserving privacy [4] demonstrates a polynomial-time reconstruction algorithm for statistical databases. (Such databases are intended to provide answers to questions about their data in aggregate while keeping individual data points anonymous.) The authors show that to mitigate the risk of reconstruction, a certain amount of noise needs to be introduced into the data. Needless to say, perturbing the original data in this way, while necessary for privacy, has implications for the quality of the responses to queries, i.e., the accuracy of the statistical database. In explaining the purpose of DP in the first chapter of their book The Algorithmic Foundations of Differential Privacy [5], Cynthia Dwork and Aaron Roth address this tradeoff between privacy and accuracy: “[T]he Fundamental Law of Information Recovery states that overly accurate answers to too many questions will destroy privacy in a spectacular way. The goal of algorithmic research on differential privacy is to postpone this inevitability as long as possible. Differential privacy addresses the paradox of learning nothing about an individual while learning useful information about a population.” [5] The notion of “learning nothing about an individual while learning useful information about a population” is captured by considering two datasets that differ by a single entry (one that includes the entry and one that doesn’t). An (ε, δ)-differentially private querying mechanism is one for which the probability of a certain output being returned when querying one dataset is at most a multiplicative factor of the probability when querying the other dataset. Denoting the mechanism by M, the set of possible outputs by S, and the datasets by x and y, we formalize this as [5]: Pr[M(x) ∈ S] ≤ exp(ε) ⋅ Pr[M(y) ∈ S] + δ Where ε is the privacy loss parameter and δ is the failure probability parameter. ε quantifies how much privacy is lost as a result of a query, while a positive δ allows for privacy to fail altogether for a query at a certain (usually very low) probability. Note that ε is an exponential parameter, meaning that even slightly increasing it can cause privacy to decay significantly. An important and useful property of DP is composition. Notice that the definition above only applies to cases where we run a single query. The composition property helps us generalize it to cover multiple queries based on the fact that privacy loss and failure probability accumulate predictably when we compose several queries, be they based on the same mechanism or different ones. This accumulation is easily proven to be (at most) linear [5]. What this means is that, rather than considering a privacy loss parameter for one query, we may view ε as a privacy budget that can be utilized across a number of queries. For example, when taken together, one query using a (1, 0)-DP mechanism and two queries using a (0.5, 0)-DP mechanism satisfy (2, 0)-DP. The value of DP comes from the theoretical privacy guarantees it promises. Setting ε = 1 and δ = 0, for example, we find that the probability of any given output occurring when querying dataset y is at most exp(1) = e ≈ 2.718 times greater than that same output occurring when querying dataset x. Why does this matter? Because the greater the discrepancy between the probabilities of certain outputs occurring, the easier it is to determine the contribution of the individual entry by which the two datasets differ, and the easier it is to ultimately reconstruct that individual entry. In practice, designing an (ε, δ)-differentially private randomized mechanism entails the addition of random noise drawn from a distribution dependent on ε and δ. The specifics are beyond the scope of this article. Shifting our focus back to machine learning, though, we find that the idea is the same: DP for ML hinges on introducing noise into the training data, which yields robust privacy guarantees in much the same way. Of course, this is where the tradeoff we mentioned comes into play. Adding noise to the training data comes at the cost of making learning more difficult. We could absolutely add enough noise to achieve ε = 0.01 and δ = 0, making the difference in output probabilities between x and y virtually nonexistent. This would be wonderful for privacy, but terrible for learning. A model trained on such a noisy dataset would perform very poorly on most tasks. There is no consensus on what constitutes a “good” ε value, or on universal methodologies or best practices for ε selection [6]. In many ways, ε embodies the privacy/accuracy tradeoff, and the “proper” value to aim for is highly context-dependent. ε = 1 is generally regarded as offering high privacy guarantees. Although privacy diminishes exponentially with respect to ε, values as high as ε = 32 are mentioned in literature and thought to provide moderately strong privacy guarantees [1].  The authors of Reconciling privacy and accuracy in AI for medical imaging [1] test the effects of DP on the accuracy of AI models on three real-world medical imaging datasets. They do so using various values of ε and comparing them to a non-private (non-DP) control. Table 1 provides a partial summary of their results for ε = 1 and ε = 8: Table 1: Comparison of AI model performance across the RadImageNet [7], HAM10000 [8], and MSD Liver [9] datasets with δ = 8⁻⁷⋅10 and privacy budgets of ε = 1, ε = 8, and without DP (non-private). A higher MCC/Dice score indicates higher accuracy. Although providing strong theoretical privacy guarantees in the face of a worst-case adversary, DP significantly degrades model accuracy. The negative impact on performance is especially noticeable in the latter two datasets, which are considered small datasets. Image by the author, based on image by A. Ziller, T.T. Mueller, S. Stieger, et al from Table 3 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license). Even approaching the higher end of the typical ε values attested in literature, DP is still as cumbersome as a bank vault door for medical imaging tasks. The noise introduced into the training data is catastrophic for AI model accuracy, especially when the datasets at hand are small. Note, for example, the huge drop-off in Dice score on the MSD Liver dataset, even with the relatively high ε value of 8. Ziller, Mueller, Stieger, et al. suggest that the accuracy drawbacks of DP with typical ε values may contribute to the lack of widespread adoption of DP in the field of Medical Ai [1]. Yes, wanting mathematically-provable privacy guarantees is definitely sensible, but at what cost? Leaving so much of the diagnostic power of AI models on the table in the name of privacy is not an easy choice to make. Revisiting our dream home scenario armed with an understanding of DP, we find that the options we (seem to) have map neatly onto the three we had for our front door. DP with typical values of ε is like installing a bank vault door: costly, but effective for privacy. As we’ll see, it’s also complete overkill in this case. Not using DP is like not installing a door at all: much easier, but risky. As mentioned above, though, DP has yet to be widely applied in medical AI [1]. Passing up opportunities to use AI is like giving up and selling the house: it saves us the headache of dealing with privacy concerns weighed against incentives to maximize accuracy, but a lot of potential is lost in the process. It looks like we’re at an impasse… unless we think outside the box. High-Budget DP: Privacy and Accuracy Aren’t an Either/Or In Reconciling privacy and accuracy in AI for medical imaging [1], Ziller, Mueller, Stieger, et al. offer the medical AI equivalent of a regular front door — an approach that manages to protect privacy while giving up very little in the way of model performance. Granted, this protection is not theoretically optimal — far from it. However, as the authors show through a series of experiments, it is good enough to counter almost any realistic threat of reconstruction.  As the saying goes, “Perfect is the enemy of good.” In this case, it is the “optimal” — an insistence on arbitrarily low ε values — that locks us into the false dichotomy of total privacy versus total accuracy. Just as a bank vault door has its place in the real world, so does DP with ε ≤ 32. Still, the existence of the bank vault door doesn’t mean plain old front doors don’t also have a place in the world. The same goes for high-budget DP. The idea behind high-budget DP is straightforward: using privacy budgets (ε values) that are so high that they “are near-universally shunned as being meaningless” [1] — budgets ranging from ε = 10⁶ to as high as ε = 10¹⁵. In theory, these provide such weak privacy guarantees that it seems like common sense to dismiss them as no better than not using DP at all. In practice, though, this couldn’t be further from the truth. As we will see by looking at the results from the paper, high-budget DP shows significant promise in countering realistic threats. As Ziller, Mueller, Stieger, et al. put it [1]: “[E]ven a ‘pinch of privacy’ has drastic effects in practical scenarios.” First, though, we need to ask ourselves what we consider to be a “realistic” threat. Any discussion of the efficacy of high-budget DP is inextricably tied to the threat model under which we choose to evaluate it. In this context, a threat model is simply the set of assumptions we make about what a bad actor interested in obtaining our model’s training data is able to do. Table 2: Comparison of threat models. For all three, we also assume that the adversary has unbounded computational ability. Image by A. Ziller, T.T. Mueller, S. Stieger, et al from Table 1 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license). The paper’s findings hinge on a calibration of the assumptions to better suit real-world threats to patient privacy. The authors argue that the worst-case model, which is the one typically used for DP, is far too pessimistic. For example, it assumes that the adversary has full access to each original image while attempting to reconstruct it based on the AI model (see Table 2) [1]. This pessimism explains the discrepancy between the reported “drastic effects in practical scenarios” of high privacy budgets and the very weak theoretical privacy guarantees that they offer. We may liken it to incorrectly assessing the security threats a typical house faces, wrongly assuming they are likely to be as sophisticated and enduring as those faced by a bank.  The authors therefore propose two alternative threat models, which they call the “relaxed” and “realistic” models. Under both of these, adversaries keep some core capabilities from the worst-case model: access to the AI model’s architecture and weights, the ability to manipulate its hyperparameters, and unbounded computational abilities (see Table 2). The realistic adversary is assumed to have no access to the original images and an imperfect reconstruction algorithm. Even these assumptions leave us with a rigorous threat model that may still be considered pessimistic for most real-world scenarios [1]. Having established the three relevant threat models to consider, Ziller, Mueller, Stieger, et al. compare AI model accuracy in conjunction with the reconstruction risk under each threat model at different values of ε. As we saw in Table 1, this is done for three exemplary Medical Imaging datasets. Their full results are presented in Table 3: Table 3: Comparison of AI model performance and reconstruction risk per threat model across the RadImageNet [7], HAM10000 [8], and MSD Liver [9] datasets with δ = 8⁻⁷⋅10 and various privacy budgets, including some as high as ε = 10⁹ and ε = 10¹². A higher MCC/Dice score indicates higher accuracy. Image by A. Ziller, T.T. Mueller, S. Stieger, et al from Table 3 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license). Unsurprisingly, high privacy budgets (exceeding ε = 10⁶) significantly mitigate the loss of accuracy seen with lower (stricter) privacy budgets. Across all tested datasets, models trained with high-budget DP at ε = 10⁹ (HAM10000, MSD Liver) or ε = 10¹² (RadImageNet) perform nearly as well as their non-privately trained counterparts. This is in line with our understanding of the privacy/accuracy tradeoff: the less noise introduced into the training data, the better a model can learn. What is surprising is the degree of empirical protection afforded by high-budget DP against reconstruction under the realistic threat model. Remarkably, the realistic reconstruction risk is assessed to be 0% for each of the aforementioned models. The high efficacy of high-budget DP in defending medical AI training images against realistic reconstruction attacks is made even clearer by looking at the results of reconstruction attempts. Figure 1 below shows the five most readily reconstructed images from the MSD Liver dataset [9] using DP with high privacy budgets of ε = 10⁶, ε = 10⁹, ε = 10¹², and ε = 10¹⁵. Figure 1: The five most readily reconstructed images from the MSD Liver dataset [9] using DP with high privacy budgets of ε = 10⁶, ε = 10⁹, ε = 10¹², and ε = 10¹⁵. Image by A. Ziller, T.T. Mueller, S. Stieger, et al from Figure 3 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license). Note that, at least to the naked eye, even the best reconstructions obtained when using the former two budgets are visually indistinguishable from random noise. This lends intuitive credence to the argument that budgets often deemed too high to provide any meaningful protection could be instrumental in protecting privacy without giving up accuracy when using AI for medical imaging. In contrast, the reconstructions when using ε = 10¹⁵ closely resemble the original images, showing that not all high budgets are created equal. Based on their findings, Ziller, Mueller, Stieger, et al. make the case for training medical imaging AI models using (at least) high-budget DP as the norm. They note the empirical efficacy of high-budget DP in countering realistic reconstruction risks at very little cost in terms of model accuracy. The authors go so far as to claim that “it seems negligent to train AI models without any form of formal privacy guarantee.” [1] Conclusion We started with a hypothetical scenario in which you were forced to decide between a bank vault door or no door at all for your dream home (or giving up and selling the incomplete house). After an exploration of the risks posed by inadequate privacy protection in medical AI, we looked into the privacy/accuracy tradeoff as well as the history and theory behind reconstruction attacks and differential privacy (DP). We then saw how DP with common privacy budgets (ε values) degrades medical AI model performance and compared it to the bank vault door in our hypothetical.  Finally, we examined empirical results from the paper Reconciling privacy and accuracy in AI for medical imaging to find out how high-budget differential privacy can be used to escape the false dichotomy of bank vault door vs. no door and protect Patient Privacy in the real world without sacrificing model accuracy in the process. If you enjoyed this article, please consider following me on LinkedIn to keep up with future articles and projects. References [1] Ziller, A., Mueller, T.T., Stieger, S. et al. Reconciling privacy and accuracy in AI for medical imaging. Nat Mach Intell 6, 764–774 (2024). https://doi.org/10.1038/s42256-024-00858-y. [2] Ray, S. Samsung bans ChatGPT and other chatbots for employees after sensitive code leak. Forbes (2023). https://www.forbes.com/sites/siladityaray/2023/05/02/samsung-bans-chatgpt-and-other-chatbots-for-employees-after-sensitive-code-leak/. [3] Ateniese, G., Mancini, L. V., Spognardi, A. et al. Hacking smart machines with smarter ones: how to extract meaningful data from machine learning classifiers. International Journal of Security and Networks 10, 137–150 (2015). https://doi.org/10.48550/arXiv.1306.4447. [4] Dinur, I. & Nissim, K. Revealing information while preserving privacy. Proc. 22nd ACM SIGMOD-SIGACT-SIGART Symp Principles Database Syst 202–210 (2003). https://doi.org/10.1145/773153.773173. [5] Dwork, C. & Roth, A. The algorithmic foundations of differential privacy. Foundations and Trends in Theoretical Computer Science 9, 211–407 (2014). https://doi.org/10.1561/0400000042. [6] Dwork, C., Kohli, N. & Mulligan, D. Differential privacy in practice: expose your epsilons! Journal of Privacy and Confidentiality 9 (2019). https://doi.org/10.29012/jpc.689. [7] Mei, X., Liu, Z., Robson, P.M. et al. RadImageNet: an open radiologic deep learning research dataset for effective transfer learning. Radiol Artif Intell 4.5, e210315 (2022). https://doi.org/10.1148/ryai.210315. [8] Tschandl, P., Rosendahl, C. & Kittler, H. The HAM10000 dataset, a large collection of multi-source dermatoscopic images of common pigmented skin lesions. Sci Data 5, 180161 (2018). https://doi.org/10.1038/sdata.2018.161. [9] Antonelli, M., Reinke, A., Bakas, S. et al. The Medical Segmentation Decathlon. Nat Commun 13, 4128 (2022). https://doi.org/10.1038/s41467-022-30695-9.

Imagine you’re building your dream home. Just about everything is ready. All that’s left to do is pick out a front door. Since the neighborhood has a low crime rate, you decide you want a door with a standard lock — nothing too fancy, but probably enough to deter 99.9% of would-be burglars.

Unfortunately, the local homeowners’ association (HOA) has a rule stating that all front doors in the neighborhood must be bank vault doors. Their reasoning? Bank vault doors are the only doors that have been mathematically proven to be absolutely secure. As far as they’re concerned, any front door below that standard may as well not be there at all.

You’re left with three options, none of which seems particularly appealing:

  • Concede defeat and have a bank vault door installed. Not only is this expensive and cumbersome, but you’ll be left with a front door that bogs you down every single time you want to open or close it. At least burglars won’t be a problem!
  • Leave your house doorless. The HOA rule imposes requirements on any front door in the neighborhood, but it doesn’t technically forbid you from not installing a door at all. That would save you a lot of time and money. The downside, of course, is that it would allow anyone to come and go as they please. On top of that, the HOA could always close the loophole, taking you back to square one.
  • Opt out entirely. Faced with such a stark dilemma (all-in on either security or practicality), you choose not to play the game at all, selling your nearly-complete house and looking for someplace else to live.

This scenario is obviously completely unrealistic. In real life, everybody strives to strike an appropriate balance between security and practicality. This balance is informed by everyone’s own circumstances and risk analysis, but it universally lands somewhere between the two extremes of bank vault door and no door at all.

But what if instead of your dream home, you imagined a medical AI model that has the power to help doctors improve patient outcomes? Highly-sensitive training data points from patients are your valuables. The privacy protection measures you take are the front door you choose to install. Healthcare providers and the scientific community are the HOA. 

Suddenly, the scenario is much closer to reality. In this article, we’ll explore why that is. After understanding the problem, we’ll consider a simple but empirically effective solution proposed in the paper Reconciling privacy and accuracy in AI for medical imaging [1]. The authors propose a balanced alternative to the three bad choices laid out above, much like the real-life approach of a typical front door.


The State of Patient Privacy in Medical AI

Over the past few years, artificial intelligence has become an ever more ubiquitous part of our day-to-day lives, proving its utility across a wide range of domains. The rising use of AI models has, however, raised questions and concerns about protecting the privacy of the data used to train them. You may remember the well-known case of ChatGPT, just months after its initial release, exposing proprietary code from Samsung [2].

Some of the privacy risks associated with AI models are obvious. For example, if the training data used for a model isn’t stored securely enough, bad actors could find ways to access it directly. Others are more insidious, such as the risk of reconstruction. As the name implies, in a reconstruction attack, a bad actor attempts to reconstruct a model’s training data without needing to gain direct access to the dataset.

Medical records are one of the most sensitive kinds of personal information there are. Although specific regulation varies by jurisdiction, patient data is generally subject to stringent safeguards, with hefty fines for inadequate protection. Beyond the letter of the law, unintentionally exposing such data could irreparably damage our ability to use specialized AI to empower medical professionals. 

As Ziller, Mueller, Stieger, et al. point out [1], fully taking advantage of medical AI requires rich datasets comprising information from actual patients. This information must be obtained with the full consent of the patient. Ethically acquiring medical data for research was challenging enough as it was before the unique challenges posed by AI came into play. But if proprietary code being exposed caused Samsung to ban the use of ChatGPT [2], what would happen if attackers managed to reconstruct MRI scans and identify the patients they belonged to? Even isolated instances of negligent protection against data reconstruction could end up being a monumental setback for medical AI as a whole.

Tying this back into our front door metaphor, the HOA statute calling for bank vault doors starts to make a little bit more sense. When the cost of a single break-in could be so catastrophic for the entire neighborhood, it’s only natural to want to go to any lengths to prevent them. 

Differential Privacy (DP) as a Theoretical Bank Vault Door

Before we discuss what an appropriate balance between privacy and practicality might look like in the context of medical AI, we have to turn our attention to the inherent tradeoff between protecting an AI model’s training data and optimizing for quality of performance. This will set the stage for us to develop a basic understanding of Differential Privacy (DP), the theoretical gold standard of privacy protection.

Although academic interest in training data privacy has increased significantly over the past four years, principles on which much of the conversation is based were pointed out by researchers well before the recent LLM boom, and even before OpenAI was founded in 2015. Though it doesn’t deal with reconstruction per se, the 2013 paper Hacking smart machines with smarter ones [3] demonstrates a generalizable attack methodology capable of accurately inferring statistical properties of machine learning classifiers, noting:

“Although ML algorithms are known and publicly released, training sets may not be reasonably ascertainable and, indeed, may be guarded as trade secrets. While much research has been performed about the privacy of the elements of training sets, […] we focus our attention on ML classifiers and on the statistical information that can be unconsciously or maliciously revealed from them. We show that it is possible to infer unexpected but useful information from ML classifiers.” [3]

Theoretical data reconstruction attacks were described even earlier, in a context not directly pertaining to machine learning. The landmark 2003 paper Revealing information while preserving privacy [4] demonstrates a polynomial-time reconstruction algorithm for statistical databases. (Such databases are intended to provide answers to questions about their data in aggregate while keeping individual data points anonymous.) The authors show that to mitigate the risk of reconstruction, a certain amount of noise needs to be introduced into the data. Needless to say, perturbing the original data in this way, while necessary for privacy, has implications for the quality of the responses to queries, i.e., the accuracy of the statistical database.

In explaining the purpose of DP in the first chapter of their book The Algorithmic Foundations of Differential Privacy [5], Cynthia Dwork and Aaron Roth address this tradeoff between privacy and accuracy:

“[T]he Fundamental Law of Information Recovery states that overly accurate answers to too many questions will destroy privacy in a spectacular way. The goal of algorithmic research on differential privacy is to postpone this inevitability as long as possible. Differential privacy addresses the paradox of learning nothing about an individual while learning useful information about a population.” [5]

The notion of “learning nothing about an individual while learning useful information about a population” is captured by considering two datasets that differ by a single entry (one that includes the entry and one that doesn’t). An (ε, δ)-differentially private querying mechanism is one for which the probability of a certain output being returned when querying one dataset is at most a multiplicative factor of the probability when querying the other dataset. Denoting the mechanism by M, the set of possible outputs by S, and the datasets by x and y, we formalize this as [5]:

Pr[M(x) ∈ S] ≤ exp(ε) ⋅ Pr[M(y) ∈ S] + δ

Where ε is the privacy loss parameter and δ is the failure probability parameter. ε quantifies how much privacy is lost as a result of a query, while a positive δ allows for privacy to fail altogether for a query at a certain (usually very low) probability. Note that ε is an exponential parameter, meaning that even slightly increasing it can cause privacy to decay significantly.

An important and useful property of DP is composition. Notice that the definition above only applies to cases where we run a single query. The composition property helps us generalize it to cover multiple queries based on the fact that privacy loss and failure probability accumulate predictably when we compose several queries, be they based on the same mechanism or different ones. This accumulation is easily proven to be (at most) linear [5]. What this means is that, rather than considering a privacy loss parameter for one query, we may view ε as a privacy budget that can be utilized across a number of queries. For example, when taken together, one query using a (1, 0)-DP mechanism and two queries using a (0.5, 0)-DP mechanism satisfy (2, 0)-DP.

The value of DP comes from the theoretical privacy guarantees it promises. Setting ε = 1 and δ = 0, for example, we find that the probability of any given output occurring when querying dataset y is at most exp(1) = e ≈ 2.718 times greater than that same output occurring when querying dataset x. Why does this matter? Because the greater the discrepancy between the probabilities of certain outputs occurring, the easier it is to determine the contribution of the individual entry by which the two datasets differ, and the easier it is to ultimately reconstruct that individual entry.

In practice, designing an (ε, δ)-differentially private randomized mechanism entails the addition of random noise drawn from a distribution dependent on ε and δ. The specifics are beyond the scope of this article. Shifting our focus back to machine learning, though, we find that the idea is the same: DP for ML hinges on introducing noise into the training data, which yields robust privacy guarantees in much the same way.

Of course, this is where the tradeoff we mentioned comes into play. Adding noise to the training data comes at the cost of making learning more difficult. We could absolutely add enough noise to achieve ε = 0.01 and δ = 0, making the difference in output probabilities between x and y virtually nonexistent. This would be wonderful for privacy, but terrible for learning. A model trained on such a noisy dataset would perform very poorly on most tasks.

There is no consensus on what constitutes a “good” ε value, or on universal methodologies or best practices for ε selection [6]. In many ways, ε embodies the privacy/accuracy tradeoff, and the “proper” value to aim for is highly context-dependent. ε = 1 is generally regarded as offering high privacy guarantees. Although privacy diminishes exponentially with respect to ε, values as high as ε = 32 are mentioned in literature and thought to provide moderately strong privacy guarantees [1]. 

The authors of Reconciling privacy and accuracy in AI for medical imaging [1] test the effects of DP on the accuracy of AI models on three real-world medical imaging datasets. They do so using various values of ε and comparing them to a non-private (non-DP) control. Table 1 provides a partial summary of their results for ε = 1 and ε = 8:

Table 1: Comparison of AI model performance across the RadImageNet [7], HAM10000 [8], and MSD Liver [9] datasets with δ = 8⁻⁷⋅10 and privacy budgets of ε = 1, ε = 8, and without DP (non-private). A higher MCC/Dice score indicates higher accuracy. Although providing strong theoretical privacy guarantees in the face of a worst-case adversary, DP significantly degrades model accuracy. The negative impact on performance is especially noticeable in the latter two datasets, which are considered small datasets. Image by the author, based on image by A. Ziller, T.T. Mueller, S. Stieger, et al from Table 3 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license).

Even approaching the higher end of the typical ε values attested in literature, DP is still as cumbersome as a bank vault door for medical imaging tasks. The noise introduced into the training data is catastrophic for AI model accuracy, especially when the datasets at hand are small. Note, for example, the huge drop-off in Dice score on the MSD Liver dataset, even with the relatively high ε value of 8.

Ziller, Mueller, Stieger, et al. suggest that the accuracy drawbacks of DP with typical ε values may contribute to the lack of widespread adoption of DP in the field of Medical Ai [1]. Yes, wanting mathematically-provable privacy guarantees is definitely sensible, but at what cost? Leaving so much of the diagnostic power of AI models on the table in the name of privacy is not an easy choice to make.

Revisiting our dream home scenario armed with an understanding of DP, we find that the options we (seem to) have map neatly onto the three we had for our front door.

  • DP with typical values of ε is like installing a bank vault door: costly, but effective for privacy. As we’ll see, it’s also complete overkill in this case.
  • Not using DP is like not installing a door at all: much easier, but risky. As mentioned above, though, DP has yet to be widely applied in medical AI [1].
  • Passing up opportunities to use AI is like giving up and selling the house: it saves us the headache of dealing with privacy concerns weighed against incentives to maximize accuracy, but a lot of potential is lost in the process.

It looks like we’re at an impasse… unless we think outside the box.

High-Budget DP: Privacy and Accuracy Aren’t an Either/Or

In Reconciling privacy and accuracy in AI for medical imaging [1], Ziller, Mueller, Stieger, et al. offer the medical AI equivalent of a regular front door — an approach that manages to protect privacy while giving up very little in the way of model performance. Granted, this protection is not theoretically optimal — far from it. However, as the authors show through a series of experiments, it is good enough to counter almost any realistic threat of reconstruction. 

As the saying goes, “Perfect is the enemy of good.” In this case, it is the “optimal” — an insistence on arbitrarily low ε values — that locks us into the false dichotomy of total privacy versus total accuracy. Just as a bank vault door has its place in the real world, so does DP with ε ≤ 32. Still, the existence of the bank vault door doesn’t mean plain old front doors don’t also have a place in the world. The same goes for high-budget DP.

The idea behind high-budget DP is straightforward: using privacy budgets (ε values) that are so high that they “are near-universally shunned as being meaningless” [1] — budgets ranging from ε = 10⁶ to as high as ε = 10¹⁵. In theory, these provide such weak privacy guarantees that it seems like common sense to dismiss them as no better than not using DP at all. In practice, though, this couldn’t be further from the truth. As we will see by looking at the results from the paper, high-budget DP shows significant promise in countering realistic threats. As Ziller, Mueller, Stieger, et al. put it [1]:

“[E]ven a ‘pinch of privacy’ has drastic effects in practical scenarios.”

First, though, we need to ask ourselves what we consider to be a “realistic” threat. Any discussion of the efficacy of high-budget DP is inextricably tied to the threat model under which we choose to evaluate it. In this context, a threat model is simply the set of assumptions we make about what a bad actor interested in obtaining our model’s training data is able to do.

Table 2: Comparison of threat models. For all three, we also assume that the adversary has unbounded computational ability. Image by A. Ziller, T.T. Mueller, S. Stieger, et al from Table 1 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license).

The paper’s findings hinge on a calibration of the assumptions to better suit real-world threats to patient privacy. The authors argue that the worst-case model, which is the one typically used for DP, is far too pessimistic. For example, it assumes that the adversary has full access to each original image while attempting to reconstruct it based on the AI model (see Table 2) [1]. This pessimism explains the discrepancy between the reported “drastic effects in practical scenarios” of high privacy budgets and the very weak theoretical privacy guarantees that they offer. We may liken it to incorrectly assessing the security threats a typical house faces, wrongly assuming they are likely to be as sophisticated and enduring as those faced by a bank. 

The authors therefore propose two alternative threat models, which they call the “relaxed” and “realistic” models. Under both of these, adversaries keep some core capabilities from the worst-case model: access to the AI model’s architecture and weights, the ability to manipulate its hyperparameters, and unbounded computational abilities (see Table 2). The realistic adversary is assumed to have no access to the original images and an imperfect reconstruction algorithm. Even these assumptions leave us with a rigorous threat model that may still be considered pessimistic for most real-world scenarios [1].

Having established the three relevant threat models to consider, Ziller, Mueller, Stieger, et al. compare AI model accuracy in conjunction with the reconstruction risk under each threat model at different values of ε. As we saw in Table 1, this is done for three exemplary Medical Imaging datasets. Their full results are presented in Table 3:

Table 3: Comparison of AI model performance and reconstruction risk per threat model across the RadImageNet [7], HAM10000 [8], and MSD Liver [9] datasets with δ = 8⁻⁷⋅10 and various privacy budgets, including some as high as ε = 10⁹ and ε = 10¹². A higher MCC/Dice score indicates higher accuracy. Image by A. Ziller, T.T. Mueller, S. Stieger, et al from Table 3 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license).

Unsurprisingly, high privacy budgets (exceeding ε = 10⁶) significantly mitigate the loss of accuracy seen with lower (stricter) privacy budgets. Across all tested datasets, models trained with high-budget DP at ε = 10⁹ (HAM10000, MSD Liver) or ε = 10¹² (RadImageNet) perform nearly as well as their non-privately trained counterparts. This is in line with our understanding of the privacy/accuracy tradeoff: the less noise introduced into the training data, the better a model can learn.

What is surprising is the degree of empirical protection afforded by high-budget DP against reconstruction under the realistic threat model. Remarkably, the realistic reconstruction risk is assessed to be 0% for each of the aforementioned models. The high efficacy of high-budget DP in defending medical AI training images against realistic reconstruction attacks is made even clearer by looking at the results of reconstruction attempts. Figure 1 below shows the five most readily reconstructed images from the MSD Liver dataset [9] using DP with high privacy budgets of ε = 10⁶, ε = 10⁹, ε = 10¹², and ε = 10¹⁵.
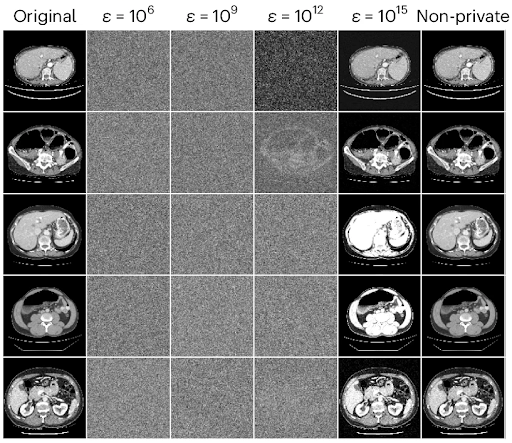
Figure 1: The five most readily reconstructed images from the MSD Liver dataset [9] using DP with high privacy budgets of ε = 10⁶, ε = 10⁹, ε = 10¹², and ε = 10¹⁵. Image by A. Ziller, T.T. Mueller, S. Stieger, et al from Figure 3 in Reconciling privacy and accuracy in AI for medical imaging [1] (use under CC-BY 4.0 license).

Note that, at least to the naked eye, even the best reconstructions obtained when using the former two budgets are visually indistinguishable from random noise. This lends intuitive credence to the argument that budgets often deemed too high to provide any meaningful protection could be instrumental in protecting privacy without giving up accuracy when using AI for medical imaging. In contrast, the reconstructions when using ε = 10¹⁵ closely resemble the original images, showing that not all high budgets are created equal.

Based on their findings, Ziller, Mueller, Stieger, et al. make the case for training medical imaging AI models using (at least) high-budget DP as the norm. They note the empirical efficacy of high-budget DP in countering realistic reconstruction risks at very little cost in terms of model accuracy. The authors go so far as to claim that “it seems negligent to train AI models without any form of formal privacy guarantee.” [1]


Conclusion

We started with a hypothetical scenario in which you were forced to decide between a bank vault door or no door at all for your dream home (or giving up and selling the incomplete house). After an exploration of the risks posed by inadequate privacy protection in medical AI, we looked into the privacy/accuracy tradeoff as well as the history and theory behind reconstruction attacks and differential privacy (DP). We then saw how DP with common privacy budgets (ε values) degrades medical AI model performance and compared it to the bank vault door in our hypothetical. 

Finally, we examined empirical results from the paper Reconciling privacy and accuracy in AI for medical imaging to find out how high-budget differential privacy can be used to escape the false dichotomy of bank vault door vs. no door and protect Patient Privacy in the real world without sacrificing model accuracy in the process.

If you enjoyed this article, please consider following me on LinkedIn to keep up with future articles and projects.

References

[1] Ziller, A., Mueller, T.T., Stieger, S. et al. Reconciling privacy and accuracy in AI for medical imaging. Nat Mach Intell 6, 764–774 (2024). https://doi.org/10.1038/s42256-024-00858-y.

[2] Ray, S. Samsung bans ChatGPT and other chatbots for employees after sensitive code leak. Forbes (2023). https://www.forbes.com/sites/siladityaray/2023/05/02/samsung-bans-chatgpt-and-other-chatbots-for-employees-after-sensitive-code-leak/.

[3] Ateniese, G., Mancini, L. V., Spognardi, A. et al. Hacking smart machines with smarter ones: how to extract meaningful data from machine learning classifiers. International Journal of Security and Networks 10, 137–150 (2015). https://doi.org/10.48550/arXiv.1306.4447.

[4] Dinur, I. & Nissim, K. Revealing information while preserving privacy. Proc. 22nd ACM SIGMOD-SIGACT-SIGART Symp Principles Database Syst 202–210 (2003). https://doi.org/10.1145/773153.773173.

[5] Dwork, C. & Roth, A. The algorithmic foundations of differential privacy. Foundations and Trends in Theoretical Computer Science 9, 211–407 (2014). https://doi.org/10.1561/0400000042.

[6] Dwork, C., Kohli, N. & Mulligan, D. Differential privacy in practice: expose your epsilons! Journal of Privacy and Confidentiality 9 (2019). https://doi.org/10.29012/jpc.689.

[7] Mei, X., Liu, Z., Robson, P.M. et al. RadImageNet: an open radiologic deep learning research dataset for effective transfer learning. Radiol Artif Intell 4.5, e210315 (2022). https://doi.org/10.1148/ryai.210315.

[8] Tschandl, P., Rosendahl, C. & Kittler, H. The HAM10000 dataset, a large collection of multi-source dermatoscopic images of common pigmented skin lesions. Sci Data 5, 180161 (2018). https://doi.org/10.1038/sdata.2018.161.

[9] Antonelli, M., Reinke, A., Bakas, S. et al. The Medical Segmentation Decathlon. Nat Commun 13, 4128 (2022). https://doi.org/10.1038/s41467-022-30695-9.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

SolarWinds launches Avior AI agents to automate network operations

The first Avior offering is a network engineering agent that can automate alert management, configuration automation, compliance checks, and incident remediation. “We started there because [the network is] kind of our bread and butter,” Childress explains. “Many of our customers, a large portion of our customers, are on our network

Read More »

Hydrocarbons and Geothermal Energy Office Executes First-Ever License for TRIG Gasification Technology

WASHINGTON—The U.S. Department of Energy’s (DOE) Hydrocarbons and Geothermal Energy Office (HGEO) today announced that the Department has executed its first-ever nonexclusive license with Latitude Energy Services for the Transport Integrated Gasification (TRIG™) technology. The license is limited to the power field of use. Latitude independently holds the rights to TRIG™ in the industrial field of use, which will be complemented by this license. The executed license marks a significant milestone in the technology transfer and commercialization of a federally co‑developed advanced coal gasification system, while creating a pathway for additional commercial deployment opportunities for America’s coal industry.  TRIG™ is a first‑of‑its‑kind gasification system jointly developed by DOE and industry partners. Designed specifically for low‑rank, high‑moisture coals, TRIG™ converts these abundant but traditionally harder-to-use resources into flexible fuel gas at higher efficiency, creating new opportunities to put America’s coal resources to work.  “TRIG shows what can happen when American innovation is paired with a clear path to commercialization,” said DOE Acting Assistant Secretary of the Hydrocarbons and Geothermal Energy Office Curt Coccodrilli. “Under President Trump’s leadership, we are reinvigorating America’s coal industry by moving innovative technologies out of the laboratory and into the marketplace. By moving this DOE co-developed technology and a deep body of real-world technical data into the hands of industry, we are strengthening American energy security and extending U.S. energy leadership at home and around the world.”  TRIG™ is a ready‑to‑use platform backed by years of engineering, testing, and real‑world operational data. Companies adopting TRIG™ have access to the extensive information collected through DOE’s work on the Kemper County, Mississippi integrated gasification combined cycle project. Resources include plant designs, construction records, operational lessons, and more than 20,000 historical data logs that document TRIG™’s demonstrated performance and support commercial development decisions. With this first nonexclusive license, TRIG™ is now

Read More »

YPF lets additional rig contracts for work in Argentina

Yacimientos Petrolíferos Fiscales (YPF) has let an additional long-term agreement for two drilling rigs to Archer for work in Argentina. The 3-year drilling contract, which holds an option for an additional 2 years, is for the addition of the DLS-160 rig to Archer’s operations in Vaca Muerta, while securing the continued deployment of the DLS-rig 163 in support of YPF’s ongoing development activities in the basin. The contract expands Archer’s operating fleet of rigs in the region and has an estimated value of US$100-110 million over the full contract term, including the optional extension years, Archer said. Vaca Muerta oil production forecast Argentina’s Vaca Muerta play is on track to reach oil production of 1 million b/d by 2030 through infrastructure buildout, capital deployment, and operational learnings, according to a report by Wood Mackenzie.  Oil production is projected to grow quickly, led by YPF and core operators across key development areas, while gas production is projected to exceed 7 bcfd post-2030, with associated gas from oil-focused drilling as a major contributor to incremental supply.

Read More »

Energy Department Announces Virginia and West Virginia Transmission Project to Receive Defense Production Act Funding, Strengthening National Security and Grid Reliability

WASHINGTON—The U.S. Department of Energy (DOE) today announced its intent to deploy Defense Production Act (DPA) funding to accelerate the expansion of transmission capacity in Virginia and West Virginia, strengthening grid reliability and infrastructure essential to national defense. Virginia Energy’s Grid Enhancing Technologies for Virginia & West Virginia Large Load Growth project will receive up to $50 million in DPA funding to deploy advanced transmission technologies across existing power lines to increase electricity delivery capacity, reduce congestion, and support growing energy demand across the region.  The proposed project will deploy advanced reconductoring and Dynamic Line Rating technologies along existing transmission corridors, adding an estimated 290 megawatts of transmission capacity across Appalachian Power’s Virginia system, one to four years faster than conventional transmission upgrades. These improvements will make the power grid more reliable, lower electricity costs, and help ensure that communities, businesses, military operations, and government and defense-related industries across the region have dependable power, especially during times of high demand or power disruptions. Thanks to President Trump and the passage of the Working Families Tax Cut, $1 billion in federal funding has been appropriated for energy-related projects deemed critical to national security. Presidential Determination No. 2026-10  identifies transmission lines and conductors, substations, and power-control and protection equipment as essential to national defense. “President Trump is committed to doing everything possible to strengthen American energy security and lower costs for the American people,” said U.S. Secretary of Energy Chris Wright. “By deploying Defense Production Act funding to secure and expand electricity access in Virginia and West Virginia, the Trump Administration is strengthening the nation’s energy security for decades to come.”  “A stronger electric grid doesn’t always mean building more power lines. Sometimes it means making better use of the ones we already have,” said Office of Electricity Assistant Secretary Katie Jereza. “This investment will help unlock more power,

Read More »

Canada rig count down 5 units

The rig count in Canada fell by 5 units to 217 rigs working for the week ended Oct. 16, according to data from Baker Hughes. All 5 rigs were gas-directed, bringing the number of rigs drilling for gas in Canada this week to 65. The oil-directed rig count in Canada remained unchanged at 150. The overall US drilling rig count was unchanged this week at 603 rigs working. That number is up 55 units from this time last year. In the US, 3 fewer rigs were drilling for oil, bringing the total count to 459. That number is up 41 units from this time last year. The number of gas-directed rigs increased by 1 to 133 working for the week. This time last year, 121 rigs were drilling for gas in the US. There were 589 rigs drilling on US land this week, down 1 unit from last week and up 61 from the year-ago period. One additional rig was drilling offshore this week for a total of 13. The number of rigs drilling in inland waters remained unchanged at 1. Leading the major oil-and gas-producing states in rigs added was Utah with a 5-unit gain to end the week with 20 rigs working. The count is up 7 units from this time in 2025. Louisiana added 2 rigs to end the week with 40 units working. Texas ended the week with 3 fewer rigs working for a total of 278. The count is 41 units higher than this time last year. New Mexico dropped 3 units to end the week with 96. Oklahoma, Wyoming, and California each dropped a single unit to end the week with respective counts of 50, 16, and 5.

Read More »

IEA: Middle East war weighs on emerging-market oil demand

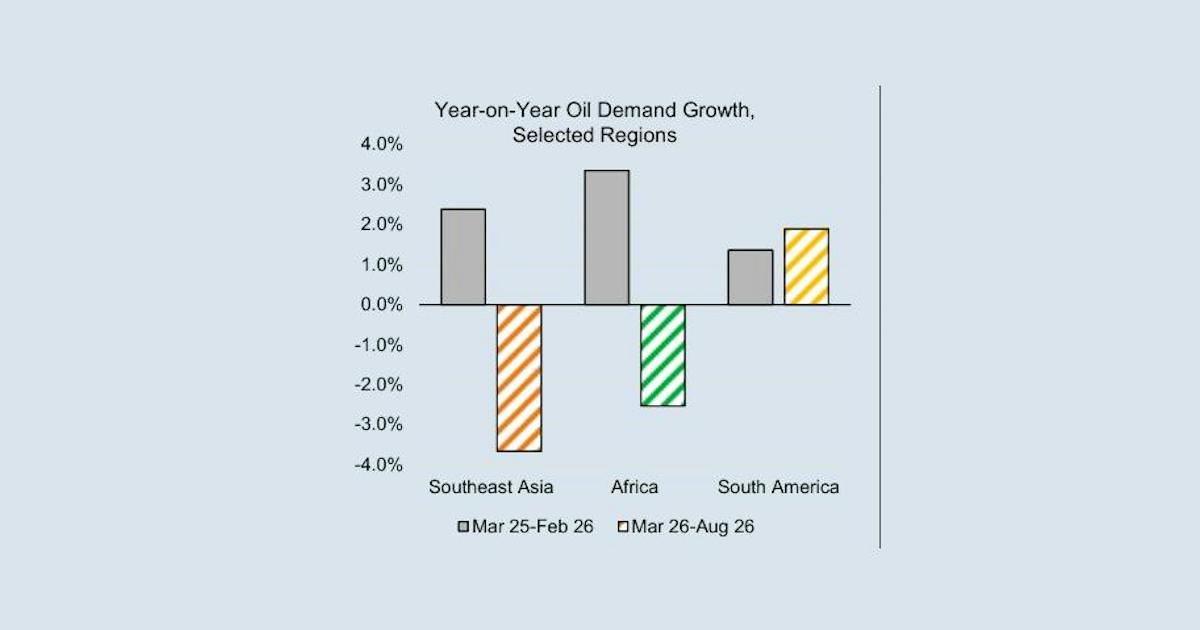
Oil demand in Southeast Asia and Africa has fallen sharply since the outbreak of the Middle East war, as disrupted trade flows, tighter fuel supplies, and higher prices weigh on consumption, according to the International Energy Agency (IEA). South America, by contrast, has remained relatively resilient, benefiting from its lower dependence on Middle Eastern oil supplies. In its October Oil Market Report, IEA said Southeast Asia, Africa, and South America together accounted for about 17.8 million b/d of oil demand in 2025. Assessing consumption trends remains challenging because timely reporting is limited across many emerging economies. Southeast Asian oil demand declined by an estimated 260,000 b/d, or 3.7%, year-on-year (y-o-y) during March-August 2026, compared with prewar expectations for 2.3% growth. The roughly 6-percentage-point deterioration reflects the region’s exposure to disruptions through the Strait of Hormuz. Apparent demand fell by an even steeper 6.3%, suggesting substantial unobserved draws from product inventories. IEA expects Southeast Asian demand to decline by 160,000 b/d, or 2%, in 2026 before rebounding by 270,000 b/d in 2027, supported by economic growth in Indonesia, Vietnam, Malaysia, the Philippines, and Thailand. African demand reverses Africa experienced a similarly sharp reversal. Following estimated demand growth of 3.4% in the 12 months before the war, regional consumption contracted by 2.5% y-o-y during March-August. Apparent demand fell by about 6%. The region’s dependence on imported refined products, particularly diesel and gasoline, has increased its vulnerability to supply disruptions and higher prices. Trade patterns have shifted toward lower imports and increased product exports, including middle distillate shipments from Nigeria. Nigerian oil demand fell by 150,000 b/d, or nearly 30%, y-o-y in July. IEA expects consumption to decline by almost 60,000 b/d in 2026 to 470,000 b/d before recovering by a similar amount in 2027. Egypt, Africa’s largest oil consumer, recorded a demand

Read More »

Energy Department Invests Over $11 Million to Strengthen America’s Energy Workforce

WASHINGTON—The U.S. Department of Energy’s (DOE) Hydrocarbons and Geothermal Energy Office (HGEO) and Office of Indian Energy Policy and Programs (IE) today announced nearly $11.1 million in federal funding for eight projects selected for negotiation through the Partnerships for Academic-Industry Career Training (PACT) Initiative. The projects will create or expand hands-on training and industry-recognized credentialing programs designed around regional workforce needs, helping prepare American workers for critical jobs that support oil, natural gas, coal, and geothermal energy industries. “President Trump’s American energy dominance agenda relies on workers with the practical skills to build, operate, maintain, and modernize the systems that power our economy,” said DOE Acting Assistant Secretary for Hydrocarbons and Geothermal Energy Curt Coccodrilli. “These projects will bring industry and educators together to ensure training reflects real-world needs. By investing in job-focused training, the Department of Energy is helping develop the workforce we need to strengthen U.S. energy resilience and supplies.”  “The Tribal energy workforce is vital to unleashing America’s energy resources,” said IE Director Eric Mahroum. “Through targeted jobs and training, Tribes are growing the next generation of Tribal energy leaders. Tribal colleges and universities are essential partners in this mission, and we are proud to select two of these institutions as they prepare workers to tackle the critical energy challenges facing America.”  The selections include almost $8.8 million for six HGEO-supported projects and approximately $2.3 million for two IE-supported projects. By bringing together colleges, technical institutions, employers, and workforce partners, PACT is designed to build a stronger pipeline of skilled workers needed to advance President Trump’s commitment to expand domestic energy production to provide more affordable, reliable, and secure energy to the American people.  Learn more about the selected eight projects here.  

Read More »

DCF Global: The Nordics’ AI Boom Meets the Power Test

Sustainability Becomes an Infrastructure Requirement Sustainability has long been central to the Nordic data center proposition. Hydropower, nuclear generation, wind resources and relatively cool ambient temperatures provide advantages for operators pursuing lower-carbon operations and efficient facility design. However, the growing concentration of AI infrastructure investment is changing the terms of that discussion. Rather than evaluating sustainability primarily through electricity sourcing or annualized power usage effectiveness, developers increasingly face questions about their contribution to regional energy systems, electricity supply, environmental protection and local economic development. One area where the Nordics offer a particularly developed model is waste-heat reuse. District heating networks are widespread across northern Europe, creating opportunities to recover thermal energy from data centers and distribute it to homes, businesses and other facilities. The approach has a long history in the region, including the Danish and Swedish projects explored by Rich Miller in Data Center Frontier’s earlier coverage of using server heat to warm nearby homes. In Espoo, Finland, atNorth has begun supplying recovered heat from its FIN02 data center to a neighboring retail property operated by Kesko. The system became operational in November 2025, providing a tangible example of data center thermal energy being put to productive use. In Helsinki, AI infrastructure developer OnZero has reached an agreement with municipal energy company Helen to connect a planned AI data center to the district heating network. The project is designed to supply as much as 525,000 MWh of recovered heat annually once operational, with service targeted for 2027. Denmark offers another variation on the approach. atNorth and Selected Group are advancing a project in Ølgod that would use surplus heat from atNorth’s DEN02 campus to support greenhouse food production. In October, Selected Group reported approval of the local development plan. The first phase involves two 10-hectare greenhouses, with the initial

Read More »

AI datacenter capex will far exceed forecast revenue through 2030

Investors are pouring more into AI data center infrastructure than they can hope to recoup by 2030, according to Gartner. “Enterprise and consumer AI revenue will be insufficient to support profitable returns on all planned AI capital expenditures during this period,” said Gartner Senior Director Analyst Will Sommer. AI data center owners would need to generate $8.5 trillion in revenue through 2030 to cover announced capital spending, financing costs and expected investment returns, he said. “However, total enterprise and consumer AI revenue that can be attributed to AI data centers during this period is forecast to reach no more than $3.6 trillion.”

Read More »

OCP 2026: AI Infrastructure Moves From Scaling to Coordination

Google: Using AI to Engineer the AI Factory Google Vice President and Engineering Fellow Parthasarathy Ranganathan closed the keynote program by extending the discussion beyond infrastructure designed for AI toward infrastructure increasingly designed and operated with AI. The distinction was central to his presentation. For several years, hyperscalers have pursued progressively more sophisticated custom systems to meet the demands of artificial intelligence. Google’s own approach has included TPUs, custom CPUs, optical networking, power distribution, liquid cooling, and extensive hardware-software co-design. But Ranganathan argued that the next opportunity involves applying AI directly to the processes of systems engineering. Google has already been pursuing the concept of agile and fungible data centers, capable of accommodating changing generations of computing hardware without requiring fundamental redesigns of every supporting system. Its OCP contributions include Project Deschutes, an open cooling distribution unit architecture; Project Brazos, intended to bring liquid cooling capabilities into existing air-cooled facilities; and power distribution specifications supporting higher-voltage DC architectures. Ranganathan also highlighted collaborative work involving Google, Meta, Microsoft, and NVIDIA on specifications intended to improve coordination between AI data centers and utility systems. Those efforts address the physical infrastructure required to support AI. The next stage, he suggested, is to apply AI to the engineering processes themselves. Google is exploring AI-assisted hardware architecture, automated software vulnerability detection and repair, data center climate modeling, and infrastructure capacity planning. Among the examples Ranganathan discussed were agentic systems capable of evaluating computer architecture choices and accelerating engineering workflows, alongside AI-assisted tools for software maintenance and operational optimization. In data center design, the company is applying AI and climate modeling to decisions involving cooling capacity, extreme weather risk, and long-term infrastructure investment. The approach could enable more site-specific designs, reducing the need to rely on broad assumptions about operating conditions throughout a facility’s useful life.

Read More »

OPC Global Summit: News spans AI-optimized hardware, cooling equipment

Arm announces methodology for evaluating CPU performance Arm released a white paper, developed with partners, that proposes a use-case-driven methodology for measuring the CPU’s contribution to agentic AI systems. It defines five representative workload types—software engineering, enterprise operations, financial and scientific research, personal assistants, and robotics—and pairs component-level benchmarking with end-to-end task measurement built on re-playable agent trajectories. Arm also highlighted independent testing by Signal65 that found its AGI CPU could deliver up to twice the rack-level performance of AMD’s Epyc Turin generation server processors across select agentic AI workloads. The comparison emphasizes completed work under rack-level constraints rather than conventional CPU benchmarks alone. In the testing, an Arm AGI CPU averaged 1.7x better performance for tooling, 2.0x for agentic workflows and orchestration, and 2.2x for reasoning and planning in modeled per-rack performance versus an AMD Epyc Turin processor. Arm’s AGI CPU reduces sandbox creation latency by up to 45% versus AMD Epyc 9965, helping agents spin up isolated execution environments faster, according to Arm. Kioxia introduces SSDs for AI Kioxia unveiled its LD4 Series enterprise solid-state drives (SSD), designed to increase flash storage density in hyperscale data centers and high density 1U servers. The drives target read-intensive workloads, including data storage applications supporting artificial intelligence infrastructure.

Read More »

Virginia’s New Data Center Bargain: Power, Permits and the Right to Build

What Took Effect—and What Still Requires Legislation Spanberger laid out the administration’s rationale in announcing the framework: “In the years before I took office, data centers came to Virginia and the Commonwealth did not have a clear or coordinated plan to address their impacts on Virginians — on their electric bills, their water, their land, their air, or their quality of life. That changes today. I have said many times that Virginia should be leading the nation in setting the highest standards for this industry. And now, I believe we are doing just that.” The distinction between what Virginia has already implemented and what the administration intends to pursue is consequential. Executive Order 22 establishes immediate directives for state agencies, while significant portions of the broader Data Center Accountability Framework remain proposals for the 2027 General Assembly or future regulatory action. Among the immediate changes, executive-branch agencies are prohibited from entering into or enforcing new nondisclosure agreements that conceal material information about proposed commercial data centers, public incentives, resource demands or community impacts. Existing contractual commitments are preserved, with limited exceptions contemplated for extraordinary circumstances, including national security. The prohibition does not yet extend automatically to local governments. The order also excludes new data center projects with anticipated peak electrical demand of 25 MW or greater from the Virginia Business Ready Sites Program and similar discretionary state site-readiness and expedited-review assistance. A separate, potentially more consequential proposal would eliminate by-right development approval for data centers using more than 25 MW, requiring local approval even for projects with prior authorizations. That provision has not been enacted statewide and could introduce significant legal questions concerning established development rights. The administration is also accelerating environmental oversight. Within 120 days of the order, the Office of the Chief Energy Officer must publish an initial

Read More »

OCP 2026: Agentic AI Drives the Data Center’s Chip-to-Grid Transformation

NVIDIA Opens More of the AI Factory Architecture NVIDIA’s Ian Buck closed the opening keynote program with an extensive presentation covering Vera Rubin systems, open rack designs, networking, power delivery and AI factory software. The company announced additional contributions to OCP based on its third-generation MGX 1.2 reference architecture. The specification includes high-density liquid-cooled computing systems, improved cooling connections, standardized power interfaces and modular mechanical designs. Buck emphasized that these developments are as much about manufacturing and serviceability as they are about computational performance. He described how NVIDIA reduced the assembly time for a compute tray from approximately 90 minutes in the Grace Blackwell generation to roughly one minute for Vera Rubin through simplified mechanical construction and more automated assembly. At the scale of thousands of racks, those manufacturing improvements can materially influence deployment schedules. NVIDIA also previewed its next-generation Vera Rubin Ultra architecture, designed to interconnect 576 GPUs using an advanced NVLink fabric with co-packaged optics. Open Data Center and Grid Resilience Specifications For data center developers and operators, however, NVIDIA’s most consequential OCP contributions may lie outside the computing rack. NVIDIA, AMD, Google and Meta have published an Open Data Center Specification, currently at version 0.7, intended to establish common design principles for AI factory facilities. The specification addresses power architecture, cooling infrastructure and physical layout, helping equipment suppliers and developers coordinate around shared infrastructure requirements. That shared facilities work unfolds alongside vendor-specific programs such as NVIDIA’s DSX Ready, which establishes qualification requirements for battery energy storage and liquid cooling equipment supporting its AI factory designs. NVIDIA also joined Google, Meta and Microsoft in publishing an OCP Grid Resilience Specification addressing the behavior of large AI installations during grid disturbances. The specification establishes expectations for facilities to remain connected, respond automatically to disturbances and recover toward normal operating

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »