Stay Ahead, Stay ONMINE

Generative AI Is Declarative

ChatGPT launched in 2022 and kicked off the Generative Ai boom. In the two years since, academics, technologists, and armchair experts have written libraries worth of articles on the technical underpinnings of generative AI and about the potential capabilities of both current and future generative AI models. Surprisingly little has been written about how we interact with these tools—the human-AI interface. The point where we interact with AI models is at least as important as the algorithms and data that create them. “There is no success where there is no possibility of failure, no art without the resistance of the medium” (Raymond Chandler). In that vein, it’s useful to examine human-AI interaction and the strengths and weaknesses inherent in that interaction. If we understand the “resistance in the medium” then product managers can make smarter decisions about how to incorporate generative AI into their products. Executives can make smarter decisions about what capabilities to invest in. Engineers and designers can build around the tools’ limitations and showcase their strengths. Everyday people can know when to use generative AI and when not to. Imagine walking into a restaurant and ordering a cheeseburger. You don’t tell the chef how to grind the beef, how hot to set the grill, or how long to toast the bun. Instead, you simply describe what you want: “I’d like a cheeseburger, medium rare, with lettuce and tomato.” The chef interprets your request, handles the implementation, and delivers the desired outcome. This is the essence of declarative interaction—focusing on the what rather than the how. Now, imagine interacting with a Large Language Model (LLM) like ChatGPT. You don’t have to provide step-by-step instructions for how to generate a response. Instead, you describe the result you’re looking for: “A user story that lets us implement A/B testing for the Buy button on our website.” The LLM interprets your prompt, fills in the missing details, and delivers a response. Just like ordering a cheeseburger, this is a declarative mode of interaction. Explaining the steps to make a cheeseburger is an imperative interaction. Our LLM prompts sometimes feel imperative. We might phrase our prompts like a question: ”What is the tallest mountain on earth?” This is equivalent to describing “the answer to the question ‘What is the tallest mountain on earth?’” We might phrase our prompt as a series of instructions: ”Write a summary of the attached report, then read it as if you are a product manager, then type up some feedback on the report.” But, again, we’re describing the result of a process with some context for what that process is. In this case, it is a sequence of descriptive results—the report then the feedback. This is a more useful way to think about LLMs and generative AI. In some ways it is more accurate; the neural network model behind the curtain doesn’t explain why or how it produced one output instead of another. More importantly though, the limitations and strengths of generative AI make more sense and become more predictable when we think of these models as declarative. LLMs as a declarative mode of interaction Computer scientists use the term “declarative” to describe coding languages. SQL is one of the most common. The code describes the output table and the procedures in the database figure out how to retrieve and combine the data to produce the result. LLMs share many of the benefits of declarative languages like SQL or declarative interactions like ordering a cheeseburger. Focus on desired outcome: Just as you describe the cheeseburger you want, you describe the output you want from the LLM. For example, “Summarize this article in three bullet points” focuses on the result, not the process. Abstraction of implementation: When you order a cheeseburger, you don’t need to know how the chef prepares it. When submitting SQL code to a server, the server figures out where the data lives, how to fetch it, and how to aggregate it based on your description. You as the user don’t need to know how. With LLMs, you don’t need to know how the model generates the response. The underlying mechanisms are abstracted away. Filling in missing details: If you don’t specify onions on your cheeseburger, the chef won’t include them. If you don’t specify a field in your SQL code, it won’t show up in the output table. This is where LLMs differ slightly from declarative coding languages like SQL. If you ask ChatGPT to create an image of “a cheeseburger with lettuce and tomato” it may also show the burger on a sesame seed bun or include pickles, even if that wasn’t in your description. The details you omit are inferred by the LLM using the “average” or “most likely” detail depending on the context, with a bit of randomness thrown in. Ask for the cheeseburger image six times; it may show you three burgers with cheddar cheese, two with Swiss, and one with pepper jack. Like other forms of declarative interaction, LLMs share one key limitation. If your description is vague, ambiguous, or lacks enough detail, then the result may not be what you hoped to see. It is up to the user to describe the result with sufficient detail. This explains why we often iterate to get what we’re looking for when using LLMs and generative AI. Going back to our cheeseburger analogy, the process to generate a cheeseburger from an LLM may look like this. “Make me a cheeseburger, medium rare, with lettuce and tomatoes.” The result also has pickles and uses cheddar cheese. The bun is toasted. There’s mayo on the top bun. “Make the same thing but this time no pickles, use pepper jack cheese, and a sriracha mayo instead of plain mayo.” The result now has pepper jack, no pickles. The sriracha mayo is applied to the bottom bun and the bun is no longer toasted. “Make the same thing again, but this time, put the sriracha mayo on the top bun. The buns should be toasted.” Finally, you have the cheeseburger you’re looking for. This example demonstrates one of the main points of friction with human-AI interaction. Human beings are really bad at describing what they want with sufficient detail on the first attempt. When we asked for a cheeseburger, we had to refine our description to be more specific (the type of cheese). In the second generation, some of the inferred details (whether the bun was toasted) changed from one iteration to the next, so then we had to add that specificity to our description as well. Iteration is an important part of AI-human generation. Insight: When using generative AI, we need to design an iterative human-AI interaction loop that enables people to discover the details of what they want and refine their descriptions accordingly. To iterate, we need to evaluate the results. Evaluation is extremely important with generative AI. Say you’re using an LLM to write code. You can evaluate the code quality if you know enough to understand it or if you can execute it and inspect the results. On the other hand, hypothetical questions can’t be tested. Say you ask ChatGPT, “What if we raise our product prices by 5 percent?” A seasoned expert could read the output and know from experience if a recommendation doesn’t take into account important details. If your product is property insurance, then increasing premiums by 5 percent may mean pushback from regulators, something an experienced veteran of the industry would know. For non-experts in a topic, there’s no way to tell if the “average” details inferred by the model make sense for your specific use case. You can’t test and iterate. Insight: LLMs work best when the user can evaluate the result quickly, whether through execution or through prior knowledge. The examples so far involve general knowledge. We all know what a cheeseburger is. When you start asking about non-general information—like when you can make dinner reservations next week—you delve into new points of friction. In the next section we’ll think about different types of information, what we can expect the AI to “know”, and how this impacts human-AI interaction. What did the AI know, and when did it know it? Above, I explained how generative AI is a declarative mode of interaction and how that helps understand its strengths and weaknesses. Here, I’ll identify how different types of information create better or worse human-AI interactions. Understanding the information available When we describe what we want to an LLM, and when it infers missing details from our description, it draws from different sources of information. Understanding these sources of information is important. Here’s a useful taxonomy for information types: General information used to train the base model. Non-general information that the base model is not aware of. Fresh information that is new or changes rapidly, like stock prices or current events. Non-public information, like facts about you and where you live or about your company, its employees, its processes, or its codebase. General information vs. non-general information LLMs are built on a massive corpus of written word data. A large part of GPT-3 was trained on a combination of books, journals, Wikipedia, Reddit, and CommonCrawl (an open-source repository of web crawl data). You can think of the models as a highly compressed version of that data, organized in a gestalt manner—all the like things are close together. When we submit a prompt, the model takes the words we use (and any words added to the prompt behind the scenes) and finds the closest set of related words based on how those things appear in the data corpus. So when we say “cheeseburger” it knows that word is related to “bun” and “tomato” and “lettuce” and “pickles” because they all occur in the same context throughout many data sources. Even when we don’t specify pickles, it uses this gestalt approach to fill in the blanks. This training information is general information, and a good rule of thumb is this: if it was in Wikipedia a year ago then the LLM “knows” about it. There could be new articles on Wikipedia, but that didn’t exist when the model was trained. The LLM doesn’t know about that unless told. Now, say you’re a company using an LLM to write a product requirements document for a new web app feature. Your company, like most companies, is full of its own lingo. It has its own lore and history scattered across thousands of Slack messages, emails, documents, and some tenured employees who remember that one meeting in Q1 last year. The LLM doesn’t know any of that. It will infer any missing details from general information. You need to supply everything else. If it wasn’t in Wikipedia a year ago, the LLM doesn’t know about it. The resulting product requirements document may be full of general facts about your industry and product but could lack important details specific to your firm. This is non-general information. This includes personal info, anything kept behind a log-in or paywall, and non-digital information. This non-general information permeates our lives, and incorporating it is another source of friction when working with generative AI. Non-general information can be incorporated into a generative AI application in three ways: Through model fine-tuning (supplying a large corpus to the base model to expand its reference data). Retrieved and fed it to the model at query time (e.g., the retrieval augmented generation or “RAG” technique). Supplied by the user in the prompt. Insight: When designing any human-AI interactions, you should think about what non-general information is required, where you will get it, and how you will expose it to the AI. Fresh information Any information that changes in real-time or is new can be called fresh information. This includes new facts like current events but also frequently changing facts like your bank account balance. If the fresh information is available in a database or some searchable source, then it needs to be retrieved and incorporated into the application. To retrieve the information from a database, the LLM must create a query, which may require specific details that the user didn’t include. Here’s an example. I have a chatbot that gives information on the stock market. You, the user, type the following: “What is the current price of Apple? Has it been increasing or decreasing recently?” The LLM doesn’t have the current price of Apple in its training data. This is fresh, non-general information. So, we need to retrieve it from a database. The LLM can read “Apple”, know that you’re talking about the computer company, and that the ticker symbol is AAPL. This is all general information. What about the “increasing or decreasing” part of the prompt? You did not specify over what period—increasing in the past day, month, year? In order to construct a database query, we need more detail. LLMs are bad at knowing when to ask for detail and when to fill it in. The application could easily pull the wrong data and provide an unexpected or inaccurate answer. Only you know what these details should be, depending on your intent. You must be more specific in your prompt. A designer of this LLM application can improve the user experience by specifying required parameters for expected queries. We can ask the user to explicitly input the time range or design the chatbot to ask for more specific details if not provided. In either case, we need to have a specific type of query in mind and explicitly design how to handle it. The LLM will not know how to do this unassisted. Insight: If a user is expecting a more specific type of output, you need to explicitly ask for enough detail. Too little detail could produce a poor quality output. Non-public information Incorporating non-public information into an LLM prompt can be done if that information can be accessed in a database. This introduces privacy issues (should the LLM be able to access my medical records?) and complexity when incorporating multiple non-public sources of information. Let’s say I have a chatbot that helps you make dinner reservations. You, the user, type the following: “Help me make dinner reservations somewhere with good Neapolitan pizza.” The LLM knows what a Neapolitan pizza is and can infer that “dinner” means this is for an evening meal. To do this task well, it needs information about your location, the restaurants near you and their booking status, or even personal details like dietary restrictions. Assuming all that non-public information is available in databases, bringing them all together into the prompt takes a lot of engineering work. Even if the LLM could find the “best” restaurant for you and book the reservation, can you be confident it has done that correctly? You never specified how many people you need a reservation for. Since only you know this information, the application needs to ask for it upfront. If you’re designing this LLM-based application, you can make some thoughtful choices to help with these problems. We could ask about a user’s dietary restrictions when they sign up for the app. Other information, like the user’s schedule that evening, can be given in a prompting tip or by showing the default prompt option “show me reservations for two for tomorrow at 7PM”. Promoting tips may not feel as automagical as a bot that does it all, but they are a straightforward way to collect and integrate the non-public information. Some non-public information is large and can’t be quickly collected and processed when the prompt is given. These need to be fine-tuned in batch or retrieved at prompt time and incorporated. A chatbot that answers information about a company’s HR policies can obtain this information from a corpus of non-public HR documents. You can fine-tune the model ahead of time by feeding it the corpus. Or you can implement a retrieval augmented generation technique, searching a corpus for relevant documents and summarizing the results. Either way, the response will only be as accurate and up-to-date as the corpus itself. Insight: When designing an AI application, you need to be aware of non-public information and how to retrieve it. Some of that information can be pulled from databases. Some needs to come from the user, which may require prompt suggestions or explicitly asking. If you understand the types of information and treat human-AI interaction as declarative, you can more easily predict which AI applications will work and which ones won’t. In the next section we’ll look at OpenAI’s Operator and deep research products. Using this framework, we can see where these applications fall short, where they work well, and why. Critiquing OpenAI’s Operator and deep research through a declarative lens I have now explained how thinking of generative AI as declarative helps us understand its strengths and weaknesses. I also identified how different types of information create better or worse human-AI interactions. Now I’ll apply these ideas by critiquing two recent products from OpenAI—Operator and deep research. It’s important to be honest about the shortcomings of AI applications. Bigger models trained on more data or using new techniques might one day solve some issues with generative AI. But other issues arise from the human-AI interaction itself and can only be addressed by making appropriate design and product choices. These critiques demonstrate how the framework can help identify where the limitations are and how to address them. The limitations of Operator Journalist Casey Newton of Platformer reviewed Operator in an article that was largely positive. Newton has covered AI extensively and optimistically. Still, Newton couldn’t help but point out some of Operator’s frustrating limitations. [Operator] can take action on your behalf in ways that are new to AI systems — but at the moment it requires a lot of hand-holding, and may cause you to throw up your hands in frustration.  My most frustrating experience with Operator was my first one: trying to order groceries. “Help me buy groceries on Instacart,” I said, expecting it to ask me some basic questions. Where do I live? What store do I usually buy groceries from? What kinds of groceries do I want?  It didn’t ask me any of that. Instead, Operator opened Instacart in the browser tab and begin searching for milk in grocery stores located in Des Moines, Iowa. The prompt “Help me buy groceries on Instacart,” viewed declaratively, describes groceries being purchased using Instacart. It doesn’t have a lot of the information someone would need to buy groceries, like what exactly to buy, when it would be delivered, and to where. It’s worth repeating: LLMs are not good at knowing when to ask additional questions unless explicitly programmed to do so in the use case. Newton gave a vague request and expected follow-up questions. Instead, the LLM filled in all the missing details with the “average”. The average item was milk. The average location was Des Moines, Iowa. Newton doesn’t mention when it was scheduled to be delivered, but if the “average” delivery time is tomorrow, then that was likely the default. If we engineered this application specifically for ordering groceries, keeping in mind the declarative nature of AI and the information it “knows”, then we could make thoughtful design choices that improve functionality. We would need to prompt the user to specify when and where they want groceries up front (non-public information). With that information, we could find an appropriate grocery store near them. We would need access to that grocery store’s inventory (more non-public information). If we have access to the user’s previous orders, we could also pre-populate a cart with items typical to their order. If not, we may add a few suggested items and guide them to add more. By limiting the use case, we only have to deal with two sources of non-public information. This is a more tractable problem than Operator’s “agent that does it all” approach. Newton also mentions that this process took eight minutes to complete, and “complete” means that Operator did everything up to placing the order. This is a long time with very little human-in-the-loop iteration. Like we said before, an iteration loop is very important for human-AI interaction. A better-designed application would generate smaller steps along the way and provide more frequent interaction. We could prompt the user to describe what to add to their shopping list. The user might say, “Add barbeque sauce to the list,” and see the list update. If they see a vinegar-based barbecue sauce, they can refine that by saying, “Replace that with a barbeque sauce that goes well with chicken,” and might be happier when it’s replaced by a honey barbecue sauce. These frequent iterations make the LLM a creative tool rather than a does-it-all agent. The does-it-all agent looks automagical in marketing, but a more guided approach provides more utility with a less frustrating and more delightful experience. Elsewhere in the article, Newton gives an example of a prompt that Operator performed well: “Put together a lesson plan on the Great Gatsby for high school students, breaking it into readable chunks and then creating assignments and connections tied to the Common Core learning standard.” This prompt describes an output using much more specificity. It also solely relies on general information—the Great Gatsby, the Common Core standard, and a general sense of what assignments are. The general-information use case lends itself better to AI generation, and the prompt is explicit and detailed in its request. In this case, very little guidance was given to create the prompt, so it worked better. (In fact, this prompt comes from Ethan Mollick who has used it to evaluate AI chatbots.) This is the risk of general-purpose AI applications like Operator. The quality of the result relies heavily on the use case and specificity provided by the user. An application with a more specific use case allows for more design guidance and can produce better output more reliably. The limitations of deep research Newton also reviewed deep research, which, according to OpenAI’s website, is an “agent that uses reasoning to synthesize large amounts of online information and complete multi-step research tasks for you.” Deep research came out after Newton’s review of Operator. Newton chose an intentionally tricky prompt that prods at some of the tool’s limitations regarding fresh information and non-general information: “I wanted to see how OpenAI’s agent would perform given that it was researching a story that was less than a day old, and for which much of the coverage was behind paywalls that the agent would not be able to access. And indeed, the bot struggled more than I expected.” Near the end of the article, Newton elaborates on some of the shortcomings he noticed with deep research. OpenAI’s deep research suffers from the same design problem that almost all AI products have: its superpowers are completely invisible and must be harnessed through a frustrating process of trial and error. Generally speaking, the more you already know about something, the more useful I think deep research is. This may be somewhat counterintuitive; perhaps you expected that an AI agent would be well suited to getting you up to speed on an important topic that just landed on your lap at work, for example.  In my early tests, the reverse felt true. Deep research excels for drilling deep into subjects you already have some expertise in, letting you probe for specific pieces of information, types of analysis, or ideas that are new to you. The “frustrating trial and error” shows a mismatch between Newton’s expectations and a necessary aspect of many generative AI applications. A good response requires more information than the user will probably give in the first attempt. The challenge is to design the application and set the user’s expectations so that this interaction is not frustrating but exciting. Newton’s more poignant criticism is that the application requires already knowing something about the topic for it to work well. From the perspective of our framework, this makes sense. The more you know about a topic, the more detail you can provide. And as you iterate, having knowledge about a topic helps you observe and evaluate the output. Without the ability to describe it well or evaluate the results, the user is less likely to use the tool to generate good output. A version of deep research designed for lawyers to perform legal research could be powerful. Lawyers have an extensive and common vocabulary for describing legal matters, and they’re more likely to see a result and know if it makes sense. Generative AI tools are fallible, though. So, the tool should focus on a generation-evaluation loop rather than writing a final draft of a legal document. The article also highlights many improvements compared to Operator. Most notably, the bot asked clarifying questions. This is the most impressive aspect of the tool. Undoubtedly, it helps that deep search has a focused use-case of retrieving and summarizing general information instead of a does-it-all approach. Having a focused use case narrows the set of likely interactions, letting you design better guidance into the prompt flow. Good application design with generative AI Designing effective generative AI applications requires thoughtful consideration of how users interact with the technology, the types of information they need, and the limitations of the underlying models. Here are some key principles to guide the design of generative AI tools: 1. Constrain the input and focus on providing details Applications are inputs and outputs. We want the outputs to be useful and pleasant. By giving a user a conversational chatbot interface, we allow for a vast surface area of potential inputs, making it a challenge to guarantee useful outputs. One strategy is to limit or guide the input to a more manageable subset. For example, FigJam, a collaborative whiteboarding tool, uses pre-set template prompts for timelines, Gantt charts, and other common whiteboard artifacts. This provides some structure and predictability to the inputs. Users still have the freedom to describe further details like color or the content for each timeline event. This approach ensures that the AI has enough specificity to generate meaningful outputs while giving users creative control. 2. Design frequent iteration and evaluation into the tool Iterating in a tight generation-evaluation loop is essential for refining outputs and ensuring they meet user expectations. OpenAI’s Dall-E is great at this. Users quickly iterate on image prompts and refine their descriptions to add additional detail. If you type “a picture of a cheeseburger on a plate”, you may then add more detail by specifying “with pepperjack cheese”. AI code generating tools work well because users can run a generated code snippet immediately to see if it works, enabling rapid iteration and validation. This quick evaluation loop produces better results and a better coder experience.  Designers of generative AI applications should pull the user in the loop early, often, in a way that is engaging rather than frustrating. Designers should also consider the user’s knowledge level. Users with domain expertise can iterate more effectively. Referring back to the FigJam example, the prompts and icons in the app quickly communicate “this is what we call a mind map” or “this is what we call a gantt chart” for users who want to generate these artifacts but don’t know the terms for them. Giving the user some basic vocabulary can help them better generate desired results quickly with less frustration. 3. Be mindful of the types of information needed LLMs excel at tasks involving general knowledge already in the base training set. For example, writing class assignments involves absorbing general information, synthesizing it, and producing a written output, so LLMs are very well-suited for that task. Use cases that require non-general information are more complex. Some questions the designer and engineer should ask include: Does this application require fresh information? Maybe this is knowledge of current events or a user’s current bank account balance. If so, that information needs to be retrieved and incorporated into the model. How much non-general information does the LLM need to know? If it’s a lot of information—like a corpus of company documentation and communication—then the model may need to be fine tuned in batch ahead of time. If the information is relatively small, a retrieval augmented generation (RAG) approach at query time may suffice.  How many sources of non-general information—small and finite or potentially infinite? General purpose agents like Operator face the challenge of potentially infinite non-general information sources. Depending on what the user requires, it could need to access their contacts, restaurant reservation lists, financial data, or even other people’s calendars. A single-purpose restaurant reservation chatbot may only need access to Yelp, OpenTable, and the user’s calendar. It’s much easier to reconcile access and authentication for a handful of known data sources. Is there context-specific information that can only come from the user? Consider our restaurant reservation chatbot. Is the user making reservations for just themselves? Probably not. “How many people and who” is a detail that only the user can provide, an example of non-public information that only the user knows. We shouldn’t expect the user to provide this information upfront and unguided. Instead, we can use prompt suggestions so they include the information. We may even be able to design the LLM to ask these questions when the detail is not provided. 4. Focus on specific use cases Broad, all-purpose chatbots often struggle to deliver consistent results due to the complexity and variability of user needs. Instead, focus on specific use cases where the AI’s shortcomings can be mitigated through thoughtful design. Narrowing the scope helps us address many of the issues above. We can identify common requests for the use case and incorporate those into prompt suggestions. We can design an iteration loop that works well with the type of thing we’re generating. We can identify sources of non-general information and devise solutions to incorporate it into the model or prompt. 5. Translation or summary tasks work well A common task for ChatGPT is to rewrite something in a different style, explain what some computer code is doing, or summarize a long document. These tasks involve converting a set of information from one form to another. We have the same concerns about non-general information and context. For instance, a Chatbot asked to explain a code script doesn’t know the system that script is part of unless that information is provided. But in general, the task of transforming or summarizing information is less prone to missing details. By definition, you have provided the details it needs. The result should have the same information in a different or more condensed form. The exception to the rules There is a case when it doesn’t matter if you break any or all of these rules—when you’re just having fun. LLMs are creative tools by nature. They can be an easel to paint on, a sandbox to build in, a blank sheet to scribe. Iteration is still important; the user wants to see the thing they’re creating as they create it. But unexpected results due to lack of information or omitted details may add to the experience. If you ask for a cheeseburger recipe, you might get some funny or interesting ingredients. If the stakes are low and the process is its own reward, don’t worry about the rules.
ChatGPT launched in 2022 and kicked off the Generative Ai boom. In the two years since, academics, technologists, and armchair experts have written libraries worth of articles on the technical underpinnings of generative AI and about the potential capabilities of both current and future generative AI models.

Surprisingly little has been written about how we interact with these tools—the human-AI interface. The point where we interact with AI models is at least as important as the algorithms and data that create them. “There is no success where there is no possibility of failure, no art without the resistance of the medium” (Raymond Chandler). In that vein, it’s useful to examine human-AI interaction and the strengths and weaknesses inherent in that interaction. If we understand the “resistance in the medium” then product managers can make smarter decisions about how to incorporate generative AI into their products. Executives can make smarter decisions about what capabilities to invest in. Engineers and designers can build around the tools’ limitations and showcase their strengths. Everyday people can know when to use generative AI and when not to.

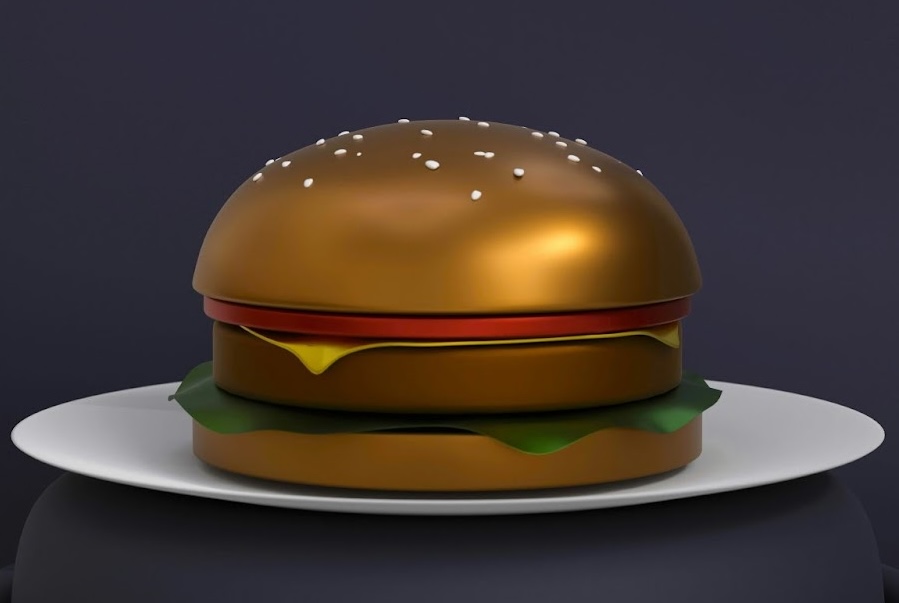
Imagine walking into a restaurant and ordering a cheeseburger. You don’t tell the chef how to grind the beef, how hot to set the grill, or how long to toast the bun. Instead, you simply describe what you want: “I’d like a cheeseburger, medium rare, with lettuce and tomato.” The chef interprets your request, handles the implementation, and delivers the desired outcome. This is the essence of declarative interaction—focusing on the what rather than the how.

Now, imagine interacting with a Large Language Model (LLM) like ChatGPT. You don’t have to provide step-by-step instructions for how to generate a response. Instead, you describe the result you’re looking for: “A user story that lets us implement A/B testing for the Buy button on our website.” The LLM interprets your prompt, fills in the missing details, and delivers a response. Just like ordering a cheeseburger, this is a declarative mode of interaction.

Explaining the steps to make a cheeseburger is an imperative interaction. Our LLM prompts sometimes feel imperative. We might phrase our prompts like a question: ”What is the tallest mountain on earth?” This is equivalent to describing “the answer to the question ‘What is the tallest mountain on earth?’” We might phrase our prompt as a series of instructions: ”Write a summary of the attached report, then read it as if you are a product manager, then type up some feedback on the report.” But, again, we’re describing the result of a process with some context for what that process is. In this case, it is a sequence of descriptive results—the report then the feedback.

This is a more useful way to think about LLMs and generative AI. In some ways it is more accurate; the neural network model behind the curtain doesn’t explain why or how it produced one output instead of another. More importantly though, the limitations and strengths of generative AI make more sense and become more predictable when we think of these models as declarative.

LLMs as a declarative mode of interaction

Computer scientists use the term “declarative” to describe coding languages. SQL is one of the most common. The code describes the output table and the procedures in the database figure out how to retrieve and combine the data to produce the result. LLMs share many of the benefits of declarative languages like SQL or declarative interactions like ordering a cheeseburger.

  1. Focus on desired outcome: Just as you describe the cheeseburger you want, you describe the output you want from the LLM. For example, “Summarize this article in three bullet points” focuses on the result, not the process.
  2. Abstraction of implementation: When you order a cheeseburger, you don’t need to know how the chef prepares it. When submitting SQL code to a server, the server figures out where the data lives, how to fetch it, and how to aggregate it based on your description. You as the user don’t need to know how. With LLMs, you don’t need to know how the model generates the response. The underlying mechanisms are abstracted away.
  3. Filling in missing details: If you don’t specify onions on your cheeseburger, the chef won’t include them. If you don’t specify a field in your SQL code, it won’t show up in the output table. This is where LLMs differ slightly from declarative coding languages like SQL. If you ask ChatGPT to create an image of “a cheeseburger with lettuce and tomato” it may also show the burger on a sesame seed bun or include pickles, even if that wasn’t in your description. The details you omit are inferred by the LLM using the “average” or “most likely” detail depending on the context, with a bit of randomness thrown in. Ask for the cheeseburger image six times; it may show you three burgers with cheddar cheese, two with Swiss, and one with pepper jack.

Like other forms of declarative interaction, LLMs share one key limitation. If your description is vague, ambiguous, or lacks enough detail, then the result may not be what you hoped to see. It is up to the user to describe the result with sufficient detail.

This explains why we often iterate to get what we’re looking for when using LLMs and generative AI. Going back to our cheeseburger analogy, the process to generate a cheeseburger from an LLM may look like this.

  • “Make me a cheeseburger, medium rare, with lettuce and tomatoes.” The result also has pickles and uses cheddar cheese. The bun is toasted. There’s mayo on the top bun.
  • “Make the same thing but this time no pickles, use pepper jack cheese, and a sriracha mayo instead of plain mayo.” The result now has pepper jack, no pickles. The sriracha mayo is applied to the bottom bun and the bun is no longer toasted.
  • “Make the same thing again, but this time, put the sriracha mayo on the top bun. The buns should be toasted.” Finally, you have the cheeseburger you’re looking for.

This example demonstrates one of the main points of friction with human-AI interaction. Human beings are really bad at describing what they want with sufficient detail on the first attempt.

When we asked for a cheeseburger, we had to refine our description to be more specific (the type of cheese). In the second generation, some of the inferred details (whether the bun was toasted) changed from one iteration to the next, so then we had to add that specificity to our description as well. Iteration is an important part of AI-human generation.

Insight: When using generative AI, we need to design an iterative human-AI interaction loop that enables people to discover the details of what they want and refine their descriptions accordingly.

To iterate, we need to evaluate the results. Evaluation is extremely important with generative AI. Say you’re using an LLM to write code. You can evaluate the code quality if you know enough to understand it or if you can execute it and inspect the results. On the other hand, hypothetical questions can’t be tested. Say you ask ChatGPT, “What if we raise our product prices by 5 percent?” A seasoned expert could read the output and know from experience if a recommendation doesn’t take into account important details. If your product is property insurance, then increasing premiums by 5 percent may mean pushback from regulators, something an experienced veteran of the industry would know. For non-experts in a topic, there’s no way to tell if the “average” details inferred by the model make sense for your specific use case. You can’t test and iterate.

Insight: LLMs work best when the user can evaluate the result quickly, whether through execution or through prior knowledge.

The examples so far involve general knowledge. We all know what a cheeseburger is. When you start asking about non-general information—like when you can make dinner reservations next week—you delve into new points of friction.

In the next section we’ll think about different types of information, what we can expect the AI to “know”, and how this impacts human-AI interaction.

What did the AI know, and when did it know it?

Above, I explained how generative AI is a declarative mode of interaction and how that helps understand its strengths and weaknesses. Here, I’ll identify how different types of information create better or worse human-AI interactions.

Understanding the information available

When we describe what we want to an LLM, and when it infers missing details from our description, it draws from different sources of information. Understanding these sources of information is important. Here’s a useful taxonomy for information types:

  • General information used to train the base model.
  • Non-general information that the base model is not aware of.
    • Fresh information that is new or changes rapidly, like stock prices or current events.
    • Non-public information, like facts about you and where you live or about your company, its employees, its processes, or its codebase.

General information vs. non-general information

LLMs are built on a massive corpus of written word data. A large part of GPT-3 was trained on a combination of books, journals, Wikipedia, Reddit, and CommonCrawl (an open-source repository of web crawl data). You can think of the models as a highly compressed version of that data, organized in a gestalt manner—all the like things are close together. When we submit a prompt, the model takes the words we use (and any words added to the prompt behind the scenes) and finds the closest set of related words based on how those things appear in the data corpus. So when we say “cheeseburger” it knows that word is related to “bun” and “tomato” and “lettuce” and “pickles” because they all occur in the same context throughout many data sources. Even when we don’t specify pickles, it uses this gestalt approach to fill in the blanks.

This training information is general information, and a good rule of thumb is this: if it was in Wikipedia a year ago then the LLM “knows” about it. There could be new articles on Wikipedia, but that didn’t exist when the model was trained. The LLM doesn’t know about that unless told.

Now, say you’re a company using an LLM to write a product requirements document for a new web app feature. Your company, like most companies, is full of its own lingo. It has its own lore and history scattered across thousands of Slack messages, emails, documents, and some tenured employees who remember that one meeting in Q1 last year. The LLM doesn’t know any of that. It will infer any missing details from general information. You need to supply everything else. If it wasn’t in Wikipedia a year ago, the LLM doesn’t know about it. The resulting product requirements document may be full of general facts about your industry and product but could lack important details specific to your firm.

This is non-general information. This includes personal info, anything kept behind a log-in or paywall, and non-digital information. This non-general information permeates our lives, and incorporating it is another source of friction when working with generative AI.

Non-general information can be incorporated into a generative AI application in three ways:

  • Through model fine-tuning (supplying a large corpus to the base model to expand its reference data).
  • Retrieved and fed it to the model at query time (e.g., the retrieval augmented generation or “RAG” technique).
  • Supplied by the user in the prompt.

Insight: When designing any human-AI interactions, you should think about what non-general information is required, where you will get it, and how you will expose it to the AI.

Fresh information

Any information that changes in real-time or is new can be called fresh information. This includes new facts like current events but also frequently changing facts like your bank account balance. If the fresh information is available in a database or some searchable source, then it needs to be retrieved and incorporated into the application. To retrieve the information from a database, the LLM must create a query, which may require specific details that the user didn’t include.

Here’s an example. I have a chatbot that gives information on the stock market. You, the user, type the following: “What is the current price of Apple? Has it been increasing or decreasing recently?”

  • The LLM doesn’t have the current price of Apple in its training data. This is fresh, non-general information. So, we need to retrieve it from a database.
  • The LLM can read “Apple”, know that you’re talking about the computer company, and that the ticker symbol is AAPL. This is all general information.
  • What about the “increasing or decreasing” part of the prompt? You did not specify over what period—increasing in the past day, month, year? In order to construct a database query, we need more detail. LLMs are bad at knowing when to ask for detail and when to fill it in. The application could easily pull the wrong data and provide an unexpected or inaccurate answer. Only you know what these details should be, depending on your intent. You must be more specific in your prompt.

A designer of this LLM application can improve the user experience by specifying required parameters for expected queries. We can ask the user to explicitly input the time range or design the chatbot to ask for more specific details if not provided. In either case, we need to have a specific type of query in mind and explicitly design how to handle it. The LLM will not know how to do this unassisted.

Insight: If a user is expecting a more specific type of output, you need to explicitly ask for enough detail. Too little detail could produce a poor quality output.

Non-public information

Incorporating non-public information into an LLM prompt can be done if that information can be accessed in a database. This introduces privacy issues (should the LLM be able to access my medical records?) and complexity when incorporating multiple non-public sources of information.

Let’s say I have a chatbot that helps you make dinner reservations. You, the user, type the following: “Help me make dinner reservations somewhere with good Neapolitan pizza.”

  • The LLM knows what a Neapolitan pizza is and can infer that “dinner” means this is for an evening meal.
  • To do this task well, it needs information about your location, the restaurants near you and their booking status, or even personal details like dietary restrictions. Assuming all that non-public information is available in databases, bringing them all together into the prompt takes a lot of engineering work.
  • Even if the LLM could find the “best” restaurant for you and book the reservation, can you be confident it has done that correctly? You never specified how many people you need a reservation for. Since only you know this information, the application needs to ask for it upfront.

If you’re designing this LLM-based application, you can make some thoughtful choices to help with these problems. We could ask about a user’s dietary restrictions when they sign up for the app. Other information, like the user’s schedule that evening, can be given in a prompting tip or by showing the default prompt option “show me reservations for two for tomorrow at 7PM”. Promoting tips may not feel as automagical as a bot that does it all, but they are a straightforward way to collect and integrate the non-public information.

Some non-public information is large and can’t be quickly collected and processed when the prompt is given. These need to be fine-tuned in batch or retrieved at prompt time and incorporated. A chatbot that answers information about a company’s HR policies can obtain this information from a corpus of non-public HR documents. You can fine-tune the model ahead of time by feeding it the corpus. Or you can implement a retrieval augmented generation technique, searching a corpus for relevant documents and summarizing the results. Either way, the response will only be as accurate and up-to-date as the corpus itself.

Insight: When designing an AI application, you need to be aware of non-public information and how to retrieve it. Some of that information can be pulled from databases. Some needs to come from the user, which may require prompt suggestions or explicitly asking.

If you understand the types of information and treat human-AI interaction as declarative, you can more easily predict which AI applications will work and which ones won’t. In the next section we’ll look at OpenAI’s Operator and deep research products. Using this framework, we can see where these applications fall short, where they work well, and why.

Critiquing OpenAI’s Operator and deep research through a declarative lens

I have now explained how thinking of generative AI as declarative helps us understand its strengths and weaknesses. I also identified how different types of information create better or worse human-AI interactions.

Now I’ll apply these ideas by critiquing two recent products from OpenAI—Operator and deep research. It’s important to be honest about the shortcomings of AI applications. Bigger models trained on more data or using new techniques might one day solve some issues with generative AI. But other issues arise from the human-AI interaction itself and can only be addressed by making appropriate design and product choices.

These critiques demonstrate how the framework can help identify where the limitations are and how to address them.

The limitations of Operator

Journalist Casey Newton of Platformer reviewed Operator in an article that was largely positive. Newton has covered AI extensively and optimistically. Still, Newton couldn’t help but point out some of Operator’s frustrating limitations.

[Operator] can take action on your behalf in ways that are new to AI systems — but at the moment it requires a lot of hand-holding, and may cause you to throw up your hands in frustration. 

My most frustrating experience with Operator was my first one: trying to order groceries. “Help me buy groceries on Instacart,” I said, expecting it to ask me some basic questions. Where do I live? What store do I usually buy groceries from? What kinds of groceries do I want? 

It didn’t ask me any of that. Instead, Operator opened Instacart in the browser tab and begin searching for milk in grocery stores located in Des Moines, Iowa.

The prompt “Help me buy groceries on Instacart,” viewed declaratively, describes groceries being purchased using Instacart. It doesn’t have a lot of the information someone would need to buy groceries, like what exactly to buy, when it would be delivered, and to where.

It’s worth repeating: LLMs are not good at knowing when to ask additional questions unless explicitly programmed to do so in the use case. Newton gave a vague request and expected follow-up questions. Instead, the LLM filled in all the missing details with the “average”. The average item was milk. The average location was Des Moines, Iowa. Newton doesn’t mention when it was scheduled to be delivered, but if the “average” delivery time is tomorrow, then that was likely the default.

If we engineered this application specifically for ordering groceries, keeping in mind the declarative nature of AI and the information it “knows”, then we could make thoughtful design choices that improve functionality. We would need to prompt the user to specify when and where they want groceries up front (non-public information). With that information, we could find an appropriate grocery store near them. We would need access to that grocery store’s inventory (more non-public information). If we have access to the user’s previous orders, we could also pre-populate a cart with items typical to their order. If not, we may add a few suggested items and guide them to add more. By limiting the use case, we only have to deal with two sources of non-public information. This is a more tractable problem than Operator’s “agent that does it all” approach.

Newton also mentions that this process took eight minutes to complete, and “complete” means that Operator did everything up to placing the order. This is a long time with very little human-in-the-loop iteration. Like we said before, an iteration loop is very important for human-AI interaction. A better-designed application would generate smaller steps along the way and provide more frequent interaction. We could prompt the user to describe what to add to their shopping list. The user might say, “Add barbeque sauce to the list,” and see the list update. If they see a vinegar-based barbecue sauce, they can refine that by saying, “Replace that with a barbeque sauce that goes well with chicken,” and might be happier when it’s replaced by a honey barbecue sauce. These frequent iterations make the LLM a creative tool rather than a does-it-all agent. The does-it-all agent looks automagical in marketing, but a more guided approach provides more utility with a less frustrating and more delightful experience.

Elsewhere in the article, Newton gives an example of a prompt that Operator performed well: “Put together a lesson plan on the Great Gatsby for high school students, breaking it into readable chunks and then creating assignments and connections tied to the Common Core learning standard.” This prompt describes an output using much more specificity. It also solely relies on general information—the Great Gatsby, the Common Core standard, and a general sense of what assignments are. The general-information use case lends itself better to AI generation, and the prompt is explicit and detailed in its request. In this case, very little guidance was given to create the prompt, so it worked better. (In fact, this prompt comes from Ethan Mollick who has used it to evaluate AI chatbots.)

This is the risk of general-purpose AI applications like Operator. The quality of the result relies heavily on the use case and specificity provided by the user. An application with a more specific use case allows for more design guidance and can produce better output more reliably.

The limitations of deep research

Newton also reviewed deep research, which, according to OpenAI’s website, is an “agent that uses reasoning to synthesize large amounts of online information and complete multi-step research tasks for you.”

Deep research came out after Newton’s review of Operator. Newton chose an intentionally tricky prompt that prods at some of the tool’s limitations regarding fresh information and non-general information: “I wanted to see how OpenAI’s agent would perform given that it was researching a story that was less than a day old, and for which much of the coverage was behind paywalls that the agent would not be able to access. And indeed, the bot struggled more than I expected.”

Near the end of the article, Newton elaborates on some of the shortcomings he noticed with deep research.

OpenAI’s deep research suffers from the same design problem that almost all AI products have: its superpowers are completely invisible and must be harnessed through a frustrating process of trial and error.

Generally speaking, the more you already know about something, the more useful I think deep research is. This may be somewhat counterintuitive; perhaps you expected that an AI agent would be well suited to getting you up to speed on an important topic that just landed on your lap at work, for example. 

In my early tests, the reverse felt true. Deep research excels for drilling deep into subjects you already have some expertise in, letting you probe for specific pieces of information, types of analysis, or ideas that are new to you.

The “frustrating trial and error” shows a mismatch between Newton’s expectations and a necessary aspect of many generative AI applications. A good response requires more information than the user will probably give in the first attempt. The challenge is to design the application and set the user’s expectations so that this interaction is not frustrating but exciting.

Newton’s more poignant criticism is that the application requires already knowing something about the topic for it to work well. From the perspective of our framework, this makes sense. The more you know about a topic, the more detail you can provide. And as you iterate, having knowledge about a topic helps you observe and evaluate the output. Without the ability to describe it well or evaluate the results, the user is less likely to use the tool to generate good output.

A version of deep research designed for lawyers to perform legal research could be powerful. Lawyers have an extensive and common vocabulary for describing legal matters, and they’re more likely to see a result and know if it makes sense. Generative AI tools are fallible, though. So, the tool should focus on a generation-evaluation loop rather than writing a final draft of a legal document.

The article also highlights many improvements compared to Operator. Most notably, the bot asked clarifying questions. This is the most impressive aspect of the tool. Undoubtedly, it helps that deep search has a focused use-case of retrieving and summarizing general information instead of a does-it-all approach. Having a focused use case narrows the set of likely interactions, letting you design better guidance into the prompt flow.

Good application design with generative AI

Designing effective generative AI applications requires thoughtful consideration of how users interact with the technology, the types of information they need, and the limitations of the underlying models. Here are some key principles to guide the design of generative AI tools:

1. Constrain the input and focus on providing details

Applications are inputs and outputs. We want the outputs to be useful and pleasant. By giving a user a conversational chatbot interface, we allow for a vast surface area of potential inputs, making it a challenge to guarantee useful outputs. One strategy is to limit or guide the input to a more manageable subset.

For example, FigJam, a collaborative whiteboarding tool, uses pre-set template prompts for timelines, Gantt charts, and other common whiteboard artifacts. This provides some structure and predictability to the inputs. Users still have the freedom to describe further details like color or the content for each timeline event. This approach ensures that the AI has enough specificity to generate meaningful outputs while giving users creative control.

2. Design frequent iteration and evaluation into the tool

Iterating in a tight generation-evaluation loop is essential for refining outputs and ensuring they meet user expectations. OpenAI’s Dall-E is great at this. Users quickly iterate on image prompts and refine their descriptions to add additional detail. If you type “a picture of a cheeseburger on a plate”, you may then add more detail by specifying “with pepperjack cheese”.

AI code generating tools work well because users can run a generated code snippet immediately to see if it works, enabling rapid iteration and validation. This quick evaluation loop produces better results and a better coder experience. 

Designers of generative AI applications should pull the user in the loop early, often, in a way that is engaging rather than frustrating. Designers should also consider the user’s knowledge level. Users with domain expertise can iterate more effectively.

Referring back to the FigJam example, the prompts and icons in the app quickly communicate “this is what we call a mind map” or “this is what we call a gantt chart” for users who want to generate these artifacts but don’t know the terms for them. Giving the user some basic vocabulary can help them better generate desired results quickly with less frustration.

3. Be mindful of the types of information needed

LLMs excel at tasks involving general knowledge already in the base training set. For example, writing class assignments involves absorbing general information, synthesizing it, and producing a written output, so LLMs are very well-suited for that task.

Use cases that require non-general information are more complex. Some questions the designer and engineer should ask include:

  • Does this application require fresh information? Maybe this is knowledge of current events or a user’s current bank account balance. If so, that information needs to be retrieved and incorporated into the model.
  • How much non-general information does the LLM need to know? If it’s a lot of information—like a corpus of company documentation and communication—then the model may need to be fine tuned in batch ahead of time. If the information is relatively small, a retrieval augmented generation (RAG) approach at query time may suffice. 
  • How many sources of non-general information—small and finite or potentially infinite? General purpose agents like Operator face the challenge of potentially infinite non-general information sources. Depending on what the user requires, it could need to access their contacts, restaurant reservation lists, financial data, or even other people’s calendars. A single-purpose restaurant reservation chatbot may only need access to Yelp, OpenTable, and the user’s calendar. It’s much easier to reconcile access and authentication for a handful of known data sources.
  • Is there context-specific information that can only come from the user? Consider our restaurant reservation chatbot. Is the user making reservations for just themselves? Probably not. “How many people and who” is a detail that only the user can provide, an example of non-public information that only the user knows. We shouldn’t expect the user to provide this information upfront and unguided. Instead, we can use prompt suggestions so they include the information. We may even be able to design the LLM to ask these questions when the detail is not provided.

4. Focus on specific use cases

Broad, all-purpose chatbots often struggle to deliver consistent results due to the complexity and variability of user needs. Instead, focus on specific use cases where the AI’s shortcomings can be mitigated through thoughtful design.

Narrowing the scope helps us address many of the issues above.

  • We can identify common requests for the use case and incorporate those into prompt suggestions.
  • We can design an iteration loop that works well with the type of thing we’re generating.
  • We can identify sources of non-general information and devise solutions to incorporate it into the model or prompt.

5. Translation or summary tasks work well

A common task for ChatGPT is to rewrite something in a different style, explain what some computer code is doing, or summarize a long document. These tasks involve converting a set of information from one form to another.

We have the same concerns about non-general information and context. For instance, a Chatbot asked to explain a code script doesn’t know the system that script is part of unless that information is provided.

But in general, the task of transforming or summarizing information is less prone to missing details. By definition, you have provided the details it needs. The result should have the same information in a different or more condensed form.

The exception to the rules

There is a case when it doesn’t matter if you break any or all of these rules—when you’re just having fun. LLMs are creative tools by nature. They can be an easel to paint on, a sandbox to build in, a blank sheet to scribe. Iteration is still important; the user wants to see the thing they’re creating as they create it. But unexpected results due to lack of information or omitted details may add to the experience. If you ask for a cheeseburger recipe, you might get some funny or interesting ingredients. If the stakes are low and the process is its own reward, don’t worry about the rules.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

What’s next for Nvidia?

That’s if he wants it. One industry watcher told this reporter that several years ago, he asked several Nvidia vice presidents if they wanted the big chair, because Nvidia had no clear successor to Huang and to a man they said no way. “I can’t and don’t want to do

Read More »

AMD takes on Intel and Nvidia with new 256-core EPYC server CPUs

AMD EPYC, Intel Xeon, and Nvidia Vera represent three different approaches to the evolving data-centre CPU market, added Rawat. “AMD competes through high core density, memory capabilities and power efficiency, while Intel leverages its established enterprise ecosystem, platform compatibility and customer relationships. Nvidia is taking a different approach with Vera,

Read More »

Kosmos lets contract to advance Tiberius project offshore Louisiana

Kosmos Energy Gulf of Mexico Operations LLC, a unit of Kosmos Energy, has let a contract to Subsea 7 SA for work on the Tiberius project in the US Gulf of Mexico. The scope of work covers the fabrication, transportation, and installation of a 14-km steel catenary riser and wet-insulated flowline to the Lucius Spar, along with the installation of an umbilical and subsea controls. The Tiberius project lies in Keathley Canyon lease 964 about 400 km south of New Orleans in about 2,283 m of water.  License partners reached a final investment decision on the Phase 1A development this year, which includes completion of an already drilled well. Long-lead items have been secured, and first oil is expected by the end of third-quarter 2028.  Subsea 7, which values the contract at $50-150 million, expects project management and engineering activities to begin in the coming months, with offshore activities expected to begin in 2028. Kosmos is operator of the Tiberius project with a 33.34% interest following a farmout alongside partner Occidental Petroleum to Navitas Petroleum US LLC earlier this year.

Read More »

ExxonMobil takes FID for Longtail development offshore Guyana

The development, in the southeastern portion of the block, will target non-associated gas and condensate-rich reservoirs. Subject to future investment decisions, market demand, and development of supporting infrastructure, gas from the project could be transported to shore by pipeline. The development will use a floating production, storage, and offloading (FPSO) vessel designed to process 1.2 bcfd of gas and produce as much as 250,000 b/d of condensate. The project is expected to include about 45 subsea production and injection wells. “By developing these gas and condensate resources, we’re unlocking new value for Guyana while delivering advantaged energy to meet growing global demand,” said Dan Ammann, president, ExxonMobil Upstream Company. ExxonMobil currently produces about 900,000 b/d of oil from four developments in the Stabroek block. Its fifth project, Uaru, is expected to start up in fourth-quarter 2026, increasing total block production capacity to more than 1 million b/d. Earlier this year, the operator and co-venturers produced the 1 billionth bbl of oil from Guyana’s Stabroek block, less than 7 years after first production began in December 2019 with Liza field. Construction also continues on the Whiptail and Hammerhead developments, the sixth and seventh approved projects on the block. Whiptail is slated to start production in 2027, followed by Hammerhead in 2029. ExxonMobil Guyana Ltd. operates the Stabroek block with a 45% interest. Hess Guyana Exploration Ltd. holds 30%, and CNOOC Petroleum Guyana Ltd. holds 25%.

Read More »

MARAD approves Energy Transfer’s $1-billion Blue Marlin crude oil export port

The US Maritime Administration (MARAD) approved Energy Transfer’s $1-billion Blue Marlin offshore crude oil export project off Louisiana Nov. 5, marking the fourth oil and gas deepwater port approval under President Donald Trump’s second administration. The proposed Blue Marlin port would have capacity to export up to 2 million b/d of crude oil, with loading rates of up to 80,000 bbl/hr, including onto very large crude carriers (VLCCs). Located 99 miles off Cameron Parish, La., the project includes conversion of an existing 36-in. Stingray natural gas pipeline to transport crude oil from Energy Transfer’s Nederland terminal in Texas to the offshore infrastructure. The US Federal Energy Regulatory Commission previously authorized abandonment and sale of Stingray pipeline infrastructure for conversion to crude oil service. Energy Transfer has yet to receive final US Environmental Protection Agency air permits and certain state approvals. The project’s commercial development schedule remains uncertain. MARAD approved Blue Marlin shortly after its Oct. 28 approval of the $8.2-billion ST LNG project offshore Texas, as the agency pursues new procedures to streamline deepwater port licensing. The Trump administration also has approved Delfin LNG, a floating LNG export project offshore Louisiana, and Texas GulfLink, a crude oil export project offshore Texas.

Read More »

IEA sees oil market surplus returning as Gulf exports recover

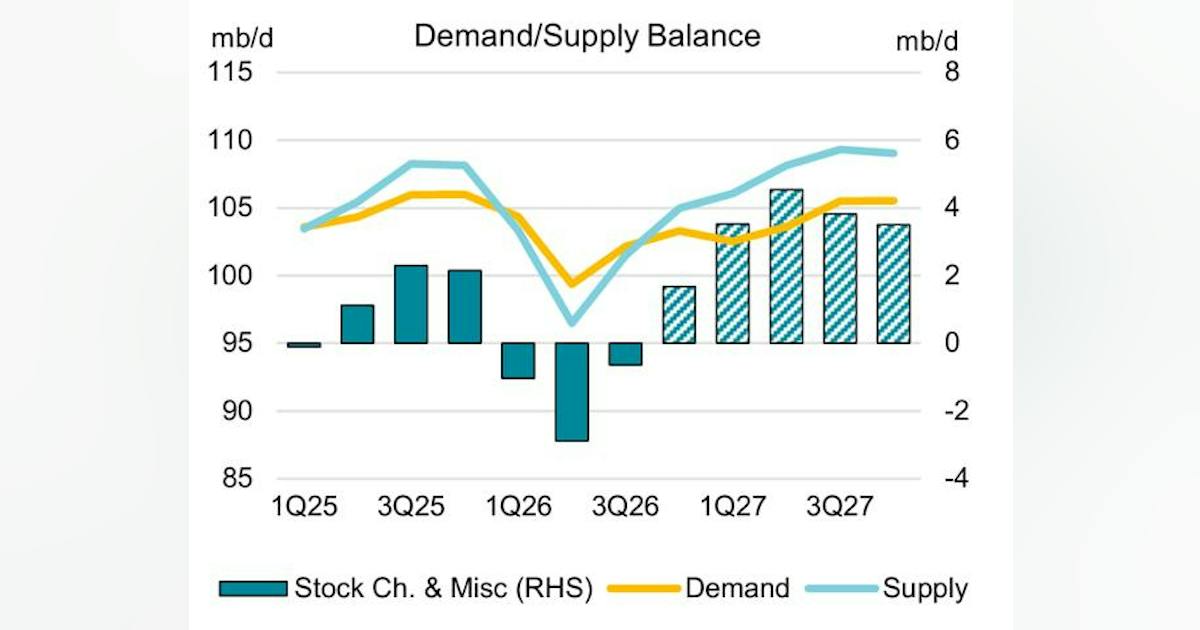
The global oil market is showing signs of rebalancing as recovering crude exports from the Middle East lift supply, although persistent disruptions to refined product markets, particularly diesel, continue to weigh on consumers, the International Energy Agency (IEA) said. In its Nov. 13 Oil Market Report, IEA said global oil supply increased 2.3 million b/d month-on-month to 105.4 million b/d in October, following a 3 million-b/d increase in September. Output has risen 5.3 million b/d since August as Gulf exports recovered despite continued attacks on energy infrastructure and commercial tankers. The stronger supply outlook has prompted the agency to raise its fourth-quarter 2026 supply estimate by 3.3 million b/d. Global supply is now expected to decline by an average 4.8 million b/d for the full year before rebounding by 6.6 million b/d in 2027 to average 108.1 million b/d. The recovery in exports has eased market tightness and pushed crude prices lower. North Sea Dated crude fell 32% from an early-October high of $136/bbl to about $93/bbl at the time of the report, although prices remained $22/bbl above prewar levels. Gulf oil exports, excluding Oman, reached 18.4 million b/d in October, about 26% below prewar levels. Crude exports accounted for most of the recovery, reaching 15 million b/d, equivalent to 82% of prewar volumes. However, IEA cautioned that continued attacks on shipping remain a significant downside risk to the supply outlook. Demand under pressure Global oil demand is forecast to decline by 2.7 million b/d in 2026 to 102.3 million b/d, reflecting disruptions to refined product and liquefied petroleum gas exports from the Gulf, elevated fuel prices, and weaker consumption across major markets. The contraction is expected to moderate in fourth-quarter 2026 to 2.7 million b/d year-on-year, compared with an average decline of 4.4 million b/d in the second and

Read More »

What’s next for California’s climate laws following an appeals court split decision

The Ninth Circuit Court of Appeals issued a split decision on California’s climate disclosure laws, Senate Bill 253 and Senate Bill 261, on Monday, allowing some emissions reporting requirements to proceed, while blocking others on the basis of them being considered in part or completely unconstitutional under the First Amendment. In the decision, the federal appellate panel partially upheld and partially overturned a district court’s decision from August 2025, which declined to enjoin the laws. The U.S. Chamber of Commerce and other business associations filed the lawsuit, requesting to temporarily block implementation of both climate laws while their constitutionality was under review. Implementation of SB 261 was already temporarily halted pending review by the Ninth Circuit last November.  SB 253, or the Climate Corporate Data Accountability Act, requires companies with more than $1 billion in revenue to report scope 1 and scope 2 emissions, with eventual scope 3 disclosures. SB 261, or the Climate-Related Financial Risk Act, requires companies with more than $500 million in revenue to publicly disclose their climate-related financial risks and countermeasures. Both climate disclosure regulations were signed into law in October 2023 by California Gov. Gavin Newsom and have since faced a spate of legal challenges. The ruling came a day before the inaugural emissions disclosure deadline for SB 253. Breaking down the split decision The Nov. 9 decision allowed for the reporting of a company’s direct emissions to proceed under SB 253’s scope 1 and scope 2 disclosure requirements, affirming the lower court’s decision. The court ruled such disclosures “regulate commercial speech,” which the appellate panel defined as factual and objective information on a company’s own operations. However, the appeals court reversed the lower court’s ruling when it came to SB 253’s scope 3 disclosure requirements, which ask companies to report the indirect emissions generated

Read More »

Repsol to add renewable hydrogen at Tarragona refining complex

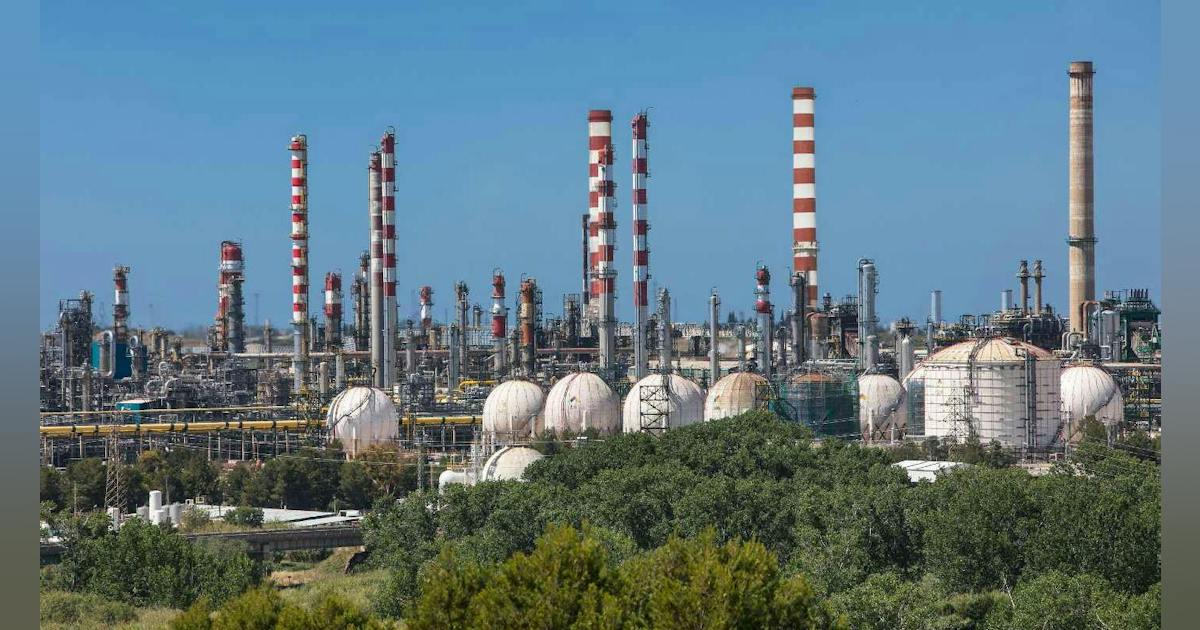
Repsol SA’s board has approved a project to install a 150-Mw renewable hydrogen electrolyzer for production of renewable hydrogen at the operator’s 190,000-b/d Tarragona integrated refining and petrochemicals industrial complex along northeastern Spain’s Costa Daurada of the Mediterranean Sea. To be developed with partner Enagás Renovable SA (25%), the green hydrogen project will require an investment of about €400 million and enable production of more than 22,000 tonnes/year (tpy) of renewable hydrogen, Respol said in a release Nov. 12. Repsol, which will operate and hold a 75% stake in the new plant, confirmed hydrogen produced by the project would be used to support Tarragona’s refining and production processes, as well as for production of chemical products. A portion of the hydrogen additionally would serve as feedstock for production of renewable methanol at the operator’s co-located Ecoplanta operations that, by 2029, will process up to 400,000 tpy municipal solid waste into 240,000 tpy renewable fuels and other circular products. The electrolyzer also could supply renewable hydrogen to the local natural gas network and Spain’s planned Hydrogen Backbone network in the future, Repsol said. Once operable, the company estimates the renewable hydrogen plant would enable the Tarragona site to avoid up to 250,000 tpy of carbon dioxide (CO2) emissions. The project has already been selected to receive up to €104 million under Spain’s regional Hydrogen Valley initiative—a public-private effort to develop a local hydrogen ecosystem—promoted by the Ministry for the Ecological Transition and the Demographic Challenge and funded through Spain’s Recovery, Transformation, and Resilience Plan with NextGenerationEU funds. Now in the engineering phase, Repsol said the plant’s electrolyzer will use recovered industrial water as well as incorporate technology designed to maximize energy efficiency of the production process as part of the operator’s broader ongoing strategy to further reduce environmental impacts of its global

Read More »

Cisco forecasts $9 billion in AI infrastructure revenue in FY27

Cisco continues to benefit from a “networking supercycle,” reporting record revenue—driven by demand for AI infrastructure, security, and campus refreshes from hyperscalers and enterprise customers—for its fiscal first quarter ended October 24. “In Q1, we delivered record quarterly revenue of $18.5 billion, up 24% year over year, and record non-GAAP earnings per share of $1.40, up 40% year over year. These are our strongest top andbottom-line growth rates in over 15 years,” Cisco CEO Chuck Robbins said on the vendor’s quarterly financial call. “Networking product orders grew 28% in Q1, delivering our ninth consecutive quarter of double-digit growth. In fact, we saw double-digit growth across every product family: service provider routing, compute, enterprise routing, wireless, data center switching and campus switching,” Robbins said. “These broad-based results support our view that we are in the early stages of a multiyear, multibillion-dollar networking supercycle.”

Read More »

How TI’s ADC34DSO75 Catches the Nanosecond Power Glitches Behind AI Data Center Downtime

Today’s advanced AI data center can be viewed as a vast, complex and interdependent digital organism in which a virtually infinite number of components must be tracked all the time, in real time. It’s a monitoring job of staggering proportions. At stake is the operation of highly critical workloads and the maintenance of return on investment for high-cost compute equipment. At risk is sub-optimal performance or, in worst-case scenarios, the nightmare of data center downtime. Sponsored Resources: Why traditional telemetry misses nanosecond power-rail events Telemetry has long been relied upon to monitor data center servers, test and measurement equipment, wireless infrastructure and other systems for real-time information about voltage, current, power, temperature and overall system health. But most systems operate at millisecond-level intervals or slower, which is six orders of magnitude longer than the transient events that now occur at the processor power rails and the tools meant to observe them. The requirements and high stakes of today’s AI data centers and workloads have called for a new generation of advanced, nanosecond-level telemetry gear. Texas Instruments has established a leadership position in this sector. The company has developed the first analog-to-digital converter (ADC) to enable 24/7, low-power, event-based remote monitoring at nanosecond resolution. Let’s unpack this statement and examine why TI’s new monitoring technology is so important for the data center industry. What is the TI ADC34DSO75?    We’re talking specifically about TI’s ADC34DSO75, the industry’s highest-performance, 3 gigasamples per second (GSPS) ADC, delivering thousands of times faster performance than current offerings. Launched at the Open Compute Project Global Summit conference in October, the ADC34DSO75 addresses the shortcomings of existing monitoring solutions that can’t detect the nanosecond-level power-rail glitches that cause costly data center downtime. The ADC34DSO75 combines ultra-high-speed sampling with advanced on-chip digital signal processing in a small form factor,

Read More »

SC26 Preview: AI-HPC Convergence Takes Center Stage in Chicago

As the high-performance computing community prepares to gather in Chicago for SC26, November 15–20, the latest episode of the Data Center Frontier Show offers a timely preview of the technologies, market developments, and infrastructure challenges expected to shape this year’s conference. Hosted by DCF Contributing Editor Doug Black, the conversation brings together Lois McKinnis, Argonne Distinguished Fellow and senior computational scientist at Argonne National Laboratory; Addison Snell, founder and CEO of Intersect 360 Research; and Earl Joseph, CEO of Hyperion Research. The episode also inaugurates Data Center Frontier’s new Frontier Computing channel, expanding DCF’s coverage of the technologies and infrastructure driving the convergence of high-performance computing, AI, QC and next-generation scientific discovery. The central theme is unmistakable. AI is no longer simply an adjunct to traditional supercomputing. It is changing how scientific computing itself is performed. “We’re really moving beyond focusing just on bigger machines, faster machines,” McKinnis observes, pointing to the growing integration of AI into scientific software development, simulations, and research workflows. Joseph underscores the acceleration, citing new Hyperion research finding that 70% of respondents are already using AI for code generation. The panel also examines the U.S. Department of Energy’s Genesis Mission, a sweeping effort to link supercomputers, large-scale AI infrastructure, and cloud resources in support of scientific discovery. Joseph calls Genesis “the first time I’ve ever seen something that’s truly a broad national resource,” while Snell emphasizes that investments in AI infrastructure must be matched by investments in science itself. For data center professionals, the discussion turns to increasingly consequential questions about the economics and sustainability of the AI buildout. Snell warns that the industry’s focus on rapid construction has outpaced serious discussion of infrastructure lifecycles and upgrades. Joseph highlights the mounting difficulty of financing supercomputers costing $100 million or more when new GPU generations arrive

Read More »

Nvidia’s leadership crisis puts enterprise AI’s dependence on one company under scrutiny

“More broadly, it throws into doubt the company’s leadership and security practices, and ignites questions around board-level governance and oversight,” he said. The ‘default choice’ in the market Huang founded Nvidia in 1993, initially targeting the gaming market. But the company pivoted in recent years to meet the intensive compute demands of AI. Its advanced GPUs not only excel at rendering graphics, but can handle an enormous number of simultaneous computations, making them a natural fit for neural networks and LLMs. The company began focusing more on developing chips and architecture for AI tools and data centers, and has continued to ink new deals and establish partnerships with tech companies serving nearly every level of the stack, including Anthropic, Meta, Dell, HPE, Microsoft, AWS, Google Cloud, Accenture, Marvell Technology, Hugging Face and many others.

Read More »

Jensen Huang Resigns as NVIDIA CEO, Sending Shockwaves Through AI Data Center Industry

NVIDIA co-founder Jensen Huang resigned Thursday morning (November 12) as president, CEO and board member of the world’s dominant AI chipmaker, a stunning leadership change that introduces new uncertainty into the global artificial intelligence infrastructure boom. In an official announcement, NVIDIA confirmed that Chief Financial Officer Colette Kress will serve as interim CEO while the board conducts a search for Huang’s permanent successor. The company also appointed longtime director Harvey C. Jones as its first board chairman. The departure ends Huang’s 33-year leadership of the company he co-founded in 1993 and comes amid a rapidly escalating controversy involving his reported personal relationships, potential Chinese intelligence activity and questions about corporate governance. According to Reuters, NVIDIA shares fell more than 10% in premarket trading Thursday as investors weighed the implications for the approximately $4 trillion company and the wider AI technology sector. The company’s announcement did not specify a reason for Huang’s resignation. National Security Investigation Precedes Leadership Change The leadership shakeup follows several days of increasing scrutiny over Huang’s reported relationship with a businesswoman whom U.S. authorities suspect of connections to Chinese intelligence, alongside separate reporting concerning a relationship with a senior NVIDIA executive. On November 8, NVIDIA’s board announced an independent investigation into whether Huang had been targeted by a foreign intelligence operation. At the time, directors stated that they had no reason to believe company secrets or national security had been compromised. The controversy subsequently attracted congressional attention, including calls for Huang’s resignation and questions about semiconductor export controls and the security of advanced AI technology. The espionage allegations remain contested, and no compromise of NVIDIA technology has been publicly established. For the data center industry, however, the immediate question extends beyond the circumstances of Huang’s departure. It concerns the potential disruption of an infrastructure ecosystem increasingly organized

Read More »

Google’s Utah Deal Puts Geothermal Power on the Data Center Map

In Taiwan, the Work Begins With Access to Land Google’s first geothermal procurement agreements in Asia call for an initial 10 MW of new generation on Taiwan’s grid to support local data centers and offices. When Google and developer Baseload Capital announced the agreements in April 2025, a Google energy executive told Taiwan Public Television Service that the companies expected operations to begin in 2029. The original timetable allowed roughly four years between signing a customer and delivering electricity. Baseload’s development work in Hualien County illustrates one reason such projects take time. In November 2025, the company reported that members of the Hongye Tribe had voted to approve a public-land lease for geothermal exploration. Baseload opened a local office, reached an agreement with the community, and secured an exploration permit for a two-year program of drilling in stages. The company has described Hongye separately from Google’s contracted supply. What the Hualien project documents is an early milestone rarely visible in a power purchase announcement: the developer secured community consent before drilling could establish what the field might produce. Kenya Has the Generating Field. The Campus Remains Unresolved. In Kenya’s Rift Valley, the appeal of Olkaria was evident when Microsoft and G42 announced their digital investment initiative in 2024. Kenya already had a fleet of geothermal generating stations at Olkaria. G42 and local partners proposed building a campus there, powered by geothermal electricity and hosting Microsoft Azure services for a new East Africa cloud region. Two difficulties emerged. In May 2026, Semafor reported that President William Ruto had cited insufficient available power as an obstacle to the project. Separately, Reuters, citing Bloomberg, reported disagreements over payment guarantees. Microsoft and G42 had sought a commitment from the Kenyan government to buy a certain amount of computing capacity annually. Kenya’s principal secretary for

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »