Stay Ahead, Stay ONMINE

Deep Data Center: Neoclouds as the ‘Picks and Shovels’ of the AI Gold Rush

In 1849, the discovery of gold in California ignited a frenzy, drawing prospectors from around the world in pursuit of quick fortune. While few struck it rich digging and sifting dirt, a different class of entrepreneurs quietly prospered: those who supplied the miners with the tools of the trade. From picks and shovels to tents […]

In 1849, the discovery of gold in California ignited a frenzy, drawing prospectors from around the world in pursuit of quick fortune. While few struck it rich digging and sifting dirt, a different class of entrepreneurs quietly prospered: those who supplied the miners with the tools of the trade. From picks and shovels to tents and provisions, these providers became indispensable to the gold rush, profiting handsomely regardless of who found gold.

Today, a new gold rush is underway, in pursuit of artificial intelligence. And just like the days of yore, the real fortunes may lie not in the gold itself, but in the infrastructure and equipment that enable its extraction. This is where neocloud players and chipmakers are positioned, representing themselves as the fundamental enablers of the AI revolution.

Neoclouds: The Essential Tools and Implements of AI Innovation

The AI boom has sparked a frenzy of innovation, investment, and competition. From generative AI applications like ChatGPT to autonomous systems and personalized recommendations, AI is rapidly transforming industries. Yet, behind every groundbreaking AI model lies an unsung hero: the infrastructure powering it. Enter neocloud providers—the specialized cloud platforms delivering the GPU horsepower that fuels AI’s meteoric rise. Let’s examine how neoclouds represent the “picks and shovels” of the AI gold rush, used for extracting the essential backbone of AI innovation.

Neoclouds are emerging as indispensable players in the AI ecosystem, offering tailored solutions for compute-intensive workloads such as training large language models (LLMs) and performing high-speed inference. Unlike traditional hyperscalers (e.g., AWS, Azure, Google Cloud), which cater to a broad range of use cases, neoclouds focus exclusively on optimizing infrastructure for AI and machine learning applications. This specialization allows them to deliver superior performance at a lower cost, making them the go-to choice for startups, enterprises, and research institutions alike.

The analogy to historical gold rushes is striking: just as miners relied on suppliers of picks and shovels to extract value from the earth, today’s AI pioneers depend on neocloud providers and chipmakers to access the computational resources needed to unlock insights and drive innovation. Neoclouds don’t compete in creating AI applications themselves; instead, they profit by enabling others to do so. This business model positions them as foundational players in the AI economy—profiting regardless of which companies or applications ultimately dominate the market.

Why Neoclouds Are Surging: Four Key Advantages

As AI development accelerates, the demand for compute is outpacing even the hyperscale cloud’s capacity to deliver. Training a foundation model like GPT-4 can require tens of thousands of GPUs running continuously for weeks—something traditional providers weren’t architected to support at scale. Enter the neoclouds: leaner, purpose-built platforms designed to meet the needs of modern AI workloads with greater precision and speed.

Here’s how they’re closing the gap:

1. Specialized Hardware

Neocloud providers are laser-focused on providing access to the newest and most powerful GPUs—often before hyperscalers can make them widely available. NVIDIA’s H100 and A100 accelerators, crucial for training and inference, are the cornerstone of these platforms. Many neoclouds go a step further, offering liquid-cooled racks, ultra-low-latency interconnects, and AI-specific storage tiers designed to keep pace with multi-petabyte datasets. For cutting-edge AI labs and fast-moving startups, this means the difference between weeks and months in development timelines.

2. Bare-Metal Performance

By eliminating the virtualization layers common in general-purpose clouds, neoclouds give users direct access to raw compute power. This bare-metal approach reduces latency and avoids the “noisy neighbor” problem, enabling highly deterministic performance—crucial when fine-tuning large language models or orchestrating tightly coupled GPU workloads. For teams pushing the edge of performance, every clock cycle matters, and neoclouds are delivering those cycles unfiltered.

3. Scalability on Demand

AI R&D is rarely linear. One month you’re iterating on small models, and the next you’re scaling to train a 70-billion-parameter transformer. Neocloud infrastructure is designed to expand and contract with those demands—supporting everything from a few nodes to full-scale superclusters. Unlike traditional clouds, which often impose capacity planning constraints or quotas, neoclouds thrive on elasticity, provisioning capacity dynamically and often within hours rather than weeks.

4. Cost Efficiency with Purpose-Built Pricing

Where hyperscalers often price GPU instances at a premium—factoring in legacy overhead and multi-tenant complexity—neoclouds keep things lean. Many operate with thinner margins and lower operational complexity, translating to significantly lower costs per training hour. Providers like Lambda, Run:ai, and Voltage Park offer transparent, workload-specific pricing that aligns with actual usage. High utilization rates and tailored provisioning models keep costs in check, making neoclouds especially appealing for startups and research groups running on grant cycles or VC runway.

These advantages make neoclouds invaluable not only for startups with limited budgets but also for established enterprises seeking to accelerate their AI initiatives.

Resilience at Scale: Why Neoclouds May Outlast the AI Hype Cycle

Investing in neoclouds offers a unique opportunity to participate in the AI boom without betting on specific applications or platforms. The rapid pace of innovation means that today’s leading AI models could be eclipsed by new breakthroughs tomorrow. However, regardless of which technologies prevail, the need for robust infrastructure will remain constant.

This dynamic mirrors historical gold rushes, where equipment suppliers thrived even as individual miners faced uncertainty. By providing essential tools for AI development, neocloud providers are positioned to benefit from sustained demand across diverse industries—from healthcare and finance to entertainment and logistics.

As the AI gold rush continues, neoclouds are poised to play an increasingly central role in shaping its trajectory. Their ability to deliver cost-effective, high-performance infrastructure makes them critical enablers of innovation. At the same time, their business model—focused on empowering others rather than competing directly—ensures they remain indispensable partners in the AI ecosystem.

Looking forward, neoclouds face challenges such as supply chain constraints for GPUs and competition from hyperscalers attempting to close the performance gap. However, their agility and specialization give them a distinct edge in navigating these hurdles. In many ways, they represent the future of cloud computing: leaner, faster, and more focused on solving specific problems.

As investors and enterprises seek ways to capitalize on AI’s transformative potential, neoclouds offer a compelling proposition—one that promises steady growth amid the chaos of rapid technological change.

Economic Disruption: How Neoclouds Are Redefining Cost and Performance

The emergence of neoclouds is causing a significant economic disruption in the AI infrastructure landscape. Unlike traditional hyperscalers that offer a broad range of services, neocloud providers concentrate on delivering optimized price-performance specifically for AI workloads. This specialization translates into several key advantages: higher GPU utilization rates, bare-metal access, and the application of deep, specialist expertise. These elements combine to create a compelling economic proposition for AI developers and enterprises.

The numbers speak for themselves. Neoclouds are achieving significant cost reductions, with reports from Uptime Institute indicating as much as 66% savings on GPU instances when compared to major hyperscalers. This substantial difference stems from the ability to maximize the use of expensive GPU resources and minimize overhead. For organizations running large-scale AI training or inference tasks, this can lead to considerable savings in operational expenses.

The efficiencies introduced by neoclouds are reshaping the overall economics of AI development. As models grow in complexity and require more compute power, the cost of training and deploying them has become a major barrier. By lowering these costs, neoclouds make it feasible for a wider array of organizations – from startups to established corporations – to engage in AI initiatives. This democratization of AI resources has the potential to accelerate innovation across diverse sectors, allowing more companies to harness the power of AI without breaking the bank.

Advancing Coopetition Between Neocloud Providers and Hyperscalers

The relationship between neocloud providers and traditional hyperscalers is increasingly defined by a complex blend of competition and collaboration. As the demand for AI infrastructure surges, both camps are vying for dominance in the lucrative GPU cloud market, yet their interactions are far from zero-sum, resulting in a competitive, yet symbiotic, market landscape.

Neoclouds have carved out a niche by specializing in GPU-accelerated infrastructure tailored for AI and machine learning workloads. Their agility, focus, and deep understanding of AI developers’ needs allow them to offer cost-effective, high-performance solutions that challenge the broader, premium-priced offerings of hyperscalers. While hyperscalers benefit from vast economies of scale and integrated ecosystems, their diversified business models and high-margin pricing strategies on their cloud businesses often result in higher prices for AI-specific resources.

Despite this competition, the two groups are increasingly intertwined. Neoclouds often position themselves not as direct competitors, but as complementary partners within enterprise multi-cloud strategies. For example, an organization might use a neocloud to train a large language model, then deploy it on a hyperscaler’s platform for inference and integration with other services. This approach allows enterprises to optimize for both performance and cost, leveraging the strengths of each provider.

Investment, Partnership, and Multi-Cloud Integration

The interplay between neoclouds and hyperscalers is further complicated by growing investment and partnership activity. Hyperscalers are not only competing with neoclouds but also investing in them and, in some cases, becoming their customers. A prominent example is Microsoft’s $10 billion commitment to CoreWeave to secure access to specialized GPU infrastructure through 2029. Such deals highlight the recognition by hyperscalers of the unique value neoclouds bring to the AI infrastructure ecosystem.

For enterprises, this dynamic is accelerating the adoption of multi-cloud strategies. By integrating neoclouds into their cloud portfolios, organizations can avoid vendor lock-in, optimize for specific workloads, and ensure access to scarce GPU resources. However, this also introduces new complexities, as enterprises must now manage interoperability and data movement across increasingly fragmented cloud environments.

Looking forward, the evolving relationship between neoclouds and hyperscalers increases the prospects (and pricing) of further M&A activity across key players. As neoclouds grow in scale and strategic importance, it is likely that some will be acquired by hyperscalers seeking to bolster their AI infrastructure capabilities and maintain competitive advantage. Such consolidation will reshape the market’s structure, potentially accelerating innovation through deeper integration, but also raising questions about pricing power and the pace of future disruption.

High Stakes Require High Investment

The capital intensity of neoclouds is staggering. Building and maintaining these specialized infrastructure platforms requires massive investments in GPUs, networking equipment, and data center facilities. To finance this expansion, neoclouds have tapped into both equity and debt markets, with some pioneering the use of GPU assets as collateral for loans. This approach allows them to leverage their hardware investments more efficiently, but also exposes them to the risk of depreciating GPU values and limited liquidity.

The market is also seeing large supply chain vulnerabilities, and rapid equipment obsolescence, increasing the risk of relying too heavily on any one provider. The rapid pace of innovation in chip design presents both opportunities and challenges. While new generations of GPUs promise increased performance and efficiency, they also render older hardware obsolete on extremely short timelines.

This creates a constant pressure to upgrade infrastructure, potentially straining finances and exacerbating supply chain vulnerabilities. Geopolitical factors and manufacturing bottlenecks can further disrupt the supply of GPUs, as we are seeing with recent tariffs affecting NVIDIA, thus impacting neocloud providers’ abilities to meet growing demand.

The Chipmaker Landscape: Navigating the Silicon Battleground of the Neocloud Era

The neocloud boom is redefining the data center ecosystem, driven by billions in venture capital and a red-hot GPU-backed debt market that’s rewriting the rules of infrastructure financing. But while the capital is flowing fast, the underlying hardware story is anything but straightforward. Supply chain constraints, hardware churn, and the specter of over-leverage hang over the sector as neocloud builders sprint to scale. At the heart of this high-stakes race sit the chipmakers — the true power brokers of the AI infrastructure gold rush.

NVIDIA holds the pole position, having effectively set the standard for AI compute with its high-performance GPUs and the proprietary CUDA software stack that developers now treat as foundational. The company’s dominance isn’t just about raw silicon; it’s about controlling the ecosystem. But as demand for AI infrastructure skyrockets, so do concerns about supply bottlenecks, pricing leverage, and the systemic risks of depending too heavily on a single vendor.

Enter AMD and Intel, both aggressively positioning themselves as viable alternatives. AMD’s Instinct accelerators have made meaningful headway, especially among hyperscalers and research labs looking for more open, programmable environments. Its embrace of open-source software and its tight integration across CPU and GPU workloads gives it an edge in environments where flexibility and long-term value matter.

Intel, meanwhile, is betting on a diversified portfolio and a vertically integrated approach. With CPUs, discrete GPUs, and dedicated AI accelerators (via Habana Labs), Intel is aiming to meet the market wherever the workload lands — from training massive models to powering real-time inference at the edge. Its growing software investments signal a deeper push to win developer mindshare, not just silicon sockets.

What’s increasingly clear is that chipmakers now play a strategic role that transcends component supply. Their influence touches everything from AI model optimization to deployment timelines and total cost of ownership. In a capital-intensive market where seconds of inference time and watts per rack can make or break a business model, silicon choices aren’t just technical — they’re existential.

For neocloud operators, the path forward demands architectural agility. Betting solely on NVIDIA may win short-term performance, but long-term resilience will require multi-vendor strategies that hedge against market shocks, broaden workload compatibility, and enhance buyer leverage. The most successful neocloud platforms will be those that understand chipmakers not just as suppliers, but as strategic partners — and occasionally, as competitive threats.

As the AI era matures, the chipmaker battleground will increasingly shape who wins the neocloud race — and who gets left behind in the silicon stampede.

Which Provides the Winning Competitive Edge: Specialization or Scale?

The rise of neoclouds has been driven by their ability to deliver specialized, high-performance infrastructure tailored for AI workloads. However, the question remains: are these advantages sustainable in the long term, or do they merely represent a transitional phase before hyperscalers catch up? For neoclouds to maintain a competitive edge, there are many potential scenarios to consider.

The Bull Case: Persistent Barriers to Entry

The argument for neoclouds’ long-term viability rests on several key factors:

Technical Complexity: Building and managing AI-optimized infrastructure requires deep expertise in GPU architecture, networking, and software. Neoclouds have cultivated this expertise over time, creating a barrier to entry that is difficult for hyperscalers to replicate quickly.

Specialization: Neoclouds focus solely on AI workloads, allowing them to optimize their infrastructure and services for the specific needs of AI developers. This specialization translates into superior performance and cost-efficiency compared to the more generalized offerings of hyperscalers.

Agility: Neoclouds tend to be smaller and more agile than hyperscalers, enabling them to adapt quickly to changing market conditions and emerging technologies. This agility is particularly valuable in the rapidly evolving field of AI.

The Bear Case: Margin Compression and Scale Advantages

Despite many advantages, neoclouds face significant challenges from hyperscalers:

Margin Compression: As hyperscalers invest more heavily in AI infrastructure and refine their offerings, they may be able to erode the price advantage currently enjoyed by neoclouds. Hyperscalers’ scale economies and ability to cross-subsidize AI services with other cloud offerings could put significant pressure on neocloud margins.

Scale Advantages: Hyperscalers possess massive economies of scale, allowing them to procure hardware at lower prices and invest more heavily in R&D. This scale advantage could enable them to leapfrog neoclouds in terms of performance and innovation.

Ecosystem Integration: Hyperscalers offer tightly integrated ecosystems of cloud services, making it easier for customers to build and deploy AI applications. Neoclouds may struggle to match this level of integration, particularly for enterprises that rely on a wide range of cloud services.

Scenarios for the Future

The future of the neocloud market is uncertain, but several scenarios are possible:

Coexistence: Neoclouds and hyperscalers coexist, with each catering to different segments of the market. Neoclouds focus on specialized AI workloads and customers who prioritize performance and cost-efficiency, while hyperscalers cater to enterprises seeking a broader range of cloud services and ecosystem integration.

Market Consolidation: Hyperscalers acquire leading neoclouds to bolster their AI infrastructure capabilities and gain access to specialized expertise. This scenario could lead to greater integration and innovation, but also raise concerns about pricing power and market competition.

Disruption: Neoclouds continue to innovate and disrupt the market, challenging the dominance of hyperscalers and attracting a growing share of AI workloads. This scenario would require neoclouds to overcome challenges related to scale, ecosystem integration, and capital access.

Ultimately, the long-term success of neoclouds will depend on their ability to differentiate themselves from hyperscalers, innovate continuously, and adapt to the rapidly evolving needs of the AI community.

Making AI More Accessible: Who’s Using Neoclouds—and Why It Matters

The neocloud market represents a dynamic and essential force driving innovation in the age of AI. By specializing in high-performance, cost-effective infrastructure, neocloud providers are not only enabling the AI revolution, but also reshaping the economics of cloud computing.

Whether as “picks and shovels” suppliers to the AI gold rush, or as competitive partners alongside hyperscalers, neoclouds are proving their enduring value in a rapidly evolving technological landscape. And as they navigate the challenges of scale, financing, and chipmaker dependencies, the neoclouds are poised to continue pushing the boundaries of what’s possible in AI, fostering a more accessible and innovative future for all.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Fuel constraints could challenge grid this winter, despite resource improvements: NERC

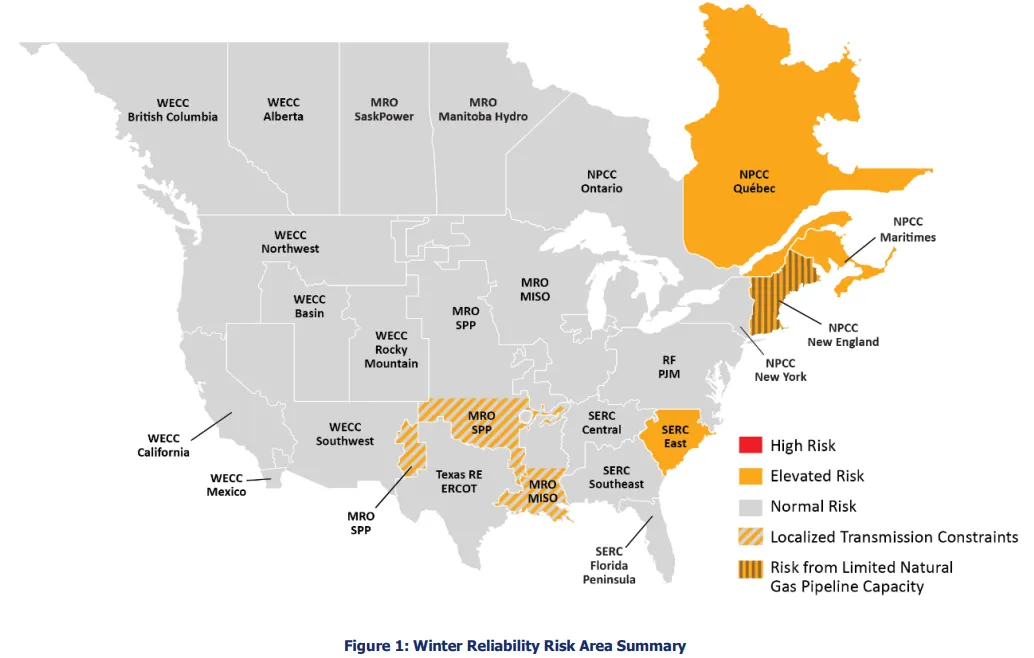
Listen to the article 3 min This audio is auto-generated. Please let us know if you have feedback. Dive Brief: The bulk power system’s winter reliability outlook has improved since last season, but the El Niño weather pattern and potential for extreme cold can present challenges that grid operators must remain aware of, the North American Electric Reliability Corp. said Wednesday in its annual seasonal outlook. On-peak capacity resources grew 26.2 GW over the 2025-26 winter, a 2.4% increase led by batteries and gas-fired generation, according to the 2026–2027 Winter Reliability Assessment. A slowdown in generator retirements is also contributing to the improved resource outlook, NERC said. The reliability watchdog’s outlook identified no areas facing a high risk of resource shortfalls this winter, but it found some areas in the Midwest, Southeast and New England where transmission system constraints, pipeline constraints and fuel risk scenarios may present problems during periods of extreme weather. Dive Insight: Electric demand is growing, but “there has also been strong growth in resources,” Mark Olson, manager of reliability assessments, said Wednesday in a call discussing the outlook. “In many ways, the industry is on better footing going into winter this year,” he said. However, Olson added that “historically, winter is the toughest operating period for the North American electric grid.”  While some models show the El Niño weather pattern can bring milder-than-average conditions that are a help to a constrained power system, “the reality is that extreme storms with ice and abnormal cold temperatures can lie within those averages,” Olson said. Retrieved from North American Electric Reliability Corp. “We’re talking to our industry stakeholders about the need for extra vigilance. El Niño is a variable that adds to uncertainty for the winter,” he said. Peak winter electric heating demand often coincides with higher residential gas usage,

Read More »

Energy Secretary Acts to Protect Mid-Atlantic Grid

WASHINGTON—U.S. Secretary of Energy Chris Wright issued an emergency order to reduce the risk of power outages and strengthen grid reliability across the mid-Atlantic region. The order permits PJM Interconnection, L.L.C. (PJM), in coordination with Talen Energy Corporation, to run Unit 4 at the Wagner Generating Station in Anne Arundel County, Maryland, to meet anticipated electricity demand. The order follows an application from PJM submitted on October 23, 2026.  “Energy shortfalls for 65 million Americans are simply unacceptable,” said U.S. Secretary of Energy Chris Wright.  “Previous orders in the mid-Atlantic region have helped keep the lights on and I’m confident this order will help do so in the coming months as well. Today’s order helps temporarily address the urgent need to strengthen grid reliability and ensure Americans across the mid-Atlantic region have access to affordable, reliable, and secure power, regardless of whether the sun shines or the wind blows.”   Secretary Wright previously granted PJM’s requests to operate Wagner Unit 4 beyond its operating limit to help maintain grid reliability.  PJM relied on Wagner Unit 4 during periods of unusually high temperatures earlier this summer, using the unit’s remaining operating hours. PJM has since reaffirmed to the Department of Energy (DOE) the continued need for Wagner Unit 4 to meet high electricity demand, strengthen grid reliability, and reduce the risk of power outages across the mid-Atlantic region.   The renewed order is effective from November 18, 2026, through December 31, 2026. 

Read More »

EIA: US crude oil inventories up 3.4 million bbl

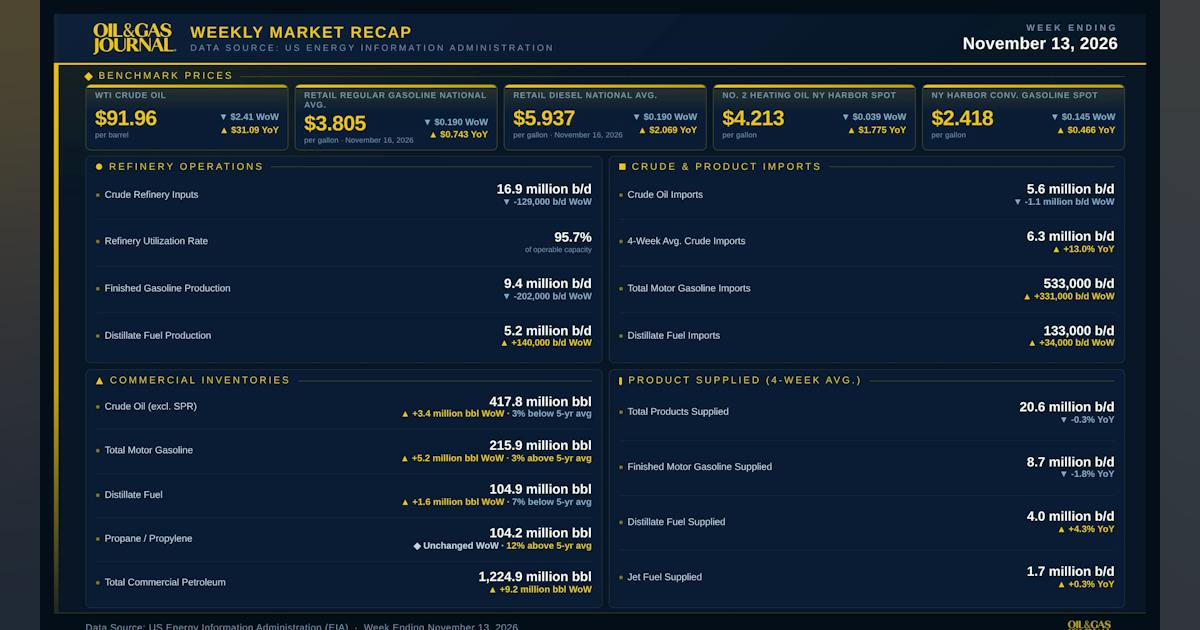
US crude oil inventories for the week ended Nov. 13, excluding the Strategic Petroleum Reserve, increased by 3.4 million bbl from the previous week, according to data from the US Energy Information Administration (EIA). At 417.8 million bbl, US crude oil inventories are 3% below the 5-year average for this time of year, the EIA report indicated. Gasoline inventories increased 5.2 million bbl, 3% above the 5-year average. Propane-propylene inventories remained unchanged, 12% above the 5-year average. Total commercial petroleum inventories increased by 9.2 million bbl for the week. Distillate inventories increased 1.6 million bbl, 7% below the 5-year average. US crude oil refinery inputs averaged 16.9 million b/d for the week ended Nov. 13, which was 129,000 b/d less than the previous week’s average. Refineries operated at 95.7% of capacity. Gasoline output averaged 9.4 million b/d, and distillate production increased to 5.2 million b/d. Crude oil imports decreased 1.1 million b/d to 5.6 million b/d. The 4-week average of 6.3 million b/d is 13% above the year-ago level. Gasoline imports increased and averaged 533,000 b/d; distillate imports also increased and averaged 133,000 b/d. Over the past four weeks, total product supplied averaged 20.6 million b/d, down 0.3% year over year. The 4-week average for gasoline product supplied decreased 1.8% year over year to 8.7 million b/d, while the 4-week average for distillate product supplied increased 4.3% to 4.0 million b/d. The 4-week average for jet fuel product supplied increased 0.3% year over year.

Read More »

Sonangol discovers hydrocarbons offshore Kwanza basin

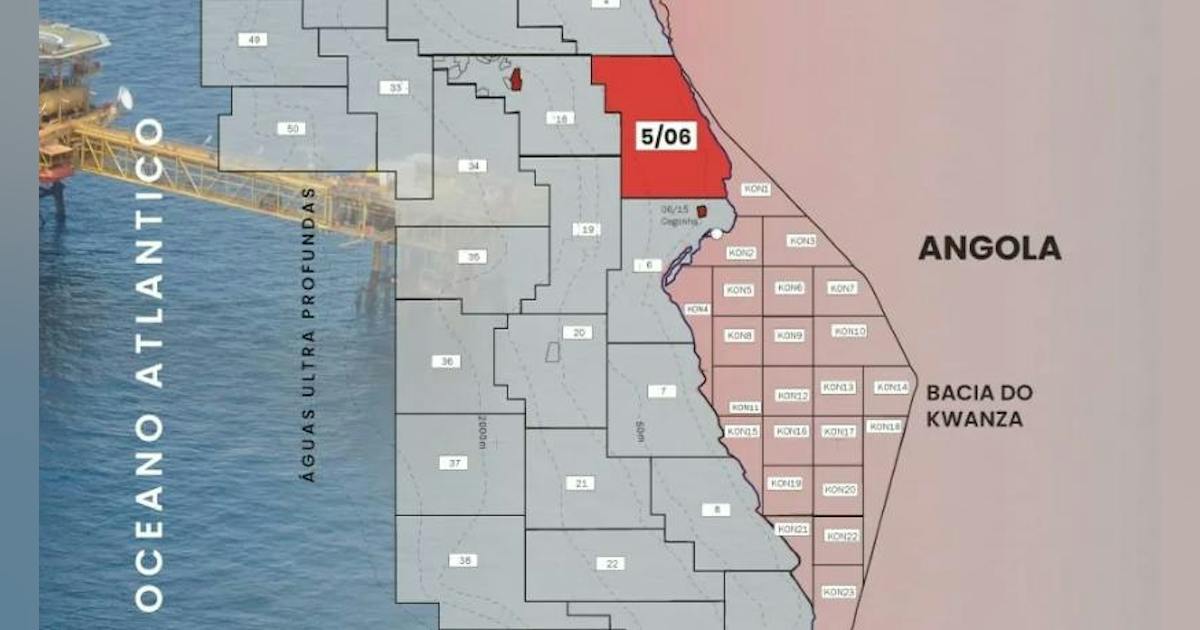
Sonangol’s Burututu-1 well has identified hydrocarbons in pre-salt reservoirs for the first time in Angola’s Block 5/06. <!–> Nov. 18, 2026 –> Key Highlights Burututu-1 is the first well to identify hydrocarbons in presalt reservoirs in Block 5/06. The discovery lies in the maritime portion of Angola’s Kwanza basin. The exploration identified 25 m of reservoir containing hydrocarbon deposits.

Read More »

The grid will fall short of AI’s power needs. These 6 resources can close the gap.

Listen to the article 7 min This audio is auto-generated. Please let us know if you have feedback. Simon Irish is CEO of Terrestrial Energy, a developer of small modular nuclear reactors. Most planning for artificial intelligence’s electricity demand starts with a forecast and asks whether it is right. I would start somewhere else: Assume the grid will fall short, then ask how to close the gap — and how fast. Simon Irish The evidence supports that starting point. McKinsey & Company estimates the U.S. will need 30 GW to 55 GW of additional capacity by 2030 as data center demand grows and aging plants retire. PJM Interconnection, the largest U.S. grid operator, has already seen the impacts of this trend. Its latest capacity auction fell about 6.6 GW short of its reliability requirement and cleared at the price cap. Forecasts can be wrong, and requested load can be speculative or duplicative. But the PJM result is a market outcome, not a forecast. The useful question is which tools can close the gap, by when and at what cost. 6 ways to close the gap, and where each runs out The first four options below address serving data centers through the grid. The final two consider generation at or near the data center, with an optional grid connection. These categories overlap; on-site generation is a delivery strategy, not a generation technology, and can use multiple technologies. Flexible demand. Duke University’s Nicholas Institute estimates the grid could absorb 76 GW of new load if that load accepted curtailment averaging 0.25% of annual consumption, in events of about 1.7 hours. It is the fastest option because it needs no new generation. It makes better use of capacity already on the grid. But that capacity is finite, and beyond it, further load growth

Read More »

NEO Next+ to acquire UK upstream business from EnQuest for up to $960 million

NEO Next+ Energy Upstream UK Ltd. has agreed to acquire EnQuest plc’s UK upstream oil and gas business and associated infrastructure for up to $960 million. The acquisition includes all issued shares of EnQuest Britain Ltd., which through subsidiaries holds EnQuest’s UK upstream interests, including the operated Magnus, Kraken, and Greater Kittiwake Area fields (Kittiwake, Mallard, Gadwall, Goosander and Grouse), the non-operated Golden Eagle field, and the undeveloped Bressay field and Bentley discovery. The assets averaged net production of 31,100 boe/d in 2025, comprising 92% liquids and 8% gas. As of Dec. 31, 2025, the portfolio contained 122 MMboe of 2P reserves and 308 MMboe of 2C resources, according to EnQuest. The deal also includes EnQuest’s UK decommissioning liabilities and midstream interests, including its operating stake in the Sullom Voe Terminal, the Northern Leg gas pipeline, and the Ninian pipeline system. EnQuest is divesting the assets as part of a broader strategy to become a Southeast Asia-focused operator with production, development, and exploration assets in Malaysia, Vietnam, Brunei, and Indonesia, as well as its Veri Energy subsidiary and associated carbon capture, utilization, and storage interests. The company cited an uncertain UK investment environment. For NEO Next+, the deal is the latest step in its North Sea consolidation strategy. In December 2025, TotalEnergies agreed to combine its UK offshore upstream business with NEO NEXT Energy Ltd., creating what the companies described as the largest independent oil and gas producer in the UK. Consideration comprises an upfront cash payment of $840 million at closing, subject to customary adjustments, and contingent payments of up to $120 million tied to future oil prices and potential changes to the UK fiscal regime, including repeal or reduction of the Energy Profits Levy between January 2027 and yearend 2029. Completion remains subject to customary conditions and regulatory approvals. The

Read More »

Sovereign AI is about control, not just location

Guetari was open about the term itself being fuzzy. “Sovereignty is very vague and not always clear,” he told me. “It’s about control, auditability, observability.” He drew a line between data locality, meaning the data stays in-country, and sovereignty, which he described as being “more about control, control of what happens to your data and your workload.” He then made the case for why F5 belongs in that conversation: “This is what we have been doing for two decades.” F5 has always sat in the data path, deciding what an application can communicate with, enforcing security rules, and logging what happened. For a regulated bank or government agency, the ability to reconstruct exactly what happened after an incident is worth more than a press release about a data center’s location. The token is the new unit of economics The most interesting part of my conversation with Guetari wasn’t about security. It was about business models. He argued that every successful technology business has found the right unit to monetize. “The cloud is selling the unit of the cloud, which is the CPU core, very well. SaaS is the seat,” he said. “Telcos have been very successful early on using the voice minute, and then they moved to the gigabyte. Sooner or later, that unit will be the token, and most telcos will have to move to the token. And the ones who will not go to token, unfortunately, will be just pipes.”

Read More »

Palo Alto Networks bets $4.5B on enterprise AI with Applied Compute acquisition

GPUs and data centers To train and host those models, Palo Alto plans to build its own compute capacity, CFO Dipak Golechha said on the call. The spending “will mostly go to GPUs and servers,” with a smaller share for the facilities that house them, he said. Palo Alto will “continue to source from our cloud partners” and add dedicated capacity over time, Golechha said. Arora said the company aims for more than100 megawatts of compute in the next three to five years. Gogia said Palo Alto has sovereignty credentials for security data, including customer-held keys and a European Cortex service governed by Deutsche Telekom. “None of that yet extends to GPUs,” he said, adding that a US-headquartered operator faces the same jurisdictional questions as the hyperscalers it rents capacity from. “A sovereign hosting offer with no named region, operator or date is a promise looking for an address,” Gogia said. Compliance officers should ask Palo Alto for a region list, the operator, and a dated certification plan, he said.

Read More »

App developers turn to QVAC for AI tooling without the cloud  

In most instances today, adding AI to an app means sending user data to a third-party API, paying per request, and hoping the connection holds.    Tether’sQVAC is built on the opposite premise. It runs AI models directly on the user’s device. Data never leaves the hardware, there are no per-request costs, no rate limits, and no need for an internet connection once a model is downloaded.   QVAC SDK: the next milestone in cloud-free AI  While open-source tools and standards like llama.cpp, GGML, and ONNX have made local AI much more accessible in recent years, creating new possibilities for consumer devices, the edge AI ecosystem remains fragmented.    Against this backdrop, in 2026, Tether released a software development kit (SDK) that pulls together the best open tooling from across different domains of machine learning.    The centerpiece of Tether’sQVACSDK isFabric. Built on llama.cpp, it expands the engine to enable on-device fine tuning and additional AI capabilities—opening access to memory-intensive workloads previously only possible with expensive hardware or cloud services.    Building on GGML’s modular framework, QVAC Fabric is primarily oriented toward three backends: Vulkan, which covers most consumer-grade desktop and mobile chips; Metal and Core ML for Apple Silicon; and CUDA for higher-end NVIDIA GPU setups.   The QVAC SDK empowers developers with a unified interface for building multiplatformAIappsthatrunon-device. But although significant progress has been made in bringing inference to consumer devices, text generation alone is only one part of the pipeline that makes modern AI useful.    Bringing search to edge AI   RAG (retrieval-augmented generation) is what equips AI to import and process contextual information to enhance its output. Instead of language models relying solely on their training  data to answer questions, RAG lets them answer using a specific set of documents.    Implementing RAG into an AI app incurs significant memory overhead versus running a

Read More »

DCF Video: CoolIT’s 3 MW CDU Brings Smart Monitoring and Fanless Cooling to AI Infrastructure

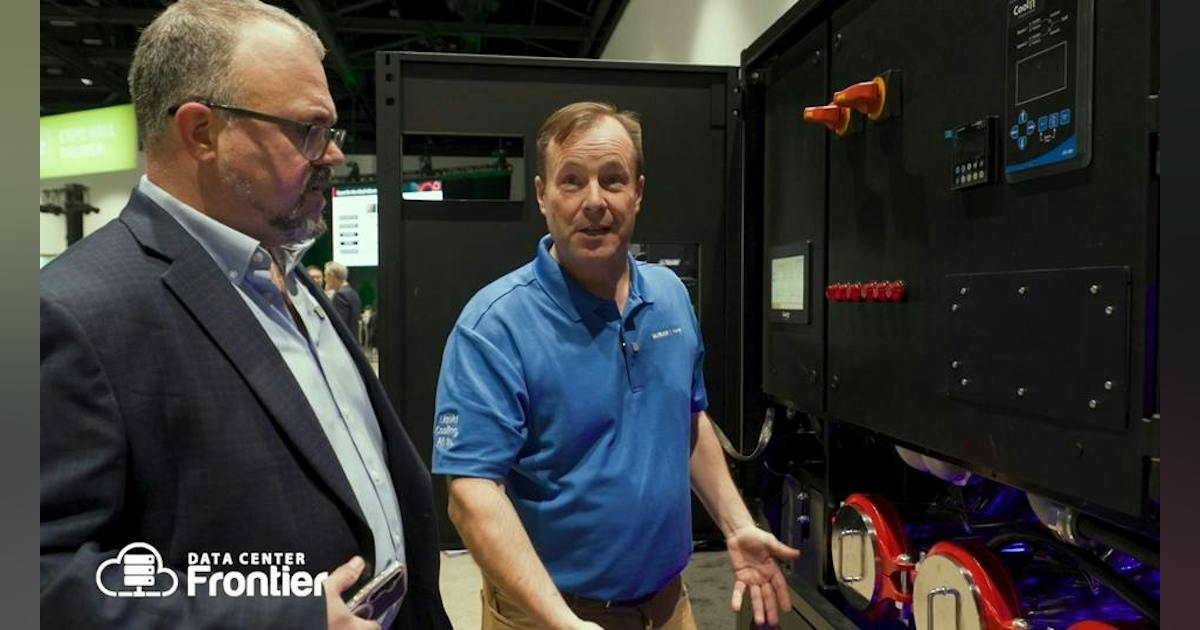
As AI infrastructure moves toward higher rack densities and increasingly liquid-cooled architectures, the next challenge is not simply removing more heat. It’s ensuring that the cooling systems themselves remain reliable, efficient, and capable of protecting increasingly valuable computing hardware. At the 2026 OCP Global Summit in San Jose, CoolIT Systems Director of Marketing Charles Robison gave Data Center Frontier a close-up look at several technologies addressing that challenge, including the company’s new 3-megawatt CHx 3000 coolant distribution unit (CDU), integrated coolant health monitoring, and a fifth-generation cold plate loop designed for fanless servers. The demonstration comes at a significant moment for CoolIT, which was acquired by Ecolab for approximately $4.75 billion in July 2026. On November 16, Ecolab formally introduced its new integrated AI cooling platform at SC26 in Chicago, placing the CHx 3000 and its embedded 3D TRASAR technology at the center of a broader strategy combining liquid cooling hardware, fluid management, and digital monitoring. Looking Inside the CHx 3000 The CoolIT CHx 3000 is a liquid-to-liquid CDU rated for 3 MW of cooling capacity at a 3°C approach temperature difference, with a specified flow rate of 4,500 liters per minute. Designed for high-density AI deployments, the unit incorporates Ecolab’s 3D TRASAR technology to continuously monitor the condition of the circulating coolant. In the video, Robison points directly to the sensor array that makes the integration possible. “3D TRASAR, and you can see the array of sensors here, allows coolant health monitoring,” Robison explains. “It allows people to see real-time what’s going on with the coolant. So before it goes out of spec, they know what’s happening and they can address it.” The distinction is important. Traditional cooling monitoring typically emphasizes temperature, pressure, and flow. Ecolab’s technology adds visibility into fluid chemistry and contamination, allowing operators to identify deteriorating

Read More »

Beyond Announced Megawatts: Metlen’s Lillian Kasa on Delivering AI Infrastructure

For an industry racing to build infrastructure at unprecedented scale, the most consequential question may no longer be how many megawatts can be announced. It is how many can actually be delivered—and which projects deserve the investment required to get there. As hyperscalers, neoclouds, and data center developers assemble increasingly ambitious capacity pipelines, the distinction between potential and execution has become central to the economics of AI infrastructure. Announcements routinely involve hundreds of megawatts or gigawatts. But behind those numbers lie unresolved questions about power availability, equipment procurement, customer commitments, construction schedules, and financing. For Lillian Kasa, Head of Energy and Data Center Infrastructure Origination for North America at Metlen, these are not simply obstacles to be overcome in pursuit of speed. They are the fundamental questions that determine whether an infrastructure opportunity is worth developing in the first place. In a new episode of the Data Center Frontier Show, Kasa joined DCF Editor in Chief Matt Vincent to examine how developers can distinguish viable projects from speculative pipelines, allocate capital under uncertainty, and build commercial structures capable of supporting the next generation of AI computing infrastructure. The conversation follows Kasa’s participation at September’s Data Centre West conference in Calgary, where she moderated a panel on Solving for Power. As DCF reported in its Data Centre West 2026 conference analysis, the industry is increasingly discovering that power availability and delivery certainty—not simply land or market demand—determine which projects can proceed. Kasa brings an additional perspective to that conversation: years spent in offshore oil and gas exploration, where capital-intensive investment decisions must routinely be made with incomplete information. Her argument is that AI infrastructure development can benefit from much the same discipline. The Difference Between Announcing Power and Delivering It “When I hear an announcement involving hundreds of megawatts or gigawatts,

Read More »

Arista expands its routing options to support secure AI inferencing

Arista is unveiling a portfolio of networking devices designed to secure and improve the performance and resiliency of connections serving AI compute and storage infrastructure. Four new Etherlink R4 high-performance routing switches are aimed at large-scale distributed data center, AI back-end, and service provider environments where high route scale, deep packet buffering, and 400G connectivity are required. In addition, the new R4s integrate line-rate encryption into every port via TunnelSec, including MACsec, IPsec, VXLANsec, and hardware-based Segment Routing over IPv6, according to a blog post co-authored by Brendan Gibbs, Arista vice president, product line management, and Tyson Lamoreaux, senior vice president, Cloud/AI. All run Arista’s Extensible Operating System, or EOS. “The initial phase of artificial intelligence (AI) buildouts concentrated compute nodes in massive, centralized clusters, but the need for greater scale has led operators to span training clusters across multiple data centers with AI scale-across solutions. Now, the operational reality of centralized inferencing has emerged as the new frontier requiring a distributed solution,” Gibbs and Lamoreaux wrote. “Training can tolerate being tucked away near remote power grids, while inferencing cannot. As AI transitions from static prompts to real-time interaction, intelligence must be distributed across front-end networks spanning distinct geographies, regional hubs, and enterprise perimeters.”

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »

Introducing Gemini 4 Neon

Delivers across enterprise, analytical, and scientific workEnterprise work lives in spreadsheets, PDFs, charts, audio, and video. Neon can synthesize across all of these inputs in

Read More »