Stay Ahead, Stay ONMINE

AI means the end of internet search as we’ve known it

We all know what it means, colloquially, to google something. You pop a few relevant words in a search box and in return get a list of blue links to the most relevant results. Maybe some quick explanations up top. Maybe some maps or sports scores or a video. But fundamentally, it’s just fetching information that’s already out there on the internet and showing it to you, in some sort of structured way.  But all that is up for grabs. We are at a new inflection point. The biggest change to the way search engines have delivered information to us since the 1990s is happening right now. No more keyword searching. No more sorting through links to click. Instead, we’re entering an era of conversational search. Which means instead of keywords, you use real questions, expressed in natural language. And instead of links, you’ll increasingly be met with answers, written by generative AI and based on live information from all across the internet, delivered the same way.  Of course, Google—the company that has defined search for the past 25 years—is trying to be out front on this. In May of 2023, it began testing AI-generated responses to search queries, using its large language model (LLM) to deliver the kinds of answers you might expect from an expert source or trusted friend. It calls these AI Overviews. Google CEO Sundar Pichai described this to MIT Technology Review as “one of the most positive changes we’ve done to search in a long, long time.” AI Overviews fundamentally change the kinds of queries Google can address. You can now ask it things like “I’m going to Japan for one week next month. I’ll be staying in Tokyo but would like to take some day trips. Are there any festivals happening nearby? How will the surfing be in Kamakura? Are there any good bands playing?” And you’ll get an answer—not just a link to Reddit, but a built-out answer with current results.  More to the point, you can attempt searches that were once pretty much impossible, and get the right answer. You don’t have to be able to articulate what, precisely, you are looking for. You can describe what the bird in your yard looks like, or what the issue seems to be with your refrigerator, or that weird noise your car is making, and get an almost human explanation put together from sources previously siloed across the internet. It’s amazing, and once you start searching that way, it’s addictive. And it’s not just Google. OpenAI’s ChatGPT now has access to the web, making it far better at finding up-to-date answers to your queries. Microsoft released generative search results for Bing in September. Meta has its own version. The startup Perplexity was doing the same, but with a “move fast, break things” ethos. Literal trillions of dollars are at stake in the outcome as these players jockey to become the next go-to source for information retrieval—the next Google. Not everyone is excited for the change. Publishers are completely freaked out. The shift has heightened fears of a “zero-click” future, where search referral traffic—a mainstay of the web since before Google existed—vanishes from the scene.  I got a vision of that future last June, when I got a push alert from the Perplexity app on my phone. Perplexity is a startup trying to reinvent web search. But in addition to delivering deep answers to queries, it will create entire articles about the news of the day, cobbled together by AI from different sources.  On that day, it pushed me a story about a new drone company from Eric Schmidt. I recognized the story. Forbes had reported it exclusively, earlier in the week, but it had been locked behind a paywall. The image on Perplexity’s story looked identical to one from Forbes. The language and structure were quite similar. It was effectively the same story, but freely available to anyone on the internet. I texted a friend who had edited the original story to ask if Forbes had a deal with the startup to republish its content. But there was no deal. He was shocked and furious and, well, perplexed. He wasn’t alone. Forbes, the New York Times, and Condé Nast have now all sent the company cease-and-desist orders. News Corp is suing for damages.  People are worried about what these new LLM-powered results will mean for our fundamental shared reality. It could spell the end of the canonical answer. It was precisely the nightmare scenario publishers have been so afraid of: The AI was hoovering up their premium content, repackaging it, and promoting it to its audience in a way that didn’t really leave any reason to click through to the original. In fact, on Perplexity’s About page, the first reason it lists to choose the search engine is “Skip the links.” But this isn’t just about publishers (or my own self-interest).  People are also worried about what these new LLM-powered results will mean for our fundamental shared reality. Language models have a tendency to make stuff up—they can hallucinate nonsense. Moreover, generative AI can serve up an entirely new answer to the same question every time, or provide different answers to different people on the basis of what it knows about them. It could spell the end of the canonical answer. But make no mistake: This is the future of search. Try it for a bit yourself, and you’ll see.  Sure, we will always want to use search engines to navigate the web and to discover new and interesting sources of information. But the links out are taking a back seat. The way AI can put together a well-reasoned answer to just about any kind of question, drawing on real-time data from across the web, just offers a better experience. That is especially true compared with what web search has become in recent years. If it’s not exactly broken (data shows more people are searching with Google more often than ever before), it’s at the very least increasingly cluttered and daunting to navigate.  Who wants to have to speak the language of search engines to find what you need? Who wants to navigate links when you can have straight answers? And maybe: Who wants to have to learn when you can just know?  In the beginning there was Archie. It was the first real internet search engine, and it crawled files previously hidden in the darkness of remote servers. It didn’t tell you what was in those files—just their names. It didn’t preview images; it didn’t have a hierarchy of results, or even much of an interface. But it was a start. And it was pretty good.  Then Tim Berners-Lee created the World Wide Web, and all manner of web pages sprang forth. The Mosaic home page and the Internet Movie Database and Geocities and the Hampster Dance and web rings and Salon and eBay and CNN and federal government sites and some guy’s home page in Turkey. Until finally, there was too much web to even know where to start. We really needed a better way to navigate our way around, to actually find the things we needed.  And so in 1994 Jerry Yang created Yahoo, a hierarchical directory of websites. It quickly became the home page for millions of people. And it was … well, it was okay. TBH, and with the benefit of hindsight, I think we all thought it was much better back then than it actually was. But the web continued to grow and sprawl and expand, every day bringing more information online. Rather than just a list of sites by category, we needed something that actually looked at all that content and indexed it. By the late ’90s that meant choosing from a variety of search engines: AltaVista and AlltheWeb and WebCrawler and HotBot. And they were good—a huge improvement. At least at first.   But alongside the rise of search engines came the first attempts to exploit their ability to deliver traffic. Precious, valuable traffic, which web publishers rely on to sell ads and retailers use to get eyeballs on their goods. Sometimes this meant stuffing pages with keywords or nonsense text designed purely to push pages higher up in search results. It got pretty bad.  And then came Google. It’s hard to overstate how revolutionary Google was when it launched in 1998. Rather than just scanning the content, it also looked at the sources linking to a website, which helped evaluate its relevance. To oversimplify: The more something was cited elsewhere, the more reliable Google considered it, and the higher it would appear in results. This breakthrough made Google radically better at retrieving relevant results than anything that had come before. It was amazing.  Google CEO Sundar Pichai describes AI Overviews as “one of the most positive changes we’ve done to search in a long, long time.”JENS GYARMATY/LAIF/REDUX For 25 years, Google dominated search. Google was search, for most people. (The extent of that domination is currently the subject of multiple legal probes in the United States and the European Union.)   But Google has long been moving away from simply serving up a series of blue links, notes Pandu Nayak, Google’s chief scientist for search.  “It’s not just so-called web results, but there are images and videos, and special things for news. There have been direct answers, dictionary answers, sports, answers that come with Knowledge Graph, things like featured snippets,” he says, rattling off a litany of Google’s steps over the years to answer questions more directly.  It’s true: Google has evolved over time, becoming more and more of an answer portal. It has added tools that allow people to just get an answer—the live score to a game, the hours a café is open, or a snippet from the FDA’s website—rather than being pointed to a website where the answer may be.  But once you’ve used AI Overviews a bit, you realize they are different.  Take featured snippets, the passages Google sometimes chooses to highlight and show atop the results themselves. Those words are quoted directly from an original source. The same is true of knowledge panels, which are generated from information stored in a range of public databases and Google’s Knowledge Graph, its database of trillions of facts about the world. While these can be inaccurate, the information source is knowable (and fixable). It’s in a database. You can look it up. Not anymore: AI Overviews can be entirely new every time, generated on the fly by a language model’s predictive text combined with an index of the web.  “I think it’s an exciting moment where we have obviously indexed the world. We built deep understanding on top of it with Knowledge Graph. We’ve been using LLMs and generative AI to improve our understanding of all that,” Pichai told MIT Technology Review. “But now we are able to generate and compose with that.” The result feels less like a querying a database than like asking a very smart, well-read friend. (With the caveat that the friend will sometimes make things up if she does not know the answer.)  “[The company’s] mission is organizing the world’s information,” Liz Reid, Google’s head of search, tells me from its headquarters in Mountain View, California. “But actually, for a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you.”  That second concept—accessibility—is what Google is really keying in on with AI Overviews. It’s a sentiment I hear echoed repeatedly while talking to Google execs: They can address more complicated types of queries more efficiently by bringing in a language model to help supply the answers. And they can do it in natural language.  That will become even more important for a future where search goes beyond text queries. For example, Google Lens, which lets people take a picture or upload an image to find out more about something, uses AI-generated answers to tell you what you may be looking at. Google has even showed off the ability to query live video.  When it doesn’t have an answer, an AI model can confidently spew back a response anyway. For Google, this could be a real problem. For the rest of us, it could actually be dangerous. “We are definitely at the start of a journey where people are going to be able to ask, and get answered, much more complex questions than where we’ve been in the past decade,” says Pichai.  There are some real hazards here. First and foremost: Large language models will lie to you. They hallucinate. They get shit wrong. When it doesn’t have an answer, an AI model can blithely and confidently spew back a response anyway. For Google, which has built its reputation over the past 20 years on reliability, this could be a real problem. For the rest of us, it could actually be dangerous. In May 2024, AI Overviews were rolled out to everyone in the US. Things didn’t go well. Google, long the world’s reference desk, told people to eat rocks and to put glue on their pizza. These answers were mostly in response to what the company calls adversarial queries—those designed to trip it up. But still. It didn’t look good. The company quickly went to work fixing the problems—for example, by deprecating so-called user-generated content from sites like Reddit, where some of the weirder answers had come from. Yet while its errors telling people to eat rocks got all the attention, the more pernicious danger might arise when it gets something less obviously wrong. For example, in doing research for this article, I asked Google when MIT Technology Review went online. It helpfully responded that “MIT Technology Review launched its online presence in late 2022.” This was clearly wrong to me, but for someone completely unfamiliar with the publication, would the error leap out?  I came across several examples like this, both in Google and in OpenAI’s ChatGPT search. Stuff that’s just far enough off the mark not to be immediately seen as wrong. Google is banking that it can continue to improve these results over time by relying on what it knows about quality sources. “When we produce AI Overviews,” says Nayak, “we look for corroborating information from the search results, and the search results themselves are designed to be from these reliable sources whenever possible. These are some of the mechanisms we have in place that assure that if you just consume the AI Overview, and you don’t want to look further … we hope that you will still get a reliable, trustworthy answer.” In the case above, the 2022 answer seemingly came from a reliable source—a story about MIT Technology Review’s email newsletters, which launched in 2022. But the machine fundamentally misunderstood. This is one of the reasons Google uses human beings—raters—to evaluate the results it delivers for accuracy. Ratings don’t correct or control individual AI Overviews; rather, they help train the model to build better answers. But human raters can be fallible. Google is working on that too.  “Raters who look at your experiments may not notice the hallucination because it feels sort of natural,” says Nayak. “And so you have to really work at the evaluation setup to make sure that when there is a hallucination, someone’s able to point out and say, That’s a problem.” The new search Google has rolled out its AI Overviews to upwards of a billion people in more than 100 countries, but it is facing upstarts with new ideas about how search should work. Search Engine GoogleThe search giant has added AI Overviews to search results. These overviews take information from around the web and Google’s Knowledge Graph and use the company’s Gemini language model to create answers to search queries. What it’s good at Google’s AI Overviews are great at giving an easily digestible summary in response to even the most complex queries, with sourcing boxes adjacent to the answers. Among the major options, its deep web index feels the most “internety.” But web publishers fear its summaries will give people little reason to click through to the source material. PerplexityPerplexity is a conversational search engine that uses third-party largelanguage models from OpenAI and Anthropic to answer queries. Perplexity is fantastic at putting together deeper dives in response to user queries, producing answers that are like mini white papers on complex topics. It’s also excellent at summing up current events. But it has gotten a bad rep with publishers, who say it plays fast and loose with their content. ChatGPTWhile Google brought AI to search, OpenAI brought search to ChatGPT. Queries that the model determines will benefit from a web search automatically trigger one, or users can manually select the option to add a web search. Thanks to its ability to preserve context across a conversation, ChatGPT works well for performing searches that benefit from follow-up questions—like planning a vacation through multiple search sessions. OpenAI says users sometimes go “20 turns deep” in researching queries. Of these three, it makes links out to publishers least prominent. When I talked to Pichai about this, he expressed optimism about the company’s ability to maintain accuracy even with the LLM generating responses. That’s because AI Overviews is based on Google’s flagship large language model, Gemini, but also draws from Knowledge Graph and what it considers reputable sources around the web.  “You’re always dealing in percentages. What we have done is deliver it at, like, what I would call a few nines of trust and factuality and quality. I’d say 99-point-few-nines. I think that’s the bar we operate at, and it is true with AI Overviews too,” he says. “And so the question is, are we able to do this again at scale? And I think we are.” There’s another hazard as well, though, which is that people ask Google all sorts of weird things. If you want to know someone’s darkest secrets, look at their search history. Sometimes the things people ask Google about are extremely dark. Sometimes they are illegal. Google doesn’t just have to be able to deploy its AI Overviews when an answer can be helpful; it has to be extremely careful not to deploy them when an answer may be harmful.  “If you go and say ‘How do I build a bomb?’ it’s fine that there are web results. It’s the open web. You can access anything,” Reid says. “But we do not need to have an AI Overview that tells you how to build a bomb, right? We just don’t think that’s worth it.”  But perhaps the greatest hazard—or biggest unknown—is for anyone downstream of a Google search. Take publishers, who for decades now have relied on search queries to send people their way. What reason will people have to click through to the original source, if all the information they seek is right there in the search result?   Rand Fishkin, cofounder of the market research firm SparkToro, publishes research on so-called zero-click searches. As Google has moved increasingly into the answer business, the proportion of searches that end without a click has gone up and up. His sense is that AI Overviews are going to explode this trend.   “If you are reliant on Google for traffic, and that traffic is what drove your business forward, you are in long- and short-term trouble,” he says.  Don’t panic, is Pichai’s message. He argues that even in the age of AI Overviews, people will still want to click through and go deeper for many types of searches. “The underlying principle is people are coming looking for information. They’re not looking for Google always to just answer,” he says. “Sometimes yes, but the vast majority of the times, you’re looking at it as a jumping-off point.”  Reid, meanwhile, argues that because AI Overviews allow people to ask more complicated questions and drill down further into what they want, they could even be helpful to some types of publishers and small businesses, especially those operating in the niches: “You essentially reach new audiences, because people can now express what they want more specifically, and so somebody who specializes doesn’t have to rank for the generic query.”  “I’m going to start with something risky,” Nick Turley tells me from the confines of a Zoom window. Turley is the head of product for ChatGPT, and he’s showing off OpenAI’s new web search tool a few weeks before it launches. “I should normally try this beforehand, but I’m just gonna search for you,” he says. “This is always a high-risk demo to do, because people tend to be particular about what is said about them on the internet.”  He types my name into a search field, and the prototype search engine spits back a few sentences, almost like a speaker bio. It correctly identifies me and my current role. It even highlights a particular story I wrote years ago that was probably my best known. In short, it’s the right answer. Phew?  A few weeks after our call, OpenAI incorporated search into ChatGPT, supplementing answers from its language model with information from across the web. If the model thinks a response would benefit from up-to-date information, it will automatically run a web search (OpenAI won’t say who its search partners are) and incorporate those responses into its answer, with links out if you want to learn more. You can also opt to manually force it to search the web if it does not do so on its own. OpenAI won’t reveal how many people are using its web search, but it says some 250 million people use ChatGPT weekly, all of whom are potentially exposed to it.   “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be a better super-assistant for you.” Kevin Weil, chief product officer, OpenAI According to Fishkin, these newer forms of AI-assisted search aren’t yet challenging Google’s search dominance. “It does not appear to be cannibalizing classic forms of web search,” he says.  OpenAI insists it’s not really trying to compete on search—although frankly this seems to me like a bit of expectation setting. Rather, it says, web search is mostly a means to get more current information than the data in its training models, which tend to have specific cutoff dates that are often months, or even a year or more, in the past. As a result, while ChatGPT may be great at explaining how a West Coast offense works, it has long been useless at telling you what the latest 49ers score is. No more.  “I come at it from the perspective of ‘How can we make ChatGPT able to answer every question that you have? How can we make it more useful to you on a daily basis?’ And that’s where search comes in for us,” Kevin Weil, the chief product officer with OpenAI, tells me. “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be able to be a better super-assistant for you.” Today ChatGPT is able to generate responses for very current news events, as well as near-real-time information on things like stock prices. And while ChatGPT’s interface has long been, well, boring, search results bring in all sorts of multimedia—images, graphs, even video. It’s a very different experience.  Weil also argues that ChatGPT has more freedom to innovate and go its own way than competitors like Google—even more than its partner Microsoft does with Bing. Both of those are ad-dependent businesses. OpenAI is not. (At least not yet.) It earns revenue from the developers, businesses, and individuals who use it directly. It’s mostly setting large amounts of money on fire right now—it’s projected to lose $14 billion in 2026, by some reports. But one thing it doesn’t have to worry about is putting ads in its search results as Google does.  “For a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you,” says Google head of search, Liz Reid.WINNI WINTERMEYER/REDUX Like Google, ChatGPT is pulling in information from web publishers, summarizing it, and including it in its answers. But it has also struck financial deals with publishers, a payment for providing the information that gets rolled into its results. (MIT Technology Review has been in discussions with OpenAI, Google, Perplexity, and others about publisher deals but has not entered into any agreements. Editorial was neither party to nor informed about the content of those discussions.) But the thing is, for web search to accomplish what OpenAI wants—to be more current than the language model—it also has to bring in information from all sorts of publishers and sources that it doesn’t have deals with. OpenAI’s head of media partnerships, Varun Shetty, told MIT Technology Review that it won’t give preferential treatment to its publishing partners. Instead, OpenAI told me, the model itself finds the most trustworthy and useful source for any given question. And that can get weird too. In that very first example it showed me—when Turley ran that name search—it described a story I wrote years ago for Wired about being hacked. That story remains one of the most widely read I’ve ever written. But ChatGPT didn’t link to it. It linked to a short rewrite from The Verge. Admittedly, this was on a prototype version of search, which was, as Turley said, “risky.”  When I asked him about it, he couldn’t really explain why the model chose the sources that it did, because the model itself makes that evaluation. The company helps steer it by identifying—sometimes with the help of users—what it considers better answers, but the model actually selects them.  “And in many cases, it gets it wrong, which is why we have work to do,” said Turley. “Having a model in the loop is a very, very different mechanism than how a search engine worked in the past.” Indeed!  The model, whether it’s OpenAI’s GPT-4o or Google’s Gemini or Anthropic’s Claude, can be very, very good at explaining things. But the rationale behind its explanations, its reasons for selecting a particular source, and even the language it may use in an answer are all pretty mysterious. Sure, a model can explain very many things, but not when that comes to its own answers.  It was almost a decade ago, in 2016, when Pichai wrote that Google was moving from “mobile first” to “AI first”: “But in the next 10 years, we will shift to a world that is AI-first, a world where computing becomes universally available—be it at home, at work, in the car, or on the go—and interacting with all of these surfaces becomes much more natural and intuitive, and above all, more intelligent.”  We’re there now—sort of. And it’s a weird place to be. It’s going to get weirder. That’s especially true as these things we now think of as distinct—querying a search engine, prompting a model, looking for a photo we’ve taken, deciding what we want to read or watch or hear, asking for a photo we wish we’d taken, and didn’t, but would still like to see—begin to merge.  The search results we see from generative AI are best understood as a waypoint rather than a destination. What’s most important may not be search in itself; rather, it’s that search has given AI model developers a path to incorporating real-time information into their inputs and outputs. And that opens up all sorts of possibilities. “A ChatGPT that can understand and access the web won’t just be about summarizing results. It might be about doing things for you. And I think there’s a fairly exciting future there,” says OpenAI’s Weil. “You can imagine having the model book you a flight, or order DoorDash, or just accomplish general tasks for you in the future. It’s just once the model understands how to use the internet, the sky’s the limit.” This is the agentic future we’ve been hearing about for some time now, and the more AI models make use of real-time data from the internet, the closer it gets.  Let’s say you have a trip coming up in a few weeks. An agent that can get data from the internet in real time can book your flights and hotel rooms, make dinner reservations, and more, based on what it knows about you and your upcoming travel—all without your having to guide it. Another agent could, say, monitor the sewage output of your home for certain diseases, and order tests and treatments in response. You won’t have to search for that weird noise your car is making, because the agent in your vehicle will already have done it and made an appointment to get the issue fixed.  “It’s not always going to be just doing search and giving answers,” says Pichai. “Sometimes it’s going to be actions. Sometimes you’ll be interacting within the real world. So there is a notion of universal assistance through it all.” And the ways these things will be able to deliver answers is evolving rapidly now too. For example, today Google can not only search text, images, and even video; it can create them. Imagine overlaying that ability with search across an array of formats and devices. “Show me what a Townsend’s warbler looks like in the tree in front of me.” Or “Use my existing family photos and videos to create a movie trailer of our upcoming vacation to Puerto Rico next year, making sure we visit all the best restaurants and top landmarks.” “We have primarily done it on the input side,” he says, referring to the ways Google can now search for an image or within a video. “But you can imagine it on the output side too.” This is the kind of future Pichai says he is excited to bring online. Google has already showed off a bit of what that might look like with NotebookLM, a tool that lets you upload large amounts of text and have it converted into a chatty podcast. He imagines this type of functionality—the ability to take one type of input and convert it into a variety of outputs—transforming the way we interact with information.  In a demonstration of a tool called Project Astra this summer at its developer conference, Google showed one version of this outcome, where cameras and microphones in phones and smart glasses understand the context all around you—online and off, audible and visual—and have the ability to recall and respond in a variety of ways. Astra can, for example, look at a crude drawing of a Formula One race car and not only identify it, but also explain its various parts and their uses.  But you can imagine things going a bit further (and they will). Let’s say I want to see a video of how to fix something on my bike. The video doesn’t exist, but the information does. AI-assisted generative search could theoretically find that information somewhere online—in a user manual buried in a company’s website, for example—and create a video to show me exactly how to do what I want, just as it could explain that to me with words today. These are the kinds of things that start to happen when you put the entire compendium of human knowledge—knowledge that’s previously been captured in silos of language and format; maps and business registrations and product SKUs; audio and video and databases of numbers and old books and images and, really, anything ever published, ever tracked, ever recorded; things happening right now, everywhere—and introduce a model into all that. A model that maybe can’t understand, precisely, but has the ability to put that information together, rearrange it, and spit it back in a variety of different hopefully helpful ways. Ways that a mere index could not. That’s what we’re on the cusp of, and what we’re starting to see. And as Google rolls this out to a billion people, many of whom will be interacting with a conversational AI for the first time, what will that mean? What will we do differently? It’s all changing so quickly. Hang on, just hang on. 
We all know what it means, colloquially, to google something. You pop a few relevant words in a search box and in return get a list of blue links to the most relevant results. Maybe some quick explanations up top. Maybe some maps or sports scores or a video. But fundamentally, it’s just fetching information that’s already out there on the internet and showing it to you, in some sort of structured way. 

But all that is up for grabs. We are at a new inflection point.

The biggest change to the way search engines have delivered information to us since the 1990s is happening right now. No more keyword searching. No more sorting through links to click. Instead, we’re entering an era of conversational search. Which means instead of keywords, you use real questions, expressed in natural language. And instead of links, you’ll increasingly be met with answers, written by generative AI and based on live information from all across the internet, delivered the same way. 

Of course, Google—the company that has defined search for the past 25 years—is trying to be out front on this. In May of 2023, it began testing AI-generated responses to search queries, using its large language model (LLM) to deliver the kinds of answers you might expect from an expert source or trusted friend. It calls these AI Overviews. Google CEO Sundar Pichai described this to MIT Technology Review as “one of the most positive changes we’ve done to search in a long, long time.”

AI Overviews fundamentally change the kinds of queries Google can address. You can now ask it things like “I’m going to Japan for one week next month. I’ll be staying in Tokyo but would like to take some day trips. Are there any festivals happening nearby? How will the surfing be in Kamakura? Are there any good bands playing?” And you’ll get an answer—not just a link to Reddit, but a built-out answer with current results. 

More to the point, you can attempt searches that were once pretty much impossible, and get the right answer. You don’t have to be able to articulate what, precisely, you are looking for. You can describe what the bird in your yard looks like, or what the issue seems to be with your refrigerator, or that weird noise your car is making, and get an almost human explanation put together from sources previously siloed across the internet. It’s amazing, and once you start searching that way, it’s addictive.

And it’s not just Google. OpenAI’s ChatGPT now has access to the web, making it far better at finding up-to-date answers to your queries. Microsoft released generative search results for Bing in September. Meta has its own version. The startup Perplexity was doing the same, but with a “move fast, break things” ethos. Literal trillions of dollars are at stake in the outcome as these players jockey to become the next go-to source for information retrieval—the next Google.

Not everyone is excited for the change. Publishers are completely freaked out. The shift has heightened fears of a “zero-click” future, where search referral traffic—a mainstay of the web since before Google existed—vanishes from the scene. 

I got a vision of that future last June, when I got a push alert from the Perplexity app on my phone. Perplexity is a startup trying to reinvent web search. But in addition to delivering deep answers to queries, it will create entire articles about the news of the day, cobbled together by AI from different sources. 

On that day, it pushed me a story about a new drone company from Eric Schmidt. I recognized the story. Forbes had reported it exclusively, earlier in the week, but it had been locked behind a paywall. The image on Perplexity’s story looked identical to one from Forbes. The language and structure were quite similar. It was effectively the same story, but freely available to anyone on the internet. I texted a friend who had edited the original story to ask if Forbes had a deal with the startup to republish its content. But there was no deal. He was shocked and furious and, well, perplexed. He wasn’t alone. Forbes, the New York Times, and Condé Nast have now all sent the company cease-and-desist orders. News Corp is suing for damages. 

People are worried about what these new LLM-powered results will mean for our fundamental shared reality. It could spell the end of the canonical answer.

It was precisely the nightmare scenario publishers have been so afraid of: The AI was hoovering up their premium content, repackaging it, and promoting it to its audience in a way that didn’t really leave any reason to click through to the original. In fact, on Perplexity’s About page, the first reason it lists to choose the search engine is “Skip the links.”

But this isn’t just about publishers (or my own self-interest). 

People are also worried about what these new LLM-powered results will mean for our fundamental shared reality. Language models have a tendency to make stuff up—they can hallucinate nonsense. Moreover, generative AI can serve up an entirely new answer to the same question every time, or provide different answers to different people on the basis of what it knows about them. It could spell the end of the canonical answer.

But make no mistake: This is the future of search. Try it for a bit yourself, and you’ll see. 

Sure, we will always want to use search engines to navigate the web and to discover new and interesting sources of information. But the links out are taking a back seat. The way AI can put together a well-reasoned answer to just about any kind of question, drawing on real-time data from across the web, just offers a better experience. That is especially true compared with what web search has become in recent years. If it’s not exactly broken (data shows more people are searching with Google more often than ever before), it’s at the very least increasingly cluttered and daunting to navigate. 

Who wants to have to speak the language of search engines to find what you need? Who wants to navigate links when you can have straight answers? And maybe: Who wants to have to learn when you can just know? 


In the beginning there was Archie. It was the first real internet search engine, and it crawled files previously hidden in the darkness of remote servers. It didn’t tell you what was in those files—just their names. It didn’t preview images; it didn’t have a hierarchy of results, or even much of an interface. But it was a start. And it was pretty good. 

Then Tim Berners-Lee created the World Wide Web, and all manner of web pages sprang forth. The Mosaic home page and the Internet Movie Database and Geocities and the Hampster Dance and web rings and Salon and eBay and CNN and federal government sites and some guy’s home page in Turkey.

Until finally, there was too much web to even know where to start. We really needed a better way to navigate our way around, to actually find the things we needed. 

And so in 1994 Jerry Yang created Yahoo, a hierarchical directory of websites. It quickly became the home page for millions of people. And it was … well, it was okay. TBH, and with the benefit of hindsight, I think we all thought it was much better back then than it actually was.

But the web continued to grow and sprawl and expand, every day bringing more information online. Rather than just a list of sites by category, we needed something that actually looked at all that content and indexed it. By the late ’90s that meant choosing from a variety of search engines: AltaVista and AlltheWeb and WebCrawler and HotBot. And they were good—a huge improvement. At least at first.  

But alongside the rise of search engines came the first attempts to exploit their ability to deliver traffic. Precious, valuable traffic, which web publishers rely on to sell ads and retailers use to get eyeballs on their goods. Sometimes this meant stuffing pages with keywords or nonsense text designed purely to push pages higher up in search results. It got pretty bad. 

And then came Google. It’s hard to overstate how revolutionary Google was when it launched in 1998. Rather than just scanning the content, it also looked at the sources linking to a website, which helped evaluate its relevance. To oversimplify: The more something was cited elsewhere, the more reliable Google considered it, and the higher it would appear in results. This breakthrough made Google radically better at retrieving relevant results than anything that had come before. It was amazing. 

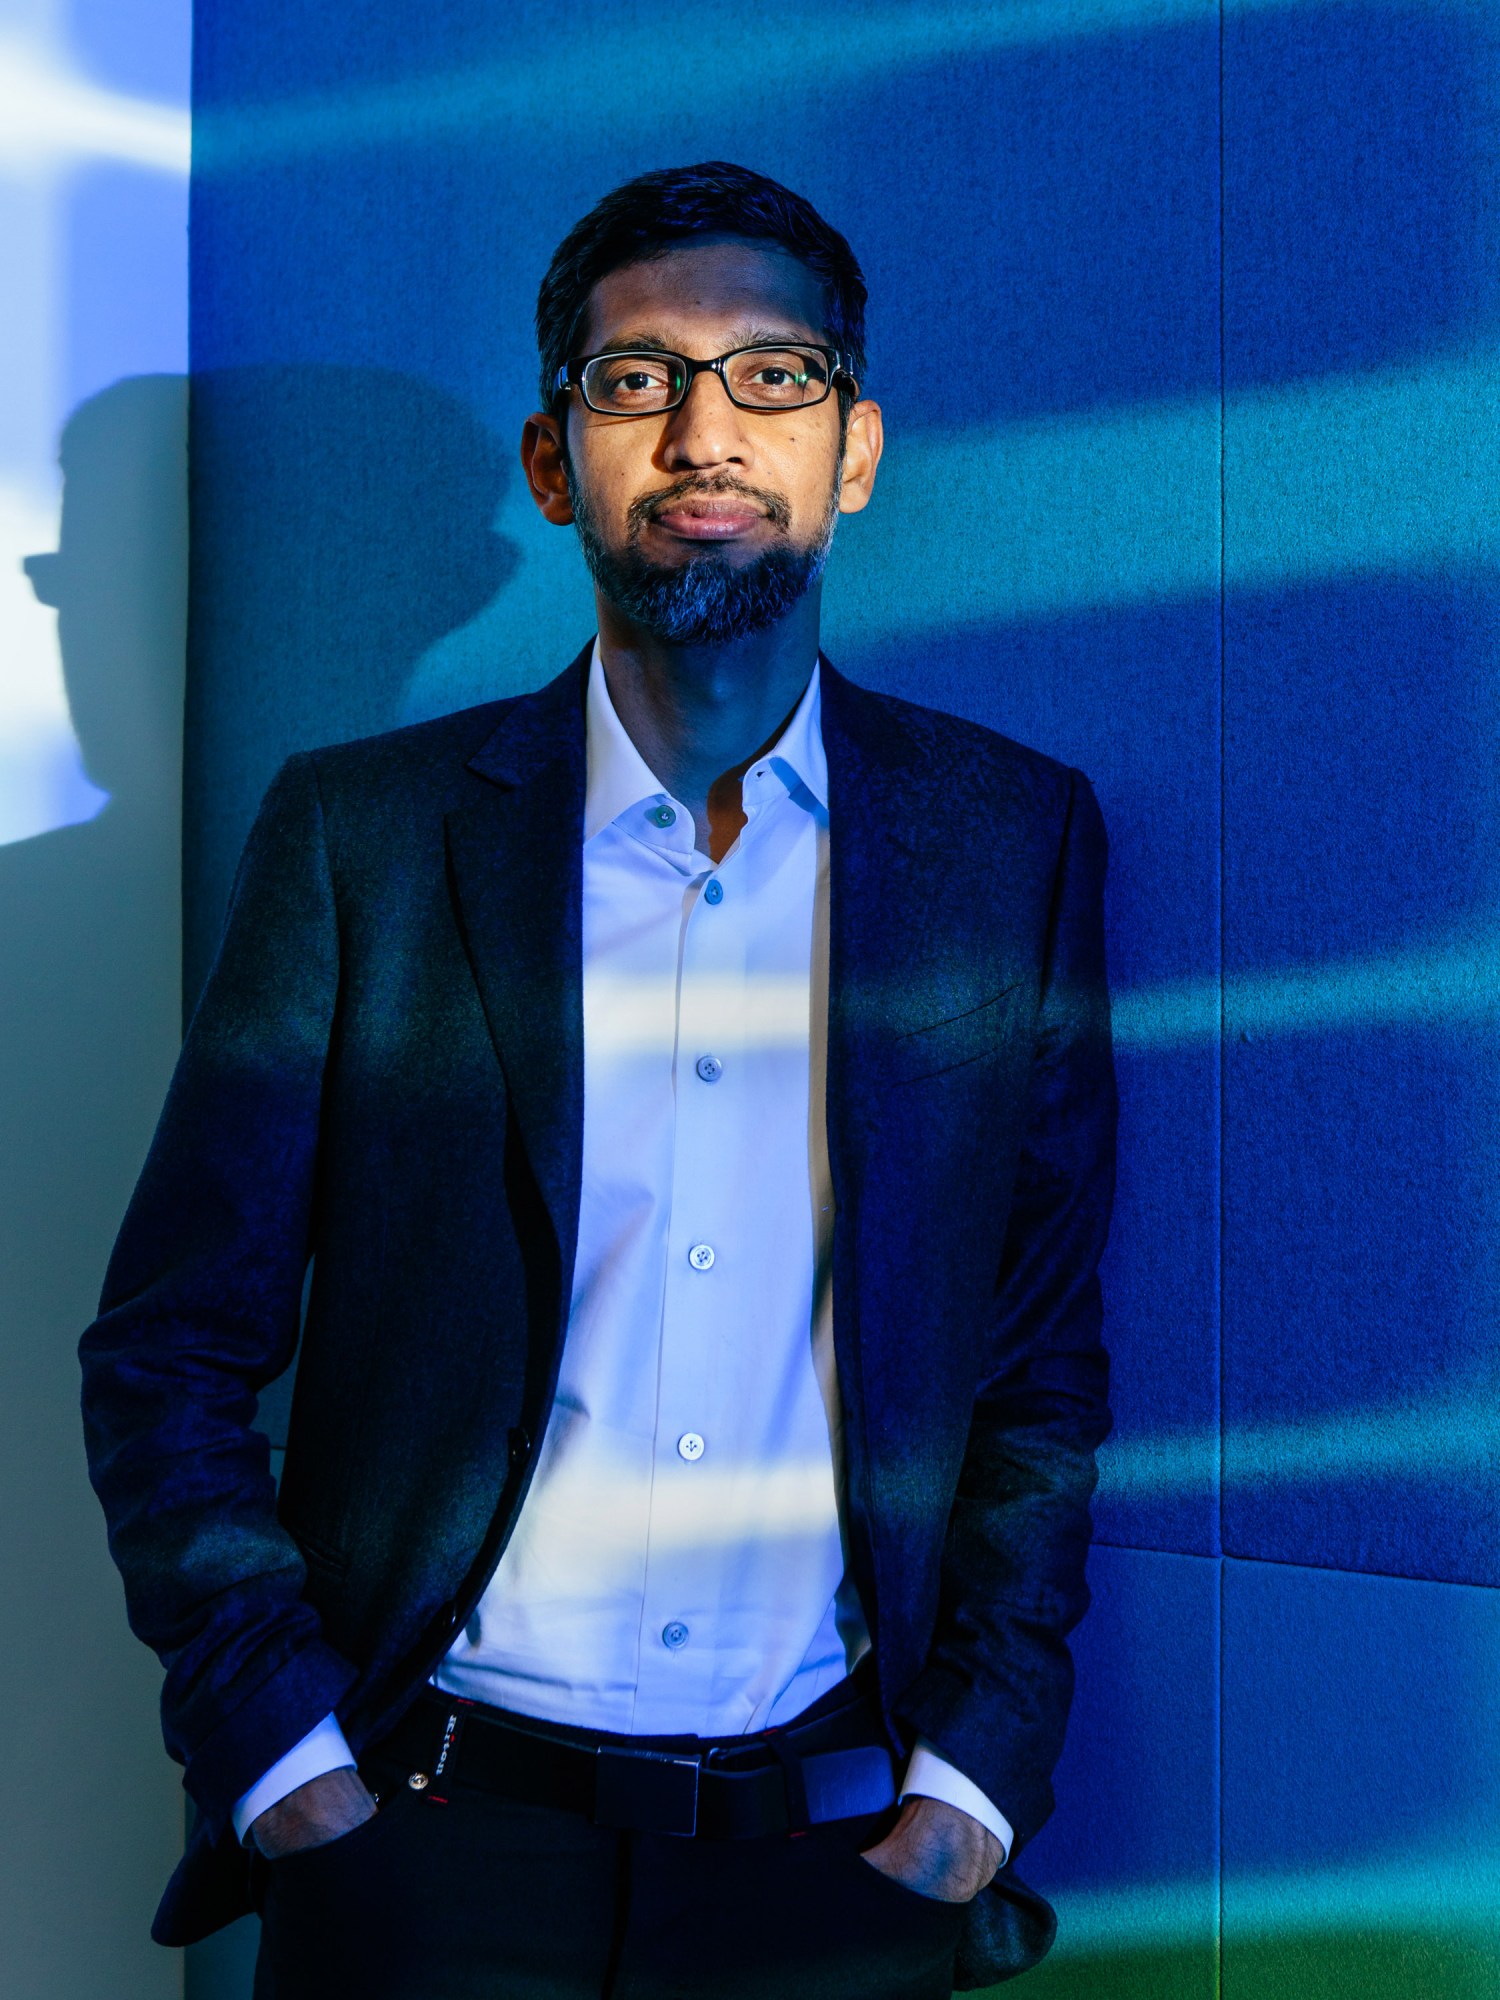
Sundar Pichai
Google CEO Sundar Pichai describes AI Overviews as “one of the most positive changes we’ve done to search in a long, long time.”
JENS GYARMATY/LAIF/REDUX

For 25 years, Google dominated search. Google was search, for most people. (The extent of that domination is currently the subject of multiple legal probes in the United States and the European Union.)  

But Google has long been moving away from simply serving up a series of blue links, notes Pandu Nayak, Google’s chief scientist for search. 

“It’s not just so-called web results, but there are images and videos, and special things for news. There have been direct answers, dictionary answers, sports, answers that come with Knowledge Graph, things like featured snippets,” he says, rattling off a litany of Google’s steps over the years to answer questions more directly. 

It’s true: Google has evolved over time, becoming more and more of an answer portal. It has added tools that allow people to just get an answer—the live score to a game, the hours a café is open, or a snippet from the FDA’s website—rather than being pointed to a website where the answer may be. 

But once you’ve used AI Overviews a bit, you realize they are different. 

Take featured snippets, the passages Google sometimes chooses to highlight and show atop the results themselves. Those words are quoted directly from an original source. The same is true of knowledge panels, which are generated from information stored in a range of public databases and Google’s Knowledge Graph, its database of trillions of facts about the world.

While these can be inaccurate, the information source is knowable (and fixable). It’s in a database. You can look it up. Not anymore: AI Overviews can be entirely new every time, generated on the fly by a language model’s predictive text combined with an index of the web. 

“I think it’s an exciting moment where we have obviously indexed the world. We built deep understanding on top of it with Knowledge Graph. We’ve been using LLMs and generative AI to improve our understanding of all that,” Pichai told MIT Technology Review. “But now we are able to generate and compose with that.”

The result feels less like a querying a database than like asking a very smart, well-read friend. (With the caveat that the friend will sometimes make things up if she does not know the answer.) 

“[The company’s] mission is organizing the world’s information,” Liz Reid, Google’s head of search, tells me from its headquarters in Mountain View, California. “But actually, for a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you.” 

That second concept—accessibility—is what Google is really keying in on with AI Overviews. It’s a sentiment I hear echoed repeatedly while talking to Google execs: They can address more complicated types of queries more efficiently by bringing in a language model to help supply the answers. And they can do it in natural language. 

That will become even more important for a future where search goes beyond text queries. For example, Google Lens, which lets people take a picture or upload an image to find out more about something, uses AI-generated answers to tell you what you may be looking at. Google has even showed off the ability to query live video. 

When it doesn’t have an answer, an AI model can confidently spew back a response anyway. For Google, this could be a real problem. For the rest of us, it could actually be dangerous.

“We are definitely at the start of a journey where people are going to be able to ask, and get answered, much more complex questions than where we’ve been in the past decade,” says Pichai. 

There are some real hazards here. First and foremost: Large language models will lie to you. They hallucinate. They get shit wrong. When it doesn’t have an answer, an AI model can blithely and confidently spew back a response anyway. For Google, which has built its reputation over the past 20 years on reliability, this could be a real problem. For the rest of us, it could actually be dangerous.

In May 2024, AI Overviews were rolled out to everyone in the US. Things didn’t go well. Google, long the world’s reference desk, told people to eat rocks and to put glue on their pizza. These answers were mostly in response to what the company calls adversarial queries—those designed to trip it up. But still. It didn’t look good. The company quickly went to work fixing the problems—for example, by deprecating so-called user-generated content from sites like Reddit, where some of the weirder answers had come from.

Yet while its errors telling people to eat rocks got all the attention, the more pernicious danger might arise when it gets something less obviously wrong. For example, in doing research for this article, I asked Google when MIT Technology Review went online. It helpfully responded that “MIT Technology Review launched its online presence in late 2022.” This was clearly wrong to me, but for someone completely unfamiliar with the publication, would the error leap out? 

I came across several examples like this, both in Google and in OpenAI’s ChatGPT search. Stuff that’s just far enough off the mark not to be immediately seen as wrong. Google is banking that it can continue to improve these results over time by relying on what it knows about quality sources.

“When we produce AI Overviews,” says Nayak, “we look for corroborating information from the search results, and the search results themselves are designed to be from these reliable sources whenever possible. These are some of the mechanisms we have in place that assure that if you just consume the AI Overview, and you don’t want to look further … we hope that you will still get a reliable, trustworthy answer.”

In the case above, the 2022 answer seemingly came from a reliable source—a story about MIT Technology Review’s email newsletters, which launched in 2022. But the machine fundamentally misunderstood. This is one of the reasons Google uses human beings—raters—to evaluate the results it delivers for accuracy. Ratings don’t correct or control individual AI Overviews; rather, they help train the model to build better answers. But human raters can be fallible. Google is working on that too. 

“Raters who look at your experiments may not notice the hallucination because it feels sort of natural,” says Nayak. “And so you have to really work at the evaluation setup to make sure that when there is a hallucination, someone’s able to point out and say, That’s a problem.”

The new search

Google has rolled out its AI Overviews to upwards of a billion people in more than 100 countries, but it is facing upstarts with new ideas about how search should work.


Search Engine

Google
The search giant has added AI Overviews to search results. These overviews take information from around the web and Google’s Knowledge Graph and use the company’s Gemini language model to create answers to search queries.

What it’s good at

Google’s AI Overviews are great at giving an easily digestible summary in response to even the most complex queries, with sourcing boxes adjacent to the answers. Among the major options, its deep web index feels the most “internety.” But web publishers fear its summaries will give people little reason to click through to the source material.


Perplexity
Perplexity is a conversational search engine that uses third-party large
language models from OpenAI and Anthropic to answer queries.

Perplexity is fantastic at putting together deeper dives in response to user queries, producing answers that are like mini white papers on complex topics. It’s also excellent at summing up current events. But it has gotten a bad rep with publishers, who say it plays fast and loose with their content.


ChatGPT
While Google brought AI to search, OpenAI brought search to ChatGPT. Queries that the model determines will benefit from a web search automatically trigger one, or users can manually select the option to add a web search.

Thanks to its ability to preserve context across a conversation, ChatGPT works well for performing searches that benefit from follow-up questions—like planning a vacation through multiple search sessions. OpenAI says users sometimes go “20 turns deep” in researching queries. Of these three, it makes links out to publishers least prominent.


When I talked to Pichai about this, he expressed optimism about the company’s ability to maintain accuracy even with the LLM generating responses. That’s because AI Overviews is based on Google’s flagship large language model, Gemini, but also draws from Knowledge Graph and what it considers reputable sources around the web. 

“You’re always dealing in percentages. What we have done is deliver it at, like, what I would call a few nines of trust and factuality and quality. I’d say 99-point-few-nines. I think that’s the bar we operate at, and it is true with AI Overviews too,” he says. “And so the question is, are we able to do this again at scale? And I think we are.”

There’s another hazard as well, though, which is that people ask Google all sorts of weird things. If you want to know someone’s darkest secrets, look at their search history. Sometimes the things people ask Google about are extremely dark. Sometimes they are illegal. Google doesn’t just have to be able to deploy its AI Overviews when an answer can be helpful; it has to be extremely careful not to deploy them when an answer may be harmful. 

“If you go and say ‘How do I build a bomb?’ it’s fine that there are web results. It’s the open web. You can access anything,” Reid says. “But we do not need to have an AI Overview that tells you how to build a bomb, right? We just don’t think that’s worth it.” 

But perhaps the greatest hazard—or biggest unknown—is for anyone downstream of a Google search. Take publishers, who for decades now have relied on search queries to send people their way. What reason will people have to click through to the original source, if all the information they seek is right there in the search result?  

Rand Fishkin, cofounder of the market research firm SparkToro, publishes research on so-called zero-click searches. As Google has moved increasingly into the answer business, the proportion of searches that end without a click has gone up and up. His sense is that AI Overviews are going to explode this trend.  

“If you are reliant on Google for traffic, and that traffic is what drove your business forward, you are in long- and short-term trouble,” he says. 

Don’t panic, is Pichai’s message. He argues that even in the age of AI Overviews, people will still want to click through and go deeper for many types of searches. “The underlying principle is people are coming looking for information. They’re not looking for Google always to just answer,” he says. “Sometimes yes, but the vast majority of the times, you’re looking at it as a jumping-off point.” 

Reid, meanwhile, argues that because AI Overviews allow people to ask more complicated questions and drill down further into what they want, they could even be helpful to some types of publishers and small businesses, especially those operating in the niches: “You essentially reach new audiences, because people can now express what they want more specifically, and so somebody who specializes doesn’t have to rank for the generic query.”


 “I’m going to start with something risky,” Nick Turley tells me from the confines of a Zoom window. Turley is the head of product for ChatGPT, and he’s showing off OpenAI’s new web search tool a few weeks before it launches. “I should normally try this beforehand, but I’m just gonna search for you,” he says. “This is always a high-risk demo to do, because people tend to be particular about what is said about them on the internet.” 

He types my name into a search field, and the prototype search engine spits back a few sentences, almost like a speaker bio. It correctly identifies me and my current role. It even highlights a particular story I wrote years ago that was probably my best known. In short, it’s the right answer. Phew? 

A few weeks after our call, OpenAI incorporated search into ChatGPT, supplementing answers from its language model with information from across the web. If the model thinks a response would benefit from up-to-date information, it will automatically run a web search (OpenAI won’t say who its search partners are) and incorporate those responses into its answer, with links out if you want to learn more. You can also opt to manually force it to search the web if it does not do so on its own. OpenAI won’t reveal how many people are using its web search, but it says some 250 million people use ChatGPT weekly, all of whom are potentially exposed to it.  

“There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be a better super-assistant for you.”

Kevin Weil, chief product officer, OpenAI

According to Fishkin, these newer forms of AI-assisted search aren’t yet challenging Google’s search dominance. “It does not appear to be cannibalizing classic forms of web search,” he says. 

OpenAI insists it’s not really trying to compete on search—although frankly this seems to me like a bit of expectation setting. Rather, it says, web search is mostly a means to get more current information than the data in its training models, which tend to have specific cutoff dates that are often months, or even a year or more, in the past. As a result, while ChatGPT may be great at explaining how a West Coast offense works, it has long been useless at telling you what the latest 49ers score is. No more. 

“I come at it from the perspective of ‘How can we make ChatGPT able to answer every question that you have? How can we make it more useful to you on a daily basis?’ And that’s where search comes in for us,” Kevin Weil, the chief product officer with OpenAI, tells me. “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be able to be a better super-assistant for you.”

Today ChatGPT is able to generate responses for very current news events, as well as near-real-time information on things like stock prices. And while ChatGPT’s interface has long been, well, boring, search results bring in all sorts of multimedia—images, graphs, even video. It’s a very different experience. 

Weil also argues that ChatGPT has more freedom to innovate and go its own way than competitors like Google—even more than its partner Microsoft does with Bing. Both of those are ad-dependent businesses. OpenAI is not. (At least not yet.) It earns revenue from the developers, businesses, and individuals who use it directly. It’s mostly setting large amounts of money on fire right now—it’s projected to lose $14 billion in 2026, by some reports. But one thing it doesn’t have to worry about is putting ads in its search results as Google does. 

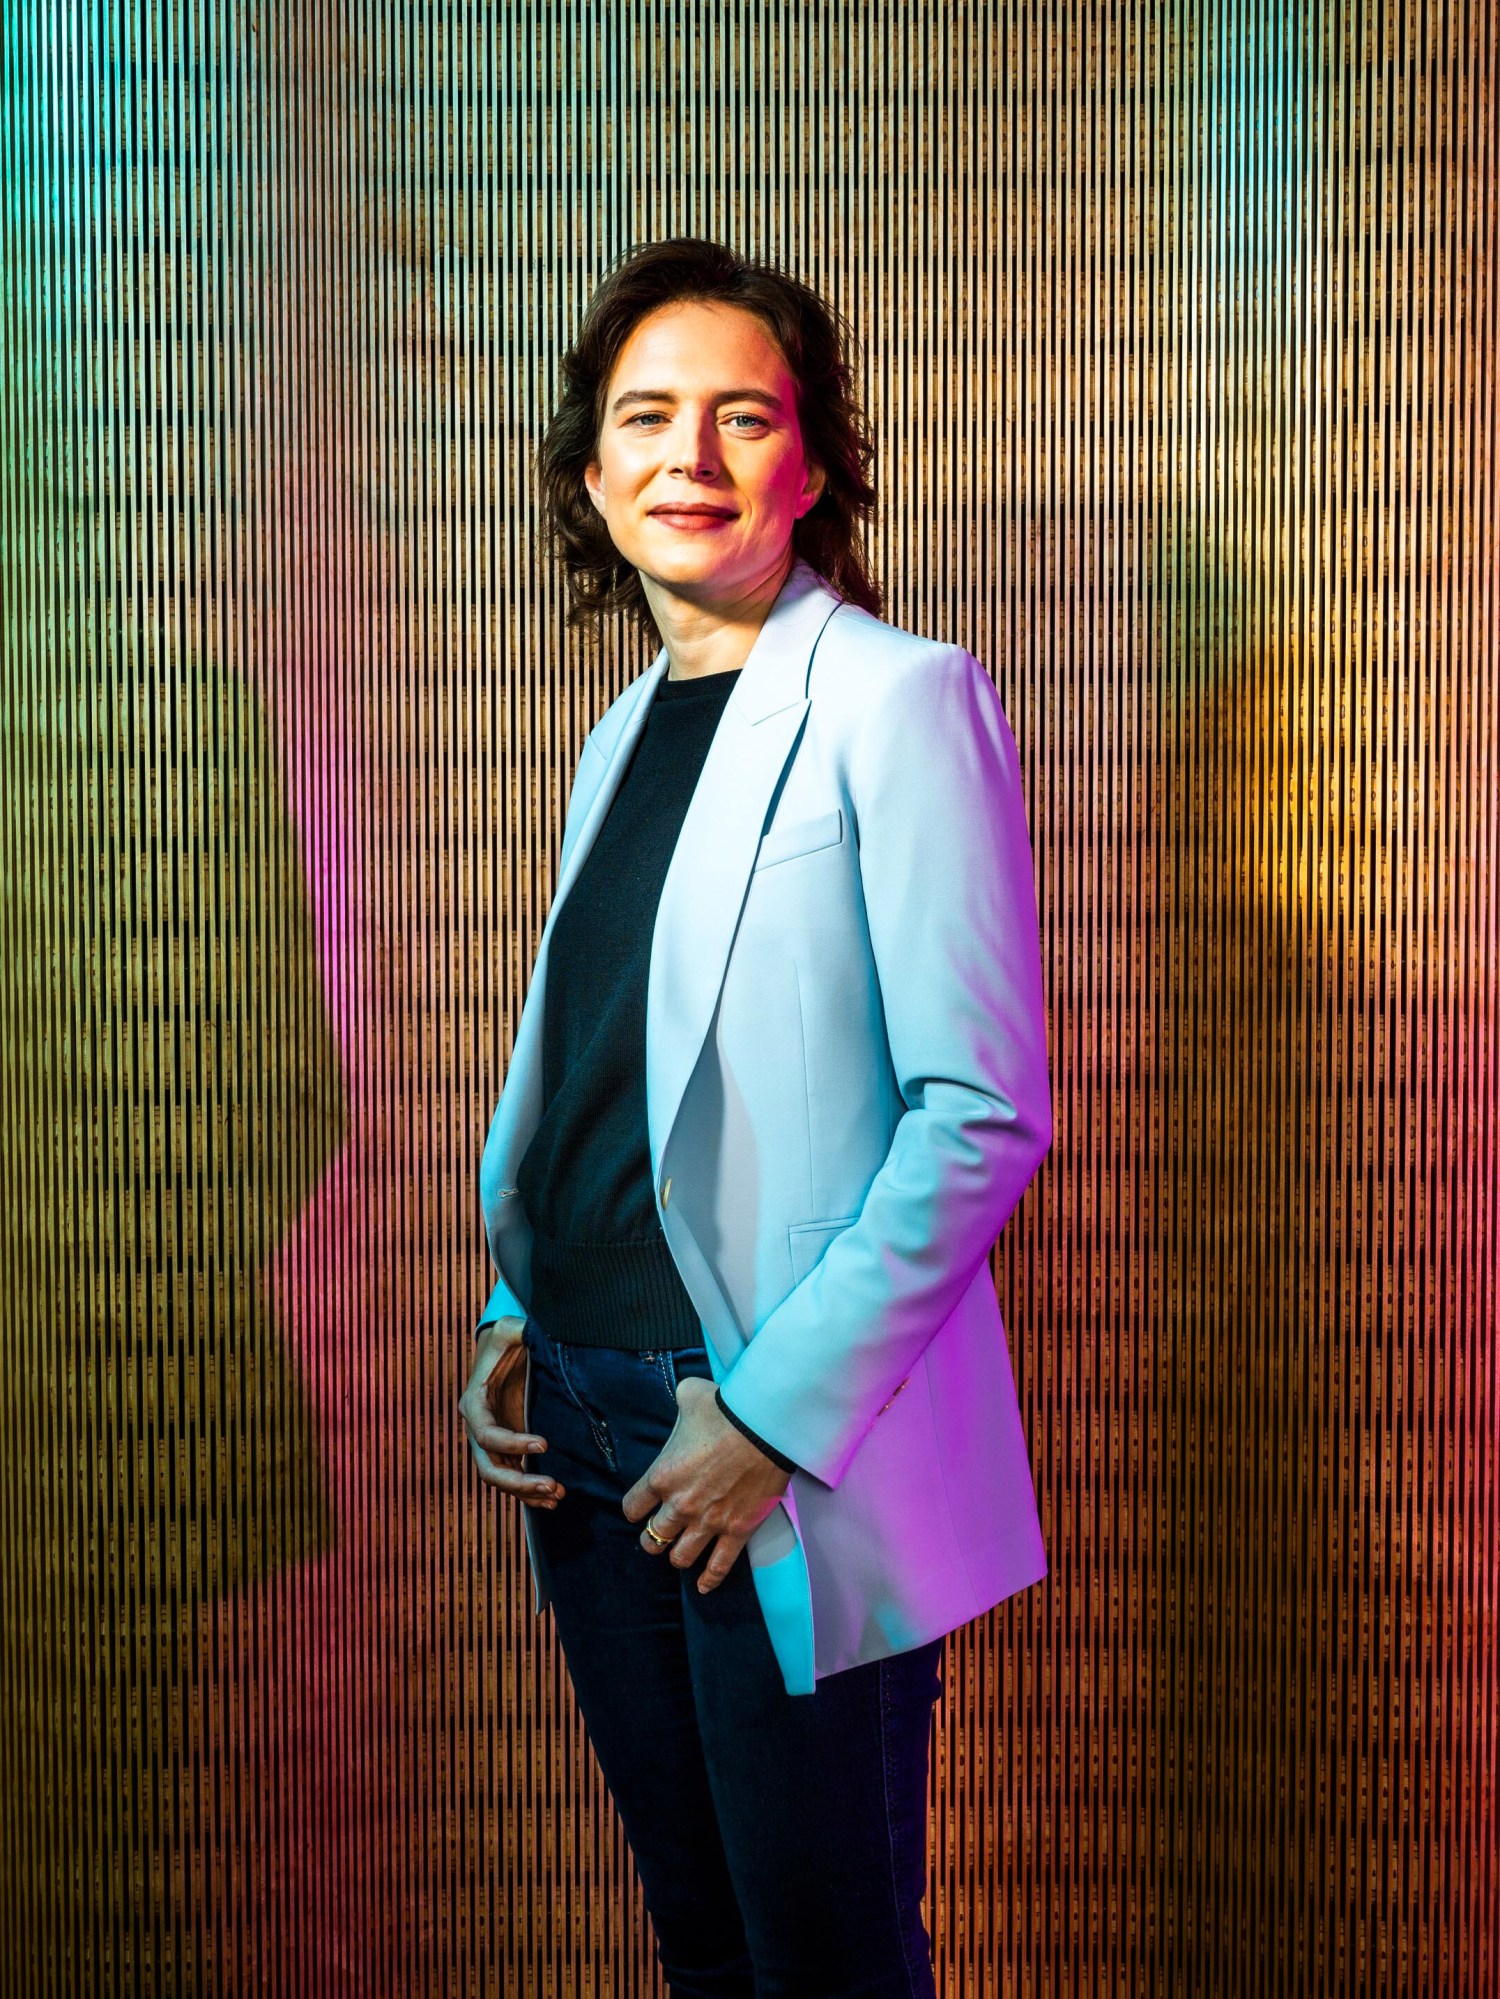
Elizabeth Reid
“For a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you,” says Google head of search, Liz Reid.
WINNI WINTERMEYER/REDUX

Like Google, ChatGPT is pulling in information from web publishers, summarizing it, and including it in its answers. But it has also struck financial deals with publishers, a payment for providing the information that gets rolled into its results. (MIT Technology Review has been in discussions with OpenAI, Google, Perplexity, and others about publisher deals but has not entered into any agreements. Editorial was neither party to nor informed about the content of those discussions.)

But the thing is, for web search to accomplish what OpenAI wants—to be more current than the language model—it also has to bring in information from all sorts of publishers and sources that it doesn’t have deals with. OpenAI’s head of media partnerships, Varun Shetty, told MIT Technology Review that it won’t give preferential treatment to its publishing partners.

Instead, OpenAI told me, the model itself finds the most trustworthy and useful source for any given question. And that can get weird too. In that very first example it showed me—when Turley ran that name search—it described a story I wrote years ago for Wired about being hacked. That story remains one of the most widely read I’ve ever written. But ChatGPT didn’t link to it. It linked to a short rewrite from The Verge. Admittedly, this was on a prototype version of search, which was, as Turley said, “risky.” 

When I asked him about it, he couldn’t really explain why the model chose the sources that it did, because the model itself makes that evaluation. The company helps steer it by identifying—sometimes with the help of users—what it considers better answers, but the model actually selects them. 

“And in many cases, it gets it wrong, which is why we have work to do,” said Turley. “Having a model in the loop is a very, very different mechanism than how a search engine worked in the past.”

Indeed! 

The model, whether it’s OpenAI’s GPT-4o or Google’s Gemini or Anthropic’s Claude, can be very, very good at explaining things. But the rationale behind its explanations, its reasons for selecting a particular source, and even the language it may use in an answer are all pretty mysterious. Sure, a model can explain very many things, but not when that comes to its own answers. 


It was almost a decade ago, in 2016, when Pichai wrote that Google was moving from “mobile first” to “AI first”: “But in the next 10 years, we will shift to a world that is AI-first, a world where computing becomes universally available—be it at home, at work, in the car, or on the go—and interacting with all of these surfaces becomes much more natural and intuitive, and above all, more intelligent.” 

We’re there now—sort of. And it’s a weird place to be. It’s going to get weirder. That’s especially true as these things we now think of as distinct—querying a search engine, prompting a model, looking for a photo we’ve taken, deciding what we want to read or watch or hear, asking for a photo we wish we’d taken, and didn’t, but would still like to see—begin to merge. 

The search results we see from generative AI are best understood as a waypoint rather than a destination. What’s most important may not be search in itself; rather, it’s that search has given AI model developers a path to incorporating real-time information into their inputs and outputs. And that opens up all sorts of possibilities.

“A ChatGPT that can understand and access the web won’t just be about summarizing results. It might be about doing things for you. And I think there’s a fairly exciting future there,” says OpenAI’s Weil. “You can imagine having the model book you a flight, or order DoorDash, or just accomplish general tasks for you in the future. It’s just once the model understands how to use the internet, the sky’s the limit.”

This is the agentic future we’ve been hearing about for some time now, and the more AI models make use of real-time data from the internet, the closer it gets. 

Let’s say you have a trip coming up in a few weeks. An agent that can get data from the internet in real time can book your flights and hotel rooms, make dinner reservations, and more, based on what it knows about you and your upcoming travel—all without your having to guide it. Another agent could, say, monitor the sewage output of your home for certain diseases, and order tests and treatments in response. You won’t have to search for that weird noise your car is making, because the agent in your vehicle will already have done it and made an appointment to get the issue fixed. 

“It’s not always going to be just doing search and giving answers,” says Pichai. “Sometimes it’s going to be actions. Sometimes you’ll be interacting within the real world. So there is a notion of universal assistance through it all.”

And the ways these things will be able to deliver answers is evolving rapidly now too. For example, today Google can not only search text, images, and even video; it can create them. Imagine overlaying that ability with search across an array of formats and devices. “Show me what a Townsend’s warbler looks like in the tree in front of me.” Or “Use my existing family photos and videos to create a movie trailer of our upcoming vacation to Puerto Rico next year, making sure we visit all the best restaurants and top landmarks.”

“We have primarily done it on the input side,” he says, referring to the ways Google can now search for an image or within a video. “But you can imagine it on the output side too.”

This is the kind of future Pichai says he is excited to bring online. Google has already showed off a bit of what that might look like with NotebookLM, a tool that lets you upload large amounts of text and have it converted into a chatty podcast. He imagines this type of functionality—the ability to take one type of input and convert it into a variety of outputs—transforming the way we interact with information. 

In a demonstration of a tool called Project Astra this summer at its developer conference, Google showed one version of this outcome, where cameras and microphones in phones and smart glasses understand the context all around you—online and off, audible and visual—and have the ability to recall and respond in a variety of ways. Astra can, for example, look at a crude drawing of a Formula One race car and not only identify it, but also explain its various parts and their uses. 

But you can imagine things going a bit further (and they will). Let’s say I want to see a video of how to fix something on my bike. The video doesn’t exist, but the information does. AI-assisted generative search could theoretically find that information somewhere online—in a user manual buried in a company’s website, for example—and create a video to show me exactly how to do what I want, just as it could explain that to me with words today.

These are the kinds of things that start to happen when you put the entire compendium of human knowledge—knowledge that’s previously been captured in silos of language and format; maps and business registrations and product SKUs; audio and video and databases of numbers and old books and images and, really, anything ever published, ever tracked, ever recorded; things happening right now, everywhere—and introduce a model into all that. A model that maybe can’t understand, precisely, but has the ability to put that information together, rearrange it, and spit it back in a variety of different hopefully helpful ways. Ways that a mere index could not.

That’s what we’re on the cusp of, and what we’re starting to see. And as Google rolls this out to a billion people, many of whom will be interacting with a conversational AI for the first time, what will that mean? What will we do differently? It’s all changing so quickly. Hang on, just hang on. 
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

F5 scrambles to fix more critical BIG-IP security flaws

CVE-2026-121805: When an iRule that processes client traffic using the PEM:subscriber command is configured on a virtual server, undisclosed requests can cause the Traffic Management Microkernel (TMM) to terminate and may lead to remote code execution (RCE); CVE-2026-120292: When an HTTP profile and an iRule using the MR:message route command

Read More »

Energy Secretary Keeps Critical Generation Available in Mid-Atlantic

WASHINGTON—U.S. Secretary of Energy Chris Wright today issued an emergency order to address critical grid reliability issues facing the mid-Atlantic region of the United States. The order directs PJM Interconnection L.L.C. (PJM), in coordination with Constellation Energy Corporation (Constellation Energy), to ensure Units 3 and 4 of the Eddystone Generating Station in Pennsylvania remain available to operate and to employ economic dispatch to minimize costs for the American people. The units were originally slated to shut down on May 31, 2025.   “The energy sources that perform when you need them most are the most valuable,” said U.S. Secretary of Energy Chris Wright. “President Trump and the Energy Department are committed to keeping critical generation available when demand is highest, reducing the risk of blackouts and ensuring Americans have affordable, reliable, and secure power—regardless of whether the wind is blowing or the sun is shining.”  Secretary Wright first ordered that the two Eddystone Generating Station units remain online past their planned retirement date in a May 30, 2025 emergency order. Subsequent orders were issued later in 2025 and 2026. Keeping these units operational has strengthened energy security in the PJM region, ensuring reliable electricity for American families and businesses. This order is in effect beginning on November 21, 2026, through February 18, 2027. 

Read More »

ExxonMobil takes FID on Angola Block 15 extension project

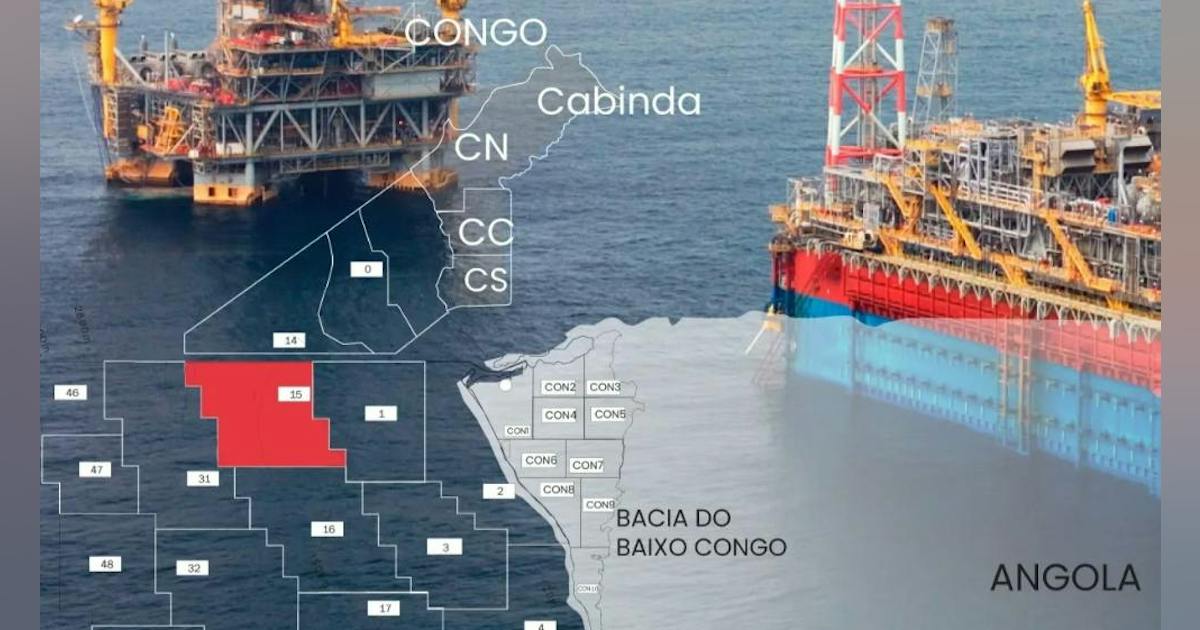
The Block 15 Lifespan Extension Project, about 145 km off Angola’s northern coast, will utilize existing infrastructure to develop additional resources throughout the Kizomba Hub area. The investment decision completes project FIDs following approval of Kizomba C redevelopment in 2025. ANPG also noted a hydrocarbon discovery in the block at the Tchihumba West-01ST1 exploration well, about 350 km northwest of Luanda. The discovery is the 21st in the block and the second this year. The well, drilled by the Valaris DS-9 in about 1,400 m of water, encountered 65.4 m of sandstone reservoir with hydrocarbon presence and good petrophysical properties. ExxonMobil is operator at Block 15 (36%) with partners Azule Energy Exploration (ANG) Ltd. (24%), Azule Energy ANG BV (18%), Equinor Angola (12%), and Sonongol E&P (10%).

Read More »

Market reforms bolster grid, may lower costs this winter: FERC

Listen to the article 4 min This audio is auto-generated. Please let us know if you have feedback. Electric market reforms in the West and Northeast may bolster grid reliability and, in some cases, lower costs this winter, according to the Federal Energy Regulatory Commission’s annual winter market and reliability report, released Thursday. Expanded markets help offset drought impacts In the West, the California Independent System Operator launched the Extended Day Ahead Market and the Southwest Power Pool expanded into the Western Interconnection earlier this year. “EDAM and SPP’s expansion should provide ratepayers in much of the West with production cost savings and improved reliability in winter 2026-2027, particularly during cold weather events,” FERC staff said in the report. This winter, the markets’ improved coordination of generation and reduced need for reserve power supplies will help offset lower power output from the Glen Canyon and Hoover dams due to historically low water levels in the Colorado River basin, staff said. “On a day-to-day basis, these conditions can create congestion and affect system operators’ ability to respond to voltage support challenges, event response mitigation needs, or any additional grid stressors,” staff said in the report. About 45% of the continental United States and 95% of the Intermountain West region is in a drought, according to the report. Hydro, oil pose challenges for Northeast In the Northeast, ISO New England lowered its capacity performance pay rate, which should lower electricity prices during emergency conditions or capacity performance events this winter, staff said. Also, the New York Independent System Operator changed its installed capacity market rules to reflect uncertainty about how much power Hydro–Québec will deliver over the 1,250-MW Champlain Hudson Power Express transmission line in the winter, they noted. The U.S. subsidiary of the Canadian utility Hydro-Québec — the primary reservation holder — has an obligation

Read More »

Dangote awards contracts advancing Lekki refining complex expansion

Dangote Group’s Dangote Petroleum Refinery and Petrochemicals FZE (DPRP) has awarded separate contracts to Kirloskar Group of India’s Kirloskar Brothers Ltd. (KBL) and Kirloskar Ebara Pumps Ltd. (KEPL)—a KBL joint venture with Ebara Corp. of Japan—for delivery of engineering services and equipment as part of a phased capacity expansion currently underway at DPRP’s 650,000-b/d refinery and petrochemical complex in the Lekki Free Zone near Lagos, Nigeria. In a Nov. 20 regulatory filing submitted to both BSE Ltd. and The National Stock Exchange of India Ltd., KBL said the combined value of the orders under the contracts amounted to about $38.94 million, $21.34 million of which would cover KEPL’s scope of work, with KBL to retain the remaining $17.60 million as compensation for a leg of the project. The service provider offered no additional details regarding either its own of KEPL’s scope of deliverables under the agreement other than that the work was to include engineering expertise and provision of “specialized pumping solutions for demanding energy applications.” The Lekki complex expansion involves increasing the refinery’s crude processing capacity by an additional 750,000 b/d to 1.4 million b/d in two phases to be executed between 2025-28 and 2028-30, respectively. The proposed expansion also includes plans to increase the site’s production of propylene by 750,000 tonnes/year (tpy), as well as adding 400,000 tpy of fresh production capacity for linear alkylbenzene (LAB).

Read More »

How NV5 Digital Twins Help Oil & Gas Facilities Reduce Downtime and Improve Safety

Refining, midstream, and production operators face increasing pressure to reduce downtime, improve safety, and make faster decisions with increasingly complex asset data. One leading international energy company partnered with NV5 Geospatial to deploy high-fidelity digital twins that unified engineering, inspection, and operational data across multiple facilities. The result: faster planning and approvals, safer operations, fewer travel requirements, and measurable reductions in outage windows.   The Challenge  The company’s refineries and offshore/onshore facilities are high-consequence environments where even brief shutdowns can cost millions per day. Engineering drawings, P&IDs, laser scans, SCADA/IoT feeds, and maintenance systems existed in separate silos making it difficult for staff to access a shared, current view of assets or to plan complex maintenance activities safely and efficiently.   Additionally, the organization sought to reduce field exposure for subject-matter experts (SMEs) by enabling remote collaboration and to improve predictability in outage planning and maintenance “switchovers,” where downtime forecasting directly affects operational revenue.   The Solution  NV5 Digital Twin = Geospatial system of record + automation.  NV5 delivered a scalable, field-to-cloud workflow that fused reality capture, engineering data, and live system integration into a unified, photorealistic 3D environment.   Reality Capture  Rotary-wing acquisition using NV5’s custom multi-sensor pod with RIEGL VUX-240 LiDAR (~300 ppsm) and 150MP nadir + oblique imagery (1″ GSD), flown with 80% side/forward lap for high-fidelity photomesh creation.  NV5 coordinated with local air-traffic control and operated from a nearby hangar to minimize mobilization time.  IS-BAO Stage 3 aviation safety certification and on-staff licensed surveyors ensured quality and compliance.   This level of detail enables operators to virtually inspect assets, plan maintenance activities, and validate engineering decisions without repeated site visits. Processing and Integration  SBET-calibrated LiDAR and imagery were processed into advanced classified point clouds, DEM/DSM surfaces, and textured 3D meshes (delivered OBJ/Esri Scene Layer, and Cesium 3D Tiles 1.1 formats).  Engineering

Read More »

FERC approves Sabine Pass LNG expansion, four other major gas projects

The US Federal Energy Regulatory Commission (FERC) approved 5 gas infrastructure projects Nov. 19, including a nearly 20-million-tonne/year (tpy) expansion of Cheniere Energy’s Sabine Pass LNG export plant in Louisiana, two associated feedgas pipeline projects, and new gas transportation and storage infrastructure in 5 other states. The approvals encompass roughly $3 billion in proposed pipeline and storage investments, excluding construction costs for the Sabine Pass liquefaction expansion. Cheniere estimates the full Sabine Pass Stage V LNG expansion will cost $15 billion, according to a June 2025 filing with the US Department of Energy. Sabine Pass Stage V expansion FERC authorized Cheniere Energy subsidiaries Sabine Pass Liquefaction LLC and Sabine Pass Liquefaction Stage V LLC to construct and operate 3 additional liquefaction trains at the existing Sabine Pass LNG plant in Cameron Parish, La. The expansion would add up to 20 million tpy of LNG production capacity to the existing 30 million tpy 6-train plant.  Phase 1 calls for Train 7, with peak production capacity of about 6 million tpy, and a boil-off gas reliquefaction unit capable of producing about 1 million tpy. Phase 2 would add Trains 8 and 9, each with peak production capacity of 6 mtpa, along with supporting infrastructure and upgrades to marine loading infrastructure.  Cheniere has not yet taken final investment decision, but expects to greenlight Phase 1 by early 2027, subject to regulatory approvals and financing arrangements. The company previously said initial LNG exports could begin in 2030, with commercial service potentially starting in mid-2031. FERC also authorized two pipeline projects to supply additional feedgas to the expanded terminal. The $1.63 billion Sabine Crossing Pipeline project would build 55.6 miles of 48-in. OD pipeline between southeast Texas and Sabine Pass, along with a new 210,000-hp compressor station and related infrastructure. The pipeline would transport up

Read More »

The Data Center Backlash Has a Playbook

The data center industry’s next development constraint may have less to do with megawatts than with the politics of where those megawatts are deployed. The warning became difficult to ignore on November 3, when American voters approved 33 local ballot measures restricting data center development or expressing opposition to it, according to Ballotpedia’s analysis of the 2026 midterm elections. The results included outright bans, partial prohibitions, temporary moratoriums, and new requirements for community oversight. Voters also rejected 13 measures that would have favored development or expressed support for it. For an industry accustomed to evaluating prospective sites through the availability of power, land, fiber, capital, and construction resources, the election results reinforced another increasingly consequential consideration: whether the communities hosting digital infrastructure are willing to accept its growing physical and economic footprint. As Data Center Frontier recently examined in its post-election assessment of the industry’s political future, the national push to accelerate AI infrastructure construction is colliding with a more complicated political reality at the state and local levels. Opposition crosses party lines, while questions surrounding utility rates, water, environmental impacts, and local economic benefits have moved from planning commission meetings into broader electoral debate. That changing environment was the subject of a conversation recorded at the DCF Trends Summit 2026 in Reston, Virginia, where DCF contributing editor Doug Black sat down with Adam Waitkunas, president of Milldam Public Relations, and Julia Chuang, founder of LocalQ Labs and an associate professor of sociology at the University of Maryland. Their discussion explored a fundamental shift in the development equation: community opposition is becoming more organized and politically consequential, but also more observable through data. The challenge for developers is to understand that risk early enough to influence site selection and project design, while recognizing that public trust cannot be manufactured through

Read More »

Oak Ridge’s AI Factory Moment: Lux, Nuclear Power, and the Next Data Center Frontier

For much of its history, Oak Ridge has been associated with the Manhattan Project and the subsequent development of America’s nuclear research and production capabilities. Established during World War II, the community became home to major facilities for uranium enrichment, nuclear materials processing, scientific research, and ultimately high-performance computing. Today, that legacy is being repurposed for a new generation of industrial development. The former K-25 uranium enrichment complex, once a critical part of the nation’s atomic weapons program, has been transformed into the East Tennessee Technology Park (ETTP), where extensive environmental cleanup and redevelopment have made former federal property available for commercial use. At an October 27 gathering in Oak Ridge, federal officials and nuclear industry representatives highlighted more than $15 billion in announced nuclear-related projects across the region, an investment wave subsequently documented in a November 17 DOE report on Oak Ridge’s emerging energy hub. The investment figure largely represents planned private-sector development rather than completed capital spending. Regional officials also anticipate demand for thousands of construction workers over the next five years, with additional permanent manufacturing and operating positions potentially following as projects advance. In March, DOE completed its largest Oak Ridge land transfer to date, conveying more than 700 acres for economic reuse. The transfer included a 624-acre parcel designated for Orano USA’s planned uranium enrichment complex and a 77-acre parcel associated with Oklo’s proposed nuclear fuel recycling development. Overall, more than 2,500 acres have been transferred from federal ownership for redevelopment, following decades of cleanup and the demolition of hundreds of former industrial structures. For nuclear developers, the appeal is straightforward: large industrial sites, existing utility and transportation infrastructure, proximity to federal laboratories, and an established community of nuclear engineers, technicians, researchers, and specialized manufacturers. For data center developers, the implications are somewhat different but no

Read More »

Dell and Microsoft drive private AI as enterprises seek greater data control

Dell Technologies and Microsoft are expanding their private cloud partnership with a new set of infrastructure offerings designed to let enterprises run AI models closer to their data, reduce reliance on public cloud services and maintain control over sensitive information. The announcement, made during Microsoft’s Ignite conference, extends Dell’s AI Factory with Nvidia initiative to Dell Private Cloud environments. It also reflects a growing industry push toward internally deployed AI inferencing, particularly among organizations dealing with sensitive corporate information, regulatory requirements and data residency restrictions, Dell stated. The expanded offering combines Dell Private Cloud, Microsoft Azure Local, Microsoft Foundry Local and Nvidia acceleration. The objective is to provide organizations with an integrated infrastructure for deploying heavy AI workloads inside their own data centers and firewalls, the companies said.

Read More »

StarlingX 13.0 updates the network stack for distributed edge deployments

Edge sites do not always come with the network gear that a data center takes for granted. That’s a challenge the open-source StarlingX project from the OpenInfra Foundation is now tackling in its 13.0 update. StarlingX is an open-source distributed cloud platform that combines Linux, Kubernetes, OpenStack, and Ceph. The OpenInfra Foundation hosts the project, and operators including Verizon, Vodafone, T-Systems and KDDI use it for 5G and Open Radio Access Network (O-RAN) infrastructure. Earlier this year, the StarlingX 12.0 update added precision timing capabilities to help networking stay on time. The 13.0 update tackles a different set of issues. Key features include: Gateway API support. Calico-based support is available to hosted applications, while platform services still use Ingress NGINX Optional certificate authority. The Enterprise Java Beans Certificate Authority (EJBCA) runs on the platform and serves certificates to hosted applications. Subcloud restore. A backup restores directly onto a factory-installed node at a subcloud, a remote edge site, with no operating system reinstall. Direct upgrades. Operators can upgrade from two releases back with a single reboot per host. Layer 2 switching. A new Open vSwitch application lets servers at sites with no router next to them bridge traffic and connect directly to aggregation routers. “The OpenvSwitch application adds Layer 2 switching to the K8S platform,” Greg Waines, a senior member of technical staff at Wind River and a StarlingX Technical Steering Committee member, told Network World. “A server can bridge traffic between its SR-IOV network interfaces and other servers, and it can forward traffic to the site routers.”

Read More »

Sovereign AI is about control, not just location

Guetari was open about the term itself being fuzzy. “Sovereignty is very vague and not always clear,” he told me. “It’s about control, auditability, observability.” He drew a line between data locality, meaning the data stays in-country, and sovereignty, which he described as being “more about control, control of what happens to your data and your workload.” He then made the case for why F5 belongs in that conversation: “This is what we have been doing for two decades.” F5 has always sat in the data path, deciding what an application can communicate with, enforcing security rules, and logging what happened. For a regulated bank or government agency, the ability to reconstruct exactly what happened after an incident is worth more than a press release about a data center’s location. The token is the new unit of economics The most interesting part of my conversation with Guetari wasn’t about security. It was about business models. He argued that every successful technology business has found the right unit to monetize. “The cloud is selling the unit of the cloud, which is the CPU core, very well. SaaS is the seat,” he said. “Telcos have been very successful early on using the voice minute, and then they moved to the gigabyte. Sooner or later, that unit will be the token, and most telcos will have to move to the token. And the ones who will not go to token, unfortunately, will be just pipes.”

Read More »

Palo Alto Networks bets $4.5B on enterprise AI with Applied Compute acquisition

GPUs and data centers To train and host those models, Palo Alto plans to build its own compute capacity, CFO Dipak Golechha said on the call. The spending “will mostly go to GPUs and servers,” with a smaller share for the facilities that house them, he said. Palo Alto will “continue to source from our cloud partners” and add dedicated capacity over time, Golechha said. Arora said the company aims for more than100 megawatts of compute in the next three to five years. Gogia said Palo Alto has sovereignty credentials for security data, including customer-held keys and a European Cortex service governed by Deutsche Telekom. “None of that yet extends to GPUs,” he said, adding that a US-headquartered operator faces the same jurisdictional questions as the hyperscalers it rents capacity from. “A sovereign hosting offer with no named region, operator or date is a promise looking for an address,” Gogia said. Compliance officers should ask Palo Alto for a region list, the operator, and a dated certification plan, he said.

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »