Stay Ahead, Stay ONMINE

AI means the end of internet search as we’ve known it

We all know what it means, colloquially, to google something. You pop a few relevant words in a search box and in return get a list of blue links to the most relevant results. Maybe some quick explanations up top. Maybe some maps or sports scores or a video. But fundamentally, it’s just fetching information that’s already out there on the internet and showing it to you, in some sort of structured way.  But all that is up for grabs. We are at a new inflection point. The biggest change to the way search engines have delivered information to us since the 1990s is happening right now. No more keyword searching. No more sorting through links to click. Instead, we’re entering an era of conversational search. Which means instead of keywords, you use real questions, expressed in natural language. And instead of links, you’ll increasingly be met with answers, written by generative AI and based on live information from all across the internet, delivered the same way.  Of course, Google—the company that has defined search for the past 25 years—is trying to be out front on this. In May of 2023, it began testing AI-generated responses to search queries, using its large language model (LLM) to deliver the kinds of answers you might expect from an expert source or trusted friend. It calls these AI Overviews. Google CEO Sundar Pichai described this to MIT Technology Review as “one of the most positive changes we’ve done to search in a long, long time.” AI Overviews fundamentally change the kinds of queries Google can address. You can now ask it things like “I’m going to Japan for one week next month. I’ll be staying in Tokyo but would like to take some day trips. Are there any festivals happening nearby? How will the surfing be in Kamakura? Are there any good bands playing?” And you’ll get an answer—not just a link to Reddit, but a built-out answer with current results.  More to the point, you can attempt searches that were once pretty much impossible, and get the right answer. You don’t have to be able to articulate what, precisely, you are looking for. You can describe what the bird in your yard looks like, or what the issue seems to be with your refrigerator, or that weird noise your car is making, and get an almost human explanation put together from sources previously siloed across the internet. It’s amazing, and once you start searching that way, it’s addictive. And it’s not just Google. OpenAI’s ChatGPT now has access to the web, making it far better at finding up-to-date answers to your queries. Microsoft released generative search results for Bing in September. Meta has its own version. The startup Perplexity was doing the same, but with a “move fast, break things” ethos. Literal trillions of dollars are at stake in the outcome as these players jockey to become the next go-to source for information retrieval—the next Google. Not everyone is excited for the change. Publishers are completely freaked out. The shift has heightened fears of a “zero-click” future, where search referral traffic—a mainstay of the web since before Google existed—vanishes from the scene.  I got a vision of that future last June, when I got a push alert from the Perplexity app on my phone. Perplexity is a startup trying to reinvent web search. But in addition to delivering deep answers to queries, it will create entire articles about the news of the day, cobbled together by AI from different sources.  On that day, it pushed me a story about a new drone company from Eric Schmidt. I recognized the story. Forbes had reported it exclusively, earlier in the week, but it had been locked behind a paywall. The image on Perplexity’s story looked identical to one from Forbes. The language and structure were quite similar. It was effectively the same story, but freely available to anyone on the internet. I texted a friend who had edited the original story to ask if Forbes had a deal with the startup to republish its content. But there was no deal. He was shocked and furious and, well, perplexed. He wasn’t alone. Forbes, the New York Times, and Condé Nast have now all sent the company cease-and-desist orders. News Corp is suing for damages.  People are worried about what these new LLM-powered results will mean for our fundamental shared reality. It could spell the end of the canonical answer. It was precisely the nightmare scenario publishers have been so afraid of: The AI was hoovering up their premium content, repackaging it, and promoting it to its audience in a way that didn’t really leave any reason to click through to the original. In fact, on Perplexity’s About page, the first reason it lists to choose the search engine is “Skip the links.” But this isn’t just about publishers (or my own self-interest).  People are also worried about what these new LLM-powered results will mean for our fundamental shared reality. Language models have a tendency to make stuff up—they can hallucinate nonsense. Moreover, generative AI can serve up an entirely new answer to the same question every time, or provide different answers to different people on the basis of what it knows about them. It could spell the end of the canonical answer. But make no mistake: This is the future of search. Try it for a bit yourself, and you’ll see.  Sure, we will always want to use search engines to navigate the web and to discover new and interesting sources of information. But the links out are taking a back seat. The way AI can put together a well-reasoned answer to just about any kind of question, drawing on real-time data from across the web, just offers a better experience. That is especially true compared with what web search has become in recent years. If it’s not exactly broken (data shows more people are searching with Google more often than ever before), it’s at the very least increasingly cluttered and daunting to navigate.  Who wants to have to speak the language of search engines to find what you need? Who wants to navigate links when you can have straight answers? And maybe: Who wants to have to learn when you can just know?  In the beginning there was Archie. It was the first real internet search engine, and it crawled files previously hidden in the darkness of remote servers. It didn’t tell you what was in those files—just their names. It didn’t preview images; it didn’t have a hierarchy of results, or even much of an interface. But it was a start. And it was pretty good.  Then Tim Berners-Lee created the World Wide Web, and all manner of web pages sprang forth. The Mosaic home page and the Internet Movie Database and Geocities and the Hampster Dance and web rings and Salon and eBay and CNN and federal government sites and some guy’s home page in Turkey. Until finally, there was too much web to even know where to start. We really needed a better way to navigate our way around, to actually find the things we needed.  And so in 1994 Jerry Yang created Yahoo, a hierarchical directory of websites. It quickly became the home page for millions of people. And it was … well, it was okay. TBH, and with the benefit of hindsight, I think we all thought it was much better back then than it actually was. But the web continued to grow and sprawl and expand, every day bringing more information online. Rather than just a list of sites by category, we needed something that actually looked at all that content and indexed it. By the late ’90s that meant choosing from a variety of search engines: AltaVista and AlltheWeb and WebCrawler and HotBot. And they were good—a huge improvement. At least at first.   But alongside the rise of search engines came the first attempts to exploit their ability to deliver traffic. Precious, valuable traffic, which web publishers rely on to sell ads and retailers use to get eyeballs on their goods. Sometimes this meant stuffing pages with keywords or nonsense text designed purely to push pages higher up in search results. It got pretty bad.  And then came Google. It’s hard to overstate how revolutionary Google was when it launched in 1998. Rather than just scanning the content, it also looked at the sources linking to a website, which helped evaluate its relevance. To oversimplify: The more something was cited elsewhere, the more reliable Google considered it, and the higher it would appear in results. This breakthrough made Google radically better at retrieving relevant results than anything that had come before. It was amazing.  Google CEO Sundar Pichai describes AI Overviews as “one of the most positive changes we’ve done to search in a long, long time.”JENS GYARMATY/LAIF/REDUX For 25 years, Google dominated search. Google was search, for most people. (The extent of that domination is currently the subject of multiple legal probes in the United States and the European Union.)   But Google has long been moving away from simply serving up a series of blue links, notes Pandu Nayak, Google’s chief scientist for search.  “It’s not just so-called web results, but there are images and videos, and special things for news. There have been direct answers, dictionary answers, sports, answers that come with Knowledge Graph, things like featured snippets,” he says, rattling off a litany of Google’s steps over the years to answer questions more directly.  It’s true: Google has evolved over time, becoming more and more of an answer portal. It has added tools that allow people to just get an answer—the live score to a game, the hours a café is open, or a snippet from the FDA’s website—rather than being pointed to a website where the answer may be.  But once you’ve used AI Overviews a bit, you realize they are different.  Take featured snippets, the passages Google sometimes chooses to highlight and show atop the results themselves. Those words are quoted directly from an original source. The same is true of knowledge panels, which are generated from information stored in a range of public databases and Google’s Knowledge Graph, its database of trillions of facts about the world. While these can be inaccurate, the information source is knowable (and fixable). It’s in a database. You can look it up. Not anymore: AI Overviews can be entirely new every time, generated on the fly by a language model’s predictive text combined with an index of the web.  “I think it’s an exciting moment where we have obviously indexed the world. We built deep understanding on top of it with Knowledge Graph. We’ve been using LLMs and generative AI to improve our understanding of all that,” Pichai told MIT Technology Review. “But now we are able to generate and compose with that.” The result feels less like a querying a database than like asking a very smart, well-read friend. (With the caveat that the friend will sometimes make things up if she does not know the answer.)  “[The company’s] mission is organizing the world’s information,” Liz Reid, Google’s head of search, tells me from its headquarters in Mountain View, California. “But actually, for a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you.”  That second concept—accessibility—is what Google is really keying in on with AI Overviews. It’s a sentiment I hear echoed repeatedly while talking to Google execs: They can address more complicated types of queries more efficiently by bringing in a language model to help supply the answers. And they can do it in natural language.  That will become even more important for a future where search goes beyond text queries. For example, Google Lens, which lets people take a picture or upload an image to find out more about something, uses AI-generated answers to tell you what you may be looking at. Google has even showed off the ability to query live video.  When it doesn’t have an answer, an AI model can confidently spew back a response anyway. For Google, this could be a real problem. For the rest of us, it could actually be dangerous. “We are definitely at the start of a journey where people are going to be able to ask, and get answered, much more complex questions than where we’ve been in the past decade,” says Pichai.  There are some real hazards here. First and foremost: Large language models will lie to you. They hallucinate. They get shit wrong. When it doesn’t have an answer, an AI model can blithely and confidently spew back a response anyway. For Google, which has built its reputation over the past 20 years on reliability, this could be a real problem. For the rest of us, it could actually be dangerous. In May 2024, AI Overviews were rolled out to everyone in the US. Things didn’t go well. Google, long the world’s reference desk, told people to eat rocks and to put glue on their pizza. These answers were mostly in response to what the company calls adversarial queries—those designed to trip it up. But still. It didn’t look good. The company quickly went to work fixing the problems—for example, by deprecating so-called user-generated content from sites like Reddit, where some of the weirder answers had come from. Yet while its errors telling people to eat rocks got all the attention, the more pernicious danger might arise when it gets something less obviously wrong. For example, in doing research for this article, I asked Google when MIT Technology Review went online. It helpfully responded that “MIT Technology Review launched its online presence in late 2022.” This was clearly wrong to me, but for someone completely unfamiliar with the publication, would the error leap out?  I came across several examples like this, both in Google and in OpenAI’s ChatGPT search. Stuff that’s just far enough off the mark not to be immediately seen as wrong. Google is banking that it can continue to improve these results over time by relying on what it knows about quality sources. “When we produce AI Overviews,” says Nayak, “we look for corroborating information from the search results, and the search results themselves are designed to be from these reliable sources whenever possible. These are some of the mechanisms we have in place that assure that if you just consume the AI Overview, and you don’t want to look further … we hope that you will still get a reliable, trustworthy answer.” In the case above, the 2022 answer seemingly came from a reliable source—a story about MIT Technology Review’s email newsletters, which launched in 2022. But the machine fundamentally misunderstood. This is one of the reasons Google uses human beings—raters—to evaluate the results it delivers for accuracy. Ratings don’t correct or control individual AI Overviews; rather, they help train the model to build better answers. But human raters can be fallible. Google is working on that too.  “Raters who look at your experiments may not notice the hallucination because it feels sort of natural,” says Nayak. “And so you have to really work at the evaluation setup to make sure that when there is a hallucination, someone’s able to point out and say, That’s a problem.” The new search Google has rolled out its AI Overviews to upwards of a billion people in more than 100 countries, but it is facing upstarts with new ideas about how search should work. Search Engine GoogleThe search giant has added AI Overviews to search results. These overviews take information from around the web and Google’s Knowledge Graph and use the company’s Gemini language model to create answers to search queries. What it’s good at Google’s AI Overviews are great at giving an easily digestible summary in response to even the most complex queries, with sourcing boxes adjacent to the answers. Among the major options, its deep web index feels the most “internety.” But web publishers fear its summaries will give people little reason to click through to the source material. PerplexityPerplexity is a conversational search engine that uses third-party largelanguage models from OpenAI and Anthropic to answer queries. Perplexity is fantastic at putting together deeper dives in response to user queries, producing answers that are like mini white papers on complex topics. It’s also excellent at summing up current events. But it has gotten a bad rep with publishers, who say it plays fast and loose with their content. ChatGPTWhile Google brought AI to search, OpenAI brought search to ChatGPT. Queries that the model determines will benefit from a web search automatically trigger one, or users can manually select the option to add a web search. Thanks to its ability to preserve context across a conversation, ChatGPT works well for performing searches that benefit from follow-up questions—like planning a vacation through multiple search sessions. OpenAI says users sometimes go “20 turns deep” in researching queries. Of these three, it makes links out to publishers least prominent. When I talked to Pichai about this, he expressed optimism about the company’s ability to maintain accuracy even with the LLM generating responses. That’s because AI Overviews is based on Google’s flagship large language model, Gemini, but also draws from Knowledge Graph and what it considers reputable sources around the web.  “You’re always dealing in percentages. What we have done is deliver it at, like, what I would call a few nines of trust and factuality and quality. I’d say 99-point-few-nines. I think that’s the bar we operate at, and it is true with AI Overviews too,” he says. “And so the question is, are we able to do this again at scale? And I think we are.” There’s another hazard as well, though, which is that people ask Google all sorts of weird things. If you want to know someone’s darkest secrets, look at their search history. Sometimes the things people ask Google about are extremely dark. Sometimes they are illegal. Google doesn’t just have to be able to deploy its AI Overviews when an answer can be helpful; it has to be extremely careful not to deploy them when an answer may be harmful.  “If you go and say ‘How do I build a bomb?’ it’s fine that there are web results. It’s the open web. You can access anything,” Reid says. “But we do not need to have an AI Overview that tells you how to build a bomb, right? We just don’t think that’s worth it.”  But perhaps the greatest hazard—or biggest unknown—is for anyone downstream of a Google search. Take publishers, who for decades now have relied on search queries to send people their way. What reason will people have to click through to the original source, if all the information they seek is right there in the search result?   Rand Fishkin, cofounder of the market research firm SparkToro, publishes research on so-called zero-click searches. As Google has moved increasingly into the answer business, the proportion of searches that end without a click has gone up and up. His sense is that AI Overviews are going to explode this trend.   “If you are reliant on Google for traffic, and that traffic is what drove your business forward, you are in long- and short-term trouble,” he says.  Don’t panic, is Pichai’s message. He argues that even in the age of AI Overviews, people will still want to click through and go deeper for many types of searches. “The underlying principle is people are coming looking for information. They’re not looking for Google always to just answer,” he says. “Sometimes yes, but the vast majority of the times, you’re looking at it as a jumping-off point.”  Reid, meanwhile, argues that because AI Overviews allow people to ask more complicated questions and drill down further into what they want, they could even be helpful to some types of publishers and small businesses, especially those operating in the niches: “You essentially reach new audiences, because people can now express what they want more specifically, and so somebody who specializes doesn’t have to rank for the generic query.”  “I’m going to start with something risky,” Nick Turley tells me from the confines of a Zoom window. Turley is the head of product for ChatGPT, and he’s showing off OpenAI’s new web search tool a few weeks before it launches. “I should normally try this beforehand, but I’m just gonna search for you,” he says. “This is always a high-risk demo to do, because people tend to be particular about what is said about them on the internet.”  He types my name into a search field, and the prototype search engine spits back a few sentences, almost like a speaker bio. It correctly identifies me and my current role. It even highlights a particular story I wrote years ago that was probably my best known. In short, it’s the right answer. Phew?  A few weeks after our call, OpenAI incorporated search into ChatGPT, supplementing answers from its language model with information from across the web. If the model thinks a response would benefit from up-to-date information, it will automatically run a web search (OpenAI won’t say who its search partners are) and incorporate those responses into its answer, with links out if you want to learn more. You can also opt to manually force it to search the web if it does not do so on its own. OpenAI won’t reveal how many people are using its web search, but it says some 250 million people use ChatGPT weekly, all of whom are potentially exposed to it.   “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be a better super-assistant for you.” Kevin Weil, chief product officer, OpenAI According to Fishkin, these newer forms of AI-assisted search aren’t yet challenging Google’s search dominance. “It does not appear to be cannibalizing classic forms of web search,” he says.  OpenAI insists it’s not really trying to compete on search—although frankly this seems to me like a bit of expectation setting. Rather, it says, web search is mostly a means to get more current information than the data in its training models, which tend to have specific cutoff dates that are often months, or even a year or more, in the past. As a result, while ChatGPT may be great at explaining how a West Coast offense works, it has long been useless at telling you what the latest 49ers score is. No more.  “I come at it from the perspective of ‘How can we make ChatGPT able to answer every question that you have? How can we make it more useful to you on a daily basis?’ And that’s where search comes in for us,” Kevin Weil, the chief product officer with OpenAI, tells me. “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be able to be a better super-assistant for you.” Today ChatGPT is able to generate responses for very current news events, as well as near-real-time information on things like stock prices. And while ChatGPT’s interface has long been, well, boring, search results bring in all sorts of multimedia—images, graphs, even video. It’s a very different experience.  Weil also argues that ChatGPT has more freedom to innovate and go its own way than competitors like Google—even more than its partner Microsoft does with Bing. Both of those are ad-dependent businesses. OpenAI is not. (At least not yet.) It earns revenue from the developers, businesses, and individuals who use it directly. It’s mostly setting large amounts of money on fire right now—it’s projected to lose $14 billion in 2026, by some reports. But one thing it doesn’t have to worry about is putting ads in its search results as Google does.  “For a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you,” says Google head of search, Liz Reid.WINNI WINTERMEYER/REDUX Like Google, ChatGPT is pulling in information from web publishers, summarizing it, and including it in its answers. But it has also struck financial deals with publishers, a payment for providing the information that gets rolled into its results. (MIT Technology Review has been in discussions with OpenAI, Google, Perplexity, and others about publisher deals but has not entered into any agreements. Editorial was neither party to nor informed about the content of those discussions.) But the thing is, for web search to accomplish what OpenAI wants—to be more current than the language model—it also has to bring in information from all sorts of publishers and sources that it doesn’t have deals with. OpenAI’s head of media partnerships, Varun Shetty, told MIT Technology Review that it won’t give preferential treatment to its publishing partners. Instead, OpenAI told me, the model itself finds the most trustworthy and useful source for any given question. And that can get weird too. In that very first example it showed me—when Turley ran that name search—it described a story I wrote years ago for Wired about being hacked. That story remains one of the most widely read I’ve ever written. But ChatGPT didn’t link to it. It linked to a short rewrite from The Verge. Admittedly, this was on a prototype version of search, which was, as Turley said, “risky.”  When I asked him about it, he couldn’t really explain why the model chose the sources that it did, because the model itself makes that evaluation. The company helps steer it by identifying—sometimes with the help of users—what it considers better answers, but the model actually selects them.  “And in many cases, it gets it wrong, which is why we have work to do,” said Turley. “Having a model in the loop is a very, very different mechanism than how a search engine worked in the past.” Indeed!  The model, whether it’s OpenAI’s GPT-4o or Google’s Gemini or Anthropic’s Claude, can be very, very good at explaining things. But the rationale behind its explanations, its reasons for selecting a particular source, and even the language it may use in an answer are all pretty mysterious. Sure, a model can explain very many things, but not when that comes to its own answers.  It was almost a decade ago, in 2016, when Pichai wrote that Google was moving from “mobile first” to “AI first”: “But in the next 10 years, we will shift to a world that is AI-first, a world where computing becomes universally available—be it at home, at work, in the car, or on the go—and interacting with all of these surfaces becomes much more natural and intuitive, and above all, more intelligent.”  We’re there now—sort of. And it’s a weird place to be. It’s going to get weirder. That’s especially true as these things we now think of as distinct—querying a search engine, prompting a model, looking for a photo we’ve taken, deciding what we want to read or watch or hear, asking for a photo we wish we’d taken, and didn’t, but would still like to see—begin to merge.  The search results we see from generative AI are best understood as a waypoint rather than a destination. What’s most important may not be search in itself; rather, it’s that search has given AI model developers a path to incorporating real-time information into their inputs and outputs. And that opens up all sorts of possibilities. “A ChatGPT that can understand and access the web won’t just be about summarizing results. It might be about doing things for you. And I think there’s a fairly exciting future there,” says OpenAI’s Weil. “You can imagine having the model book you a flight, or order DoorDash, or just accomplish general tasks for you in the future. It’s just once the model understands how to use the internet, the sky’s the limit.” This is the agentic future we’ve been hearing about for some time now, and the more AI models make use of real-time data from the internet, the closer it gets.  Let’s say you have a trip coming up in a few weeks. An agent that can get data from the internet in real time can book your flights and hotel rooms, make dinner reservations, and more, based on what it knows about you and your upcoming travel—all without your having to guide it. Another agent could, say, monitor the sewage output of your home for certain diseases, and order tests and treatments in response. You won’t have to search for that weird noise your car is making, because the agent in your vehicle will already have done it and made an appointment to get the issue fixed.  “It’s not always going to be just doing search and giving answers,” says Pichai. “Sometimes it’s going to be actions. Sometimes you’ll be interacting within the real world. So there is a notion of universal assistance through it all.” And the ways these things will be able to deliver answers is evolving rapidly now too. For example, today Google can not only search text, images, and even video; it can create them. Imagine overlaying that ability with search across an array of formats and devices. “Show me what a Townsend’s warbler looks like in the tree in front of me.” Or “Use my existing family photos and videos to create a movie trailer of our upcoming vacation to Puerto Rico next year, making sure we visit all the best restaurants and top landmarks.” “We have primarily done it on the input side,” he says, referring to the ways Google can now search for an image or within a video. “But you can imagine it on the output side too.” This is the kind of future Pichai says he is excited to bring online. Google has already showed off a bit of what that might look like with NotebookLM, a tool that lets you upload large amounts of text and have it converted into a chatty podcast. He imagines this type of functionality—the ability to take one type of input and convert it into a variety of outputs—transforming the way we interact with information.  In a demonstration of a tool called Project Astra this summer at its developer conference, Google showed one version of this outcome, where cameras and microphones in phones and smart glasses understand the context all around you—online and off, audible and visual—and have the ability to recall and respond in a variety of ways. Astra can, for example, look at a crude drawing of a Formula One race car and not only identify it, but also explain its various parts and their uses.  But you can imagine things going a bit further (and they will). Let’s say I want to see a video of how to fix something on my bike. The video doesn’t exist, but the information does. AI-assisted generative search could theoretically find that information somewhere online—in a user manual buried in a company’s website, for example—and create a video to show me exactly how to do what I want, just as it could explain that to me with words today. These are the kinds of things that start to happen when you put the entire compendium of human knowledge—knowledge that’s previously been captured in silos of language and format; maps and business registrations and product SKUs; audio and video and databases of numbers and old books and images and, really, anything ever published, ever tracked, ever recorded; things happening right now, everywhere—and introduce a model into all that. A model that maybe can’t understand, precisely, but has the ability to put that information together, rearrange it, and spit it back in a variety of different hopefully helpful ways. Ways that a mere index could not. That’s what we’re on the cusp of, and what we’re starting to see. And as Google rolls this out to a billion people, many of whom will be interacting with a conversational AI for the first time, what will that mean? What will we do differently? It’s all changing so quickly. Hang on, just hang on. 
We all know what it means, colloquially, to google something. You pop a few relevant words in a search box and in return get a list of blue links to the most relevant results. Maybe some quick explanations up top. Maybe some maps or sports scores or a video. But fundamentally, it’s just fetching information that’s already out there on the internet and showing it to you, in some sort of structured way. 

But all that is up for grabs. We are at a new inflection point.

The biggest change to the way search engines have delivered information to us since the 1990s is happening right now. No more keyword searching. No more sorting through links to click. Instead, we’re entering an era of conversational search. Which means instead of keywords, you use real questions, expressed in natural language. And instead of links, you’ll increasingly be met with answers, written by generative AI and based on live information from all across the internet, delivered the same way. 

Of course, Google—the company that has defined search for the past 25 years—is trying to be out front on this. In May of 2023, it began testing AI-generated responses to search queries, using its large language model (LLM) to deliver the kinds of answers you might expect from an expert source or trusted friend. It calls these AI Overviews. Google CEO Sundar Pichai described this to MIT Technology Review as “one of the most positive changes we’ve done to search in a long, long time.”

AI Overviews fundamentally change the kinds of queries Google can address. You can now ask it things like “I’m going to Japan for one week next month. I’ll be staying in Tokyo but would like to take some day trips. Are there any festivals happening nearby? How will the surfing be in Kamakura? Are there any good bands playing?” And you’ll get an answer—not just a link to Reddit, but a built-out answer with current results. 

More to the point, you can attempt searches that were once pretty much impossible, and get the right answer. You don’t have to be able to articulate what, precisely, you are looking for. You can describe what the bird in your yard looks like, or what the issue seems to be with your refrigerator, or that weird noise your car is making, and get an almost human explanation put together from sources previously siloed across the internet. It’s amazing, and once you start searching that way, it’s addictive.

And it’s not just Google. OpenAI’s ChatGPT now has access to the web, making it far better at finding up-to-date answers to your queries. Microsoft released generative search results for Bing in September. Meta has its own version. The startup Perplexity was doing the same, but with a “move fast, break things” ethos. Literal trillions of dollars are at stake in the outcome as these players jockey to become the next go-to source for information retrieval—the next Google.

Not everyone is excited for the change. Publishers are completely freaked out. The shift has heightened fears of a “zero-click” future, where search referral traffic—a mainstay of the web since before Google existed—vanishes from the scene. 

I got a vision of that future last June, when I got a push alert from the Perplexity app on my phone. Perplexity is a startup trying to reinvent web search. But in addition to delivering deep answers to queries, it will create entire articles about the news of the day, cobbled together by AI from different sources. 

On that day, it pushed me a story about a new drone company from Eric Schmidt. I recognized the story. Forbes had reported it exclusively, earlier in the week, but it had been locked behind a paywall. The image on Perplexity’s story looked identical to one from Forbes. The language and structure were quite similar. It was effectively the same story, but freely available to anyone on the internet. I texted a friend who had edited the original story to ask if Forbes had a deal with the startup to republish its content. But there was no deal. He was shocked and furious and, well, perplexed. He wasn’t alone. Forbes, the New York Times, and Condé Nast have now all sent the company cease-and-desist orders. News Corp is suing for damages. 

People are worried about what these new LLM-powered results will mean for our fundamental shared reality. It could spell the end of the canonical answer.

It was precisely the nightmare scenario publishers have been so afraid of: The AI was hoovering up their premium content, repackaging it, and promoting it to its audience in a way that didn’t really leave any reason to click through to the original. In fact, on Perplexity’s About page, the first reason it lists to choose the search engine is “Skip the links.”

But this isn’t just about publishers (or my own self-interest). 

People are also worried about what these new LLM-powered results will mean for our fundamental shared reality. Language models have a tendency to make stuff up—they can hallucinate nonsense. Moreover, generative AI can serve up an entirely new answer to the same question every time, or provide different answers to different people on the basis of what it knows about them. It could spell the end of the canonical answer.

But make no mistake: This is the future of search. Try it for a bit yourself, and you’ll see. 

Sure, we will always want to use search engines to navigate the web and to discover new and interesting sources of information. But the links out are taking a back seat. The way AI can put together a well-reasoned answer to just about any kind of question, drawing on real-time data from across the web, just offers a better experience. That is especially true compared with what web search has become in recent years. If it’s not exactly broken (data shows more people are searching with Google more often than ever before), it’s at the very least increasingly cluttered and daunting to navigate. 

Who wants to have to speak the language of search engines to find what you need? Who wants to navigate links when you can have straight answers? And maybe: Who wants to have to learn when you can just know? 


In the beginning there was Archie. It was the first real internet search engine, and it crawled files previously hidden in the darkness of remote servers. It didn’t tell you what was in those files—just their names. It didn’t preview images; it didn’t have a hierarchy of results, or even much of an interface. But it was a start. And it was pretty good. 

Then Tim Berners-Lee created the World Wide Web, and all manner of web pages sprang forth. The Mosaic home page and the Internet Movie Database and Geocities and the Hampster Dance and web rings and Salon and eBay and CNN and federal government sites and some guy’s home page in Turkey.

Until finally, there was too much web to even know where to start. We really needed a better way to navigate our way around, to actually find the things we needed. 

And so in 1994 Jerry Yang created Yahoo, a hierarchical directory of websites. It quickly became the home page for millions of people. And it was … well, it was okay. TBH, and with the benefit of hindsight, I think we all thought it was much better back then than it actually was.

But the web continued to grow and sprawl and expand, every day bringing more information online. Rather than just a list of sites by category, we needed something that actually looked at all that content and indexed it. By the late ’90s that meant choosing from a variety of search engines: AltaVista and AlltheWeb and WebCrawler and HotBot. And they were good—a huge improvement. At least at first.  

But alongside the rise of search engines came the first attempts to exploit their ability to deliver traffic. Precious, valuable traffic, which web publishers rely on to sell ads and retailers use to get eyeballs on their goods. Sometimes this meant stuffing pages with keywords or nonsense text designed purely to push pages higher up in search results. It got pretty bad. 

And then came Google. It’s hard to overstate how revolutionary Google was when it launched in 1998. Rather than just scanning the content, it also looked at the sources linking to a website, which helped evaluate its relevance. To oversimplify: The more something was cited elsewhere, the more reliable Google considered it, and the higher it would appear in results. This breakthrough made Google radically better at retrieving relevant results than anything that had come before. It was amazing. 

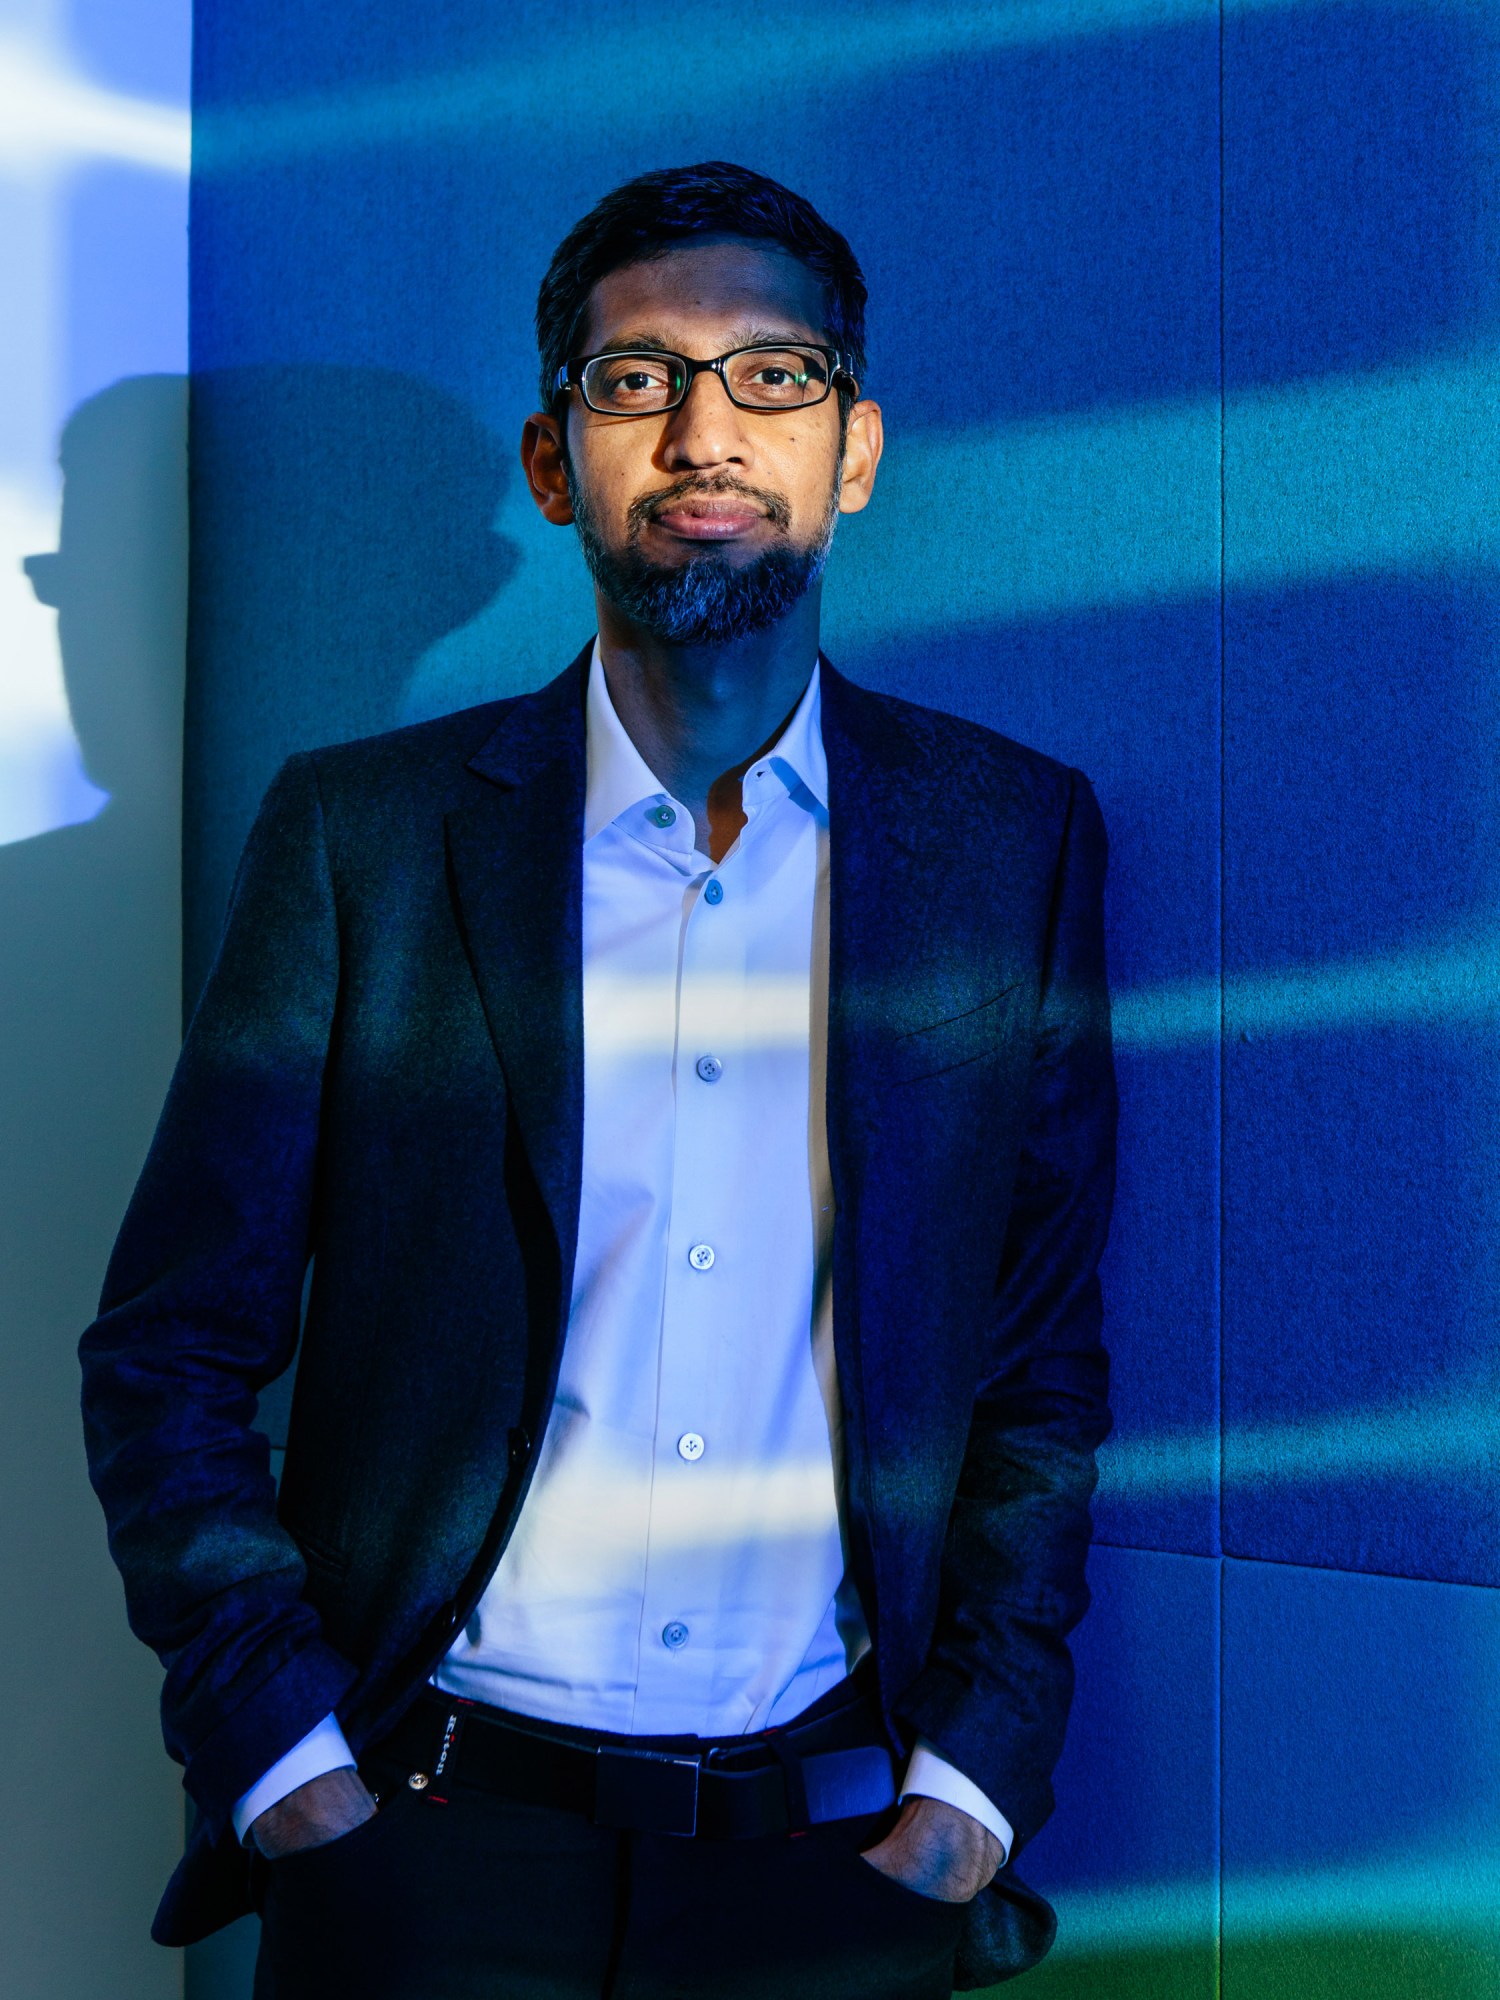
Sundar Pichai
Google CEO Sundar Pichai describes AI Overviews as “one of the most positive changes we’ve done to search in a long, long time.”
JENS GYARMATY/LAIF/REDUX

For 25 years, Google dominated search. Google was search, for most people. (The extent of that domination is currently the subject of multiple legal probes in the United States and the European Union.)  

But Google has long been moving away from simply serving up a series of blue links, notes Pandu Nayak, Google’s chief scientist for search. 

“It’s not just so-called web results, but there are images and videos, and special things for news. There have been direct answers, dictionary answers, sports, answers that come with Knowledge Graph, things like featured snippets,” he says, rattling off a litany of Google’s steps over the years to answer questions more directly. 

It’s true: Google has evolved over time, becoming more and more of an answer portal. It has added tools that allow people to just get an answer—the live score to a game, the hours a café is open, or a snippet from the FDA’s website—rather than being pointed to a website where the answer may be. 

But once you’ve used AI Overviews a bit, you realize they are different. 

Take featured snippets, the passages Google sometimes chooses to highlight and show atop the results themselves. Those words are quoted directly from an original source. The same is true of knowledge panels, which are generated from information stored in a range of public databases and Google’s Knowledge Graph, its database of trillions of facts about the world.

While these can be inaccurate, the information source is knowable (and fixable). It’s in a database. You can look it up. Not anymore: AI Overviews can be entirely new every time, generated on the fly by a language model’s predictive text combined with an index of the web. 

“I think it’s an exciting moment where we have obviously indexed the world. We built deep understanding on top of it with Knowledge Graph. We’ve been using LLMs and generative AI to improve our understanding of all that,” Pichai told MIT Technology Review. “But now we are able to generate and compose with that.”

The result feels less like a querying a database than like asking a very smart, well-read friend. (With the caveat that the friend will sometimes make things up if she does not know the answer.) 

“[The company’s] mission is organizing the world’s information,” Liz Reid, Google’s head of search, tells me from its headquarters in Mountain View, California. “But actually, for a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you.” 

That second concept—accessibility—is what Google is really keying in on with AI Overviews. It’s a sentiment I hear echoed repeatedly while talking to Google execs: They can address more complicated types of queries more efficiently by bringing in a language model to help supply the answers. And they can do it in natural language. 

That will become even more important for a future where search goes beyond text queries. For example, Google Lens, which lets people take a picture or upload an image to find out more about something, uses AI-generated answers to tell you what you may be looking at. Google has even showed off the ability to query live video. 

When it doesn’t have an answer, an AI model can confidently spew back a response anyway. For Google, this could be a real problem. For the rest of us, it could actually be dangerous.

“We are definitely at the start of a journey where people are going to be able to ask, and get answered, much more complex questions than where we’ve been in the past decade,” says Pichai. 

There are some real hazards here. First and foremost: Large language models will lie to you. They hallucinate. They get shit wrong. When it doesn’t have an answer, an AI model can blithely and confidently spew back a response anyway. For Google, which has built its reputation over the past 20 years on reliability, this could be a real problem. For the rest of us, it could actually be dangerous.

In May 2024, AI Overviews were rolled out to everyone in the US. Things didn’t go well. Google, long the world’s reference desk, told people to eat rocks and to put glue on their pizza. These answers were mostly in response to what the company calls adversarial queries—those designed to trip it up. But still. It didn’t look good. The company quickly went to work fixing the problems—for example, by deprecating so-called user-generated content from sites like Reddit, where some of the weirder answers had come from.

Yet while its errors telling people to eat rocks got all the attention, the more pernicious danger might arise when it gets something less obviously wrong. For example, in doing research for this article, I asked Google when MIT Technology Review went online. It helpfully responded that “MIT Technology Review launched its online presence in late 2022.” This was clearly wrong to me, but for someone completely unfamiliar with the publication, would the error leap out? 

I came across several examples like this, both in Google and in OpenAI’s ChatGPT search. Stuff that’s just far enough off the mark not to be immediately seen as wrong. Google is banking that it can continue to improve these results over time by relying on what it knows about quality sources.

“When we produce AI Overviews,” says Nayak, “we look for corroborating information from the search results, and the search results themselves are designed to be from these reliable sources whenever possible. These are some of the mechanisms we have in place that assure that if you just consume the AI Overview, and you don’t want to look further … we hope that you will still get a reliable, trustworthy answer.”

In the case above, the 2022 answer seemingly came from a reliable source—a story about MIT Technology Review’s email newsletters, which launched in 2022. But the machine fundamentally misunderstood. This is one of the reasons Google uses human beings—raters—to evaluate the results it delivers for accuracy. Ratings don’t correct or control individual AI Overviews; rather, they help train the model to build better answers. But human raters can be fallible. Google is working on that too. 

“Raters who look at your experiments may not notice the hallucination because it feels sort of natural,” says Nayak. “And so you have to really work at the evaluation setup to make sure that when there is a hallucination, someone’s able to point out and say, That’s a problem.”

The new search

Google has rolled out its AI Overviews to upwards of a billion people in more than 100 countries, but it is facing upstarts with new ideas about how search should work.


Search Engine

Google
The search giant has added AI Overviews to search results. These overviews take information from around the web and Google’s Knowledge Graph and use the company’s Gemini language model to create answers to search queries.

What it’s good at

Google’s AI Overviews are great at giving an easily digestible summary in response to even the most complex queries, with sourcing boxes adjacent to the answers. Among the major options, its deep web index feels the most “internety.” But web publishers fear its summaries will give people little reason to click through to the source material.


Perplexity
Perplexity is a conversational search engine that uses third-party large
language models from OpenAI and Anthropic to answer queries.

Perplexity is fantastic at putting together deeper dives in response to user queries, producing answers that are like mini white papers on complex topics. It’s also excellent at summing up current events. But it has gotten a bad rep with publishers, who say it plays fast and loose with their content.


ChatGPT
While Google brought AI to search, OpenAI brought search to ChatGPT. Queries that the model determines will benefit from a web search automatically trigger one, or users can manually select the option to add a web search.

Thanks to its ability to preserve context across a conversation, ChatGPT works well for performing searches that benefit from follow-up questions—like planning a vacation through multiple search sessions. OpenAI says users sometimes go “20 turns deep” in researching queries. Of these three, it makes links out to publishers least prominent.


When I talked to Pichai about this, he expressed optimism about the company’s ability to maintain accuracy even with the LLM generating responses. That’s because AI Overviews is based on Google’s flagship large language model, Gemini, but also draws from Knowledge Graph and what it considers reputable sources around the web. 

“You’re always dealing in percentages. What we have done is deliver it at, like, what I would call a few nines of trust and factuality and quality. I’d say 99-point-few-nines. I think that’s the bar we operate at, and it is true with AI Overviews too,” he says. “And so the question is, are we able to do this again at scale? And I think we are.”

There’s another hazard as well, though, which is that people ask Google all sorts of weird things. If you want to know someone’s darkest secrets, look at their search history. Sometimes the things people ask Google about are extremely dark. Sometimes they are illegal. Google doesn’t just have to be able to deploy its AI Overviews when an answer can be helpful; it has to be extremely careful not to deploy them when an answer may be harmful. 

“If you go and say ‘How do I build a bomb?’ it’s fine that there are web results. It’s the open web. You can access anything,” Reid says. “But we do not need to have an AI Overview that tells you how to build a bomb, right? We just don’t think that’s worth it.” 

But perhaps the greatest hazard—or biggest unknown—is for anyone downstream of a Google search. Take publishers, who for decades now have relied on search queries to send people their way. What reason will people have to click through to the original source, if all the information they seek is right there in the search result?  

Rand Fishkin, cofounder of the market research firm SparkToro, publishes research on so-called zero-click searches. As Google has moved increasingly into the answer business, the proportion of searches that end without a click has gone up and up. His sense is that AI Overviews are going to explode this trend.  

“If you are reliant on Google for traffic, and that traffic is what drove your business forward, you are in long- and short-term trouble,” he says. 

Don’t panic, is Pichai’s message. He argues that even in the age of AI Overviews, people will still want to click through and go deeper for many types of searches. “The underlying principle is people are coming looking for information. They’re not looking for Google always to just answer,” he says. “Sometimes yes, but the vast majority of the times, you’re looking at it as a jumping-off point.” 

Reid, meanwhile, argues that because AI Overviews allow people to ask more complicated questions and drill down further into what they want, they could even be helpful to some types of publishers and small businesses, especially those operating in the niches: “You essentially reach new audiences, because people can now express what they want more specifically, and so somebody who specializes doesn’t have to rank for the generic query.”


 “I’m going to start with something risky,” Nick Turley tells me from the confines of a Zoom window. Turley is the head of product for ChatGPT, and he’s showing off OpenAI’s new web search tool a few weeks before it launches. “I should normally try this beforehand, but I’m just gonna search for you,” he says. “This is always a high-risk demo to do, because people tend to be particular about what is said about them on the internet.” 

He types my name into a search field, and the prototype search engine spits back a few sentences, almost like a speaker bio. It correctly identifies me and my current role. It even highlights a particular story I wrote years ago that was probably my best known. In short, it’s the right answer. Phew? 

A few weeks after our call, OpenAI incorporated search into ChatGPT, supplementing answers from its language model with information from across the web. If the model thinks a response would benefit from up-to-date information, it will automatically run a web search (OpenAI won’t say who its search partners are) and incorporate those responses into its answer, with links out if you want to learn more. You can also opt to manually force it to search the web if it does not do so on its own. OpenAI won’t reveal how many people are using its web search, but it says some 250 million people use ChatGPT weekly, all of whom are potentially exposed to it.  

“There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be a better super-assistant for you.”

Kevin Weil, chief product officer, OpenAI

According to Fishkin, these newer forms of AI-assisted search aren’t yet challenging Google’s search dominance. “It does not appear to be cannibalizing classic forms of web search,” he says. 

OpenAI insists it’s not really trying to compete on search—although frankly this seems to me like a bit of expectation setting. Rather, it says, web search is mostly a means to get more current information than the data in its training models, which tend to have specific cutoff dates that are often months, or even a year or more, in the past. As a result, while ChatGPT may be great at explaining how a West Coast offense works, it has long been useless at telling you what the latest 49ers score is. No more. 

“I come at it from the perspective of ‘How can we make ChatGPT able to answer every question that you have? How can we make it more useful to you on a daily basis?’ And that’s where search comes in for us,” Kevin Weil, the chief product officer with OpenAI, tells me. “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be able to be a better super-assistant for you.”

Today ChatGPT is able to generate responses for very current news events, as well as near-real-time information on things like stock prices. And while ChatGPT’s interface has long been, well, boring, search results bring in all sorts of multimedia—images, graphs, even video. It’s a very different experience. 

Weil also argues that ChatGPT has more freedom to innovate and go its own way than competitors like Google—even more than its partner Microsoft does with Bing. Both of those are ad-dependent businesses. OpenAI is not. (At least not yet.) It earns revenue from the developers, businesses, and individuals who use it directly. It’s mostly setting large amounts of money on fire right now—it’s projected to lose $14 billion in 2026, by some reports. But one thing it doesn’t have to worry about is putting ads in its search results as Google does. 

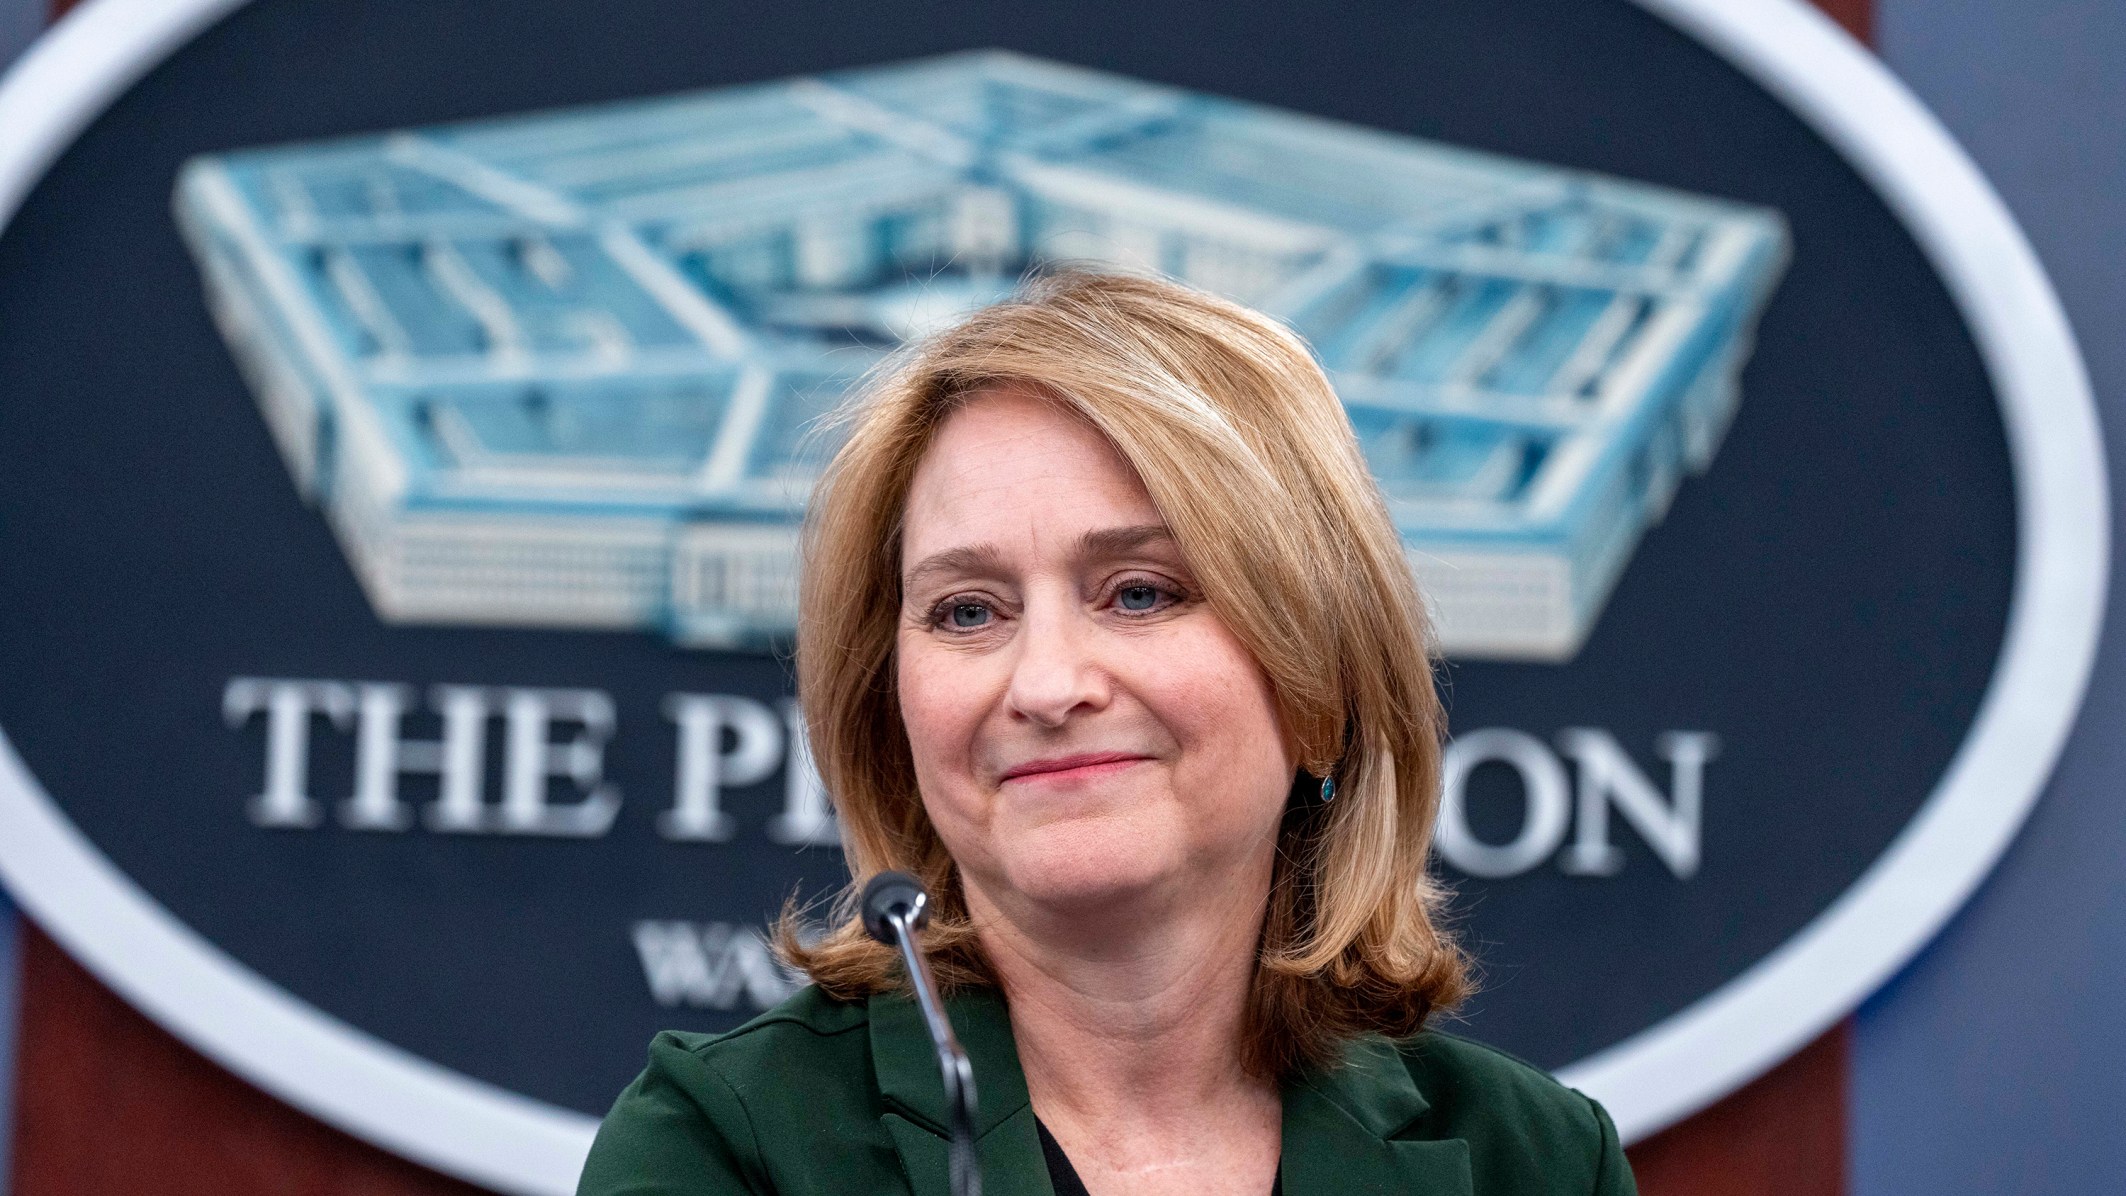
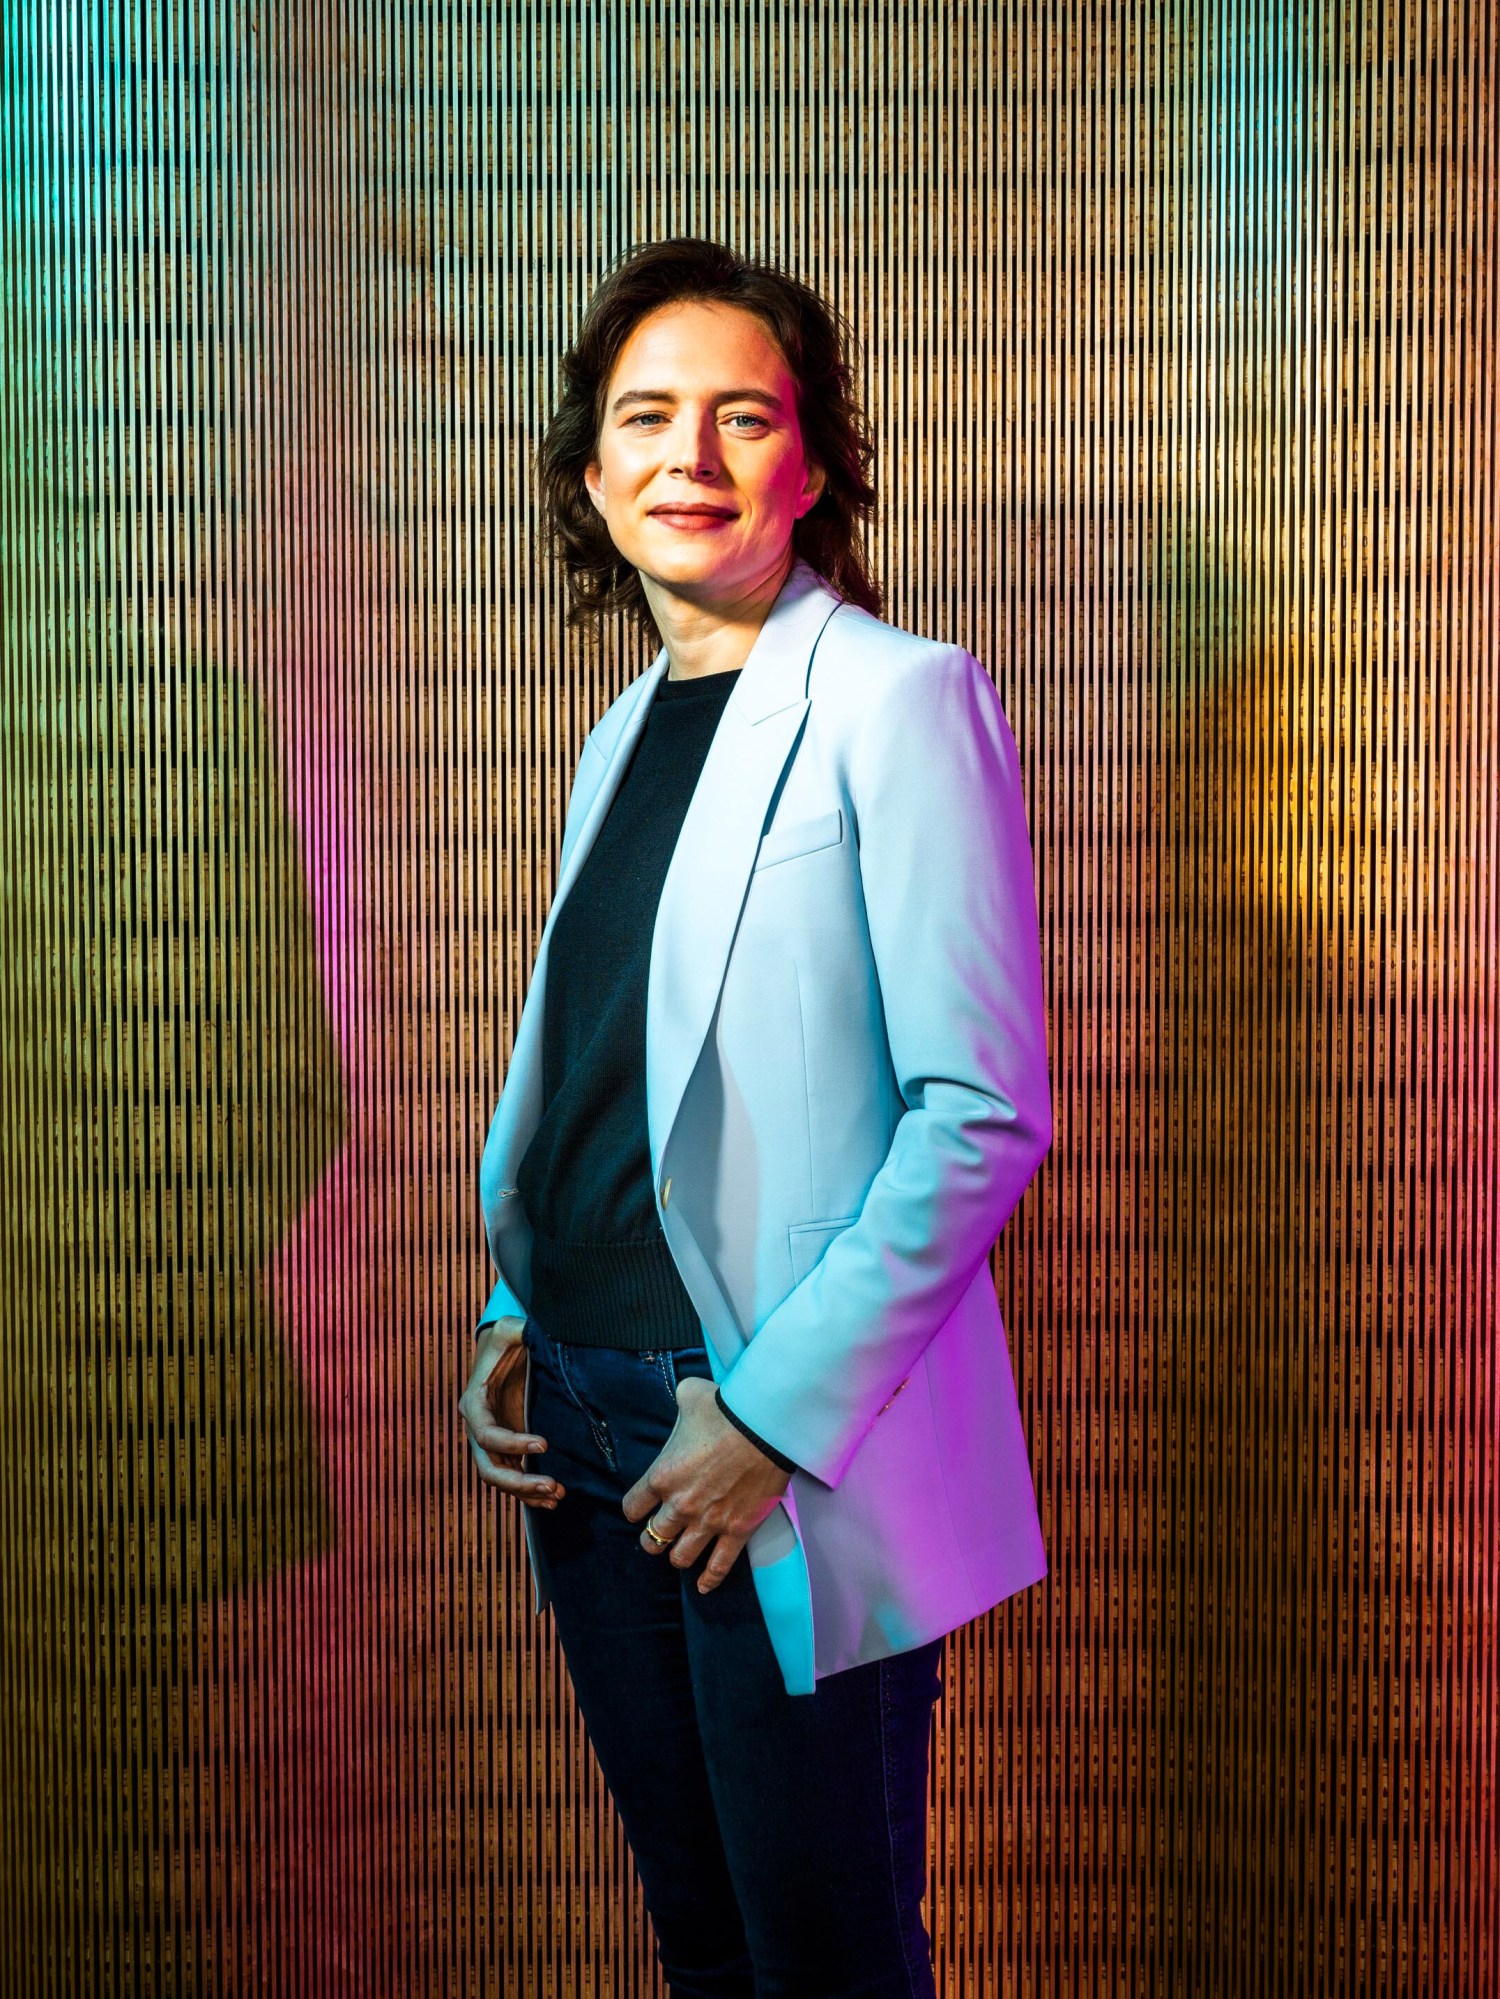
Elizabeth Reid
“For a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you,” says Google head of search, Liz Reid.
WINNI WINTERMEYER/REDUX

Like Google, ChatGPT is pulling in information from web publishers, summarizing it, and including it in its answers. But it has also struck financial deals with publishers, a payment for providing the information that gets rolled into its results. (MIT Technology Review has been in discussions with OpenAI, Google, Perplexity, and others about publisher deals but has not entered into any agreements. Editorial was neither party to nor informed about the content of those discussions.)

But the thing is, for web search to accomplish what OpenAI wants—to be more current than the language model—it also has to bring in information from all sorts of publishers and sources that it doesn’t have deals with. OpenAI’s head of media partnerships, Varun Shetty, told MIT Technology Review that it won’t give preferential treatment to its publishing partners.

Instead, OpenAI told me, the model itself finds the most trustworthy and useful source for any given question. And that can get weird too. In that very first example it showed me—when Turley ran that name search—it described a story I wrote years ago for Wired about being hacked. That story remains one of the most widely read I’ve ever written. But ChatGPT didn’t link to it. It linked to a short rewrite from The Verge. Admittedly, this was on a prototype version of search, which was, as Turley said, “risky.” 

When I asked him about it, he couldn’t really explain why the model chose the sources that it did, because the model itself makes that evaluation. The company helps steer it by identifying—sometimes with the help of users—what it considers better answers, but the model actually selects them. 

“And in many cases, it gets it wrong, which is why we have work to do,” said Turley. “Having a model in the loop is a very, very different mechanism than how a search engine worked in the past.”

Indeed! 

The model, whether it’s OpenAI’s GPT-4o or Google’s Gemini or Anthropic’s Claude, can be very, very good at explaining things. But the rationale behind its explanations, its reasons for selecting a particular source, and even the language it may use in an answer are all pretty mysterious. Sure, a model can explain very many things, but not when that comes to its own answers. 


It was almost a decade ago, in 2016, when Pichai wrote that Google was moving from “mobile first” to “AI first”: “But in the next 10 years, we will shift to a world that is AI-first, a world where computing becomes universally available—be it at home, at work, in the car, or on the go—and interacting with all of these surfaces becomes much more natural and intuitive, and above all, more intelligent.” 

We’re there now—sort of. And it’s a weird place to be. It’s going to get weirder. That’s especially true as these things we now think of as distinct—querying a search engine, prompting a model, looking for a photo we’ve taken, deciding what we want to read or watch or hear, asking for a photo we wish we’d taken, and didn’t, but would still like to see—begin to merge. 

The search results we see from generative AI are best understood as a waypoint rather than a destination. What’s most important may not be search in itself; rather, it’s that search has given AI model developers a path to incorporating real-time information into their inputs and outputs. And that opens up all sorts of possibilities.

“A ChatGPT that can understand and access the web won’t just be about summarizing results. It might be about doing things for you. And I think there’s a fairly exciting future there,” says OpenAI’s Weil. “You can imagine having the model book you a flight, or order DoorDash, or just accomplish general tasks for you in the future. It’s just once the model understands how to use the internet, the sky’s the limit.”

This is the agentic future we’ve been hearing about for some time now, and the more AI models make use of real-time data from the internet, the closer it gets. 

Let’s say you have a trip coming up in a few weeks. An agent that can get data from the internet in real time can book your flights and hotel rooms, make dinner reservations, and more, based on what it knows about you and your upcoming travel—all without your having to guide it. Another agent could, say, monitor the sewage output of your home for certain diseases, and order tests and treatments in response. You won’t have to search for that weird noise your car is making, because the agent in your vehicle will already have done it and made an appointment to get the issue fixed. 

“It’s not always going to be just doing search and giving answers,” says Pichai. “Sometimes it’s going to be actions. Sometimes you’ll be interacting within the real world. So there is a notion of universal assistance through it all.”

And the ways these things will be able to deliver answers is evolving rapidly now too. For example, today Google can not only search text, images, and even video; it can create them. Imagine overlaying that ability with search across an array of formats and devices. “Show me what a Townsend’s warbler looks like in the tree in front of me.” Or “Use my existing family photos and videos to create a movie trailer of our upcoming vacation to Puerto Rico next year, making sure we visit all the best restaurants and top landmarks.”

“We have primarily done it on the input side,” he says, referring to the ways Google can now search for an image or within a video. “But you can imagine it on the output side too.”

This is the kind of future Pichai says he is excited to bring online. Google has already showed off a bit of what that might look like with NotebookLM, a tool that lets you upload large amounts of text and have it converted into a chatty podcast. He imagines this type of functionality—the ability to take one type of input and convert it into a variety of outputs—transforming the way we interact with information. 

In a demonstration of a tool called Project Astra this summer at its developer conference, Google showed one version of this outcome, where cameras and microphones in phones and smart glasses understand the context all around you—online and off, audible and visual—and have the ability to recall and respond in a variety of ways. Astra can, for example, look at a crude drawing of a Formula One race car and not only identify it, but also explain its various parts and their uses. 

But you can imagine things going a bit further (and they will). Let’s say I want to see a video of how to fix something on my bike. The video doesn’t exist, but the information does. AI-assisted generative search could theoretically find that information somewhere online—in a user manual buried in a company’s website, for example—and create a video to show me exactly how to do what I want, just as it could explain that to me with words today.

These are the kinds of things that start to happen when you put the entire compendium of human knowledge—knowledge that’s previously been captured in silos of language and format; maps and business registrations and product SKUs; audio and video and databases of numbers and old books and images and, really, anything ever published, ever tracked, ever recorded; things happening right now, everywhere—and introduce a model into all that. A model that maybe can’t understand, precisely, but has the ability to put that information together, rearrange it, and spit it back in a variety of different hopefully helpful ways. Ways that a mere index could not.

That’s what we’re on the cusp of, and what we’re starting to see. And as Google rolls this out to a billion people, many of whom will be interacting with a conversational AI for the first time, what will that mean? What will we do differently? It’s all changing so quickly. Hang on, just hang on. 
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Chevron preps for big 2027 exploration capex ramp

Chevron Corp., Houston, could increase its exploration capital budget by more than $500 million in 2027 as executives look to capitalize on strong commodity markets and build on an organizational shuffle that has centralized and accelerated decision-making. Speaking after Chevron reported its third-quarter results, vice-chairman Mark Nelson told analysts that

Read More »

New Cisco firewall zero-day being actively exploited

A high-severity flaw in the Remote Access SSL VPN service of Cisco Secure Firewall Adaptive Security Appliance (ASA) and Cisco Secure Firewall Threat Defense (FTD) is under active exploitation to crash vulnerable devices. The vulnerability, tracked as CVE-2026-76418 and rated 8.6 in severity, is due to logic errors when secondary

Read More »

Shell adds to Gulf of Mexico production with Silvertip Phase 3 startup

@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor

Read More »

DOE’s Office of Critical Minerals and Energy Innovation Launches PROSPECT Implementation Prize To Expand America’s Mining and Critical Minerals Workforce

WASHINGTON—The U.S. Department of Energy’s (DOE) Office of Critical Minerals and Energy Innovation today launched the PROSPECT Implementation Prize, which will award up to $70 million to support universities in expanding the skilled workforce required to domestically produce, process, recover, and recycle critical minerals. This prize competition is part of DOE’s broader up to $100 million Providing Opportunities for Specialized Education in Critical Technologies (PROSPECT) initiative, which delivers on President Trump’s bold agenda to restore American energy dominance, secure long term economic growth, rebuild domestic supply chains, and reduce reliance on foreign adversaries for critical minerals. “DOE has laid the groundwork for growing America’s critical minerals workforce—and now we’re turning those plans into reality. Universities are taking the necessary steps to deliver measurable results, from expanding student support through scholarships to modernizing curricula with new training modules, certificates, and Super Intelligence,” said Assistant Secretary of Energy Audrey Robertson. “The Trump Administration is committed to freeing America from dependence on foreign sources of critical minerals that are essential to powering our economy, and creating good-paying, fulfilling jobs for Americans.” PROSPECT has established a near-term goal of doubling the number of graduates with mining, minerals, and associated supply chain credentials within two years. The PROSPECT Implementation Prize follows the recently completed PROSPECT Planning Prize, which awarded funding to universities for developing comprehensive workforce-expansion plans. The Implementation Prize focuses on putting workforce development programs into action and demonstrating measurable results. The U.S. faces a growing shortage of skilled mining and critical minerals professionals, with an estimated 6,000 new mining engineers needed over the next decade. Expanding America’s talent pipeline is essential to strengthening domestic supply chains and reducing reliance on foreign nations for critical materials. Mining and geological engineering careers offer strong earning potential, with a median annual wage of $106,220 in 2025.

Read More »

Energy Department Announces Over $230 Million Funding Opportunity to Strengthen America’s Grid Supply Chain and Lower Electricity Costs

WASHINGTON— The U.S. Department of Energy (DOE) today announced a $237 million funding opportunity to boost American manufacturing and strengthen supply chains for critical electric grid components. The investment is expected to deliver an estimated $125 million in annual utility savings and keep an estimated $50 million per year in the U.S. economy that would otherwise go to foreign suppliers. The investments will help facilitate the reliable flow of electricity for American families and businesses and position the U.S. as a global leader in foundational technologies, by incentivizing the refurbishment and reuse of critical equipment and encouraging the adoption of alternative materials and subcomponents that are sourced and made in America. These efforts will lower costs, strengthen grid reliability, and meet growing electricity demand.  “President Trump is bringing American industry and manufacturing back home, including the critical equipment and components needed to power our nation,” said U.S. Secretary of Energy Chris Wright. “The Energy Department is investing in American-made technologies and modernizing our grid to reduce reliance on foreign suppliers and deliver affordable, reliable, electricity.” This funding opportunity will support projects in two key areas:  Up to $50 million will be provided to projects that promote greater refurbishment and reuse of existing grid equipment and materials; Up to $187 million will be provided to projects that will increase the use of alternative materials and subcomponents sourced and made in the U.S, reducing dependence on imports.  “America should never have to rely on foreign suppliers to keep the lights on,” said Office of Electricity Assistant Secretary Katie Jereza. “We’re putting American ingenuity to work, developing next-generation grid technologies that strengthen our domestic supply chain, help lower costs, and make our grid more reliable. The power to secure our energy future should be in our own hands.” The Grid Supply Chain Alternatives to

Read More »

States must take a critical eye to gas plants proposed over clean energy

Listen to the article 5 min This audio is auto-generated. Please let us know if you have feedback. Will Scott is the North Carolina policy director of the Environmental Defense Fund. Hudson Kingston is the legal director at CURE, a nonprofit rural environmental and energy democracy organization in Minnesota. The data center boom has become a cash cow for investor-owned utilities across the country. Many utility companies are seeking approval for costly new gas plants and other fossil fuel infrastructure based on uncertain projections of future demand for data centers and other large customers. If those projections fall short, ratepayers are left with 30 years of payments for projects that are increasingly expensive to build and slow to develop. We can’t let phantom projections for new data centers leave regular ratepayers with the bill. Hudson Kingston Historically, state regulators have given utilities significant latitude to pursue new generation. Yet, as heating and cooling bills become painfully unaffordable for families and local businesses, utility regulators are increasingly skeptical of proposals that could leave them paying for decades of dirty and expensive fossil fuel infrastructure, when clean, renewable energy and batteries provide a reliable, homegrown and affordable alternative. Indeed, a recent study found that batteries are now cheaper than gas peaker plants, globally. Will Scott While customers are forced to pay increasingly higher energy bills, utility shareholders are guaranteed profits on centralized fossil energy projects. The bigger and more costly the construction, the more money energy corporations make. Once new energy infrastructure is approved by state regulators, utilities can start recovering the costs through customer rates even before the project is built and in use. Because utilities make profits off the infrastructure they build, and not the energy they sell, executives have a financial incentive to keep building to benefit shareholders.  To

Read More »

TotalEnergies farms out partial interest in block offshore Nigeria ahead of appraisal

TotalEnergies agreed to farm out a 40% participating interest in Block OPL257 offshore Nigeria to South Atlantic Petroleum Ltd. (SAPETRO). Upon completion of the deal, TotalEnergies will hold a 50% operated interest in the block with SAPETRO (40%) and Conoil (10%) as partners. TotalEnergies became operator of the block following a 2025 asset interest exchange with Conoil. OPL257 lies 150 km offshore Nigeria and covers an area of about 370 sq km. The block is adjacent to PPL261 where TotalEnergies (24%) and its partners, including SAPETRO, discovered Egina South oil field in 2005, which lies in 1,650 m of water and straddles both blocks. Drilling of an Egina South appraisal well is expected in the coming months on the OPL257 side. The field is expected to be developed as a tie-back to the Egina FPSO about 30 km away. The project has the potential to deliver up to 140 million bbl of oil reserves, according to SAPETRO. Consolidating the partnership “paves the way for a quick appraisal campaign and subsequent development of Egina South in the success case,” said Mike Sangster, senior vice-president Africa exploration and production at TotalEnergies. Completion of the farm-out agreement is subject to customary conditions, including regulatory approvals.

Read More »

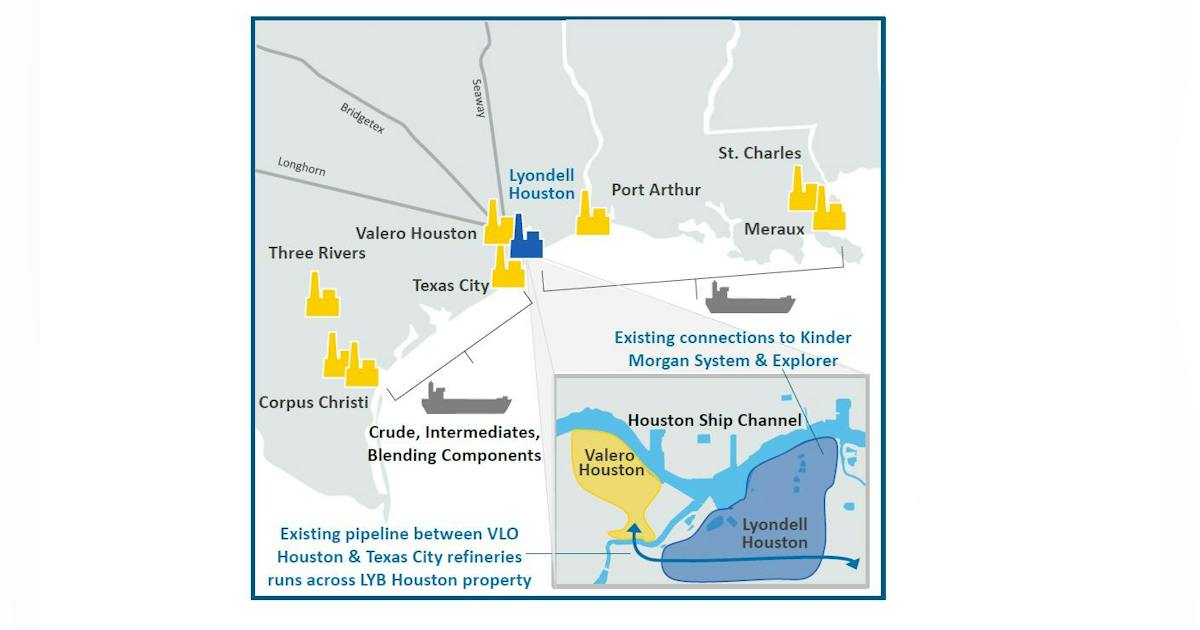
Valero to acquire former LyondellBasell Houston oil refinery, restart 165,000 b/d by end-2027

Valero Energy Corp. plans to acquire a former LyondellBasell Industries NV Houston refinery and restart 165,000 b/d of light sweet crude oil processing by yearend 2027. Valero Refining-Texas LP has agreed to acquire the shuttered full-conversion refinery from LyondellBasell for $320.5 million. The transaction includes about 700 acres on the Houston Ship Channel adjacent to the Valero Houston Refinery, 13.5 million bbl of storage capacity, and logistics infrastructure including marine docks, rail-loading facilities, and truck racks. The acquisition will help address intermediate feedstock shortages across Valero’s US Gulf Coast refining system, reducing reliance on third-party purchases while creating opportunities to integrate refining and logistics operations, the company said in an Oct. 30 presentation. Incremental FCC and hydrocracker feed production would reduce external feedstock sourcing, while excess hydrotreating capacity could be used to upgrade intermediates from other Valero US Gulf Coast refineries, the company said. By yearend 2027, Valero expects to restart light sweet crude oil processing and said the site could support future investment in heavy sour crude processing, according to chairman, chief executive officer, and president Lane Riggs. The company did not provide financial details or a timetable for potential heavy sour crude processing projects. LyondellBasell announced plans in April 2022 to cease operation of subsidiary Houston Refining LP’s 268,000-b/d refinery as part of its exit from the crude oil refining business. Following delays, the refinery was shuttered in March 2025. Over the years, LyondellBasell evaluated options for the site, including a potential plan to transition the refinery into a hydrogen production site. Ultimately, the company said, it determined selling the asset “offered the most compelling opportunity” to advance the company’s priorities. Closing of the transaction is expected by yearend, subject to customary closing conditions.

Read More »

Celebrate National Bioenergy Day: Explore the Possibilities of Biomass

How can biomass power new possibilities for energy innovation and the products we use every day?  Today is National Bioenergy Day, an annual opportunity to recognize the role biomass and innovative technologies can play in strengthening the U.S. bioeconomy. Bioenergy is a form of energy produced from alternative feedstocks called biomass. These resources, which include agricultural and forestry residues, purpose-grown crops, algae, and waste materials, can be converted into chemicals, fertilizers, alternative fuels, and other materials to support farmers, ranchers, and consumers while also lowering prices through increased supply. The United States has an abundant supply of biomass. The U.S. Department of Energy’s (DOE) Alternative Fuels and Feedstocks Office (AFFO) Billion-Ton Report establishes America’s potential to produce more than 1 billion tons of biomass annually, highlighting the scale of resources available to support a growing bioeconomy and energy security and dominance.  In celebration of National Bioenergy Day, AFFO is highlighting recent investments, research accomplishments, and resources that demonstrate the possibilities of biomass and the innovative technologies that transform these resources into valuable products. Exploring Bioenergy in Action What does that transformation look like? Explore AFFO resources that cover the basics of bioenergy and offer a closer look at how researchers are advancing technologies across the bioenergy supply chain.  Watch the Bioenergy 101 video to learn how biomass is broken down and refined through various methods, including combustion, gasification, and fermentation, to advance technology development and innovation across the entire biomass-to-bioenergy supply chain.  Take a look inside the Idaho National Laboratory’s Biomass Feedstock National User Facility, which offers technology and expertise to help the U.S. bioenergy industry overcome challenges associated with the scale-up and integration of biomass preprocessing facilities. Investing in Emerging Chemical Technologies  These efforts are part of a broader push to move promising technologies from research to commercial application. AFFO recently announced the Accelerating Scale-up

Read More »

7×24 Fall 2026: AI Frontier Futurist Meets Data Center OG

A 1988 Data Center Becomes a 20 MW AI Asset The second presentation, Converting a 1990 Enterprise Data Center to 20MW AI Workloads, featured Coe alongside Ari Chernikoff, vice president of development at Legacy Investing, and Dan Amundson, project manager at Gardner Builders. The project centered on 1001 Third Avenue South in downtown Minneapolis, a financial-services computing facility originally constructed in 1988. The building had supported earlier generations of enterprise computing before portions were converted to commercial office space and smaller colocation operations. Although its remaining operating data center load had declined to approximately 500 kilowatts by the time the AI redevelopment began, the property retained substantial infrastructure inherited from its original mission-critical design. Tall ceilings, robust floor loading, raised access floors, existing medium-voltage substations, and established utility connections made the building an unusually strong candidate for conversion. These characteristics, Chernikoff explained, can determine whether an existing building offers a practical path to high-density computing or proves economically unsuitable for redevelopment. Legacy Investing had identified a market opportunity in what Chernikoff called the industry’s “missing middle”: facilities generally ranging from 20 MW to 80 MW, rather than the 100 MW-plus campuses increasingly associated with hyperscale and frontier AI development. The company viewed existing buildings with available power and favorable infrastructure characteristics as potential shortcuts to deployment, particularly where demand for AI inference and other latency-sensitive workloads favored proximity to major urban markets. Following an AI tenant commitment in summer 2024, the development team faced an aggressive initial requirement: Deliver the first 5 MW of capacity by the end of that year. The first phase was ready for service approximately four months after Gardner’s involvement became formalized, followed by another 5 MW in 2025 and an expansion program ultimately reaching 20 MW over roughly 20 months. All of this had to

Read More »

Gartner warns $3.5T in AI infrastructure spending could be at risk by 2030

Musk predicted that more than 200 neocloud companies could face significant financial distress, predicting that only a small number would survive the coming shakeout. He also said SpaceX would not acquire any of the companies, describing such purchases as “pointless.” The chickens are already coming home to roost on the neoclouds. CoreWeave, Nebius, Applied Digital and TeraWulf have reported quarterly losses over the past year, while IREN has failed to turn a profit in its past three quarters. Shares of CoreWeave, Nebius and IREN have fallen more than 30% during October, according to Reuters. Building AI data centers requires substantial upfront investment in GPUs, networking equipment, power systems, cooling infrastructure and facilities. Operators must then generate enough revenue from leasing computing capacity to cover operating expenses, interest payments and equipment replacement.

Read More »

The 50-Gigawatt Test: SemiAnalysis Sees a Historic Data Center Surge in 2027

The global data center industry is approaching a potentially historic test of its ability to turn artificial intelligence investment into operational infrastructure. In a provocative new forecast, semiconductor and AI infrastructure research firm SemiAnalysis predicts that approximately 51.2 gigawatts of net data center IT capacity will be added globally, excluding China, during 2027. That would represent more than double the 25 GW the firm expects to be added in 2026. Published October 19, the report, Datacenters 2027: The Year of Acceleration, +50GW in a Single Year, makes a forceful argument that much of this unprecedented expansion is already visible in the industry’s construction pipeline. Authored by Jeremie Eliahou Ontiveros, Reyk Knuhtsen and Dylan Patel, the analysis draws on SemiAnalysis’ proprietary tracking of construction starts, individual buildings, hyperscale leasing commitments, equipment procurement and project financing. Its researchers identify more than 60 GW of data center capacity under construction. Among the 40 largest campuses they examined, more than 24 GW is reportedly in advanced stages of development, with much of that capacity expected to be delivered in 2027. The forecast is not entirely composed of projects already under construction, however. SemiAnalysis’ capacity chart includes approximately 11.9 GW of 2027 additions associated with projects still classified as planned. The remainder is associated with facilities already operating or under construction, according to the model’s building-status categories. SemiAnalysis argues that the volume and maturity of projects already underway make a dramatic acceleration increasingly likely, despite well-documented constraints involving electricity, construction labor, equipment and capital. But the prediction has also become the subject of a revealing industry debate, with competing forecasts and new corporate disclosures raising questions about how much infrastructure can actually be delivered on schedule. The disagreement is no longer principally about whether AI infrastructure demand is real. It is about whether the industrial

Read More »

HPE’s Quantum Computing Bet: A Multi-Vendor Path to the Data Center

QuEra Deal Targets On-Premises Quantum Integration Under the expanded collaboration, HPE and QuEra intend to develop integrated testbeds, software interoperability, hybrid algorithms and performance benchmarks to support future quantum deployments alongside HPE Cray supercomputing infrastructure. The work is intended to address the practical requirements of coordinating quantum processors with the classical computing systems that prepare workloads, process results and support quantum error correction. QuEra Chief Commercial Officer Yuval Boger, who previously discussed the development of hybrid quantum-classical infrastructure on the DCF Show, emphasized that integrating quantum hardware into an HPC environment presents different engineering challenges than providing access through the cloud. Boger said, “HPE’s deep experience in supercomputing gives organizations the benefit of working with a partner who can solve that problem at the scale they need.” The collaboration envisions deploying future fault-tolerant quantum hardware at customer facilities rather than requiring organizations to rely exclusively on cloud-based quantum computing services. That option could appeal to national laboratories, defense organizations, pharmaceutical researchers and other institutions managing classified information, proprietary intellectual property or data subject to sovereignty requirements. QuEra’s neutral-atom architecture uses individual atoms as qubits, manipulating them with lasers and electromagnetic controls. Unlike superconducting quantum processors, which generally require dilution refrigerators operating at temperatures measured in millikelvin, neutral-atom systems can operate without extreme cryogenic refrigeration. They still require specialized laser systems, vacuum equipment, precision optics and environmental controls, presenting facility requirements substantially different from those of conventional servers. On-premises quantum-HPC integration is already being tested. In Japan, the National Institute of Advanced Industrial Science and Technology (AIST) operates QuEra’s 260-physical-qubit Gemini neutral-atom computer as part of its ABCI-Q research platform, which also incorporates an NVIDIA H100-based AI supercomputer. An October 26 case study published by QuEra describes Gemini operating in a separate building approximately 350 meters from the main GPU installation,

Read More »

At 7×24 Exchange, AI Data Center Growth Confronts New Realities of Power, Grid Reliability and Community Trust

DC BLOX: Community Engagement Must Go Beyond Public Relations The afternoon program shifted attention from electrical infrastructure to the growing challenges surrounding data center development and community acceptance. In a discussion moderated by Juli Ierulli, strategic account manager at Environmental Air Systems and vice president of 7×24 Exchange International, Michael Clark, senior vice president of data center construction at DC BLOX, described how the company has revised its approach to engaging communities as it expands into new markets. Clark acknowledged that DC BLOX had encountered significant opposition after entering markets where it lacked the established relationships that had supported earlier developments across the Southeast. “We made multiple stumbles in some of those new markets,” he said, describing how the company sometimes found itself responding to negative publicity rather than presenting a clear explanation of its plans and commitments. The experience led DC BLOX to develop a more systematic approach to community engagement, emphasizing early communication, site-specific websites, accessible explanations of resource consumption and written commitments that residents and officials can evaluate. Clark also pointed to what he called the industry’s “NDA hangover,” reflecting years of development activity conducted under confidentiality agreements that frequently left neighboring communities unaware of what was being planned. But perhaps the most revealing moment came when Clark recounted a conversation with residents near a DC BLOX development in Rockdale County, Georgia. After the company outlined the countywide economic and community benefits expected from the project, one neighbor challenged the distribution of those benefits. “So the rest of the county gets the benefit and we have to pay all the costs,” the resident observed, according to Clark. The question captured a fundamental tension in the industry’s community engagement efforts: tax revenues and economic development benefits may extend across a county, while nearby residents experience the immediate effects

Read More »

NVIDIA’s DSX POD Pushes AI Factory Construction Toward the Assembly Line

Crusoe Brings an Established Modular Model to DSX POD For Crusoe, NVIDIA’s announcement builds on a modular computing strategy already in operation. In its October 21 announcement, Crusoe confirmed that its Spark modular AI data center platform will support DSX POD, extending a manufacturing and deployment approach the company says it has pursued since 2020. Crusoe has expanded its manufacturing capabilities through the acquisition of electrical equipment specialist Easter-Owens Electric and the development of its 352,000-square-foot Crusoe Spark Factory in Brighton, Colorado. The company also introduced Crusoe Spark Liquid, a sixth-generation modular system engineered for ultra-high-density infrastructure, including NVIDIA Vera Rubin NVL72. Next-generation liquid-cooled units are planned for 2027. Crusoe’s vertically integrated model connects infrastructure design and manufacturing with deployment and cloud operations through Crusoe Cloud. The company says it can deliver productive AI capacity in as little as three months, although that timeline is distinct from NVIDIA’s narrower 14-day prepared-site deployment claim. “Modular isn’t a new strategy or pivot for us. It’s been in our DNA since our founding,” said Bryan Schramm, Crusoe’s head of Spark. Crusoe’s involvement demonstrates that the manufacturing model predates DSX POD. NVIDIA is not inventing modular data center infrastructure; it is attempting to establish a common architecture around capabilities that suppliers such as Crusoe have already spent years developing. That distinction matters as the industry evaluates whether standardized AI factory designs can deliver manufacturing efficiencies at a scale beyond individual suppliers’ existing operations. Vertiv and Polar Put the Deployment Model to Work in Norway The European dimension of NVIDIA’s announcement is reflected in a deployment involving Vertiv and Polar Data Centers at Herøya, Norway. According to Vertiv’s October 21 announcement, Polar is applying a factory-built infrastructure approach to the initial 41 MW phase of a multiphase AI data center campus designed to scale to

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »