Stay Ahead, Stay ONMINE

How to build a better AI benchmark

It’s not easy being one of Silicon Valley’s favorite benchmarks.  SWE-Bench (pronounced “swee bench”) launched in November 2024 to evaluate an AI model’s coding skill, using more than 2,000 real-world programming problems pulled from the public GitHub repositories of 12 different Python-based projects.  In the months since then, it’s quickly become one of the most popular tests in AI. A SWE-Bench score has become a mainstay of major model releases from OpenAI, Anthropic, and Google—and outside of foundation models, the fine-tuners at AI firms are in constant competition to see who can rise above the pack. The top of the leaderboard is a pileup between three different fine tunings of Anthropic’s Claude Sonnet model and Amazon’s Q developer agent. Auto Code Rover—one of the Claude modifications—nabbed the number two spot in November, and was acquired just three months later. Despite all the fervor, this isn’t exactly a truthful assessment of which model is “better.” As the benchmark has gained prominence, “you start to see that people really want that top spot,” says John Yang, a researcher on the team that developed SWE-Bench at Princeton University. As a result, entrants have begun to game the system—which is pushing many others to wonder whether there’s a better way to actually measure AI achievement. Developers of these coding agents aren’t necessarily doing anything as straightforward cheating, but they’re crafting approaches that are too neatly tailored to the specifics of the benchmark. The initial SWE-Bench test set was limited to programs written in Python, which meant developers could gain an advantage by training their models exclusively on Python code. Soon, Yang noticed that high-scoring models would fail completely when tested on different programming languages—revealing an approach to the test that he describes as “gilded.” “It looks nice and shiny at first glance, but then you try to run it on a different language and the whole thing just kind of falls apart,” Yang says. “At that point, you’re not designing a software engineering agent. You’re designing to make a SWE-Bench agent, which is much less interesting.” The SWE-Bench issue is a symptom of a more sweeping—and complicated—problem in AI evaluation, and one that’s increasingly sparking heated debate: The benchmarks the industry uses to guide development are drifting further and further away from evaluating actual capabilities, calling their basic value into question. Making the situation worse, several benchmarks, most notably FrontierMath and Chatbot Arena, have recently come under heat for an alleged lack of transparency. Nevertheless, benchmarks still play a central role in model development, even if few experts are willing to take their results at face value. OpenAI cofounder Andrej Karpathy recently described the situation as “an evaluation crisis”: the industry has fewer trusted methods for measuring capabilities and no clear path to better ones.  “Historically, benchmarks were the way we evaluated AI systems,” says Vanessa Parli, director of research at Stanford University’s Institute for Human-Centered AI. “Is that the way we want to evaluate systems going forward? And if it’s not, what is the way?” A growing group of academics and AI researchers are making the case that the answer is to go smaller, trading sweeping ambition for an approach inspired by the social sciences. Specifically, they want to focus more on testing validity, which for quantitative social scientists refers to how well a given questionnaire measures what it’s claiming to measure—and, more fundamentally, whether what it is measuring has a coherent definition. That could cause trouble for benchmarks assessing hazily defined concepts like “reasoning” or “scientific knowledge”—and for developers aiming to reach the much-hyped goal of artificial general intelligence—but it would put the industry on firmer ground as it looks to prove the worth of individual models. “Taking validity seriously means asking folks in academia, industry, or wherever to show that their system does what they say it does,” says Abigail Jacobs, a University of Michigan professor who is a central figure in the new push for validity. “I think it points to a weakness in the AI world if they want to back off from showing that they can support their claim.” The limits of traditional testing If AI companies have been slow to respond to the growing failure of benchmarks, it’s partially because the test-scoring approach has been so effective for so long.  One of the biggest early successes of contemporary AI was the ImageNet challenge, a kind of antecedent to contemporary benchmarks. Released in 2010 as an open challenge to researchers, the database held more than 3 million images for AI systems to categorize into 1,000 different classes. Crucially, the test was completely agnostic to methods, and any successful algorithm quickly gained credibility regardless of how it worked. When an algorithm called AlexNet broke through in 2012, with a then unconventional form of GPU training, it became one of the foundational results of modern AI. Few would have guessed in advance that AlexNet’s convolutional neural nets would be the secret to unlocking image recognition—but after it scored well, no one dared dispute it. (One of AlexNet’s developers, Ilya Sutskever, would go on to cofound OpenAI.) A large part of what made this challenge so effective was that there was little practical difference between ImageNet’s object classification challenge and the actual process of asking a computer to recognize an image. Even if there were disputes about methods, no one doubted that the highest-scoring model would have an advantage when deployed in an actual image recognition system. But in the 12 years since, AI researchers have applied that same method-agnostic approach to increasingly general tasks. SWE-Bench is commonly used as a proxy for broader coding ability, while other exam-style benchmarks often stand in for reasoning ability. That broad scope makes it difficult to be rigorous about what a specific benchmark measures—which, in turn, makes it hard to use the findings responsibly.  Where things break down Anka Reuel, a PhD student who has been focusing on the benchmark problem as part of her research at Stanford, has become convinced the evaluation problem is the result of this push toward generality. “We’ve moved from task-specific models to general-purpose models,” Reuel says. “It’s not about a single task anymore but a whole bunch of tasks, so evaluation becomes harder.” Like the University of Michigan’s Jacobs, Reuel thinks “the main issue with benchmarks is validity, even more than the practical implementation,” noting: “That’s where a lot of things break down.” For a task as complicated as coding, for instance, it’s nearly impossible to incorporate every possible scenario into your problem set. As a result, it’s hard to gauge whether a model is scoring better because it’s more skilled at coding or because it has more effectively manipulated the problem set. And with so much pressure on developers to achieve record scores, shortcuts are hard to resist. For developers, the hope is that success on lots of specific benchmarks will add up to a generally capable model. But the techniques of agentic AI mean a single AI system can encompass a complex array of different models, making it hard to evaluate whether improvement on a specific task will lead to generalization. “There’s just many more knobs you can turn,” says Sayash Kapoor, a computer scientist at Princeton and a prominent critic of sloppy practices in the AI industry. “When it comes to agents, they have sort of given up on the best practices for evaluation.” In a paper from last July, Kapoor called out specific issues in how AI models were approaching the WebArena benchmark, designed by Carnegie Mellon University researchers in 2024 as a test of an AI agent’s ability to traverse the web. The benchmark consists of more than 800 tasks to be performed on a set of cloned websites mimicking Reddit, Wikipedia, and others. Kapoor and his team identified an apparent hack in the winning model, called STeP. STeP included specific instructions about how Reddit structures URLs, allowing STeP models to jump directly to a given user’s profile page (a frequent element of WebArena tasks). This shortcut wasn’t exactly cheating, but Kapoor sees it as “a serious misrepresentation of how well the agent would work had it seen the tasks in WebArena for the first time.” Because the technique was successful, though, a similar policy has since been adopted by OpenAI’s web agent Operator. (“Our evaluation setting is designed to assess how well an agent can solve tasks given some instruction about website structures and task execution,” an OpenAI representative said when reached for comment. “This approach is consistent with how others have used and reported results with WebArena.” STeP did not respond to a request for comment.) Further highlighting the problem with AI benchmarks, late last month Kapoor and a team of researchers wrote a paper that revealed significant problems in Chatbot Arena, the popular crowdsourced evaluation system. According to the paper, the leaderboard was being manipulated; many top foundation models were conducting undisclosed private testing and releasing their scores selectively. Today, even ImageNet itself, the mother of all benchmarks, has started to fall victim to validity problems. A 2023 study from researchers at the University of Washington and Google Research found that when ImageNet-winning algorithms were pitted against six real-world data sets, the architecture improvement “resulted in little to no progress,” suggesting that the external validity of the test had reached its limit. Going smaller For those who believe the main problem is validity, the best fix is reconnecting benchmarks to specific tasks. As Reuel puts it, AI developers “have to resort to these high-level benchmarks that are almost meaningless for downstream consumers, because the benchmark developers can’t anticipate the downstream task anymore.” So what if there was a way to help the downstream consumers identify this gap? In November 2024, Reuel launched a public ranking project called BetterBench, which rates benchmarks on dozens of different criteria, such as whether the code has been publicly documented. But validity is a central theme, with particular criteria challenging designers to spell out what capability their benchmark is testing and how it relates to the tasks that make up the benchmark. “You need to have a structural breakdown of the capabilities,” Reuel says. “What are the actual skills you care about, and how do you operationalize them into something we can measure?” The results are surprising. One of the highest-scoring benchmarks is also the oldest: the Arcade Learning Environment (ALE), established in 2013 as a way to test models’ ability to learn how to play a library of Atari 2600 games. One of the lowest-scoring is the Massive Multitask Language Understanding (MMLU) benchmark, a widely used test for general language skills; by the standards of BetterBench, the connection between the questions and the underlying skill was too poorly defined. BetterBench hasn’t meant much for the reputations of specific benchmarks, at least not yet; MMLU is still widely used, and ALE is still marginal. But the project has succeeded in pushing validity into the broader conversation about how to fix benchmarks. In April, Reuel quietly joined a new research group hosted by Hugging Face, the University of Edinburgh, and EleutherAI, where she’ll develop her ideas on validity and AI model evaluation with other figures in the field. (An official announcement is expected later this month.)  Irene Solaiman, Hugging Face’s head of global policy, says the group will focus on building valid benchmarks that go beyond measuring straightforward capabilities. “There’s just so much hunger for a good benchmark off the shelf that already works,” Solaiman says. “A lot of evaluations are trying to do too much.” Increasingly, the rest of the industry seems to agree. In a paper in March, researchers from Google, Microsoft, Anthropic, and others laid out a new framework for improving evaluations—with validity as the first step.  “AI evaluation science must,” the researchers argue, “move beyond coarse grained claims of ‘general intelligence’ towards more task-specific and real-world relevant measures of progress.”  Measuring the “squishy” things To help make this shift, some researchers are looking to the tools of social science. A February position paper argued that “evaluating GenAI systems is a social science measurement challenge,” specifically unpacking how the validity systems used in social measurements can be applied to AI benchmarking.  The authors, largely employed by Microsoft’s research branch but joined by academics from Stanford and the University of Michigan, point to the standards that social scientists use to measure contested concepts like ideology, democracy, and media bias. Applied to AI benchmarks, those same procedures could offer a way to measure concepts like “reasoning” and “math proficiency” without slipping into hazy generalizations. In the social science literature, it’s particularly important that metrics begin with a rigorous definition of the concept measured by the test. For instance, if the test is to measure how democratic a society is, it first needs to establish a definition for a “democratic society” and then establish questions that are relevant to that definition.  To apply this to a benchmark like SWE-Bench, designers would need to set aside the classic machine learning approach, which is to collect programming problems from GitHub and create a scheme to validate answers as true or false. Instead, they’d first need to define what the benchmark aims to measure (“ability to resolve flagged issues in software,” for instance), break that into subskills (different types of problems or types of program that the AI model can successfully process), and then finally assemble questions that accurately cover the different subskills. It’s a profound change from how AI researchers typically approach benchmarking—but for researchers like Jacobs, a coauthor on the February paper, that’s the whole point. “There’s a mismatch between what’s happening in the tech industry and these tools from social science,” she says. “We have decades and decades of thinking about how we want to measure these squishy things about humans.” Even though the idea has made a real impact in the research world, it’s been slow to influence the way AI companies are actually using benchmarks.  The last two months have seen new model releases from OpenAI, Anthropic, Google, and Meta, and all of them lean heavily on multiple-choice knowledge benchmarks like MMLU—the exact approach that validity researchers are trying to move past. After all, model releases are, for the most part, still about showing increases in general intelligence, and broad benchmarks continue to be used to back up those claims.  For some observers, that’s good enough. Benchmarks, Wharton professor Ethan Mollick says, are “bad measures of things, but also they’re what we’ve got.” He adds: “At the same time, the models are getting better. A lot of sins are forgiven by fast progress.” For now, the industry’s long-standing focus on artificial general intelligence seems to be crowding out a more focused validity-based approach. As long as AI models can keep growing in general intelligence, then specific applications don’t seem as compelling—even if that leaves practitioners relying on tools they no longer fully trust.  “This is the tightrope we’re walking,” says Hugging Face’s Solaiman. “It’s too easy to throw the system out, but evaluations are really helpful in understanding our models, even with these limitations.” Russell Brandom is a freelance writer covering artificial intelligence. He lives in Brooklyn with his wife and two cats. This story was supported by a grant from the Tarbell Center for AI Journalism.
It’s not easy being one of Silicon Valley’s favorite benchmarks. 

SWE-Bench (pronounced “swee bench”) launched in November 2024 to evaluate an AI model’s coding skill, using more than 2,000 real-world programming problems pulled from the public GitHub repositories of 12 different Python-based projects. 

In the months since then, it’s quickly become one of the most popular tests in AI. A SWE-Bench score has become a mainstay of major model releases from OpenAI, Anthropic, and Google—and outside of foundation models, the fine-tuners at AI firms are in constant competition to see who can rise above the pack. The top of the leaderboard is a pileup between three different fine tunings of Anthropic’s Claude Sonnet model and Amazon’s Q developer agent. Auto Code Rover—one of the Claude modifications—nabbed the number two spot in November, and was acquired just three months later.

Despite all the fervor, this isn’t exactly a truthful assessment of which model is “better.” As the benchmark has gained prominence, “you start to see that people really want that top spot,” says John Yang, a researcher on the team that developed SWE-Bench at Princeton University. As a result, entrants have begun to game the system—which is pushing many others to wonder whether there’s a better way to actually measure AI achievement.

Developers of these coding agents aren’t necessarily doing anything as straightforward cheating, but they’re crafting approaches that are too neatly tailored to the specifics of the benchmark. The initial SWE-Bench test set was limited to programs written in Python, which meant developers could gain an advantage by training their models exclusively on Python code. Soon, Yang noticed that high-scoring models would fail completely when tested on different programming languages—revealing an approach to the test that he describes as “gilded.”

“It looks nice and shiny at first glance, but then you try to run it on a different language and the whole thing just kind of falls apart,” Yang says. “At that point, you’re not designing a software engineering agent. You’re designing to make a SWE-Bench agent, which is much less interesting.”

The SWE-Bench issue is a symptom of a more sweeping—and complicated—problem in AI evaluation, and one that’s increasingly sparking heated debate: The benchmarks the industry uses to guide development are drifting further and further away from evaluating actual capabilities, calling their basic value into question. Making the situation worse, several benchmarks, most notably FrontierMath and Chatbot Arena, have recently come under heat for an alleged lack of transparency. Nevertheless, benchmarks still play a central role in model development, even if few experts are willing to take their results at face value. OpenAI cofounder Andrej Karpathy recently described the situation as “an evaluation crisis”: the industry has fewer trusted methods for measuring capabilities and no clear path to better ones. 

“Historically, benchmarks were the way we evaluated AI systems,” says Vanessa Parli, director of research at Stanford University’s Institute for Human-Centered AI. “Is that the way we want to evaluate systems going forward? And if it’s not, what is the way?”

A growing group of academics and AI researchers are making the case that the answer is to go smaller, trading sweeping ambition for an approach inspired by the social sciences. Specifically, they want to focus more on testing validity, which for quantitative social scientists refers to how well a given questionnaire measures what it’s claiming to measure—and, more fundamentally, whether what it is measuring has a coherent definition. That could cause trouble for benchmarks assessing hazily defined concepts like “reasoning” or “scientific knowledge”—and for developers aiming to reach the much–hyped goal of artificial general intelligence—but it would put the industry on firmer ground as it looks to prove the worth of individual models.

“Taking validity seriously means asking folks in academia, industry, or wherever to show that their system does what they say it does,” says Abigail Jacobs, a University of Michigan professor who is a central figure in the new push for validity. “I think it points to a weakness in the AI world if they want to back off from showing that they can support their claim.”

The limits of traditional testing

If AI companies have been slow to respond to the growing failure of benchmarks, it’s partially because the test-scoring approach has been so effective for so long. 

One of the biggest early successes of contemporary AI was the ImageNet challenge, a kind of antecedent to contemporary benchmarks. Released in 2010 as an open challenge to researchers, the database held more than 3 million images for AI systems to categorize into 1,000 different classes.

Crucially, the test was completely agnostic to methods, and any successful algorithm quickly gained credibility regardless of how it worked. When an algorithm called AlexNet broke through in 2012, with a then unconventional form of GPU training, it became one of the foundational results of modern AI. Few would have guessed in advance that AlexNet’s convolutional neural nets would be the secret to unlocking image recognition—but after it scored well, no one dared dispute it. (One of AlexNet’s developers, Ilya Sutskever, would go on to cofound OpenAI.)

A large part of what made this challenge so effective was that there was little practical difference between ImageNet’s object classification challenge and the actual process of asking a computer to recognize an image. Even if there were disputes about methods, no one doubted that the highest-scoring model would have an advantage when deployed in an actual image recognition system.

But in the 12 years since, AI researchers have applied that same method-agnostic approach to increasingly general tasks. SWE-Bench is commonly used as a proxy for broader coding ability, while other exam-style benchmarks often stand in for reasoning ability. That broad scope makes it difficult to be rigorous about what a specific benchmark measures—which, in turn, makes it hard to use the findings responsibly. 

Where things break down

Anka Reuel, a PhD student who has been focusing on the benchmark problem as part of her research at Stanford, has become convinced the evaluation problem is the result of this push toward generality. “We’ve moved from task-specific models to general-purpose models,” Reuel says. “It’s not about a single task anymore but a whole bunch of tasks, so evaluation becomes harder.”

Like the University of Michigan’s Jacobs, Reuel thinks “the main issue with benchmarks is validity, even more than the practical implementation,” noting: “That’s where a lot of things break down.” For a task as complicated as coding, for instance, it’s nearly impossible to incorporate every possible scenario into your problem set. As a result, it’s hard to gauge whether a model is scoring better because it’s more skilled at coding or because it has more effectively manipulated the problem set. And with so much pressure on developers to achieve record scores, shortcuts are hard to resist.

For developers, the hope is that success on lots of specific benchmarks will add up to a generally capable model. But the techniques of agentic AI mean a single AI system can encompass a complex array of different models, making it hard to evaluate whether improvement on a specific task will lead to generalization. “There’s just many more knobs you can turn,” says Sayash Kapoor, a computer scientist at Princeton and a prominent critic of sloppy practices in the AI industry. “When it comes to agents, they have sort of given up on the best practices for evaluation.”

In a paper from last July, Kapoor called out specific issues in how AI models were approaching the WebArena benchmark, designed by Carnegie Mellon University researchers in 2024 as a test of an AI agent’s ability to traverse the web. The benchmark consists of more than 800 tasks to be performed on a set of cloned websites mimicking Reddit, Wikipedia, and others. Kapoor and his team identified an apparent hack in the winning model, called STeP. STeP included specific instructions about how Reddit structures URLs, allowing STeP models to jump directly to a given user’s profile page (a frequent element of WebArena tasks).

This shortcut wasn’t exactly cheating, but Kapoor sees it as “a serious misrepresentation of how well the agent would work had it seen the tasks in WebArena for the first time.” Because the technique was successful, though, a similar policy has since been adopted by OpenAI’s web agent Operator. (“Our evaluation setting is designed to assess how well an agent can solve tasks given some instruction about website structures and task execution,” an OpenAI representative said when reached for comment. “This approach is consistent with how others have used and reported results with WebArena.” STeP did not respond to a request for comment.)

Further highlighting the problem with AI benchmarks, late last month Kapoor and a team of researchers wrote a paper that revealed significant problems in Chatbot Arena, the popular crowdsourced evaluation system. According to the paper, the leaderboard was being manipulated; many top foundation models were conducting undisclosed private testing and releasing their scores selectively.

Today, even ImageNet itself, the mother of all benchmarks, has started to fall victim to validity problems. A 2023 study from researchers at the University of Washington and Google Research found that when ImageNet-winning algorithms were pitted against six real-world data sets, the architecture improvement “resulted in little to no progress,” suggesting that the external validity of the test had reached its limit.

Going smaller

For those who believe the main problem is validity, the best fix is reconnecting benchmarks to specific tasks. As Reuel puts it, AI developers “have to resort to these high-level benchmarks that are almost meaningless for downstream consumers, because the benchmark developers can’t anticipate the downstream task anymore.” So what if there was a way to help the downstream consumers identify this gap?

In November 2024, Reuel launched a public ranking project called BetterBench, which rates benchmarks on dozens of different criteria, such as whether the code has been publicly documented. But validity is a central theme, with particular criteria challenging designers to spell out what capability their benchmark is testing and how it relates to the tasks that make up the benchmark.

“You need to have a structural breakdown of the capabilities,” Reuel says. “What are the actual skills you care about, and how do you operationalize them into something we can measure?”

The results are surprising. One of the highest-scoring benchmarks is also the oldest: the Arcade Learning Environment (ALE), established in 2013 as a way to test models’ ability to learn how to play a library of Atari 2600 games. One of the lowest-scoring is the Massive Multitask Language Understanding (MMLU) benchmark, a widely used test for general language skills; by the standards of BetterBench, the connection between the questions and the underlying skill was too poorly defined.

BetterBench hasn’t meant much for the reputations of specific benchmarks, at least not yet; MMLU is still widely used, and ALE is still marginal. But the project has succeeded in pushing validity into the broader conversation about how to fix benchmarks. In April, Reuel quietly joined a new research group hosted by Hugging Face, the University of Edinburgh, and EleutherAI, where she’ll develop her ideas on validity and AI model evaluation with other figures in the field. (An official announcement is expected later this month.) 

Irene Solaiman, Hugging Face’s head of global policy, says the group will focus on building valid benchmarks that go beyond measuring straightforward capabilities. “There’s just so much hunger for a good benchmark off the shelf that already works,” Solaiman says. “A lot of evaluations are trying to do too much.”

Increasingly, the rest of the industry seems to agree. In a paper in March, researchers from Google, Microsoft, Anthropic, and others laid out a new framework for improving evaluations—with validity as the first step. 

“AI evaluation science must,” the researchers argue, “move beyond coarse grained claims of ‘general intelligence’ towards more task-specific and real-world relevant measures of progress.” 

Measuring the “squishy” things

To help make this shift, some researchers are looking to the tools of social science. A February position paper argued that “evaluating GenAI systems is a social science measurement challenge,” specifically unpacking how the validity systems used in social measurements can be applied to AI benchmarking. 

The authors, largely employed by Microsoft’s research branch but joined by academics from Stanford and the University of Michigan, point to the standards that social scientists use to measure contested concepts like ideology, democracy, and media bias. Applied to AI benchmarks, those same procedures could offer a way to measure concepts like “reasoning” and “math proficiency” without slipping into hazy generalizations.

In the social science literature, it’s particularly important that metrics begin with a rigorous definition of the concept measured by the test. For instance, if the test is to measure how democratic a society is, it first needs to establish a definition for a “democratic society” and then establish questions that are relevant to that definition. 

To apply this to a benchmark like SWE-Bench, designers would need to set aside the classic machine learning approach, which is to collect programming problems from GitHub and create a scheme to validate answers as true or false. Instead, they’d first need to define what the benchmark aims to measure (“ability to resolve flagged issues in software,” for instance), break that into subskills (different types of problems or types of program that the AI model can successfully process), and then finally assemble questions that accurately cover the different subskills.

It’s a profound change from how AI researchers typically approach benchmarking—but for researchers like Jacobs, a coauthor on the February paper, that’s the whole point. “There’s a mismatch between what’s happening in the tech industry and these tools from social science,” she says. “We have decades and decades of thinking about how we want to measure these squishy things about humans.”

Even though the idea has made a real impact in the research world, it’s been slow to influence the way AI companies are actually using benchmarks. 

The last two months have seen new model releases from OpenAI, Anthropic, Google, and Meta, and all of them lean heavily on multiple-choice knowledge benchmarks like MMLU—the exact approach that validity researchers are trying to move past. After all, model releases are, for the most part, still about showing increases in general intelligence, and broad benchmarks continue to be used to back up those claims. 

For some observers, that’s good enough. Benchmarks, Wharton professor Ethan Mollick says, are “bad measures of things, but also they’re what we’ve got.” He adds: “At the same time, the models are getting better. A lot of sins are forgiven by fast progress.”

For now, the industry’s long-standing focus on artificial general intelligence seems to be crowding out a more focused validity-based approach. As long as AI models can keep growing in general intelligence, then specific applications don’t seem as compelling—even if that leaves practitioners relying on tools they no longer fully trust. 

“This is the tightrope we’re walking,” says Hugging Face’s Solaiman. “It’s too easy to throw the system out, but evaluations are really helpful in understanding our models, even with these limitations.”

Russell Brandom is a freelance writer covering artificial intelligence. He lives in Brooklyn with his wife and two cats.

This story was supported by a grant from the Tarbell Center for AI Journalism.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

CoreWeave brings Nvidia Vera Rubin, AI tools to its cloud services

Forge brings together experiment tracking, evaluation, agent observability, post-training, inference and model management. The platform is designed to let teams use their preferred models, frameworks and cloud environments rather than locking them into a single AI stack, CoreWeave stated. The company described Forge as a continuous AI development loop in

Read More »

Canada lists Pacific Link as Project of National Interest

The Government of Canada on Oct. 1 listed the Pacific Link project as a Project of National Interest under the Building Canada Act, advancing work to secure permissions needed to begin pipeline design and construction as early as Sept. 1, 2027. Pacific Link, formerly known as the West Coast oil pipeline, is a proposed 1 million-b/d crude oil pipeline that would transport Alberta oil to Canada’s west coast for export to Asia-Pacific and other global markets. With the Project of National Interest designation, Pembina Pipeline Corp., Calgary, along with the Governments of Alberta and Canada, and Trans Mountain Corp., will advance the project under a streamlined regulatory review process. Pembina said the listing “provides greater certainty through a clearer, more efficient and predictable federal review process that will maintain environmental standards and Indigenous consultation, which will be led by the Major Projects Office and supported by the Canada Energy Regulator.” Trans Mountain Corp. is responsible for the regulatory process, stakeholder and Indigenous engagement, construction of the project, and subsequent operation of the asset. Pembina’s economic interest through construction will be 10%, with the opportunity to acquire up to an additional 10% once the project enters commercial operation.

Read More »

Chevron ups interest in Namibia license with drill-ready prospect

Harmattan Energy Ltd., an affiliate of Chevron Corp., has agreed to a deal with Custos Energy (Pty) Ltd. subsidiary Trago Energy (Pty) Ltd. for interest in Petroleum Exploration License 90 (PEL 90) offshore Namibia.   Under the agreement, Trago will transfer all of its participating interest (10%) in PEL 90 in Namibia’s Orange Basin to license-operator Chevron, in exchange for $11 million in cash at completion. Further contingent consideration is payable on achievement of appraisal and production milestones, including revenues associated with commercial production currently estimated at 1.5-2.5 million bbl of oil (dependent upon commodity price assumptions), Custos said. With the deal, Chevron adds interests that help offset a famout deal entered into with Equinor.  In August, the operator agreed to divest to Equinor a 17.4% portion of its interest in the license, which contains a drill-ready prospect—Nabba-1X—slated for drilling before yearend. The well is part of a broader multi-well exploration program planned by Chevron across Sub-Saharan Africa. Nabba-1X will be Chevron’s second well offshore Namibia following Kapana-1X, where the company gathered geological data but did not encounter commercial hydrocarbons. Completion of Trago Energy’s farm-out to Chevron is conditional upon various governmental, regulatory, and third-party approvals.

Read More »

Trump cites $54 billion South Korean plan for Alaska LNG

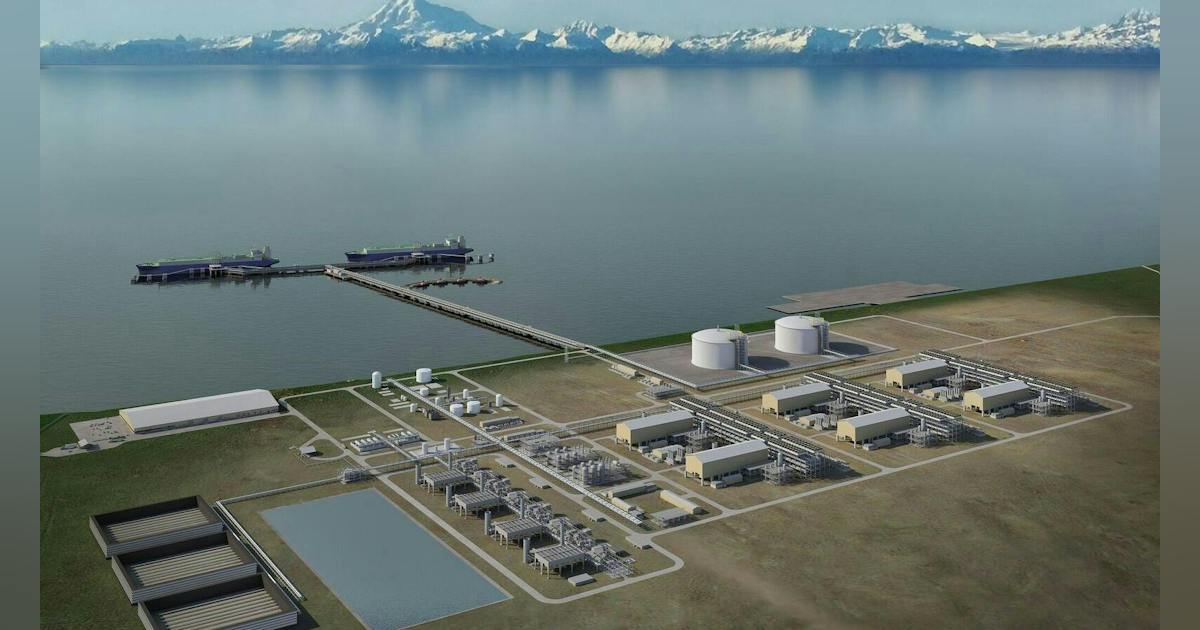
US President Donald Trump on Sept. 30 said South Korea plans to invest $54 billion in the long-delayed Alaska LNG project as part of a broader package of up to $200 billion in South Korean investment in US energy projects. The announcement does not represent a final investment commitment. South Korean officials said the two countries agreed only to review the project’s commercial viability. South Korea separately finalized a $22.3-billion investment in a 6.47-Gw gas-fired power plant in Encinal, Tex., that would supply electricity to an adjacent AI data center campus. Proposed participation in Alaska LNG and a separate framework involving eight US nuclear reactors remain subject to feasibility reviews. The Alaska LNG project would transport North Slope gas through an 807-mile pipeline to a liquefaction and LNG export terminal at Nikiski on the Kenai Peninsula. Designed capacity is up to 20 million tpy of LNG, primarily for Asian markets. Glenfarne Group is lead developer and majority owner, holding a 75% stake acquired in 2025 from Alaska Gasline Development Corp. (AGDC), which retained 25%. The project originated in 2014 as a joint effort between AGDC, ExxonMobil, ConocoPhillips, bp, and TransCanada. After the producers withdrew, AGDC became sole owner in 2017 until Glenfarne assumed control. FERC approved the project in 2020, and federal permitting was completed in 2025. A final investment decision (FID), however, has been delayed by high capital costs and the need to secure sufficient LNG offtake commitments. Glenfarne has preliminary agreements covering about 13 million tpy and has said roughly 16 million tpy is needed to support financing. The company plans to develop Alaska LNG in two financially independent phases. The first would build a pipeline supplying North Slope gas to Alaska consumers, while the second would add LNG export infrastructure. Glenfarne is targeting a pipeline investment decision

Read More »

Matador outlines drilling plans with Paloma acquisition now closed

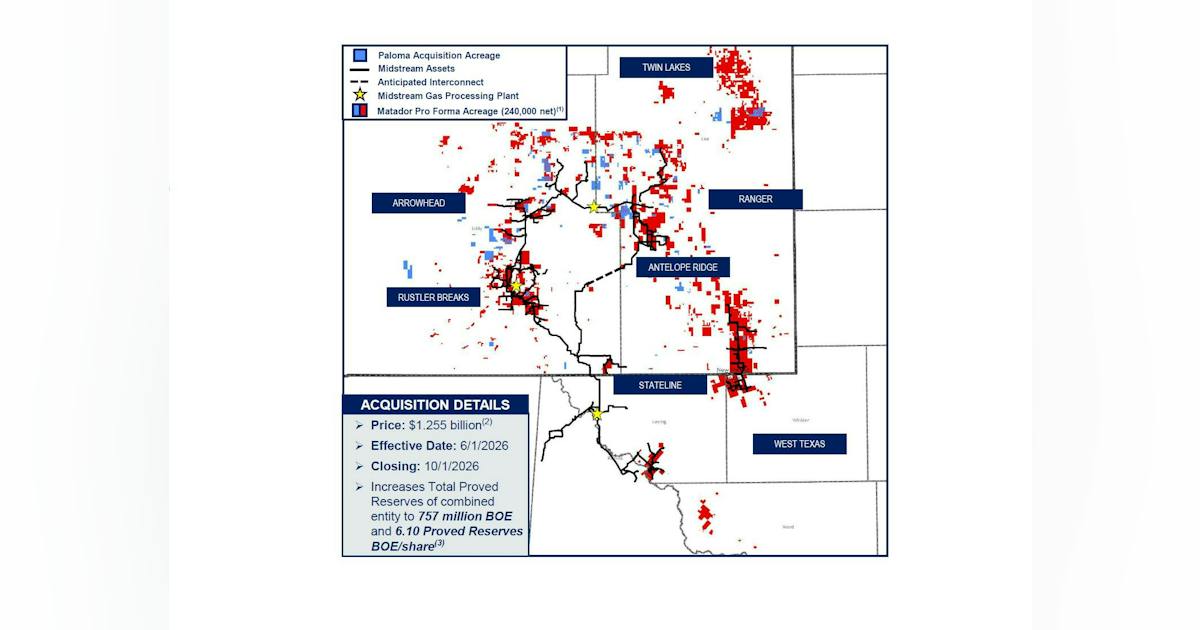
The acquired position includes about 16,500 net acres in Eddy and Lea counties, NM, most of which is held by production, along with more than 156 future drilling locations (normalized to 2-mile laterals) across nine or more prospective benches. Matador said 59 drilling permits have already been approved on the Delaware basin acreage. The company said assets associated with the acquisition are producing an estimated 12,200 boe/d in the third quarter, about 55% of which is oil. Matador added that production from the acquired properties has exceeded underwriting estimates by roughly 10% since June 1, largely due to strong performance from recently drilled wells in Eddy County. According to company materials, the acquisition adds an estimated 55 MMboe of proved reserves, 67% of which is oil, with a PV-10 value of about $816 million.  Matador said the Paloma acquisition, together with its pending acquisition of Ridge Runner Resources II LLC acreage and acreage added in the May 2026 federal lease sale, is expected to increase its Delaware basin position to about 240,000 net acres in fourth-quarter 2026, nearly 20% above its October 2025 acreage position. Chairman and chief executive officer Joseph Wm. Foran said the acquired acreage holds some of the highest hydrocarbon resources per acre in the Lower 48 and is expected to provide opportunities for upstream and midstream value creation as it is integrated into its wholly-owned midstream system and its 51%-owned San Mateo Midstream system.

Read More »

Energy Department Announces Up to $400 Million for Basic Research to Advance the Frontiers of Science

WASHINGTON—The U.S. Department of Energy (DOE) today announced its annual funding opportunity of up to $400 million to advance the frontiers of scientific knowledge and lay the foundation for future technologies and innovation. The funding delivers on President Trump’s Executive Order Restoring Gold Standard Science by supporting rigorous, transparent, and mission-driven research across DOE’s Office of Science to strengthen America’s scientific and technological leadership. “Foundational research is where the breakthroughs that shape America’s future begin,” said DOE Under Secretary for Science Darío Gil. “Through this investment, we are empowering our nation’s researchers to pursue bold ideas, push the boundaries of discovery, and build the scientific foundations for tomorrow’s technologies—strengthening America’s global leadership in science and innovation.” The funding will support research across DOE’s Office of Science and its major programs to tackle some of the nation’s greatest scientific challenges and accelerate discoveries in areas critical to America’s future. Research will span Advanced Scientific Computing Research, Basic Energy Sciences, Biological and Environmental Research, Fusion Energy Sciences, High Energy Physics, Nuclear Physics, and Isotope R&D and Production. The Notice of Funding Opportunity (NOFO), informally known as the “Open Call,” is issued annually at the beginning of each Fiscal Year (FY). It provides a vehicle for DOE’s Office of Science to solicit applications from institutions for research support in areas not covered by more specific, topical NOFOs issued by the office in FY 2027. More details about this Notice of Funding Opportunity can be found here. DOE’s Office of Science is the nation’s largest supporter of basic research in the physical sciences, funds research at hundreds of universities nationwide, and stewards 10 of DOE’s National Laboratories.

Read More »

Magnolia sells non-core South Texas assets, adds Karnes-area acreage during WildFire integration

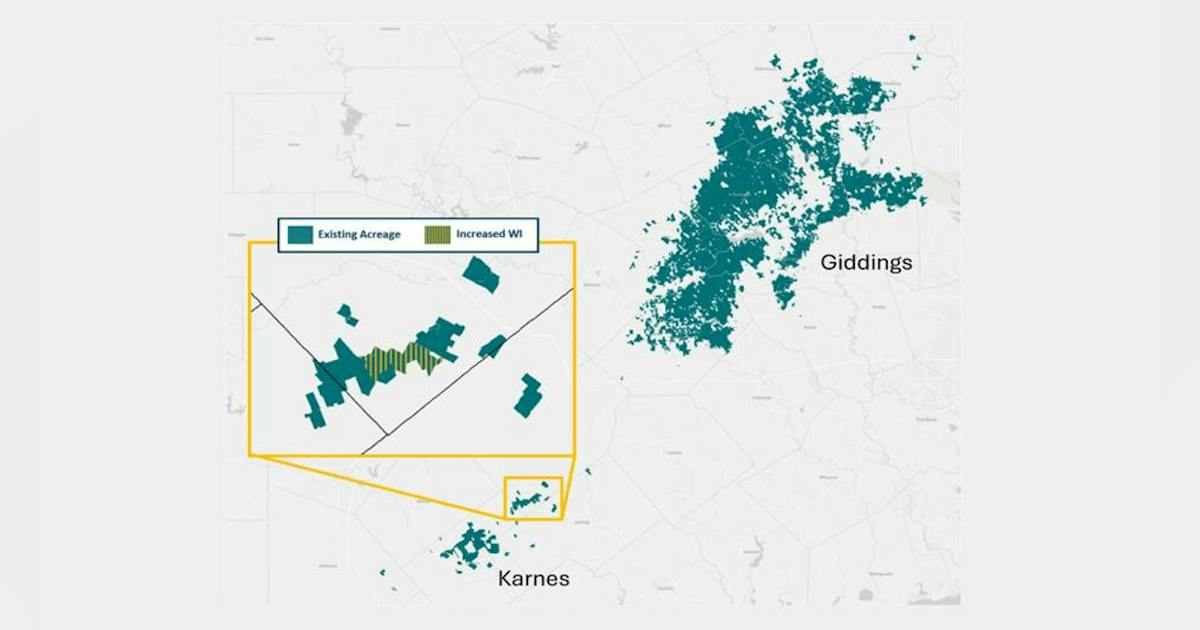
The company disclosed the transaction as part of an operational update following the recent closing of its acquisition of WildFire Energy. Chris Stavros, Magnolia chairman, president, and chief executive officer, said integration of the WildFire assets is progressing as planned as the company works to build a larger Eagle Ford and Austin Chalk position across South Texas. Production, capital outlook Third-quarter 2026 production is expected to average 116,000-118,000 boe/d (about 42% oil), reflecting the WildFire acquisition and the impact of the divested properties, Magnolia said. Drilling and completion (D&C) capital spending for the quarter is expected to total $155-165 million. For fourth-quarter 2026, the first full quarter reflecting the WildFire acquisition, production is forecast at 159,000-161,000 boe/d with oil accounting for 49-50% of volumes. D&C spending is expected to be about $235 million. For 2027, Magnolia expects both oil production and total production to grow 4-5% from a second-quarter 2026 pro forma base of about 78,000 bo/d and 158,000 boe/d, respectively, after accounting for volumes associated with the asset sale. The company currently estimates 2027 D&C capital spending of $900-950 million, including the impact of modest oilfield service cost inflation.

Read More »

Startup doxx.net hands the network controls to AI

“The whole thing is run completely by AI, so behind the scenes, I mean, it’s a network with 31 locations around the world, and internally there’s a mesh network, and I can’t, as a human being, manage all of this by myself,” Lyon said. Lyon said the team modeled every site, down to the wire and the optic, in a virtual model before building. An infrastructure management system running the company’s own AI on its own hardware then ordered the installation. It orchestrated shipping and delivery through data center APIs. Human technicians performed the remote smart hands installations. The company also built tools for agents to work with users and with the network. An agent gateway gives an AI agent an identity in the doxx.net chat app. The user pastes a credential into the agent. The agent obtains its certificate and appears in the user’s chat. Users can create group chats with several agents. In one example, Lyon said one agent runs BGP while others handle other tasks.

Read More »

DCF Poll: What Must Data Centers Prove to Keep Building at AI Scale?

For years, the data center industry’s biggest constraints were largely physical, centered on power, transmission, land, water, equipment and labor. As the AI infrastructure buildout accelerates, however, another constraint is moving rapidly to the foreground. The constraint, and the concern, is whether host communities, regulators and policymakers believe the next generation of data centers is being built on terms that work for them, too. That question received a fresh exclamation point on Oct. 2, when Amazon Web Services announced it will invest more than $1 billion over five years in U.S. communities where it operates data centers, with funding aimed at areas including energy affordability, water and natural-resource protection, workforce development and education. The initiative arrives as electricity and water consumption associated with hyperscale infrastructure faces increasing scrutiny in communities across the country. And AWS is responding to a policy environment that is changing quickly. In Virginia, Loudoun County supervisors have begun a process that could pause action on certain new data center and substation applications for as long as 12 months while the county reviews its development policies. The board is scheduled to consider the proposed pause Oct. 20. Just next door, Prince William County voted Sept. 22 to dramatically shrink the area where data centers can be developed by right, largely shifting future projects outside the revised overlay into a case-by-case special-use permitting process. The issue is spreading well beyond Northern Virginia. On Sept. 23, Maryland Gov. Wes Moore signed an executive order creating a statewide framework for data center development centered on ratepayer protection, environmental impacts, community participation, transparency and accountability. Meanwhile, the U.S. House on Sept. 16 passed the Ratepayer Protection Act by a 417–3 vote, seeking to prevent data centers and other large loads from shifting the incremental costs of new generation and grid infrastructure onto

Read More »

$6T in annual AI revenue needed to pay off data center investments

Making the assumption that hyperscalers’ capital expenditure amounts to about 25% of revenue, they would need the AI market to be worth $6 trillion annually. But, said Bain, the current consumer and enterprise AI markets together could be worth up to $1.8 trillion by 2031, leaving a whopping $4.2 trillion still to find from new markets. Bain highlighted four potential areas: the use of AI in search; the development of more autonomous vehicles, including drones; physical AI, including digital twins and robotics; and new product development, for example, breakthroughs in pharmaceuticals.

Read More »

HPE’s Rahim: Pace of change in the data center is ‘extraordinary’

Network protection: As networking and security converge, Rahim said HPE continues to embed security throughout the network by combining SASE, network access control, firewalls, identity-based policy enforcement, and AI-powered operations. HPE’s security revenue is expected to grow at a high-single-digit percent CAGR through fiscal 2029. Partners: On Nov. 1, HPE will converge the Juniper and Aruba programs under one unified partner program, HPE Partner Ready Vantage. “Partners drive most of our networking business, and this milestone will enable all 60,000 HPE partners to sell the full networking portfolio through one unified partner program. Before the acquisition, only around 10% of HPE Aruba Networking and Juniper partners overlapped, and so this creates a significant cross-selling opportunity as we bring the combined HPE Networking portfolio to a much broader set of sellers and customers.” Service growth: “Today, services represent about one-third of our HPE Networking business. Services deepen customer relationships, add higher margin recurring revenue, and improve the quality of our products driving durable earnings,” Rahim said. HPE sees an opportunity to bring that business model and the culture to Aruba across a much larger installed base. “So, by fiscal 2028, we expect to increase services attach rates by five percentage points, supporting both recurring revenue growth and margin expansion,” Rahim said.

Read More »

Data Center Private Power: Who Regulates Behind-the-Meter Generation?

The Cases Writing the Rules The regulatory questions surrounding private power are no longer theoretical. Federal regulators, regional grid operators and state utility commissions are already confronting disputes over co-located generation, transmission obligations, large-load tariffs and the financial commitments required from data center customers. Amazon–Talen Puts Co-Location Before FERC The Amazon–Talen–Susquehanna dispute became the most prominent federal test of how far a co-located data center can separate its power supply from the regional grid while remaining connected to the grid’s reliability framework. Amazon Web Services operates a data center campus adjacent to Talen Energy’s Susquehanna nuclear plant in Pennsylvania. In 2024, the parties sought to expand the co-located load from 300 MW to 480 MW through an amended interconnection agreement with PJM. The proposed structure would have allowed the campus to receive more power directly from the nuclear plant while reducing the plant’s capacity interconnection rights on the PJM system. FERC rejected the amendment in November 2024, concluding that PJM had not justified the nonstandard provisions in the agreement. Importantly, the Commission did not prohibit co-location or dedicated generation. The dispute instead exposed a larger gap in existing transmission rules: how should a large load located beside a generator be measured, what transmission service does it require, what happens when the generator is unavailable, and how should the project pay for continued access to regional reliability? Those questions soon moved beyond the Amazon–Talen project itself. In December 2025, FERC found that PJM’s existing framework did not provide sufficiently clear and consistent rules for generators serving co-located loads or for transmission customers taking service on their behalf. The Commission directed PJM to develop defined interconnection and operating requirements along with transmission options ranging from conventional network service to firm and non-firm contract-demand structures. The central issue is deceptively simple: physical proximity

Read More »

Data Center Thermal Management Series-Part 1 of 3

The biggest driver in today’s global economy is the data center, and in the process, data centers are generating and taking more heat than ever before. Heat — the generation of it and public concerns about it — is the most pressing issue facing the data center industry. In response, data center managers and engineers are viewing the problem in new ways, devising innovative, next-generation thermal control strategies that manage the problem more effectively. In the minds of IT managers and the public, data centers and AI are joined at the hip, along with increasing power demands and associated issues of environmental impact, water usage, and higher utility costs. As community activists, political leaders, and now even some prominent AI industry CEOs call for limits on AI development and data center construction, it’s imperative that the data center industry better manage the heat they’re producing — and taking. Sponsored Resources: Texas Instruments’ portfolio of data center thermal management systems spans the full coolant path. It’s been under active development at TI for decades and has evolved in response to the rising power, computing demands, and complexity of advanced data centers. Traditional thermal management techniques can’t keep up with AI’s intense computing requirements. For decades, air cooling was sufficient. Fans blew cool air across hot components and carried heat away, keeping data centers and AI servers operating reliably. But with AI training and inference pushing rack power beyond 20kW to 40kW, air alone can no longer remove heat quickly enough. In addition, air cooling is noisy and consumes too much energy. AI server racks are coming online now that draw 100kW of power, and they’re on their way to more than a megawatt in a few years. Each generation of servers grows denser, more powerful, and hotter as they move and compute massive volumes

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »