Stay Ahead, Stay ONMINE

LLM + RAG: Creating an AI-Powered File Reader Assistant

Introduction AI is everywhere.  It is hard not to interact at least once a day with a Large Language Model (LLM). The chatbots are here to stay. They’re in your apps, they help you write better, they compose emails, they read emails…well, they do a lot. And I don’t think that that is bad. In fact, my opinion is the other way – at least so far. I defend and advocate for the use of AI in our daily lives because, let’s agree, it makes everything much easier. I don’t have to spend time double-reading a document to find punctuation problems or type. AI does that for me. I don’t waste time writing that follow-up email every single Monday. AI does that for me. I don’t need to read a huge and boring contract when I have an AI to summarize the main takeaways and action points to me! These are only some of AI’s great uses. If you’d like to know more use cases of LLMs to make our lives easier, I wrote a whole book about them. Now, thinking as a data scientist and looking at the technical side, not everything is that bright and shiny.  LLMs are great for several general use cases that apply to anyone or any company. For example, coding, summarizing, or answering questions about general content created until the training cutoff date. However, when it comes to specific business applications, for a single purpose, or something new that didn’t make the cutoff date, that is when the models won’t be that useful if used out-of-the-box – meaning, they will not know the answer. Thus, it will need adjustments. Training an LLM model can take months and millions of dollars. What is even worse is that if we don’t adjust and tune the model to our purpose, there will be unsatisfactory results or hallucinations (when the model’s response doesn’t make sense given our query). So what is the solution, then? Spending a lot of money retraining the model to include our data? Not really. That’s when the Retrieval-Augmented Generation (RAG) becomes useful. RAG is a framework that combines getting information from an external knowledge base with large language models (LLMs). It helps AI models produce more accurate and relevant responses. Let’s learn more about RAG next. What is RAG? Let me tell you a story to illustrate the concept. I love movies. For some time in the past, I knew which movies were competing for the best movie category at the Oscars or the best actors and actresses. And I would certainly know which ones got the statue for that year. But now I am all rusty on that subject. If you asked me who was competing, I would not know. And even if I tried to answer you, I would give you a weak response.  So, to provide you with a quality response, I will do what everybody else does: search for the information online, obtain it, and then give it to you. What I just did is the same idea as the RAG: I obtained data from an external database to give you an answer. When we enhance the LLM with a content store where it can go and retrieve data to augment (increase) its knowledge base, that is the RAG framework in action. RAG is like creating a content store where the model can enhance its knowledge and respond more accurately. User prompt about Content C. LLM retrieves external content to aggregate to the answer. Image by the author. Summarizing: Uses search algorithms to query external data sources, such as databases, knowledge bases, and web pages. Pre-processes the retrieved information. Incorporates the pre-processed information into the LLM. Why use RAG? Now that we know what the RAG framework is let’s understand why we should be using it. Here are some of the benefits: Enhances factual accuracy by referencing real data. RAG can help LLMs process and consolidate knowledge to create more relevant answers  RAG can help LLMs access additional knowledge bases, such as internal organizational data  RAG can help LLMs create more accurate domain-specific content  RAG can help reduce knowledge gaps and AI hallucination As previously explained, I like to say that with the RAG framework, we are giving an internal search engine for the content we want it to add to the knowledge base. Well. All of that is very interesting. But let’s see an application of RAG. We will learn how to create an AI-powered PDF Reader Assistant. Project This is an application that allows users to upload a PDF document and ask questions about its content using AI-powered natural language processing (NLP) tools.  The app uses Streamlit as the front end. Langchain, OpenAI’s GPT-4 model, and FAISS (Facebook AI Similarity Search) for document retrieval and question answering in the backend. Let’s break down the steps for better understanding: Loading a PDF file and splitting it into chunks of text. This makes the data optimized for retrieval Present the chunks to an embedding tool. Embeddings are numerical vector representations of data used to capture relationships, similarities, and meanings in a way that machines can understand. They are widely used in Natural Language Processing (NLP), recommender systems, and search engines. Next, we put those chunks of text and embeddings in the same DB for retrieval. Finally, we make it available to the LLM. Data preparation Preparing a content store for the LLM will take some steps, as we just saw. So, let’s start by creating a function that can load a file and split it into text chunks for efficient retrieval. # Imports from langchain_community.document_loaders import PyPDFLoader from langchain.text_splitter import RecursiveCharacterTextSplitter def load_document(pdf): # Load a PDF “”” Load a PDF and split it into chunks for efficient retrieval. :param pdf: PDF file to load :return: List of chunks of text “”” loader = PyPDFLoader(pdf) docs = loader.load() # Instantiate Text Splitter with Chunk Size of 500 words and Overlap of 100 words so that context is not lost text_splitter = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=100) # Split into chunks for efficient retrieval chunks = text_splitter.split_documents(docs) # Return return chunks Next, we will start building our Streamlit app, and we’ll use that function in the next script. Web application We will begin importing the necessary modules in Python. Most of those will come from the langchain packages. FAISS is used for document retrieval; OpenAIEmbeddings transforms the text chunks into numerical scores for better similarity calculation by the LLM; ChatOpenAI is what enables us to interact with the OpenAI API; create_retrieval_chain is what actually the RAG does, retrieving and augmenting the LLM with that data; create_stuff_documents_chain glues the model and the ChatPromptTemplate. Note: You will need to generate an OpenAI Key to be able to run this script. If it’s the first time you’re creating your account, you get some free credits. But if you have it for some time, it is possible that you will have to add 5 dollars in credits to be able to access OpenAI’s API. An option is using Hugging Face’s Embedding.  # Imports from langchain_community.vectorstores import FAISS from langchain_openai import OpenAIEmbeddings from langchain.chains import create_retrieval_chain from langchain_openai import ChatOpenAI from langchain.chains.combine_documents import create_stuff_documents_chain from langchain_core.prompts import ChatPromptTemplate from scripts.secret import OPENAI_KEY from scripts.document_loader import load_document import streamlit as st This first code snippet will create the App title, create a box for file upload, and prepare the file to be added to the load_document() function. # Create a Streamlit app st.title(“AI-Powered Document Q&A”) # Load document to streamlit uploaded_file = st.file_uploader(“Upload a PDF file”, type=”pdf”) # If a file is uploaded, create the TextSplitter and vector database if uploaded_file :     # Code to work around document loader from Streamlit and make it readable by langchain     temp_file = “./temp.pdf”     with open(temp_file, “wb”) as file:         file.write(uploaded_file.getvalue())         file_name = uploaded_file.name     # Load document and split it into chunks for efficient retrieval.     chunks = load_document(temp_file)     # Message user that document is being processed with time emoji     st.write(“Processing document… :watch:”) Machines understand numbers better than text, so in the end, we will have to provide the model with a database of numbers that it can compare and check for similarity when performing a query. That’s where the embeddings will be useful to create the vector_db, in this next piece of code. # Generate embeddings     # Embeddings are numerical vector representations of data, typically used to capture relationships, similarities,     # and meanings in a way that machines can understand. They are widely used in Natural Language Processing (NLP),     # recommender systems, and search engines.     embeddings = OpenAIEmbeddings(openai_api_key=OPENAI_KEY,                                   model=”text-embedding-ada-002″)     # Can also use HuggingFaceEmbeddings     # from langchain_huggingface.embeddings import HuggingFaceEmbeddings     # embeddings = HuggingFaceEmbeddings(model_name=”sentence-transformers/all-MiniLM-L6-v2″)     # Create vector database containing chunks and embeddings     vector_db = FAISS.from_documents(chunks, embeddings) Next, we create a retriever object to navigate in the vector_db. # Create a document retriever     retriever = vector_db.as_retriever()     llm = ChatOpenAI(model_name=”gpt-4o-mini”, openai_api_key=OPENAI_KEY) Then, we will create the system_prompt, which is a set of instructions to the LLM on how to answer, and we will create a prompt template, preparing it to be added to the model once we get the input from the user. # Create a system prompt     # It sets the overall context for the model.     # It influences tone, style, and focus before user interaction starts.     # Unlike user inputs, a system prompt is not visible to the end user.     system_prompt = (         “You are a helpful assistant. Use the given context to answer the question.”         “If you don’t know the answer, say you don’t know. ”         “{context}”     )     # Create a prompt Template     prompt = ChatPromptTemplate.from_messages(         [             (“system”, system_prompt),             (“human”, “{input}”),         ]     )     # Create a chain     # It creates a StuffDocumentsChain, which takes multiple documents (text data) and “stuffs” them together before passing them to the LLM for processing.     question_answer_chain = create_stuff_documents_chain(llm, prompt) Moving on, we create the core of the RAG framework, pasting together the retriever object and the prompt. This object adds relevant documents from a data source (e.g., a vector database) and makes it ready to be processed using an LLM to generate a response. # Creates the RAG      chain = create_retrieval_chain(retriever, question_answer_chain) Finally, we create the variable question for the user input. If this question box is filled with a query, we pass it to the chain, which calls the LLM to process and return the response, which will be printed on the app’s screen. # Streamlit input for question     question = st.text_input(“Ask a question about the document:”)     if question:         # Answer         response = chain.invoke({“input”: question})[‘answer’]         st.write(response) Here is a screenshot of the result. Screenshot of the final app. Image by the author. And this is a GIF for you to see the File Reader Ai Assistant in action! File Reader AI Assistant in action. Image by the author. Before you go In this project, we learned what the RAG framework is and how it helps the Llm to perform better and also perform well with specific knowledge. AI can be powered with knowledge from an instruction manual, databases from a company, some finance files, or contracts, and then become fine-tuned to respond accurately to domain-specific content queries. The knowledge base is augmented with a content store. To recap, this is how the framework works: 1️⃣ User Query → Input text is received. 2️⃣ Retrieve Relevant Documents → Searches a knowledge base (e.g., a database, vector store). 3️⃣ Augment Context → Retrieved documents are added to the input. 4️⃣ Generate Response → An LLM processes the combined input and produces an answer. GitHub repository https://github.com/gurezende/Basic-Rag About me If you liked this content and want to learn more about my work, here is my website, where you can also find all my contacts. https://gustavorsantos.me References https://cloud.google.com/use-cases/retrieval-augmented-generation https://www.ibm.com/think/topics/retrieval-augmented-generation https://python.langchain.com/docs/introduction https://www.geeksforgeeks.org/how-to-get-your-own-openai-api-key

Introduction

AI is everywhere. 

It is hard not to interact at least once a day with a Large Language Model (LLM). The chatbots are here to stay. They’re in your apps, they help you write better, they compose emails, they read emails…well, they do a lot.

And I don’t think that that is bad. In fact, my opinion is the other way – at least so far. I defend and advocate for the use of AI in our daily lives because, let’s agree, it makes everything much easier.

I don’t have to spend time double-reading a document to find punctuation problems or type. AI does that for me. I don’t waste time writing that follow-up email every single Monday. AI does that for me. I don’t need to read a huge and boring contract when I have an AI to summarize the main takeaways and action points to me!

These are only some of AI’s great uses. If you’d like to know more use cases of LLMs to make our lives easier, I wrote a whole book about them.

Now, thinking as a data scientist and looking at the technical side, not everything is that bright and shiny. 

LLMs are great for several general use cases that apply to anyone or any company. For example, coding, summarizing, or answering questions about general content created until the training cutoff date. However, when it comes to specific business applications, for a single purpose, or something new that didn’t make the cutoff date, that is when the models won’t be that useful if used out-of-the-box – meaning, they will not know the answer. Thus, it will need adjustments.

Training an LLM model can take months and millions of dollars. What is even worse is that if we don’t adjust and tune the model to our purpose, there will be unsatisfactory results or hallucinations (when the model’s response doesn’t make sense given our query).

So what is the solution, then? Spending a lot of money retraining the model to include our data?

Not really. That’s when the Retrieval-Augmented Generation (RAG) becomes useful.

RAG is a framework that combines getting information from an external knowledge base with large language models (LLMs). It helps AI models produce more accurate and relevant responses.

Let’s learn more about RAG next.

What is RAG?

Let me tell you a story to illustrate the concept.

I love movies. For some time in the past, I knew which movies were competing for the best movie category at the Oscars or the best actors and actresses. And I would certainly know which ones got the statue for that year. But now I am all rusty on that subject. If you asked me who was competing, I would not know. And even if I tried to answer you, I would give you a weak response. 

So, to provide you with a quality response, I will do what everybody else does: search for the information online, obtain it, and then give it to you. What I just did is the same idea as the RAG: I obtained data from an external database to give you an answer.

When we enhance the LLM with a content store where it can go and retrieve data to augment (increase) its knowledge base, that is the RAG framework in action.

RAG is like creating a content store where the model can enhance its knowledge and respond more accurately.
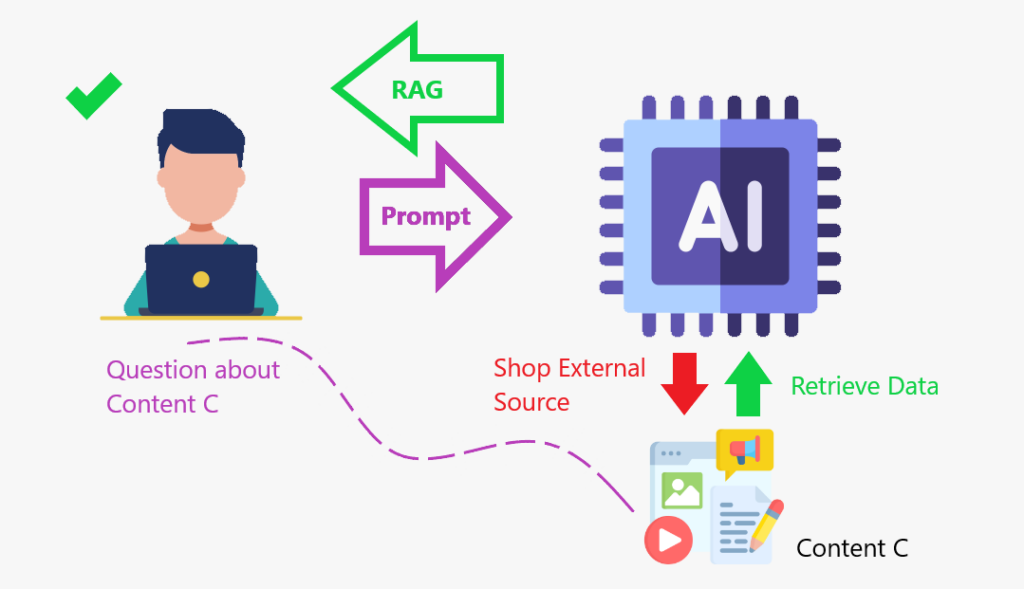
Diagram: User prompts and content using LLM + RAG
User prompt about Content C. LLM retrieves external content to aggregate to the answer. Image by the author.

Summarizing:

  1. Uses search algorithms to query external data sources, such as databases, knowledge bases, and web pages.
  2. Pre-processes the retrieved information.
  3. Incorporates the pre-processed information into the LLM.

Why use RAG?

Now that we know what the RAG framework is let’s understand why we should be using it.

Here are some of the benefits:

  • Enhances factual accuracy by referencing real data.
  • RAG can help LLMs process and consolidate knowledge to create more relevant answers 
  • RAG can help LLMs access additional knowledge bases, such as internal organizational data 
  • RAG can help LLMs create more accurate domain-specific content 
  • RAG can help reduce knowledge gaps and AI hallucination

As previously explained, I like to say that with the RAG framework, we are giving an internal search engine for the content we want it to add to the knowledge base.

Well. All of that is very interesting. But let’s see an application of RAG. We will learn how to create an AI-powered PDF Reader Assistant.

Project

This is an application that allows users to upload a PDF document and ask questions about its content using AI-powered natural language processing (NLP) tools. 

  • The app uses Streamlit as the front end.
  • Langchain, OpenAI’s GPT-4 model, and FAISS (Facebook AI Similarity Search) for document retrieval and question answering in the backend.

Let’s break down the steps for better understanding:

  1. Loading a PDF file and splitting it into chunks of text.
    1. This makes the data optimized for retrieval
  2. Present the chunks to an embedding tool.
    1. Embeddings are numerical vector representations of data used to capture relationships, similarities, and meanings in a way that machines can understand. They are widely used in Natural Language Processing (NLP), recommender systems, and search engines.
  3. Next, we put those chunks of text and embeddings in the same DB for retrieval.
  4. Finally, we make it available to the LLM.

Data preparation

Preparing a content store for the LLM will take some steps, as we just saw. So, let’s start by creating a function that can load a file and split it into text chunks for efficient retrieval.

# Imports
from  langchain_community.document_loaders import PyPDFLoader
from langchain.text_splitter import RecursiveCharacterTextSplitter

def load_document(pdf):
    # Load a PDF
    """
    Load a PDF and split it into chunks for efficient retrieval.

    :param pdf: PDF file to load
    :return: List of chunks of text
    """

    loader = PyPDFLoader(pdf)
    docs = loader.load()

    # Instantiate Text Splitter with Chunk Size of 500 words and Overlap of 100 words so that context is not lost
    text_splitter = RecursiveCharacterTextSplitter(chunk_size=500, chunk_overlap=100)
    # Split into chunks for efficient retrieval
    chunks = text_splitter.split_documents(docs)

    # Return
    return chunks

Next, we will start building our Streamlit app, and we’ll use that function in the next script.

Web application

We will begin importing the necessary modules in Python. Most of those will come from the langchain packages.

FAISS is used for document retrieval; OpenAIEmbeddings transforms the text chunks into numerical scores for better similarity calculation by the LLM; ChatOpenAI is what enables us to interact with the OpenAI API; create_retrieval_chain is what actually the RAG does, retrieving and augmenting the LLM with that data; create_stuff_documents_chain glues the model and the ChatPromptTemplate.

Note: You will need to generate an OpenAI Key to be able to run this script. If it’s the first time you’re creating your account, you get some free credits. But if you have it for some time, it is possible that you will have to add 5 dollars in credits to be able to access OpenAI’s API. An option is using Hugging Face’s Embedding. 

# Imports
from langchain_community.vectorstores import FAISS
from langchain_openai import OpenAIEmbeddings
from langchain.chains import create_retrieval_chain
from langchain_openai import ChatOpenAI
from langchain.chains.combine_documents import create_stuff_documents_chain
from langchain_core.prompts import ChatPromptTemplate
from scripts.secret import OPENAI_KEY
from scripts.document_loader import load_document
import streamlit as st

This first code snippet will create the App title, create a box for file upload, and prepare the file to be added to the load_document() function.

# Create a Streamlit app
st.title("AI-Powered Document Q&A")

# Load document to streamlit
uploaded_file = st.file_uploader("Upload a PDF file", type="pdf")

# If a file is uploaded, create the TextSplitter and vector database
if uploaded_file :

    # Code to work around document loader from Streamlit and make it readable by langchain
    temp_file = "./temp.pdf"
    with open(temp_file, "wb") as file:
        file.write(uploaded_file.getvalue())
        file_name = uploaded_file.name

    # Load document and split it into chunks for efficient retrieval.
    chunks = load_document(temp_file)

    # Message user that document is being processed with time emoji
    st.write("Processing document... :watch:")

Machines understand numbers better than text, so in the end, we will have to provide the model with a database of numbers that it can compare and check for similarity when performing a query. That’s where the embeddings will be useful to create the vector_db, in this next piece of code.

# Generate embeddings
    # Embeddings are numerical vector representations of data, typically used to capture relationships, similarities,
    # and meanings in a way that machines can understand. They are widely used in Natural Language Processing (NLP),
    # recommender systems, and search engines.
    embeddings = OpenAIEmbeddings(openai_api_key=OPENAI_KEY,
                                  model="text-embedding-ada-002")

    # Can also use HuggingFaceEmbeddings
    # from langchain_huggingface.embeddings import HuggingFaceEmbeddings
    # embeddings = HuggingFaceEmbeddings(model_name="sentence-transformers/all-MiniLM-L6-v2")

    # Create vector database containing chunks and embeddings
    vector_db = FAISS.from_documents(chunks, embeddings)

Next, we create a retriever object to navigate in the vector_db.

# Create a document retriever
    retriever = vector_db.as_retriever()
    llm = ChatOpenAI(model_name="gpt-4o-mini", openai_api_key=OPENAI_KEY)

Then, we will create the system_prompt, which is a set of instructions to the LLM on how to answer, and we will create a prompt template, preparing it to be added to the model once we get the input from the user.

# Create a system prompt
    # It sets the overall context for the model.
    # It influences tone, style, and focus before user interaction starts.
    # Unlike user inputs, a system prompt is not visible to the end user.

    system_prompt = (
        "You are a helpful assistant. Use the given context to answer the question."
        "If you don't know the answer, say you don't know. "
        "{context}"
    )

    # Create a prompt Template
    prompt = ChatPromptTemplate.from_messages(
        [
            ("system", system_prompt),
            ("human", "{input}"),
        ]
    )

    # Create a chain
    # It creates a StuffDocumentsChain, which takes multiple documents (text data) and "stuffs" them together before passing them to the LLM for processing.

    question_answer_chain = create_stuff_documents_chain(llm, prompt)

Moving on, we create the core of the RAG framework, pasting together the retriever object and the prompt. This object adds relevant documents from a data source (e.g., a vector database) and makes it ready to be processed using an LLM to generate a response.

# Creates the RAG
     chain = create_retrieval_chain(retriever, question_answer_chain)

Finally, we create the variable question for the user input. If this question box is filled with a query, we pass it to the chain, which calls the LLM to process and return the response, which will be printed on the app’s screen.

# Streamlit input for question
    question = st.text_input("Ask a question about the document:")
    if question:
        # Answer
        response = chain.invoke({"input": question})['answer']
        st.write(response)

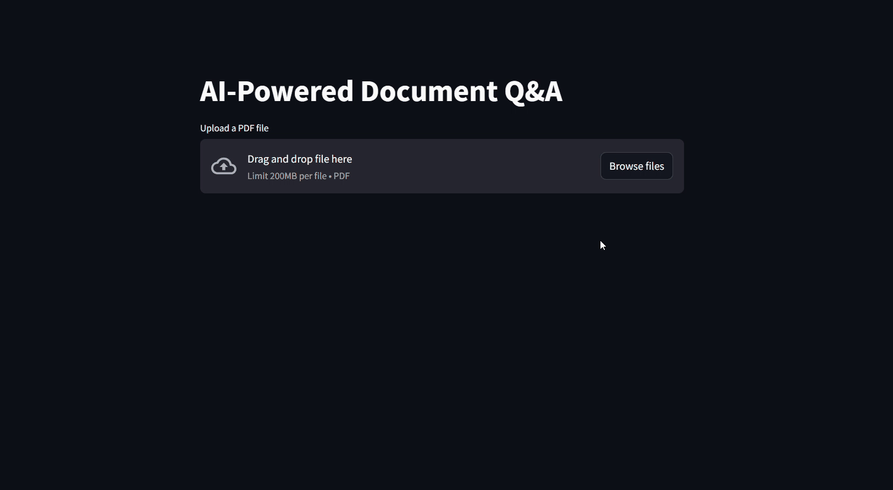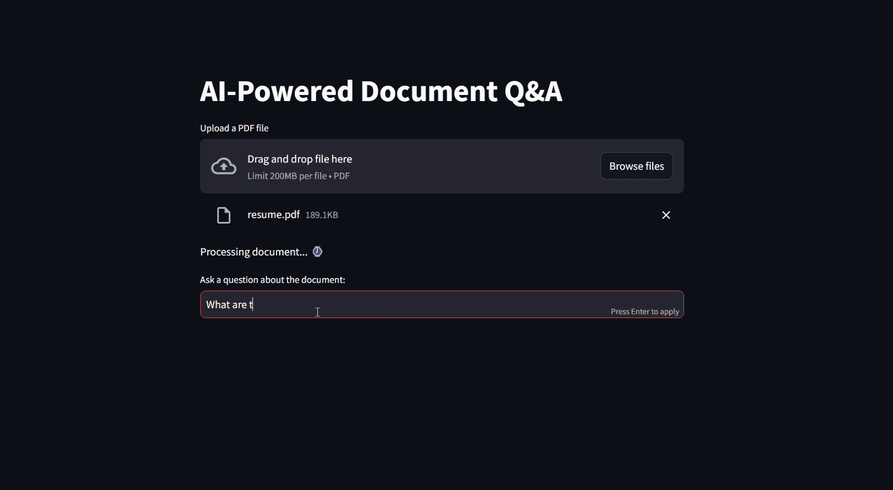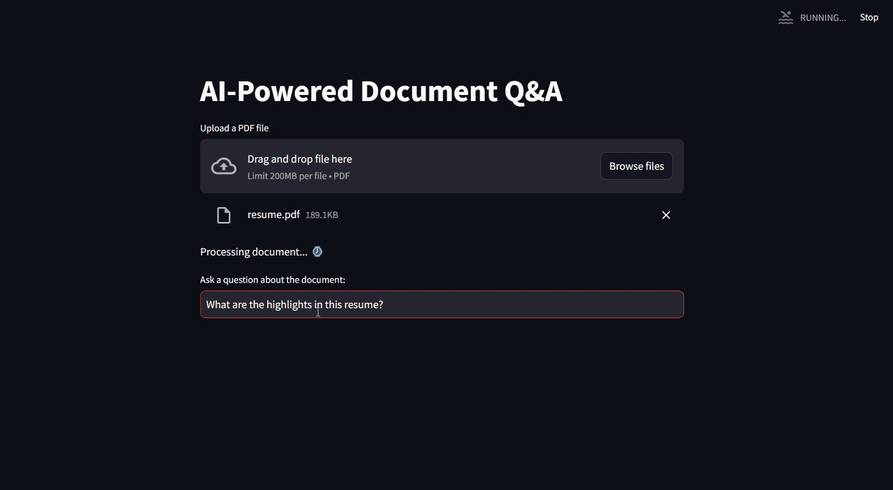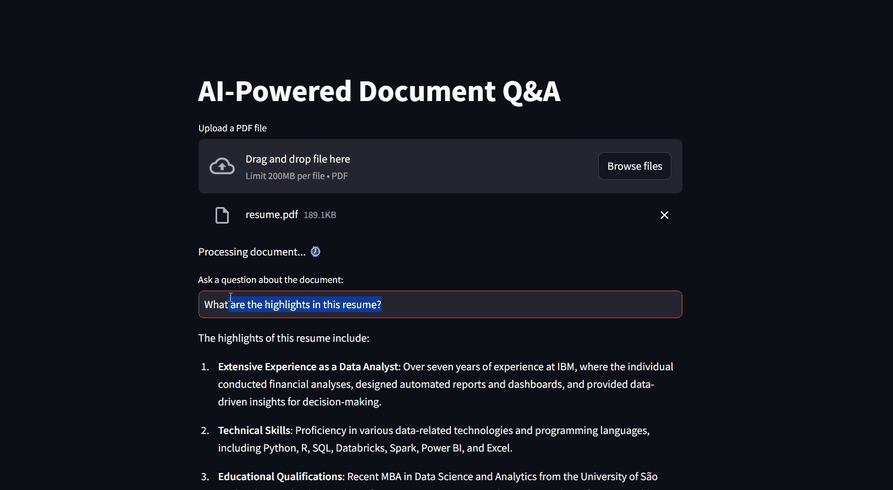
Here is a screenshot of the result.
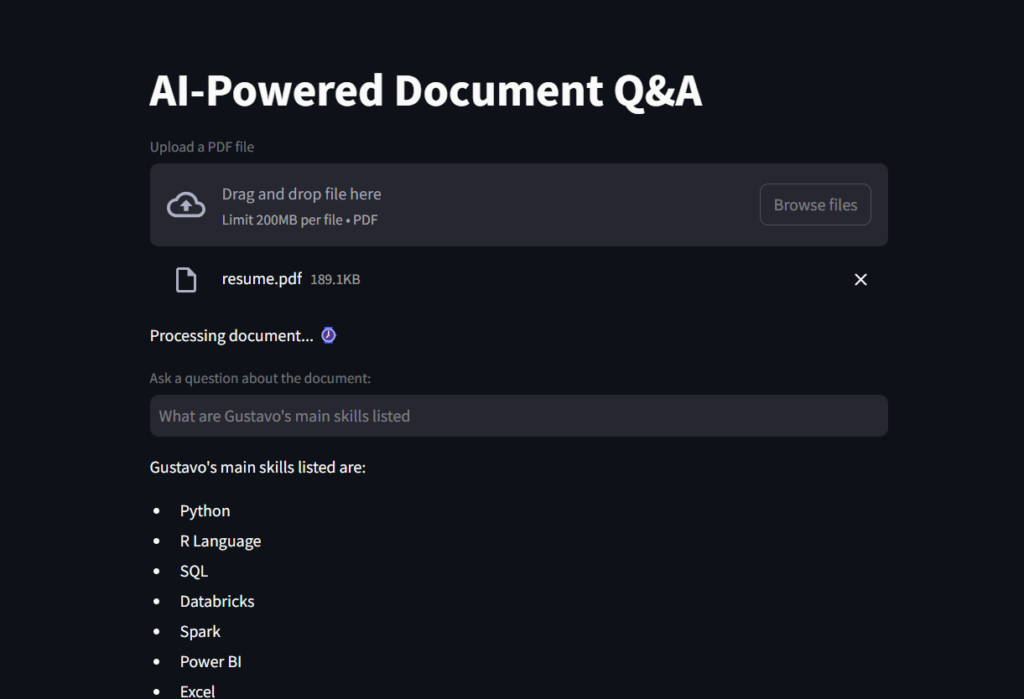
Screenshot of the AI-Powered Document Q&A
Screenshot of the final app. Image by the author.

And this is a GIF for you to see the File Reader Ai Assistant in action!
GIF of the File Reader AI Assistant in action
File Reader AI Assistant in action. Image by the author.

Before you go

In this project, we learned what the RAG framework is and how it helps the Llm to perform better and also perform well with specific knowledge.

AI can be powered with knowledge from an instruction manual, databases from a company, some finance files, or contracts, and then become fine-tuned to respond accurately to domain-specific content queries. The knowledge base is augmented with a content store.

To recap, this is how the framework works:

1️⃣ User Query → Input text is received.

2️⃣ Retrieve Relevant Documents → Searches a knowledge base (e.g., a database, vector store).

3️⃣ Augment Context → Retrieved documents are added to the input.

4️⃣ Generate Response → An LLM processes the combined input and produces an answer.

GitHub repository

https://github.com/gurezende/Basic-Rag

About me

If you liked this content and want to learn more about my work, here is my website, where you can also find all my contacts.

https://gustavorsantos.me

References

https://cloud.google.com/use-cases/retrieval-augmented-generation

https://www.ibm.com/think/topics/retrieval-augmented-generation

https://youtu.be/T-D1OfcDW1M?si=G0UWfH5-wZnMu0nw

https://python.langchain.com/docs/introduction

https://www.geeksforgeeks.org/how-to-get-your-own-openai-api-key
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Venture Global moves up first LNG date for CP2

The leaders of Venture Global Inc., Arlington, Va., have moved up to July the date at which they expect to produce the company’s first LNG from its CP2 complex in Louisiana. Chief executive officer Mike Sabel had previously told investors that Venture Global were targeting the second half of 2027

Read More »

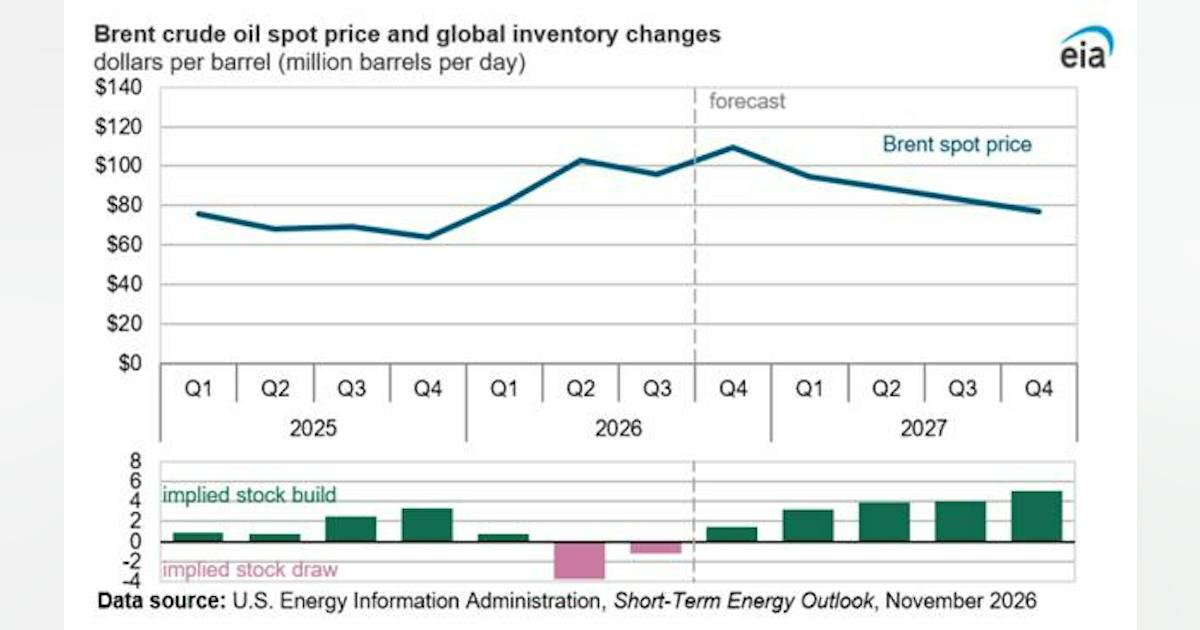
EIA sees Brent near $100/bbl through yearend 2026 as Middle East supply constraints persist

Global crude oil prices are expected to remain near $100/bbl through yearend 2026 as continued Middle East supply disruptions, tanker attacks, and constrained shipping capacity keep oil markets tight, the US Energy Information Administration (EIA) said in its November Short-Term Energy Outlook (STEO). EIA forecasts Brent crude oil spot prices will average about $100/bbl in November and December before gradually declining in 2027 as Middle East production recovers and global inventories rebuild. Brent is projected to average $97/bbl in 2026 and $86/bbl in 2027, falling to $77/bbl by fourth-quarter 2027. Brent averaged $124/bbl in October, up $10/bbl from September and the highest monthly average since July 2022 on an inflation-adjusted basis. Prices rose for a third consecutive month as declining inventories, tanker attacks in the Middle East and Black Sea, and higher shipping costs disrupted global oil flows. However, Middle East exports increased slightly in October following the restart of Saudi Arabia’s East-West Pipeline, according to Vortexa vessel-tracking data cited by EIA. Continued shipments through the Strait of Hormuz, supported by ship-to-ship transfers along Oman’s coast, also helped ease supply constraints. Brent fell below $100/bbl on Nov. 4. Middle East crude oil production shut-ins averaged an estimated 2.5 million b/d in October, down sharply from a peak of 10.9 million b/d in May. EIA expects disruptions to remain near 2.5 million b/d through fourth-quarter 2026 before declining to 1.9 million b/d in first-half 2027 and 1.3 million b/d in the second half. EIA assumes most Middle East production outside Iran will return to pre-conflict levels by mid-2027, supported by pipeline bypass routes, ship-to-ship transfers, and additional pipeline capacity in the United Arab Emirates. Iranian exports, however, are expected to remain constrained throughout the forecast period. Global oil inventories declined by an estimated 1.2 million b/d in third-quarter 2026 but are

Read More »

Salt Creek advances Delaware basin gas processing expansion

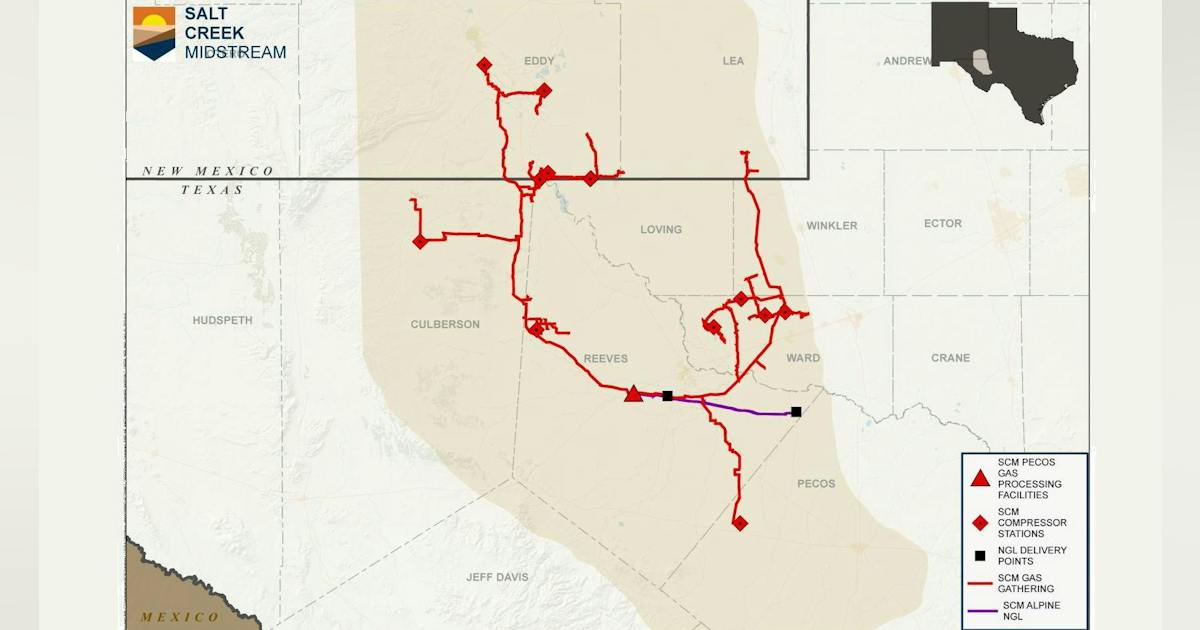
Salt Creek Midstream LLC has ordered long-lead equipment for a fourth cryogenic natural gas processing plant at its Pecos Processing Complex in Reeves County, Tex. Slated for final investment decision by yearend 2026, the proposed Pecos IV train project, if approved, would add up to 300 MMcfd of capacity and enter service in second-half 2028, the operator said in a release Nov. 11. Depending on a final capacity decision for the project, the expansion could lift the company’s overall installed Permian gas processing capacity to as much as 900 MMcfd. With the Pecos site designed for further expandability up to 1.2 billion bcfd from its current 600-MMcfd capacity, Salt Creek said it has also now secured grid power to support that potential buildout. The proposed project follows customer and volume growth across Salt Creek’s Delaware basin system, which the company said will exceed its existing system’s 600 MMcfd of processing capacity in first-half 2027. To support its planned Permian growth program, Salt Creek confirmed it has also secured strategic offloading contracts to provide firm processing capacity as a bridge to the planned expansions. Those offloads are scheduled to enter service by the end of first-quarter 2027, according to the operator. Salt Creek reported the addition of nearly 300,000 acres dedicated across the Permian’s eight core counties, following additional acreage commitments signed earlier in the year. The dedications cover more than 20 unidentified customers. The operator said it expects about 75% of anticipated 2027 throughput to come from investment-grade counterparties, while customer volume commitments to support about 35% of projected volumes. The company’s acreage position includes about 40,000 dedicated acres in the liquids-rich core of the Woodford fairway, along with additional exposure to prospective areas. Salt Creek estimated Woodford volumes to exceed 200 MMcfd by yearend 2027 based on more than

Read More »

No home left behind: Scaling VPP participation while maintaining customer control

Listen to the article 5 min This audio is auto-generated. Please let us know if you have feedback. Gisela Glandt is vice president of virtual power plants at Uplight, a provider of utility demand management solutions. Load growth is back, and it isn’t slowing down. Electrification, data centers and extreme weather are pushing utilities to find flexible capacity faster than they can build it. Demand-side programs including demand response, virtual power plants, time-varying rates and energy efficiency are one of the few levers that scale quickly and cost-effectively — yet the industry keeps hitting the same wall. Gisela Glandt Roughly 80% of customers say they want help managing their energy, but utilities are still seeing enrollment in demand management programs around 10% — despite larger incentives, more innovative technology, and more targeted marketing. What if the problem isn’t the customers and instead is the process of asking them to raise their hand? Opt-in utility program enrollment puts the burden on the customer: to understand the program, check to see if they are eligible, decide it’s worth it, and then take action. The benefits and incentives can show up months down the road, and they may even forget about them. Most people don’t make it past enrollment and it’s not because of lack of interest. It simply involves too many steps and too much brain power.  The industry is shifting from programs customers must join to flexibility that’s already embedded as a default or activated at the point of sale of a device, with no enrollment required. Where utilities have made this shift, customer participation climbs from 10% into the 70% to 100% range. One Midwestern utility that restructured a program from opt-in to opt-out scaled capacity four to five times faster — and had 70% to 80% of customers participate. 

Read More »

Planet One encounters hydrocarbons at Nya Gyidie-1X offshore Ghana

Planet One Oil & Gas has encountered hydrocarbons in the Nya Gyidie-1X exploration well on the Deepwater Cape Three Points (DWCTP) Block offshore Ghana, opening what the company describes as a new carbonate exploration play in the country. The well, drilled about 148 km offshore in 2,289 m of water, encountered hydrocarbons in carbonate reservoirs between 3,364 m and 3,499 m measured depth. Planet One said further technical evaluation is under way to determine the discovery’s size and commercial potential. According to the operator, Nya Gyidie-1X is Ghana’s first successful test of a Cenomanian-Turonian carbonate reservoir system as a primary exploration target. Most of the country’s commercial oil and gas discoveries to date have been associated with sandstone reservoirs. “The significance of Nya Gyidie-1X goes beyond the hydrocarbons encountered in this well,” said Kwame Ntow Amoah, chief executive officer of Ghana National Petroleum Corp. “For the first time in Ghana, we have tested and confirmed hydrocarbons in a carbonate reservoir system, opening up a new geological play for further exploration.” The DWCTP block covers about 1,454 sq km in the Deepwater Tano basin. Planet One operates the block with partners GOIL Upstream Ltd. and Ghana National Petroleum Corp.

Read More »

Chevron signs Namibia license farm-out deal with QatarEnergy

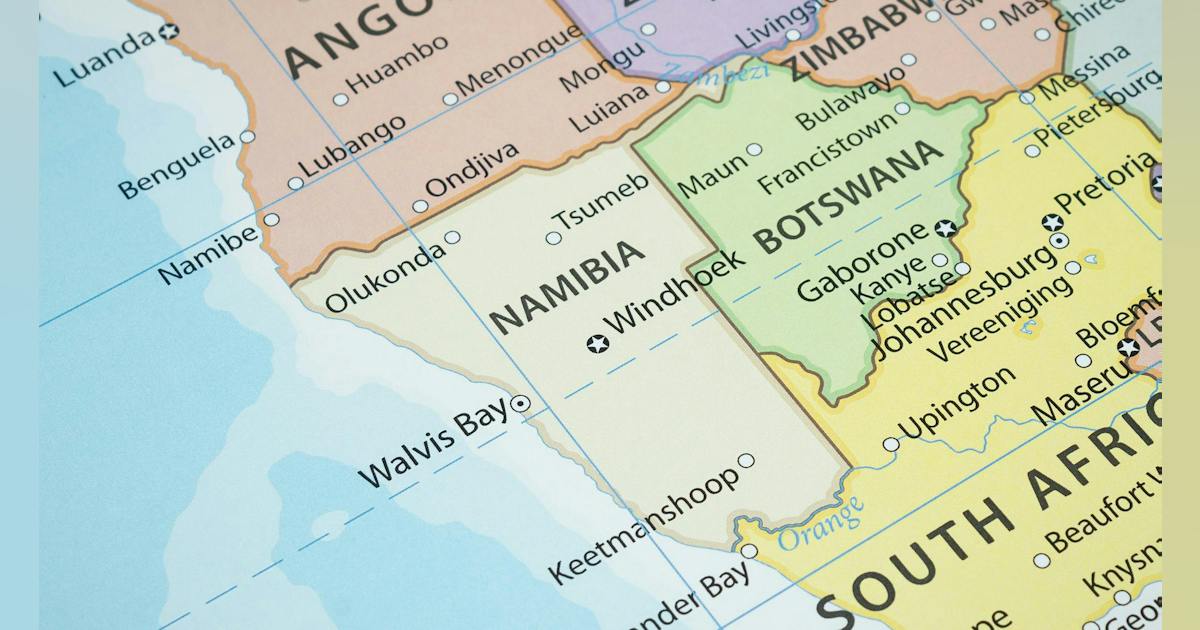
@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } Chevron Corp. has agreed to farm out to QatarEnergy a partial, non-operated interest in an exploration block offshore Namibia. Financial details were not disclosed.   Through the agreement, Chevron subsidiary Chevron Namibia Exploration II Ltd. will farm out 25% interest in Petroleum Exploration License 0082 (PEL82), comprising blocks 2112B and 2212A in Walvis basin, QatarEnergy said in a release this week. Upon completion of the deal, Chevron will remain operator of the block with 55% interest. Namcor E&P and Custos Energy will each hold a 10% interest. PEL82 covers an area of about 11,444 sq km in water depths of 350-2,300 m. Chevron acquired an 80% operated interest in the license in 2024 through a farm-in deal with National Petroleum Corp. of Namibia (Namcor). At the time of Chevron’s farmout with Namcor, about 70% of the total block area was covered by existing seismic (3,500 km of 2D and 9,500 sq km of 3D) data. Previous drilling activity on the license included the Murombe-1 and Wingat-1 wells. Results confirmed regional extension and presence of the Barremian-Aptianoil-prone source rock (Kudu shale). The Murombe-1 penetrated the Baobab sands with about 20% porosity. The Wingat-1 well recovered 38-41° API oil to surface.

Read More »

Energy Department Closes $480 Million Loan to Expand American Energy Production and Strengthen Offshore Infrastructure in the Gulf of America

The U.S. Department of Energy’s (DOE) Office of Energy Dominance Financing (EDF) today announced the financial close of a $480 million loan for Arena Energy’s Project Elkhorn to increase oil and natural gas production across the Gulf of America shelf. The project will modernize 22 offshore platforms off the coast of Louisiana and, at peak production, is expected to add up to 38,600 barrels of oil per day and up to 77 million cubic feet of natural gas per day to U.S. energy production. Today’s announcement is made possible by President Trump’s Working Families Tax Cut and marks the Energy Department’s first closed loan supporting domestic oil and natural gas production, underscoring DOE’s commitment to advancing American energy dominance and delivering affordable, reliable, and secure energy for American families and businesses. “The United States is the world’s largest producer and exporter of oil and natural gas, and thanks to President Trump, American energy production will continue to grow,” said U.S. Secretary of Energy Chris Wright. “Project Elkhorn will increase oil production by up to 38,600 barrels per day and create thousands of jobs. By providing financing for projects like Project Elkhorn, the Energy Department is expanding domestic production and strengthening our energy security to power American prosperity for decades to come.” Arena Energy currently produces approximately 30,000 barrels of oil per day offshore in the Gulf of America. Project Elkhorn will modernize existing offshore infrastructure and expand production capacity—adding approximately 125 million barrels of oil and 250 billion cubic feet of natural gas to U.S. energy production over the life of the project. The project will create 2,400 construction-related jobs and 400 operations jobs in one of the nation’s most important offshore energy corridors. “Thanks to President Trump and Secretary Wright’s leadership, EDF is putting existing energy infrastructure back to work for the American people,” said EDF Director Gregory A. Beard. “Project Elkhorn will expand domestic oil and natural gas production, create good-paying

Read More »

Google’s Utah Deal Puts Geothermal Power on the Data Center Map

In Taiwan, the Work Begins With Access to Land Google’s first geothermal procurement agreements in Asia call for an initial 10 MW of new generation on Taiwan’s grid to support local data centers and offices. When Google and developer Baseload Capital announced the agreements in April 2025, a Google energy executive told Taiwan Public Television Service that the companies expected operations to begin in 2029. The original timetable allowed roughly four years between signing a customer and delivering electricity. Baseload’s development work in Hualien County illustrates one reason such projects take time. In November 2025, the company reported that members of the Hongye Tribe had voted to approve a public-land lease for geothermal exploration. Baseload opened a local office, reached an agreement with the community, and secured an exploration permit for a two-year program of drilling in stages. The company has described Hongye separately from Google’s contracted supply. What the Hualien project documents is an early milestone rarely visible in a power purchase announcement: the developer secured community consent before drilling could establish what the field might produce. Kenya Has the Generating Field. The Campus Remains Unresolved. In Kenya’s Rift Valley, the appeal of Olkaria was evident when Microsoft and G42 announced their digital investment initiative in 2024. Kenya already had a fleet of geothermal generating stations at Olkaria. G42 and local partners proposed building a campus there, powered by geothermal electricity and hosting Microsoft Azure services for a new East Africa cloud region. Two difficulties emerged. In May 2026, Semafor reported that President William Ruto had cited insufficient available power as an obstacle to the project. Separately, Reuters, citing Bloomberg, reported disagreements over payment guarantees. Microsoft and G42 had sought a commitment from the Kenyan government to buy a certain amount of computing capacity annually. Kenya’s principal secretary for

Read More »

Alberta’s Gigawatt Play: Why Building Data Centers Means Building an Industry

For Alberta’s emerging data center industry, the difference between a roadmap and an excavator has become increasingly consequential. A few years ago, Western Canada’s data center conversation revolved around the possibilities: abundant energy resources, available land, a favorable climate and the prospect of attracting hyperscale investment to a region better known for oil, gas and other industrial development. Today, earthmoving equipment is preparing the ground for what is expected to become Canada’s largest data center, and the questions facing the province have changed accordingly. The shift was on display at Data Centre West 2026, held in Calgary in September, where some 500 industry and government leaders gathered to examine the infrastructure and policy requirements of Alberta’s rapidly expanding digital economy. But for conference founder Vlad Oujegov, the most revealing development wasn’t simply the appearance of projects measured in gigawatts. It was the growing recognition that building those projects will require Alberta to develop an entire supporting industry, while confronting the environmental, political and community questions that increasingly accompany large-scale AI infrastructure. “The theme last year was the data center roadmap,” Oujegov told Data Center Frontier Editor in Chief Matt Vincent during a new episode of the Data Center Frontier Show podcast. “This year’s theme really to me was about execution and actually getting things done, actually seeing projects materialize and construction beginning.” Oujegov is president and founder of the Western Canada Data Centre Alliance, which organizes Data Centre West, and serves as National Data Center Power Systems Lead at Schneider Electric. His perspective draws on both Alberta’s emerging development pipeline and the wider industrial ecosystem now being assembled around it. In DCF’s earlier reporting from Data Centre West 2026, the central question was how quickly Alberta could convert growing hyperscale demand into deliverable capacity. The latest podcast conversation takes that

Read More »

Data center champions lose badly as ballot initiatives target AI infrastructure

In other locales, data centers lost badly. In Joliet Township, Illinois, a restriction on new data centers passed with 80% of the vote. In Hubbard, Ohio, more than three-quarters of voters gave data centers a thumbs down. Ohio emerged as the main battleground, accounting for 21 of the 50 measures tracked by Ballotpedia. The votes covered several different approaches to controlling development: outright bans, power-consumption thresholds, temporary permitting moratoriums, mandatory public votes and requirements for developers seeking tax incentives. California and Florida saw outright bans. California voters in the cities of Alhambra and Monterey Park, where voters approved a measure prohibiting data centers. In Florida, Edgewater voters approved a charter amendment opposing new data centers and expansions of existing facilities.

Read More »

Land & Expand: Texas’ AI Boom Meets a New Political Reality

Hut 8 Advances a Gigawatt-Scale Campus Near Corpus Christi Another significant development came November 4, when Hut 8 reported continued progress on its Beacon Point AI data center campus in the Corpus Christi region. The company said that its previously announced second 352 MW IT-capacity lease had fully commercialized the campus, bringing the total contracted IT capacity associated with the two phases to 704 MW. The campus is designed around approximately 1 GW of utility capacity, a separate measure from the critical IT load under lease. Hut 8 estimates approximately $19.6 billion in base-term contract value across the two phases. In its third-quarter results, the company said construction of the campus substation had begun, alongside foundation and underground utility work for the first phase. Initial data hall delivery is targeted for the third quarter of 2027, with the second phase targeted for the second quarter of 2028. The company also disclosed agreements to acquire two energized sites in West Texas, with up to 230 MW of utility capacity at full energization, subject to outstanding approvals and infrastructure development. Those acquisitions point to another important trend: the increasing value of existing electrical infrastructure and sites that can potentially be adapted to serve advanced computing. As new greenfield projects face lengthy power studies and regulatory requirements, already energized locations may offer an alternative route to capacity. The distinction is especially important in markets such as Dallas-Fort Worth, where DCF’s analysis of CBRE’s first-half 2026 data found that approximately 95% of the region’s 765 MW under construction had already been preleased. PowerHouse and Big Watt Win Approval for Taylor Technology Campus Not every large new project is meeting resistance at the municipal level. On October 8, the City of Taylor approved a development agreement with PowerHouse Data Centers and Big Watt Digital for

Read More »

Google targets AI’s next infrastructure bottlenecks with two new TPUs

“It’s like adding more lanes to the highway,” he observed. “We’re not necessarily making each car travel faster, we’re creating more capacity so more traffic can move through the system at the same time.” Handling bursts, idling However, an agentic workload doesn’t behave exactly like a traditional inference workload. “It is bursty, long running, but often idle,” Lohmeyer noted. While it might generate outputs and call tools, it still has to wait for a response, maybe from a human, “literally for days.” During that time, it doesn’t need to do anything; it just needs to preserve context. But if resources are tied up for that entire multi-day period, they’re being wasted “90% plus of the time,” he said. Google Cloud’s open source TPU Sync is designed to address these issues by unifying memory, storage, and networking in software. The model-state layer for TPUs turns chip high bandwidth memory (HBM), host DRAM, shared storage, and the data center network into a “single, co-designed memory hierarchy,” the company said. It automatically tiers KV caches off the chip in milliseconds, streams context across nodes, and synchronizes RL weights to cut transfer latency and Time to First Token (TTFT) by more than 90%.

Read More »

DCF Global: Britain’s New Bargain With the AI Data Center Industry

The Global Perspective: A New Bargain for the AI Economy? Britain’s new Data Centre Covenant may ultimately prove important well beyond the United Kingdom. Governments across the world are attempting to reconcile the economic promise of AI infrastructure with the extraordinary physical requirements of building it. Electricity networks must accommodate loads measured in hundreds of megawatts. Utilities must plan transmission and generation investments years in advance. Communities are being asked to host facilities whose construction costs can run into billions, but whose permanent employment footprints may be relatively modest. At the same time, national governments increasingly view domestic computing capacity as a strategic asset. Britain is attempting to connect those issues within a single policy framework. Its approach differs in important respects from the fragmented regulatory environment in the United States, where utility commissions, state governments, local authorities, and regional grid operators exercise separate—and sometimes competing—powers over development. Nevertheless, the underlying questions are increasingly similar. In DCF’s October examination of Virginia’s changing data center policies, the industry’s largest established market was confronting new expectations concerning infrastructure costs, utility commitments, community impacts, and the conditions under which large facilities should receive development approval. Britain’s Covenant addresses comparable pressures through a more coordinated national initiative. It effectively proposes that preferential treatment for strategically important data center development should be accompanied by demonstrable public value. That is a meaningful evolution in the relationship between government and the industry. For years, data center investment announcements have emphasized capital expenditure, construction employment, technological leadership, and economic development. Those considerations remain important. But Britain’s emerging framework asks a more demanding set of questions: Can the project obtain real electricity capacity? Will it pay its fair share of infrastructure costs? Does it contribute to domestic capability? What obligations does it have to its host community? And can

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »