Stay Ahead, Stay ONMINE

Overcome Failing Document Ingestion & RAG Strategies with Agentic Knowledge Distillation

Introduction Many generative AI use cases still revolve around Retrieval Augmented Generation (RAG), yet consistently fall short of user expectations. Despite the growing body of research on RAG improvements and even adding Agents into the process, many solutions still fail to return exhaustive results, miss information that is critical but infrequently mentioned in the documents, require multiple search iterations, and generally struggle to reconcile key themes across multiple documents. To top it all off, many implementations still rely on cramming as much “relevant” information as possible into the model’s context window alongside detailed system and user prompts. Reconciling all this information often exceeds the model’s cognitive capacity and compromises response quality and consistency. This is where our Agentic Knowledge Distillation + Pyramid Search Approach comes into play. Instead of chasing the best chunking strategy, retrieval algorithm, or inference-time reasoning method, my team, Jim Brown, Mason Sawtell, Sandi Besen, and I, take an agentic approach to document ingestion. We leverage the full capability of the model at ingestion time to focus exclusively on distilling and preserving the most meaningful information from the document dataset. This fundamentally simplifies the RAG process by allowing the model to direct its reasoning abilities toward addressing the user/system instructions rather than struggling to understand formatting and disparate information across document chunks.  We specifically target high-value questions that are often difficult to evaluate because they have multiple correct answers or solution paths. These cases are where traditional RAG solutions struggle most and existing RAG evaluation datasets are largely insufficient for testing this problem space. For our research implementation, we downloaded annual and quarterly reports from the last year for the 30 companies in the DOW Jones Industrial Average. These documents can be found through the SEC EDGAR website. The information on EDGAR is accessible and able to be downloaded for free or can be queried through EDGAR public searches. See the SEC privacy policy for additional details, information on the SEC website is “considered public information and may be copied or further distributed by users of the web site without the SEC’s permission”. We selected this dataset for two key reasons: first, it falls outside the knowledge cutoff for the models evaluated, ensuring that the models cannot respond to questions based on their knowledge from pre-training; second, it’s a close approximation for real-world business problems while allowing us to discuss and share our findings using publicly available data.  While typical RAG solutions excel at factual retrieval where the answer is easily identified in the document dataset (e.g., “When did Apple’s annual shareholder’s meeting occur?”), they struggle with nuanced questions that require a deeper understanding of concepts across documents (e.g., “Which of the DOW companies has the most promising AI strategy?”). Our Agentic Knowledge Distillation + Pyramid Search Approach addresses these types of questions with much greater success compared to other standard approaches we tested and overcomes limitations associated with using knowledge graphs in RAG systems.  In this article, we’ll cover how our knowledge distillation process works, key benefits of this approach, examples, and an open discussion on the best way to evaluate these types of systems where, in many cases, there is no singular “right” answer. Building the pyramid: How Agentic Knowledge Distillation works Image by author and team depicting pyramid structure for document ingestion. Robots meant to represent agents building the pyramid. Overview Our knowledge distillation process creates a multi-tiered pyramid of information from the raw source documents. Our approach is inspired by the pyramids used in deep learning computer vision-based tasks, which allow a model to analyze an image at multiple scales. We take the contents of the raw document, convert it to markdown, and distill the content into a list of atomic insights, related concepts, document abstracts, and general recollections/memories. During retrieval it’s possible to access any or all levels of the pyramid to respond to the user request.  How to distill documents and build the pyramid:  Convert documents to Markdown: Convert all raw source documents to Markdown. We’ve found models process markdown best for this task compared to other formats like JSON and it is more token efficient. We used Azure Document Intelligence to generate the markdown for each page of the document, but there are many other open-source libraries like MarkItDown which do the same thing. Our dataset included 331 documents and 16,601 pages.  Extract atomic insights from each page: We process documents using a two-page sliding window, which allows each page to be analyzed twice. This gives the agent the opportunity to correct any potential mistakes when processing the page initially. We instruct the model to create a numbered list of insights that grows as it processes the pages in the document. The agent can overwrite insights from the previous page if they were incorrect since it sees each page twice. We instruct the model to extract insights in simple sentences following the subject-verb-object (SVO) format and to write sentences as if English is the second language of the user. This significantly improves performance by encouraging clarity and precision. Rolling over each page multiple times and using the SVO format also solves the disambiguation problem, which is a huge challenge for knowledge graphs. The insight generation step is also particularly helpful for extracting information from tables since the model captures the facts from the table in clear, succinct sentences. Our dataset produced 216,931 total insights, about 13 insights per page and 655 insights per document. Distilling concepts from insights: From the detailed list of insights, we identify higher-level concepts that connect related information about the document. This step significantly reduces noise and redundant information in the document while preserving essential information and themes. Our dataset produced 14,824 total concepts, about 1 concept per page and 45 concepts per document.  Creating abstracts from concepts: Given the insights and concepts in the document, the LLM writes an abstract that appears both better than any abstract a human would write and more information-dense than any abstract present in the original document. The LLM generated abstract provides incredibly comprehensive knowledge about the document with a small token density that carries a significant amount of information. We produce one abstract per document, 331 total. Storing recollections/memories across documents: At the top of the pyramid we store critical information that is useful across all tasks. This can be information that the user shares about the task or information the agent learns about the dataset over time by researching and responding to tasks. For example, we can store the current 30 companies in the DOW as a recollection since this list is different from the 30 companies in the DOW at the time of the model’s knowledge cutoff. As we conduct more and more research tasks, we can continuously improve our recollections and maintain an audit trail of which documents these recollections originated from. For example, we can keep track of AI strategies across companies, where companies are making major investments, etc. These high-level connections are super important since they reveal relationships and information that are not apparent in a single page or document. Sample subset of insights extracted from IBM 10Q, Q3 2024 (page 4) We store the text and embeddings for each layer of the pyramid (pages and up) in Azure PostgreSQL. We originally used Azure AI Search, but switched to PostgreSQL for cost reasons. This required us to write our own hybrid search function since PostgreSQL doesn’t yet natively support this feature. This implementation would work with any vector database or vector index of your choosing. The key requirement is to store and efficiently retrieve both text and vector embeddings at any level of the pyramid.  This approach essentially creates the essence of a knowledge graph, but stores information in natural language, the way an LLM natively wants to interact with it, and is more efficient on token retrieval. We also let the LLM pick the terms used to categorize each level of the pyramid, this seemed to let the model decide for itself the best way to describe and differentiate between the information stored at each level. For example, the LLM preferred “insights” to “facts” as the label for the first level of distilled knowledge. Our goal in doing this was to better understand how an LLM thinks about the process by letting it decide how to store and group related information.  Using the pyramid: How it works with RAG & Agents At inference time, both traditional RAG and agentic approaches benefit from the pre-processed, distilled information ingested in our knowledge pyramid. The pyramid structure allows for efficient retrieval in both the traditional RAG case, where only the top X related pieces of information are retrieved or in the Agentic case, where the Agent iteratively plans, retrieves, and evaluates information before returning a final response.  The benefit of the pyramid approach is that information at any and all levels of the pyramid can be used during inference. For our implementation, we used PydanticAI to create a search agent that takes in the user request, generates search terms, explores ideas related to the request, and keeps track of information relevant to the request. Once the search agent determines there’s sufficient information to address the user request, the results are re-ranked and sent back to the LLM to generate a final reply. Our implementation allows a search agent to traverse the information in the pyramid as it gathers details about a concept/search term. This is similar to walking a knowledge graph, but in a way that’s more natural for the LLM since all the information in the pyramid is stored in natural language. Depending on the use case, the Agent could access information at all levels of the pyramid or only at specific levels (e.g. only retrieve information from the concepts). For our experiments, we did not retrieve raw page-level data since we wanted to focus on token efficiency and found the LLM-generated information for the insights, concepts, abstracts, and recollections was sufficient for completing our tasks. In theory, the Agent could also have access to the page data; this would provide additional opportunities for the agent to re-examine the original document text; however, it would also significantly increase the total tokens used.  Here is a high-level visualization of our Agentic approach to responding to user requests: Image created by author and team providing an overview of the agentic research & response process Results from the pyramid: Real-world examples To evaluate the effectiveness of our approach, we tested it against a variety of question categories, including typical fact-finding questions and complex cross-document research and analysis tasks.  Fact-finding (spear fishing):  These tasks require identifying specific information or facts that are buried in a document. These are the types of questions typical RAG solutions target but often require many searches and consume lots of tokens to answer correctly.  Example task: “What was IBM’s total revenue in the latest financial reporting?” Example response using pyramid approach: “IBM’s total revenue for the third quarter of 2024 was $14.968 billion [ibm-10q-q3-2024.pdf, pg. 4] Total tokens used to research and generate response This result is correct (human-validated) and was generated using only 9,994 total tokens, with 1,240 tokens in the generated final response.  Complex research and analysis:  These tasks involve researching and understanding multiple concepts to gain a broader understanding of the documents and make inferences and informed assumptions based on the gathered facts. Example task: “Analyze the investments Microsoft and NVIDIA are making in AI and how they are positioning themselves in the market. The report should be clearly formatted.” Example response: Response generated by the agent analyzing AI investments and positioning for Microsoft and NVIDIA. The result is a comprehensive report that executed quickly and contains detailed information about each of the companies. 26,802 total tokens were used to research and respond to the request with a significant percentage of them used for the final response (2,893 tokens or ~11%). These results were also reviewed by a human to verify their validity. Snippet indicating total token usage for the task Example task: “Create a report on analyzing the risks disclosed by the various financial companies in the DOW. Indicate which risks are shared and unique.” Example response: Part 1 of response generated by the agent on disclosed risks. Part 2 of response generated by the agent on disclosed risks. Similarly, this task was completed in 42.7 seconds and used 31,685 total tokens, with 3,116 tokens used to generate the final report.  Snippet indicating total token usage for the task These results for both fact-finding and complex analysis tasks demonstrate that the pyramid approach efficiently creates detailed reports with low latency using a minimal amount of tokens. The tokens used for the tasks carry dense meaning with little noise allowing for high-quality, thorough responses across tasks. Benefits of the pyramid: Why use it? Overall, we found that our pyramid approach provided a significant boost in response quality and overall performance for high-value questions.  Some of the key benefits we observed include:  Reduced model’s cognitive load: When the agent receives the user task, it retrieves pre-processed, distilled information rather than the raw, inconsistently formatted, disparate document chunks. This fundamentally improves the retrieval process since the model doesn’t waste its cognitive capacity on trying to break down the page/chunk text for the first time.  Superior table processing: By breaking down table information and storing it in concise but descriptive sentences, the pyramid approach makes it easier to retrieve relevant information at inference time through natural language queries. This was particularly important for our dataset since financial reports contain lots of critical information in tables.  Improved response quality to many types of requests: The pyramid enables more comprehensive context-aware responses to both precise, fact-finding questions and broad analysis based tasks that involve many themes across numerous documents.  Preservation of critical context: Since the distillation process identifies and keeps track of key facts, important information that might appear only once in the document is easier to maintain. For example, noting that all tables are represented in millions of dollars or in a particular currency. Traditional chunking methods often cause this type of information to slip through the cracks.  Optimized token usage, memory, and speed: By distilling information at ingestion time, we significantly reduce the number of tokens required during inference, are able to maximize the value of information put in the context window, and improve memory use.  Scalability: Many solutions struggle to perform as the size of the document dataset grows. This approach provides a much more efficient way to manage a large volume of text by only preserving critical information. This also allows for a more efficient use of the LLMs context window by only sending it useful, clear information. Efficient concept exploration: The pyramid enables the agent to explore related information similar to navigating a knowledge graph, but does not require ever generating or maintaining relationships in the graph. The agent can use natural language exclusively and keep track of important facts related to the concepts it’s exploring in a highly token-efficient and fluid way.  Emergent dataset understanding: An unexpected benefit of this approach emerged during our testing. When asking questions like “what can you tell me about this dataset?” or “what types of questions can I ask?”, the system is able to respond and suggest productive search topics because it has a more robust understanding of the dataset context by accessing higher levels in the pyramid like the abstracts and recollections.  Beyond the pyramid: Evaluation challenges & future directions Challenges While the results we’ve observed when using the pyramid search approach have been nothing short of amazing, finding ways to establish meaningful metrics to evaluate the entire system both at ingestion time and during information retrieval is challenging. Traditional RAG and Agent evaluation frameworks often fail to address nuanced questions and analytical responses where many different responses are valid. Our team plans to write a research paper on this approach in the future, and we are open to any thoughts and feedback from the community, especially when it comes to evaluation metrics. Many of the existing datasets we found were focused on evaluating RAG use cases within one document or precise information retrieval across multiple documents rather than robust concept and theme analysis across documents and domains.  The main use cases we are interested in relate to broader questions that are representative of how businesses actually want to interact with GenAI systems. For example, “tell me everything I need to know about customer X” or “how do the behaviors of Customer A and B differ? Which am I more likely to have a successful meeting with?”. These types of questions require a deep understanding of information across many sources. The answers to these questions typically require a person to synthesize data from multiple areas of the business and think critically about it. As a result, the answers to these questions are rarely written or saved anywhere which makes it impossible to simply store and retrieve them through a vector index in a typical RAG process.  Another consideration is that many real-world use cases involve dynamic datasets where documents are consistently being added, edited, and deleted. This makes it difficult to evaluate and track what a “correct” response is since the answer will evolve as the available information changes.  Future directions In the future, we believe that the pyramid approach can address some of these challenges by enabling more effective processing of dense documents and storing learned information as recollections. However, tracking and evaluating the validity of the recollections over time will be critical to the system’s overall success and remains a key focus area for our ongoing work.  When applying this approach to organizational data, the pyramid process could also be used to identify and assess discrepancies across areas of the business. For example, uploading all of a company’s sales pitch decks could surface where certain products or services are being positioned inconsistently. It could also be used to compare insights extracted from various line of business data to help understand if and where teams have developed conflicting understandings of topics or different priorities. This application goes beyond pure information retrieval use cases and would allow the pyramid to serve as an organizational alignment tool that helps identify divergences in messaging, terminology, and overall communication.  Conclusion: Key takeaways and why the pyramid approach matters The knowledge distillation pyramid approach is significant because it leverages the full power of the LLM at both ingestion and retrieval time. Our approach allows you to store dense information in fewer tokens which has the added benefit of reducing noise in the dataset at inference. Our approach also runs very quickly and is incredibly token efficient, we are able to generate responses within seconds, explore potentially hundreds of searches, and on average use
Introduction

Many generative AI use cases still revolve around Retrieval Augmented Generation (RAG), yet consistently fall short of user expectations. Despite the growing body of research on RAG improvements and even adding Agents into the process, many solutions still fail to return exhaustive results, miss information that is critical but infrequently mentioned in the documents, require multiple search iterations, and generally struggle to reconcile key themes across multiple documents. To top it all off, many implementations still rely on cramming as much “relevant” information as possible into the model’s context window alongside detailed system and user prompts. Reconciling all this information often exceeds the model’s cognitive capacity and compromises response quality and consistency.

This is where our Agentic Knowledge Distillation + Pyramid Search Approach comes into play. Instead of chasing the best chunking strategy, retrieval algorithm, or inference-time reasoning method, my team, Jim Brown, Mason Sawtell, Sandi Besen, and I, take an agentic approach to document ingestion.

We leverage the full capability of the model at ingestion time to focus exclusively on distilling and preserving the most meaningful information from the document dataset. This fundamentally simplifies the RAG process by allowing the model to direct its reasoning abilities toward addressing the user/system instructions rather than struggling to understand formatting and disparate information across document chunks. 

We specifically target high-value questions that are often difficult to evaluate because they have multiple correct answers or solution paths. These cases are where traditional RAG solutions struggle most and existing RAG evaluation datasets are largely insufficient for testing this problem space. For our research implementation, we downloaded annual and quarterly reports from the last year for the 30 companies in the DOW Jones Industrial Average. These documents can be found through the SEC EDGAR website. The information on EDGAR is accessible and able to be downloaded for free or can be queried through EDGAR public searches. See the SEC privacy policy for additional details, information on the SEC website is “considered public information and may be copied or further distributed by users of the web site without the SEC’s permission”. We selected this dataset for two key reasons: first, it falls outside the knowledge cutoff for the models evaluated, ensuring that the models cannot respond to questions based on their knowledge from pre-training; second, it’s a close approximation for real-world business problems while allowing us to discuss and share our findings using publicly available data. 

While typical RAG solutions excel at factual retrieval where the answer is easily identified in the document dataset (e.g., “When did Apple’s annual shareholder’s meeting occur?”), they struggle with nuanced questions that require a deeper understanding of concepts across documents (e.g., “Which of the DOW companies has the most promising AI strategy?”). Our Agentic Knowledge Distillation + Pyramid Search Approach addresses these types of questions with much greater success compared to other standard approaches we tested and overcomes limitations associated with using knowledge graphs in RAG systems. 

In this article, we’ll cover how our knowledge distillation process works, key benefits of this approach, examples, and an open discussion on the best way to evaluate these types of systems where, in many cases, there is no singular “right” answer.

Building the pyramid: How Agentic Knowledge Distillation works

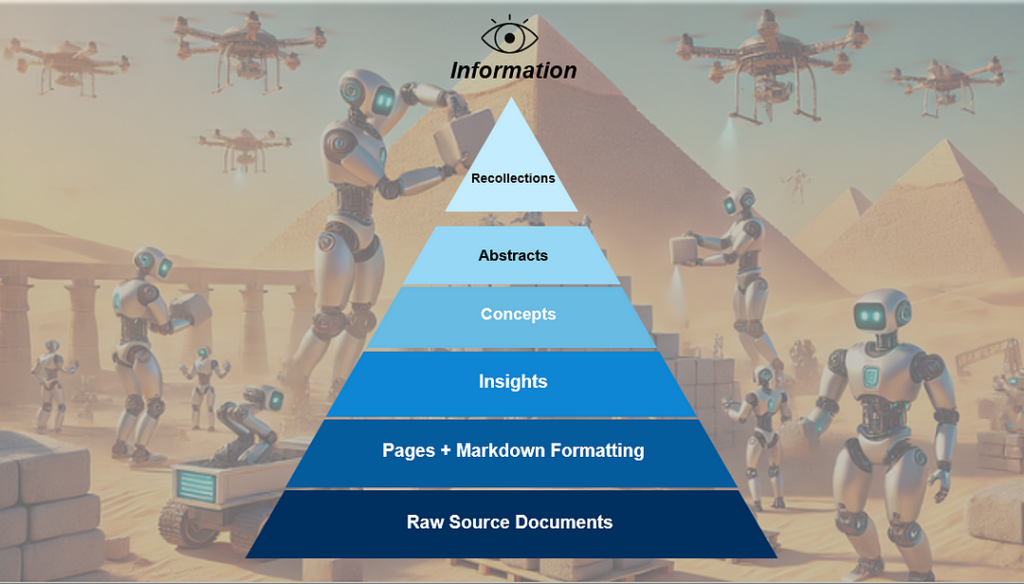
AI-generated image showing a pyramid structure for document ingestion with labelled sections.
Image by author and team depicting pyramid structure for document ingestion. Robots meant to represent agents building the pyramid.

Overview

Our knowledge distillation process creates a multi-tiered pyramid of information from the raw source documents. Our approach is inspired by the pyramids used in deep learning computer vision-based tasks, which allow a model to analyze an image at multiple scales. We take the contents of the raw document, convert it to markdown, and distill the content into a list of atomic insights, related concepts, document abstracts, and general recollections/memories. During retrieval it’s possible to access any or all levels of the pyramid to respond to the user request. 

How to distill documents and build the pyramid: 

  1. Convert documents to Markdown: Convert all raw source documents to Markdown. We’ve found models process markdown best for this task compared to other formats like JSON and it is more token efficient. We used Azure Document Intelligence to generate the markdown for each page of the document, but there are many other open-source libraries like MarkItDown which do the same thing. Our dataset included 331 documents and 16,601 pages. 
  2. Extract atomic insights from each page: We process documents using a two-page sliding window, which allows each page to be analyzed twice. This gives the agent the opportunity to correct any potential mistakes when processing the page initially. We instruct the model to create a numbered list of insights that grows as it processes the pages in the document. The agent can overwrite insights from the previous page if they were incorrect since it sees each page twice. We instruct the model to extract insights in simple sentences following the subject-verb-object (SVO) format and to write sentences as if English is the second language of the user. This significantly improves performance by encouraging clarity and precision. Rolling over each page multiple times and using the SVO format also solves the disambiguation problem, which is a huge challenge for knowledge graphs. The insight generation step is also particularly helpful for extracting information from tables since the model captures the facts from the table in clear, succinct sentences. Our dataset produced 216,931 total insights, about 13 insights per page and 655 insights per document.
  3. Distilling concepts from insights: From the detailed list of insights, we identify higher-level concepts that connect related information about the document. This step significantly reduces noise and redundant information in the document while preserving essential information and themes. Our dataset produced 14,824 total concepts, about 1 concept per page and 45 concepts per document. 
  4. Creating abstracts from concepts: Given the insights and concepts in the document, the LLM writes an abstract that appears both better than any abstract a human would write and more information-dense than any abstract present in the original document. The LLM generated abstract provides incredibly comprehensive knowledge about the document with a small token density that carries a significant amount of information. We produce one abstract per document, 331 total.
  5. Storing recollections/memories across documents: At the top of the pyramid we store critical information that is useful across all tasks. This can be information that the user shares about the task or information the agent learns about the dataset over time by researching and responding to tasks. For example, we can store the current 30 companies in the DOW as a recollection since this list is different from the 30 companies in the DOW at the time of the model’s knowledge cutoff. As we conduct more and more research tasks, we can continuously improve our recollections and maintain an audit trail of which documents these recollections originated from. For example, we can keep track of AI strategies across companies, where companies are making major investments, etc. These high-level connections are super important since they reveal relationships and information that are not apparent in a single page or document.
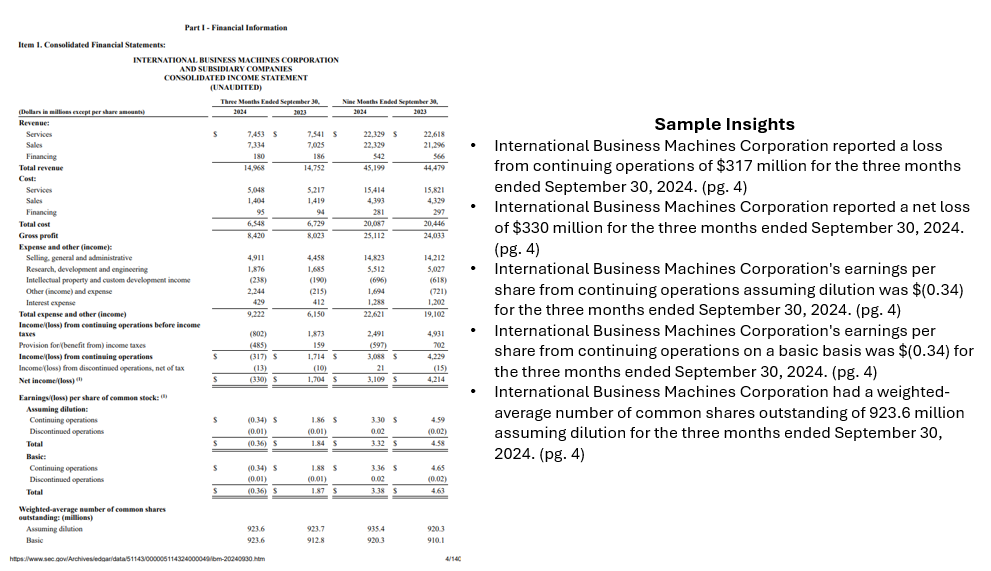
Sample subset of insights extracted from IBM 10Q, Q3 2024
Sample subset of insights extracted from IBM 10Q, Q3 2024 (page 4)

We store the text and embeddings for each layer of the pyramid (pages and up) in Azure PostgreSQL. We originally used Azure AI Search, but switched to PostgreSQL for cost reasons. This required us to write our own hybrid search function since PostgreSQL doesn’t yet natively support this feature. This implementation would work with any vector database or vector index of your choosing. The key requirement is to store and efficiently retrieve both text and vector embeddings at any level of the pyramid. 

This approach essentially creates the essence of a knowledge graph, but stores information in natural language, the way an LLM natively wants to interact with it, and is more efficient on token retrieval. We also let the LLM pick the terms used to categorize each level of the pyramid, this seemed to let the model decide for itself the best way to describe and differentiate between the information stored at each level. For example, the LLM preferred “insights” to “facts” as the label for the first level of distilled knowledge. Our goal in doing this was to better understand how an LLM thinks about the process by letting it decide how to store and group related information. 

Using the pyramid: How it works with RAG & Agents

At inference time, both traditional RAG and agentic approaches benefit from the pre-processed, distilled information ingested in our knowledge pyramid. The pyramid structure allows for efficient retrieval in both the traditional RAG case, where only the top X related pieces of information are retrieved or in the Agentic case, where the Agent iteratively plans, retrieves, and evaluates information before returning a final response. 

The benefit of the pyramid approach is that information at any and all levels of the pyramid can be used during inference. For our implementation, we used PydanticAI to create a search agent that takes in the user request, generates search terms, explores ideas related to the request, and keeps track of information relevant to the request. Once the search agent determines there’s sufficient information to address the user request, the results are re-ranked and sent back to the LLM to generate a final reply. Our implementation allows a search agent to traverse the information in the pyramid as it gathers details about a concept/search term. This is similar to walking a knowledge graph, but in a way that’s more natural for the LLM since all the information in the pyramid is stored in natural language.

Depending on the use case, the Agent could access information at all levels of the pyramid or only at specific levels (e.g. only retrieve information from the concepts). For our experiments, we did not retrieve raw page-level data since we wanted to focus on token efficiency and found the LLM-generated information for the insights, concepts, abstracts, and recollections was sufficient for completing our tasks. In theory, the Agent could also have access to the page data; this would provide additional opportunities for the agent to re-examine the original document text; however, it would also significantly increase the total tokens used. 

Here is a high-level visualization of our Agentic approach to responding to user requests:
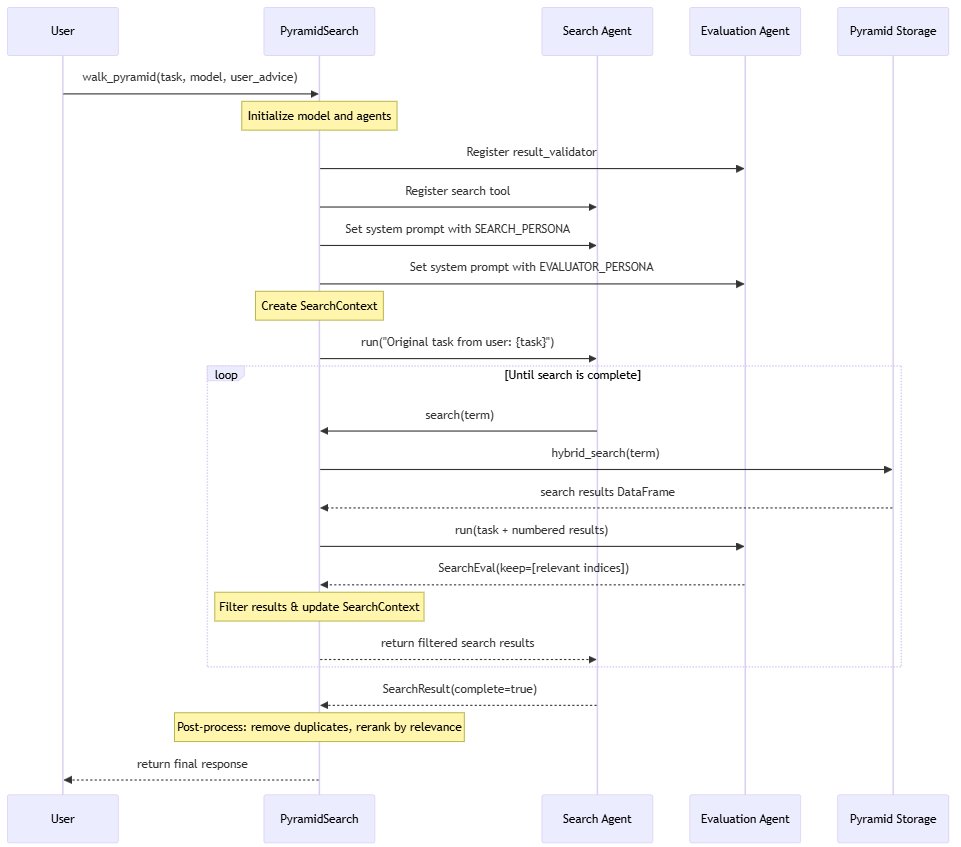
Overview of the agentic research & response process
Image created by author and team providing an overview of the agentic research & response process

Results from the pyramid: Real-world examples

To evaluate the effectiveness of our approach, we tested it against a variety of question categories, including typical fact-finding questions and complex cross-document research and analysis tasks. 

Fact-finding (spear fishing): 

These tasks require identifying specific information or facts that are buried in a document. These are the types of questions typical RAG solutions target but often require many searches and consume lots of tokens to answer correctly. 

Example task: “What was IBM’s total revenue in the latest financial reporting?”

Example response using pyramid approach: “IBM’s total revenue for the third quarter of 2024 was $14.968 billion [ibm-10q-q3-2024.pdf, pg. 4]
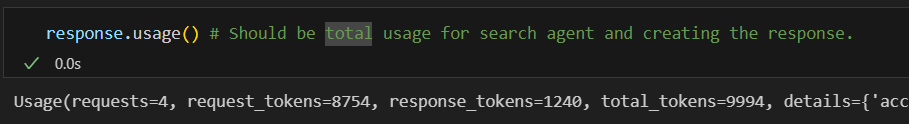
Screenshot of total tokens used to research and generate response
Total tokens used to research and generate response

This result is correct (human-validated) and was generated using only 9,994 total tokens, with 1,240 tokens in the generated final response. 

Complex research and analysis: 

These tasks involve researching and understanding multiple concepts to gain a broader understanding of the documents and make inferences and informed assumptions based on the gathered facts.

Example task: “Analyze the investments Microsoft and NVIDIA are making in AI and how they are positioning themselves in the market. The report should be clearly formatted.”

Example response:
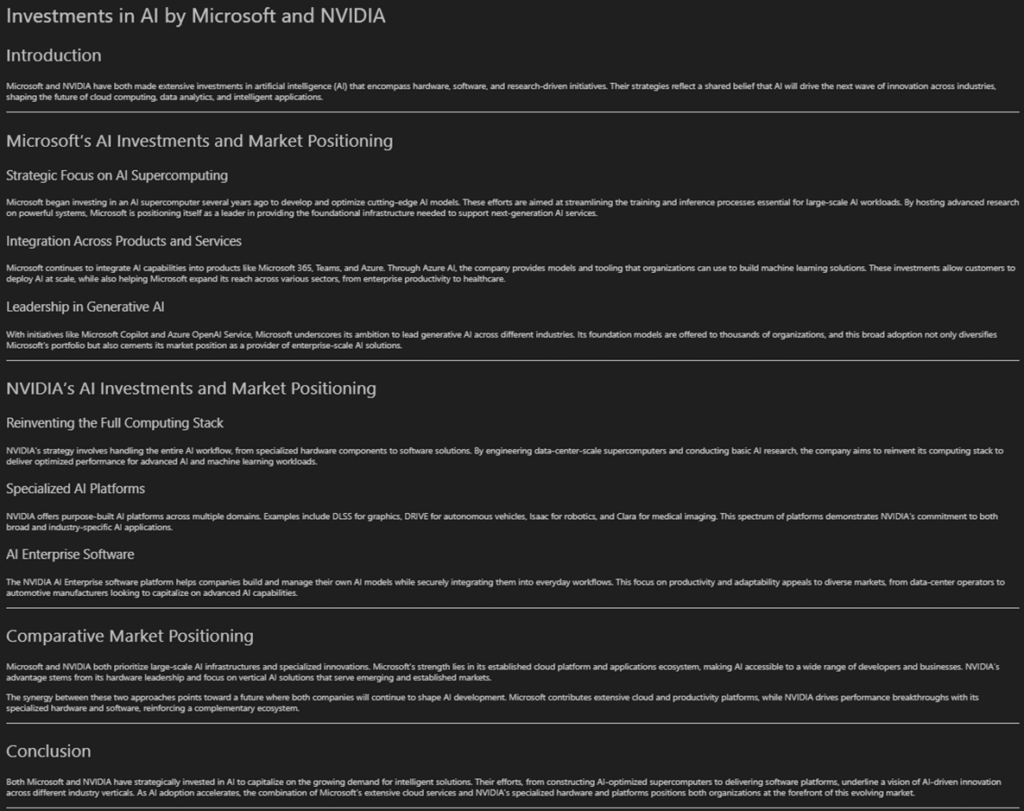
Screenshot of the response generated by the agent analyzing AI investments and positioning for Microsoft and NVIDIA.
Response generated by the agent analyzing AI investments and positioning for Microsoft and NVIDIA.

The result is a comprehensive report that executed quickly and contains detailed information about each of the companies. 26,802 total tokens were used to research and respond to the request with a significant percentage of them used for the final response (2,893 tokens or ~11%). These results were also reviewed by a human to verify their validity.
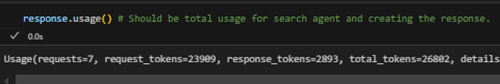
Screenshot of snippet indicating total token usage for the task
Snippet indicating total token usage for the task

Example task: “Create a report on analyzing the risks disclosed by the various financial companies in the DOW. Indicate which risks are shared and unique.”

Example response:
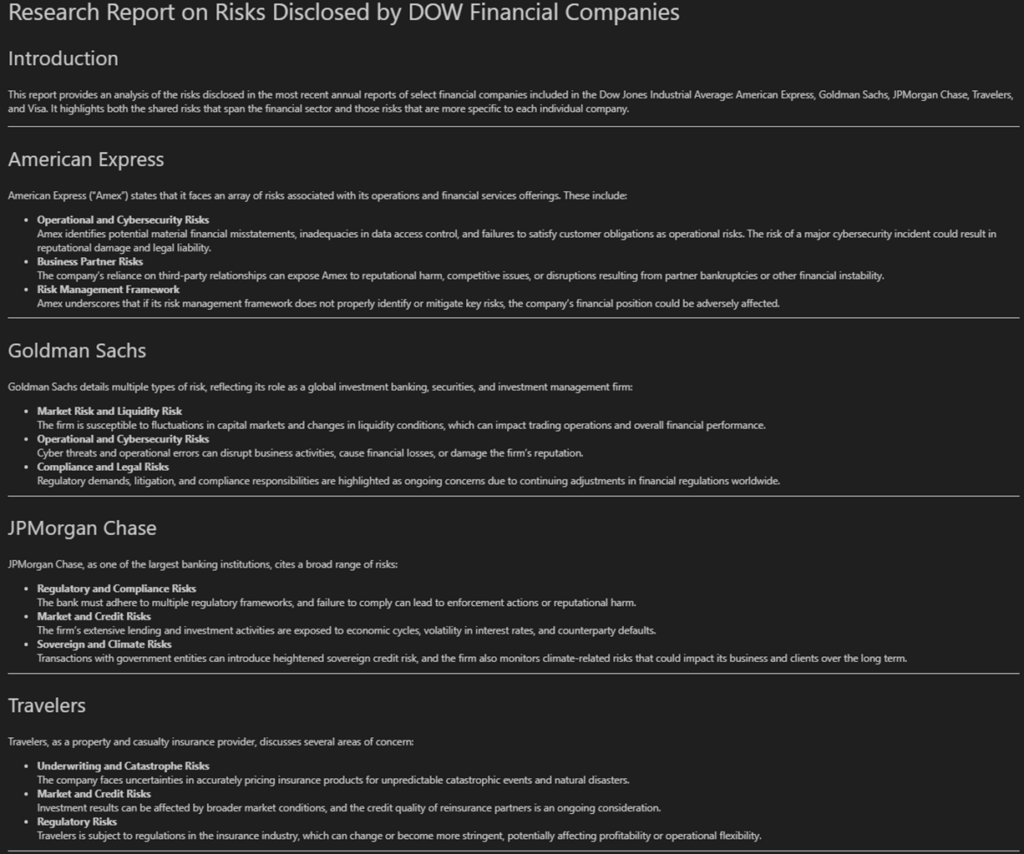
Screenshot of part 1 of a response generated by the agent on disclosed risks.
Part 1 of response generated by the agent on disclosed risks.
Screenshot of part 2 of a response generated by the agent on disclosed risks.
Part 2 of response generated by the agent on disclosed risks.

Similarly, this task was completed in 42.7 seconds and used 31,685 total tokens, with 3,116 tokens used to generate the final report. 
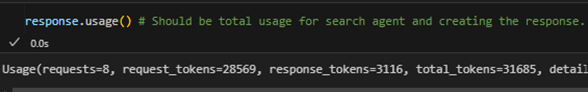
Screenshot of a snippet indicating total token usage for the task
Snippet indicating total token usage for the task

These results for both fact-finding and complex analysis tasks demonstrate that the pyramid approach efficiently creates detailed reports with low latency using a minimal amount of tokens. The tokens used for the tasks carry dense meaning with little noise allowing for high-quality, thorough responses across tasks.

Benefits of the pyramid: Why use it?

Overall, we found that our pyramid approach provided a significant boost in response quality and overall performance for high-value questions. 

Some of the key benefits we observed include: 

  • Reduced model’s cognitive load: When the agent receives the user task, it retrieves pre-processed, distilled information rather than the raw, inconsistently formatted, disparate document chunks. This fundamentally improves the retrieval process since the model doesn’t waste its cognitive capacity on trying to break down the page/chunk text for the first time. 
  • Superior table processing: By breaking down table information and storing it in concise but descriptive sentences, the pyramid approach makes it easier to retrieve relevant information at inference time through natural language queries. This was particularly important for our dataset since financial reports contain lots of critical information in tables. 
  • Improved response quality to many types of requests: The pyramid enables more comprehensive context-aware responses to both precise, fact-finding questions and broad analysis based tasks that involve many themes across numerous documents. 
  • Preservation of critical context: Since the distillation process identifies and keeps track of key facts, important information that might appear only once in the document is easier to maintain. For example, noting that all tables are represented in millions of dollars or in a particular currency. Traditional chunking methods often cause this type of information to slip through the cracks. 
  • Optimized token usage, memory, and speed: By distilling information at ingestion time, we significantly reduce the number of tokens required during inference, are able to maximize the value of information put in the context window, and improve memory use. 
  • Scalability: Many solutions struggle to perform as the size of the document dataset grows. This approach provides a much more efficient way to manage a large volume of text by only preserving critical information. This also allows for a more efficient use of the LLMs context window by only sending it useful, clear information.
  • Efficient concept exploration: The pyramid enables the agent to explore related information similar to navigating a knowledge graph, but does not require ever generating or maintaining relationships in the graph. The agent can use natural language exclusively and keep track of important facts related to the concepts it’s exploring in a highly token-efficient and fluid way. 
  • Emergent dataset understanding: An unexpected benefit of this approach emerged during our testing. When asking questions like “what can you tell me about this dataset?” or “what types of questions can I ask?”, the system is able to respond and suggest productive search topics because it has a more robust understanding of the dataset context by accessing higher levels in the pyramid like the abstracts and recollections. 

Beyond the pyramid: Evaluation challenges & future directions

Challenges

While the results we’ve observed when using the pyramid search approach have been nothing short of amazing, finding ways to establish meaningful metrics to evaluate the entire system both at ingestion time and during information retrieval is challenging. Traditional RAG and Agent evaluation frameworks often fail to address nuanced questions and analytical responses where many different responses are valid.

Our team plans to write a research paper on this approach in the future, and we are open to any thoughts and feedback from the community, especially when it comes to evaluation metrics. Many of the existing datasets we found were focused on evaluating RAG use cases within one document or precise information retrieval across multiple documents rather than robust concept and theme analysis across documents and domains. 

The main use cases we are interested in relate to broader questions that are representative of how businesses actually want to interact with GenAI systems. For example, “tell me everything I need to know about customer X” or “how do the behaviors of Customer A and B differ? Which am I more likely to have a successful meeting with?”. These types of questions require a deep understanding of information across many sources. The answers to these questions typically require a person to synthesize data from multiple areas of the business and think critically about it. As a result, the answers to these questions are rarely written or saved anywhere which makes it impossible to simply store and retrieve them through a vector index in a typical RAG process. 

Another consideration is that many real-world use cases involve dynamic datasets where documents are consistently being added, edited, and deleted. This makes it difficult to evaluate and track what a “correct” response is since the answer will evolve as the available information changes. 

Future directions

In the future, we believe that the pyramid approach can address some of these challenges by enabling more effective processing of dense documents and storing learned information as recollections. However, tracking and evaluating the validity of the recollections over time will be critical to the system’s overall success and remains a key focus area for our ongoing work. 

When applying this approach to organizational data, the pyramid process could also be used to identify and assess discrepancies across areas of the business. For example, uploading all of a company’s sales pitch decks could surface where certain products or services are being positioned inconsistently. It could also be used to compare insights extracted from various line of business data to help understand if and where teams have developed conflicting understandings of topics or different priorities. This application goes beyond pure information retrieval use cases and would allow the pyramid to serve as an organizational alignment tool that helps identify divergences in messaging, terminology, and overall communication. 

Conclusion: Key takeaways and why the pyramid approach matters

The knowledge distillation pyramid approach is significant because it leverages the full power of the LLM at both ingestion and retrieval time. Our approach allows you to store dense information in fewer tokens which has the added benefit of reducing noise in the dataset at inference. Our approach also runs very quickly and is incredibly token efficient, we are able to generate responses within seconds, explore potentially hundreds of searches, and on average use (this includes all the search iterations!). 

We find that the LLM is much better at writing atomic insights as sentences and that these insights effectively distill information from both text-based and tabular data. This distilled information written in natural language is very easy for the LLM to understand and navigate at inference since it does not have to expend unnecessary energy reasoning about and breaking down document formatting or filtering through noise. 

The ability to retrieve and aggregate information at any level of the pyramid also provides significant flexibility to address a variety of query types. This approach offers promising performance for large datasets and enables high-value use cases that require nuanced information retrieval and analysis. 


Note: The opinions expressed in this article are solely my own and do not necessarily reflect the views or policies of my employer.

Interested in discussing further or collaborating? Reach out on LinkedIn!
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Chevron preps for big 2027 exploration capex ramp

Chevron Corp., Houston, could increase its exploration capital budget by more than $500 million in 2027 as executives look to capitalize on strong commodity markets and build on an organizational shuffle that has centralized and accelerated decision-making. Speaking after Chevron reported its third-quarter results, vice-chairman Mark Nelson told analysts that

Read More »

New Cisco firewall zero-day being actively exploited

A high-severity flaw in the Remote Access SSL VPN service of Cisco Secure Firewall Adaptive Security Appliance (ASA) and Cisco Secure Firewall Threat Defense (FTD) is under active exploitation to crash vulnerable devices. The vulnerability, tracked as CVE-2026-76418 and rated 8.6 in severity, is due to logic errors when secondary

Read More »

Shell adds to Gulf of Mexico production with Silvertip Phase 3 startup

@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor

Read More »

DOE’s Office of Critical Minerals and Energy Innovation Launches PROSPECT Implementation Prize To Expand America’s Mining and Critical Minerals Workforce

WASHINGTON—The U.S. Department of Energy’s (DOE) Office of Critical Minerals and Energy Innovation today launched the PROSPECT Implementation Prize, which will award up to $70 million to support universities in expanding the skilled workforce required to domestically produce, process, recover, and recycle critical minerals. This prize competition is part of DOE’s broader up to $100 million Providing Opportunities for Specialized Education in Critical Technologies (PROSPECT) initiative, which delivers on President Trump’s bold agenda to restore American energy dominance, secure long term economic growth, rebuild domestic supply chains, and reduce reliance on foreign adversaries for critical minerals. “DOE has laid the groundwork for growing America’s critical minerals workforce—and now we’re turning those plans into reality. Universities are taking the necessary steps to deliver measurable results, from expanding student support through scholarships to modernizing curricula with new training modules, certificates, and Super Intelligence,” said Assistant Secretary of Energy Audrey Robertson. “The Trump Administration is committed to freeing America from dependence on foreign sources of critical minerals that are essential to powering our economy, and creating good-paying, fulfilling jobs for Americans.” PROSPECT has established a near-term goal of doubling the number of graduates with mining, minerals, and associated supply chain credentials within two years. The PROSPECT Implementation Prize follows the recently completed PROSPECT Planning Prize, which awarded funding to universities for developing comprehensive workforce-expansion plans. The Implementation Prize focuses on putting workforce development programs into action and demonstrating measurable results. The U.S. faces a growing shortage of skilled mining and critical minerals professionals, with an estimated 6,000 new mining engineers needed over the next decade. Expanding America’s talent pipeline is essential to strengthening domestic supply chains and reducing reliance on foreign nations for critical materials. Mining and geological engineering careers offer strong earning potential, with a median annual wage of $106,220 in 2025.

Read More »

Energy Department Announces Over $230 Million Funding Opportunity to Strengthen America’s Grid Supply Chain and Lower Electricity Costs

WASHINGTON— The U.S. Department of Energy (DOE) today announced a $237 million funding opportunity to boost American manufacturing and strengthen supply chains for critical electric grid components. The investment is expected to deliver an estimated $125 million in annual utility savings and keep an estimated $50 million per year in the U.S. economy that would otherwise go to foreign suppliers. The investments will help facilitate the reliable flow of electricity for American families and businesses and position the U.S. as a global leader in foundational technologies, by incentivizing the refurbishment and reuse of critical equipment and encouraging the adoption of alternative materials and subcomponents that are sourced and made in America. These efforts will lower costs, strengthen grid reliability, and meet growing electricity demand.  “President Trump is bringing American industry and manufacturing back home, including the critical equipment and components needed to power our nation,” said U.S. Secretary of Energy Chris Wright. “The Energy Department is investing in American-made technologies and modernizing our grid to reduce reliance on foreign suppliers and deliver affordable, reliable, electricity.” This funding opportunity will support projects in two key areas:  Up to $50 million will be provided to projects that promote greater refurbishment and reuse of existing grid equipment and materials; Up to $187 million will be provided to projects that will increase the use of alternative materials and subcomponents sourced and made in the U.S, reducing dependence on imports.  “America should never have to rely on foreign suppliers to keep the lights on,” said Office of Electricity Assistant Secretary Katie Jereza. “We’re putting American ingenuity to work, developing next-generation grid technologies that strengthen our domestic supply chain, help lower costs, and make our grid more reliable. The power to secure our energy future should be in our own hands.” The Grid Supply Chain Alternatives to

Read More »

States must take a critical eye to gas plants proposed over clean energy

Listen to the article 5 min This audio is auto-generated. Please let us know if you have feedback. Will Scott is the North Carolina policy director of the Environmental Defense Fund. Hudson Kingston is the legal director at CURE, a nonprofit rural environmental and energy democracy organization in Minnesota. The data center boom has become a cash cow for investor-owned utilities across the country. Many utility companies are seeking approval for costly new gas plants and other fossil fuel infrastructure based on uncertain projections of future demand for data centers and other large customers. If those projections fall short, ratepayers are left with 30 years of payments for projects that are increasingly expensive to build and slow to develop. We can’t let phantom projections for new data centers leave regular ratepayers with the bill. Hudson Kingston Historically, state regulators have given utilities significant latitude to pursue new generation. Yet, as heating and cooling bills become painfully unaffordable for families and local businesses, utility regulators are increasingly skeptical of proposals that could leave them paying for decades of dirty and expensive fossil fuel infrastructure, when clean, renewable energy and batteries provide a reliable, homegrown and affordable alternative. Indeed, a recent study found that batteries are now cheaper than gas peaker plants, globally. Will Scott While customers are forced to pay increasingly higher energy bills, utility shareholders are guaranteed profits on centralized fossil energy projects. The bigger and more costly the construction, the more money energy corporations make. Once new energy infrastructure is approved by state regulators, utilities can start recovering the costs through customer rates even before the project is built and in use. Because utilities make profits off the infrastructure they build, and not the energy they sell, executives have a financial incentive to keep building to benefit shareholders.  To

Read More »

TotalEnergies farms out partial interest in block offshore Nigeria ahead of appraisal

TotalEnergies agreed to farm out a 40% participating interest in Block OPL257 offshore Nigeria to South Atlantic Petroleum Ltd. (SAPETRO). Upon completion of the deal, TotalEnergies will hold a 50% operated interest in the block with SAPETRO (40%) and Conoil (10%) as partners. TotalEnergies became operator of the block following a 2025 asset interest exchange with Conoil. OPL257 lies 150 km offshore Nigeria and covers an area of about 370 sq km. The block is adjacent to PPL261 where TotalEnergies (24%) and its partners, including SAPETRO, discovered Egina South oil field in 2005, which lies in 1,650 m of water and straddles both blocks. Drilling of an Egina South appraisal well is expected in the coming months on the OPL257 side. The field is expected to be developed as a tie-back to the Egina FPSO about 30 km away. The project has the potential to deliver up to 140 million bbl of oil reserves, according to SAPETRO. Consolidating the partnership “paves the way for a quick appraisal campaign and subsequent development of Egina South in the success case,” said Mike Sangster, senior vice-president Africa exploration and production at TotalEnergies. Completion of the farm-out agreement is subject to customary conditions, including regulatory approvals.

Read More »

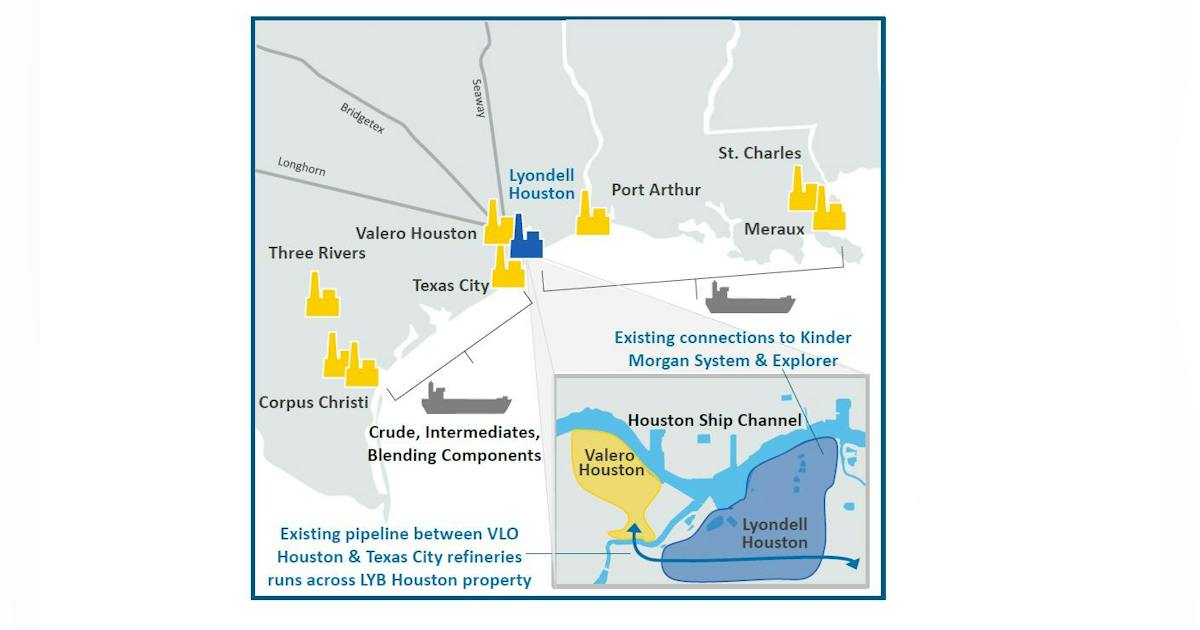
Valero to acquire former LyondellBasell Houston oil refinery, restart 165,000 b/d by end-2027

Valero Energy Corp. plans to acquire a former LyondellBasell Industries NV Houston refinery and restart 165,000 b/d of light sweet crude oil processing by yearend 2027. Valero Refining-Texas LP has agreed to acquire the shuttered full-conversion refinery from LyondellBasell for $320.5 million. The transaction includes about 700 acres on the Houston Ship Channel adjacent to the Valero Houston Refinery, 13.5 million bbl of storage capacity, and logistics infrastructure including marine docks, rail-loading facilities, and truck racks. The acquisition will help address intermediate feedstock shortages across Valero’s US Gulf Coast refining system, reducing reliance on third-party purchases while creating opportunities to integrate refining and logistics operations, the company said in an Oct. 30 presentation. Incremental FCC and hydrocracker feed production would reduce external feedstock sourcing, while excess hydrotreating capacity could be used to upgrade intermediates from other Valero US Gulf Coast refineries, the company said. By yearend 2027, Valero expects to restart light sweet crude oil processing and said the site could support future investment in heavy sour crude processing, according to chairman, chief executive officer, and president Lane Riggs. The company did not provide financial details or a timetable for potential heavy sour crude processing projects. LyondellBasell announced plans in April 2022 to cease operation of subsidiary Houston Refining LP’s 268,000-b/d refinery as part of its exit from the crude oil refining business. Following delays, the refinery was shuttered in March 2025. Over the years, LyondellBasell evaluated options for the site, including a potential plan to transition the refinery into a hydrogen production site. Ultimately, the company said, it determined selling the asset “offered the most compelling opportunity” to advance the company’s priorities. Closing of the transaction is expected by yearend, subject to customary closing conditions.

Read More »

Celebrate National Bioenergy Day: Explore the Possibilities of Biomass

How can biomass power new possibilities for energy innovation and the products we use every day?  Today is National Bioenergy Day, an annual opportunity to recognize the role biomass and innovative technologies can play in strengthening the U.S. bioeconomy. Bioenergy is a form of energy produced from alternative feedstocks called biomass. These resources, which include agricultural and forestry residues, purpose-grown crops, algae, and waste materials, can be converted into chemicals, fertilizers, alternative fuels, and other materials to support farmers, ranchers, and consumers while also lowering prices through increased supply. The United States has an abundant supply of biomass. The U.S. Department of Energy’s (DOE) Alternative Fuels and Feedstocks Office (AFFO) Billion-Ton Report establishes America’s potential to produce more than 1 billion tons of biomass annually, highlighting the scale of resources available to support a growing bioeconomy and energy security and dominance.  In celebration of National Bioenergy Day, AFFO is highlighting recent investments, research accomplishments, and resources that demonstrate the possibilities of biomass and the innovative technologies that transform these resources into valuable products. Exploring Bioenergy in Action What does that transformation look like? Explore AFFO resources that cover the basics of bioenergy and offer a closer look at how researchers are advancing technologies across the bioenergy supply chain.  Watch the Bioenergy 101 video to learn how biomass is broken down and refined through various methods, including combustion, gasification, and fermentation, to advance technology development and innovation across the entire biomass-to-bioenergy supply chain.  Take a look inside the Idaho National Laboratory’s Biomass Feedstock National User Facility, which offers technology and expertise to help the U.S. bioenergy industry overcome challenges associated with the scale-up and integration of biomass preprocessing facilities. Investing in Emerging Chemical Technologies  These efforts are part of a broader push to move promising technologies from research to commercial application. AFFO recently announced the Accelerating Scale-up

Read More »

7×24 Fall 2026: AI Frontier Futurist Meets Data Center OG

A 1988 Data Center Becomes a 20 MW AI Asset The second presentation, Converting a 1990 Enterprise Data Center to 20MW AI Workloads, featured Coe alongside Ari Chernikoff, vice president of development at Legacy Investing, and Dan Amundson, project manager at Gardner Builders. The project centered on 1001 Third Avenue South in downtown Minneapolis, a financial-services computing facility originally constructed in 1988. The building had supported earlier generations of enterprise computing before portions were converted to commercial office space and smaller colocation operations. Although its remaining operating data center load had declined to approximately 500 kilowatts by the time the AI redevelopment began, the property retained substantial infrastructure inherited from its original mission-critical design. Tall ceilings, robust floor loading, raised access floors, existing medium-voltage substations, and established utility connections made the building an unusually strong candidate for conversion. These characteristics, Chernikoff explained, can determine whether an existing building offers a practical path to high-density computing or proves economically unsuitable for redevelopment. Legacy Investing had identified a market opportunity in what Chernikoff called the industry’s “missing middle”: facilities generally ranging from 20 MW to 80 MW, rather than the 100 MW-plus campuses increasingly associated with hyperscale and frontier AI development. The company viewed existing buildings with available power and favorable infrastructure characteristics as potential shortcuts to deployment, particularly where demand for AI inference and other latency-sensitive workloads favored proximity to major urban markets. Following an AI tenant commitment in summer 2024, the development team faced an aggressive initial requirement: Deliver the first 5 MW of capacity by the end of that year. The first phase was ready for service approximately four months after Gardner’s involvement became formalized, followed by another 5 MW in 2025 and an expansion program ultimately reaching 20 MW over roughly 20 months. All of this had to

Read More »

Gartner warns $3.5T in AI infrastructure spending could be at risk by 2030

Musk predicted that more than 200 neocloud companies could face significant financial distress, predicting that only a small number would survive the coming shakeout. He also said SpaceX would not acquire any of the companies, describing such purchases as “pointless.” The chickens are already coming home to roost on the neoclouds. CoreWeave, Nebius, Applied Digital and TeraWulf have reported quarterly losses over the past year, while IREN has failed to turn a profit in its past three quarters. Shares of CoreWeave, Nebius and IREN have fallen more than 30% during October, according to Reuters. Building AI data centers requires substantial upfront investment in GPUs, networking equipment, power systems, cooling infrastructure and facilities. Operators must then generate enough revenue from leasing computing capacity to cover operating expenses, interest payments and equipment replacement.

Read More »

The 50-Gigawatt Test: SemiAnalysis Sees a Historic Data Center Surge in 2027

The global data center industry is approaching a potentially historic test of its ability to turn artificial intelligence investment into operational infrastructure. In a provocative new forecast, semiconductor and AI infrastructure research firm SemiAnalysis predicts that approximately 51.2 gigawatts of net data center IT capacity will be added globally, excluding China, during 2027. That would represent more than double the 25 GW the firm expects to be added in 2026. Published October 19, the report, Datacenters 2027: The Year of Acceleration, +50GW in a Single Year, makes a forceful argument that much of this unprecedented expansion is already visible in the industry’s construction pipeline. Authored by Jeremie Eliahou Ontiveros, Reyk Knuhtsen and Dylan Patel, the analysis draws on SemiAnalysis’ proprietary tracking of construction starts, individual buildings, hyperscale leasing commitments, equipment procurement and project financing. Its researchers identify more than 60 GW of data center capacity under construction. Among the 40 largest campuses they examined, more than 24 GW is reportedly in advanced stages of development, with much of that capacity expected to be delivered in 2027. The forecast is not entirely composed of projects already under construction, however. SemiAnalysis’ capacity chart includes approximately 11.9 GW of 2027 additions associated with projects still classified as planned. The remainder is associated with facilities already operating or under construction, according to the model’s building-status categories. SemiAnalysis argues that the volume and maturity of projects already underway make a dramatic acceleration increasingly likely, despite well-documented constraints involving electricity, construction labor, equipment and capital. But the prediction has also become the subject of a revealing industry debate, with competing forecasts and new corporate disclosures raising questions about how much infrastructure can actually be delivered on schedule. The disagreement is no longer principally about whether AI infrastructure demand is real. It is about whether the industrial

Read More »

HPE’s Quantum Computing Bet: A Multi-Vendor Path to the Data Center

QuEra Deal Targets On-Premises Quantum Integration Under the expanded collaboration, HPE and QuEra intend to develop integrated testbeds, software interoperability, hybrid algorithms and performance benchmarks to support future quantum deployments alongside HPE Cray supercomputing infrastructure. The work is intended to address the practical requirements of coordinating quantum processors with the classical computing systems that prepare workloads, process results and support quantum error correction. QuEra Chief Commercial Officer Yuval Boger, who previously discussed the development of hybrid quantum-classical infrastructure on the DCF Show, emphasized that integrating quantum hardware into an HPC environment presents different engineering challenges than providing access through the cloud. Boger said, “HPE’s deep experience in supercomputing gives organizations the benefit of working with a partner who can solve that problem at the scale they need.” The collaboration envisions deploying future fault-tolerant quantum hardware at customer facilities rather than requiring organizations to rely exclusively on cloud-based quantum computing services. That option could appeal to national laboratories, defense organizations, pharmaceutical researchers and other institutions managing classified information, proprietary intellectual property or data subject to sovereignty requirements. QuEra’s neutral-atom architecture uses individual atoms as qubits, manipulating them with lasers and electromagnetic controls. Unlike superconducting quantum processors, which generally require dilution refrigerators operating at temperatures measured in millikelvin, neutral-atom systems can operate without extreme cryogenic refrigeration. They still require specialized laser systems, vacuum equipment, precision optics and environmental controls, presenting facility requirements substantially different from those of conventional servers. On-premises quantum-HPC integration is already being tested. In Japan, the National Institute of Advanced Industrial Science and Technology (AIST) operates QuEra’s 260-physical-qubit Gemini neutral-atom computer as part of its ABCI-Q research platform, which also incorporates an NVIDIA H100-based AI supercomputer. An October 26 case study published by QuEra describes Gemini operating in a separate building approximately 350 meters from the main GPU installation,

Read More »

At 7×24 Exchange, AI Data Center Growth Confronts New Realities of Power, Grid Reliability and Community Trust

DC BLOX: Community Engagement Must Go Beyond Public Relations The afternoon program shifted attention from electrical infrastructure to the growing challenges surrounding data center development and community acceptance. In a discussion moderated by Juli Ierulli, strategic account manager at Environmental Air Systems and vice president of 7×24 Exchange International, Michael Clark, senior vice president of data center construction at DC BLOX, described how the company has revised its approach to engaging communities as it expands into new markets. Clark acknowledged that DC BLOX had encountered significant opposition after entering markets where it lacked the established relationships that had supported earlier developments across the Southeast. “We made multiple stumbles in some of those new markets,” he said, describing how the company sometimes found itself responding to negative publicity rather than presenting a clear explanation of its plans and commitments. The experience led DC BLOX to develop a more systematic approach to community engagement, emphasizing early communication, site-specific websites, accessible explanations of resource consumption and written commitments that residents and officials can evaluate. Clark also pointed to what he called the industry’s “NDA hangover,” reflecting years of development activity conducted under confidentiality agreements that frequently left neighboring communities unaware of what was being planned. But perhaps the most revealing moment came when Clark recounted a conversation with residents near a DC BLOX development in Rockdale County, Georgia. After the company outlined the countywide economic and community benefits expected from the project, one neighbor challenged the distribution of those benefits. “So the rest of the county gets the benefit and we have to pay all the costs,” the resident observed, according to Clark. The question captured a fundamental tension in the industry’s community engagement efforts: tax revenues and economic development benefits may extend across a county, while nearby residents experience the immediate effects

Read More »

NVIDIA’s DSX POD Pushes AI Factory Construction Toward the Assembly Line

Crusoe Brings an Established Modular Model to DSX POD For Crusoe, NVIDIA’s announcement builds on a modular computing strategy already in operation. In its October 21 announcement, Crusoe confirmed that its Spark modular AI data center platform will support DSX POD, extending a manufacturing and deployment approach the company says it has pursued since 2020. Crusoe has expanded its manufacturing capabilities through the acquisition of electrical equipment specialist Easter-Owens Electric and the development of its 352,000-square-foot Crusoe Spark Factory in Brighton, Colorado. The company also introduced Crusoe Spark Liquid, a sixth-generation modular system engineered for ultra-high-density infrastructure, including NVIDIA Vera Rubin NVL72. Next-generation liquid-cooled units are planned for 2027. Crusoe’s vertically integrated model connects infrastructure design and manufacturing with deployment and cloud operations through Crusoe Cloud. The company says it can deliver productive AI capacity in as little as three months, although that timeline is distinct from NVIDIA’s narrower 14-day prepared-site deployment claim. “Modular isn’t a new strategy or pivot for us. It’s been in our DNA since our founding,” said Bryan Schramm, Crusoe’s head of Spark. Crusoe’s involvement demonstrates that the manufacturing model predates DSX POD. NVIDIA is not inventing modular data center infrastructure; it is attempting to establish a common architecture around capabilities that suppliers such as Crusoe have already spent years developing. That distinction matters as the industry evaluates whether standardized AI factory designs can deliver manufacturing efficiencies at a scale beyond individual suppliers’ existing operations. Vertiv and Polar Put the Deployment Model to Work in Norway The European dimension of NVIDIA’s announcement is reflected in a deployment involving Vertiv and Polar Data Centers at Herøya, Norway. According to Vertiv’s October 21 announcement, Polar is applying a factory-built infrastructure approach to the initial 41 MW phase of a multiphase AI data center campus designed to scale to

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »