Stay Ahead, Stay ONMINE

The second wave of AI coding is here

Ask people building generative AI what generative AI is good for right now—what they’re really fired up about—and many will tell you: coding.  “That’s something that’s been very exciting for developers,” Jared Kaplan, chief scientist at Anthropic, told MIT Technology Review this month: “It’s really understanding what’s wrong with code, debugging it.” Copilot, a tool built on top of OpenAI’s large language models and launched by Microsoft-backed GitHub in 2022, is now used by millions of developers around the world. Millions more turn to general-purpose chatbots like Anthropic’s Claude, OpenAI’s ChatGPT, and Google DeepMind’s Gemini for everyday help. “Today, more than a quarter of all new code at Google is generated by AI, then reviewed and accepted by engineers,” Alphabet CEO Sundar Pichai claimed on an earnings call in October: “This helps our engineers do more and move faster.” Expect other tech companies to catch up, if they haven’t already. It’s not just the big beasts rolling out AI coding tools. A bunch of new startups have entered this buzzy market too. Newcomers such as Zencoder, Merly, Cosine, Tessl (valued at $750 million within months of being set up), and Poolside (valued at $3 billion before it even released a product) are all jostling for their slice of the pie. “It actually looks like developers are willing to pay for copilots,” says Nathan Benaich, an analyst at investment firm Air Street Capital: “And so code is one of the easiest ways to monetize AI.” Such companies promise to take generative coding assistants to the next level. Instead of providing developers with a kind of supercharged autocomplete, like most existing tools, this next generation can prototype, test, and debug code for you. The upshot is that developers could essentially turn into managers, who may spend more time reviewing and correcting code written by a model than writing it from scratch themselves.  But there’s more. Many of the people building generative coding assistants think that they could be a fast track to artificial general intelligence (AGI), the hypothetical superhuman technology that a number of top firms claim to have in their sights. “The first time we will see a massively economically valuable activity to have reached human-level capabilities will be in software development,” says Eiso Kant, CEO and cofounder of Poolside. (OpenAI has already boasted that its latest o3 model beat the company’s own chief scientist in a competitive coding challenge.) Welcome to the second wave of AI coding.  Correct code  Software engineers talk about two types of correctness. There’s the sense in which a program’s syntax (its grammar) is correct—meaning all the words, numbers, and mathematical operators are in the right place. This matters a lot more than grammatical correctness in natural language. Get one tiny thing wrong in thousands of lines of code and none of it will run. The first generation of coding assistants are now pretty good at producing code that’s correct in this sense. Trained on billions of pieces of code, they have assimilated the surface-level structures of many types of programs.   But there’s also the sense in which a program’s function is correct: Sure, it runs, but does it actually do what you wanted it to? It’s that second level of correctness that the new wave of generative coding assistants are aiming for—and this is what will really change the way software is made. “Large language models can write code that compiles, but they may not always write the program that you wanted,” says Alistair Pullen, a cofounder of Cosine. “To do that, you need to re-create the thought processes that a human coder would have gone through to get that end result.” The problem is that the data most coding assistants have been trained on—the billions of pieces of code taken from online repositories—doesn’t capture those thought processes. It represents a finished product, not what went into making it. “There’s a lot of code out there,” says Kant. “But that data doesn’t represent software development.” What Pullen, Kant, and others are finding is that to build a model that does a lot more than autocomplete—one that can come up with useful programs, test them, and fix bugs—you need to show it a lot more than just code. You need to show it how that code was put together.   In short, companies like Cosine and Poolside are building models that don’t just mimic what good code looks like—whether it works well or not—but mimic the process that produces such code in the first place. Get it right and the models will come up with far better code and far better bug fixes.  Breadcrumbs But you first need a data set that captures that process—the steps that a human developer might take when writing code. Think of these steps as a breadcrumb trail that a machine could follow to produce a similar piece of code itself. Part of that is working out what materials to draw from: Which sections of the existing codebase are needed for a given programming task? “Context is critical,” says Zencoder founder Andrew Filev. “The first generation of tools did a very poor job on the context, they would basically just look at your open tabs. But your repo [code repository] might have 5000 files and they’d miss most of it.” Zencoder has hired a bunch of search engine veterans to help it build a tool that can analyze large codebases and figure out what is and isn’t relevant. This detailed context reduces hallucinations and improves the quality of code that large language models can produce, says Filev: “We call it repo grokking.” Cosine also thinks context is key. But it draws on that context to create a new kind of data set. The company has asked dozens of coders to record what they were doing as they worked through hundreds of different programming tasks. “We asked them to write down everything,” says Pullen: “Why did you open that file? Why did you scroll halfway through? Why did you close it?” They also asked coders to annotate finished pieces of code, marking up sections that would have required knowledge of other pieces of code or specific documentation to write. Cosine then takes all that information and generates a large synthetic data set that maps the typical steps coders take, and the sources of information they draw on, to finished pieces of code. They use this data set to train a model to figure out what breadcrumb trail it might need to follow to produce a particular program, and then how to follow it.   Poolside, based in San Francisco, is also creating a synthetic data set that captures the process of coding, but it leans more on a technique called RLCE—reinforcement learning from code execution. (Cosine uses this too, but to a lesser degree.) RLCE is analogous to the technique used to make chatbots like ChatGPT slick conversationalists, known as RLHF—reinforcement learning from human feedback. With RLHF, a model is trained to produce text that’s more like the kind human testers say they favor. With RLCE, a model is trained to produce code that’s more like the kind that does what it is supposed to do when it is run (or executed).   Gaming the system Cosine and Poolside both say they are inspired by the approach DeepMind took with its game-playing model AlphaZero. AlphaZero was given the steps it could take—the moves in a game—and then left to play against itself over and over again, figuring out via trial and error what sequence of moves were winning moves and which were not.   “They let it explore moves at every possible turn, simulate as many games as you can throw compute at—that led all the way to beating Lee Sedol,” says Pengming Wang, a founding scientist at Poolside, referring to the Korean Go grandmaster that AlphaZero beat in 2016. Before Poolside, Wang worked at Google DeepMind on applications of AlphaZero beyond board games, including FunSearch, a version trained to solve advanced math problems. When that AlphaZero approach is applied to coding, the steps involved in producing a piece of code—the breadcrumbs—become the available moves in a game, and a correct program becomes winning that game. Left to play by itself, a model can improve far faster than a human could. “A human coder tries and fails one failure at a time,” says Kant. “Models can try things 100 times at once.” A key difference between Cosine and Poolside is that Cosine is using a custom version of GPT-4o provided by OpenAI, which makes it possible to train on a larger data set than the base model can cope with, but Poolside is building its own large language model from scratch. Poolside’s Kant thinks that training a model on code from the start will give better results than adapting an existing model that has sucked up not only billions of pieces of code but most of the internet. “I’m perfectly fine with our model forgetting about butterfly anatomy,” he says.   Cosine claims that its generative coding assistant, called Genie, tops the leaderboard on SWE-Bench, a standard set of tests for coding models. Poolside is still building its model but claims that what it has so far already matches the performance of GitHub’s Copilot. “I personally have a very strong belief that large language models will get us all the way to being as capable as a software developer,” says Kant. Not everyone takes that view, however. Illogical LLMs To Justin Gottschlich, the CEO and founder of Merly, large language models are the wrong tool for the job—period. He invokes his dog: “No amount of training for my dog will ever get him to be able to code, it just won’t happen,” he says. “He can do all kinds of other things, but he’s just incapable of that deep level of cognition.”   Having worked on code generation for more than a decade, Gottschlich has a similar sticking point with large language models. Programming requires the ability to work through logical puzzles with unwavering precision. No matter how well large language models may learn to mimic what human programmers do, at their core they are still essentially statistical slot machines, he says: “I can’t train an illogical system to become logical.” Instead of training a large language model to generate code by feeding it lots of examples, Merly does not show its system human-written code at all. That’s because to really build a model that can generate code, Gottschlich argues, you need to work at the level of the underlying logic that code represents, not the code itself. Merly’s system is therefore trained on an intermediate representation—something like the machine-readable notation that most programming languages get translated into before they are run. Gottschlich won’t say exactly what this looks like or how the process works. But he throws out an analogy: There’s this idea in mathematics that the only numbers that have to exist are prime numbers, because you can calculate all other numbers using just the primes. “Take that concept and apply it to code,” he says. Not only does this approach get straight to the logic of programming; it’s also fast, because millions of lines of code are reduced to a few thousand lines of intermediate language before the system analyzes them. Shifting mindsets What you think of these rival approaches may depend on what you want generative coding assistants to be.   In November, Cosine banned its engineers from using tools other than its own products. It is now seeing the impact of Genie on its own engineers, who often find themselves watching the tool as it comes up with code for them. “You now give the model the outcome you would like, and it goes ahead and worries about the implementation for you,” says Yang Li, another Cosine cofounder. Pullen admits that it can be baffling, requiring a switch of mindset. “We have engineers doing multiple tasks at once, flitting between windows,” he says. “While Genie is running code in one, they might be prompting it to do something else in another.” These tools also make it possible to protype multiple versions of a system at once. Say you’re developing software that needs a payment system built in. You can get a coding assistant to simultaneously try out several different options—Stripe, Mango, Checkout—instead of having to code them by hand one at a time. Genie can be left to fix bugs around the clock. Most software teams use bug-reporting tools that let people upload descriptions of errors they have encountered. Genie can read these descriptions and come up with fixes. Then a human just needs to review them before updating the code base. No single human understands the trillions of lines of code in today’s biggest software systems, says Li, “and as more and more software gets written by other software, the amount of code will only get bigger.” This will make coding assistants that maintain that code for us essential. “The bottleneck will become how fast humans can review the machine-generated code,” says Li. How do Cosine’s engineers feel about all this? According to Pullen, at least, just fine. “If I give you a hard problem, you’re still going to think about how you want to describe that problem to the model,” he says. “Instead of writing the code, you have to write it in natural language. But there’s still a lot of thinking that goes into that, so you’re not really taking the joy of engineering away. The itch is still scratched.” Some may adapt faster than others. Cosine likes to invite potential hires to spend a few days coding with its team. A couple of months ago it asked one such candidate to build a widget that would let employees share cool bits of software they were working on to social media.  The task wasn’t straightforward, requiring working knowledge of multiple sections of Cosine’s millions of lines of code. But the candidate got it done in a matter of hours. “This person who had never seen our code base turned up on Monday and by Tuesday afternoon he’d shipped something,” says Li. “We thought it would take him all week.” (They hired him.) But there’s another angle too. Many companies will use this technology to cut down on the number of programmers they hire. Li thinks we will soon see tiers of software engineers. At one end there will be elite developers with million-dollar salaries who can diagnose problems when the AI goes wrong. At the other end, smaller teams of 10 to 20 people will do a job that once required hundreds of coders. “It will be like how ATMs transformed banking,” says Li. “Anything you want to do will be determined by compute and not head count,” he says. “I think it’s generally accepted that the era of adding another few thousand engineers to your organization is over.” Warp drives Indeed, for Gottschlich, machines that can code better than humans are going to be essential. For him, that’s the only way we will build the vast, complex software systems that he thinks we will eventually need. Like many in Silicon Valley, he anticipates a future in which humans move to other planets. That’s only going to be possible if we get AI to build the software required, he says: “Merly’s real goal is to get us to Mars.” Gottschlich prefers to talk about “machine programming” rather than “coding assistants,” because he thinks that term frames the problem the wrong way. “I don’t think that these systems should be assisting humans—I think humans should be assisting them,” he says. “They can move at the speed of AI. Why restrict their potential?” “There’s this cartoon called The Flintstones where they have these cars, but they only move when the drivers use their feet,” says Gottschlich. “This is sort of how I feel most people are doing AI for software systems.” “But what Merly’s building is, essentially, spaceships,” he adds. He’s not joking. “And I don’t think spaceships should be powered by humans on a bicycle. Spaceships should be powered by a warp engine.” If that sounds wild—it is. But there’s a serious point to be made about what the people building this technology think the end goal really is. Gottschlich is not an outlier with his galaxy-brained take. Despite their focus on products that developers will want to use today, most of these companies have their sights on a far bigger payoff. Visit Cosine’s website and the company introduces itself as a “Human Reasoning Lab.” It sees coding as just the first step toward a more general-purpose model that can mimic human problem-solving in a number of domains. Poolside has similar goals: The company states upfront that it is building AGI. “Code is a way of formalizing reasoning,” says Kant. Wang invokes agents. Imagine a system that can spin up its own software to do any task on the fly, he says. “If you get to a point where your agent can really solve any computational task that you want through the means of software—that is a display of AGI, essentially.” Down here on Earth, such systems may remain a pipe dream. And yet software engineering is changing faster than many at the cutting edge expected.  “We’re not at a point where everything’s just done by machines, but we’re definitely stepping away from the usual role of a software engineer,” says Cosine’s Pullen. “We’re seeing the sparks of that new workflow—what it means to be a software engineer going into the future.”

Ask people building generative AI what generative AI is good for right now—what they’re really fired up about—and many will tell you: coding. 

“That’s something that’s been very exciting for developers,” Jared Kaplan, chief scientist at Anthropic, told MIT Technology Review this month: “It’s really understanding what’s wrong with code, debugging it.”

Copilot, a tool built on top of OpenAI’s large language models and launched by Microsoft-backed GitHub in 2022, is now used by millions of developers around the world. Millions more turn to general-purpose chatbots like Anthropic’s Claude, OpenAI’s ChatGPT, and Google DeepMind’s Gemini for everyday help.

“Today, more than a quarter of all new code at Google is generated by AI, then reviewed and accepted by engineers,” Alphabet CEO Sundar Pichai claimed on an earnings call in October: “This helps our engineers do more and move faster.” Expect other tech companies to catch up, if they haven’t already.

It’s not just the big beasts rolling out AI coding tools. A bunch of new startups have entered this buzzy market too. Newcomers such as Zencoder, Merly, Cosine, Tessl (valued at $750 million within months of being set up), and Poolside (valued at $3 billion before it even released a product) are all jostling for their slice of the pie. “It actually looks like developers are willing to pay for copilots,” says Nathan Benaich, an analyst at investment firm Air Street Capital: “And so code is one of the easiest ways to monetize AI.”

Such companies promise to take generative coding assistants to the next level. Instead of providing developers with a kind of supercharged autocomplete, like most existing tools, this next generation can prototype, test, and debug code for you. The upshot is that developers could essentially turn into managers, who may spend more time reviewing and correcting code written by a model than writing it from scratch themselves. 

But there’s more. Many of the people building generative coding assistants think that they could be a fast track to artificial general intelligence (AGI), the hypothetical superhuman technology that a number of top firms claim to have in their sights.

“The first time we will see a massively economically valuable activity to have reached human-level capabilities will be in software development,” says Eiso Kant, CEO and cofounder of Poolside. (OpenAI has already boasted that its latest o3 model beat the company’s own chief scientist in a competitive coding challenge.)

Welcome to the second wave of AI coding. 

Correct code 

Software engineers talk about two types of correctness. There’s the sense in which a program’s syntax (its grammar) is correct—meaning all the words, numbers, and mathematical operators are in the right place. This matters a lot more than grammatical correctness in natural language. Get one tiny thing wrong in thousands of lines of code and none of it will run.

The first generation of coding assistants are now pretty good at producing code that’s correct in this sense. Trained on billions of pieces of code, they have assimilated the surface-level structures of many types of programs.  

But there’s also the sense in which a program’s function is correct: Sure, it runs, but does it actually do what you wanted it to? It’s that second level of correctness that the new wave of generative coding assistants are aiming for—and this is what will really change the way software is made.

“Large language models can write code that compiles, but they may not always write the program that you wanted,” says Alistair Pullen, a cofounder of Cosine. “To do that, you need to re-create the thought processes that a human coder would have gone through to get that end result.”

The problem is that the data most coding assistants have been trained on—the billions of pieces of code taken from online repositories—doesn’t capture those thought processes. It represents a finished product, not what went into making it. “There’s a lot of code out there,” says Kant. “But that data doesn’t represent software development.”

What Pullen, Kant, and others are finding is that to build a model that does a lot more than autocomplete—one that can come up with useful programs, test them, and fix bugs—you need to show it a lot more than just code. You need to show it how that code was put together.  

In short, companies like Cosine and Poolside are building models that don’t just mimic what good code looks like—whether it works well or not—but mimic the process that produces such code in the first place. Get it right and the models will come up with far better code and far better bug fixes. 

Breadcrumbs

But you first need a data set that captures that process—the steps that a human developer might take when writing code. Think of these steps as a breadcrumb trail that a machine could follow to produce a similar piece of code itself.

Part of that is working out what materials to draw from: Which sections of the existing codebase are needed for a given programming task? “Context is critical,” says Zencoder founder Andrew Filev. “The first generation of tools did a very poor job on the context, they would basically just look at your open tabs. But your repo [code repository] might have 5000 files and they’d miss most of it.”

Zencoder has hired a bunch of search engine veterans to help it build a tool that can analyze large codebases and figure out what is and isn’t relevant. This detailed context reduces hallucinations and improves the quality of code that large language models can produce, says Filev: “We call it repo grokking.”

Cosine also thinks context is key. But it draws on that context to create a new kind of data set. The company has asked dozens of coders to record what they were doing as they worked through hundreds of different programming tasks. “We asked them to write down everything,” says Pullen: “Why did you open that file? Why did you scroll halfway through? Why did you close it?” They also asked coders to annotate finished pieces of code, marking up sections that would have required knowledge of other pieces of code or specific documentation to write.

Cosine then takes all that information and generates a large synthetic data set that maps the typical steps coders take, and the sources of information they draw on, to finished pieces of code. They use this data set to train a model to figure out what breadcrumb trail it might need to follow to produce a particular program, and then how to follow it.  

Poolside, based in San Francisco, is also creating a synthetic data set that captures the process of coding, but it leans more on a technique called RLCE—reinforcement learning from code execution. (Cosine uses this too, but to a lesser degree.)

RLCE is analogous to the technique used to make chatbots like ChatGPT slick conversationalists, known as RLHF—reinforcement learning from human feedback. With RLHF, a model is trained to produce text that’s more like the kind human testers say they favor. With RLCE, a model is trained to produce code that’s more like the kind that does what it is supposed to do when it is run (or executed).  

Gaming the system

Cosine and Poolside both say they are inspired by the approach DeepMind took with its game-playing model AlphaZero. AlphaZero was given the steps it could take—the moves in a game—and then left to play against itself over and over again, figuring out via trial and error what sequence of moves were winning moves and which were not.  

“They let it explore moves at every possible turn, simulate as many games as you can throw compute at—that led all the way to beating Lee Sedol,” says Pengming Wang, a founding scientist at Poolside, referring to the Korean Go grandmaster that AlphaZero beat in 2016. Before Poolside, Wang worked at Google DeepMind on applications of AlphaZero beyond board games, including FunSearch, a version trained to solve advanced math problems.

When that AlphaZero approach is applied to coding, the steps involved in producing a piece of code—the breadcrumbs—become the available moves in a game, and a correct program becomes winning that game. Left to play by itself, a model can improve far faster than a human could. “A human coder tries and fails one failure at a time,” says Kant. “Models can try things 100 times at once.”

A key difference between Cosine and Poolside is that Cosine is using a custom version of GPT-4o provided by OpenAI, which makes it possible to train on a larger data set than the base model can cope with, but Poolside is building its own large language model from scratch.

Poolside’s Kant thinks that training a model on code from the start will give better results than adapting an existing model that has sucked up not only billions of pieces of code but most of the internet. “I’m perfectly fine with our model forgetting about butterfly anatomy,” he says.  

Cosine claims that its generative coding assistant, called Genie, tops the leaderboard on SWE-Bench, a standard set of tests for coding models. Poolside is still building its model but claims that what it has so far already matches the performance of GitHub’s Copilot.

“I personally have a very strong belief that large language models will get us all the way to being as capable as a software developer,” says Kant.

Not everyone takes that view, however.

Illogical LLMs

To Justin Gottschlich, the CEO and founder of Merly, large language models are the wrong tool for the job—period. He invokes his dog: “No amount of training for my dog will ever get him to be able to code, it just won’t happen,” he says. “He can do all kinds of other things, but he’s just incapable of that deep level of cognition.”  

Having worked on code generation for more than a decade, Gottschlich has a similar sticking point with large language models. Programming requires the ability to work through logical puzzles with unwavering precision. No matter how well large language models may learn to mimic what human programmers do, at their core they are still essentially statistical slot machines, he says: “I can’t train an illogical system to become logical.”

Instead of training a large language model to generate code by feeding it lots of examples, Merly does not show its system human-written code at all. That’s because to really build a model that can generate code, Gottschlich argues, you need to work at the level of the underlying logic that code represents, not the code itself. Merly’s system is therefore trained on an intermediate representation—something like the machine-readable notation that most programming languages get translated into before they are run.

Gottschlich won’t say exactly what this looks like or how the process works. But he throws out an analogy: There’s this idea in mathematics that the only numbers that have to exist are prime numbers, because you can calculate all other numbers using just the primes. “Take that concept and apply it to code,” he says.

Not only does this approach get straight to the logic of programming; it’s also fast, because millions of lines of code are reduced to a few thousand lines of intermediate language before the system analyzes them.

Shifting mindsets

What you think of these rival approaches may depend on what you want generative coding assistants to be.  

In November, Cosine banned its engineers from using tools other than its own products. It is now seeing the impact of Genie on its own engineers, who often find themselves watching the tool as it comes up with code for them. “You now give the model the outcome you would like, and it goes ahead and worries about the implementation for you,” says Yang Li, another Cosine cofounder.

Pullen admits that it can be baffling, requiring a switch of mindset. “We have engineers doing multiple tasks at once, flitting between windows,” he says. “While Genie is running code in one, they might be prompting it to do something else in another.”

These tools also make it possible to protype multiple versions of a system at once. Say you’re developing software that needs a payment system built in. You can get a coding assistant to simultaneously try out several different options—Stripe, Mango, Checkout—instead of having to code them by hand one at a time.

Genie can be left to fix bugs around the clock. Most software teams use bug-reporting tools that let people upload descriptions of errors they have encountered. Genie can read these descriptions and come up with fixes. Then a human just needs to review them before updating the code base.

No single human understands the trillions of lines of code in today’s biggest software systems, says Li, “and as more and more software gets written by other software, the amount of code will only get bigger.”

This will make coding assistants that maintain that code for us essential. “The bottleneck will become how fast humans can review the machine-generated code,” says Li.

How do Cosine’s engineers feel about all this? According to Pullen, at least, just fine. “If I give you a hard problem, you’re still going to think about how you want to describe that problem to the model,” he says. “Instead of writing the code, you have to write it in natural language. But there’s still a lot of thinking that goes into that, so you’re not really taking the joy of engineering away. The itch is still scratched.”

Some may adapt faster than others. Cosine likes to invite potential hires to spend a few days coding with its team. A couple of months ago it asked one such candidate to build a widget that would let employees share cool bits of software they were working on to social media. 

The task wasn’t straightforward, requiring working knowledge of multiple sections of Cosine’s millions of lines of code. But the candidate got it done in a matter of hours. “This person who had never seen our code base turned up on Monday and by Tuesday afternoon he’d shipped something,” says Li. “We thought it would take him all week.” (They hired him.)

But there’s another angle too. Many companies will use this technology to cut down on the number of programmers they hire. Li thinks we will soon see tiers of software engineers. At one end there will be elite developers with million-dollar salaries who can diagnose problems when the AI goes wrong. At the other end, smaller teams of 10 to 20 people will do a job that once required hundreds of coders. “It will be like how ATMs transformed banking,” says Li.

“Anything you want to do will be determined by compute and not head count,” he says. “I think it’s generally accepted that the era of adding another few thousand engineers to your organization is over.”

Warp drives

Indeed, for Gottschlich, machines that can code better than humans are going to be essential. For him, that’s the only way we will build the vast, complex software systems that he thinks we will eventually need. Like many in Silicon Valley, he anticipates a future in which humans move to other planets. That’s only going to be possible if we get AI to build the software required, he says: “Merly’s real goal is to get us to Mars.”

Gottschlich prefers to talk about “machine programming” rather than “coding assistants,” because he thinks that term frames the problem the wrong way. “I don’t think that these systems should be assisting humans—I think humans should be assisting them,” he says. “They can move at the speed of AI. Why restrict their potential?”

“There’s this cartoon called The Flintstones where they have these cars, but they only move when the drivers use their feet,” says Gottschlich. “This is sort of how I feel most people are doing AI for software systems.”

“But what Merly’s building is, essentially, spaceships,” he adds. He’s not joking. “And I don’t think spaceships should be powered by humans on a bicycle. Spaceships should be powered by a warp engine.”

If that sounds wild—it is. But there’s a serious point to be made about what the people building this technology think the end goal really is.

Gottschlich is not an outlier with his galaxy-brained take. Despite their focus on products that developers will want to use today, most of these companies have their sights on a far bigger payoff. Visit Cosine’s website and the company introduces itself as a “Human Reasoning Lab.” It sees coding as just the first step toward a more general-purpose model that can mimic human problem-solving in a number of domains.

Poolside has similar goals: The company states upfront that it is building AGI. “Code is a way of formalizing reasoning,” says Kant.

Wang invokes agents. Imagine a system that can spin up its own software to do any task on the fly, he says. “If you get to a point where your agent can really solve any computational task that you want through the means of software—that is a display of AGI, essentially.”

Down here on Earth, such systems may remain a pipe dream. And yet software engineering is changing faster than many at the cutting edge expected. 

“We’re not at a point where everything’s just done by machines, but we’re definitely stepping away from the usual role of a software engineer,” says Cosine’s Pullen. “We’re seeing the sparks of that new workflow—what it means to be a software engineer going into the future.”

Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Nvidia will use Palantir to gain insight its supply chain

Nvidia will use Palantir’s Foundry software to analyze its global network of suppliers and partners for supply chain risks — and Palantir will incorporate Nvida’s Nemotron open AI model into its existing AI software stack. The deal will enhance both companies’ offerings, they said: Nvidia will use Palantir’s AI stack

Read More »

ZPC to expand Zhoushan complex with new PDH unit

Zhejiang Petroleum & Chemical Co. Ltd. (ZPC) has let a contract to Lummus Technology LLC to license its proprietary propane dehydrogenation (PDH) technology for a new unit to be installed at the operator’s 40-million tonne/year (tpy) integrated refining and petrochemical complex at the Zhoushan Green Petrochemical Base on Yushan Island,

Read More »

Energy Secretary Keeps Northwest Coal Generating Plant Online

WASHINGTON—U.S. Secretary of Energy Chris Wright today issued an emergency order to keep affordable, reliable, and secure coal generation in the State of Washington online to help address critical grid reliability issues facing the Northwestern region of the United States. The emergency order directs TransAlta Centralia Generation, LLC (TransAlta) to ensure that Unit 2 of the Centralia Generating Station in Centralia, Washington, a coal-fired power plant, remains available to operate. Centralia Unit 2 was scheduled to shut down at the end of 2025. “America needs more reliable power, not less, and today’s order will help ensure reliable electricity generation remains available to help address periods of peak demand,” said Secretary Wright. “The Trump Administration remains committed to reversing the misguided energy subtraction policies it inherited from past leaders. Instead, we are advancing energy addition and expanding the American people’s access to affordable, reliable, and secure electricity. Similar actions preventing the premature shutdown of reliable power generation have prevented blackouts and likely saved lives.” Thanks to President Trump’s leadership, coal generating plants across the country are being saved from premature retirement. For example, in 2025, more than 17 gigawatts of coal-power electricity generation were saved from going offline.  The availability of Centralia to operate will continue to be an asset to maintain reliability in the Western Electricity Coordinating Council (WECC) Northwest region and is necessary to address elevated reliability risks in the WECC-Northwest region during extreme weather and reduce the risk of power outages that could threaten public health and safety.  As outlined in DOE’s Resource Adequacy Report, premature retirements of reliable generation resources increase the risk of power outages. This order is in effect beginning on September 13, 2026, through December 11, 2026.

Read More »

S&P Global: Middle East crude flows to stay below prewar levels through 2027

Crude markets are settling into a prolonged period in which supply disruption is a standing condition rather than a series of discrete shocks, according to a new analysis from S&P Global Energy. For the first time since the US-Iran war began, the firm no longer expects Middle Eastern crude production to recover to prewar levels by yearend 2027. The outlook assumes no definitive end to the conflict, no normalization of traffic through the Strait of Hormuz, and no removal of Red Sea disruption risk from Iran’s Houthi allies over that period. Middle Eastern crude and condensate exports are now forecast to average roughly 10-16 million b/d on a monthly basis through 2027, compared with about 20 million b/d in January-February 2026, immediately before the war. Regional crude and condensate production is expected to average 21 million b/d over the same period, 4.2 million b/d below S&P Global’s previous projection. Production capacity has not been permanently lost, but security and logistical constraints are limiting how much oil can reach the market, S&P Global said. Gulf producers have strong incentives to find ways to move more oil to market and can be expected to adapt around political and security constraints where possible, said Jim Burkhard, vice-president and global head of crude oil research at S&P Global Energy. The market, however, “is not returning to calm,” Burkhard said. Instead, it is adjusting to conditions defined by unresolved conflict and persistent maritime risk, with oil flows remaining below prewar levels and an uneven path toward recovery. Price outlook S&P Global now expects crude oil prices broadly in an $80-100/bbl range through 2027. Dated Brent is expected to average around $90/bbl or higher for the balance of 2026 and $86/bbl in 2027, $5/bbl above the firm’s previous forecast. Brent recently traded above $100/bbl for the

Read More »

Oil extends rally on further Middle East disruptions

Oil, fundamental analysis Global crude oil prices have now been on a 10-day, +$24.50/bbl rally spurred by increasing military actions on both sides of the Iran war. Furthermore, rebel groups have entered on the side of Iran. Strategic Petroleum Reserves (SPR) inventories declined again while commercial stocks saw a minor draw. Both gasoline and distillate storages showed increases. WTI’s High was Friday’s $104.45/bbl for October while the Low was Tuesday’s $91.80 (markets were closed Monday). October Brent crude also hit its High also on Friday at $109.95/bbl with the low on Monday at $95.95. After running “too high, too fast,” the market retreated on Friday. However, both grades settled considerably higher on the week. The WTI/Brent spread has now widened to $5.35. This week’s prices were the highest in 90 days. Yemen-based Houthi rebels have entered the regional conflict by attacking Saudi Arabian oil infrastructure on the Red Sea. They managed to capture the port city of Mokha and the island of Perim. Perim sits in the middle of the Bab el-Mandab Strait and essentially divides the strait into two distinct shipping lanes. Bab el-Mandab is the gateway to the Gulf of Oman. Blocking the strait would force Saudi oil shipments to move north in the Red Sea to the Mediterranean Sea, a route that would then involve circumnavigating the African continent to get to Asian markets. Saudi oil production for August was down 1.9 million b/d to about 6.0 million b/d. The US Navy hit three Iranian oil tankers, halting their efforts to pass through the Strait of Hormuz. Meanwhile, Iran has struck two vessels near Oman. There has been some talk that certain entities are working with Iran about safe passage arrangements, which is part of the reason for Friday’s lower prices. Meanwhile, at its meeting last Sunday,

Read More »

Barclays conference: EOG prepares for steel inflation while Murphy weighs long-term portfolio options

Executives from EOG Resources Inc. and Murphy Oil Corp. spoke at the Barclays 40th Annual Energy-Power Conference in New York this week to discuss inflation pressures, service costs, capital allocation, and the strategic priorities shaping future investment decisions. OGJ also reported on comments from Chevron Corp. and ExxonMobil Corp. at this year’s conference and compiled a similar . EOG Resources Barclays analyst Betty Jiang said chatter is growing about inflationary pressures among service firms as oil prices continue to push higher (and help drive commodity production). Speaking with Jeff Leitzell, chief operating officer of EOG Resources, she asked if those cost trends are essentially devouring efficiency gains EOG is producing via various channels. “There has been some slight inflation but we really haven’t seen a huge shift,” Leitzell told the Barclays audience. “We’ve got very strategic partners […] We don’t gouge them for the lowest cost whenever it’s a downturn and they don’t gouge us for the highest cost whenever it’s an upturn.” One area to watch, Leitzell added, is steel. “We’ve leveraged our inventory where we normally keep kind of a 6- to 12-month inventory […] so we can opportunistically purchase ahead of time,” he added. “We’ve already started purchasing well into ’27 to try to insulate ourselves.” For reference, the price of US Midwest domestic hot-rolled steel has and the US Bureau of Labor Statistics says the year-over-year increase in producer prices for steel pipes and tubes has been . Murphy Oil Eric Hambly, president and chief executive officer of Murphy Oil, and his team have been favoring their offshore portfolio in recent years, including in earlier this summer. With Côte d’Ivoire, Vietnam, and the Gulf of Mexico set to be the focus of exploration work for a while, Jiang asked Hambly about the role of Canadian assets in Murphy’s

Read More »

IEA sees oil demand decline deepening as Middle East disruptions persist

The International Energy Agency (IEA) has sharply lowered its outlook for global oil demand in 2026 as continued disruptions in the Middle East and stalled US-Iran negotiations delay the recovery of oil flows. In its September Oil Market Report (OMR), IEA forecast global oil demand will decline by 2.5 million b/d in 2026, 940,000 b/d more than projected in its August report. Demand is expected to rebound by 2.6 million b/d in 2027, narrowly offsetting this year’s decline. IEA said losses in consumption will be concentrated in middle distillates and petrochemical feedstocks, particularly in Asia. Global demand is forecast at 102.45 million b/d in 2026, down 2.5 million b/d from 2025, before rising to 105.01 million b/d in 2027. The agency said oil demand will not return to its prewar February level of about 106 million b/d until late 2027. As a result, 2026-27 will represent “essentially a lost period” for oil demand growth, it said. IEA also warned that the ongoing Middle East conflict creates downside risks to its assumption of a relatively rapid demand recovery in 2027. Supply remains constrained Global oil production fell 1.6 million b/d month-over-month in August to 100.1 million b/d, with more than 10 million b/d of Gulf production remaining shut in because of heightened security risks. IEA expects global oil supply to average 100.7 million b/d in 2026, down 5.7 million b/d from 2025 and 1.3 million b/d below its previous forecast. The agency has pushed its expected recovery in Gulf production into 2027. Global supply is projected to increase by 8 million b/d next year. Gulf oil supply fell 2 million b/d in August to 21.9 million b/d, or 10.1 million b/d below prewar levels. Gulf exports declined 2.1 million b/d to 13 million b/d, including 10.4 million b/d of crude and

Read More »

EIA forecasts continued growth in US crude oil production through 2026

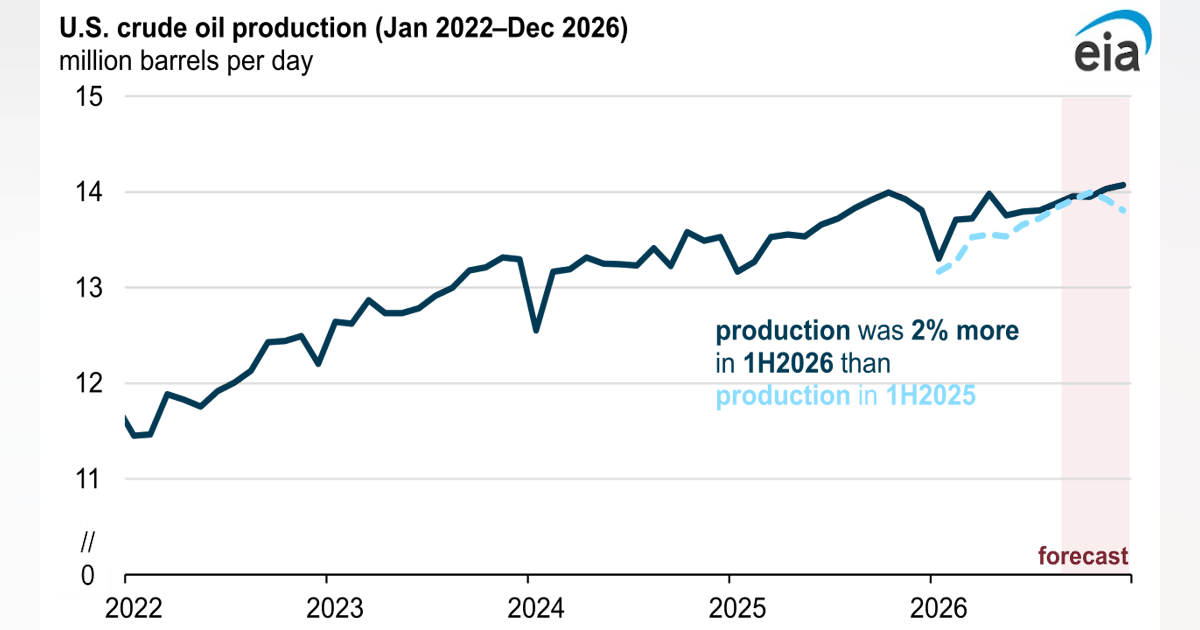
US crude oil production will average a record 13.8 million b/d in 2026, up from the previous record of 13.7 million b/d set in 2025, according to the US Energy Information Administration’s (EIA) latest Short-Term Energy Outlook. Crude production averaged 13.7 million b/d during first-half 2026, an increase of 0.3 million b/d, or 2%, from the same period a year earlier. EIA attributed most of the growth to increased output from the Permian region of Texas and New Mexico and the Federal Gulf of Mexico. Permian crude oil production is forecasted to average 6.8 million b/d in 2026, up 3% from 2025. EIA said higher crude oil prices are supporting production growth in the basin. West Texas Intermediate averaged $84/bbl through August, compared with $65/bbl in 2025. Current prices remain above reported Permian breakeven levels. According to the Dallas Fed Energy Survey in March, oil executives reported average breakeven prices of $69/bbl in the Midland basin and $63/bbl in the Delaware basin. Federal Gulf of Mexico crude production increased 10%, or 0.2 million b/d, during first-half 2026 compared with the same period a year earlier. EIA expects full-year 2026 Gulf production will increase 3%, or 0.1 million b/d. Four major projects that came online during the past year contributed to the Gulf increase. The Shenandoah floating production unit has averaged 70,000 b/d since starting production in July 2025, while the Ballymore subsea tieback has averaged 58,000 b/d since April 2025. The Whale floating production unit has averaged 38,000 b/d since January 2025, and the Salamanca floating production unit has averaged 25,000 b/d since late 2025. EIA expects four additional smaller projects to come online by yearend, providing further support for Gulf production growth.

Read More »

DCF Poll: How Should Utilities Vet Real vs. ‘Ghost’ Data Center Demand?

Matt Vincent is Editor in Chief of Data Center Frontier, where he leads editorial strategy and coverage focused on the infrastructure powering cloud computing, artificial intelligence, and the digital economy. A veteran B2B technology journalist with more than two decades of experience, Vincent specializes in the intersection of data centers, power, cooling, and emerging AI-era infrastructure. Since assuming the EIC role in 2023, he has helped guide Data Center Frontier’s coverage of the industry’s transition into the gigawatt-scale AI era, with a focus on hyperscale development, behind-the-meter power strategies, liquid cooling architectures, and the evolving energy demands of high-density compute, while working closely with the Digital Infrastructure Group at Endeavor Business Media to expand the brand’s analytical and multimedia footprint. Vincent also hosts The Data Center Frontier Show podcast, where he interviews industry leaders across hyperscale, colocation, utilities, and the data center supply chain to examine the technologies and business models reshaping digital infrastructure. Since its inception he serves as Head of Content for the Data Center Frontier Trends Summit. Before becoming Editor in Chief, he served in multiple senior editorial roles across Endeavor Business Media’s digital infrastructure portfolio, with coverage spanning data centers and hyperscale infrastructure, structured cabling and networking, telecom and datacom, IP physical security, and wireless and Pro AV markets. He began his career in 2005 within PennWell’s Advanced Technology Division and later held senior editorial positions supporting brands such as Cabling Installation & Maintenance, Lightwave Online, Broadband Technology Report, and Smart Buildings Technology. Vincent is a frequent moderator, interviewer, and keynote speaker at industry events including the HPC Forum, where he delivers forward-looking analysis on how AI and high-performance computing are reshaping digital infrastructure. He graduated with honors from Indiana University Bloomington with a B.A. in English Literature and Creative Writing and lives in southern New Hampshire with

Read More »

Nvidia invests $3.5B in MediaTek to extend its grip on AI

AI infrastructure: MediaTek will work with Nvidia’s NVLink Fusion ecosystem to enable customers to develop custom AI infrastructure designed to integrate with Nvidia rack-scale systems and AI factories. Local AI computing: The companies will continue to collaborate on multiple generations of Nvidia RTX Spark and DGX Spark PC chips, powering consumer PCs, AI developer supercomputers, and enterprise-class workstations, that integrate Nvidia GPUs with MediaTek SoCs. Automotive: MediaTek and Nvidia will continue developing platforms for AI-powered, software-defined vehicles in the era of physical AI.  “MediaTek is one of the world’s great semiconductor companies, with exceptional expertise in system-on-chip design, connectivity, leading performance and power efficiency,” said Jensen Huang, founder and CEO of Nvidia, in a statement. “Together, we’re building platforms that bring Nvidia accelerated computing to new markets and give customers the freedom to create differentiated AI systems at enormous scale.” NVLink is a high-performance interface, but this move also helps lock in customers to the Nvidia platform, since NVLink Fusion is not about to hook up to AMD processors. For MediaTek, the Nvidia investment provides a big pile of cash and access to Nvidia’s infrastructure as it attempts to establish itself as a major supplier of custom data center silicon.

Read More »

AI Puts Fiber on the Critical Path

Fiber Becomes Part of the Build A decade ago, DC Blox might have prioritized land near existing fiber from AT&T, Verizon, Zayo or another established network provider. That calculation is different today. As data center campuses have grown and hyperscalers have become a larger share of the customer base, Wabik said connectivity has increasingly become another construction package associated with the project itself. “If Zayo or Verizon or AT&T just happens to be there close by, that’s a good thing,” he said. “But fiber construction is inherently anymore just part of the construction component.” That changes the site-selection question from Is there fiber nearby? to Can fiber be built here at the scale and diversity the customer requires? For DC Blox, Wabik said that can mean assessing whether sufficient public right-of-way exists to establish three or sometimes four diverse fiber paths into a data center. That distinction is important, as AI workloads push infrastructure into markets where power, land and energy options may be more abundant than established carrier density. The hyperscalers themselves have also become major network builders. Wabik characterized them provocatively as today’s telecom providers, pointing to the scale of terrestrial fiber they commission as well as the growing role of companies such as Amazon, Google and Meta in subsea cable development. The point is less that traditional carriers have disappeared than that hyperscalers increasingly design, commission and control enormous portions of the connectivity required to support their own infrastructure. DC Blox now sees requests for 864-count fiber as routine and, in some cases, 1,728-count cable. That would have been difficult to imagine during an earlier era when a handful of fibers from an established carrier could satisfy a data center’s connectivity requirements. AI-Scale Fiber Gets Physical The scale becomes clearer when the discussion moves from abstract network

Read More »

Power First: AI Data Centers Become Energy Systems

For decades, data centers consumed electricity much like other large commercial customers: power arrived from the utility, while batteries and diesel generators stood behind it to protect the load. AI is starting to break that model. As data center campuses grow toward hundreds of megawatts and, in some cases, gigawatt scale, developers are increasingly taking responsibility for an energy system that once sat largely outside the data center boundary. Natural gas supply, onsite generation, fuel cells, batteries, controls and the behavior of the compute load itself are increasingly becoming parts of the same infrastructure system. That was the central thread running through “Power First: The New Playbook for Delivering AI Data Centers,” an Aug. 4 session at the Data Center Frontier Trends Summit 2026 in Reston, Virginia. Moderated by Fengrong Li, Senior Managing Director at FTI Consulting, the panel brought together Jim Summers, CEO of GPC Infrastructure; Shankar Achanta, EVP and Chief Product and Technology Officer at FuelCell Energy; Judith Judson, Executive Vice President at Calibrant Energy; and Yuval Bachar, Founder and CEO of EdgeCloudLink. The discussion began with the immediate constraint — the grid cannot deliver capacity on the timetable AI developers increasingly require — but quickly moved beyond the familiar concept of “bridge power.” The larger question was what happens when the data center itself becomes an energy system. From Backup Power to Prime Power Behind-the-meter generation is not new. What has changed is its role and scale. “Traditionally, behind-the-meter generation has been for backup and the sizes were smaller,” Achanta said. “But what they’re seeing is the demand for the power is growing rapidly due to the data center load.” Interconnection queues, transmission limitations and equipment supply constraints are pushing onsite generation into what Achanta called the “front seat,” supplying primary power rather than waiting behind the

Read More »

NVIDIA Pushes DSX Deeper Into Data Center Infrastructure

The joint reference design appears in Trane’s Continuum Rubin DSX and Eaton’s Beam Rubin DSX platforms. The goal is a pre-coordinated architecture stretching from grid power to the chip rather than requiring developers and engineering teams to independently assemble electrical and mechanical systems for each project. The systems are also intended to exchange operating data. Rather than cooling and electrical systems responding independently, the systems can instead exchange leading indicators and respond more dynamically to changing operating requirements. This is an approach that closely mirrors NVIDIA’s larger DSX philosophy. Trane and Eaton are also designing the architecture to accommodate future liquid-cooling and direct-current power-distribution technologies. That future-proofing matters as rack power densities continue to rise. An electrical and cooling plant optimized for one GPU generation may otherwise become a constraint several hardware generations later. The Broader DSX Buildout The Lancium, Cloverleaf and Trane/Eaton agreements are part of a considerably wider expansion of the DSX ecosystem. Earlier deals show NVIDIA moving into many of the same infrastructure layers through partnerships spanning powered land, electrical design, digital twins and even project financing. In May, NVIDIA and IREN announced plans to support as much as 5 GW of DSX-aligned AI infrastructure across IREN’s global development pipeline, with the companies identifying IREN’s 2 GW Sweetwater campus in Texas as an expected flagship DSX deployment. NVIDIA also received a five-year right to purchase up to 30 million IREN shares at $70 each, representing a potential investment of as much as $2.1 billion. The infrastructure ecosystem has widened as well. Siemens, NVIDIA and Fluence, incorporating nVent design considerations, have developed a DSX Vera Rubin-aligned electrical, power and controls architecture extending from the utility connection to the rack. ABB is integrating digital models of medium-voltage switchgear, power-distribution equipment and UPS systems into the Omniverse DSX Blueprint, while Vertiv

Read More »

ERCOT Puts Texas AI Megawatts to the Test

Texas has no shortage of proposed data center megawatts. The harder question is how many of them are real. That distinction is becoming central to the Electric Reliability Council of Texas (ERCOT) as the state works through an unprecedented wave of AI, hyperscale and other large-load requests. In June, ERCOT said it was tracking more than 438 GW of proposed large loads, nearly 89% associated with data centers. By Aug. 3, Gov. Greg Abbott said ERCOT was considering approximately 474 GW of connection requests, roughly 90% from data centers and more than five times the system’s record peak demand. Neither figure represents a forecast of what will actually get built. And that is increasingly the point. ERCOT’s new Batch Zero process is beginning to put harder boundaries around Texas’ enormous development pipeline, asking which projects have enough maturity, technical information and commitment to warrant space in the transmission plan. At the same time, new requirements surrounding voltage ride-through and dynamic modeling are forcing another realization on the AI infrastructure industry: at hundreds of megawatts, a data center is no longer simply a customer at the edge of the grid. Its behavior can affect the grid itself. For developers, utilities and investors, Texas is becoming a large-scale test of what separates an announced AI campus from executable infrastructure. The Queue Is Not the Grid The sheer scale of ERCOT’s large-load queue can obscure how early many projects remain. ERCOT’s April 2026 monthly report offered a revealing snapshot. Large-load applications totaled 445.8 GW through 2033, but 321 GW had no studies submitted to ERCOT. Another 93.7 GW was under ERCOT review, while 22 GW had met the applicable Section 9.5 requirements. Against that enormous development funnel, ERCOT reported just 5.9 GW of observed energized large loads, with another 3.2 GW approved to

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »