Stay Ahead, Stay ONMINE

This Is How LLMs Break Down the Language

Do you remember the hype when OpenAI released GPT-3 in 2020? Though not the first in its series, GPT-3 gained widespread popularity due to its impressive text generation capabilities. Since then, a diverse group of Large Language Models(Llms) have flooded the AI landscape. The golden question is: Have you ever wondered how ChatGPT or any other LLMs break down the language? If you haven’t yet, we are going to discuss the mechanism by which LLMs process the textual input given to them during training and inference. In principle, we call it tokenization. This article is inspired by the YouTube video titled Deep Dive into LLMs like ChatGPT from former Senior Director of AI at Tesla, Andrej Karpathy. His general audience video series is highly recommended for those who want to take a deep dive into the intricacies behind LLMs. Before diving into the main topic, I need you to have an understanding of the inner workings of a LLM. In the next section, I’ll break down the internals of a language model and its underlying architecture. If you’re already familiar with neural networks and LLMs in general, you can skip the next section without affecting your reading experience. Internals of large language models LLMs are made up of transformer neural networks. Consider neural networks as giant mathematical expressions. Inputs to neural networks are a sequence of tokens that are typically processed through embedding layers, which convert the tokens into numerical representations. For now, think of tokens as basic units of input data, such as words, phrases, or characters. In the next section, we’ll explore how to create tokens from input text data in depth. When we feed these inputs to the network, they are mixed into a giant mathematical expression along with the parameters or weights of these neural networks. Modern neural networks have billions of parameters. At the beginning, these parameters or weights are set randomly. Therefore, the neural network randomly guesses its predictions. During the training process, we iteratively update these weights so that the outputs of our neural network become consistent with the patterns observed in our training set. In a sense, neural network training is about finding the right set of weights that seem to be consistent with the statistics of the training set. The transformer architecture was introduced in the paper titled “Attention is All You Need” by Vaswani et al. in 2017. This is a neural network with a special kind of structure designed for sequence processing. Initially intended for Neural Machine Translation, it has since become the founding building block for LLMs. To get a sense of what production grade transformer neural networks look like visit https://bbycroft.net/llm. This site provides interactive 3D visualizations of generative pre-trained transformer (GPT) architectures and guides you through their inference process. Visualization of Nano-GPT at https://bbycroft.net/llm (Image by the author) This particular architecture, called Nano-GPT, has around 85,584 parameters. We feed the inputs, which are token sequences, at the top of the network. Information then flows through the layers of the network, where the input undergoes a series of transformations, including attention mechanisms and feed-forward networks, to produce an output. The output is the model’s prediction for the next token in the sequence. Tokenization Training a state-of-the-art language model like ChatGPT or Claude involves several stages arranged sequentially. In my previous article about hallucinations, I briefly explained the training pipeline for an LLM. If you want to learn more about training stages and hallucinations, you can read it here. Now, imagine we’re at the initial stage of training called pretraining. This stage requires a large, high-quality, web-scale dataset of terabyte size. The datasets used by major LLM providers are not publicly available. Therefore, we will look into an open-source dataset curated by Hugging Face, called FineWeb distributed under the Open Data Commons Attribution License. You can read more about how they collected and created this dataset here. FineWeb dataset curated by Hugging Face (Image by the author) I downloaded a sample from the FineWeb dataset, selected the first 100 examples, and concatenated them into a single text file. This is just raw internet text with various patterns within it. Sampled text from the FineWeb dataset (Image by the author) So our goal is to feed this data to the transformer neural network so that the model learns the flow of this text. We need to train our neural network to mimic the text. Before plugging this text into the neural network, we must decide how to represent it. Neural networks expect a one-dimensional sequence of symbols. That requires a finite set of possible symbols. Therefore, we must determine what these symbols are and how to represent our data as a one-dimensional sequence of them. What we have at this point is a one-dimensional sequence of text. There is an underlined representation of a sequence of raw bits for this text. We can encode the original sequence of text with UTF-8 encoding to get the sequence of raw bits. If you check the image below, you can see that the first 8 bits of the raw bit sequence correspond to the first letter ‘A’ of the original one-dimensional text sequence. Sampled text, represented as a one-dimensional sequence of bits (Image by the author) Now, we have a very long sequence with two symbols: zero and one. This is, in fact, what we were looking for — a one-dimensional sequence of symbols with a finite set of possible symbols. Now the problem is that sequence length is a precious resource in a neural network primarily because of computational efficiency, memory constraints, and the difficulty of processing long dependencies. Therefore, we don’t want extremely long sequences of just two symbols. We prefer shorter sequences of more symbols. So, we are going to trade off the number of symbols in our vocabulary against the resulting sequence length. As we need to further compress or shorten our sequence, we can group every 8 consecutive bits into a single byte. Since each bit is either 0 or 1, there are exactly 256 possible combinations of 8-bit sequences. Thus, we can represent this sequence as a sequence of bytes instead. Grouping bits to bytes (Image by the author) This representation reduces the length by a factor of 8, while expanding the symbol set to 256 possibilities. Consequently, each value in the sequence will fall within the range of 0 to 255. Sampled text, represented as a one-dimensional sequence of bytes (Image by the author) These numbers do not have any value in a numerical sense. They are just placeholders for unique identifiers or symbols. In fact, we could replace each of these numbers with a unique emoji and the core idea would still stand. Think of this as a sequence of emojis, each chosen from 256 unique options. Sampled text, represented as a one-dimensional sequence of emojis (Image by the author) This process of converting from raw text into symbols is called Tokenization. Tokenization in state-of-the-art language models goes even beyond this. We can further compress the length of the sequence in return for more symbols in our vocabulary using the Byte-Pair Encoding (BPE) algorithm. Initially developed for text compression, BPE is now widely used by transformer models for tokenization. OpenAI’s GPT series uses standard and customized versions of the BPE algorithm. Essentially, byte pair encoding involves identifying frequent consecutive bytes or symbols. For example, we can look into our byte level sequence of text. Sequence 101, followed by 114, is quite frequent (Image by the author) As you can see, the sequence 101 followed by 114 appears frequently. Therefore, we can replace this pair with a new symbol and assign it a unique identifier. We are going to rewrite every occurrence of 101 114 using this new symbol. This process can be repeated multiple times, with each iteration further shortening the sequence length while introducing additional symbols, thereby increasing the vocabulary size. Using this process, GPT-4 has come up with a token vocabulary of around 100,000. We can further explore tokenization using Tiktokenizer. Tiktokenizer provides an interactive web-based graphical user interface where you can input text and see how it’s tokenized according to different models. Play with this tool to get an intuitive understanding of what these tokens look like. For example, we can take the first four sentences of the text sequence and input them into the Tiktokenizer. From the dropdown menu, select the GPT-4 base model encoder: cl100k_base. Tiktokenizer (Image by the author) The colored text shows how the chunks of text correspond to the symbols. The following text, which is a sequence of length 51, is what GPT-4 will see at the end of the day. 11787, 499, 21815, 369, 90250, 763, 14689, 30, 7694, 1555, 279, 21542, 3770, 323, 499, 1253, 1120, 1518, 701, 4832, 2457, 13, 9359, 1124, 323, 6642, 264, 3449, 709, 3010, 18396, 13, 1226, 617, 9214, 315, 1023, 3697, 430, 1120, 649, 10379, 83, 3868, 311, 3449, 18570, 1120, 1093, 499, 0 We can now take our entire sample dataset and re-represent it as a sequence of tokens using the GPT-4 base model tokenizer, cl100k_base. Note that the original FineWeb dataset consists of a 15-trillion-token sequence, while our sample dataset contains only a few thousand tokens from the original dataset. Sampled text, represented as a one-dimensional sequence of tokens (Image by the author) Conclusion Tokenization is a fundamental step in how LLMs process text, transforming raw text data into a structured format before being fed into neural networks. As neural networks require a one-dimensional sequence of symbols, we need to achieve a balance between sequence length and the number of symbols in the vocabulary, optimizing for efficient computation. Modern state-of-the-art transformer-based LLMs, including GPT and GPT-2, use Byte-Pair Encoding tokenization. Breaking down tokenization helps demystify how LLMs interpret text inputs and generate coherent responses. Having an intuitive sense of what tokenization looks like helps in understanding the internal mechanisms behind the training and inference of LLMs. As LLMs are increasingly used as a knowledge base, a well-designed tokenization strategy is crucial for improving model efficiency and overall performance. If you enjoyed this article, connect with me on X (formerly Twitter) for more insights. References

Do you remember the hype when OpenAI released GPT-3 in 2020? Though not the first in its series, GPT-3 gained widespread popularity due to its impressive text generation capabilities. Since then, a diverse group of Large Language Models(Llms) have flooded the AI landscape. The golden question is: Have you ever wondered how ChatGPT or any other LLMs break down the language? If you haven’t yet, we are going to discuss the mechanism by which LLMs process the textual input given to them during training and inference. In principle, we call it tokenization.

This article is inspired by the YouTube video titled Deep Dive into LLMs like ChatGPT from former Senior Director of AI at Tesla, Andrej Karpathy. His general audience video series is highly recommended for those who want to take a deep dive into the intricacies behind LLMs.

Before diving into the main topic, I need you to have an understanding of the inner workings of a LLM. In the next section, I’ll break down the internals of a language model and its underlying architecture. If you’re already familiar with neural networks and LLMs in general, you can skip the next section without affecting your reading experience.

Internals of large language models

LLMs are made up of transformer neural networks. Consider neural networks as giant mathematical expressions. Inputs to neural networks are a sequence of tokens that are typically processed through embedding layers, which convert the tokens into numerical representations. For now, think of tokens as basic units of input data, such as words, phrases, or characters. In the next section, we’ll explore how to create tokens from input text data in depth. When we feed these inputs to the network, they are mixed into a giant mathematical expression along with the parameters or weights of these neural networks.

Modern neural networks have billions of parameters. At the beginning, these parameters or weights are set randomly. Therefore, the neural network randomly guesses its predictions. During the training process, we iteratively update these weights so that the outputs of our neural network become consistent with the patterns observed in our training set. In a sense, neural network training is about finding the right set of weights that seem to be consistent with the statistics of the training set.

The transformer architecture was introduced in the paper titled “Attention is All You Need” by Vaswani et al. in 2017. This is a neural network with a special kind of structure designed for sequence processing. Initially intended for Neural Machine Translation, it has since become the founding building block for LLMs.

To get a sense of what production grade transformer neural networks look like visit https://bbycroft.net/llm. This site provides interactive 3D visualizations of generative pre-trained transformer (GPT) architectures and guides you through their inference process.
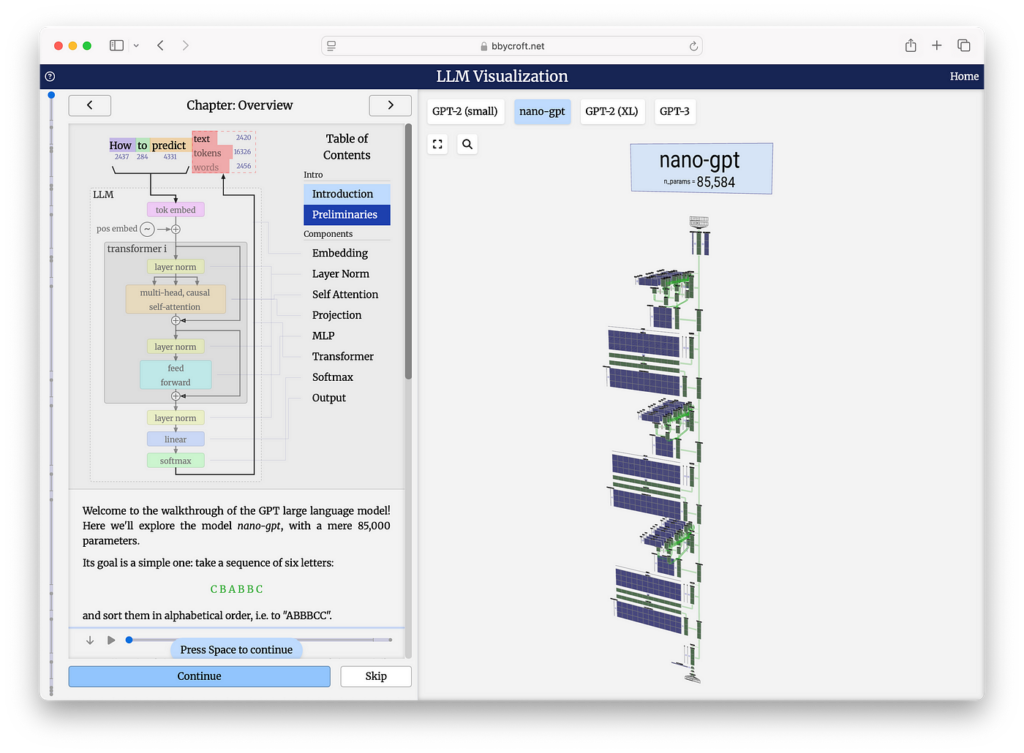
Visualization of Nano-GPT at https://bbycroft.net/llm (Image by the author)

This particular architecture, called Nano-GPT, has around 85,584 parameters. We feed the inputs, which are token sequences, at the top of the network. Information then flows through the layers of the network, where the input undergoes a series of transformations, including attention mechanisms and feed-forward networks, to produce an output. The output is the model’s prediction for the next token in the sequence.

Tokenization

Training a state-of-the-art language model like ChatGPT or Claude involves several stages arranged sequentially. In my previous article about hallucinations, I briefly explained the training pipeline for an LLM. If you want to learn more about training stages and hallucinations, you can read it here.

Now, imagine we’re at the initial stage of training called pretraining. This stage requires a large, high-quality, web-scale dataset of terabyte size. The datasets used by major LLM providers are not publicly available. Therefore, we will look into an open-source dataset curated by Hugging Face, called FineWeb distributed under the Open Data Commons Attribution License. You can read more about how they collected and created this dataset here.
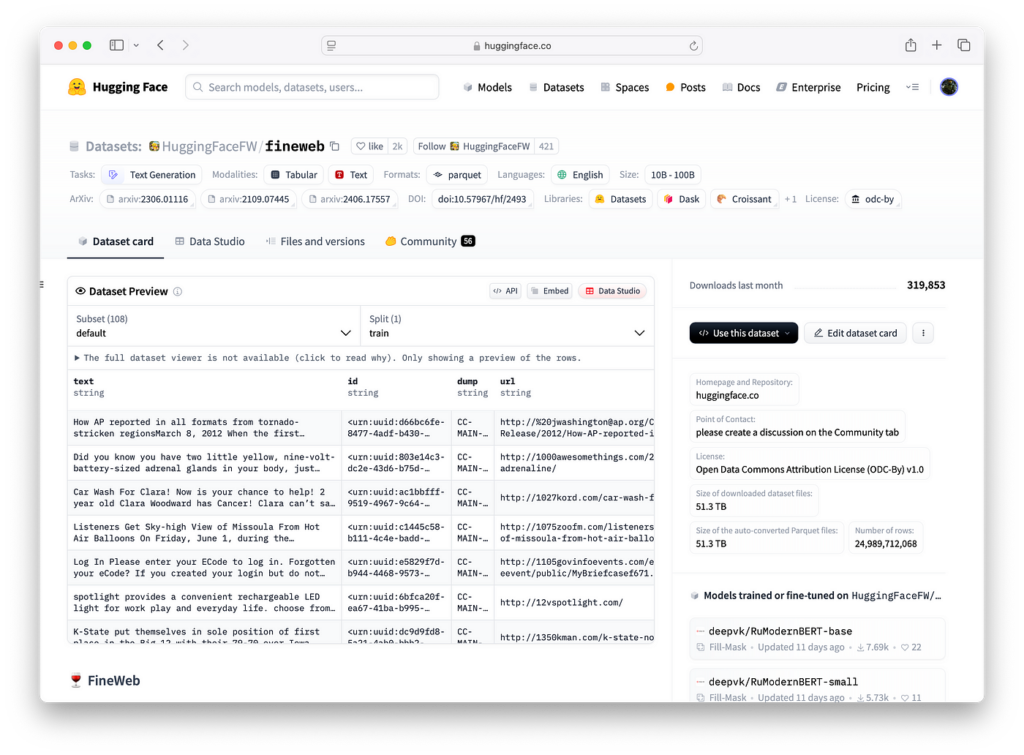
FineWeb dataset curated by Hugging Face (Image by the author)

I downloaded a sample from the FineWeb dataset, selected the first 100 examples, and concatenated them into a single text file. This is just raw internet text with various patterns within it.
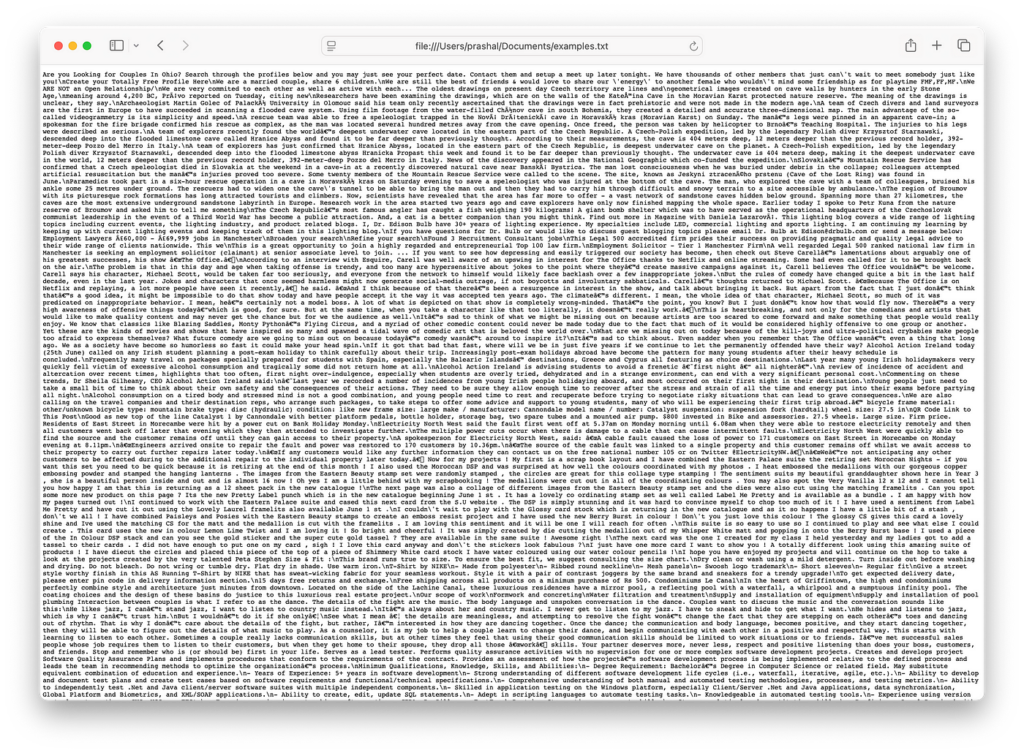
Sampled text from the FineWeb dataset (Image by the author)

So our goal is to feed this data to the transformer neural network so that the model learns the flow of this text. We need to train our neural network to mimic the text. Before plugging this text into the neural network, we must decide how to represent it. Neural networks expect a one-dimensional sequence of symbols. That requires a finite set of possible symbols. Therefore, we must determine what these symbols are and how to represent our data as a one-dimensional sequence of them.

What we have at this point is a one-dimensional sequence of text. There is an underlined representation of a sequence of raw bits for this text. We can encode the original sequence of text with UTF-8 encoding to get the sequence of raw bits. If you check the image below, you can see that the first 8 bits of the raw bit sequence correspond to the first letter ‘A’ of the original one-dimensional text sequence.
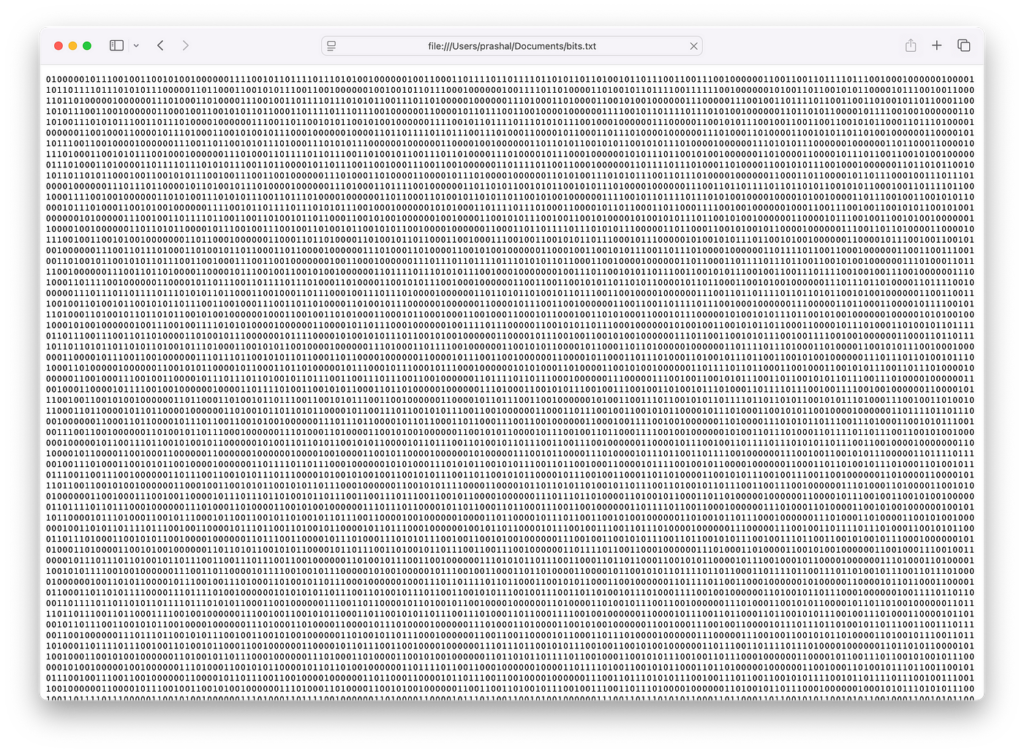
Sampled text, represented as a one-dimensional sequence of bits (Image by the author)

Now, we have a very long sequence with two symbols: zero and one. This is, in fact, what we were looking for — a one-dimensional sequence of symbols with a finite set of possible symbols. Now the problem is that sequence length is a precious resource in a neural network primarily because of computational efficiency, memory constraints, and the difficulty of processing long dependencies. Therefore, we don’t want extremely long sequences of just two symbols. We prefer shorter sequences of more symbols. So, we are going to trade off the number of symbols in our vocabulary against the resulting sequence length.

As we need to further compress or shorten our sequence, we can group every 8 consecutive bits into a single byte. Since each bit is either 0 or 1, there are exactly 256 possible combinations of 8-bit sequences. Thus, we can represent this sequence as a sequence of bytes instead.
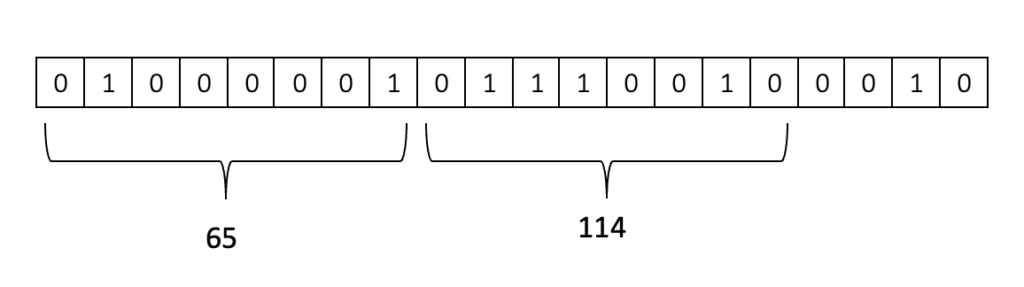
Grouping bits to bytes (Image by the author)

This representation reduces the length by a factor of 8, while expanding the symbol set to 256 possibilities. Consequently, each value in the sequence will fall within the range of 0 to 255.

Sampled text, represented as a one-dimensional sequence of bytes (Image by the author)

These numbers do not have any value in a numerical sense. They are just placeholders for unique identifiers or symbols. In fact, we could replace each of these numbers with a unique emoji and the core idea would still stand. Think of this as a sequence of emojis, each chosen from 256 unique options.
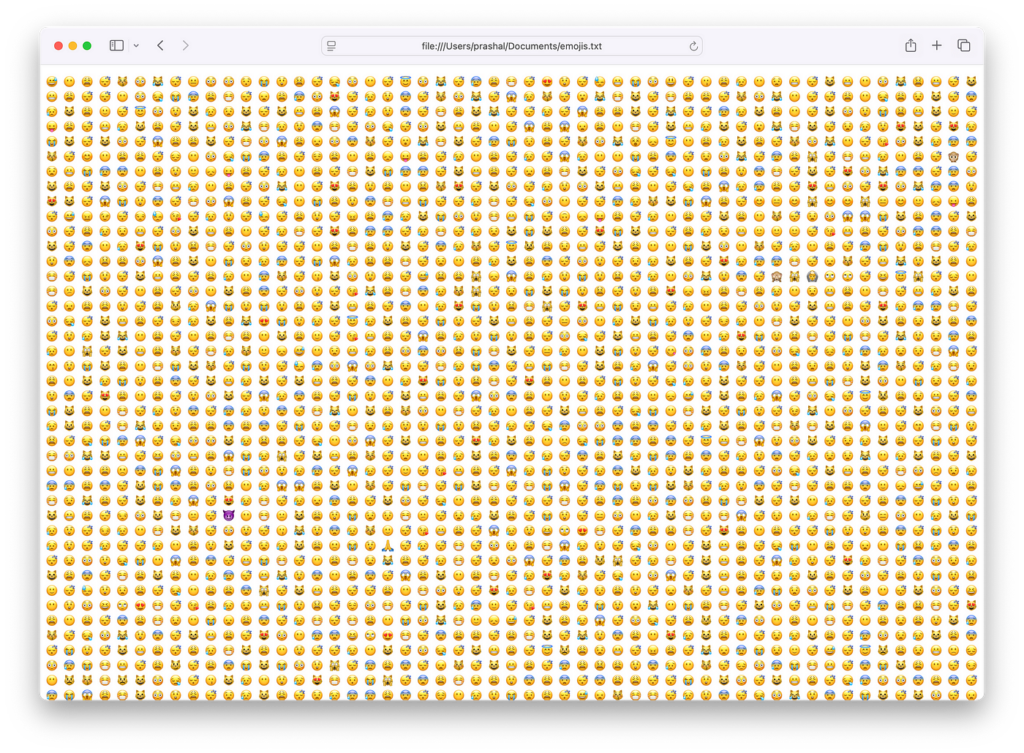
Sampled text, represented as a one-dimensional sequence of emojis (Image by the author)

This process of converting from raw text into symbols is called Tokenization. Tokenization in state-of-the-art language models goes even beyond this. We can further compress the length of the sequence in return for more symbols in our vocabulary using the Byte-Pair Encoding (BPE) algorithm. Initially developed for text compression, BPE is now widely used by transformer models for tokenization. OpenAI’s GPT series uses standard and customized versions of the BPE algorithm.

Essentially, byte pair encoding involves identifying frequent consecutive bytes or symbols. For example, we can look into our byte level sequence of text.

Sequence 101, followed by 114, is quite frequent (Image by the author)

As you can see, the sequence 101 followed by 114 appears frequently. Therefore, we can replace this pair with a new symbol and assign it a unique identifier. We are going to rewrite every occurrence of 101 114 using this new symbol. This process can be repeated multiple times, with each iteration further shortening the sequence length while introducing additional symbols, thereby increasing the vocabulary size. Using this process, GPT-4 has come up with a token vocabulary of around 100,000.

We can further explore tokenization using Tiktokenizer. Tiktokenizer provides an interactive web-based graphical user interface where you can input text and see how it’s tokenized according to different models. Play with this tool to get an intuitive understanding of what these tokens look like.

For example, we can take the first four sentences of the text sequence and input them into the Tiktokenizer. From the dropdown menu, select the GPT-4 base model encoder: cl100k_base.
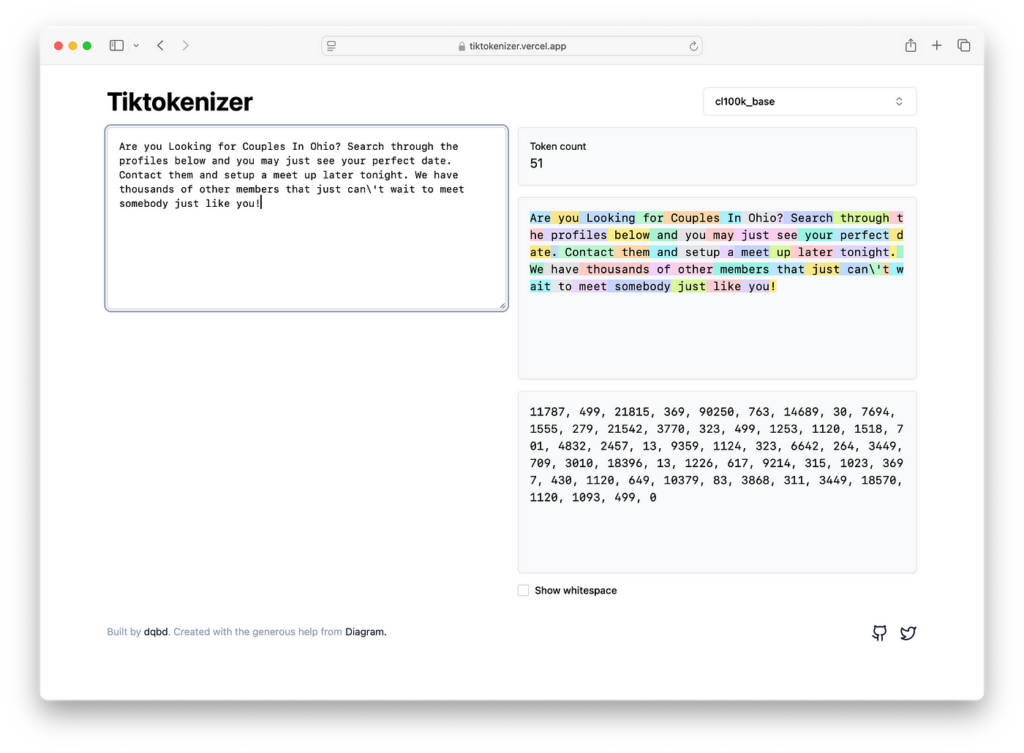
Tiktokenizer (Image by the author)

The colored text shows how the chunks of text correspond to the symbols. The following text, which is a sequence of length 51, is what GPT-4 will see at the end of the day.

11787, 499, 21815, 369, 90250, 763, 14689, 30, 7694, 1555, 279, 21542, 3770, 323, 499, 1253, 1120, 1518, 701, 4832, 2457, 13, 9359, 1124, 323, 6642, 264, 3449, 709, 3010, 18396, 13, 1226, 617, 9214, 315, 1023, 3697, 430, 1120, 649, 10379, 83, 3868, 311, 3449, 18570, 1120, 1093, 499, 0

We can now take our entire sample dataset and re-represent it as a sequence of tokens using the GPT-4 base model tokenizer, cl100k_base. Note that the original FineWeb dataset consists of a 15-trillion-token sequence, while our sample dataset contains only a few thousand tokens from the original dataset.
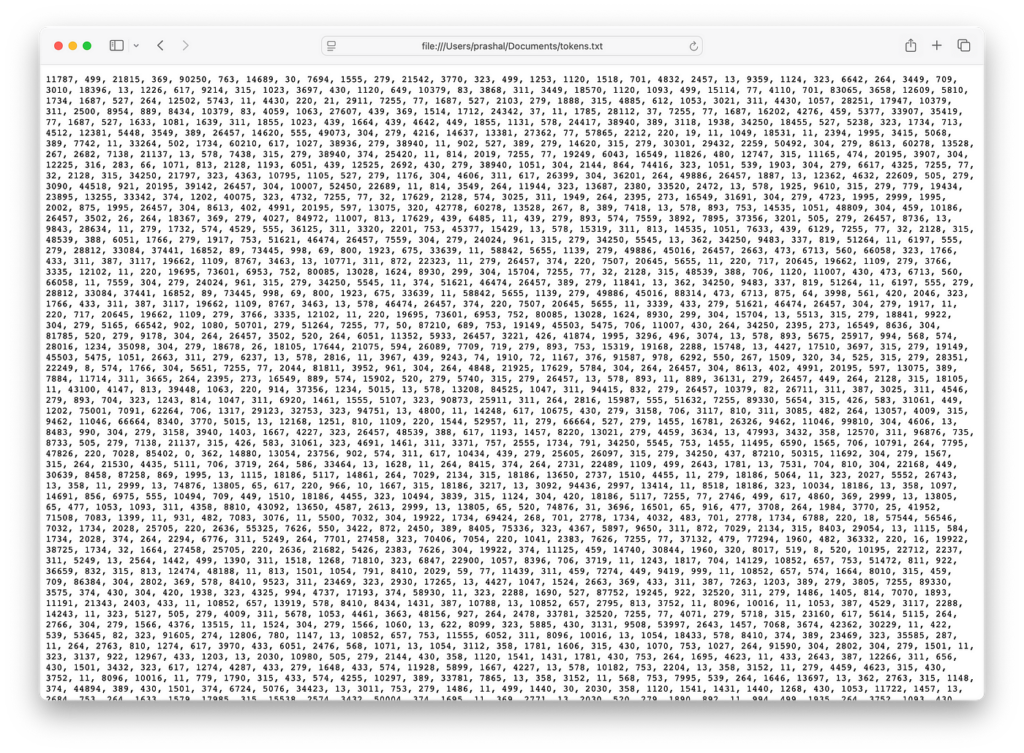
Sampled text, represented as a one-dimensional sequence of tokens (Image by the author)

Conclusion

Tokenization is a fundamental step in how LLMs process text, transforming raw text data into a structured format before being fed into neural networks. As neural networks require a one-dimensional sequence of symbols, we need to achieve a balance between sequence length and the number of symbols in the vocabulary, optimizing for efficient computation. Modern state-of-the-art transformer-based LLMs, including GPT and GPT-2, use Byte-Pair Encoding tokenization.

Breaking down tokenization helps demystify how LLMs interpret text inputs and generate coherent responses. Having an intuitive sense of what tokenization looks like helps in understanding the internal mechanisms behind the training and inference of LLMs. As LLMs are increasingly used as a knowledge base, a well-designed tokenization strategy is crucial for improving model efficiency and overall performance.

If you enjoyed this article, connect with me on X (formerly Twitter) for more insights.
References

Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Ovintiv shuffles some fourth-quarter spending to Permian basin

The leaders of Ovintiv Inc., Denver, are diverting $50 million in fourth-quarter capital spending to the operator’s Permian basin operations from the Montney to account for an Alberta gas plant being offline. President and chief executive officer Brendan McCracken and his team told analysts and investors on Nov. 4 that the adjustment to fourth-quarter spending plans should help oil and condensate production in the Permian basin average 125,000 and 130,000 b/d this quarter, in line with the third-quarter’s 127,000 b/d. The $50 million amounts to about 9% of Ovintiv’s planned capex this quarter and will let the company further manage the unplanned outage of CSV Midstream Solutions’ Albright sour gas plant in northern Alberta, which went offline in late July. Greg Givens, Ovintiv’s chief operating officer, said the CSV team has told Ovintiv that Albright should be up and running again before yearend and that Ovintiv has been able to manage the plant’s outage so that the company is only losing out on 3,000 boe/d. “If we think about that [capex] shift, that is really just us leaning into the flexibility of our portfolio,” Givens said on a conference call discussing Ovintiv’s third-quarter results. “The team has been doing a great job operating year to date. Our drilling performance was a little ahead of schedule so it just allowed us to accelerate some completion activity there.”

Read More »

EIA: US crude oil inventories down 900,000 bbl

US crude oil inventories for the week ended Oct. 30, excluding the Strategic Petroleum Reserve, decreased by 900,000 bbl from the previous week, according to data from the US Energy Information Administration (EIA). At 409.8 million bbl, US crude oil inventories are 4% below the 5-year average for this time of year, the EIA report indicated. Gasoline inventories decreased 200,000 bbl, 2% below the 5-year average. Propane-propylene inventories decreased 1.6 million bbl, 10% above the 5-year average. Total commercial petroleum inventories decreased by 8.2 million bbl for the week. Distillate inventories decreased 3.6 million bbl, 13% below the 5-year average. US crude oil refinery inputs averaged 16.7 million b/d for the week ended Oct. 30, which was 199,000 b/d more than the previous week’s average. Refineries operated at 94.5% of capacity. Gasoline output averaged 9.7 million b/d, and distillate production decreased to 5.2 million b/d. Crude oil imports decreased 1,000 b/d to 6.4 million b/d. The 4-week average of 6.1 million b/d is 9.5% above the year-ago level. Gasoline imports averaged 351,000 b/d; distillate imports averaged 117,000 b/d. Over the past four weeks, total product supplied averaged 21.2 million b/d, up 4.2% year over year. The 4-week average for gasoline product supplied decreased 0.4% year over year to 8.6 million b/d, while the 4-week average for distillate product supplied increased 8.7% to 4.2 million b/d. The 4-week average for jet fuel product supplied decreased 2.8% year over year.  

Read More »

Vedanta to explore off India’s east coast

@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } Vedanta Oil & Gas Ltd. (VOGL) entered a strategic partnership with Exceed to explore the KG-DWHP-2017/1 deepwater block in Krishna-Godavari (KG) basin off India’s east coast. The block, which lies in 600-2,000 m of water, contains four existing gas discoveries spanning 4,616.85 sq m. Under the agreement, Exceed will provide integrated support across the campaign, including subsurface evaluation, well planning, drilling readiness, and operational management. Vedanta expects a multi-well exploration drilling campaign to begin early next year. The plan follows a phased approach covering project planning, engineering, operational readiness, and well execution. The company is evaluating the Vermilion prospect as a distinct new play with potential. Recently, Vedanta secured two offshore blocks including deepwater block KG/DWDSF/GD10/2025 in the KG basin. Vedanta is operator at DWHP-2017/1 with 100% interest.

Read More »

JPMorgan sees global oil market return to surplus

The global oil market returned to surplus in September as recovering Middle Eastern exports and weaker demand eased supply pressures stemming from the Iran war, according to JPMorgan estimates. The assessment contrasts with the International Energy Agency’s (IEA) October outlook, which projected continued supply deficits through yearend. JPMorgan estimated that global oil supply exceeded demand by 1.1 million b/d in September, with the surplus widening to 1.4 million b/d in October. By comparison, IEA’s Oct. 14 Oil Market Report estimated a supply deficit of about 790,000 b/d in September, a difference of nearly 1.9 million b/d between the two assessments. IEA’s estimates indicated continued inventory depletion. Global observed oil stocks declined by about 10 million bbl in September, as a 113 million bbl draw in onshore inventories more than offset a 103 million bbl increase in oil on water. At the end of September, global observed inventories were 509 million bbl below end-February levels. The contrasting assessments may reflect differences in supply and demand estimates, inventory coverage, and reporting cutoffs. IEA’s October report projected a fourth-quarter supply deficit of about 1.8 million b/d, based on global supply of 101.7 million b/d and demand of 103.5 million b/d. Supply recovery According to JPMorgan, Middle Eastern oil exports recovered to about 20.7 million b/d in October from a low of 9.8 million b/d in March, although volumes remained below prewar levels. Global crude imports reached 44.9 million b/d, up 1.3 million b/d year over year (y-o-y). Supply growth outside the Middle East also contributed to the improving balance. JPMorgan estimated Latin American crude production increased by about 1.5 million b/d y-o-y, supported by gains in Brazil, Venezuela, Guyana, and Argentina. At the same time, global oil demand has declined by an estimated 3.3 million b/d since the conflict began in late February,

Read More »

Trump ban on foreign grid components sparks industry concern over practicality, cost

Listen to the article 8 min This audio is auto-generated. Please let us know if you have feedback. President Donald Trump’s recent executive order seeking to protect the bulk power system from foreign threats correctly identifies the risk of U.S. reliance on outside suppliers, but mitigating those risks without stalling the grid’s buildout or saddling ratepayers with even more costs will be tricky, stakeholders told Utility Dive. Executive Order 14421, issued Aug. 26, gives Secretary of Energy Chris Wright the power to block the installation of foreign-produced equipment – “or any critical component, software, firmware, digital service, maintenance service, or remote-access capability associated with such equipment” – that poses an “undue risk” to national security, either through intentional sabotage or supply chain disruption.  It also gave the secretary the authority to order the removal and replacement of previously installed equipment. The Department of Energy has until Dec. 24 to publish rules and regulations implementing the order. In September, DOE asked industry and other stakeholders to weigh in.  Their responses to DOE’s request show broad support for the intent of the order, but concern over how it will be implemented. A number pointed out that security standards, especially for software that would enable remote access, can be more important than country of origin since flaws in any system can be exploited by anyone, anywhere. The vast majority of stakeholder responses that took a position on the “function over origin” question favored DOE emphasizing functional controls as opposed to a software product’s origin, according to data compiled by industry analyst Brendon Shank. Many respondents also said they wanted DOE to take a phased approach to introducing new compliance rules and allow some vendors to “prequalify” as trustworthy. Utilities are projected to spend more than a trillion dollars on grid upgrades through 2030

Read More »

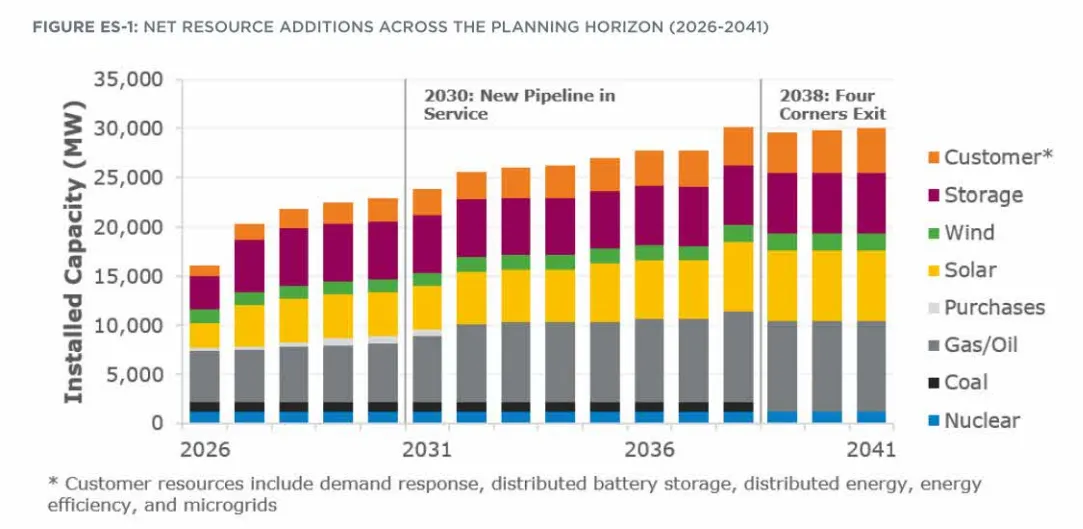
APS expects sales to double by 2041, plans extending coal use to 2038

Listen to the article 6 min This audio is auto-generated. Please let us know if you have feedback. Dive Brief: The largest electric utility in Arizona projects retail sales to double in the next 15 years and peak demand to grow 3.4% annually, after accounting for customer resources like demand-side management, driven by large-load industrial and data center customers. Arizona Public Service filed in an integrated resource plan with state regulators on Friday indicating it will extend the life of its Four Corners coal plant seven years past a planned 2031 retirement, in addition to bringing 2,000 MW of solar and 2,500 MW of storage resources online by 2029 and adding 4,000 MW of gas generation through 2036. APS also said it expects customer adoption of electric vehicles and behind-the-meter solar resources to be 18% and 30% lower than previous forecasts, respectively; customer-sited storage, however, could reach 1.2 GW by 2045, almost doubling the last storage forecast developed in 2023. Dive Insight: APS projects peak demand of more than 14.5 GW in 2041, almost 60% higher than its current record peak of about 9.2 GW, set in August. And the utility expects annual retail sales to grow to about 80,600 GWh in 2041, up from about 34,200 GWh in 2025. There is some uncertainty behind APS’ load projections, but the utility said it has taken steps to protect customers. Despite refinements to APS’ large-load interconnection process, the “sustained record levels of interest” from large customers poses “a risk in increased potential for unrealized loads,” APS said in its resource plan, which it files every three years with the Arizona Corporation Commission. To mitigate the risk, APS said it adopted strategies such as having customers commit to “minimum demand and energy-based contract terms, providing collateral in case of default, and instituting early exit fees.” As a

Read More »

Arista posts record growth as AI networking supercycle accelerates

One of the core answers to that threat is the company’s Autonomous Virtual Assistant (AVA), which lets administrators ask it questions about network conditions and receive explanations, recommendations, and assistance diagnosing problems. “AVA is incredibly powerful. It seamlessly navigates networking and security infrastructure from campus to WAN, to data center, to cloud, continuously monitoring and troubleshooting, isolating root causes without manual labor-intensive tasks,” said Ken Duda, Arista co-founder, president, CTO & director. “The bad news, of course, is the massive challenge AI poses for us and our customers by discovering and exploiting security vulnerabilities. This threat landscape demands secure and robust networking. Over the past few months, we’ve been collaborating with Anthropic, Google, OpenAI, and many others to integrate new AI-enabled security capabilities from frontier models into our existing software security pipeline,” Duda said.

Read More »

AEP, Google Advance $4 Billion Fuel-Cell Project to Power Cheyenne Data Centers

A Power Commitment That Began Two Years Earlier Although Google’s participation was publicly identified in October 2026, the procurement strategy underlying the Cheyenne project dates to November 2024, when Bloom Energy announced an agreement with AEP covering up to 1 gigawatt of solid oxide fuel-cell equipment. As Data Center Frontier reported at the time, the agreement included an initial commitment to purchase 100 MW, with options for an additional 900 MW. The arrangement was intended to help AEP serve large commercial and industrial customers facing growing electricity requirements without waiting for the completion of conventional grid infrastructure upgrades. The relationship advanced in January 2026, when AEP disclosed in a regulatory filing that an unregulated subsidiary had committed approximately $2.65 billion to purchase a substantial portion of the fuel-cell capacity covered by its earlier option. The company also reported a 20-year agreement to sell the planned facility’s entire electricity output to an unidentified investment-grade customer, now confirmed as Google. The equipment purchase formed part of the project’s development history, rather than representing a separate $2.65 billion investment in addition to the $4 billion project announced in October. The scale of the investment is significant, but so is the transaction structure. Rather than requiring Google to own and operate the generation equipment directly, the arrangement places development and ownership responsibilities with an established energy company while providing the hyperscaler long-term access to the facility’s electricity output. For AEP, it also represents an opportunity to deploy capital in support of large-load customers beyond its traditional regulated utility territory. At approximately $4 billion for 702 MW, the project represents roughly $5.7 million per megawatt of planned generating capacity. That figure offers a measure of the investment’s capital intensity, although it is not directly comparable with the construction cost of a conventional gas-fired power plant

Read More »

DCF Show: Can AI Unlock Data Centers’ Stranded Megawatts?

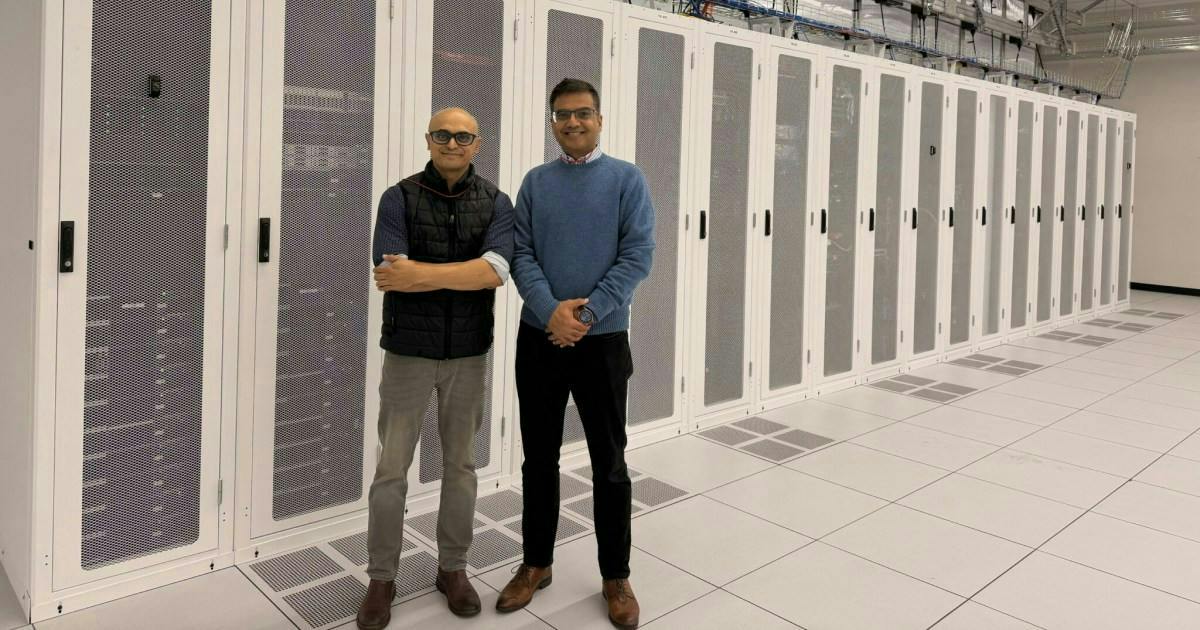
The data center industry’s race for power has become a contest against time. Developers are pursuing new generating capacity, transmission upgrades, utility interconnections, and increasingly elaborate behind-the-meter strategies to satisfy an AI infrastructure market whose demand keeps outrunning delivery schedules. Yet another possibility is emerging alongside the construction boom: Some of the power needed to expand AI computing may already be available inside operational facilities, committed to customers but not consistently consumed. That is the proposition behind Hammerhead AI, a Redwood City, California-based company developing software to coordinate electrical infrastructure, cooling systems, and computing workloads. Rather than treating a data center’s power allocation as a fixed ceiling that can only be raised through construction, Hammerhead argues that more compute can be accommodated by managing existing resources dynamically. In a new episode of the Data Center Frontier Show, Hammerhead AI founder and CEO Rahul Kar discussed the company’s approach with DCF Editor-in-Chief Matt Vincent, examining how reinforcement learning and workload orchestration could convert otherwise idle electrical capacity into revenue-producing AI infrastructure. The idea arrives at a consequential moment for the colocation market. DCF’s analysis of CBRE’s first-half 2026 data center market report found North American primary-market vacancy at just 1.4%, even as new construction reached record levels. Power commitments, delivery timelines, and access to ready infrastructure continue to determine where and when additional compute can be deployed. Hammerhead’s central argument is that the industry should examine how much of its already allocated capacity can be made productive before assuming that every increment of computing demand requires another increment of physical infrastructure. The commercial opportunity is substantial. Whether it can be realized without undermining the reliability expectations of mission-critical facilities is the harder question. A Power Shortage, or a Utilization Problem? Kar begins with a distinction between the electricity infrastructure available to

Read More »

Data Center Jobs: Engineering, Construction, Commissioning, Sales, Field Service and Facility Tech Jobs Available in Major Data Center Hotspots

Each month Data Center Frontier, in partnership with Pkaza, posts some of the hottest data center career opportunities in the market. Here’s a look at some of the latest data center jobs posted on the Data Center Frontier jobs board, powered by Pkaza Critical Facilities Recruiting. Looking for Data Center Candidates? Check out Pkaza’s Active Candidate / Featured Candidate Hotlist  Lead Mechanical Engineer – Data Center Design Dallas, TX / Remote This position is also available in: Denver, CO; Indianapolis, IN; Cedar Rapids, IA; Austin, TX; White Plains, NY; New York, NY; Richmond, VA; Ashburn, VA; Charlotte, NC; Atlanta, GA; Phoenix, AZ; Salt Lake City, UT; Kansas City, MO; Chicago, IL; Los Angeles, CA; Seattle, WA or San Jose, CA. Our client is a leading engineering design and commissioning company that is a subject matter expert in the data center space. They will provide design coordination and construction administration, consulting and management support for the data center / mission critical facilities space with the mindset to provide reliability, energy efficiency, and sustainable design expertise when providing these consulting services for enterprise, colocation and hyperscale companies. This career-growth minded opportunity offers exciting projects with leading-edge technology and innovation as well as competitive salaries and benefits. Electrical Commissioning Agent – Data Centers Phoenix, AZ (limited travel) Non-traveling CxA positions available in: Indianapolis, IN; Cedar Rapids, IA; Atlanta, GA and Columbus, OH. Traveling CxA based near any major airport, otherwise traveling to: New York, NY; White Plains, NY; Montvale, NJ; Richmond, VA; Boydton, VA; York, SC; Charlotte, NC; Salt Lake City, UT; Kansas City, MO; Chesterton, IN or Chicago, IL. *** Also looking for a lead EE and ME CxA agents and CxA PMs *** This opportunity is with a leading EPC company of data center design / build / commissioning solutions. This company provides a

Read More »

OCP 2026: Cooler Master Scales Liquid Cooling from Cold Plates to 2.5 MW CDUs

Modular Air-Assisted Cooling Targets Existing Data Centers One of the most instructive systems examined during the tour was Cooler Master’s 300 kW Air-Assisted Liquid Cooling (AALC) CDU, a modular liquid-to-air design intended for data centers without an existing facility water distribution system. Rather than transferring server heat into a building’s chilled-water or facility-water loop, the AALC system circulates coolant through the IT equipment and rejects the captured heat through fan-driven radiators. The distinction matters for operators seeking to introduce liquid-cooled AI racks into facilities that were not built with dedicated liquid cooling infrastructure. Although air-assisted systems still require sufficient facility airflow and heat rejection capacity, they offer an alternative to extending a new water distribution network throughout the data hall. The approach is already finding applications in the field. As DCF recently reported, Corvex deployed liquid-cooled NVIDIA Blackwell infrastructure inside an existing air-cooled data center, using Lenovo Neptune technology to avoid a conventional facility-wide liquid cooling conversion. Cooler Master’s 300 kW design separates the pumping equipment from its radiator assemblies. During the tour, a company representative explained that the system can be configured with a central pump rack and either one or two radiator racks, each providing a nominal 150 kW of cooling capacity. This modular arrangement allows cooling capacity to be matched more closely to the installation, rather than requiring every deployment to use the full 300 kW configuration. Serviceability is a major feature of the design. The system uses redundant pumps in a 2+1 arrangement, with two pumps supporting normal operation and a third providing standby capacity. Pump modules are designed for replacement without interrupting cooling operations. Other field-replaceable components include fans, filters, expansion tanks, and power-related assemblies. The product also incorporates redundant filtration and monitoring capabilities intended to help operators identify faults and maintain cooling performance. The

Read More »

7×24 Fall 2026: AI Frontier Futurist Meets Data Center OG

A 1988 Data Center Becomes a 20 MW AI Asset The second presentation, Converting a 1990 Enterprise Data Center to 20MW AI Workloads, featured Coe alongside Ari Chernikoff, vice president of development at Legacy Investing, and Dan Amundson, project manager at Gardner Builders. The project centered on 1001 Third Avenue South in downtown Minneapolis, a financial-services computing facility originally constructed in 1988. The building had supported earlier generations of enterprise computing before portions were converted to commercial office space and smaller colocation operations. Although its remaining operating data center load had declined to approximately 500 kilowatts by the time the AI redevelopment began, the property retained substantial infrastructure inherited from its original mission-critical design. Tall ceilings, robust floor loading, raised access floors, existing medium-voltage substations, and established utility connections made the building an unusually strong candidate for conversion. These characteristics, Chernikoff explained, can determine whether an existing building offers a practical path to high-density computing or proves economically unsuitable for redevelopment. Legacy Investing had identified a market opportunity in what Chernikoff called the industry’s “missing middle”: facilities generally ranging from 20 MW to 80 MW, rather than the 100 MW-plus campuses increasingly associated with hyperscale and frontier AI development. The company viewed existing buildings with available power and favorable infrastructure characteristics as potential shortcuts to deployment, particularly where demand for AI inference and other latency-sensitive workloads favored proximity to major urban markets. Following an AI tenant commitment in summer 2024, the development team faced an aggressive initial requirement: Deliver the first 5 MW of capacity by the end of that year. The first phase was ready for service approximately four months after Gardner’s involvement became formalized, followed by another 5 MW in 2025 and an expansion program ultimately reaching 20 MW over roughly 20 months. All of this had to

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »