Stay Ahead, Stay ONMINE

AI Clusters and the New Economics of Data Center Optics: A Conversation with Cisco’s Bill Gartner

Three Networks Inside the AI Factory Understanding the optical challenge begins with recognizing that an AI cluster contains several distinct networking environments. Gartner divided AI infrastructure into three broad tiers: scale-up, scale-out and scale-across. Each operates over a different distance, carries a different level of traffic and creates a different set of requirements for the […]

Three Networks Inside the AI Factory

Understanding the optical challenge begins with recognizing that an AI cluster contains several distinct networking environments.

Gartner divided AI infrastructure into three broad tiers: scale-up, scale-out and scale-across. Each operates over a different distance, carries a different level of traffic and creates a different set of requirements for the interconnect.

Scale-up describes the connections within a rack, where operators place as many GPUs as possible inside servers and then pack those servers into the available rack footprint. Gartner estimated that the bandwidth within this environment can be approximately 500 times that of a traditional wide-area network application.

Scale-up connections still rely heavily on electrical interfaces because electrical interconnects remain relatively inexpensive and power efficient over short distances.

Once the compute capacity of a rack has been exhausted, the cluster must expand into additional racks. This is the scale-out network, where 400G and 800G pluggable optics connect large numbers of GPU systems operating in parallel.

Gartner characterized scale-out bandwidth as roughly 50 times the capacity associated with a conventional WAN environment.

The third tier, scale-across, emerges when a data center reaches its practical power limit and the AI infrastructure must extend into another facility. Those data centers may be separated by tens or hundreds of kilometers, requiring coherent optical technology capable of carrying extremely high-capacity signals over longer distances.

Scale-across networks can represent approximately 14 times traditional WAN bandwidth, according to Gartner.

Taken together, the three tiers illustrate why optics has become inseparable from the AI infrastructure discussion. Network capacity must expand inside the rack, across rows of racks and increasingly between separate data centers—all without consuming an untenable share of the power budget or introducing failures that leave GPUs idle.

When One Link Slows the Whole Cluster

The reliability requirement for AI networks differs sharply from that of conventional enterprise or internet infrastructure.

In a traditional TCP/IP network, an error may trigger a packet retransmission. The application or user may never realize that the error occurred.

AI training clusters operate differently. GPUs work on large problems in parallel and must remain synchronized. When an error occurs on one link, the impact can extend across the cluster.

“All of the GPUs need to stop and back up to a checkpoint and restart,” Gartner said. “Because everything is running in parallel in a GPU infrastructure, a link error on one link actually impacts neighboring links.”

Those failures can be caused by a bad connection, a dirty optical connector, noise on the link or other physical and electronic problems. The resulting instability is often described as a link flap—a connection repeatedly dropping and recovering.

Gartner said information Cisco has received from hyperscale customers indicates that link flaps can reduce the efficiency of GPU infrastructure by as much as 40%.

That figure changes the practical meaning of optical reliability. A transceiver is no longer simply one component among thousands in the network. An unstable link can undermine the utilization of the far more expensive accelerators attached to it.

“We have every incentive to make sure that the optics are super reliable,” Gartner said.

The economics are stark. Operators are investing billions of dollars in AI campuses designed to keep accelerators running at the highest possible utilization. A network issue that forces thousands of GPUs to stop, return to a checkpoint and restart can erode the productivity of the entire deployment.

In that environment, optical reliability becomes a compute-efficiency metric.

1.6T Moves Toward Deployment

Most large AI training networks are currently being built around 400G and 800G connectivity. Gartner described those technologies as ubiquitous within hyperscale training infrastructure, with each serving different portions of the network.

The next step is already approaching.

Cisco is sampling 1.6-terabit optics with customers, and Gartner said the first volume deployments are expected to begin later this year. As with previous transitions from 10G to 100G, 100G to 400G and 400G to 800G, the appeal lies in improving cost and power efficiency per bit.

“There’s no question that there’s a demand for 1.6T,” he said. “We’re looking beyond 1.6T as well, as to what happens next.”

Adoption will remain uneven across customer segments.

Hyperscalers are driving most of the demand and volume for 800G and 1.6T technology. Traditional service providers remain earlier in their 400G and 800G deployments, while 400G is still in the early stages within many enterprise networks.

That distinction matters because hyperscale purchasing volume will help determine the technology’s cost curve. Gartner advised service providers and enterprises to closely watch the architectures being adopted by the largest cloud and AI infrastructure operators.

“If you want to be on the low-cost curve, you should be on the hyperscaler cost curve,” he said.

The Coming Electrical-to-Optical Transition

The progression from 400G to 800G and then 1.6T is significant, but Gartner views it as a familiar generational evolution. The more disruptive transition will occur when electrical connections can no longer carry the bandwidth required within the scale-up network.

The constraint comes down to physics.

As the bitrate of a signal increases, the distance it can travel generally decreases. Electrical interconnects remain attractive inside the rack because they are inexpensive and efficient, but the industry will eventually reach a point where they cannot support the required capacity over even short distances.

“My bet is ultimately on an optical solution,” Gartner said.

Several potential architectures are under development, including co-packaged optics, near-packaged optics, wide electrical buses using slower-rate signals and radio-frequency technologies.

Co-packaged optics and near-packaged optics move optical components away from the front panel of the switch and closer to the switching silicon. Instead of transmitting a high-speed electrical signal several inches across a line card to a pluggable transceiver, the system converts the signal into light nearer to the chip.

That shorter electrical path can reduce the need to repeatedly retime the signal, lowering power consumption. Removing pluggable modules from the faceplate could also increase port density because optical connectors require less space than complete transceivers.

Cisco expects co-packaged solutions to enter the market this year, giving operators an opportunity to gain practical experience with the architecture.

But the transition introduces operational tradeoffs.

Pluggable optics are replaceable, interoperable and available from multiple vendors. When one fails, a technician can replace the affected module. In a co-packaged design, the optical components may be mounted directly to a line card or integrated with the switch silicon.

That raises a more difficult question: What happens when a single optical channel fails?

Operators may need to rely on software to route around the failed link, replace a larger portion of the system or reconsider how they stock and service network equipment. Questions involving multi-vendor sourcing and component interoperability will also have to be resolved.

Gartner expects those operational issues to be worked through over the next several years before co-packaged or near-packaged optics become commonplace in scale-up networks.

Routed Optics Reduce the Scale-Across Penalty

Optical architecture is already changing how operators connect data centers.

Traditional long-distance optical networks use transponder line cards housed in dedicated chassis. The transponder receives an optical signal from a switch or router, converts it into a form capable of traveling over a long distance and combines it with other wavelengths on the same fiber.

Through its acquisition of Acacia, Cisco developed an architecture known as routed optical networking. The approach replaces the standalone transponder line card with a coherent pluggable optic inserted directly into the router.

Gartner said the architecture can consume approximately 90% less power than the conventional transponder-based approach while requiring less space and reducing cost.

Hyperscalers were among the earliest adopters, using coherent pluggables to connect AI infrastructure across data centers. The technology is now moving into service-provider networks and enterprise campus environments.

For AI operators, routed optical networking makes scale-across architectures more practical. When the power ceiling at one location prevents a cluster from expanding further, coherent optical links can extend the training environment into another facility.

Rather than acting as a bottleneck, Gartner said, optics is helping AI networks continue to scale beyond the physical and electrical limits of a single building.

“We’re going to see increasing use of multiple data centers involved in a single training infrastructure,” he said.

Coherent Optics Moves Inside the Data Center

The boundaries between scale-out and scale-across may also become less distinct.

Conventional data center optics commonly use intensity-modulation direct-detection technology, or IMDD, for connections rated over distances of approximately two kilometers. As bitrates continue increasing, maintaining that reach becomes more difficult.

The physical distance between switches does not become shorter simply because the network has moved to a faster generation. Operators expect each new technology to support the cabling and layouts already in place.

At some point, Gartner said, conventional data center optics may no longer be able to maintain the required reach. The industry may then need to adopt techniques from coherent optics, which have historically been used for metro, regional and long-haul networks.

“The likelihood is that we’ll have to borrow some of the coherent techniques that are used outside the data center and bring them in the data center,” he said.

That evolution could further blur the distinction between a data center campus, a metro cluster and geographically distributed AI infrastructure. Optical systems capable of supporting connections beyond 1,000 kilometers are already extending the practical reach of data center interconnection.

Bringing coherent techniques inside the facility would create new power and cost considerations, but it could allow operators to continue increasing bitrates without redesigning every physical network around shorter reaches.

Inference Changes the Optimization Target

Training clusters currently command much of the industry’s attention because of their enormous scale and capital requirements. Gartner expects the next major deployment wave to arrive as trained models move into inference.

Inference environments generally require smaller systems than frontier training clusters, but they will be deployed much more broadly across hyperscalers, service providers and enterprises.

The optimization target will therefore change.

Training places a premium on scale and the ability to connect enormous numbers of GPUs. Inference will place greater pressure on cost efficiency, power efficiency and the ability to support specialized models closer to users and applications.

That will keep optics at the center of the infrastructure equation, even as the type and size of the deployment changes.

For data center operators, the underlying lesson is that networking can no longer be treated as a secondary layer added after decisions about compute, power and facilities have been made. Optical cost, power consumption, reach and reliability are becoming design inputs for the AI factory itself.

As Gartner put it, optics is not limiting the growth of AI networks today. It is one of the technologies allowing them to move beyond the power and geographic boundaries of a single data center.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Leap second proposal will keep software stacks in sync

“That means an enterprise does not only have to worry about what its own servers do. It has to consider what happens when its cloud provider, operating system, identity provider, database, external APIs, and on premises systems interpret the same moment differently,” Kolev said. “This is precisely the type of

Read More »

Cisco bundles fixes for multiple vulnerabilities, some critical, into one patch

CVE-2026-20274 and CVE-2026-20279 both address lifetime resource control issues, such as inappropriate certificate validation, incorrect or missing authorization for critical functions, resource operation after release or expiration, out-of-bounds read or write, initialization of resources with insecure details, and resource allocation without throttling limits. The five other vulnerabilities are rated between

Read More »

EIA forecasts continued growth in US crude oil production through 2026

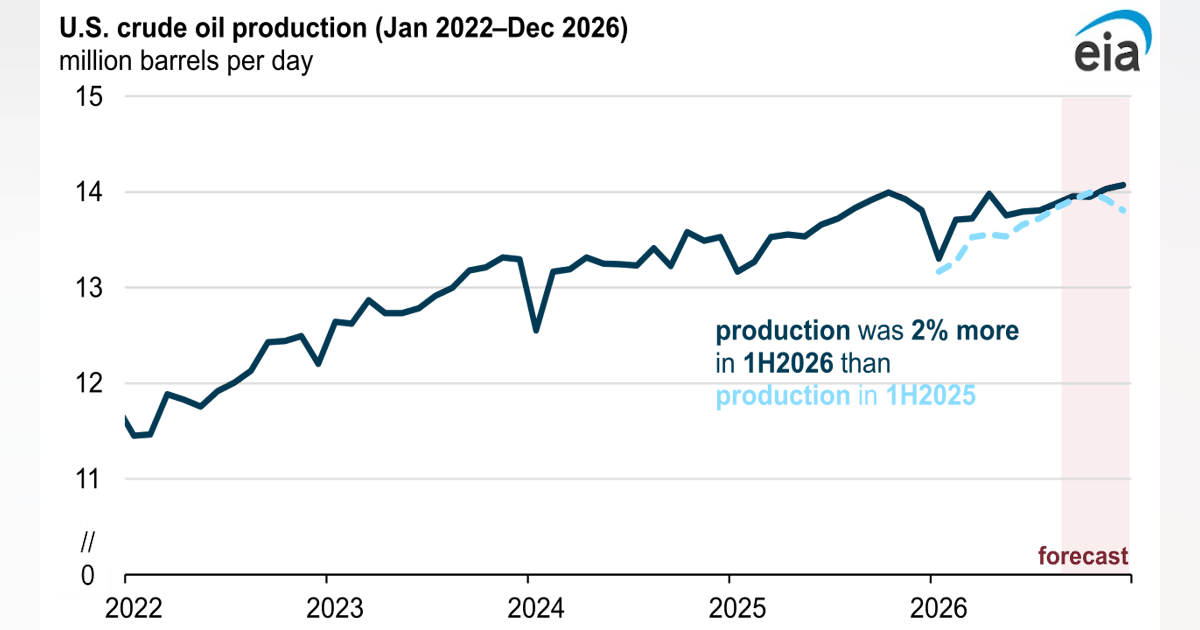
US crude oil production will average a record 13.8 million b/d in 2026, up from the previous record of 13.7 million b/d set in 2025, according to the US Energy Information Administration’s (EIA) latest Short-Term Energy Outlook. Crude production averaged 13.7 million b/d during first-half 2026, an increase of 0.3 million b/d, or 2%, from the same period a year earlier. EIA attributed most of the growth to increased output from the Permian region of Texas and New Mexico and the Federal Gulf of Mexico. Permian crude oil production is forecasted to average 6.8 million b/d in 2026, up 3% from 2025. EIA said higher crude oil prices are supporting production growth in the basin. West Texas Intermediate averaged $84/bbl through August, compared with $65/bbl in 2025. Current prices remain above reported Permian breakeven levels. According to the Dallas Fed Energy Survey in March, oil executives reported average breakeven prices of $69/bbl in the Midland basin and $63/bbl in the Delaware basin. Federal Gulf of Mexico crude production increased 10%, or 0.2 million b/d, during first-half 2026 compared with the same period a year earlier. EIA expects full-year 2026 Gulf production will increase 3%, or 0.1 million b/d. Four major projects that came online during the past year contributed to the Gulf increase. The Shenandoah floating production unit has averaged 70,000 b/d since starting production in July 2025, while the Ballymore subsea tieback has averaged 58,000 b/d since April 2025. The Whale floating production unit has averaged 38,000 b/d since January 2025, and the Salamanca floating production unit has averaged 25,000 b/d since late 2025. EIA expects four additional smaller projects to come online by yearend, providing further support for Gulf production growth.

Read More »

EIA: US crude inventories down 400,000 bbl

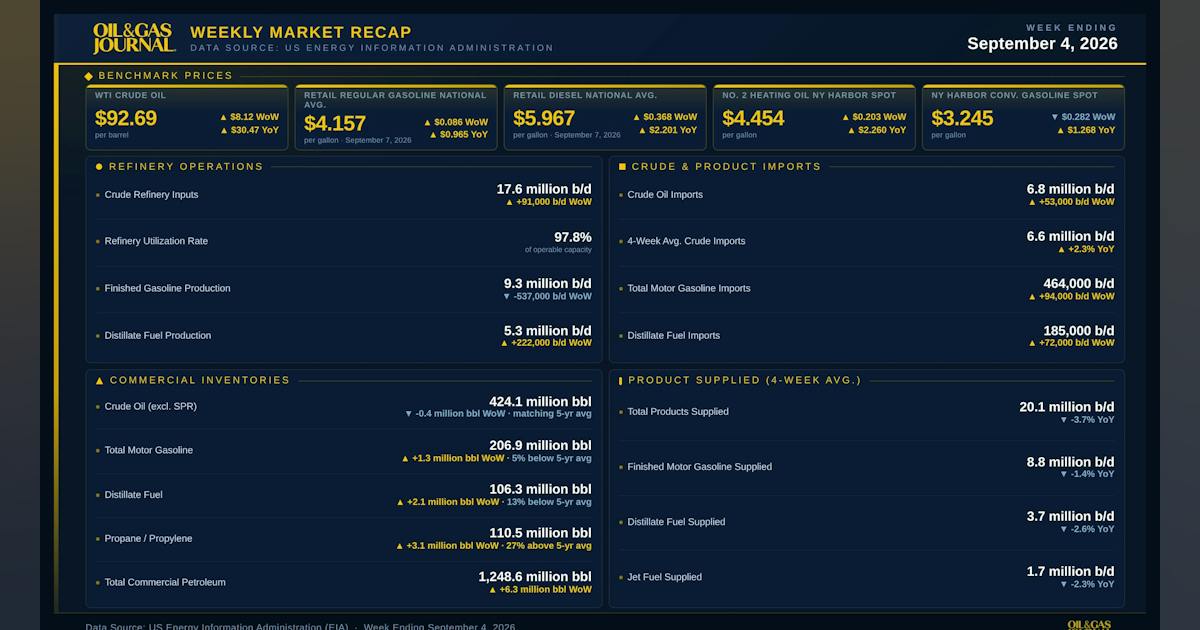
US crude oil inventories for the week ended Sept. 4, excluding the Strategic Petroleum Reserve, decreased by 400,000 bbl from the previous week, according to data from the US Energy Information Administration (EIA). The data was released a day later than usual due to the closure of the agency for the US Labor Day holiday on Monday, Sept. 7. At 424.1 million bbl, US crude oil inventories are the same as the 5-year average for this time of year, the EIA report indicated. EIA said total motor gasoline inventories increased by 1.3 million bbl from last week and are 5% below the 5-year average for this time of year. Distillate inventories increased by 2.1 million bbl last week and are about 13% below the 5-year average for this time of year. Propane-propylene inventories increased 3.1 million bbl, 27% above the 5-year average. Total commercial petroleum inventories increased by 6.3 million bbl for the week. US refineries processed 17.6 million b/d for the week ended Sept. 4, which was 91,000 b/d more than the previous week’s average. Refineries operated at 97.8% of capacity. Gasoline output averaged 9.3 million b/d, and distillate production increased to 5.3 million b/d. US crude oil imports averaged 6.8 million b/d, up 53,000 b/d from the previous week. Over the last 4 weeks, crude oil imports averaged about 6.6 million b/d, 2.3% more than the same 4-week period last year. Total motor gasoline imports averaged 464,000 b/d. Distillate fuel imports averaged 185,000 b/d.

Read More »

Shell, partners sign agreement for Angola offshore blocks

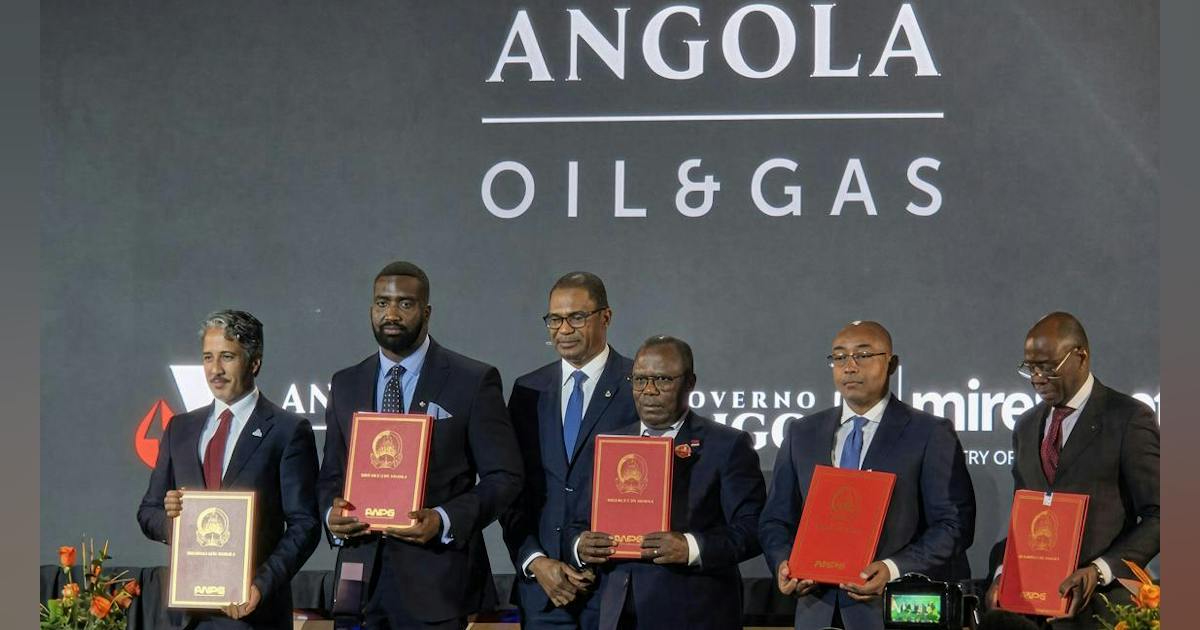
Shell, QatarEnergy, and Sonangol E&P signed Heads of Terms regarding the Risk Service Contracts for Blocks 8 and 22 offshore Angola, with Angola’s National Agency for Oil, Gas and Biofuels (ANPG).  The move is a step in evaluating offshore potential and building on Angola’s established role in Africa’s energy sector, Shell said in a release Sept. 9. Alioune Sourang, country chair of Shell Angola, said the signing is “another positive step in Shell’s renewed engagement with Angola,” and that it “builds on the momentum from exploration block entries with Chevron, Equinor, and Sonangol P&P.”  Under the agreement, Shell will be operator with 50% interest, QatarEnergy will hold 30% working interest, and Sonangol will hold 20% in the two offshore blocks. Shell’s participation in the Heads of Terms is through BG International Ltd. – Sucursal em Angola, a Shell company. The agreement was signed in the Angolan capital Luanda on the sidelines of the Angola Oil & Gas Conference. It is subject to the relevant governmental approvals and final contractual arrangements.

Read More »

Barclays conference: Chevron eyes ‘factory-type’ development in Venezuela; Exxon says operators matter more than ever

Executives from Chevron Corp. and ExxonMobil Corp. spoke at the Barclays 40th Annual Energy-Power Conference in New York this week, expanding on how they’re approaching the next phase of upstream growth, highlighting opportunities from Venezuela to Guyana, and offering clues about how major operators are evaluating future resource development opportunities. As OGJ did following , we’ve gathered notable comments from company leaders about the opportunities and challenges shaping their businesses. Chevron Unsurprisingly, a significant share of the conversation between Barclays analyst Betty Jiang and Chevron Corp. chief financial officer Eimear Bonner focused on the company’s ambitions in Venezuela, where the company last week signed a deal to over the next 5 years. Bonner reiterated the attractive financial picture for Chevron, pointing to operating costs below $20/bbl and a goal of hitting 600,000 b/d in 2031 (from today’s roughly 280,000 b/d) just from primary recovery. Chevron teams expect that production will plateau between 600,000 and 700,000 b/d for most, if not all, of the 2030s. “There’s a lot more upside there,” Bonner said. “This is growth at low cost and very attractive returns.” Helping to solidify Chevron’s financial equation, Bonner added, is that the company’s existing infrastructure in Venezuela is in good shape and that its expansion plans won’t require major capital projects but will instead lean on pipeline and utility expansion work. “The best way to think about this is we are developing or intend to develop this like the way we develop the Permian,” Bonner said. “It really is just another factory-type development. There will be a period of investment and a period of plateau. We’re looking forward to adopting and scaling and implementing all the lessons learned from the factory experience that we have.” ExxonMobil With a next quarter in the Stabroek block offshore Guyana, ExxonMobil Corp. is

Read More »

Hydrocarbons and Geothermal Energy Office Announces $300,000 to Help Identify Hidden Geothermal Systems

WASHINGTON — The U.S. Department of Energy’s (DOE) Hydrocarbons and Geothermal Energy Office (HGEO) today announced the $300,000 Geologic Enhanced Mapping System (GEMS) Prize to help identify hidden geothermal systems by using geophysical data to identify faults and structures indicative of geothermal resources. Activities enabled by this prize will help deliver on President Trump’s Executive Order, Unleashing American Energy, by advancing geothermal exploration, in turn supporting the potential for geothermal to provide affordable, reliable, around-the-clock domestic electricity to Americans. “Unlocking America’s vast geothermal potential is essential to securing our energy dominance and providing the reliable, dispatchable baseload power our nation needs,” said DOE Acting Assistant Secretary of the Hydrocarbons and Geothermal Energy Office Curt Coccodrilli. “By challenging innovators to map hidden geothermal resources, the GEMS Prize will boost efforts to strengthen grid stability, reduce utility expenses for U.S. households, and deliver the secure, steady electricity required to fuel our domestic manufacturing resurgence and next-generation AI data centers.” The GEMS Prize challenges competitors to develop, train, and test algorithms that generate enhanced geologic fault datasets—which, in turn, can support mapping and modeling for geothermal and critical mineral resources. By using real-world datasets and testing ideas against geophysical data, the GEMS Prize is expected to accelerate discoveries of new, commercially viable hidden geothermal systems while reducing exploration and development risks. The competition comprises two rounds, with prizes ranging from $15,000 to $100,000. Both individual and group competitors can participate, and submissions are due December 3, 2026. Learn more on the competition website. Learn how HGEO is unleashing the full potential of America’s hydrocarbon and geothermal resources to provide affordable, reliable, and secure energy here.

Read More »

EIA sees Brent near $90/bbl in second-half 2026 amid Middle East disruptions

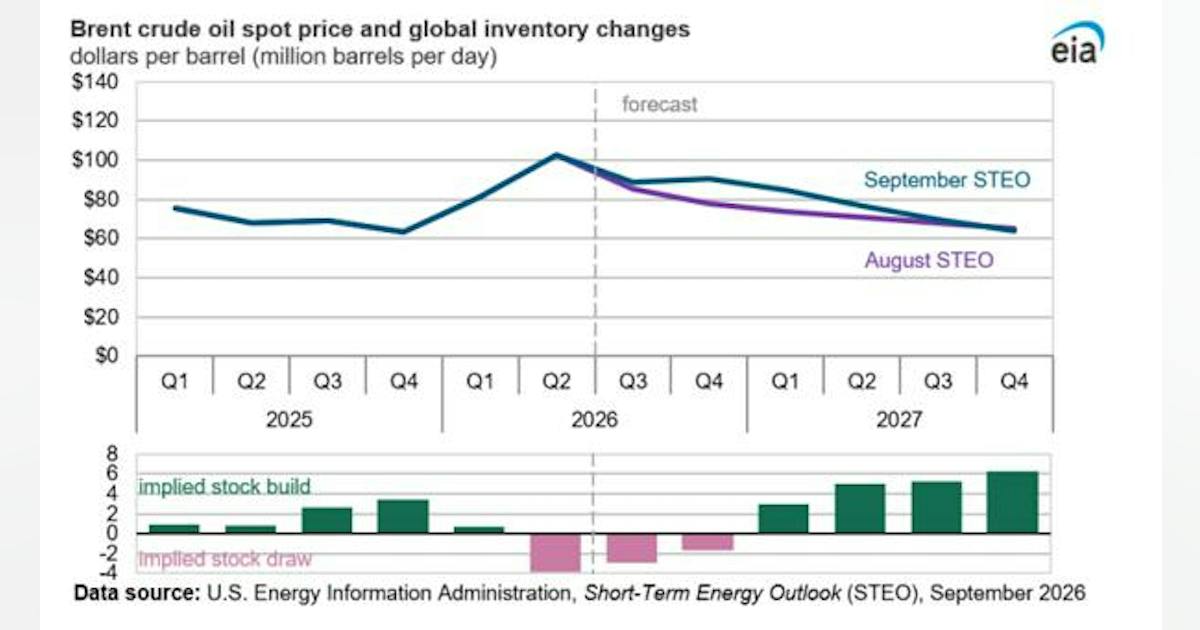
Global crude oil prices are expected to remain elevated through yearend 2026 as Middle East production disruptions and constrained exports continue to draw down inventories, the US Energy Information Administration (EIA) said in its September Short-Term Energy Outlook (STEO). EIA forecasts Brent crude oil spot prices will average about $90/bbl in second-half 2026, $8/bbl higher than projected in its August outlook. Brent averaged $91/bbl in August, up $7/bbl from July, as constrained Middle East exports led to additional production shut-ins. Middle East crude production shut-ins averaged an estimated 6.7 million b/d in August, up from 5.0 million b/d in July. EIA expects disruptions to ease gradually but remain substantial, with shut-in volumes averaging about 5.7 million b/d in fourth-quarter 2026. Oil flows through the Strait of Hormuz and Bab el-Mandeb remain constrained, although producers and shippers are increasingly using pipeline and overland bypass routes and ship-to-ship transfers. Stay updated on oil price volatility, shipping disruptions, LNG market analysis, and production output through OGJ’s Iran war content hub. Renewed US blockade of Iranian exports after Iran’s tanker attacks in Hormuz, plus the Treasury Department’s Office of Foreign Assets Control (OFAC) sanctions against Iranian economic and oil interests, will cut Iran’s exports and production, EIA said. In addition, attacks in Bab el-Mandeb roughly halved August loadings at Yanbu, the Red Sea port that bypasses Hormuz, according to Vortexa estimates. Saudi Arabia has rerouted barrels through the Suez Canal—longer and costlier for Asian buyers—and reportedly started ship-to-ship transfers outside the Persian Gulf, but EIA expects Red Sea constraints to cap Saudi supply near term. The disruptions have led to sharp inventory draws. EIA estimates global oil inventories fell by an average 3.9 million b/d in second-quarter 2026 and forecasts additional draws of 3.0 million b/d in the third quarter and 1.7 million b/d

Read More »

Nvidia invests $3.5B in MediaTek to extend its grip on AI

AI infrastructure: MediaTek will work with Nvidia’s NVLink Fusion ecosystem to enable customers to develop custom AI infrastructure designed to integrate with Nvidia rack-scale systems and AI factories. Local AI computing: The companies will continue to collaborate on multiple generations of Nvidia RTX Spark and DGX Spark PC chips, powering consumer PCs, AI developer supercomputers, and enterprise-class workstations, that integrate Nvidia GPUs with MediaTek SoCs. Automotive: MediaTek and Nvidia will continue developing platforms for AI-powered, software-defined vehicles in the era of physical AI.  “MediaTek is one of the world’s great semiconductor companies, with exceptional expertise in system-on-chip design, connectivity, leading performance and power efficiency,” said Jensen Huang, founder and CEO of Nvidia, in a statement. “Together, we’re building platforms that bring Nvidia accelerated computing to new markets and give customers the freedom to create differentiated AI systems at enormous scale.” NVLink is a high-performance interface, but this move also helps lock in customers to the Nvidia platform, since NVLink Fusion is not about to hook up to AMD processors. For MediaTek, the Nvidia investment provides a big pile of cash and access to Nvidia’s infrastructure as it attempts to establish itself as a major supplier of custom data center silicon.

Read More »

AI Puts Fiber on the Critical Path

Fiber Becomes Part of the Build A decade ago, DC Blox might have prioritized land near existing fiber from AT&T, Verizon, Zayo or another established network provider. That calculation is different today. As data center campuses have grown and hyperscalers have become a larger share of the customer base, Wabik said connectivity has increasingly become another construction package associated with the project itself. “If Zayo or Verizon or AT&T just happens to be there close by, that’s a good thing,” he said. “But fiber construction is inherently anymore just part of the construction component.” That changes the site-selection question from Is there fiber nearby? to Can fiber be built here at the scale and diversity the customer requires? For DC Blox, Wabik said that can mean assessing whether sufficient public right-of-way exists to establish three or sometimes four diverse fiber paths into a data center. That distinction is important, as AI workloads push infrastructure into markets where power, land and energy options may be more abundant than established carrier density. The hyperscalers themselves have also become major network builders. Wabik characterized them provocatively as today’s telecom providers, pointing to the scale of terrestrial fiber they commission as well as the growing role of companies such as Amazon, Google and Meta in subsea cable development. The point is less that traditional carriers have disappeared than that hyperscalers increasingly design, commission and control enormous portions of the connectivity required to support their own infrastructure. DC Blox now sees requests for 864-count fiber as routine and, in some cases, 1,728-count cable. That would have been difficult to imagine during an earlier era when a handful of fibers from an established carrier could satisfy a data center’s connectivity requirements. AI-Scale Fiber Gets Physical The scale becomes clearer when the discussion moves from abstract network

Read More »

Power First: AI Data Centers Become Energy Systems

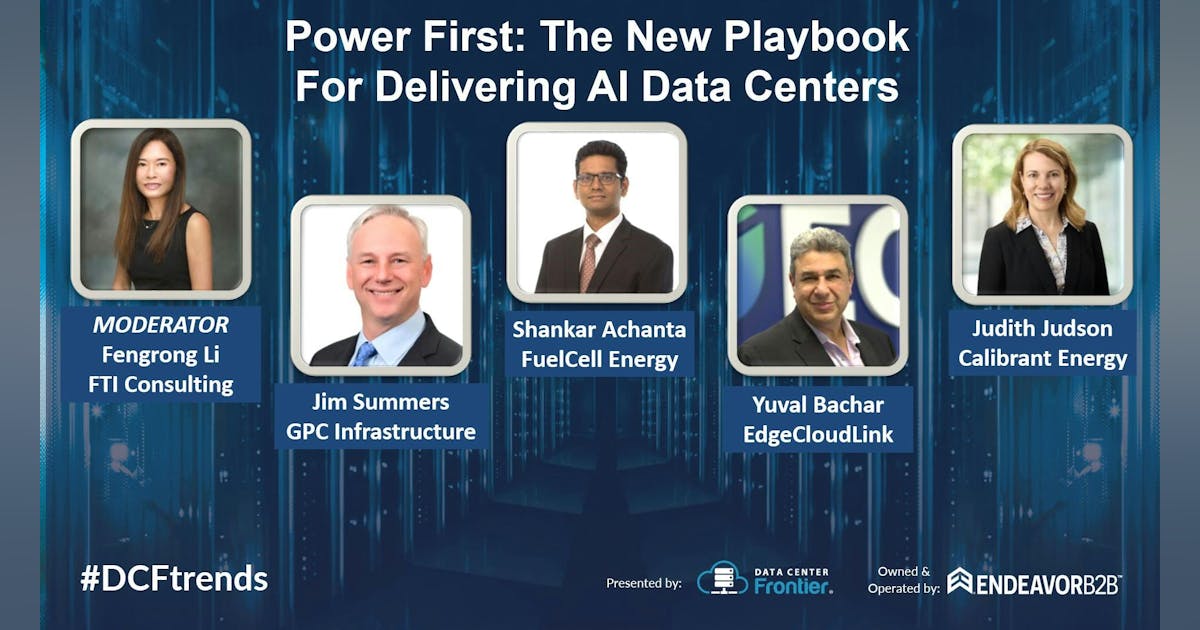
For decades, data centers consumed electricity much like other large commercial customers: power arrived from the utility, while batteries and diesel generators stood behind it to protect the load. AI is starting to break that model. As data center campuses grow toward hundreds of megawatts and, in some cases, gigawatt scale, developers are increasingly taking responsibility for an energy system that once sat largely outside the data center boundary. Natural gas supply, onsite generation, fuel cells, batteries, controls and the behavior of the compute load itself are increasingly becoming parts of the same infrastructure system. That was the central thread running through “Power First: The New Playbook for Delivering AI Data Centers,” an Aug. 4 session at the Data Center Frontier Trends Summit 2026 in Reston, Virginia. Moderated by Fengrong Li, Senior Managing Director at FTI Consulting, the panel brought together Jim Summers, CEO of GPC Infrastructure; Shankar Achanta, EVP and Chief Product and Technology Officer at FuelCell Energy; Judith Judson, Executive Vice President at Calibrant Energy; and Yuval Bachar, Founder and CEO of EdgeCloudLink. The discussion began with the immediate constraint — the grid cannot deliver capacity on the timetable AI developers increasingly require — but quickly moved beyond the familiar concept of “bridge power.” The larger question was what happens when the data center itself becomes an energy system. From Backup Power to Prime Power Behind-the-meter generation is not new. What has changed is its role and scale. “Traditionally, behind-the-meter generation has been for backup and the sizes were smaller,” Achanta said. “But what they’re seeing is the demand for the power is growing rapidly due to the data center load.” Interconnection queues, transmission limitations and equipment supply constraints are pushing onsite generation into what Achanta called the “front seat,” supplying primary power rather than waiting behind the

Read More »

NVIDIA Pushes DSX Deeper Into Data Center Infrastructure

The joint reference design appears in Trane’s Continuum Rubin DSX and Eaton’s Beam Rubin DSX platforms. The goal is a pre-coordinated architecture stretching from grid power to the chip rather than requiring developers and engineering teams to independently assemble electrical and mechanical systems for each project. The systems are also intended to exchange operating data. Rather than cooling and electrical systems responding independently, the systems can instead exchange leading indicators and respond more dynamically to changing operating requirements. This is an approach that closely mirrors NVIDIA’s larger DSX philosophy. Trane and Eaton are also designing the architecture to accommodate future liquid-cooling and direct-current power-distribution technologies. That future-proofing matters as rack power densities continue to rise. An electrical and cooling plant optimized for one GPU generation may otherwise become a constraint several hardware generations later. The Broader DSX Buildout The Lancium, Cloverleaf and Trane/Eaton agreements are part of a considerably wider expansion of the DSX ecosystem. Earlier deals show NVIDIA moving into many of the same infrastructure layers through partnerships spanning powered land, electrical design, digital twins and even project financing. In May, NVIDIA and IREN announced plans to support as much as 5 GW of DSX-aligned AI infrastructure across IREN’s global development pipeline, with the companies identifying IREN’s 2 GW Sweetwater campus in Texas as an expected flagship DSX deployment. NVIDIA also received a five-year right to purchase up to 30 million IREN shares at $70 each, representing a potential investment of as much as $2.1 billion. The infrastructure ecosystem has widened as well. Siemens, NVIDIA and Fluence, incorporating nVent design considerations, have developed a DSX Vera Rubin-aligned electrical, power and controls architecture extending from the utility connection to the rack. ABB is integrating digital models of medium-voltage switchgear, power-distribution equipment and UPS systems into the Omniverse DSX Blueprint, while Vertiv

Read More »

ERCOT Puts Texas AI Megawatts to the Test

Texas has no shortage of proposed data center megawatts. The harder question is how many of them are real. That distinction is becoming central to the Electric Reliability Council of Texas (ERCOT) as the state works through an unprecedented wave of AI, hyperscale and other large-load requests. In June, ERCOT said it was tracking more than 438 GW of proposed large loads, nearly 89% associated with data centers. By Aug. 3, Gov. Greg Abbott said ERCOT was considering approximately 474 GW of connection requests, roughly 90% from data centers and more than five times the system’s record peak demand. Neither figure represents a forecast of what will actually get built. And that is increasingly the point. ERCOT’s new Batch Zero process is beginning to put harder boundaries around Texas’ enormous development pipeline, asking which projects have enough maturity, technical information and commitment to warrant space in the transmission plan. At the same time, new requirements surrounding voltage ride-through and dynamic modeling are forcing another realization on the AI infrastructure industry: at hundreds of megawatts, a data center is no longer simply a customer at the edge of the grid. Its behavior can affect the grid itself. For developers, utilities and investors, Texas is becoming a large-scale test of what separates an announced AI campus from executable infrastructure. The Queue Is Not the Grid The sheer scale of ERCOT’s large-load queue can obscure how early many projects remain. ERCOT’s April 2026 monthly report offered a revealing snapshot. Large-load applications totaled 445.8 GW through 2033, but 321 GW had no studies submitted to ERCOT. Another 93.7 GW was under ERCOT review, while 22 GW had met the applicable Section 9.5 requirements. Against that enormous development funnel, ERCOT reported just 5.9 GW of observed energized large loads, with another 3.2 GW approved to

Read More »

DCF Trends Summit: AI Compresses the Data Center Hardware Lifecycle and Raises the Stakes for ITAD

The AI infrastructure race is largely a story about getting more computing into data centers faster. But the accelerated hardware cycle is creating an equally consequential problem at the other end of the rack: getting yesterday’s equipment back out while it is still valuable. GPU systems built around increasingly dense and specialized AI architectures are beginning to challenge traditional assumptions about IT asset disposition, or ITAD. Where conventional enterprise infrastructure might remain in service for three to five years, newer GPU platforms can face refresh cycles of 18 to 24 months, according to Josh Humm, Data Center Solutions Manager at Dynamic Lifecycle Innovations. That compression changes the economics as well as the mechanics of decommissioning. “The faster we can get the materials out of your building, the more it’s worth, the more we can return to your program,” Humm said. Humm joined DCF Contributing Editor Doug Black for a DCF Show podcast recorded at the third annual Data Center Frontier Trends Summit, held Aug. 4-6 in Reston, Virginia. Their conversation focused on a less visible part of the AI infrastructure buildout: what happens to servers, accelerators, memory, storage and networking gear when the next generation arrives. The answer increasingly touches facility operations, data security, logistics, sustainability and potentially millions of dollars in recoverable hardware value. AI Hardware Changes the Exit Path AI systems create some obvious physical challenges for decommissioning. Traditional ITAD teams accustomed to pulling 1U and 2U servers out of air-cooled racks may instead encounter liquid-cooling manifolds, substantially heavier systems and equipment requiring specialized rigging and handling procedures. Humm said some systems can weigh between 5,000 and 6,000 pounds. “We’re not pulling out just 1U, 2U servers out of racks anymore,” he said. Liquid cooling adds another layer. Removing infrastructure designed around direct-to-chip or other liquid-cooling architectures can

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

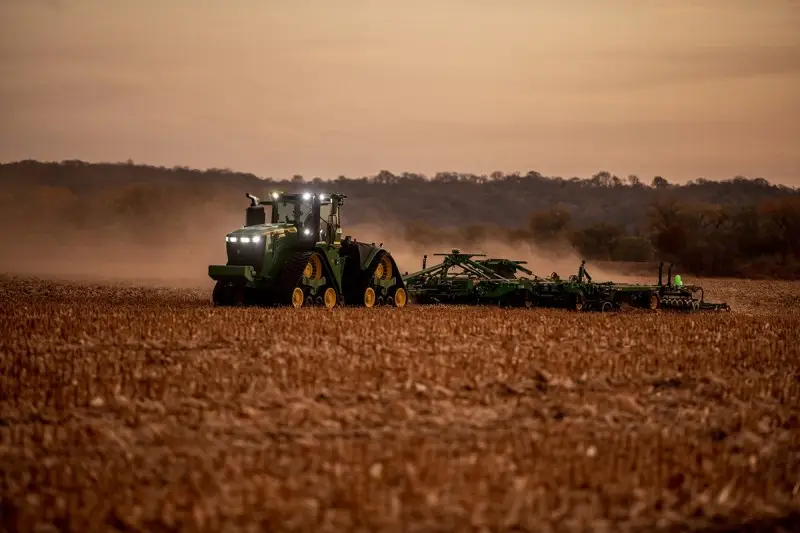
Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »