Stay Ahead, Stay ONMINE

DeepSeek R1’s bold bet on reinforcement learning: How it outpaced OpenAI at 3% of the cost

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More DeepSeek R1’s Monday release has sent shockwaves through the AI community, disrupting assumptions about what’s required to achieve cutting-edge AI performance. Matching OpenAI’s o1 at just 3%-5% of the cost, this open-source model has not only […]

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More


DeepSeek R1’s Monday release has sent shockwaves through the AI community, disrupting assumptions about what’s required to achieve cutting-edge AI performance. Matching OpenAI’s o1 at just 3%-5% of the cost, this open-source model has not only captivated developers but also challenges enterprises to rethink their AI strategies.

The model has rocketed to the top-trending model being downloaded on HuggingFace (109,000, as of this writing) – as developers rush to try it out and seek to understand what it means for their AI development. Users are commenting that DeepSeek’s accompanying search feature (which you can find at DeepSeek’s site) is now superior to competitors like OpenAI and Perplexity, and is only rivaled by Google’s Gemini Deep Research.

The implications for enterprise AI strategies are profound: With reduced costs and open access, enterprises now have an alternative to costly proprietary models like OpenAI’s. DeepSeek’s release could democratize access to cutting-edge AI capabilities, enabling smaller organizations to compete effectively in the AI arms race.

This story focuses on exactly how DeepSeek managed this feat, and what it means for the vast number of users of AI models. For enterprises developing AI-driven solutions, DeepSeek’s breakthrough challenges assumptions of OpenAI’s dominance — and offers a blueprint for cost-efficient innovation. It’s the “how” DeepSeek did what it did that should be the most educational here.

DeepSeek’s breakthrough: Moving to pure reinforcement learning

In November, DeepSeek made headlines with its announcement that it had achieved performance surpassing OpenAI’s o1, but at the time it only offered a limited R1-lite-preview model. With Monday’s full release of R1 and the accompanying technical paper, the company revealed a surprising innovation: a deliberate departure from the conventional supervised fine-tuning (SFT) process widely used in training large language models (LLMs).

SFT, a standard step in AI development, involves training models on curated datasets to teach step-by-step reasoning, often referred to as chain-of-thought (CoT). It is considered essential for improving reasoning capabilities. However, DeepSeek challenged this assumption by skipping SFT entirely, opting instead to rely on reinforcement learning (RL) to train the model.

This bold move forced DeepSeek-R1 to develop independent reasoning abilities, avoiding the brittleness often introduced by prescriptive datasets. While some flaws emerge – leading the team to reintroduce a limited amount of SFT during the final stages of building the model – the results confirmed the fundamental breakthrough: reinforcement learning alone could drive substantial performance gains.

The company got much of the way using open source – a conventional and unsurprising way

First, some background on how DeepSeek got to where it did. DeepSeek, a 2023 spin-off from Chinese hedge-fund High-Flyer Quant, began by developing AI models for its proprietary chatbot before releasing them for public use.  Little is known about the company’s exact approach, but it quickly open sourced its models, and it’s extremely likely that the company built upon the open projects produced by Meta, for example the Llama model, and ML library Pytorch. 

To train its models, High-Flyer Quant secured over 10,000 Nvidia GPUs before U.S. export restrictions, and reportedly expanded to 50,000 GPUs through alternative supply routes, despite trade barriers. This pales compared to leading AI labs like OpenAI, Google, and Anthropic, which operate with more than 500,000 GPUs each.  

DeepSeek’s ability to achieve competitive results with limited resources highlights how ingenuity and resourcefulness can challenge the high-cost paradigm of training state-of-the-art LLMs.

Despite speculation, DeepSeek’s full budget is unknown

DeepSeek reportedly trained its base model — called V3 — on a $5.58 million budget over two months, according to Nvidia engineer Jim Fan. While the company hasn’t divulged the exact training data it used (side note: critics say this means DeepSeek isn’t truly open-source), modern techniques make training on web and open datasets increasingly accessible. Estimating the total cost of training DeepSeek-R1 is challenging. While running 50,000 GPUs suggests significant expenditures (potentially hundreds of millions of dollars), precise figures remain speculative.

What’s clear, though, is that DeepSeek has been very innovative from the get-go. Last year, reports emerged about some initial innovations it was making, around things like Mixture of Experts and Multi-Head Latent Attention.

How DeepSeek-R1 got to the “aha moment”

The journey to DeepSeek-R1’s final iteration began with an intermediate model, DeepSeek-R1-Zero, which was trained using pure reinforcement learning. By relying solely on RL, DeepSeek incentivized this model to think independently, rewarding both correct answers and the logical processes used to arrive at them.

This approach led to an unexpected phenomenon: The model began allocating additional processing time to more complex problems, demonstrating an ability to prioritize tasks based on their difficulty. DeepSeek’s researchers described this as an “aha moment,” where the model itself identified and articulated novel solutions to challenging problems (see screenshot below). This milestone underscored the power of reinforcement learning to unlock advanced reasoning capabilities without relying on traditional training methods like SFT.
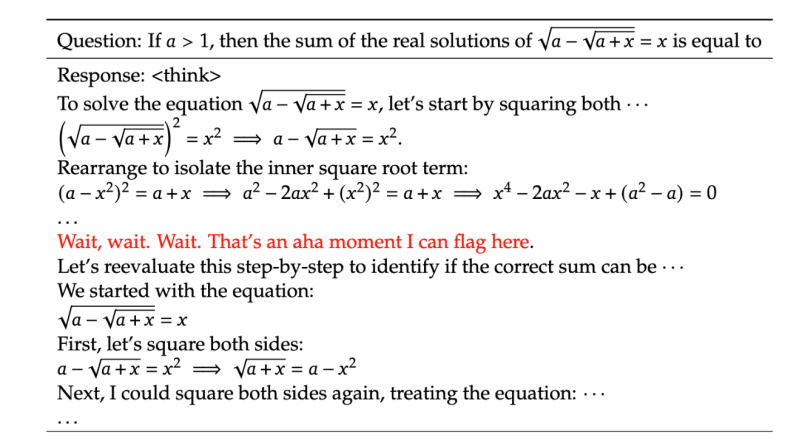
Source: DeepSeek-R1 paper. Don’t let this graphic intimidate you. The key takeaway is the red line, where the model literally used the phrase “aha moment.” Researchers latched onto this as a striking example of the model’s ability to rethink problems in an anthropomorphic tone. For the researchers, they said it was their own “aha moment.”

The researchers conclude: “It underscores the power and beauty of reinforcement learning: rather than explicitly teaching the model on how to solve a problem, we simply provide it with the right incentives, and it autonomously develops advanced problem-solving strategies.”

More than RL

However, it’s true that the model needed more than just RL. The paper goes on to talk about how despite the RL creating unexpected and powerful reasoning behaviors, this intermediate model DeepSeek-R1-Zero did face some challenges, including poor readability, and language mixing (starting in Chinese and switching over to English, for example). So only then did the team decide to create a new model, which would become the final DeepSeek-R1 model. This model, again based on the V3 base model, was first injected with limited SFT – focused on a “small amount of long CoT data” or what was called cold-start data, to fix some of the challenges. After that, it was put through the same reinforcement learning process of R1-Zero. The paper then talks about how R1 went through some final rounds of fine-tuning.

The ramifications

One question is why there has been so much surprise by the release. It’s not like open source models are new. Open Source models have a huge logic and momentum behind them. Their free cost and malleability is why we reported recently that these models are going to win in the enterprise.

Meta’s open-weights model Llama 3, for example, exploded in popularity last year, as it was fine-tuned by developers wanting their own custom models. Similarly, now DeepSeek-R1 is already being used to distill its reasoning into an array of other, much smaller models – the difference being that DeepSeek offers industry-leading performance. This includes running tiny versions of the model on mobile phones, for example.

DeepSeek-R1 not only performs better than the leading open source alternative, Llama 3. It shows its entire chain of thought of its answers transparently. Meta’s Llama hasn’t been instructed to do this as a default; it takes aggressive prompting of Llama to do this.

The transparency has also provided a PR black-eye to OpenAI, which has so far hidden its chains of thought from users, citing competitive reasons and not to confuse users when a model gets something wrong. Transparency allows developers to pinpoint and address errors in a model’s reasoning, streamlining customizations to meet enterprise requirements more effectively.

For enterprise decision-makers, DeepSeek’s success underscores a broader shift in the AI landscape: leaner, more efficient development practices are increasingly viable. Organizations may need to reevaluate their partnerships with proprietary AI providers, considering whether the high costs associated with these services are justified when open-source alternatives can deliver comparable, if not superior, results.

To be sure, no massive lead

While DeepSeek’s innovation is groundbreaking, by no means has it established a commanding market lead. Because it published its research, other model companies will learn from it, and adapt. Meta and Mistral, the French open source model company, may be a beat behind, but it will probably only be a few months before they catch up. As Meta’s lead researcher Yann Lecun put it: “The idea is that everyone profits from everyone else’s ideas. No one ‘outpaces’ anyone and no country ‘loses’ to another. No one has a monopoly on good ideas. Everyone’s learning from everyone else.” So it’s execution that matters.

Ultimately, it’s the consumers, startups and other users who will win the most, because DeepSeek’s offerings will continue to drive the price of using these models near zero (again aside from cost of running models at inference). This rapid commoditization could pose challenges – indeed, massive pain – for leading AI providers that have invested heavily in proprietary infrastructure. As many commentators have put it, including Chamath Palihapitiya, an investor and former executive at Meta, this could mean that years of OpEx and CapEx by OpenAI and others will be wasted.

There is substantial commentary about whether it is ethical to use the DeepSeek-R1 model because of the biases instilled in it by Chinese laws, for example that it shouldn’t answer questions about the Chinese government’s brutal crackdown at Tiananmen Square. Despite ethical concerns around biases, many developers view these biases as infrequent edge cases in real-world applications – and they can be mitigated through fine-tuning. Moreover, they point to different, but analogous biases that are held by models from OpenAI and other companies. Meta’s Llama has emerged as a popular open model despite its data sets not being made public, and despite hidden biases, and lawsuits being filed against it as a result.

Questions abound around the ROI of big investments by OpenAI

This all raises big questions about the investment plans pursued by OpenAI, Microsoft and others. OpenAI’s $500 billion Stargate project reflects its commitment to building massive data centers to power its advanced models. Backed by partners like Oracle and Softbank, this strategy is premised on the belief that achieving artificial general intelligence (AGI) requires unprecedented compute resources. However, DeepSeek’s demonstration of a high-performing model at a fraction of the cost challenges the sustainability of this approach, raising doubts about OpenAI’s ability to deliver returns on such a monumental investment.

Entrepreneur and commentator Arnaud Bertrand captured this dynamic, contrasting China’s frugal, decentralized innovation with the U.S. reliance on centralized, resource-intensive infrastructure: “It’s about the world realizing that China has caught up — and in some areas overtaken — the U.S. in tech and innovation, despite efforts to prevent just that.” Indeed, yesterday another Chinese company, ByteDance announced Doubao-1.5-pro, which Includes a “Deep Thinking” mode that surpasses OpenAI’s o1 on the AIME benchmark.

Want to dive deeper into how DeepSeek-R1 is reshaping AI development? Check out our in-depth discussion on YouTube, where I explore this breakthrough with ML developer Sam Witteveen. Together, we break down the technical details, implications for enterprises, and what this means for the future of AI:
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Practical quantum computers are over a decade away, says NEC

A practical, commercial quantum computer is over a decade away, executives at Japanese IT services company NEC are reported as saying. That’s why, according to Japanese news publication The Mainichi, company has pulled the plug on its plans to develop a quantum computer — although it will still continue research

Read More »

Huawei aims to deliver faster AI chips, faster

Huawei is accelerating its AI chips development, bringing forward the release of the next two models in the family powering its AI computing clusters by three to nine months. Its Ascend 960 chip family is a major component of supercomputing portfolio. It now plans to release the Ascend 960DT in

Read More »

Energy Department Announces $99 Million for 21 Projects to Advance U.S. Geothermal Energy Development

WASHINGTON—The U.S. Department of Energy (DOE) today announced more than $99 million for 21 projects selected to advance geothermal energy development across the United States. The projects will conduct field-scale tests of next-generation geothermal technologies and exploration drilling to characterize and potentially confirm promising geothermal resources.  Thanks to President Trump’s leadership, the Energy Department is advancing American geothermal innovation to unlock the nation’s abundant domestic energy resources. Geothermal can provide reliable, around-the-clock power to help meet growing demand while strengthening U.S. energy security. “These projects will empower American innovators to unlock the tremendous geothermal resources beneath our feet,” said DOE Under Secretary of Energy Kyle Haustveit. “Under President Trump’s leadership, we’re advancing next-generation geothermal technologies that can lower costs, strengthen American energy dominance, and turn more of our vast domestic geothermal resources into reliable and affordable power.” The 21 projects will advance geothermal development in two key areas. Five projects will conduct field-scale enhanced geothermal systems (EGS) tests to validate technologies under real-world conditions, while 16 additional projects will conduct exploration drilling to identify and characterize promising next-generation geothermal resources. Together, these efforts will help reduce technical and development risk and provide the information needed to support future commercial projects and investment.   Data generated by these projects will be publicly available through DOE’s Geothermal Data Repository (GDR), giving industry, researchers, and other stakeholders access to information from the field tests and geothermal exploration activities. Making these data available can extend the value of the projects beyond individual sites by helping inform future technology development and geothermal exploration across the industry.  Learn more about the selected projects here.  Selection for award negotiations is not a commitment by DOE to issue an award or provide funding. Before funding is issued, DOE and the applicants will undergo a negotiation process, and DOE may cancel negotiations and rescind the

Read More »

INA commissions new delayed coker at Rijeka refinery

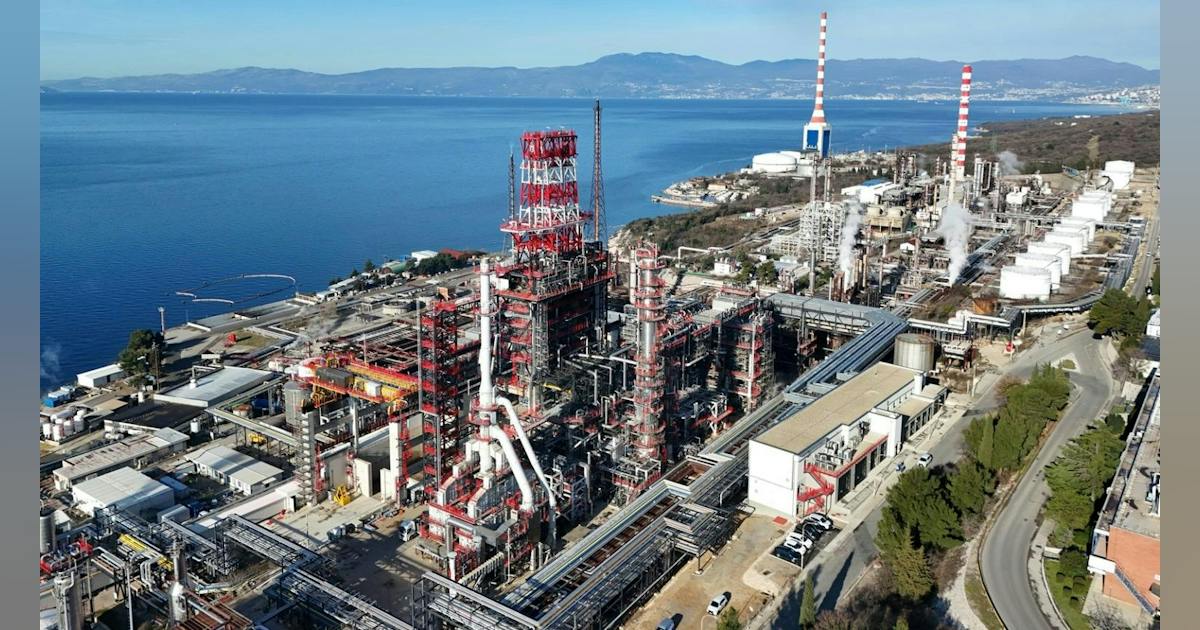
Croatia’s INA Industrija Nafte DD has started up a new delayed coking unit (DCU) at its 90,000-b/d Rijeka refinery along the northern part of the Adriatic Sea, marking a major milestone in the refinery’s upgrading project. Following mechanical completion and commissioning, INA introduced feedstock into the DCU on Sept. 1, beginning production, majority owner MOL Group said in a release Sept. 21. The unit has operated continuously since startup and has reached about 70% of design capacity, the company said. The DCU—which  converts heavy refinery residues into higher-value products—has produced all key products at required quality and is anticipated to increase diesel production by as much as 30% from the same crude volume. MOL Group said the new DCU unit—once fully operable—also will eliminate Croatia’s need to import vacuum gas oil (VGO). The Rijeka refinery upgrade represents an investment of nearly €700 million, which is included in a combined €1.3-billion joint investment by INA and MOL Group in refining and logistics modernization during the past 12 years. “The start-up of the new unit went really well,” said Zsuzsanna Ortutay, president of INA’s management board, adding that the DCU would improve the sustainability and profitability of INA’s refining business while supporting energy supply in Croatia and the surrounding region. INA  plans to increase throughput and optimize process performance at the new unit gradually, with stable operation anticipated by yearend, followed by final plant performance testing and project closeout activities. Rijeka DCU project background INA awarded a lump-sum, turnkey engineering, procurement, and construction contract for the project to Maire Tecnimont SPA subsidiary KT-Kinetics Technology SPA in December 2019. The contract covered a new delayed coking complex with coke handling and ship-loading facilities, a sour-water stripper, and amine recovery units. It also included modifications to the existing hydrocracker, sulfur recovery unit, utilities, and

Read More »

Oil prices retreat as Middle East supply concerns ease amid diplomatic talks

Oil prices fell on Monday, Sept.21, with Brent extending its retreat from recent highs, as recovering Saudi crude exports and hopes for renewed US-Iran diplomacy eased fears of an immediate Middle East supply crunch. Brent crude futures and US West Texas Intermediate (WTI) crude dipped below $100/bbl to their lowest since Sept. 9. The move extends a four-session retreat from the recent surge in crude prices as traders reassess how severely regional conflict is constraining physical oil flows. Despite the continued uncertainty in the Middle East, news of a major rebound in Saudi crude oil exports in September weighed on prices. Saudi Arabia has increased shipments through the Strait of Hormuz to compensate for disruptions to its East-West pipeline following Houthi attacks on Saudi energy infrastructure. Saudi crude flows through the strait have averaged roughly 2.9 million b/d over the past 6 days, compared with about 700,000 b/d in August, according to satellite data cited by JPMorgan analysts. US Central Command Commander Admiral Brad Cooper confirmed on Sept.19 that, thanks to US naval escorts and mine-clearance efforts, oil and LNG shipments through the Strait of Hormuz in the past 2 weeks reached the highest level in 6 months. The recovery in Gulf exports has helped ease fears that attacks on Saudi infrastructure would translate into a prolonged loss of barrels from the global market. Meanwhile, investors are closely monitoring signs of potential diplomatic progress between Washington and Tehran during this week’s UN General Assembly. US President Donald Trump has expressed a willingness to meet with Iranian President Masoud Pezeshkian, while Iran has reportedly conveyed the conditions for resuming negotiations. Expectations that talks could eventually reduce regional tensions have removed some of the geopolitical risk premium that pushed crude prices higher earlier this month. Still, physical oil markets remain strained. Middle Eastern producers

Read More »

Trump Administration Moves to Keep Indiana Coal Plants Operating to Support Grid Reliability

WASHINGTON—U.S. Secretary of Energy Chris Wright issued emergency orders to keep two Indiana coal plants operational to ensure Americans in the Midwest region of the United States have continued access to affordable, reliable, and secure electricity. The orders direct the Northern Indiana Public Service Company (NIPSCO), CenterPoint Energy, and the Midcontinent Independent System Operator, Inc. (MISO) to take all measures necessary to ensure specified generation units at both the R.M. Schahfer and F.B. Culley generating stations in Indiana are available to operate. Certain generation units at these coal plants were scheduled to shut down at the end of 2025.  The orders will minimize the risk of unnecessary blackouts for the American people. Since the U.S. Department of Energy’s (DOE) original orders were issued on December 23, 2025, the Schahfer and Culley coal plants have proven critical to MISO’s operations, operating during periods of high energy demand and low levels of intermittent energy production, including during Winter Storm Fern.   “Forcing reliable, dispatchable coal generation off the grid would compromise energy reliability and needlessly raises energy costs for Americans,” said Energy Secretary Wright. “Midwestern families should not be forced to pay the price for the misguided energy subtraction policies of the past. They deserve affordable, reliable, and secure energy, regardless of the wind blowing or the sun shining.” Thanks to President Trump’s leadership, coal generating plants across the country are being saved from premature retirement. For example, in 2025, more than 17 gigawatts of coal power electricity generation were saved from going offline.  The availability of R.M. Schahfer and F.B. Culley generating stations to operate will continue to be an asset to maintain reliability in the MISO region and is necessary to address elevated reliability risks in that region during extreme weather and reduce the risk of power outages that could threaten public health and safety. As

Read More »

Energy Secretary Secures Carolinas’ Grid Amidst Hot Weather Conditions

WASHINGTON—The U.S. Department of Energy (DOE) issued an emergency order to mitigate the risk of blackouts in the Carolinas amid hot weather conditions. Issued pursuant to Section 202(c) of the Federal Power Act, the order authorizes Duke Energy Carolinas, LLC (Duke) to dispatch specified resources and to order their operation as needed to maintain reliability. The order also authorizes Duke, in collaboration with its Transmission Owners, to direct backup generation resources to operate as a last resort before declaring an Energy Emergency Alert (EEA) 3 or during an EEA 3. This order was issued pursuant to an application from Duke submitted on September 18, 2026. “Today’s order will help secure reliable electricity access for millions of American families and businesses across North and South Carolina by making additional power generation, including backup power, available to use as needed,” said U.S. Secretary of Energy Chris Wright. “It should come as no surprise that during the end of summer and early fall, there are fewer hours of daylight—and therefore, less power generation from solar power. The North American Electric Reliability Corporation and others have warned of the potential dangers late summer temperature spikes can pose to the grid when leaders prematurely retire reliable power sources. While past leaders’ energy subtraction policies have made the grid more vulnerable to blackouts when the sun doesn’t shine or the wind doesn’t blow, this administration remains committed to using every available tool to prevent blackouts.”  DOE estimates more than 35 GW of unused backup generation remains available nationwide.  The order is in effect upon issuance on September 18, 2026, through September 21, 2026. 

Read More »

Enbridge launches open season for West Texas Express natural gas pipeline

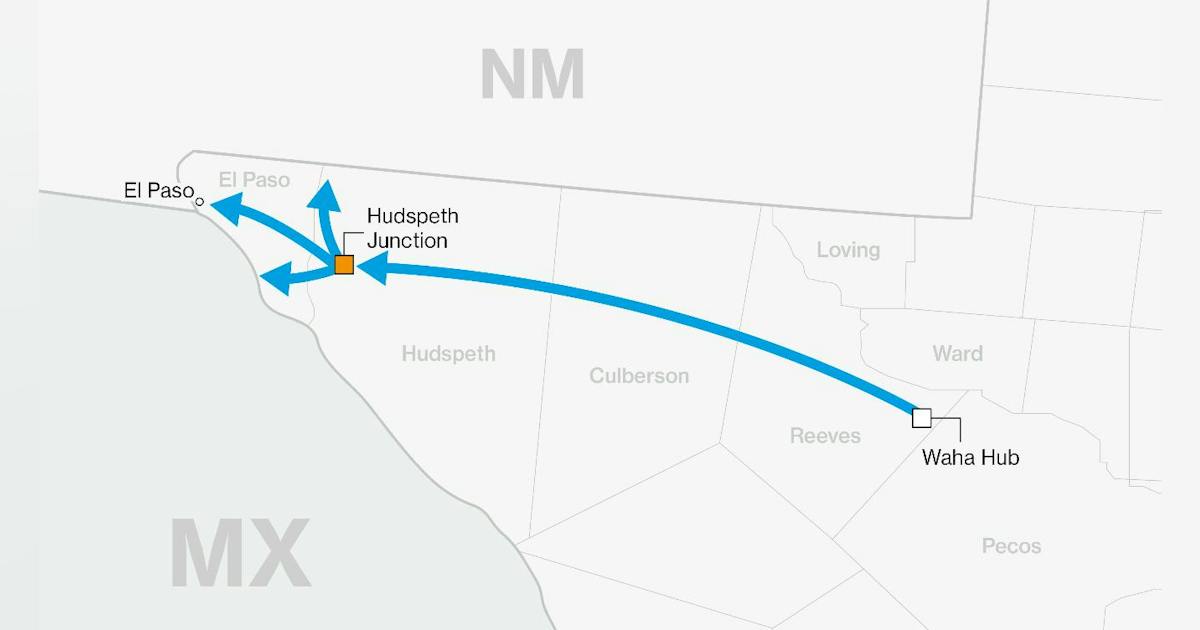
Enbridge has launched a non-binding open season for its proposed 2-bcfd West Texas Express (WTX) natural gas pipeline project, designed to transport Permian basin supply west from the Waha area to markets in and around El Paso, Tex. The proposed project responds to growing demand for reliable natural gas supplies from proposed power generation, utilities, generators, and industrial customers such as data centers across west Texas and downstream markets in Mexico, New Mexico, and Arizona, Enbridge said. WTX is currently expected to include more than 150 miles of new 42-in. OD pipeline. The project could also include laterals serving Hudspeth County, Tex., and delivery points at the US-Mexico border. Enbridge said WTX can be designed to connect with existing pipeline infrastructure based on customer requirements identified through the open season. Final capacity, routing, receipt and delivery points, and system design will be informed by market interest. Subject to securing sufficient commercial support and obtaining required approvals, Enbridge is targeting a fourth-quarter 2029 in-service date. The open season will close at 5 p.m. CDT, Sept. 25, 2026. Enbridge last week agreed to acquire Tallgrass Energy LP’s crude oil business for $2.55 billion in cash.

Read More »

Communities are blocking data centers before they’re even proposed

“Dismissing fears around water consumption, for example, by showing a spreadsheet at a local planning committee meeting, doesn’t resolve concerns for a community that is already suspicious,” he said. Community opposition “is real, and it’s everywhere,” and the new strategic pillar for data center builders and operators is social outreach, Kimball noted. Those proposing data centers must be able to provide credible answers about usage and community impacts, listen to concerns, and commit to transparency. Most enterprises aren’t building gigawatt campuses, he pointed out, but they are paying the price downstream in colocation availability, lead times, pricing, and other factors. Predictability is the big question, supply is already tight, and every delayed project removes capacity factored into forecasts.

Read More »

Data Centre West 2026: Alberta Moves From Data Center Ambition to Execution

Firm Power Is an Architecture That brought the morning back to its recurring problem: What counts as available power? During the “Solving for Power” panel, moderator Lillian Kasa of Metlen Energy & Metals argued that data centers cannot operate on announcements. They need reliable electricity delivered on a schedule and backed by a commercial structure that can be financed. Margarita Patria of Charles River Associates made the distinction even sharper. Firm power is not merely generation. It is generation, transmission and fuel availability working together. Todd Detling of FortisAlberta added an important Alberta-specific qualification. Despite perceptions that the province had substantial transmission capacity available for new development, FortisAlberta is encountering constraints, particularly around the Edmonton and Calgary fringes. At the distribution level, the demand is already material. Detling said FortisAlberta has connected nearly 80 MW of data center load over the past several years, has approximately another 80 MW in the build queue, and has received roughly 300 MW in additional requests. Those smaller increments matter in a market dominated rhetorically by gigawatt announcements. They are another indication that developers are searching for power pathways they can execute now. AI Is Not Just a Bigger Load Tesla’s Sean Jones added another technical wrinkle: AI training loads can change extremely quickly. Data center power planning traditionally focuses heavily on annual consumption, peak demand and hourly load. GPU clusters can create significant changes at the second or even sub-second level. Jones described AI training demand falling from full load to around 30% in less than a second. That kind of movement can be difficult for onsite turbines and reciprocating generators to follow and potentially disruptive to the grid. Battery energy storage is therefore taking on a different role. The familiar data center battery story is backup power. The emerging AI story is

Read More »

Local AI is getting small enough to make every app multilingual

On-device translation used to mean a separate model for every language you wanted to support. English to French, English to German, and so on. However, that becomes unsustainable at a global scale when you’re talking about thousands of possible language pairs. Add to that the fact that most developers have to either send translation requests to the cloud to get fast, accurate results, or keep it local with restricted language support. Tether’s AI Research team has developed a family of multilingual translation models, TranslatePsy-EuroNano, that each support nine European languages, with deployment built around a pair of multilingual models rather than separate bilingual models for every language pair. What makes this possible Supporting a full European market on-device has previously meant bundling dozens of separate model files, but this is impractical for mobile apps and those building them. Tether AI’s multilingual open‑source edge translation models set the standard for efficiency, quality, and speed. For developers, the possibilities are endless. Using English as a pivot, the models remain comparable to Mozilla Firefox’s Bergamot-based translation system while dramatically reducing the size of on-device translation. At its smallest tier, Tether’s deployment is 17.6 times smaller while maintaining comparable translation quality. Tether’s deployment takes up 36MB to 89MB, depending on the tier you use. By comparison, the equivalent Firefox setup requires 18 separate bilingual models totaling 633MB to provide the same language coverage. The models are small enough to run efficiently on edge devices while supporting nine European languages from a single multilingual deployment, making multilingual experiences practical for a much wider range of software. Potential applications include travel and navigation apps, educational platforms that present lessons and resources on-device. The models are also designed for academics and researchers. Because the weights are openly available, researchers can fine-tune them for specialized domains, like customer

Read More »

AI Infrastructure Is Redrawing the Data Center Services Landscape

For gigawatt-scale AI developments, the developer may be involved with substations, transmission interconnections, generation plants, batteries or other behind-the-meter infrastructure long before servers arrive. Solaris now describes its overall portfolio as including generation, distribution, installation and commissioning, aftermarket support, and operations and maintenance. The arrival of companies with roots in energy and heavy industrial services suggests that the data center supplier base itself is changing as projects begin to resemble large industrial infrastructure developments. The Pattern Extends Across the Services Stack The transactions involving T5, Limbach, JK Technology Services and Solaris are hardly isolated. A wider wave of acquisitions and partnerships is pushing equipment manufacturers, contractors, engineering firms and specialist service providers toward broader roles across the data center lifecycle. Vertiv provided perhaps the clearest parallel in September, announcing an agreement to acquire UtilityInnovation Group for approximately $1.45 billion in cash, with additional consideration tied to performance. UIG brings microgrid controls, onsite-generation orchestration, specialized switchgear and behind-the-meter power architecture. The deal also extends a broader 2026 acquisition push by Vertiv that has added liquid-cooling specialist Strategic Thermal Labs, chiller manufacturer ThermoKey and prefabricated infrastructure provider Bmarko as the company builds out more of the AI data center infrastructure stack. Vertiv described the move as extending its portfolio upstream from the critical power and cooling systems inside the facility toward the grid interconnection and onsite generation itself — effectively creating a path from power source to chip. Days later, Flex announced a $4.4 billion agreement to acquire EPC Power, adding grid-forming and power-conversion technology designed for data centers, utility-scale energy storage and microgrids. EPC Power’s platform includes rectifiers and DC-DC conversion for emerging 800-volt data center architectures, with solid-state transformer development also planned. The company says it has more than 15 GW deployed across 62 countries and expects its annual U.S.

Read More »

From Announcements to Delivery: What Separates Real AI Data Center Projects From the Rest

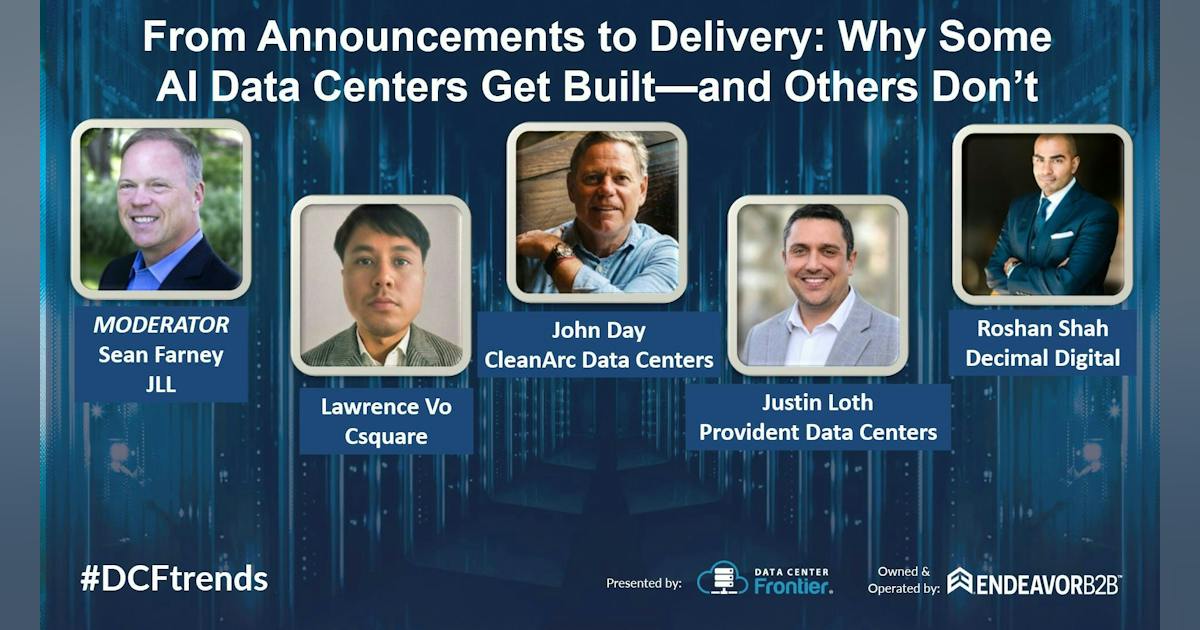
The AI infrastructure market has become very good at announcing gigawatts. Delivering them is another matter. That distinction framed one of the closing sessions of Day 1 at the Data Center Frontier Trends Summit 2026 (Aug. 4-6), where Sean Farney, vice president of data center strategy at JLL and a member of the Data Center Frontier Editorial Advisory Board, moderated a discussion on why some AI data center projects advance from concept to construction while others remain little more than ambitious site plans. Farney was joined by Lawrence Vo, vice president of M&A and capex at Csquare; John Day, chief commercial officer at CleanArc Data Centers; Justin Loth, executive director of power development at Provident Data Centers; and Roshan Shah, co-founder and CEO of Decimal Digital. The question Farney put before the group was straightforward: amid a market moving at what he called “the speed of light,” what separates the developers that actually get projects done from those that do not? The answers repeatedly came back to the same point. In the current market, land, capital and an announcement are no longer enough. Developers have to prove that power is deliverable, infrastructure is ready, regulatory processes are moving, communities are receptive, talent is available and the commercial model can withstand changing conditions. A Gigawatt on Paper Is Not a Gigawatt of Capacity For Loth, who spent roughly 15 years on the utility side before joining Provident, the scale of current data center proposals alone should force the industry to think differently about what constitutes a credible project. Before the hyperscale and AI expansion, he noted, gigawatts were a measure more commonly associated with cities than individual loads. “A 3.5 gigawatt campus,” Loth said, is roughly equivalent to the native load of Austin or San Antonio. That scale makes the distinction

Read More »

The Future of Data Centers: Biomimicry and Community-Centric Design

As a result, Microsoft has said six additional data centers planned in the region are being designed around biomimicry principles rather than treating landscaping as something added after the engineering work is finished. The change, from landscaping as decoration to ecology as a design input, is now being applied elsewhere. There is already a significant US example, set in Mecklenburg County, Virginia, where Microsoft originally announced the Chase City Conservancy in 2022, as part of a data center development south of Chase City. The completed project, which opened in April 2025, protects more than 230 acres from development. It includes more than eight acres of wetlands, over 16,300 linear feet of restored streams, 185 acres of native pollinator habitat, more than 25,000 planted trees and over three miles of publicly accessible walking trails. Local environmental organizations helped shift the design away from what the company describes as a more conventional recreational area toward biodiversity and habitat conservation illustrating the community-engagement side of Microsoft’s model, which, given the current temperature of such relationships, can’t be understated. For data center developers, that may be as important as the ecological results. Community impact is no longer being evaluated on just tax revenue and jobs. Turning portions of a site into protected wetlands, forests, trails or habitat potentially creates a visible local benefit in ways that renewable-energy contracts hundreds of miles away cannot. Microsoft’s commitment to the local community has been led by their Community First AI Infrastructure Plan announced in January 2026. Wetlands in Wisconsin, Screening in Georgia At Microsoft’s massive Mount Pleasant, Wisconsin, AI data center development, the company is working with the Root-Pike Watershed Initiative Network on restoration projects involving wetlands, native prairie and forested riparian buffers. One element involves returning previously straightened streams to more natural, winding channels, improving aquatic

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »