Stay Ahead, Stay ONMINE

More capability, less equipment: the future of capacitor bank control

As utilities work to expand system capacity and improve power quality, one challenge continues to surface: how to add capability without adding more equipment, more maintenance and more space. Traditionally, capacitor bank applications require multiple devices to perform separate functions. One device energizes and de-energizes the bank. Another provides protection. Additional equipment may be required […]

As utilities work to expand system capacity and improve power quality, one challenge continues to surface: how to add capability without adding more equipment, more maintenance and more space.

Traditionally, capacitor bank applications require multiple devices to perform separate functions. One device energizes and de-energizes the bank. Another provides protection. Additional equipment may be required to manage switching transients and inrush currents.

Today’s advanced medium-voltage breaker technology changes that equation.

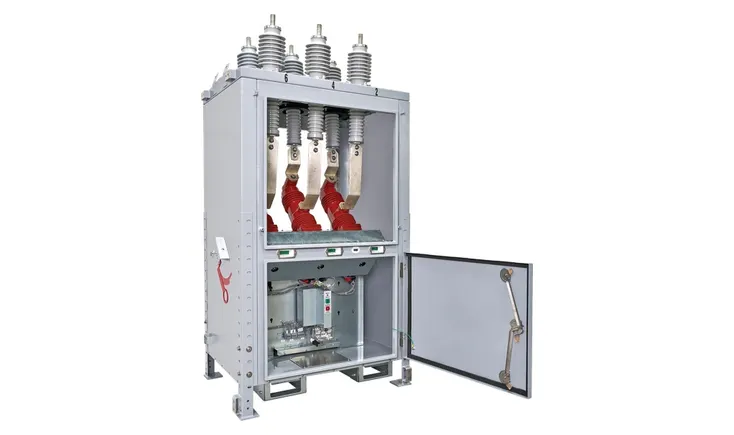
By combining point-on-wave switching and protection in a single breaker, utilities can eliminate separate switching devices while maintaining precise capacitor bank control. The result is a simpler installation with fewer components, a smaller footprint and lower overall system complexity.

More functionality in less footprint

In many substations, available space has become a valuable asset. Adding new equipment often means expanding infrastructure, increasing costs or limiting future growth.

Advanced breaker technology can serve as both the energizing device and the protection device for capacitor banks, eliminating the need for separate switching equipment between the breaker and the bank.

With fewer devices installed in the yard, utilities can:

  • Reduce substation footprint
  • Simplify installation and commissioning
  • Lower equipment and maintenance costs
  • Create room for future expansion
  • Improve overall system reliability

Rather than adding more components to solve power quality challenges, utilities can accomplish more with less equipment.

Consistent performance in real-world conditions

Modern utility equipment is increasingly being asked to operate in environments that are far different from traditional indoor substations. Installations may be exposed to extreme temperatures, dust, humidity and rapidly changing operating conditions.

Conventional switching technologies often depend on highly controlled operating conditions and precise timing. Variations in voltage supply, temperature or environmental conditions can impact performance.

New actuator and control technologies provide highly repeatable operating performance regardless of environmental conditions. Whether deployed in a hot industrial facility, an outdoor substation or a region with significant temperature swings, the breaker delivers the same switching performance time after time.

This operating consistency helps utilities improve reliability while reducing concerns about environmental impacts on equipment operation.

A new approach to capacitor bank control

Point-on-wave switching provides another significant advantage by minimizing the transients typically associated with capacitor bank energization.

When switching occurs at the optimal point on the voltage waveform, utilities can reduce inrush currents and power quality disturbances that may otherwise require additional mitigation equipment, significantly reducing transient and ripple effects over conventional switching.

Because the breaker itself provides both switching and protection functions, utilities can simplify capacitor bank designs while achieving better overall performance.

Configured as either single- or three-phase operation, the breaker can switch individual phases independently when the application requires it. This flexibility helps utilities better manage faults, improve power quality and maintain service continuity in situations where traditional three-pole operations would interrupt more customers, potentially improving SAIDI & SAIFI scores by as much as 70 percent.

Building smarter systems

Utilities are under increasing pressure to improve reliability metrics, increase system flexibility and support growing energy demands without dramatically expanding infrastructure.

The most effective solutions are often not the ones that add more equipment. They are the ones that allow existing systems to do more with fewer components.

By combining protection, capacitor bank switching, transient mitigation and advanced control capabilities into a single platform, utilities can reduce complexity, improve reliability and create space for future growth, all while delivering better service to customers.

Working with a trusted future-forward partner who understands both the demands of new modern infrastructure and how to upgrade legacy installations is critical to this transition.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Aker BP, Höegh Evi secure EU funding for Atlas CCS project

Aker BP and Höegh Evi have been awarded €223 million (about US$250 million) from the European Union Innovation Fund to support development of the Atlas carbon capture and storage (CCS) project in Norway. The Atlas project is designed as a large-scale CCS network linking industrial CO2 emitters in Europe with

Read More »

Extreme wants to use idle network compute capacity for local AI

“We’ve spent decades building networks that reach every corner of the enterprise, and those networks hold a lot of idle compute. Exchange zones will put that compute to work, letting AI run locally on infrastructure customers already own. That delivers sovereignty, local inferencing, and better economics than sending everything to

Read More »

When does a BI value stop being the right number?

For energy companies, the assumptions behind a BI value can change materially during the policy period. Margins and throughput can shift, while repair timelines can extend. External events can also change the economics of an operation quickly. Yet the declared BI value and the policy provisions governing recovery may remain unchanged. This raises a practical question: what should trigger a reassessment, and how will the policy respond if the exposure has changed materially? A BI value has a shelf life A BI calculation draws on assumptions about revenue, margins, production, throughput, fixed costs and recovery time. Those inputs can change at different rates and for different reasons. For a downstream operator, a significant movement in crack spreads can change the earnings exposure associated with an interruption. For a midstream operation, a change in throughput or a prolonged constraint on a critical pipeline can alter the financial impact. Across the energy value chain, an extended repair or recovery period can materially increase the duration of a loss. Organizations should establish materiality thresholds for reassessment, supported by a consistent methodology for revisiting the valuation when conditions change. Where a material change increases exposure, organizations may also need to consider whether to redeclare their values. Aon’s approach to business interruption valuation provides a methodology for reassessing the valuation when material changes occur. The percentage on a volatility clause tells only part of the story A stated volatility allowance can overstate the protection available if the exposure has increased materially or operations resume during the recovery period. The Lloyd’s Market Association introduced an updated Onshore Energy BI Volatility Clause in 2024 after carriers identified the previous version as unsuitable for partial losses. The revised clause was intended to address the policy’s indemnity exposure in those circumstances. Organizations should model the provision against realistic loss

Read More »

More capability, less equipment: the future of capacitor bank control

As utilities work to expand system capacity and improve power quality, one challenge continues to surface: how to add capability without adding more equipment, more maintenance and more space. Traditionally, capacitor bank applications require multiple devices to perform separate functions. One device energizes and de-energizes the bank. Another provides protection. Additional equipment may be required to manage switching transients and inrush currents. Today’s advanced medium-voltage breaker technology changes that equation. By combining point-on-wave switching and protection in a single breaker, utilities can eliminate separate switching devices while maintaining precise capacitor bank control. The result is a simpler installation with fewer components, a smaller footprint and lower overall system complexity. More functionality in less footprint In many substations, available space has become a valuable asset. Adding new equipment often means expanding infrastructure, increasing costs or limiting future growth. Advanced breaker technology can serve as both the energizing device and the protection device for capacitor banks, eliminating the need for separate switching equipment between the breaker and the bank. With fewer devices installed in the yard, utilities can: Reduce substation footprint Simplify installation and commissioning Lower equipment and maintenance costs Create room for future expansion Improve overall system reliability Rather than adding more components to solve power quality challenges, utilities can accomplish more with less equipment. Consistent performance in real-world conditions Modern utility equipment is increasingly being asked to operate in environments that are far different from traditional indoor substations. Installations may be exposed to extreme temperatures, dust, humidity and rapidly changing operating conditions. Conventional switching technologies often depend on highly controlled operating conditions and precise timing. Variations in voltage supply, temperature or environmental conditions can impact performance. New actuator and control technologies provide highly repeatable operating performance regardless of environmental conditions. Whether deployed in a hot industrial facility, an outdoor substation

Read More »

The push to DC: Why data centers are rethinking power architecture

As rack densities climb toward 1 MW and beyond, traditional low-voltage alternating current (AC) architecture is being pushed into territory it wasn’t originally designed to handle. A primary reason the industry is increasingly looking toward 800 VDC to support the next generation of high-density compute.  But the bigger question isn’t whether direct current (DC) can power these new racks. It’s where the conversion to DC should happen and how much of the traditional power architecture is still necessary.  Sidecars offer a bridge to 800 VDC  One near-term answer is the sidecar, a power-conversion unit positioned next to the compute rack.  Sidecars give operators a practical way to introduce 800 VDC racks into facilities built around existing low-voltage AC distribution. Rather than redesigning the facility, operators can convert AC power to DC beside the rack.  That makes sidecars an important bridge between today’s infrastructure and emerging DC compute. But much of the existing electrical architecture remains in place. Power still moves through transformers and low-voltage UPS infrastructure before another conversion takes place near the rack.  Each stage introduces losses and nearly all of that lost energy ultimately turns into heat, putting more pressure on the cooling system to remove it.    SMA’s white paper models the difference. In the architecture studied, delivering 1 MW through a traditional AC system with rack-level conversion results in approximately 80 kW of power loss per megawatt delivered to the rack. Converting medium-voltage AC to 800 VDC outside the building and distributing DC directly reduces that loss to approximately 20 kW.  At data center scale, the difference becomes more than significant.  Moving power infrastructure outside  Efficiency is only part of the equation. Data center operators are also under pressure to maximize one of their most valuable resources: white space.  A native DC architecture takes a different approach.

Read More »

Inside the resilience gap

Utilities do not need research to tell them the operating environment has become more demanding. They see it in the systems they manage, the investment decisions they make and the expectations customers and regulators place on them. New research helps quantify that experience. Three in four utility and energy industry professionals surveyed for the 2026 State of Grid Resilience say operational risk is higher than it was five years ago. More than half expect load growth on their distribution systems to be very or extremely significant over the next decade. Nearly four in five expect resilience-related investment to increase over the next five years. At the same time, 61% identify affordability and customer rate pressure as the biggest barrier to accelerating that investment. Taken together, the findings show a challenge utilities have navigated for years. They are committed to resilience, but how resilience is measured, funded and deployed can affect how quickly they can act. Measuring performance under stress Utilities already recognize a distinction between reliability and resilience. Nearly half of respondents define reliability as day-to-day operational performance and resilience as performance under disruption. The measures guiding investment do not always reflect that distinction. Traditional reliability metrics such as SAIDI, SAIFI and CAIDI provide an important and consistent view of everyday grid performance. But only 48% of respondents agree that current reliability metrics adequately capture performance during major disruptive events. The difference becomes clearer when utilities are asked what matters during those events. More than half say restoring service as quickly as possible is the most important outcome during a major storm or disruption. When asked what best demonstrates a resilient grid, respondents first point to limiting the number of customers affected and quickly restoring normal operations. Yet investment decisions remain weighted toward traditional reliability. SAIDI and customer outage frequency

Read More »

Kazakhstan and Guyana Join International Coalition Calling for Delay of EU Methane Regulation

WASHINGTON — Kazakhstan and Guyana have joined Algeria, Nigeria, Qatar, and the United States in calling on the European Union to delay implementation of, and make targeted changes to, the EU Methane Regulation (EUMR), removing unnecessary barriers to energy exports into Europe while ensuring a workable compliance framework. This approach would provide greater regulatory certainty for energy suppliers, including for American producers and exporters.  “American energy exports play a vital role in supporting our allies and driving economic growth,” said U.S. Department of Energy Assistant Secretary for International Affairs Kaveh Farzad. “The growing coalition on this initiative underscores the importance of a pragmatic approach that provides regulatory certainty and ensures reliable energy continues to reach our European allies.” The U.S. Department of Energy recognizes the action by the European Parliament to advance a three-year delay of EUMR implementation as a step forward and encourages swift final adoption of this measure through trilogue negotiations between the European Parliament, Council, and Commission.  The expanded coalition of critical crude oil and natural gas suppliers urges EU leaders to address significant gaps in the regulation’s reporting, verification, and compliance framework. Continued delays in establishing these requirements leave energy producers and importers without the clarity and certainty they need to comply, putting Europe’s energy security, competitiveness, and access to reliable energy supplies at risk.  The six signatories represent a broad and geographically diverse group of energy suppliers to Europe. In 2025, Kazakhstan, the United States, Nigeria and Guyana together accounted for roughly 37% of EU crude-oil imports by volume, while Algeria, Qatar, Nigeria and the United States were collectively responsible for approximately nearly 50% of EU natural gas imports, including LNG.  These figures underscore the importance of ensuring that the EUMR strengthens methane performance without inadvertently restricting access to diverse sources of energy.  Kazakhstan and Guyana join the initiative launched in

Read More »

Equinor lets Wisting FPSO topsides FEED contract to Aibel

@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } <!–> Equinor Energy AS awarded Aibel a front-end engineering and design (FEED) study contract covering topside modules for the proposed floating production, storage, and offloading (FPSO) vessel for Wisting field development in the Barents Sea. The contract includes FEED work and further maturation of the FPSO topsides design to support the Wisting partners’ project execution decision. It also contains an option for engineering, procurement, and project management (EPma) services. Any contract for fabrication of the topside modules would be awarded later, Equinor said. Work will begin immediately and is scheduled for completion in late 2027. The FEED study will form part of the basis for the Wisting license partners’ planned investment decision in late 2027. Equinor and partners plan to decide on concept selection and the project’s further progression by yearend 2026. “We are at an early stage in the development of Wisting, and considerable work remains to develop a project that is profitable and feasible,” said Trond Bokn, Equinor’s senior vice-president for project development. ]–> <!–> –> <!–> Dec. 2, 2019 ]–> <!–> –> <!–> April 22, 2024 ]–> <!–> –> <!–> May 21, 2026 ]–> Wisting Wisting, discovered in 2013 in the Hoop area of the Barents Sea about 310 km north of Hammerfest, is the largest oil discovery on the Norwegian continental shelf yet to be developed. The field contains estimated recoverable resources of just under 500 MMboe. Water depths across the development area are 390-418 m. In July, Equinor submitted for public consultation

Read More »

NVIDIA’s DSX POD Pushes AI Factory Construction Toward the Assembly Line

Crusoe Brings an Established Modular Model to DSX POD For Crusoe, NVIDIA’s announcement builds on a modular computing strategy already in operation. In its October 21 announcement, Crusoe confirmed that its Spark modular AI data center platform will support DSX POD, extending a manufacturing and deployment approach the company says it has pursued since 2020. Crusoe has expanded its manufacturing capabilities through the acquisition of electrical equipment specialist Easter-Owens Electric and the development of its 352,000-square-foot Crusoe Spark Factory in Brighton, Colorado. The company also introduced Crusoe Spark Liquid, a sixth-generation modular system engineered for ultra-high-density infrastructure, including NVIDIA Vera Rubin NVL72. Next-generation liquid-cooled units are planned for 2027. Crusoe’s vertically integrated model connects infrastructure design and manufacturing with deployment and cloud operations through Crusoe Cloud. The company says it can deliver productive AI capacity in as little as three months, although that timeline is distinct from NVIDIA’s narrower 14-day prepared-site deployment claim. “Modular isn’t a new strategy or pivot for us. It’s been in our DNA since our founding,” said Bryan Schramm, Crusoe’s head of Spark. Crusoe’s involvement demonstrates that the manufacturing model predates DSX POD. NVIDIA is not inventing modular data center infrastructure; it is attempting to establish a common architecture around capabilities that suppliers such as Crusoe have already spent years developing. That distinction matters as the industry evaluates whether standardized AI factory designs can deliver manufacturing efficiencies at a scale beyond individual suppliers’ existing operations. Vertiv and Polar Put the Deployment Model to Work in Norway The European dimension of NVIDIA’s announcement is reflected in a deployment involving Vertiv and Polar Data Centers at Herøya, Norway. According to Vertiv’s October 21 announcement, Polar is applying a factory-built infrastructure approach to the initial 41 MW phase of a multiphase AI data center campus designed to scale to

Read More »

Hyperscalers allow more scrutiny of controversial data center plans

Hyperscalers are getting decidedly twitchy about citizens’ reactions to their secretive data center construction plans, and are looking for ways to de-escalate some of the conflicts. Earlier this month, Amazon announced its Data Center Commitment which, among other things, would disclose more information about energy and water use and consider a moratorium asking government officials to sign non-disclosure agreements covering their planning applications. Amazon is not alone in this. Earlier this week, Meta said that it was reviewing its use of NDAs after the company was widely criticized for its secrecy in proposing Hyperion, a Louisiana data center in July.

Read More »

Google will pay people to use less electricity so its data centers can use more

Google has an answer to some of the electricity supply problems that data center construction is causing: It has signed an agreement with energy supplier Voltus to build what it’s calling a 1-gigawatt virtual power plant, expanding on an earlier 100 megawatt deal the two signed earlier this year. This power plant is virtual in the sense that it doesn’t generate any electricity itself, but aggregates so-called flexible grid capacity into one central resource that can be deployed at times of peak demand. This flexible capacity can be in the form of batteries or of load-shedding: asking others to temporarily stop consuming electricity by shutting down industrial processes or adjusting tens of thousands of smart thermostats at once, effectively moving their electricity usage to a time when there is less demand. Voltus operates by offering incentives to companies to reduce their power consumption temporarily, and also offers inducements to electricity resellers that they can pass on to their customers.

Read More »

Big Tech’s Next Nuclear Bet: More Power From Reactors Already Running

The next wave of nuclear power for AI data centers may come not from new reactors, but from generating stations that have been operating for decades. In a pair of agreements announced just a week apart, Google and Amazon committed to long-term electricity purchases supporting approximately 1,080 MW of additional nuclear generating capacity from Constellation Energy’s existing fleet. The transactions follow earlier commitments by Meta to support reactor upgrades at operating nuclear facilities in Ohio, Pennsylvania and Illinois, establishing a broader commercial model in which hyperscale technology companies help finance increases in nuclear output. Under its October 6 agreement with Google, Constellation plans to invest more than $4.3 billion in equipment and technology upgrades at 11 operating reactor units across Illinois, Pennsylvania and New Jersey. The 20-year power purchase agreement supports 890 MW of new generating capacity, with the first upgrades expected to begin delivering additional electricity in 2028. A separate 15-year agreement covers 2,700 MW of existing nuclear generation, underscoring the distinction between securing today’s electricity supply and financing additional capacity. Amazon’s September 30 agreement similarly supports 190 MW of new generation at Maryland’s Calvert Cliffs nuclear station, alongside purchases of existing output. Together, the two arrangements underpin more than $7 billion in planned infrastructure investment. Unlike proposed advanced reactors, these facilities already have operating licenses, grid connections, established workforces and decades of operating experience. Increasing their output avoids some of the cost, permitting and construction challenges associated with building entirely new nuclear plants, although significant upgrades still require extensive engineering, equipment modifications and regulatory approval. The potential scale is substantial. According to the Nuclear Regulatory Commission’s current application schedule, the agency anticipates 31 applications for reactor power uprates through 2032, representing approximately 2,421 MW of potential additional electrical generating capacity. That is roughly equivalent to the output of

Read More »

AMD Helion Puts CPU Density at the Center of Agentic AI Infrastructure

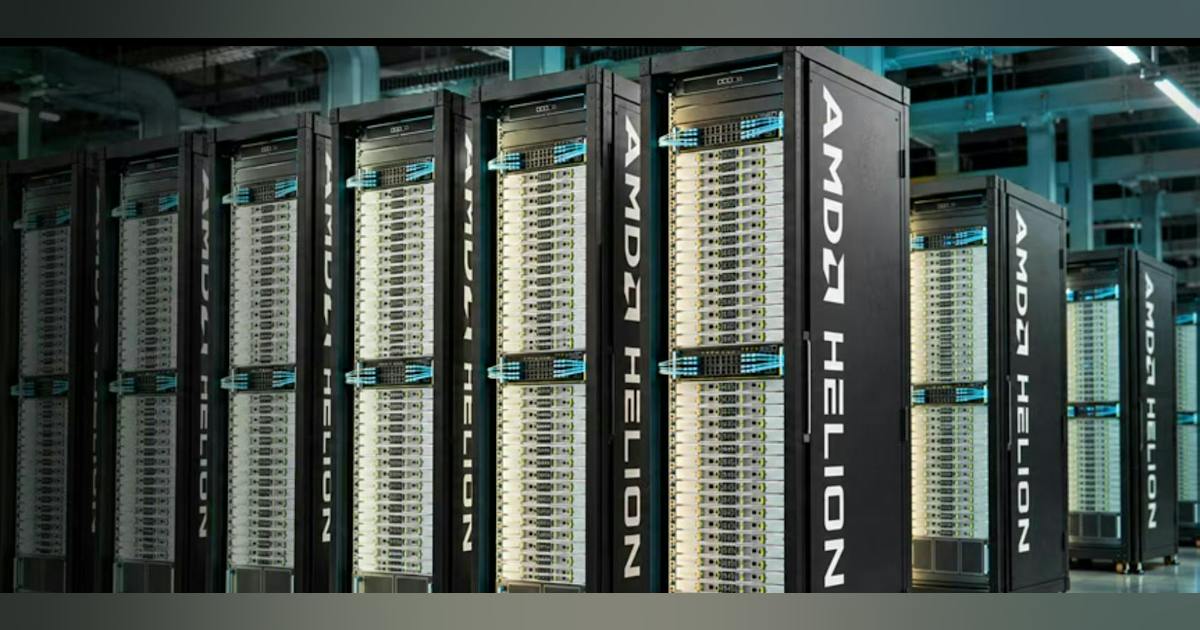
AMD expects the growth of agentic applications to substantially increase demand for server CPUs alongside GPU infrastructure. During her October 12 OCP keynote, CEO Lisa Su said the company now projects the server CPU market will exceed $200 billion by 2030, a significant upward revision from its earlier $120 billion estimate. While that remains AMD’s market forecast rather than an independent measure of future demand, it underscores the company’s conviction that general-purpose computing will play a much larger role in AI infrastructure. Two Rack Designs for Different Markets Helion’s two principal configurations reflect different approaches to deploying and managing agentic workloads. For hyperscale operators, the architecture emphasizes high-density CPU infrastructure dedicated to agent execution, with model inference handled by separate GPU-accelerated systems. This separation allows operators to expand CPU and GPU capacity independently, potentially improving resource utilization as the balance between agent activity and inference demand changes. The approach also introduces infrastructure considerations. Agents may communicate repeatedly with models hosted elsewhere in a data center or across distributed environments, making network performance, latency and workload orchestration important factors in overall system efficiency. The ability to scale computing resources independently is an architectural advantage, but realizing that benefit will depend on how effectively those resources are connected and managed. For enterprise deployments, Helion takes a more integrated approach, combining EPYC CPU blades, Instinct MI350P GPU blades and general-purpose computing resources within the same rack. The reference design accommodates up to 16 MI350P accelerators in two independent eight-GPU servers, each occupying five rack units. These GPU nodes operate separately rather than through a common rack-level scale-up fabric, reflecting the architecture’s emphasis on enterprise inference rather than the tightly coupled accelerator environments used for frontier-model training. The enterprise configuration also accommodates dedicated resources for databases, storage and technical computing, supporting the broader range

Read More »

AI’s Fragmented Regulatory Landscape Becomes a Data Center Design Challenge

Designing for Verifiable Operations For an operator serving tenants across jurisdictions, a claim about where a workload runs must be one that the responsible service provider can substantiate. That means identifying who can administer the workload, how data moves between regions, where backups are maintained, and which records document those arrangements. A tenant promising to run a workload within a particular jurisdiction needs assurance that its data, backups, and access arrangements satisfy the applicable requirements. Workload placement alone cannot establish where a backup resides or from where an administrator can access a system. Those questions must be addressed across compute, storage, network paths, security controls, and third-party access, with responsibilities established during procurement and verified before service begins. Not all of those controls necessarily reside with the data center operator. A colocation provider may be responsible for physical access, facility security, and designated infrastructure services, while a tenant or cloud provider controls the applications, storage configuration, backup locations, and logical access to workloads. The operating agreement must distinguish between what the facility provider can verify directly and what remains within the tenant’s systems. The EU AI Act makes that division of responsibility particularly important. Its requirements for covered high-risk AI systems include logging, documentation, human oversight, robustness, and cybersecurity, subject to the law’s applicable implementation dates. These obligations attach to the relevant providers and deployers of AI systems, rather than automatically to every company hosting them. A data center operator may nevertheless be required by contract to provide physical-access records, security evidence, or information about infrastructure location so that a tenant can substantiate its own compliance. A further distinction concerns data residency. The AI Act is not itself a general requirement to keep all AI workloads or associated data within the European Union. Geographic restrictions may instead arise from data-protection

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

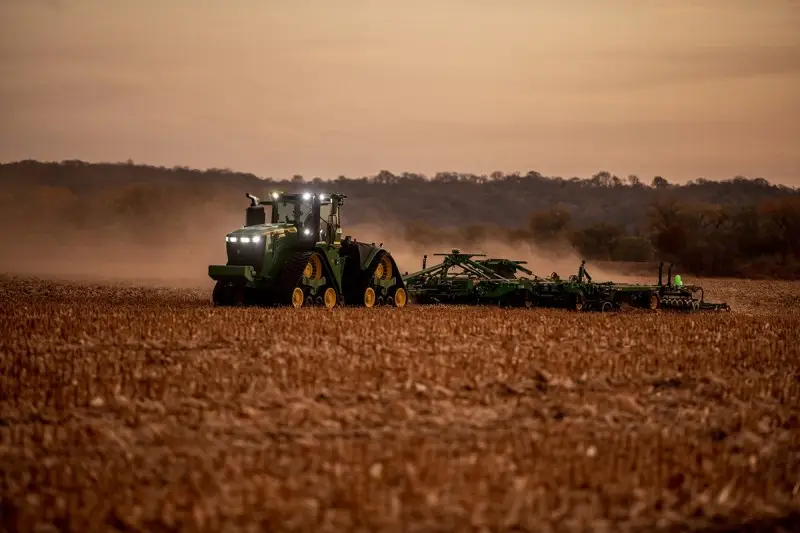
Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »