Stay Ahead, Stay ONMINE

DCF Trends Summit: AI Compresses the Data Center Hardware Lifecycle and Raises the Stakes for ITAD

The AI infrastructure race is largely a story about getting more computing into data centers faster. But the accelerated hardware cycle is creating an equally consequential problem at the other end of the rack: getting yesterday’s equipment back out while it is still valuable. GPU systems built around increasingly dense and specialized AI architectures are […]

The AI infrastructure race is largely a story about getting more computing into data centers faster. But the accelerated hardware cycle is creating an equally consequential problem at the other end of the rack: getting yesterday’s equipment back out while it is still valuable.

GPU systems built around increasingly dense and specialized AI architectures are beginning to challenge traditional assumptions about IT asset disposition, or ITAD. Where conventional enterprise infrastructure might remain in service for three to five years, newer GPU platforms can face refresh cycles of 18 to 24 months, according to Josh Humm, Data Center Solutions Manager at Dynamic Lifecycle Innovations.

That compression changes the economics as well as the mechanics of decommissioning. “The faster we can get the materials out of your building, the more it’s worth, the more we can return to your program,” Humm said.

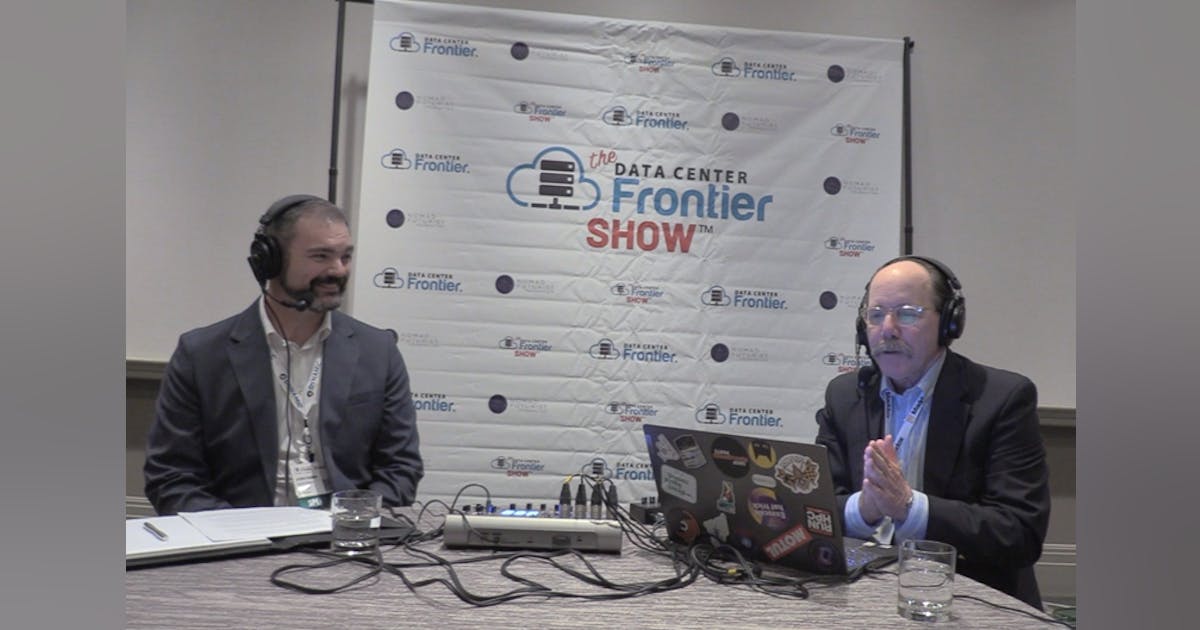
Humm joined DCF Contributing Editor Doug Black for a DCF Show podcast recorded at the third annual Data Center Frontier Trends Summit, held Aug. 4-6 in Reston, Virginia. Their conversation focused on a less visible part of the AI infrastructure buildout: what happens to servers, accelerators, memory, storage and networking gear when the next generation arrives.

The answer increasingly touches facility operations, data security, logistics, sustainability and potentially millions of dollars in recoverable hardware value.

AI Hardware Changes the Exit Path

AI systems create some obvious physical challenges for decommissioning.

Traditional ITAD teams accustomed to pulling 1U and 2U servers out of air-cooled racks may instead encounter liquid-cooling manifolds, substantially heavier systems and equipment requiring specialized rigging and handling procedures.

Humm said some systems can weigh between 5,000 and 6,000 pounds. “We’re not pulling out just 1U, 2U servers out of racks anymore,” he said.

Liquid cooling adds another layer. Removing infrastructure designed around direct-to-chip or other liquid-cooling architectures can require equipment and procedures well beyond conventional hot-aisle/cold-aisle server environments.

But Humm pointed to another complication that may prove equally significant: increasingly proprietary hardware.

AI systems can be highly optimized around particular workloads, networks and accelerator architectures. That reduces some of the commoditized repeatability on which traditional ITAD processes have relied and puts more emphasis on engineering, testing and component-level evaluation.

Then comes speed. “The traditional ITAD refresh structure for working with an enterprise client is three to five years on a refresh,” Humm said. “A lot of this new GPU and a lot of new equipment, we’re talking 18 to 24 months.”

Those shortened cycles mean decommissioned hardware cannot simply sit in a staging area waiting for somebody to decide what happens next.

Processors, memory, networking equipment and other components continue to depreciate after they are removed from production. In markets where certain components remain in short supply, that delay can represent a measurable loss of recoverable value.

“The longer you sit on it, the more it depreciates,” Humm said. “It’s a detriment to your program to sit and wait.”

Plan the Exit Before the Hardware Arrives

That dynamic is pushing ITAD toward a larger role in data center lifecycle planning.

Operators devote enormous resources to determining how equipment will enter a facility: power requirements, rack density, cooling architecture, network connectivity, commissioning and deployment schedules.

Humm argues that the process for removing that infrastructure eventually deserves earlier consideration as well.

“We shouldn’t be a reactive thing that happens at the point of disposition at the end of life,” he said.

For large enterprises, simply onboarding a new ITAD provider can take months as security, compliance, environmental and operational requirements are reviewed.

Waiting until a refresh is underway creates a mismatch between that process and the increasingly rapid hardware cycles of AI infrastructure.

Humm recommends designing decommissioning workflows into facility operations, including the tracking systems needed to maintain relationships between equipment and its components. A server and the drives removed from it, for example, need to remain linked through the disposition process so operators can establish what happened to each data-bearing asset.

The aim is to create a predetermined path from removal through data sanitization or destruction, testing, remarketing and, where necessary, recycling.

The principle sounds familiar because the industry is confronting a similar issue on the construction side: infrastructure velocity increasingly rewards decisions made earlier.

ITAD now has its own version of that equation.

Every Handoff Adds Risk

Data security makes the disposition process more consequential than ordinary equipment logistics.

A retired server may move from the data hall to an onsite decommissioning contractor, then to a transportation provider, processor, refurbisher, remarketer and ultimately a recycler.

Humm identifies those vendor handoffs as some of the principal exposure points. The ITAD industry can be highly segmented, he said, with separate companies responsible for onsite services, transportation, processing and recycling.

Dynamic’s model, by contrast, is vertically integrated. The company says it uses its own project managers and technicians, operates its own logistics capabilities, processes and refurbishes equipment and operates electronics recycling infrastructure.

Humm said its technicians can perform data erasure down to the chip level on certain network equipment before assets are evaluated for reuse or recycling.

For operators, however, the broader lesson extends beyond any particular ITAD provider: reducing handoffs can simplify the chain of custody, while every additional partner needs to be understood and documented.

Certification provides one way to scrutinize that chain. Dynamic publicly lists R2v3, e-Stewards, ISO 14001 and NAID AAA among its certifications and practices. NAID AAA, administered by i-SIGMA, uses scheduled and unannounced audits to validate secure information-destruction practices.

Humm said operators should also demand transparency into downstream providers rather than relying on general sustainability or security claims.

Finding the Hardware’s “Next Best Life”

Once data is secured, another question begins: What is the equipment actually worth? The answer can be more complicated than checking what a used server appears to sell for online.

Dynamic describes its approach as finding an asset’s “next best life.” That could mean selling a system intact, reconfiguring it, harvesting valuable components or sending equipment with no viable reuse value into certified recycling streams.

Humm said grading and configuration can materially change the economics. Memory might have substantially greater value outside a chassis headed for recycling. Components can also become more valuable when sufficient quantities are accumulated to satisfy demand for a particular configuration.

Under some circumstances, Humm said those decisions can produce improvements of 10%, 20%, 30% or even 40% in recovered value. Those figures should be understood as outcomes Dynamic says it has seen in particular disposition scenarios, rather than a universal benchmark for retired hardware.

The process requires testing as well. Equipment being returned to the secondary market has to be evaluated as working hardware, which can mean testing processors, memory and other components rather than simply identifying them by part number.

Humm cautioned against relying heavily on automated market valuations, saying AI-based estimates can produce “pie-in-the-sky overvaluation” that fails to reflect actual equipment condition and grading.

Instead, he said customers should expect a detailed breakout showing what happened to their assets and where their recovery came from: whole-system resale, chassis, memory, processors, storage, other components or recycling.

That level of transparency becomes particularly important as shortages and long lead times strengthen parts of the secondary infrastructure market.

Humm said Dynamic has even seen customers accelerate planned equipment refreshes after determining that unusually strong component pricing could offset more of the cost of replacing the hardware.

That introduces an interesting new variable into the AI infrastructure lifecycle. Refresh cadence is usually viewed as something technology suppliers impose on data center operators. But strong residual values can occasionally give operators an economic reason to move faster as well.

A $17 Million Data Center Decommissioning

The potential scale of those economics emerged in a recent Dynamic project in Colorado. Humm said an existing enterprise customer was migrating from an approximately 8- to 10-MW on-premises data center into cloud infrastructure.

Dynamic had previously handled more conventional endpoint ITAD work for the company. This time, the project encompassed the data center. Over approximately three months, Humm said Dynamic removed equipment, cabinets, racks and other infrastructure from the facility while meeting the customer’s schedule.

Data-bearing equipment received additional treatment onsite. Hard drives were wiped at the facility, while drives that could not be successfully sanitized were shredded there.

Humm said onsite destruction can be especially valuable when an operator wants the strongest possible assurance that sensitive storage media never leaves its control before sanitization or destruction.

When the Colorado project was completed, the recovered value changed the economics dramatically. Dynamic returned more than $17 million net to the customer, Humm said — approximately $15 million more than the customer had expected.

For an operations organization accustomed to treating decommissioning primarily as a cost, that kind of recovery gets attention.

“Being able to show your leadership a check for $17 million is something that makes you look good,” Humm said. It also illustrates why the retirement side of the hardware lifecycle deserves more scrutiny as AI investment accelerates.

Decommissioning remains an operational expense. But when equipment contains processors, memory and other components with significant secondary-market demand, disposition can also become a source of capital for the next infrastructure cycle.

Measuring the Sustainability Side

Reuse also intersects with the data center industry’s sustainability objectives.

Keeping functional hardware or components in service can avoid some of the environmental impact associated with manufacturing replacement equipment, while responsible material recovery provides an alternative for assets that cannot economically be reused.

Humm said Dynamic provides customers with sustainability reporting intended to translate those outcomes into more tangible terms.

For every 100,000 pounds of electronics processed, he cited company calculations equating the impact to metrics such as powering approximately 150 homes for a year, planting 12,000 trees or saving about 60 swimming pools worth of water.

Those numbers are Dynamic’s sustainability-reporting equivalents rather than industry-wide conversion factors, but they illustrate the growing demand for something more concrete than simply declaring old equipment “recycled.”

For data center operators, downstream visibility is increasingly part of that expectation.

A disposition program needs to show where equipment went, what was reused, what was destroyed and how remaining materials moved through recycling channels.

Trust — and Scale

Black closed the conversation by asking Humm for one question every operator should ask before its next major refresh.

Humm offered two. “Can I trust you? And can you scale with me?”

The first covers security, compliance and accountability.

Operators should understand the certifications applicable to their ITAD partner, how data destruction is documented, how assets are tracked and where equipment or recovered materials ultimately go.

“Nobody wants to be in the news for having their stuff show up somewhere where it shouldn’t be,” Humm said.

The second question may become increasingly important as AI infrastructure grows.

An ITAD operation sized to process enterprise laptops, desktops and mobile devices is very different from one capable of absorbing repeated truckloads of rack-scale infrastructure.

Operators should therefore look at processing turnaround, physical footprint, staffing, technical capabilities and the ability to handle simultaneous large projects.

Humm posed the issue in terms that will sound familiar to anybody planning AI capacity today: If a provider is asked to support a large-scale refresh two or three years from now, will it actually have the infrastructure to keep up?

That question is likely to get more urgent. The data center industry has spent the AI era learning how quickly assumptions about power, cooling, density and deployment schedules can change. Hardware lifecycle planning may be next.

If GPU infrastructure increasingly turns over in 18 to 24 months, the equipment entering today’s data halls is already moving toward tomorrow’s decommissioning queue.

The operators that plan that exit before the racks come offline will have a better chance of protecting the data, controlling the chain of custody — and capturing whatever value remains inside the hardware.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

Aker BP, Höegh Evi secure EU funding for Atlas CCS project

Aker BP and Höegh Evi have been awarded €223 million (about US$250 million) from the European Union Innovation Fund to support development of the Atlas carbon capture and storage (CCS) project in Norway. The Atlas project is designed as a large-scale CCS network linking industrial CO2 emitters in Europe with

Read More »

Extreme wants to use idle network compute capacity for local AI

“We’ve spent decades building networks that reach every corner of the enterprise, and those networks hold a lot of idle compute. Exchange zones will put that compute to work, letting AI run locally on infrastructure customers already own. That delivers sovereignty, local inferencing, and better economics than sending everything to

Read More »

Equinor lets Wisting FPSO topsides FEED contract to Aibel

@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } <!–> Equinor Energy AS awarded Aibel a front-end engineering and design (FEED) study contract covering topside modules for the proposed floating production, storage, and offloading (FPSO) vessel for Wisting field development in the Barents Sea. The contract includes FEED work and further maturation of the FPSO topsides design to support the Wisting partners’ project execution decision. It also contains an option for engineering, procurement, and project management (EPma) services. Any contract for fabrication of the topside modules would be awarded later, Equinor said. Work will begin immediately and is scheduled for completion in late 2027. The FEED study will form part of the basis for the Wisting license partners’ planned investment decision in late 2027. Equinor and partners plan to decide on concept selection and the project’s further progression by yearend 2026. “We are at an early stage in the development of Wisting, and considerable work remains to develop a project that is profitable and feasible,” said Trond Bokn, Equinor’s senior vice-president for project development. ]–> <!–> –> <!–> Dec. 2, 2019 ]–> <!–> –> <!–> April 22, 2024 ]–> <!–> –> <!–> May 21, 2026 ]–> Wisting Wisting, discovered in 2013 in the Hoop area of the Barents Sea about 310 km north of Hammerfest, is the largest oil discovery on the Norwegian continental shelf yet to be developed. The field contains estimated recoverable resources of just under 500 MMboe. Water depths across the development area are 390-418 m. In July, Equinor submitted for public consultation

Read More »

Oil prices climb as Saudi attacks heighten supply concerns

Oil prices rose sharply Oct. 23 as escalating attacks on Saudi Arabian energy infrastructure and mounting threats to Middle East shipping heightened concerns over further supply disruptions. Oil prices rose more than 3% on Oct. 23, with Brent crude futures climbing above $117/bbl, their highest level since late April, while US benchmark West Texas Intermediate (WTI) advanced above $103/bbl. Brent was on track for a third consecutive weekly gain, reflecting a growing geopolitical risk premium amid continued regional hostilities. Market concerns intensified following attacks by Yemen’s Houthi movement on Saudi targets, including energy infrastructure and airports. On Oct. 21, Saudi air defenses intercepted a drone targeting a processing plant at Saudi Aramco’s Shaybah oil field. Falling debris caused a fire in a contractor’s vehicle, killing two people and injuring two others, according to the Saudi Energy Ministry. Operations at the field were unaffected. Saudi Aramco also instructed employees to evacuate its headquarters in Dhahran and work remotely as regional hostilities escalated, Reuters reported Oct. 22, citing people familiar with the matter. Although the latest incident at Shaybah did not interrupt production, continued attacks have raised concerns about the security of Saudi energy infrastructure and the reliability of regional supplies. Shipping risks have added to market uncertainty. October has recorded the highest number of attacks on commercial vessels in the Strait of Hormuz and surrounding waterways since tracking began in 2017, according to data compiled by the Washington Institute for Near East Policy. Although Middle Eastern crude exports have recovered strongly from earlier disruptions, the escalation in maritime attacks has raised questions about whether those flows can be sustained. The United Arab Emirates (UAE) also reported an oil spill from a tanker off Umm Al Quwain on Oct. 23. Authorities did not identify the vessel or establish the cause of the

Read More »

INGAA appoints Chris Schindler as 2026-2027 chair

The board of directors for the Interstate Natural Gas Association of America (INGAA) has appointed Chris Schindler to serve as chairman of the organization for a 1-year term. Schindler serves as executive vice-president, general counsel, corporate secretary, and chief compliance officer of Southern Star Central Gas Pipeline, which transports natural gas through about 5,800 miles of pipeline in the Midwest and Mid-Continent regions of the United States. Schindler joined Southern Star in June 2019 following a 25-year legal career at Hogan Lovells, in Washington, DC. He handled regulatory matters before the Federal Energy Regulatory Commission (FERC), Commodity Futures Trading Commission (CFTC), and state commissions; executed regulatory strategies for energy infrastructure projects; litigated FERC rate cases; and was a frequent national speaker on FERC and CFTC regulatory issues. INGAA also appointed Rob Johnson, president of WBI Energy Inc., as first vice chair, and David Brast, president of US Natural Gas Pipelines, TC Energy, as second vice chair.

Read More »

Energy Department Authorizes Strategic Petroleum Reserve Exchange to Support Fuel Supply Stability

WASHINGTON— The U.S. Department of Energy (DOE) today announced the authorization of an emergency exchange of up to 400,000 barrels of crude oil from the Strategic Petroleum Reserve (SPR) to address a crude oil supply disruption affecting the Phillips 66 Lake Charles Refinery in Louisiana. Under the terms of the exchange, all borrowed crude oil will be returned with additional premium barrels, helping replenish and strengthen the SPR at no additional cost to taxpayers.  “With this exchange, the Energy Department is taking definitive action to support refinery operations, maintain stable fuel supplies, and ensure all Americans continue to have access to the affordable, reliable, and secure energy they rely on every day,” said DOE Under Secretary of Energy Kyle Haustveit. “This emergency exchange helps alleviate supply disruption and requires Phillips 66 to return more barrels to the SPR than are currently being withdrawn, saving hardworking taxpayers millions of dollars and delivering on the Trump Administration’s commitment to strengthen and safeguard America’s energy security.” The Energy Department has authorized the exchange of up to 400,000 barrels for the Phillips 66 Lake Charles Refinery from the West Hackberry SPR site for immediate delivery. The supply will help offset temporary disruptions affecting crude oil deliveries to the refinery and support continued production of transportation fuels serving Louisiana and surrounding markets.  DOE will continue working with industry partners to help ensure stability across the fuel supply chain and stands ready to utilize available authorities, as appropriate, to support the reliable delivery of energy supplies and protect U.S. energy security.  For more information on the SPR, please visit DOE’s SPR website. 

Read More »

Energy Department Designates Helium as Critical Material to Strengthen American Manufacturing and Supply Chain Security

WASHINGTON—The U.S. Department of Energy (DOE) today announced that Secretary of Energy Chris Wright has designated helium as a critical material under the Energy Act of 2020. The designation advances the Trump Administration’s commitment to freeing America from reliance on foreign sources of critical materials, strengthening domestic manufacturing, supporting American jobs, and securing the materials essential to U.S. economic and national security.  “President Trump is bringing back America’s manufacturing industry, and that means making sure we have the materials needed to build things in America again,” said U.S . Secretary of Energy Chris Wright. “Helium is essential to producing the semiconductors and advanced technologies that power our economy. By designating helium as a critical material, we are taking another step toward securing our supply chains, creating American jobs, and ensuring the United States leads the world in energy and technological innovation.” DOE determined that helium meets the statutory definition of a critical material due to its essential role in American manufacturing and growing exposure to supply chain risks. Helium’s unique properties make it indispensable to semiconductor production, with no viable substitutes in many critical applications. The United States has significant domestic deposits of helium-rich natural gas to support growing industrial demand. “The U.S. Department of Energy is committed to strengthening our country’s supply chain of critical materials that are essential to continued economic and job growth, energy dominance, and U.S. leadership in cutting-edge technologies such as SI and semiconductors,” said Assistant Secretary of Energy Audrey Robertson. “Under Secretary Wright’s leadership, DOE is taking decisive action to ensure American manufacturers have reliable access to helium as a critical resource they need.” Global demand for helium is growing faster than production, increasing supply risks for American manufacturers. Despite the nation’s abundant helium resources, limited refining capacity and lengthy permitting timelines continue to

Read More »

Energy Department to Use Defense Production Act Funding to Restart American Refinery and Expand Refining Capacity

WASHINGTON—President Donald J. Trump today announced plans to provide up to $150 million in Defense Production Act (DPA) Title III funding to expand domestic petroleum production, storage, and logistics at refineries across the United States.  By leveraging DPA authorities, DOE will help increase domestic production of gasoline, diesel, jet fuel, and other petroleum products, strengthening America’s fuel supply and lowering prices for American families and businesses. Together, this funding is expected to increase U.S. refining output by millions of gallons per day.  “After 17 years of Democrat leaders enacting energy subtraction policies that led to the closure of refineries and more expensive refined oil products, the Trump Administration is taking action to expand our nation’s refining capacity and strengthen our energy security,” said U.S. Secretary of Energy Chris Wright. “Thanks to President Trump, America is producing more oil and gas than ever before and thanks to President Trump, we will soon be producing more refined products as well. These Defense Production Act funds will be used strategically and in partnership with private industry to rapidly bolster America’s existing energy infrastructure. By restoring energy addition policies, we will continue to unleash American energy dominance and lower costs for the American people.” The investment supports President Trump’s commitment to ensuring all Americans have access to affordable, reliable, and secure energy while strengthening energy infrastructure critical to national defense. Thanks to the Working Families Tax Cuts, $1 billion in federal funding has been appropriated for energy-related projects deemed critical to national security. Presidential Determination No. 2026-11 identifies domestic petroleum production, refining, and logistics capacity as essential to national defense. The selection process is ongoing and will be announced in the near future.

Read More »

Hyperscalers allow more scrutiny of controversial data center plans

Hyperscalers are getting decidedly twitchy about citizens’ reactions to their secretive data center construction plans, and are looking for ways to de-escalate some of the conflicts. Earlier this month, Amazon announced its Data Center Commitment which, among other things, would disclose more information about energy and water use and consider a moratorium asking government officials to sign non-disclosure agreements covering their planning applications. Amazon is not alone in this. Earlier this week, Meta said that it was reviewing its use of NDAs after the company was widely criticized for its secrecy in proposing Hyperion, a Louisiana data center in July.

Read More »

Google will pay people to use less electricity so its data centers can use more

Google has an answer to some of the electricity supply problems that data center construction is causing: It has signed an agreement with energy supplier Voltus to build what it’s calling a 1-gigawatt virtual power plant, expanding on an earlier 100 megawatt deal the two signed earlier this year. This power plant is virtual in the sense that it doesn’t generate any electricity itself, but aggregates so-called flexible grid capacity into one central resource that can be deployed at times of peak demand. This flexible capacity can be in the form of batteries or of load-shedding: asking others to temporarily stop consuming electricity by shutting down industrial processes or adjusting tens of thousands of smart thermostats at once, effectively moving their electricity usage to a time when there is less demand. Voltus operates by offering incentives to companies to reduce their power consumption temporarily, and also offers inducements to electricity resellers that they can pass on to their customers.

Read More »

Big Tech’s Next Nuclear Bet: More Power From Reactors Already Running

The next wave of nuclear power for AI data centers may come not from new reactors, but from generating stations that have been operating for decades. In a pair of agreements announced just a week apart, Google and Amazon committed to long-term electricity purchases supporting approximately 1,080 MW of additional nuclear generating capacity from Constellation Energy’s existing fleet. The transactions follow earlier commitments by Meta to support reactor upgrades at operating nuclear facilities in Ohio, Pennsylvania and Illinois, establishing a broader commercial model in which hyperscale technology companies help finance increases in nuclear output. Under its October 6 agreement with Google, Constellation plans to invest more than $4.3 billion in equipment and technology upgrades at 11 operating reactor units across Illinois, Pennsylvania and New Jersey. The 20-year power purchase agreement supports 890 MW of new generating capacity, with the first upgrades expected to begin delivering additional electricity in 2028. A separate 15-year agreement covers 2,700 MW of existing nuclear generation, underscoring the distinction between securing today’s electricity supply and financing additional capacity. Amazon’s September 30 agreement similarly supports 190 MW of new generation at Maryland’s Calvert Cliffs nuclear station, alongside purchases of existing output. Together, the two arrangements underpin more than $7 billion in planned infrastructure investment. Unlike proposed advanced reactors, these facilities already have operating licenses, grid connections, established workforces and decades of operating experience. Increasing their output avoids some of the cost, permitting and construction challenges associated with building entirely new nuclear plants, although significant upgrades still require extensive engineering, equipment modifications and regulatory approval. The potential scale is substantial. According to the Nuclear Regulatory Commission’s current application schedule, the agency anticipates 31 applications for reactor power uprates through 2032, representing approximately 2,421 MW of potential additional electrical generating capacity. That is roughly equivalent to the output of

Read More »

AMD Helion Puts CPU Density at the Center of Agentic AI Infrastructure

AMD expects the growth of agentic applications to substantially increase demand for server CPUs alongside GPU infrastructure. During her October 12 OCP keynote, CEO Lisa Su said the company now projects the server CPU market will exceed $200 billion by 2030, a significant upward revision from its earlier $120 billion estimate. While that remains AMD’s market forecast rather than an independent measure of future demand, it underscores the company’s conviction that general-purpose computing will play a much larger role in AI infrastructure. Two Rack Designs for Different Markets Helion’s two principal configurations reflect different approaches to deploying and managing agentic workloads. For hyperscale operators, the architecture emphasizes high-density CPU infrastructure dedicated to agent execution, with model inference handled by separate GPU-accelerated systems. This separation allows operators to expand CPU and GPU capacity independently, potentially improving resource utilization as the balance between agent activity and inference demand changes. The approach also introduces infrastructure considerations. Agents may communicate repeatedly with models hosted elsewhere in a data center or across distributed environments, making network performance, latency and workload orchestration important factors in overall system efficiency. The ability to scale computing resources independently is an architectural advantage, but realizing that benefit will depend on how effectively those resources are connected and managed. For enterprise deployments, Helion takes a more integrated approach, combining EPYC CPU blades, Instinct MI350P GPU blades and general-purpose computing resources within the same rack. The reference design accommodates up to 16 MI350P accelerators in two independent eight-GPU servers, each occupying five rack units. These GPU nodes operate separately rather than through a common rack-level scale-up fabric, reflecting the architecture’s emphasis on enterprise inference rather than the tightly coupled accelerator environments used for frontier-model training. The enterprise configuration also accommodates dedicated resources for databases, storage and technical computing, supporting the broader range

Read More »

AI’s Fragmented Regulatory Landscape Becomes a Data Center Design Challenge

Designing for Verifiable Operations For an operator serving tenants across jurisdictions, a claim about where a workload runs must be one that the responsible service provider can substantiate. That means identifying who can administer the workload, how data moves between regions, where backups are maintained, and which records document those arrangements. A tenant promising to run a workload within a particular jurisdiction needs assurance that its data, backups, and access arrangements satisfy the applicable requirements. Workload placement alone cannot establish where a backup resides or from where an administrator can access a system. Those questions must be addressed across compute, storage, network paths, security controls, and third-party access, with responsibilities established during procurement and verified before service begins. Not all of those controls necessarily reside with the data center operator. A colocation provider may be responsible for physical access, facility security, and designated infrastructure services, while a tenant or cloud provider controls the applications, storage configuration, backup locations, and logical access to workloads. The operating agreement must distinguish between what the facility provider can verify directly and what remains within the tenant’s systems. The EU AI Act makes that division of responsibility particularly important. Its requirements for covered high-risk AI systems include logging, documentation, human oversight, robustness, and cybersecurity, subject to the law’s applicable implementation dates. These obligations attach to the relevant providers and deployers of AI systems, rather than automatically to every company hosting them. A data center operator may nevertheless be required by contract to provide physical-access records, security evidence, or information about infrastructure location so that a tenant can substantiate its own compliance. A further distinction concerns data residency. The AI Act is not itself a general requirement to keep all AI workloads or associated data within the European Union. Geographic restrictions may instead arise from data-protection

Read More »

Microsoft exits UK AI data center project over electricity delays

“We remain committed to both the Loughton project and the UK, and we are exploring alternative power sources for the site, as well ​as other expansion sites in the UK,” Nscale added. “This decision relates to a single ​site,” a Microsoft spokesperson said of its termination of an agreement for the data ​center in Loughton, Essex, where Nscale had faced delays, with electricity grid ⁠officials telling the AI company they did not expect to supply power to the site ​until the 2030s. “Our relationship with Microsoft remains strong and long-term, and this unfortunate London-wide grid ​issue has no impact on our other contracts,” a spokesperson for Nscale told Reuters.

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »