Stay Ahead, Stay ONMINE

HPE’s Quantum Computing Bet: A Multi-Vendor Path to the Data Center

QuEra Deal Targets On-Premises Quantum Integration Under the expanded collaboration, HPE and QuEra intend to develop integrated testbeds, software interoperability, hybrid algorithms and performance benchmarks to support future quantum deployments alongside HPE Cray supercomputing infrastructure. The work is intended to address the practical requirements of coordinating quantum processors with the classical computing systems that prepare […]

QuEra Deal Targets On-Premises Quantum Integration

Under the expanded collaboration, HPE and QuEra intend to develop integrated testbeds, software interoperability, hybrid algorithms and performance benchmarks to support future quantum deployments alongside HPE Cray supercomputing infrastructure. The work is intended to address the practical requirements of coordinating quantum processors with the classical computing systems that prepare workloads, process results and support quantum error correction.

QuEra Chief Commercial Officer Yuval Boger, who previously discussed the development of hybrid quantum-classical infrastructure on the DCF Show, emphasized that integrating quantum hardware into an HPC environment presents different engineering challenges than providing access through the cloud.

Boger said, “HPE’s deep experience in supercomputing gives organizations the benefit of working with a partner who can solve that problem at the scale they need.”

The collaboration envisions deploying future fault-tolerant quantum hardware at customer facilities rather than requiring organizations to rely exclusively on cloud-based quantum computing services. That option could appeal to national laboratories, defense organizations, pharmaceutical researchers and other institutions managing classified information, proprietary intellectual property or data subject to sovereignty requirements.

QuEra’s neutral-atom architecture uses individual atoms as qubits, manipulating them with lasers and electromagnetic controls. Unlike superconducting quantum processors, which generally require dilution refrigerators operating at temperatures measured in millikelvin, neutral-atom systems can operate without extreme cryogenic refrigeration. They still require specialized laser systems, vacuum equipment, precision optics and environmental controls, presenting facility requirements substantially different from those of conventional servers.

On-premises quantum-HPC integration is already being tested. In Japan, the National Institute of Advanced Industrial Science and Technology (AIST) operates QuEra’s 260-physical-qubit Gemini neutral-atom computer as part of its ABCI-Q research platform, which also incorporates an NVIDIA H100-based AI supercomputer. An October 26 case study published by QuEra describes Gemini operating in a separate building approximately 350 meters from the main GPU installation, mounted on vibration-isolation equipment and connected through a software-defined network.

The installation demonstrates how specialized quantum hardware can be incorporated into a broader computing environment without occupying the same physical space as conventional HPC resources. The broader ABCI-Q testbed also highlights an important distinction: loosely coupled, batch-oriented quantum-classical workflows are feasible today, while future fault-tolerant systems will require tighter, lower-latency coordination between quantum processors and their classical control infrastructure.

QuEra’s next-generation roadmap illustrates the potential implications for data center design. The company projects that its planned Libra system will operate without cryogenic refrigeration, consume less than 40 kW and occupy less than 1,000 square feet. Those remain vendor development targets rather than verified commercial deployment specifications, but they suggest that some quantum architectures could be accommodated within existing data center environments without the extensive cryogenic infrastructure required by superconducting systems.

The HPE collaboration complements QuEra’s existing relationship with Amazon Web Services. Libra, targeted for availability through Amazon Braket in 2028, is designed to provide 256 error-corrected logical qubits and execute on the order of one million reliable logical quantum operations. Logical qubits represent quantum information protected through error-correction techniques, rather than the much larger population of physical qubits required to maintain that information. QuEra projects that Libra will require more than 10,000 physical qubits.

QuEra has also outlined a next-generation gigaquop-class system, targeted for 2028–2029, designed to support more than 1,000 logical qubits and approximately one billion reliable logical operations. The HPE collaboration could provide a path for deploying such a system on premises. These remain development targets; neither company has announced a completed HPE-integrated fault-tolerant installation, a firm customer delivery schedule or pricing for a commercial on-premises configuration.

Building a Quantum Ecosystem Without Choosing a Winning Architecture

HPE’s broader quantum strategy is built around supporting multiple competing quantum computing architectures rather than committing its infrastructure investments to a single approach. Its June announcement identified eight industry collaborators spanning quantum processors, control technologies and error correction, reflecting the range of technical approaches still competing for commercial viability.

Intel is developing semiconductor-based silicon spin qubits, while IQM and Rigetti are pursuing superconducting quantum processors. Quantinuum specializes in trapped-ion systems, and QuEra focuses on neutral-atom technology. Beyond the processors themselves, Qblox and Quantum Machines develop the control electronics and software needed to operate quantum hardware, while Riverlane specializes in quantum error correction.

HPE’s objective is to develop an infrastructure framework capable of accommodating these different technologies within established HPC environments. The approach resembles the evolution of conventional supercomputing and AI infrastructure, where CPUs, GPUs and specialized accelerators increasingly operate as components of larger computing systems.

For HPE, supporting multiple architectures could reduce the risk of committing to a particular quantum technology before the industry establishes which approaches offer the best combination of reliability, scalability, performance and manufacturing cost. It could also allow research institutions and enterprise customers to evaluate different quantum processors while retaining more of their existing classical computing infrastructure.

The challenge is that quantum architectures differ substantially in their physical requirements, control mechanisms and operating characteristics. A common HPC environment does not eliminate those differences. HPE’s June announcement identified hybrid algorithm co-design, software interoperability and system-level benchmarking as priorities. Developing those capabilities will be essential to making quantum processors usable within established computing workflows, regardless of which qubit technology ultimately prevails.

Quantinuum Adds Another Hardware Path

A separate June 22 collaboration with Quantinuum extends HPE’s quantum-HPC integration efforts to trapped-ion computing. Under the agreement, Quantinuum will provide access to quantum systems, development tools and engineering expertise, while HPE contributes high-performance computing infrastructure and experience deploying large-scale computing environments.

The companies plan to develop and evaluate hybrid reference architectures, application workflows, interoperability and performance benchmarks. Trapped-ion systems use electrically charged atoms confined by electromagnetic fields, differing from QuEra’s neutral-atom approach in their physical implementation and control requirements. Supporting both technologies within an HPE computing environment would provide a practical test of how much infrastructure and software integration can be standardized across competing quantum architectures.

Quantinuum is also pursuing a separate route into commercial data center infrastructure. In August, the company announced a multiyear partnership with Oracle to deploy its 98-physical-qubit Helios trapped-ion quantum computer inside a U.S. Oracle Cloud Infrastructure (OCI) AI data center. The planned installation would make quantum computing available alongside OCI’s GPU, HPC, networking and cloud services, allowing customers to explore hybrid workloads without operating specialized quantum hardware at their own facilities.

That partnership has begun moving toward customer access. In October, Oracle opened applications for its Quantum AI Compute beta program, through which approved participants are expected to gain cloud-based access to Helios alongside OCI’s GPU and HPC infrastructure. An October 22 update from Quantinuum indicated that the physical Helios installation inside Oracle’s infrastructure was still forthcoming.

The two partnerships illustrate distinct but potentially complementary approaches to commercial quantum integration. HPE is concentrating on incorporating multiple quantum architectures into established supercomputing environments, including installations operated directly by research and enterprise customers. Oracle is developing a managed cloud model in which quantum computing becomes another specialized resource accessible through an existing infrastructure platform.

For data center operators, both approaches point toward a future in which quantum hardware is integrated into broader computing systems rather than treated as a standalone laboratory installation. Neither partnership, however, has yet established that such integration will translate into commercially scalable fault-tolerant computing.

Quantum Error Correction Creates a New Infrastructure Workload

One of the less visible but potentially consequential elements of HPE’s quantum strategy involves quantum error correction. Quantum processors are exceptionally sensitive to disturbances that can corrupt calculations. Temperature fluctuations, electromagnetic interference, imperfect control operations and other sources of noise can introduce errors that must be managed as computations proceed.

Making quantum computing reliable at scale requires detecting and correcting those errors without interrupting the calculation. That creates a demanding workload for classical computing systems operating alongside the quantum hardware.

A fault-tolerant quantum computer continuously generates measurement data that can reveal errors in its physical qubits. Classical processors must interpret those measurements, identify the appropriate corrective action and communicate the results to quantum control systems within tightly constrained time windows. Depending on the error-correction method, responses may involve physical control operations or updates to how subsequent calculations are interpreted.

The processing requirements are substantially different from those of conventional enterprise applications. In September, Qblox and Riverlane reported a hardware integration demonstration in which a complete error-detection and correction feedback loop achieved approximately 6.9 microseconds of round-trip latency for a smaller surface-code configuration and 11.9 microseconds for a larger configuration. The integration connected Qblox quantum control electronics with Riverlane’s Deltaflow 2 error-correction system through QECi, an open interface for exchanging measurement and correction data.

The demonstration used physical control and decoding hardware but emulated qubit measurement data rather than measurements from a live quantum processor. The companies completed 50,000 error-correction cycles, demonstrating sustained operation of the control and decoding pathway under test conditions. The results represent progress toward real-time quantum error correction, not evidence of a completed fault-tolerant quantum computer.

Other suppliers are advancing complementary approaches to quantum-classical integration. In September, Quantum Machines demonstrated an end-to-end NVIDIA CUDA-Q program running across live qubits, specialized classical control hardware, CPUs and GPUs using NVIDIA NVQLink. Quantum Machines reported completing the cross-system exchange in approximately one microsecond, illustrating how quantum processors and conventional computing resources can exchange information within a coordinated workflow. Unlike the Qblox-Riverlane benchmark, the demonstration involved live qubits, although it measured a different integration process and did not establish full fault-tolerant operation.

Together, these developments suggest that future quantum installations could require two distinct but interconnected classes of classical computing infrastructure. The first would handle time-critical quantum control, measurement processing and error correction, using specialized electronics and potentially GPU-accelerated processing close to the quantum hardware. The second would supply the broader HPC resources needed for algorithm execution, simulation, preprocessing and analysis.

That distinction has practical implications for data center design. The most time-sensitive operations require predictable, low-latency communication between quantum hardware and its control systems, while other hybrid computing workloads can draw on larger, more conventional HPC installations. A large HPE Cray system could support those broader computational tasks, while dedicated control electronics and error-correction processors manage the operations that cannot tolerate significant delays.

Integrating both layers into a coordinated operating environment, without assuming that conventional HPC infrastructure can handle every real-time quantum control function, will be a defining engineering challenge as hybrid quantum computing moves toward commercial deployment.

Data Center Infrastructure Must Accommodate a Different Type of Machine

Bringing quantum computing into established data center environments involves more than finding space for another type of processor. Depending on the architecture, quantum installations can require extreme cryogenic cooling, vacuum systems, precision lasers, electromagnetic shielding and protection against mechanical vibration. The physical requirements vary considerably among quantum technologies, making it premature to establish a universal quantum data center design.

For facility designers, the challenge extends to power distribution, cooling, equipment placement and the communications infrastructure linking quantum processors with conventional computing resources. Time-sensitive quantum control electronics may need to operate close to the quantum hardware, while larger HPC systems supporting simulations, workload scheduling and analysis can be located elsewhere. Accommodating both creates new considerations for equipment isolation, environmental controls, networking and long-term serviceability.

A working example emerged in June at Oak Ridge National Laboratory (ORNL), which commissioned Pathfinder, a 20-qubit IQM Radiance superconducting quantum computer installed in its Translational Research Capability (TRC) building. The system uses a helium-based cryogenic cooling arrangement that brings portions of the equipment to 4 kelvin, while its superconducting quantum circuits operate at temperatures below 10 millikelvin, just a fraction of a degree above absolute zero.

The TRC building, completed in 2025 specifically for quantum information science research, incorporates ground-floor laboratories with isolated structural slabs designed to minimize vibration affecting sensitive equipment. The installation illustrates how quantum computing can introduce facility requirements that differ fundamentally from conventional server deployments, particularly where cryogenic systems and precision instrumentation must operate alongside classical computing hardware.

Pathfinder is intended to connect with HPC resources in the National Center for Computational Sciences Technology Integration Group’s testbed, located in another building on the Oak Ridge campus. Researchers are also developing hardware-agnostic software interfaces intended to coordinate quantum systems from different vendors with conventional computing environments, including common approaches to resource management, scheduling and application workflows.

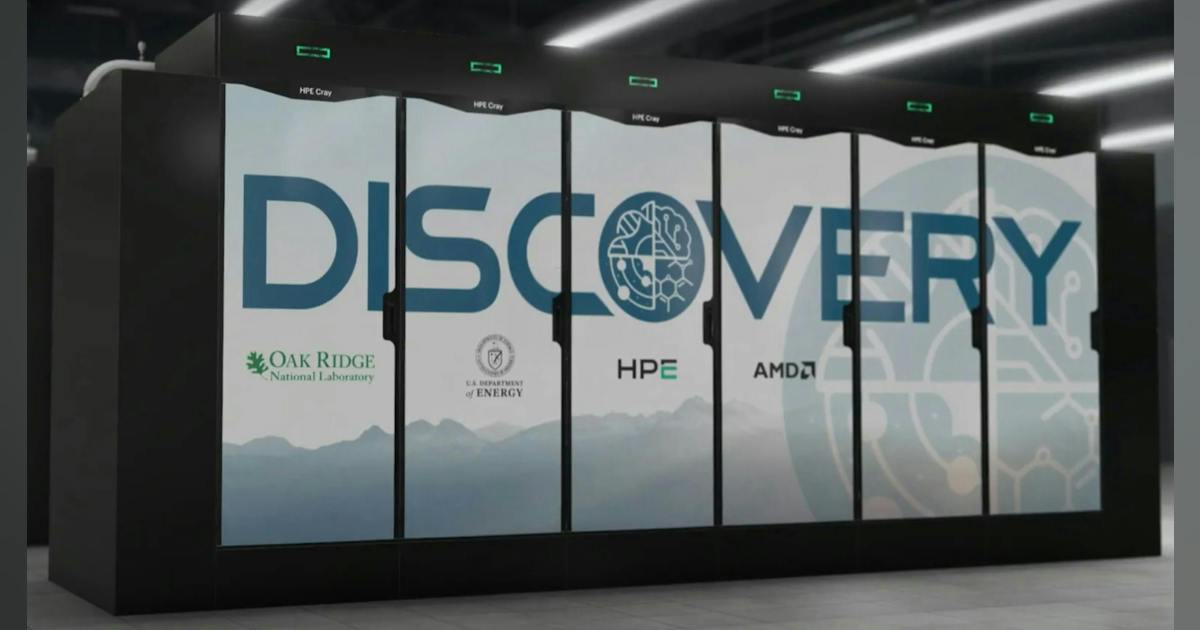
Oak Ridge already operates the HPE Cray Frontier exascale supercomputer and plans to deploy its AMD-powered successor, Discovery, in 2028. Built on the HPE Cray Supercomputing GX5000 platform, Discovery is intended to support HPC and AI workloads while serving as a testbed for the laboratory’s continuing quantum computing research. The relationship between these systems reflects a broader effort to make quantum processors usable within established supercomputing environments without requiring every component to occupy the same physical space.

HPE Cray Provides the Classical Computing Foundation

HPE’s quantum strategy is closely tied to its broader investment in supercomputing infrastructure. In July, the company announced additional capabilities for its HPE Cray Supercomputing GX5000 platform, incorporating sixth-generation AMD EPYC processors and a fully direct-liquid-cooled architecture.

HPE says the GX5000’s CPU-only GX250 compute blade configuration can support up to 81,920 AMD EPYC processor cores per rack, with direct-liquid-cooling technology designed to accommodate warmer facility water temperatures. Those specifications apply to the classical computing infrastructure rather than to quantum processors themselves, but they illustrate the scale of processing, thermal management and systems integration HPE brings to its quantum strategy.

In a hybrid computing application, classical HPC systems might prepare a computational problem, execute selected portions on a quantum processor and return results to CPUs or GPUs for additional processing. The objective is not to replace conventional computing with quantum hardware, but to combine different processing technologies within coordinated workflows.

AI could also play an operational role in quantum computing infrastructure. In August, QuEra and Anthropic reported an AI-assisted hardware control experiment in which Anthropic’s Claude developed and validated software to restore the precise laser frequencies required by QuEra’s neutral-atom systems. The resulting controller successfully recovered the laser system in 695 of 700 timed trials, typically completing recoveries in seconds rather than the several minutes required by a specialist.

Importantly, the finished controller operates through deterministic software rather than an AI model making real-time hardware decisions. The demonstration addresses one specialized subsystem, not the operation of a complete quantum computer, but it illustrates how AI-assisted engineering could eventually reduce maintenance burdens and improve operational consistency.

Quantum computing and AI still address different computational problems, and no broadly demonstrated quantum advantage has emerged for mainstream AI training or inference. Their potential convergence lies in using specialized processors and classical computing resources where each is most effective.

For data center operators, making that convergence practical will require common scheduling, management and monitoring environments. A quantum processor accessible only through specialized laboratory software is a very different proposition from one that can participate in established HPC workflows with predictable performance, operational visibility and support requirements.

IBM Demonstrates Another Path to Quantum-Classical Integration

HPE is not alone in pursuing that goal. In March 2026, IBM published a quantum-centric supercomputing reference architecture outlining how quantum processing units could operate alongside CPUs and GPUs through coordinated software, networking and application workflows.

IBM’s strategy is supported by actual integration work. In February, IBM and Japan’s RIKEN research institute reported a closed-loop quantum-classical computing demonstration linking an on-premises IBM Heron quantum processor with the Fugaku supercomputer.

The experiment involved a quantum chemistry calculation using the full 152,064-node Fugaku system, with quantum and classical computing resources exchanging data within a coordinated workflow. It demonstrated the ability to orchestrate the two computing environments at substantial scale, although it did not establish a general commercial performance advantage over conventional HPC.

The demonstration is significant because it moves quantum-HPC integration beyond reference architectures and planned partnerships. IBM and RIKEN have shown that quantum processors and large classical supercomputers can participate in a common computational workflow, even as the broader economics and application advantages remain unresolved.

IBM and HPE are approaching this emerging market from different positions. IBM develops its own quantum processors and supporting technologies, while HPE is concentrating on integrating quantum systems from multiple hardware suppliers into established supercomputing platforms. Both approaches recognize that commercially useful quantum computing will depend on the classical infrastructure surrounding the quantum processor as much as on advances in qubit technology.

What Data Center Operators Should Be Watching For

The next stage of HPE’s quantum initiative will depend on whether its partnerships produce functioning, repeatable and commercially supportable systems. Three developments will help determine when those capabilities become practical infrastructure investments.

The first is the emergence of HPE-integrated quantum computing testbeds that demonstrate meaningful applications using actual quantum hardware alongside HPE Cray platforms. These installations will need to establish how workloads are scheduled, how computing resources communicate, how performance is measured and whether integration can be repeated across different quantum architectures.

The second is continued progress in quantum error correction. Systems capable of performing sustained, reliable logical operations will be more commercially relevant than those emphasizing large physical-qubit counts without corresponding improvements in computational reliability.

Progress is measurable, although important limitations remain. On October 19, Quantinuum reported that its Helios trapped-ion system achieved 99.9995% logical memory fidelity per syndrome-extraction cycle in an error-correction experiment, equivalent to a logical failure probability of approximately five in one million per cycle under the tested conditions. The result represents a significant improvement in protecting quantum information, but it does not establish that the system can execute a million arbitrary computational operations without error or deliver sustained commercial fault-tolerant performance.

The third is the development of practical data center deployment specifications. Operators will need verified information about power consumption, cooling, physical footprint, environmental conditions, equipment maintenance and lifecycle costs. They will also need to understand which components must remain physically close to the quantum processor, which workloads can use remote HPC resources and how specialized quantum equipment can be serviced without disrupting broader computing operations.

Those considerations extend beyond hardware specifications to the commercial model itself. Data center operators will need evidence that quantum installations can deliver predictable availability, manageable operating costs and useful computational results before treating them as routine infrastructure investments.

The unanswered question is no longer whether quantum hardware can be installed alongside conventional computing infrastructure. Research facilities are already demonstrating that capability, and commercial providers are beginning to develop more integrated deployment models. The larger challenge is turning those installations into repeatable, commercially supportable systems with reliable operation, measurable application advantages and predictable facility requirements.

HPE is positioning its supercomputing infrastructure to support that transition without committing to a single quantum processor architecture. Whether those partnerships can deliver the performance, economics and operational maturity required for widespread commercial deployment of fault-tolerant quantum computing remains an open question.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

IBM aims to bring AI agent sprawl under enterprise control

HashiCorp Vault already secures non-human identities for organizations including ABN AMRO, Adobe, athenahealth, BBVA, BlackRock, Canva, Duke Energy, Expedia, London Stock Exchange, Starbucks, and Swiss Federal Railways. Now, HashiCorp will extend those capabilities to AI agents, issuing secured, short-lived credentials that limit each agent to what it needs, IBM says. When used with HashiCorp Vault,

Read More »

HPE extends AI-driven networking to SD-WAN and SASE

In a blog post explaining how the system works, Gabriel Gomane, HPE senior product marketing manager, wrote: “In HPE Mist, HPE Mist Networking WAN Assurance aggregates telemetry from HPE Networking EdgeConnect to measure end-user experience using service level expectations (SLEs) and simplify troubleshooting. WAN Insights provides visibility into device status,

Read More »

Equinor nearly doubles third-quarter earnings on higher commodity prices, production gains

Equinor ASA reported adjusted operating income of $12.35 billion for third-quarter 2026, nearly double the $6.22 billion recorded a year earlier, supported by higher oil and natural gas prices, increased production, and stronger refining margins. The Norwegian energy major posted net income of $2.54 billion, compared with a net loss of $204 million in the year-earlier quarter. Adjusted net income reached $2.86 billion, or $1.20/share. Equinor realized an average liquids price of $92.30/bbl and a European natural gas price of $20/MMbtu during the quarter, reflecting tighter energy markets amid Middle East supply disruptions. Production, outlook Equinor’s equity oil and gas production averaged 2.166 MMboe/d in the quarter, up 2% year over year. Production on the Norwegian continental shelf remained broadly stable as contributions from new fields, including Halten East and Verdande, and new wells offset natural declines and unplanned losses at Johan Castberg and Troll. International production increased 21%, driven by higher volumes from Adura in the UK and Bacalhau offshore Brazil, as well as reduced maintenance activity. US production declined due to planned offshore downtime and natural field declines. Citing stronger operational performance, Equinor raised its full-year 2026 oil and gas production growth guidance to about 4% from 3%. “High production in the third quarter enabled us to capture additional value from higher prices,” said Anders Opedal, Equinor’s president and chief executive officer. Refining, financial performance Equinor’s Marketing, Midstream and Processing segment benefited from stronger refining margins, high utilization, and LNG trading activity. The Mongstad refinery in Norway delivered a record earnings contribution during the quarter. Cash flow from operations after taxes reached $8.14 billion. Organic capital expenditures totaled $3.28 billion, while the company’s adjusted net debt-to-capital-employed ratio declined to 3.8% at quarter-end from 10.4% in the previous quarter. Portfolio developments Equinor continued reshaping its upstream portfolio, including acquiring

Read More »

EIA: US crude oil inventories down 1.9 million bbl

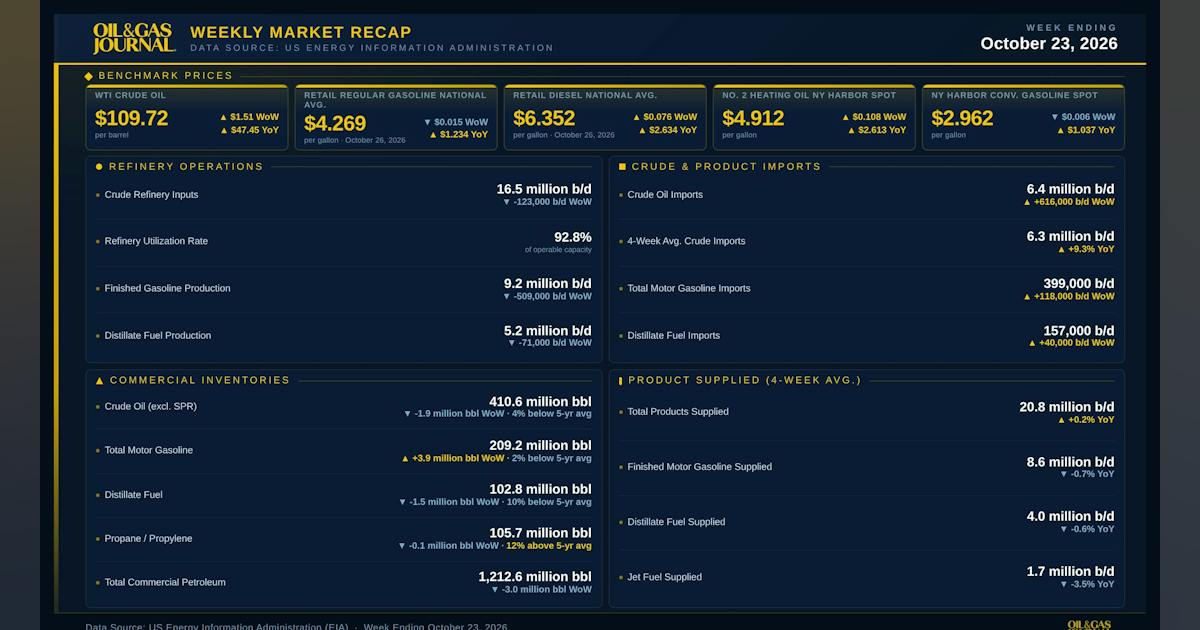
US crude oil inventories for the week ended Oct. 23, excluding the Strategic Petroleum Reserve, decreased by 1.9 million bbl from the previous week, according to data from the US Energy Information Administration (EIA). At 410.6 million bbl, US crude oil inventories are 4% below the 5-year average for this time of year, the EIA report indicated. Gasoline inventories increased 3.9 million bbl, 2% below the 5-year average. Propane-propylene inventories decreased 100,000 bbl, 12% above the 5-year average. Total commercial petroleum inventories decreased by 3.0 million bbl for the week. Distillate inventories decreased 1.5 million bbl, 10% below the 5-year average. US crude oil refinery inputs averaged 16.5 million b/d for the week ended Oct. 23, which was 123,000 b/d less than the previous week’s average. Refineries operated at 92.8% of capacity. Gasoline output averaged 9.2 million b/d, and distillate production decreased to 5.2 million b/d. Crude oil imports increased 616,000 b/d to 6.4 million b/d. The 4-week average of 6.3 million b/d is 9.3% above the year-ago level. Gasoline imports averaged 399,000 b/d; distillate imports averaged 157,000 b/d. Over the past four weeks, total product supplied averaged 20.8 million b/d, up 0.2% year over year. The 4-week average for gasoline product supplied decreased 0.7% year over year to 8.6 million b/d, while the 4-week average for distillate product supplied decreased 0.6% to 4.0 million b/d. The 4-week average for jet fuel product supplied decreased 3.5% year over year.

Read More »

Energy Department Closes $5.1 Billion Loan to Lower Electricity Costs and Strengthen Grid Reliability in Iowa and Wisconsin

WASHINGTON—The U.S. Department of Energy’s (DOE) Office of Energy Dominance Financing (EDF) today announced the financial close of a $5.1 billion loan package to Alliant Energy to lower electricity costs, expand firm power generation, and strengthen grid reliability in Iowa and Wisconsin. The investments will add more than 2.6 gigawatts (GW) of new or upgraded power generation capacity and deliver more than $1 billion in electricity cost savings for American families and businesses across both states. Today’s announcement advances President Trump’s Executive Order Strengthening the Reliability and Security of the United States Electric Grid by ensuring our nation has the dependable power needed to meet growing electricity demand and strengthen American energy security. “The Energy Department is delivering on President Trump’s promise to lower electricity costs and unleash the full potential of American energy,” said U.S. Secretary of Energy Chris Wright. “These investments will drive down energy costs for families and businesses in Iowa and Wisconsin, strengthen our nation’s electric grid, and fuel American prosperity for decades to come.” The projects will add enough electricity to power the equivalent of nearly 2 million homes—lowering costs and strengthening grid reliability in Iowa and Wisconsin. The investments will support new natural gas-fired power plants, energy storage systems, and upgrades to existing generation facilities, create hundreds of construction-related jobs, and deliver affordable, reliable energy for American families and businesses. “Thanks to President Trump and Secretary Wright’s leadership, EDF is putting capital to work to expand America’s reliable energy infrastructure,” said EDF Director Gregory A. Beard. “By bringing new, dependable power online, we are strengthening our nation’s energy security and lowering electricity costs for families and businesses across Iowa and Wisconsin.” This loan marks the Trump Administration’s tenth financial close, and the sixth and seventh utility financing completed through the Energy Dominance Financing Program.

Read More »

Chevron adds operated Gulf of Mexico positions in interest swap with TotalEnergies

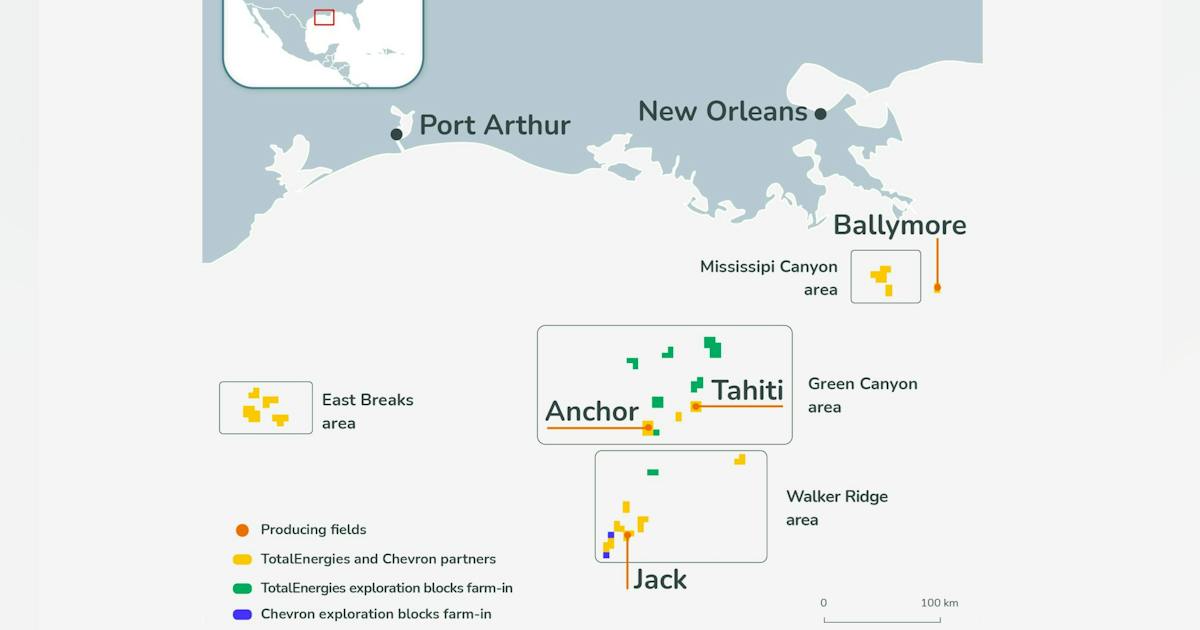
@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } Chevron Corp. has agreed to acquire operatorship and a 75% working interest in two exploration leases in the US Gulf of Mexico from TotalEnergies as part of a deal that will see the companies shuffle interest positions in jointly held acreage, TotalEnergies said in a release Oct. 28. As part of the same transaction, TotalEnergies has taken a 25% working interest in 26 Chevron-operated exploration leases. Financial terms were not disclosed. The acreage package includes 24 leases in the Green Canyon area and two in Walker Ridge, located 150-250 km offshore. The blocks target what TotalEnergies described as well-proven geological plays. TotalEnergies said the deal strengthens collaboration between the two companies, while expanding its US offshore exploration portfolio, building on its 2025 entry into 40 Chevron-operated exploration blocks. Since 2022, TotalEnergies has invested nearly $12 billion in the US to accelerate development in oil, LNG, and electricity.

Read More »

Energy Department Announces $5 Billion Loan to Boost Nuclear Power and Help Lower Costs in Illinois, Maryland, and Pennsylvania

The U.S. Department of Energy’s (DOE) Office of Energy Dominance Financing (EDF) today announced a conditional loan commitment of up to $5 billion to finance nuclear uprates and modernization across Constellation Energy’s nuclear fleet in Illinois, Maryland, and Pennsylvania. The modernization efforts will add nearly 1.1 gigawatts (GW) of electricity, strengthening the grid and lowering costs for millions of Americans across the PJM Interconnection, L.L.C. (PJM) and Midcontinent Independent System Operator (MISO) regions. The loan advances President Trump’s Executive Order, Reinvigorating the Nuclear Industrial Base, which calls for DOE to facilitate 5 GW of power uprates from existing nuclear reactors. In March 2026, in accordance with the Executive Order, DOE launched its Utility Power Reactor Incremental Scaling Effort (UPRISE) to accelerate the expansion of the nation’s nuclear capacity by maximizing power generation from existing reactors. To date, 95% of President Trump’s 5-GW uprate and restart goal has been identified. “The Energy Department is accelerating President Trump’s American nuclear renaissance and unlocking the full potential of our nation’s nuclear fleet,” said U.S. Secretary of Energy Chris Wright. “Uprates that maximize power generation from our existing nuclear facilities are yet another example of the commonsense energy addition policies the Trump Administration is embracing—ensuring more affordable, reliable, and secure energy for American families and businesses.” The projects will add enough electricity to power more than 930,000 homes—lowering costs and strengthening grid reliability in Illinois, Maryland, Pennsylvania, and across the PJM and MISO regions. The investments will support more than 10,000 project-related jobs across Constellation’s nuclear fleet while delivering affordable, reliable power to American homes and businesses. “EDF is delivering on President Trump and Secretary Wright’s commitment to unleash American nuclear power by financing projects that modernize and expand our nation’s existing nuclear plants,” said EDF Director Gregory A. Beard. “These investments will add

Read More »

Neuquén awards eight blocks to expand Vaca Muerta exploration

Argentina’s Neuquén province awarded eight blocks to PCR, Patagonia Energy, GeoPark, JPM Energía, the Phoenix–Continental Resources partnership, and Selva María Oil in a round intended to expand exploration of Vaca Muerta. Committed work programs include 11 horizontal wells to assess acreage outside the formation’s main commercial developments. The awards were made Oct. 21 under Round 1/2026 of the Neuquén Exploration Plan, organized by Gas y Petróleo del Neuquén (GyP). The provincial company will retain an interest in all the blocks. The round attracted 20 bids from 10 bidders for eight of the 15 areas offered. Petrolera Comodoro Rivadavia (PCR) secured three blocks: La Tropilla I, Águila Mora Noreste, and Santo Domingo II. Its program includes one horizontal well per block, each with a 1,500-m lateral and 25 hydraulic fracturing stages. The company will also acquire and process 3D seismic data covering a total of 380 sq km. Patagonia Energy secured Corralera Noroeste, where it will drill three horizontal wells with 3,000-m laterals and a combined 150 fracturing stages. Its commitment also includes 85 sq km of 3D seismic. GeoPark will add Corralera Noreste to its portfolio. The initial program comprises two horizontal wells, each with a 2,000-m lateral and 30 fracturing stages, during a 4-year exploration period. The company will hold a 90% working interest, with GyP retaining 10%. JPM Energía secured Pampa de las Yeguas II NE. Its proposal includes one horizontal well with a 3,000-m lateral and 53 fracturing stages. The Phoenix–Continental Resources partnership was selected for Corralera Sur, with a program comprising one horizontal well with a 1,500-m lateral and 14 fracturing stages. Seismic work includes 150 sq km of acquisition and 105 sq km of specialized processing. Selva María Oil secured Chasquivil Sur, where it will drill one horizontal well with a 1,500-m lateral and 30

Read More »

HPE’s Quantum Computing Bet: A Multi-Vendor Path to the Data Center

QuEra Deal Targets On-Premises Quantum Integration Under the expanded collaboration, HPE and QuEra intend to develop integrated testbeds, software interoperability, hybrid algorithms and performance benchmarks to support future quantum deployments alongside HPE Cray supercomputing infrastructure. The work is intended to address the practical requirements of coordinating quantum processors with the classical computing systems that prepare workloads, process results and support quantum error correction. QuEra Chief Commercial Officer Yuval Boger, who previously discussed the development of hybrid quantum-classical infrastructure on the DCF Show, emphasized that integrating quantum hardware into an HPC environment presents different engineering challenges than providing access through the cloud. Boger said, “HPE’s deep experience in supercomputing gives organizations the benefit of working with a partner who can solve that problem at the scale they need.” The collaboration envisions deploying future fault-tolerant quantum hardware at customer facilities rather than requiring organizations to rely exclusively on cloud-based quantum computing services. That option could appeal to national laboratories, defense organizations, pharmaceutical researchers and other institutions managing classified information, proprietary intellectual property or data subject to sovereignty requirements. QuEra’s neutral-atom architecture uses individual atoms as qubits, manipulating them with lasers and electromagnetic controls. Unlike superconducting quantum processors, which generally require dilution refrigerators operating at temperatures measured in millikelvin, neutral-atom systems can operate without extreme cryogenic refrigeration. They still require specialized laser systems, vacuum equipment, precision optics and environmental controls, presenting facility requirements substantially different from those of conventional servers. On-premises quantum-HPC integration is already being tested. In Japan, the National Institute of Advanced Industrial Science and Technology (AIST) operates QuEra’s 260-physical-qubit Gemini neutral-atom computer as part of its ABCI-Q research platform, which also incorporates an NVIDIA H100-based AI supercomputer. An October 26 case study published by QuEra describes Gemini operating in a separate building approximately 350 meters from the main GPU installation,

Read More »

At 7×24 Exchange, AI Data Center Growth Confronts New Realities of Power, Grid Reliability and Community Trust

DC BLOX: Community Engagement Must Go Beyond Public Relations The afternoon program shifted attention from electrical infrastructure to the growing challenges surrounding data center development and community acceptance. In a discussion moderated by Juli Ierulli, strategic account manager at Environmental Air Systems and vice president of 7×24 Exchange International, Michael Clark, senior vice president of data center construction at DC BLOX, described how the company has revised its approach to engaging communities as it expands into new markets. Clark acknowledged that DC BLOX had encountered significant opposition after entering markets where it lacked the established relationships that had supported earlier developments across the Southeast. “We made multiple stumbles in some of those new markets,” he said, describing how the company sometimes found itself responding to negative publicity rather than presenting a clear explanation of its plans and commitments. The experience led DC BLOX to develop a more systematic approach to community engagement, emphasizing early communication, site-specific websites, accessible explanations of resource consumption and written commitments that residents and officials can evaluate. Clark also pointed to what he called the industry’s “NDA hangover,” reflecting years of development activity conducted under confidentiality agreements that frequently left neighboring communities unaware of what was being planned. But perhaps the most revealing moment came when Clark recounted a conversation with residents near a DC BLOX development in Rockdale County, Georgia. After the company outlined the countywide economic and community benefits expected from the project, one neighbor challenged the distribution of those benefits. “So the rest of the county gets the benefit and we have to pay all the costs,” the resident observed, according to Clark. The question captured a fundamental tension in the industry’s community engagement efforts: tax revenues and economic development benefits may extend across a county, while nearby residents experience the immediate effects

Read More »

NVIDIA’s DSX POD Pushes AI Factory Construction Toward the Assembly Line

Crusoe Brings an Established Modular Model to DSX POD For Crusoe, NVIDIA’s announcement builds on a modular computing strategy already in operation. In its October 21 announcement, Crusoe confirmed that its Spark modular AI data center platform will support DSX POD, extending a manufacturing and deployment approach the company says it has pursued since 2020. Crusoe has expanded its manufacturing capabilities through the acquisition of electrical equipment specialist Easter-Owens Electric and the development of its 352,000-square-foot Crusoe Spark Factory in Brighton, Colorado. The company also introduced Crusoe Spark Liquid, a sixth-generation modular system engineered for ultra-high-density infrastructure, including NVIDIA Vera Rubin NVL72. Next-generation liquid-cooled units are planned for 2027. Crusoe’s vertically integrated model connects infrastructure design and manufacturing with deployment and cloud operations through Crusoe Cloud. The company says it can deliver productive AI capacity in as little as three months, although that timeline is distinct from NVIDIA’s narrower 14-day prepared-site deployment claim. “Modular isn’t a new strategy or pivot for us. It’s been in our DNA since our founding,” said Bryan Schramm, Crusoe’s head of Spark. Crusoe’s involvement demonstrates that the manufacturing model predates DSX POD. NVIDIA is not inventing modular data center infrastructure; it is attempting to establish a common architecture around capabilities that suppliers such as Crusoe have already spent years developing. That distinction matters as the industry evaluates whether standardized AI factory designs can deliver manufacturing efficiencies at a scale beyond individual suppliers’ existing operations. Vertiv and Polar Put the Deployment Model to Work in Norway The European dimension of NVIDIA’s announcement is reflected in a deployment involving Vertiv and Polar Data Centers at Herøya, Norway. According to Vertiv’s October 21 announcement, Polar is applying a factory-built infrastructure approach to the initial 41 MW phase of a multiphase AI data center campus designed to scale to

Read More »

Hyperscalers allow more scrutiny of controversial data center plans

Hyperscalers are getting decidedly twitchy about citizens’ reactions to their secretive data center construction plans, and are looking for ways to de-escalate some of the conflicts. Earlier this month, Amazon announced its Data Center Commitment which, among other things, would disclose more information about energy and water use and consider a moratorium asking government officials to sign non-disclosure agreements covering their planning applications. Amazon is not alone in this. Earlier this week, Meta said that it was reviewing its use of NDAs after the company was widely criticized for its secrecy in proposing Hyperion, a Louisiana data center in July.

Read More »

Google will pay people to use less electricity so its data centers can use more

Google has an answer to some of the electricity supply problems that data center construction is causing: It has signed an agreement with energy supplier Voltus to build what it’s calling a 1-gigawatt virtual power plant, expanding on an earlier 100 megawatt deal the two signed earlier this year. This power plant is virtual in the sense that it doesn’t generate any electricity itself, but aggregates so-called flexible grid capacity into one central resource that can be deployed at times of peak demand. This flexible capacity can be in the form of batteries or of load-shedding: asking others to temporarily stop consuming electricity by shutting down industrial processes or adjusting tens of thousands of smart thermostats at once, effectively moving their electricity usage to a time when there is less demand. Voltus operates by offering incentives to companies to reduce their power consumption temporarily, and also offers inducements to electricity resellers that they can pass on to their customers.

Read More »

Big Tech’s Next Nuclear Bet: More Power From Reactors Already Running

The next wave of nuclear power for AI data centers may come not from new reactors, but from generating stations that have been operating for decades. In a pair of agreements announced just a week apart, Google and Amazon committed to long-term electricity purchases supporting approximately 1,080 MW of additional nuclear generating capacity from Constellation Energy’s existing fleet. The transactions follow earlier commitments by Meta to support reactor upgrades at operating nuclear facilities in Ohio, Pennsylvania and Illinois, establishing a broader commercial model in which hyperscale technology companies help finance increases in nuclear output. Under its October 6 agreement with Google, Constellation plans to invest more than $4.3 billion in equipment and technology upgrades at 11 operating reactor units across Illinois, Pennsylvania and New Jersey. The 20-year power purchase agreement supports 890 MW of new generating capacity, with the first upgrades expected to begin delivering additional electricity in 2028. A separate 15-year agreement covers 2,700 MW of existing nuclear generation, underscoring the distinction between securing today’s electricity supply and financing additional capacity. Amazon’s September 30 agreement similarly supports 190 MW of new generation at Maryland’s Calvert Cliffs nuclear station, alongside purchases of existing output. Together, the two arrangements underpin more than $7 billion in planned infrastructure investment. Unlike proposed advanced reactors, these facilities already have operating licenses, grid connections, established workforces and decades of operating experience. Increasing their output avoids some of the cost, permitting and construction challenges associated with building entirely new nuclear plants, although significant upgrades still require extensive engineering, equipment modifications and regulatory approval. The potential scale is substantial. According to the Nuclear Regulatory Commission’s current application schedule, the agency anticipates 31 applications for reactor power uprates through 2032, representing approximately 2,421 MW of potential additional electrical generating capacity. That is roughly equivalent to the output of

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

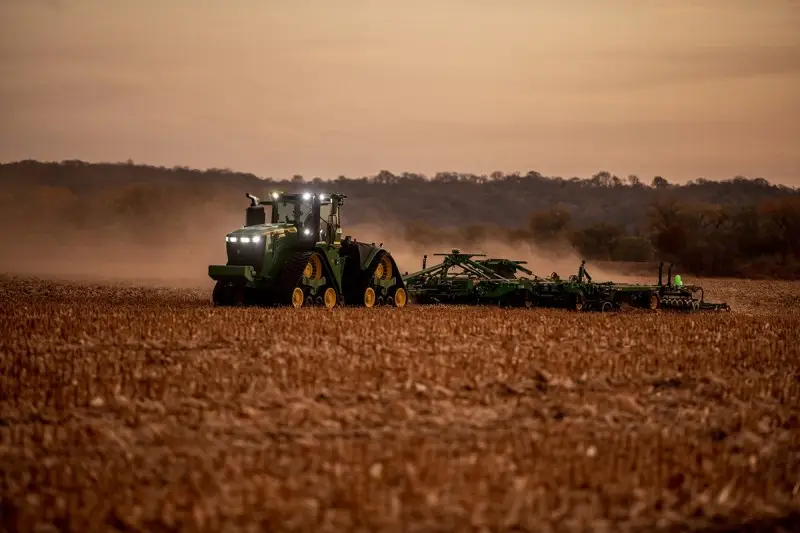
Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »