Your Gateway to Power, Energy, Datacenters, Bitcoin and AI

Dive into the latest industry updates, our exclusive Paperboy Newsletter, and curated insights designed to keep you informed. Stay ahead with minimal time spent.

Discover What Matters Most to You

Explore ONMINE’s curated content, from our Paperboy Newsletter to industry-specific insights tailored for energy, Bitcoin mining, and AI professionals.

AI

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Bitcoin:

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Datacenter:

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Energy:

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Shape
Discover What Matter Most to You

Featured Articles

Grid operators need data center ride-through rules that protect reliability

Listen to the article 7 min This audio is auto-generated. Please let us know if you have feedback. Alan Cooper is CEO of ON.energy, a developer of power infrastructure.  On July 22, a mechanical failure forced a 230-kV transmission line in Northern Virginia offline. Within milliseconds, grid protection systems cleared the fault, as they are designed to do. The event would not have been a particularly noteworthy story, had it stopped there. It’s what happened next, though, that pointed to a growing challenge for grid reliability. Optional Caption Permission granted by Alan Cooper In response to the fault, data centers that had been drawing nearly 4 GW of energy, close to 4% of PJM’s load, collectively disconnected and switched to their on-site backup generation. The move sent voltage and frequency spiking across the system, a technically wonky but threatening result that caused power flickers as far away as Chicago. Thankfully, the prevailing grid conditions were strong enough to absorb the shock of the fault, so the grid held. But if the same event had hit Texas or even Northern Virginia at a time of higher demand, it could have caused a widespread outage. In West Texas, the Electric Reliability Counil of Texas estimates that a loss of as little as 3.2 GW could threaten grid reliability. The power sector is not unfamiliar with the need for things hooked up to the electricity grid to “ride through” disturbance events. In 2023, the Federal Energy Regulatory Commission told the North American Electricity Reliability Corp. to develop requirements that inverter-based supply resources like wind and solar facilities must follow to ensure they “ride through,” i.e., stay online, during certain disturbances. And this time around, NERC, FERC and several grid regions have been quick to identify a similar need for large loads to adhere

Read More »

How OpenAI’s Performance Factory keeps ChatGPT fast

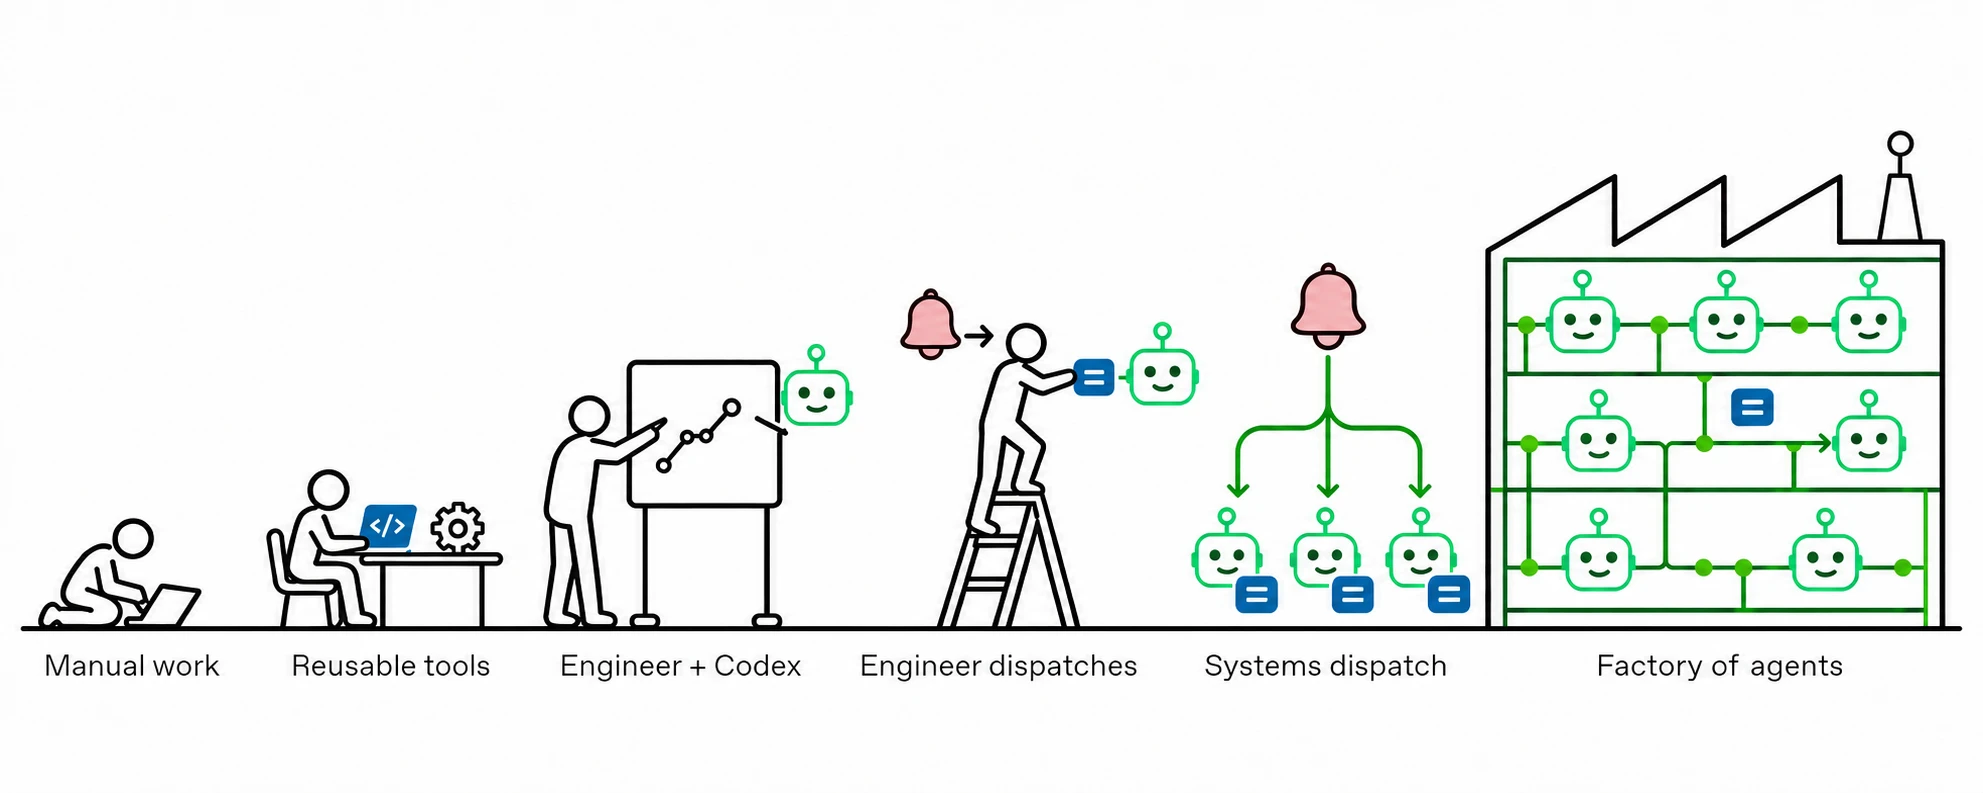
The staggering pace of agentic development has made traditional approaches to performance engineering unsustainable. To keep up, we built the Performance Factory, an autonomous system that uses the full capabilities of Codex and our models to find and fix regressions at an unprecedented speed. The Performance Factory, which runs in the cloud and automates investigating and resolving performance problems, enables us to keep pace with the ambition of our roadmap.In the Performance Factory, our engineers define workflows for recurring jobs and write instructions for the Codex agents that carry them out. In particular, the Regression Workflow opens a task when a performance alert fires. An agent investigates the slowdown, records its findings in the task, and proposes a fix for an engineer to review. After deployment, another agent picks up the same task to check whether performance has returned to baseline. From investigating to authoring the fix to verifying mitigation, this first workflow in the Performance Factory has automated the entire process of fixing regressions. In just over three months, the Regression Workflow tracked more than 1,700 investigations and root caused over 600 cases. That’s 17 automated investigations every day.Here, we’ll share how our use of Codex evolved into what’s now the Performance Factory, walk through our first running workflow, and share early lessons from building and running agent workflows in production.The path from manual investigations to automated workflowsAs we used Codex for more of our performance work, we noticed a progression in how our team worked. We hope other service teams can learn from our process as they adopt agentic workflows in other domains.Software work evolves from manual labor to partnering with machines to agent factories.1. Pre-Codex. Before Codex, engineers manually examined metrics and logs, compared traces, debugged live machines, and read code to investigate a slowdown. This work was time consuming, and knowing where to look often required deep knowledge of the service. Relevant signals were easy to miss. When we encountered the same kinds of problems repeatedly—like regressions in ChatGPT’s first token latency—we built advanced tools, like CPU and allocation profilers, to make those investigations easier. Over time, we accumulated more than 30 performance tools.2. Codex as a partner. Once we had Codex as a partner, engineers could ask, “Why did this get slower?” and work with Codex to investigate, even in an unfamiliar system. Codex could search large codebases, find relevant metrics and traces, follow interactions across services, and do appropriate profiling to piece together what had happened. But engineers still had to steer the process, knowing which performance tools to use and how to guide the investigation. Difficult investigations were more debuggable for more people, with less expertise and time required.3. Reusable skills. To automate further, we captured our performance team’s investigation process in a shared skill called perf-forensics. It tells Codex which tools are available, when to use them, and how to work through a slowdown so Codex can try to resolve the problem from a few angles:Find when the slowdown beganIdentify the affected requestsInvestigate whether deployments or configuration changes could explain itWe tested and refined the perf-forensics skill using evals based on past regressions. For the types of regressions we focused on (for example, ChatGPT latency and availability drops), we could now give Codex an alert and get back a diagnosis in a single run, without guiding it through each step.4. The human proxy. As we added and refined perf-related Codex skills like perf-forensics, we started to feel like a proxy between our alerts and Codex. An alert would fire, and an engineer would simply copy and paste it into Codex with the right skill, then paste the findings back into Slack.5. Automated investigations. Next, we moved investigations to the cloud so an alert could start a Codex session automatically. Codex investigated the slowdown and posted its findings in the Slack thread, but the automation ended with that reply. An engineer still had to pick up the diagnosis, develop a fix, and check whether it worked after deployment. As alerts accumulated, even figuring out which regressions needed attention meant sifting through Slack threads.6. The factory. We built the Performance Factory to run end-to-end agentic performance engineering workflows. It tracks what each active task needs next and assigns an agent when that step is ready. Each task keeps its state and findings, so work can pass between agents and engineers and resume after a code review or deployment. For a regression, the work starts with investigating an alert and ends with verifying recovery in production. We can turn common optimizations into workflows that run regularly across our services. A workflow that spots a potential optimization can open a task in another workflow to test and implement it.The Performance Factory system’s four partsThe Performance Factory is made up of four components: a task tracker with configurable workflows, a dispatch loop that assigns ready work to agents, an API that runs Codex in the cloud, and subscriptions that wake agents when something changes (such as a GitHub review comment posting or a deployment completing).Performance Factory consists of a task service, dispatch loop, cloud execution, and subscriptions.Task service with configurable workflowsThe task service is where engineers define workflows by adding configuration files and prompts for the agents to follow, written in Markdown. The configuration lists the states a task can move through, the allowed transitions, and which steps need an engineer. Separate prompts tell agents what to do at each step.Plain textA code change task contains a configuration file, along with Markdown prompts for implementing and reviewing.Each piece of work becomes a task in a workflow, and all workflows are visible in a UI. Engineers can see what’s open, follow progress, and share a task with a teammate who might have more context or be able to help with the next step.Dispatch loop that assigns workA dispatch loop periodically checks which tasks are ready for the next step. It assigns an agent to each task by starting a Codex turn with the instructions for the task’s current state. The agent records its progress on the task and moves it to the next state if it completes the step.Codex in the cloudOnce a task is assigned, the agent needs a place to do the work, with access to the same tools an engineer would use. We built an internal API to programmatically invoke a Codex turn in the cloud. The Codex turn runs on an environment inside our network, with access to our code repositories and the observability tools our engineers use, such as metrics, logs, traces, CPU profiles, and memory snapshots.The agent runs under a service identity, so we can scope its permissions and see which actions came from our performance agents. Moving agentic work to the cloud lets us run work in parallel without relying on engineers’ laptops being open or manually managing individual cloud development boxes.Subscriptions that wake the agent when something changesSome work has to wait for a person or a deployment; an agent shouldn’t have to keep running in the meantime. When a task needs to wait, it can subscribe to events like review comments or failed CI checks on a GitHub pull request to get notified when it’s time to pick the work back up. When an incoming event matches the subscription, the task becomes ready again and the dispatch loop can then assign an agent to continue the work.The first workflow: from alert to recoveryFinding, root causing, and solving regressions is the first workflow we built inside the Performance Factory. We call it the Regression Workflow. A performance regression moves through several stages: needs investigation, root caused, fix proposed, and resolved, so we built the automated workflow to reflect and move a task through those same stages.When one of its configured performance alerts fires, the Regression Workflow opens a task that agents pick up and move across these stages. The task records its status and key findings outside of any one agent’s context so that other agents or engineers can pick up the work. Engineers can follow the work in Slack or the Regression Workflow UI, add context, and review proposed changes. After a fix is deployed, an agent checks whether the performance has recovered to its original state before resolving the task.Performance Factory regression workflowA regression is detected.An agent finds the cause and proposes a fix.An engineer takes over and decides what ships.After deployment, the agent wakes up to check recovery.Still regressed? Back to investigation.A regression is detected.A regression is detected.PauseDetectedSystemFind root causeAgentPropose fixAgentReview & deployEngineerVerify recoveryAgentResolved Active stage: DetectedThe Regression Workflow’s steps include finding the root cause, proposing a fix, reviewing and deploying, and verifying recovery.Agents find the root causeFinding the root cause (or causes) is the first major step in the workflow. The agent starts by figuring out which metrics got worse, when they started to change, and which service requests were affected. The perf-forensics skill gives Codex access to the tools our performance engineers use and a playbook for working through those questions.An alert fires when a metric crosses a threshold, but the regression may have started hours earlier. The agent looks back through the data to find when the metric first got worse. It then compares groups of requests: did similar requests actually get slower, or were we serving more requests that were already slow? Those findings point to different causes.Once it knows when and where to look, the agent examines deployments and feature flag changes, then reads the relevant code. It checks when a change actually reached the affected requests and uses logs or traces to test whether the code could explain what happened.Adversarial review strengthens the diagnosisEarly on, agents sometimes stopped at the first plausible explanation they found, and some of those diagnoses turned out to be wrong. To catch these mistakes, we added an adversarial review: a separate Codex session that tries to disprove the proposed diagnosis. The reviewer rechecks the assumptions and tests counterfactuals. If a rollout caused the slowdown, did similar requests that weren’t exposed stay healthy? If the suspected change was rolled back, did the affected metric recover?In one investigation, an agent traced failing ChatGPT conversations to errors in image downloads and marked the cause as found. The Codex reviewer noticed that the internal service responsible for locating files had already recovered while image requests were still failing. The diagnosis did not explain the continuing failures, so the AI reviewer reopened the investigation and recorded what still needed to be established.We’ve had success breaking larger jobs into focused Codex turns. In a manual review of 100 root cause suggestions, we graded 70% as accurate, with 30% needing further refinement or not fully establishing causality. In the Regression Workflow, different turns investigate regressions, challenge diagnoses, and propose fixes to increase accuracy numbers through checks and balances.Fixing the regression is the hard partOnce the diagnosis passes adversarial review, the workflow asks Codex to implement a fix and open a pull request. An engineer reviews the PR and decides whether to merge it. We’ve put a significant amount of work into making this handoff as easy as possible. Each task has a report with an automatically generated summary of the regression, its impact, the root cause, and the proposed fix. We’ve tuned these summaries to be easy to scan, including metrics time series, CPU flame graphs, and traces to help engineers quickly understand the findings and inspect the evidence. Engineers can edit the PR directly or use the diagnosis to write their own fix. If they leave comments on the PR, the workflow wakes an agent to address them.An example task report for a regression shows key details, root cause, and proposed fix.After an engineer deploys the fix, the workflow wakes an agent to check whether performance has returned to its earlier baseline. If it has, the agent marks the task as resolved. If performance has only partially recovered, the agent resolves the original regression and opens a new task for the remaining slowdown, which may have a different cause. If there’s no improvement, the agent records what happened and sends the regression back for investigation.Getting fixes right has been harder than finding the cause. For example, we’ve seen cases where the agent-proposed changes are more complicated than necessary or introduce new issues. Similar to the root cause step, we added an adversarial review of each proposed fix to check whether they address the root cause and help catch bugs or unintended consequences. Some fixes also require higher level architectural decisions. For example, adding a cache might improve performance but introduce stale data. Changes like these benefit from guidance from an engineer who knows the service and can weigh the tradeoffs.We’re building an evaluation and improvement loop using these cases. By comparing the fixes agents propose with the changes engineers ultimately merge, we can better understand where proposals fall short, build evals, and improve the workflow. We’re also working on using synthetic performance tests so agents can measure proposed fixes and revise them before asking an engineer for review. We’re also exploring how agents could use our other agentic review tools to identify low-risk changes and eventually ship those fixes without a human in the loop.What we learnedBuilding and running the Performance Factory has taught us a lot about developing and operating agent workflows in production. Here are some lessons for teams building their own agentic workflows.Protect engineers’ attentionThe raw output from a Codex investigation can be a wall of text that’s hard to parse. It takes effort to figure out what the agent is claiming and track down the graphs to see whether the data backs it up. We want engineers to spend their attention on decisions rather than reconstructing the agent’s work.Agents can investigate more regressions than a team has time to read about. Our first version gave engineers a UI full of findings, but someone still had to decide which information mattered. One regression can also appear as several incidents across alerts, monitors, and channels. The workflow now links related incidents, groups them by the metrics teams care about, and ranks their estimated impact. Engineers can focus on adding context, weighing tradeoffs, and deciding what to ship.Evaluate changes to your agentsUpdating an investigation skill or upgrading the model can make the agent better at diagnosing some cases and worse at others, so we need to test their impact before updating them. We test two things separately: 1) how well the agent investigates and 2) how useful its summaries are to engineers.Evaluating investigationsFor investigations, we backtest against past production incidents. We turn those incidents into a suite of test cases we can rerun when we change the skill. A Codex agent attempts to investigate and resolve the incident, and we compare the agent’s behavior to the actual past resolution data. Each case starts with a fresh Codex investigator and the original signal, stripped of details that might give away the answer.Historical tests need care. Metrics and traces expire, while evidence collected after recovery can give away the cause. A test is only useful if we understand what evidence the investigator could see. The agent can inspect code and query production telemetry within set limits. It cannot use saved memories (notes from earlier investigations), read the incident writeup, or see results from previous runs. We also inspect its transcript afterward for information that might have spoiled the test.We score when the problem began, how large it was, and which requests were affected. We also evaluate how the agent uses evidence to rank possible causes and explain what remains uncertain. An agent can get the timing right and still blame the wrong deployment, so we score those separately.Evaluating agent-to-engineer handoffsWe evaluate task summaries using snapshots of saved tasks. These make particularly good backtests because summarization does not depend on external metrics or traces that expire. A separate grader checks whether an engineer unfamiliar with the system can understand what happened and why it matters, whether useful charts were kept, and whether the proposed next step is supported by the evidence.Turn recurring failures into self-repairLastly, our agents need monitoring just as much as the services they investigate. A broken profiler or a missing permission can keep an agent from verifying what caused a slowdown. Those failures can be hard to spot in the final report, so we run an agent every day to look through messages and logs from recent runs for tool failures and access errors.We use the Performance Factory to self-repair and fix the problems this check uncovers. When the same tool error blocks several investigations, the agent creates a task to fix it. If the cause is clear, an agent proposes a fix, and an engineer reviews the change and decides whether to merge it. After merging changes like this, we also use evals to check whether agents can get past the step that previously blocked them.What’s next: broader applications, proactive monitoringThe Regression Workflow is just one instance of the agent factory pattern that moves tasks through explicit states. Agents advance the task when more work is ready; separate reviewers challenge the conclusions; engineers step in when the next decision requires judgment. Other workflows can reuse the same machinery with different states, instructions, and events.From one workflow to many. The Performance Factory can coordinate agents across workflows, with agents in one workflow creating tasks for another.Currently, our Regression Workflow starts when an alert fires. However, we’re working on more proactive ways for the Performance Factory to find slowdowns and optimizations even when no alert fires. We want agents to use the large amount of fine-grained performance data we already collect to spot regressions our alerts miss or discover optimizations. By comparing different kinds of data (batches of CPU and memory profiles, heap dumps, and request traces across releases), an agent might notice a small increase in CPU for a given request. It can then open a task in the Regression Workflow to trace the increase to its cause, implement a fix, and open a PR for an engineer to review.In cases where we already know what to look for, we’re working to encode known signals into more Performance Factory workflows. Our service rightsizing skill, for example, helps agents spot autoscaling settings that keep more replicas running than a service needs. When we learn to recognize a pattern like that, we want to build and regularly run a workflow for it across all our services, constantly optimizing in a rapidly changing environment. With the Performance Factory, what an engineer learns from one slowdown can shape how we investigate and fix the next one, even months later in a different service.Next time you’re using ChatGPT and notice a slowdown, there’s a good chance the Performance Factory is already figuring out why. Today, the bottleneck may be waiting for an engineer to review and merge the fix. We’re already exploring whether agents can do this themselves. As product development keeps accelerating with Codex, performance systems need to become increasingly autonomous and self-improving to keep up. Codex already helps us build ChatGPT faster. Now it’s helping us keep ChatGPT fast.

Read More »

StarlingX 13.0 updates the network stack for distributed edge deployments

Edge sites do not always come with the network gear that a data center takes for granted. That’s a challenge the open-source StarlingX project from the OpenInfra Foundation is now tackling in its 13.0 update. StarlingX is an open-source distributed cloud platform that combines Linux, Kubernetes, OpenStack, and Ceph. The OpenInfra Foundation hosts the project, and operators including Verizon, Vodafone, T-Systems and KDDI use it for 5G and Open Radio Access Network (O-RAN) infrastructure. Earlier this year, the StarlingX 12.0 update added precision timing capabilities to help networking stay on time. The 13.0 update tackles a different set of issues. Key features include: Gateway API support. Calico-based support is available to hosted applications, while platform services still use Ingress NGINX Optional certificate authority. The Enterprise Java Beans Certificate Authority (EJBCA) runs on the platform and serves certificates to hosted applications. Subcloud restore. A backup restores directly onto a factory-installed node at a subcloud, a remote edge site, with no operating system reinstall. Direct upgrades. Operators can upgrade from two releases back with a single reboot per host. Layer 2 switching. A new Open vSwitch application lets servers at sites with no router next to them bridge traffic and connect directly to aggregation routers. “The OpenvSwitch application adds Layer 2 switching to the K8S platform,” Greg Waines, a senior member of technical staff at Wind River and a StarlingX Technical Steering Committee member, told Network World. “A server can bridge traffic between its SR-IOV network interfaces and other servers, and it can forward traffic to the site routers.”

Read More »

Fuel constraints could challenge grid this winter, despite resource improvements: NERC

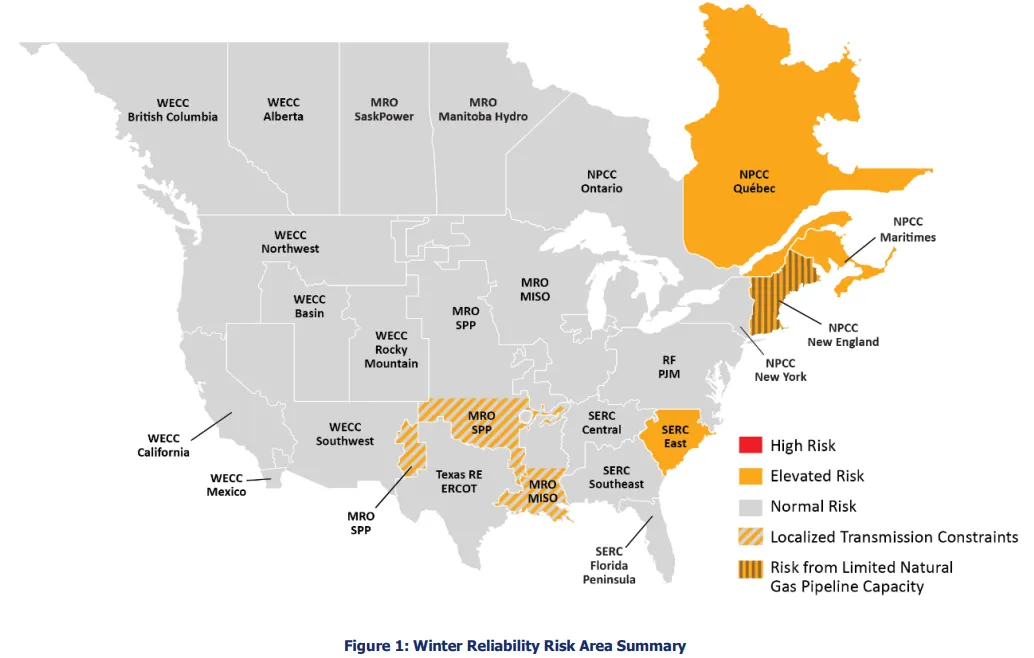
Listen to the article 3 min This audio is auto-generated. Please let us know if you have feedback. Dive Brief: The bulk power system’s winter reliability outlook has improved since last season, but the El Niño weather pattern and potential for extreme cold can present challenges that grid operators must remain aware of, the North American Electric Reliability Corp. said Wednesday in its annual seasonal outlook. On-peak capacity resources grew 26.2 GW over the 2025-26 winter, a 2.4% increase led by batteries and gas-fired generation, according to the 2026–2027 Winter Reliability Assessment. A slowdown in generator retirements is also contributing to the improved resource outlook, NERC said. The reliability watchdog’s outlook identified no areas facing a high risk of resource shortfalls this winter, but it found some areas in the Midwest, Southeast and New England where transmission system constraints, pipeline constraints and fuel risk scenarios may present problems during periods of extreme weather. Dive Insight: Electric demand is growing, but “there has also been strong growth in resources,” Mark Olson, manager of reliability assessments, said Wednesday in a call discussing the outlook. “In many ways, the industry is on better footing going into winter this year,” he said. However, Olson added that “historically, winter is the toughest operating period for the North American electric grid.”  While some models show the El Niño weather pattern can bring milder-than-average conditions that are a help to a constrained power system, “the reality is that extreme storms with ice and abnormal cold temperatures can lie within those averages,” Olson said. Retrieved from North American Electric Reliability Corp. “We’re talking to our industry stakeholders about the need for extra vigilance. El Niño is a variable that adds to uncertainty for the winter,” he said. Peak winter electric heating demand often coincides with higher residential gas usage,

Read More »

The Download: a living liver, a billion-dollar battery deal, and AI hype

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. A human liver has been kept alive outside the body for seven weeks, setting a record Researchers in Australia claim they’ve kept a human liver alive on life support outside the body for seven weeks, smashing the previous record of about two weeks. They achieved the feat by connecting a donated liver to a system of automated pumps and sensors that fed the organ nutrients, supplied it with blood, and whisked away waste. The approach could open up new possibilities in biomedical engineering, from repairing damaged organs to growing new ones. Some researchers are even exploring artificial wombs.
Take a closer look at the technology keeping human organs alive. —Antonio Regalado
What a billion-dollar deal says about the US battery market After a tough few years littered with high-profile failures, there’s some positive news for next-generation batteries in the US: Sila has signed a deal with battery maker Panasonic Energy to supply silicon-carbon anode material that could be worth more than $1 billion. The agreement will help Sila scale production, potentially bringing smaller, lighter batteries to market. But it also reveals how battery politics have shifted. The factory is backed by a $1.4 billion loan from the Trump administration’s Defense Department—and the industry is increasingly focused on geopolitics rather than the energy transition. Find out what this deal reveals about the US battery industry. —Casey Crownhart This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. The AI Hype Index returns Separating AI reality from hyped-up fiction isn’t always easy. That’s why we’ve created the AI Hype Index—a simple, at-a-glance summary of what’s shaping the industry right now.  The latest edition tracks AI’s spread across everything from literary prizes and cyberattacks to a Grok-ified version of The Odyssey. See where it all landed on this month’s index. The must-reads

I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Anthropic has raised $81 billion in the biggest-ever IPOIt eclipsed SpaceX as the largest stock-market debut. (Bloomberg $)+ Its stated mission could conflict with shareholders’ interests. (NYT $)+ The IPO comes amid new safety fears about its AI advances. (FT $)+ Its performance will test the strength of the AI boom. (BBC)+ What even is the AI bubble? (MIT Technology Review) 2 China is reportedly seeking Nvidia chips for AI-powered weaponsBeijing is trying to circumvent US export controls. (CNBC)+ Alibaba tapped Nvidia to support a military-linked lab. (NYT $)+ When the US military implemented AI, civilian deaths rose. (Intercept)+ “Humans in the loop” in AI war is an illusion. (MIT Technology Review) 3 Elon Musk has joined Silicon Valley’s retreat from TrumpHe called his midterm spending “foolish” and broke with MAGA. (FT $)+ OpenAI and Palantir leaders have also struck new tones. (Gizmodo)+ Silicon Valley got the midterms badly wrong. (MIT Technology Review) 4 Ukraine used relay drones to strike Putin’s bridge without StarlinkThe strike showed how it’s learning to fight without SpaceX. (Ars Technica)+ Musk has denied Kyiv’s claims about restrictions on Starlink. (CNBC) 5 A major cyberattack has hit the European CommissionIt may have exposed large amounts of staff personal data. (Politico)+ Trump has blamed Minnesota for water system hacks. (ABC) 6 Trump may force US firms to disclose their use of Chinese AIThe proposal aims to discourage reliance on Chinese models. (Reuters $) 7 The US has slashed funding for biomedical science abroadIt’s also weakened oversight of foreign grants. (Economist $)
8 AI datacentres are set to drive a 70% rise in emissions by 2030The US and China are turning to fossil fuels to power AI. (Guardian)+ The climate case for AI has not been made. (MIT Technology Review) 9 Grand Theft Auto 6 has become the best-reviewed game everIt scored 99 out of 100 on review aggregation site Metacritic. (BBC)+ Schools and businesses are bracing for “GTA Flu” season. (NYT $)
10 A new underwater research station aims to protect coral reefsAquanauts there will monitor struggling ecosystems. (New Scientist $) Quote of the day “Here are some of the smartest people on the planet being completely idiotic.” —Thomas Nagel, a philosopher and professor emeritus at NYU, tells Wired why he objects to Anthropic giving Claude more independence, just as the company makes its record-breaking stock-market debut. One more thing China has approved the world’s first invasive brain-computer chip—here’s what’s next Sitting in the courtyard of his house in China’s Henan province last October, Dong Hui decided to try holding a pen. Six years after a car accident left him paralyzed from the neck down, he slowly wrote his name, “Thank you,” and the date. The breakthrough was made possible by a brain implant called NEO. In March, it became the world’s first invasive brain-computer interface approved for use beyond clinical trials. The approval is expected to accelerate China’s push to become a global leader in brain implants.
Here’s how China reached the milestone—and what it means for the future of BCIs. —You Xiaoying We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Chloe the dog loves Chinese food even more than her owner.+ Getting outdoors can do wonders not only for your mood, but also for your diet.+ Sit back and enjoy the intriguing tale of the 12-year-old DJ who pioneered record scratching.+ This extraordinary collection of Cold War-era matchbox labels is a treasure trove of Soviet art.

Read More »

Sovereign AI is about control, not just location

Guetari was open about the term itself being fuzzy. “Sovereignty is very vague and not always clear,” he told me. “It’s about control, auditability, observability.” He drew a line between data locality, meaning the data stays in-country, and sovereignty, which he described as being “more about control, control of what happens to your data and your workload.” He then made the case for why F5 belongs in that conversation: “This is what we have been doing for two decades.” F5 has always sat in the data path, deciding what an application can communicate with, enforcing security rules, and logging what happened. For a regulated bank or government agency, the ability to reconstruct exactly what happened after an incident is worth more than a press release about a data center’s location. The token is the new unit of economics The most interesting part of my conversation with Guetari wasn’t about security. It was about business models. He argued that every successful technology business has found the right unit to monetize. “The cloud is selling the unit of the cloud, which is the CPU core, very well. SaaS is the seat,” he said. “Telcos have been very successful early on using the voice minute, and then they moved to the gigabyte. Sooner or later, that unit will be the token, and most telcos will have to move to the token. And the ones who will not go to token, unfortunately, will be just pipes.”

Read More »

Grid operators need data center ride-through rules that protect reliability

Listen to the article 7 min This audio is auto-generated. Please let us know if you have feedback. Alan Cooper is CEO of ON.energy, a developer of power infrastructure.  On July 22, a mechanical failure forced a 230-kV transmission line in Northern Virginia offline. Within milliseconds, grid protection systems cleared the fault, as they are designed to do. The event would not have been a particularly noteworthy story, had it stopped there. It’s what happened next, though, that pointed to a growing challenge for grid reliability. Optional Caption Permission granted by Alan Cooper In response to the fault, data centers that had been drawing nearly 4 GW of energy, close to 4% of PJM’s load, collectively disconnected and switched to their on-site backup generation. The move sent voltage and frequency spiking across the system, a technically wonky but threatening result that caused power flickers as far away as Chicago. Thankfully, the prevailing grid conditions were strong enough to absorb the shock of the fault, so the grid held. But if the same event had hit Texas or even Northern Virginia at a time of higher demand, it could have caused a widespread outage. In West Texas, the Electric Reliability Counil of Texas estimates that a loss of as little as 3.2 GW could threaten grid reliability. The power sector is not unfamiliar with the need for things hooked up to the electricity grid to “ride through” disturbance events. In 2023, the Federal Energy Regulatory Commission told the North American Electricity Reliability Corp. to develop requirements that inverter-based supply resources like wind and solar facilities must follow to ensure they “ride through,” i.e., stay online, during certain disturbances. And this time around, NERC, FERC and several grid regions have been quick to identify a similar need for large loads to adhere

Read More »

How OpenAI’s Performance Factory keeps ChatGPT fast

The staggering pace of agentic development has made traditional approaches to performance engineering unsustainable. To keep up, we built the Performance Factory, an autonomous system that uses the full capabilities of Codex and our models to find and fix regressions at an unprecedented speed. The Performance Factory, which runs in the cloud and automates investigating and resolving performance problems, enables us to keep pace with the ambition of our roadmap.In the Performance Factory, our engineers define workflows for recurring jobs and write instructions for the Codex agents that carry them out. In particular, the Regression Workflow opens a task when a performance alert fires. An agent investigates the slowdown, records its findings in the task, and proposes a fix for an engineer to review. After deployment, another agent picks up the same task to check whether performance has returned to baseline. From investigating to authoring the fix to verifying mitigation, this first workflow in the Performance Factory has automated the entire process of fixing regressions. In just over three months, the Regression Workflow tracked more than 1,700 investigations and root caused over 600 cases. That’s 17 automated investigations every day.Here, we’ll share how our use of Codex evolved into what’s now the Performance Factory, walk through our first running workflow, and share early lessons from building and running agent workflows in production.The path from manual investigations to automated workflowsAs we used Codex for more of our performance work, we noticed a progression in how our team worked. We hope other service teams can learn from our process as they adopt agentic workflows in other domains.Software work evolves from manual labor to partnering with machines to agent factories.1. Pre-Codex. Before Codex, engineers manually examined metrics and logs, compared traces, debugged live machines, and read code to investigate a slowdown. This work was time consuming, and knowing where to look often required deep knowledge of the service. Relevant signals were easy to miss. When we encountered the same kinds of problems repeatedly—like regressions in ChatGPT’s first token latency—we built advanced tools, like CPU and allocation profilers, to make those investigations easier. Over time, we accumulated more than 30 performance tools.2. Codex as a partner. Once we had Codex as a partner, engineers could ask, “Why did this get slower?” and work with Codex to investigate, even in an unfamiliar system. Codex could search large codebases, find relevant metrics and traces, follow interactions across services, and do appropriate profiling to piece together what had happened. But engineers still had to steer the process, knowing which performance tools to use and how to guide the investigation. Difficult investigations were more debuggable for more people, with less expertise and time required.3. Reusable skills. To automate further, we captured our performance team’s investigation process in a shared skill called perf-forensics. It tells Codex which tools are available, when to use them, and how to work through a slowdown so Codex can try to resolve the problem from a few angles:Find when the slowdown beganIdentify the affected requestsInvestigate whether deployments or configuration changes could explain itWe tested and refined the perf-forensics skill using evals based on past regressions. For the types of regressions we focused on (for example, ChatGPT latency and availability drops), we could now give Codex an alert and get back a diagnosis in a single run, without guiding it through each step.4. The human proxy. As we added and refined perf-related Codex skills like perf-forensics, we started to feel like a proxy between our alerts and Codex. An alert would fire, and an engineer would simply copy and paste it into Codex with the right skill, then paste the findings back into Slack.5. Automated investigations. Next, we moved investigations to the cloud so an alert could start a Codex session automatically. Codex investigated the slowdown and posted its findings in the Slack thread, but the automation ended with that reply. An engineer still had to pick up the diagnosis, develop a fix, and check whether it worked after deployment. As alerts accumulated, even figuring out which regressions needed attention meant sifting through Slack threads.6. The factory. We built the Performance Factory to run end-to-end agentic performance engineering workflows. It tracks what each active task needs next and assigns an agent when that step is ready. Each task keeps its state and findings, so work can pass between agents and engineers and resume after a code review or deployment. For a regression, the work starts with investigating an alert and ends with verifying recovery in production. We can turn common optimizations into workflows that run regularly across our services. A workflow that spots a potential optimization can open a task in another workflow to test and implement it.The Performance Factory system’s four partsThe Performance Factory is made up of four components: a task tracker with configurable workflows, a dispatch loop that assigns ready work to agents, an API that runs Codex in the cloud, and subscriptions that wake agents when something changes (such as a GitHub review comment posting or a deployment completing).Performance Factory consists of a task service, dispatch loop, cloud execution, and subscriptions.Task service with configurable workflowsThe task service is where engineers define workflows by adding configuration files and prompts for the agents to follow, written in Markdown. The configuration lists the states a task can move through, the allowed transitions, and which steps need an engineer. Separate prompts tell agents what to do at each step.Plain textA code change task contains a configuration file, along with Markdown prompts for implementing and reviewing.Each piece of work becomes a task in a workflow, and all workflows are visible in a UI. Engineers can see what’s open, follow progress, and share a task with a teammate who might have more context or be able to help with the next step.Dispatch loop that assigns workA dispatch loop periodically checks which tasks are ready for the next step. It assigns an agent to each task by starting a Codex turn with the instructions for the task’s current state. The agent records its progress on the task and moves it to the next state if it completes the step.Codex in the cloudOnce a task is assigned, the agent needs a place to do the work, with access to the same tools an engineer would use. We built an internal API to programmatically invoke a Codex turn in the cloud. The Codex turn runs on an environment inside our network, with access to our code repositories and the observability tools our engineers use, such as metrics, logs, traces, CPU profiles, and memory snapshots.The agent runs under a service identity, so we can scope its permissions and see which actions came from our performance agents. Moving agentic work to the cloud lets us run work in parallel without relying on engineers’ laptops being open or manually managing individual cloud development boxes.Subscriptions that wake the agent when something changesSome work has to wait for a person or a deployment; an agent shouldn’t have to keep running in the meantime. When a task needs to wait, it can subscribe to events like review comments or failed CI checks on a GitHub pull request to get notified when it’s time to pick the work back up. When an incoming event matches the subscription, the task becomes ready again and the dispatch loop can then assign an agent to continue the work.The first workflow: from alert to recoveryFinding, root causing, and solving regressions is the first workflow we built inside the Performance Factory. We call it the Regression Workflow. A performance regression moves through several stages: needs investigation, root caused, fix proposed, and resolved, so we built the automated workflow to reflect and move a task through those same stages.When one of its configured performance alerts fires, the Regression Workflow opens a task that agents pick up and move across these stages. The task records its status and key findings outside of any one agent’s context so that other agents or engineers can pick up the work. Engineers can follow the work in Slack or the Regression Workflow UI, add context, and review proposed changes. After a fix is deployed, an agent checks whether the performance has recovered to its original state before resolving the task.Performance Factory regression workflowA regression is detected.An agent finds the cause and proposes a fix.An engineer takes over and decides what ships.After deployment, the agent wakes up to check recovery.Still regressed? Back to investigation.A regression is detected.A regression is detected.PauseDetectedSystemFind root causeAgentPropose fixAgentReview & deployEngineerVerify recoveryAgentResolved Active stage: DetectedThe Regression Workflow’s steps include finding the root cause, proposing a fix, reviewing and deploying, and verifying recovery.Agents find the root causeFinding the root cause (or causes) is the first major step in the workflow. The agent starts by figuring out which metrics got worse, when they started to change, and which service requests were affected. The perf-forensics skill gives Codex access to the tools our performance engineers use and a playbook for working through those questions.An alert fires when a metric crosses a threshold, but the regression may have started hours earlier. The agent looks back through the data to find when the metric first got worse. It then compares groups of requests: did similar requests actually get slower, or were we serving more requests that were already slow? Those findings point to different causes.Once it knows when and where to look, the agent examines deployments and feature flag changes, then reads the relevant code. It checks when a change actually reached the affected requests and uses logs or traces to test whether the code could explain what happened.Adversarial review strengthens the diagnosisEarly on, agents sometimes stopped at the first plausible explanation they found, and some of those diagnoses turned out to be wrong. To catch these mistakes, we added an adversarial review: a separate Codex session that tries to disprove the proposed diagnosis. The reviewer rechecks the assumptions and tests counterfactuals. If a rollout caused the slowdown, did similar requests that weren’t exposed stay healthy? If the suspected change was rolled back, did the affected metric recover?In one investigation, an agent traced failing ChatGPT conversations to errors in image downloads and marked the cause as found. The Codex reviewer noticed that the internal service responsible for locating files had already recovered while image requests were still failing. The diagnosis did not explain the continuing failures, so the AI reviewer reopened the investigation and recorded what still needed to be established.We’ve had success breaking larger jobs into focused Codex turns. In a manual review of 100 root cause suggestions, we graded 70% as accurate, with 30% needing further refinement or not fully establishing causality. In the Regression Workflow, different turns investigate regressions, challenge diagnoses, and propose fixes to increase accuracy numbers through checks and balances.Fixing the regression is the hard partOnce the diagnosis passes adversarial review, the workflow asks Codex to implement a fix and open a pull request. An engineer reviews the PR and decides whether to merge it. We’ve put a significant amount of work into making this handoff as easy as possible. Each task has a report with an automatically generated summary of the regression, its impact, the root cause, and the proposed fix. We’ve tuned these summaries to be easy to scan, including metrics time series, CPU flame graphs, and traces to help engineers quickly understand the findings and inspect the evidence. Engineers can edit the PR directly or use the diagnosis to write their own fix. If they leave comments on the PR, the workflow wakes an agent to address them.An example task report for a regression shows key details, root cause, and proposed fix.After an engineer deploys the fix, the workflow wakes an agent to check whether performance has returned to its earlier baseline. If it has, the agent marks the task as resolved. If performance has only partially recovered, the agent resolves the original regression and opens a new task for the remaining slowdown, which may have a different cause. If there’s no improvement, the agent records what happened and sends the regression back for investigation.Getting fixes right has been harder than finding the cause. For example, we’ve seen cases where the agent-proposed changes are more complicated than necessary or introduce new issues. Similar to the root cause step, we added an adversarial review of each proposed fix to check whether they address the root cause and help catch bugs or unintended consequences. Some fixes also require higher level architectural decisions. For example, adding a cache might improve performance but introduce stale data. Changes like these benefit from guidance from an engineer who knows the service and can weigh the tradeoffs.We’re building an evaluation and improvement loop using these cases. By comparing the fixes agents propose with the changes engineers ultimately merge, we can better understand where proposals fall short, build evals, and improve the workflow. We’re also working on using synthetic performance tests so agents can measure proposed fixes and revise them before asking an engineer for review. We’re also exploring how agents could use our other agentic review tools to identify low-risk changes and eventually ship those fixes without a human in the loop.What we learnedBuilding and running the Performance Factory has taught us a lot about developing and operating agent workflows in production. Here are some lessons for teams building their own agentic workflows.Protect engineers’ attentionThe raw output from a Codex investigation can be a wall of text that’s hard to parse. It takes effort to figure out what the agent is claiming and track down the graphs to see whether the data backs it up. We want engineers to spend their attention on decisions rather than reconstructing the agent’s work.Agents can investigate more regressions than a team has time to read about. Our first version gave engineers a UI full of findings, but someone still had to decide which information mattered. One regression can also appear as several incidents across alerts, monitors, and channels. The workflow now links related incidents, groups them by the metrics teams care about, and ranks their estimated impact. Engineers can focus on adding context, weighing tradeoffs, and deciding what to ship.Evaluate changes to your agentsUpdating an investigation skill or upgrading the model can make the agent better at diagnosing some cases and worse at others, so we need to test their impact before updating them. We test two things separately: 1) how well the agent investigates and 2) how useful its summaries are to engineers.Evaluating investigationsFor investigations, we backtest against past production incidents. We turn those incidents into a suite of test cases we can rerun when we change the skill. A Codex agent attempts to investigate and resolve the incident, and we compare the agent’s behavior to the actual past resolution data. Each case starts with a fresh Codex investigator and the original signal, stripped of details that might give away the answer.Historical tests need care. Metrics and traces expire, while evidence collected after recovery can give away the cause. A test is only useful if we understand what evidence the investigator could see. The agent can inspect code and query production telemetry within set limits. It cannot use saved memories (notes from earlier investigations), read the incident writeup, or see results from previous runs. We also inspect its transcript afterward for information that might have spoiled the test.We score when the problem began, how large it was, and which requests were affected. We also evaluate how the agent uses evidence to rank possible causes and explain what remains uncertain. An agent can get the timing right and still blame the wrong deployment, so we score those separately.Evaluating agent-to-engineer handoffsWe evaluate task summaries using snapshots of saved tasks. These make particularly good backtests because summarization does not depend on external metrics or traces that expire. A separate grader checks whether an engineer unfamiliar with the system can understand what happened and why it matters, whether useful charts were kept, and whether the proposed next step is supported by the evidence.Turn recurring failures into self-repairLastly, our agents need monitoring just as much as the services they investigate. A broken profiler or a missing permission can keep an agent from verifying what caused a slowdown. Those failures can be hard to spot in the final report, so we run an agent every day to look through messages and logs from recent runs for tool failures and access errors.We use the Performance Factory to self-repair and fix the problems this check uncovers. When the same tool error blocks several investigations, the agent creates a task to fix it. If the cause is clear, an agent proposes a fix, and an engineer reviews the change and decides whether to merge it. After merging changes like this, we also use evals to check whether agents can get past the step that previously blocked them.What’s next: broader applications, proactive monitoringThe Regression Workflow is just one instance of the agent factory pattern that moves tasks through explicit states. Agents advance the task when more work is ready; separate reviewers challenge the conclusions; engineers step in when the next decision requires judgment. Other workflows can reuse the same machinery with different states, instructions, and events.From one workflow to many. The Performance Factory can coordinate agents across workflows, with agents in one workflow creating tasks for another.Currently, our Regression Workflow starts when an alert fires. However, we’re working on more proactive ways for the Performance Factory to find slowdowns and optimizations even when no alert fires. We want agents to use the large amount of fine-grained performance data we already collect to spot regressions our alerts miss or discover optimizations. By comparing different kinds of data (batches of CPU and memory profiles, heap dumps, and request traces across releases), an agent might notice a small increase in CPU for a given request. It can then open a task in the Regression Workflow to trace the increase to its cause, implement a fix, and open a PR for an engineer to review.In cases where we already know what to look for, we’re working to encode known signals into more Performance Factory workflows. Our service rightsizing skill, for example, helps agents spot autoscaling settings that keep more replicas running than a service needs. When we learn to recognize a pattern like that, we want to build and regularly run a workflow for it across all our services, constantly optimizing in a rapidly changing environment. With the Performance Factory, what an engineer learns from one slowdown can shape how we investigate and fix the next one, even months later in a different service.Next time you’re using ChatGPT and notice a slowdown, there’s a good chance the Performance Factory is already figuring out why. Today, the bottleneck may be waiting for an engineer to review and merge the fix. We’re already exploring whether agents can do this themselves. As product development keeps accelerating with Codex, performance systems need to become increasingly autonomous and self-improving to keep up. Codex already helps us build ChatGPT faster. Now it’s helping us keep ChatGPT fast.

Read More »

StarlingX 13.0 updates the network stack for distributed edge deployments

Edge sites do not always come with the network gear that a data center takes for granted. That’s a challenge the open-source StarlingX project from the OpenInfra Foundation is now tackling in its 13.0 update. StarlingX is an open-source distributed cloud platform that combines Linux, Kubernetes, OpenStack, and Ceph. The OpenInfra Foundation hosts the project, and operators including Verizon, Vodafone, T-Systems and KDDI use it for 5G and Open Radio Access Network (O-RAN) infrastructure. Earlier this year, the StarlingX 12.0 update added precision timing capabilities to help networking stay on time. The 13.0 update tackles a different set of issues. Key features include: Gateway API support. Calico-based support is available to hosted applications, while platform services still use Ingress NGINX Optional certificate authority. The Enterprise Java Beans Certificate Authority (EJBCA) runs on the platform and serves certificates to hosted applications. Subcloud restore. A backup restores directly onto a factory-installed node at a subcloud, a remote edge site, with no operating system reinstall. Direct upgrades. Operators can upgrade from two releases back with a single reboot per host. Layer 2 switching. A new Open vSwitch application lets servers at sites with no router next to them bridge traffic and connect directly to aggregation routers. “The OpenvSwitch application adds Layer 2 switching to the K8S platform,” Greg Waines, a senior member of technical staff at Wind River and a StarlingX Technical Steering Committee member, told Network World. “A server can bridge traffic between its SR-IOV network interfaces and other servers, and it can forward traffic to the site routers.”

Read More »

Fuel constraints could challenge grid this winter, despite resource improvements: NERC

Listen to the article 3 min This audio is auto-generated. Please let us know if you have feedback. Dive Brief: The bulk power system’s winter reliability outlook has improved since last season, but the El Niño weather pattern and potential for extreme cold can present challenges that grid operators must remain aware of, the North American Electric Reliability Corp. said Wednesday in its annual seasonal outlook. On-peak capacity resources grew 26.2 GW over the 2025-26 winter, a 2.4% increase led by batteries and gas-fired generation, according to the 2026–2027 Winter Reliability Assessment. A slowdown in generator retirements is also contributing to the improved resource outlook, NERC said. The reliability watchdog’s outlook identified no areas facing a high risk of resource shortfalls this winter, but it found some areas in the Midwest, Southeast and New England where transmission system constraints, pipeline constraints and fuel risk scenarios may present problems during periods of extreme weather. Dive Insight: Electric demand is growing, but “there has also been strong growth in resources,” Mark Olson, manager of reliability assessments, said Wednesday in a call discussing the outlook. “In many ways, the industry is on better footing going into winter this year,” he said. However, Olson added that “historically, winter is the toughest operating period for the North American electric grid.”  While some models show the El Niño weather pattern can bring milder-than-average conditions that are a help to a constrained power system, “the reality is that extreme storms with ice and abnormal cold temperatures can lie within those averages,” Olson said. Retrieved from North American Electric Reliability Corp. “We’re talking to our industry stakeholders about the need for extra vigilance. El Niño is a variable that adds to uncertainty for the winter,” he said. Peak winter electric heating demand often coincides with higher residential gas usage,

Read More »

The Download: a living liver, a billion-dollar battery deal, and AI hype

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. A human liver has been kept alive outside the body for seven weeks, setting a record Researchers in Australia claim they’ve kept a human liver alive on life support outside the body for seven weeks, smashing the previous record of about two weeks. They achieved the feat by connecting a donated liver to a system of automated pumps and sensors that fed the organ nutrients, supplied it with blood, and whisked away waste. The approach could open up new possibilities in biomedical engineering, from repairing damaged organs to growing new ones. Some researchers are even exploring artificial wombs.
Take a closer look at the technology keeping human organs alive. —Antonio Regalado
What a billion-dollar deal says about the US battery market After a tough few years littered with high-profile failures, there’s some positive news for next-generation batteries in the US: Sila has signed a deal with battery maker Panasonic Energy to supply silicon-carbon anode material that could be worth more than $1 billion. The agreement will help Sila scale production, potentially bringing smaller, lighter batteries to market. But it also reveals how battery politics have shifted. The factory is backed by a $1.4 billion loan from the Trump administration’s Defense Department—and the industry is increasingly focused on geopolitics rather than the energy transition. Find out what this deal reveals about the US battery industry. —Casey Crownhart This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. The AI Hype Index returns Separating AI reality from hyped-up fiction isn’t always easy. That’s why we’ve created the AI Hype Index—a simple, at-a-glance summary of what’s shaping the industry right now.  The latest edition tracks AI’s spread across everything from literary prizes and cyberattacks to a Grok-ified version of The Odyssey. See where it all landed on this month’s index. The must-reads

I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Anthropic has raised $81 billion in the biggest-ever IPOIt eclipsed SpaceX as the largest stock-market debut. (Bloomberg $)+ Its stated mission could conflict with shareholders’ interests. (NYT $)+ The IPO comes amid new safety fears about its AI advances. (FT $)+ Its performance will test the strength of the AI boom. (BBC)+ What even is the AI bubble? (MIT Technology Review) 2 China is reportedly seeking Nvidia chips for AI-powered weaponsBeijing is trying to circumvent US export controls. (CNBC)+ Alibaba tapped Nvidia to support a military-linked lab. (NYT $)+ When the US military implemented AI, civilian deaths rose. (Intercept)+ “Humans in the loop” in AI war is an illusion. (MIT Technology Review) 3 Elon Musk has joined Silicon Valley’s retreat from TrumpHe called his midterm spending “foolish” and broke with MAGA. (FT $)+ OpenAI and Palantir leaders have also struck new tones. (Gizmodo)+ Silicon Valley got the midterms badly wrong. (MIT Technology Review) 4 Ukraine used relay drones to strike Putin’s bridge without StarlinkThe strike showed how it’s learning to fight without SpaceX. (Ars Technica)+ Musk has denied Kyiv’s claims about restrictions on Starlink. (CNBC) 5 A major cyberattack has hit the European CommissionIt may have exposed large amounts of staff personal data. (Politico)+ Trump has blamed Minnesota for water system hacks. (ABC) 6 Trump may force US firms to disclose their use of Chinese AIThe proposal aims to discourage reliance on Chinese models. (Reuters $) 7 The US has slashed funding for biomedical science abroadIt’s also weakened oversight of foreign grants. (Economist $)
8 AI datacentres are set to drive a 70% rise in emissions by 2030The US and China are turning to fossil fuels to power AI. (Guardian)+ The climate case for AI has not been made. (MIT Technology Review) 9 Grand Theft Auto 6 has become the best-reviewed game everIt scored 99 out of 100 on review aggregation site Metacritic. (BBC)+ Schools and businesses are bracing for “GTA Flu” season. (NYT $)
10 A new underwater research station aims to protect coral reefsAquanauts there will monitor struggling ecosystems. (New Scientist $) Quote of the day “Here are some of the smartest people on the planet being completely idiotic.” —Thomas Nagel, a philosopher and professor emeritus at NYU, tells Wired why he objects to Anthropic giving Claude more independence, just as the company makes its record-breaking stock-market debut. One more thing China has approved the world’s first invasive brain-computer chip—here’s what’s next Sitting in the courtyard of his house in China’s Henan province last October, Dong Hui decided to try holding a pen. Six years after a car accident left him paralyzed from the neck down, he slowly wrote his name, “Thank you,” and the date. The breakthrough was made possible by a brain implant called NEO. In March, it became the world’s first invasive brain-computer interface approved for use beyond clinical trials. The approval is expected to accelerate China’s push to become a global leader in brain implants.
Here’s how China reached the milestone—and what it means for the future of BCIs. —You Xiaoying We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Chloe the dog loves Chinese food even more than her owner.+ Getting outdoors can do wonders not only for your mood, but also for your diet.+ Sit back and enjoy the intriguing tale of the 12-year-old DJ who pioneered record scratching.+ This extraordinary collection of Cold War-era matchbox labels is a treasure trove of Soviet art.

Read More »

Sovereign AI is about control, not just location

Guetari was open about the term itself being fuzzy. “Sovereignty is very vague and not always clear,” he told me. “It’s about control, auditability, observability.” He drew a line between data locality, meaning the data stays in-country, and sovereignty, which he described as being “more about control, control of what happens to your data and your workload.” He then made the case for why F5 belongs in that conversation: “This is what we have been doing for two decades.” F5 has always sat in the data path, deciding what an application can communicate with, enforcing security rules, and logging what happened. For a regulated bank or government agency, the ability to reconstruct exactly what happened after an incident is worth more than a press release about a data center’s location. The token is the new unit of economics The most interesting part of my conversation with Guetari wasn’t about security. It was about business models. He argued that every successful technology business has found the right unit to monetize. “The cloud is selling the unit of the cloud, which is the CPU core, very well. SaaS is the seat,” he said. “Telcos have been very successful early on using the voice minute, and then they moved to the gigabyte. Sooner or later, that unit will be the token, and most telcos will have to move to the token. And the ones who will not go to token, unfortunately, will be just pipes.”

Read More »

Diamondback to acquire remaining Double Eagle Midland basin interest in multibillion cash, stock deal

The deal continues Diamondback’s long-running consolidation strategy in the basin. Andrew Dittmar, principal analyst at Enverus Intelligence Research (EIR), said the company has emerged as “the most consistent consolidator in the Midland basin” through a series of deals that have expanded its inventory position, noting Diamondback has spent more than $40 billion on acquisitions since 2020 and now trails only ExxonMobil in ownership of Midland basin inventory and owns more than two times the locations of the third-place exploration and production company.  Dittmar said the latest deal strengthens Diamondback’s exposure to the Barnett-Woodford, which he described as “the largest undeveloped oil expansion opportunity in US shale.” Along with news of the acquisition, Van’t Hof reported early results from the operator’s first full-section Barnett development in the Spanish Trail area of Midland County. The project consists of four 10,000-ft lateral wells that at peak produced about 7,500 b/d of oil and 37 MMcfd of natural gas, exceeding internal expectations and supporting plans for broader Barnett development beginning in 2027, he said.  Diamondback expects the transaction to close Dec. 21, 2026, subject to customary closing conditions.

Read More »

ExxonMobil Guyana starts production at Uaru

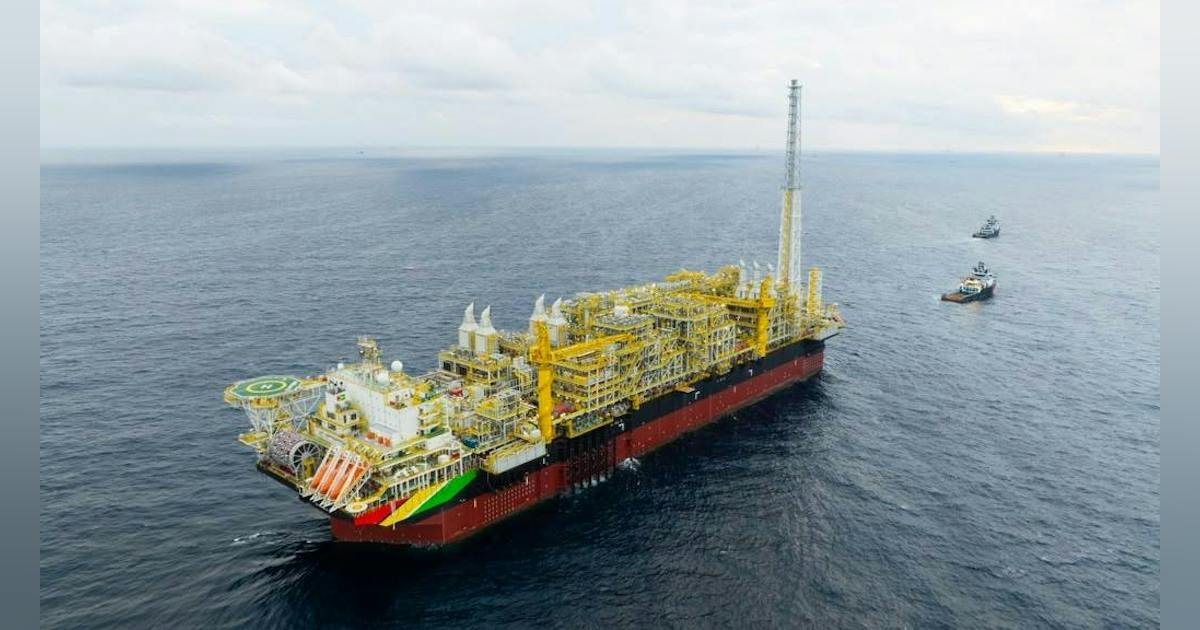
@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } ExxonMobil Guyana Ltd. started production at Uaru, raising Guyana’s installed crude oil production capacity to 1.1 million b/d. With production now underway, the Errea Wittu FPSO is slated to achieve its initial production capacity of 250,000 b/d in first-quarter 2027. Equipped with a storage capacity of 2 million bbl, Errea Wittu becomes the fifth FPSO operating in Stabroek block. ExxonMobil Guyana operates Stabroek block (45%) on behalf of partners Hess Guyana Exploration Ltd. (30%), and CNOOC Petroleum Guyana Ltd. (25%).

Read More »

China’s oil demand falls 7.1% as economic weakness deepens

In September, China’s oil demand fell sharply by 1.3 million b/d year-on-year (y-o-y), a 7.1% decline, according to latest data from the International Energy Agency (IEA). This drop is nearly double the decline seen in August and only slightly less than the 1.4-million b/d slump recorded in June following the Iran-related conflict. According to IEA data, the decline in demand has affected virtually all categories of petroleum products. Demand for liquefied petroleum gas (LPG)/ethane, naphtha, gasoline, diesel, and fuel oil each fell by about 200,000-250,000 b/d. In percentage terms, naphtha demand dropped by 11%—nearly twice the 6% decline seen in LPG/ethane, another petrochemical feedstock. This reflects an ongoing shift in the feedstock mix for steam crackers, which are increasingly favoring LPG and ethane over naphtha. Demand for gasoline and diesel, the primary fuels for transportation, both fell by about 5% y-o-y. China’s transition toward the electrification of passenger vehicles and trucks is far exceeding that of any other nations, a trend further accelerated by surging fuel prices, IEA said. Retail prices for gasoline and diesel in China have risen by about 25% y-o-y, according to GlobalPetrolPrices, hovering just below the all-time highs reached in mid-2022. Meanwhile, sluggish economic growth continues to weigh on oil consumption and overall demand. The downturn in China’s real estate market has entered its sixth year without yet hitting bottom, persistently eroding household wealth and undermining economic confidence. In the first 9 months of 2026, real estate investment fell by 20.6% y-o-y—an acceleration from the 19.9% ​​decline recorded between January-August. The latest data for October show that economic momentum in industrial output and retail sales continues to weaken. This prolonged slump has severely dampened public sentiment; since the beginning of 2026, the consumer confidence index has remained near post-pandemic lows. Exports have played a growing role

Read More »

People and Vertical AI: The responsible and trusted framework for energy and water

I have always held a simple conviction — energy and water utilities should not be spectators to the AI transformation of their own industry. They should shape it, together with the partners and technologists building alongside them. That conviction matters because few industries carry the weight that energy and water do. They are the services every other part of modern life is built on — be it homes, hospitals, schools, businesses, data centers and increasingly, the AI economy itself. When they work, they are invisible. When they fail, everything else stops. Their success is measured in three outcomes the public feels directly: affordability, reliability and trust. Rising energy costs, extreme weather, electrification and the growing demand from large loads are putting these outcomes under increasing pressure. At the same time, utilities are being asked to modernize operations, make better use of data and respond faster to changing customer and grid demands. This is changing the conversation around AI. The question is no longer simply what AI can do, but where it can deliver value, how much autonomy it should have and what safeguards must govern its use. At this year’s WE3 Global AI Summit, conversations among energy and utility leaders reflected this shift. As AI moves from individual applications into customer, workforce, business and grid operations, the industry must think beyond capability to the conditions under which AI can be trusted to act. My belief is that the answer lies in People + Vertical AI: an approach that combines industry-specific intelligence with human experience, judgment and accountability. Vertical AI brings the data, domain knowledge and operational context required to work within the realities of energy and water. People establish its purpose, define its boundaries and remain accountable for its outcomes. Four principles should guide this approach. 1. Convergence: Bringing customers

Read More »

People and Vertical AI: The new operating model for energy and utilities

For generations, the energy and utility industry has depended on the judgment of its people.  Across the industry, people are responsible for keeping energy and water running and serving the communities that depend on them. A field crew is there when a community needs power restored. A grid operator carries the responsibility of keeping the network stable and reliable. A customer service representative is often the human connection between a customer and the utility service. An engineer makes decisions that can shape the safety, resilience and reliability of infrastructure for decades.  That expertise remains essential. What has changed is the complexity surrounding it.  Electrification, distributed energy resources, renewable generation, electric vehicles, extreme weather, aging infrastructure, affordability pressures, rising customer expectations and data centers becoming new energy consumers are all connecting decisions that were once managed independently.  The industry has spent decades digitizing those decisions, generating more data along the way. The challenge now is different: how do you make that intelligence work together and make the expertise of the people using it scalable?  This is where AI has to evolve beyond generic intelligence to a Vertical AI approach built around the specific context, complexity and interconnected realities of the energy and utility industry.  The opportunity is not to automate the people who run the industry. It is to give them better context, better intelligence and the ability to extend their judgment across more decisions, more customers and more of the ecosystem than was previously possible.  That is the premise behind People + Vertical AI.  From Human Expertise to Connected Intelligence  People + Vertical AI is not a technology layer placed on top of existing operations. It is an operating model in which Vertical AI works alongside people, connecting information across the enterprise while people provide judgment, accountability and context.  The

Read More »

Energy Secretary Keeps Critical, Coal-Fired Generation Operational Ahead of Winter in the Midwest

WASHINGTON—The U.S. Department of Energy (DOE) issued an emergency order to address critical grid reliability issues in the Midwest. The emergency order directs the Midcontinent Independent System Operator (MISO), in coordination with Consumers Energy Company, to ensure that the coal-fired J.H. Campbell Generating Plant (Campbell Plant) in West Olive, Michigan, is available to operate and meet emergency needs while employing economic dispatch to minimize costs for hardworking American families and businesses. The Campbell Plant was originally slated to shut down on May 31, 2025, 15 years before the end of its scheduled design life.  “President Trump and the Energy Department remain committed to doing everything in our power to stop power outages for American families and businesses,” said U.S. Secretary of Energy Chris Wright. “Ensuring coal plants such as the Campbell Plant are available to operate has prevented blackouts and likely saved lives. Americans deserve access to affordable, reliable, and secure electricity regardless of whether the wind is blowing or the sun is shining.” Thanks to President Trump, coal generating plants across the country are being saved from premature retirement. For example, in 2025, more than 17 gigawatts of coal-fired electricity generation were saved from going offline. During periods of peak electricity demand, many of those plants keep the lights on.  The emergency conditions that led to the issuance of the original order persist. A joint report from the Federal Energy Regulatory Commission (FERC), the North American Electric Reliability Corporation (NERC), and NERC’s Regional Entities highlights how events that occurred during the Winter 2026 Arctic Cold Period, including Winter Storm Fern, demonstrated the need for dispatchable generation capacity from facilities like the Campbell Plant.  This order is in effect from November 15, 2026, through February 12, 2027. 

Read More »

AI means the end of internet search as we’ve known it

We all know what it means, colloquially, to google something. You pop a few relevant words in a search box and in return get a list of blue links to the most relevant results. Maybe some quick explanations up top. Maybe some maps or sports scores or a video. But fundamentally, it’s just fetching information that’s already out there on the internet and showing it to you, in some sort of structured way.  But all that is up for grabs. We are at a new inflection point. The biggest change to the way search engines have delivered information to us since the 1990s is happening right now. No more keyword searching. No more sorting through links to click. Instead, we’re entering an era of conversational search. Which means instead of keywords, you use real questions, expressed in natural language. And instead of links, you’ll increasingly be met with answers, written by generative AI and based on live information from all across the internet, delivered the same way.  Of course, Google—the company that has defined search for the past 25 years—is trying to be out front on this. In May of 2023, it began testing AI-generated responses to search queries, using its large language model (LLM) to deliver the kinds of answers you might expect from an expert source or trusted friend. It calls these AI Overviews. Google CEO Sundar Pichai described this to MIT Technology Review as “one of the most positive changes we’ve done to search in a long, long time.”
AI Overviews fundamentally change the kinds of queries Google can address. You can now ask it things like “I’m going to Japan for one week next month. I’ll be staying in Tokyo but would like to take some day trips. Are there any festivals happening nearby? How will the surfing be in Kamakura? Are there any good bands playing?” And you’ll get an answer—not just a link to Reddit, but a built-out answer with current results.  More to the point, you can attempt searches that were once pretty much impossible, and get the right answer. You don’t have to be able to articulate what, precisely, you are looking for. You can describe what the bird in your yard looks like, or what the issue seems to be with your refrigerator, or that weird noise your car is making, and get an almost human explanation put together from sources previously siloed across the internet. It’s amazing, and once you start searching that way, it’s addictive.
And it’s not just Google. OpenAI’s ChatGPT now has access to the web, making it far better at finding up-to-date answers to your queries. Microsoft released generative search results for Bing in September. Meta has its own version. The startup Perplexity was doing the same, but with a “move fast, break things” ethos. Literal trillions of dollars are at stake in the outcome as these players jockey to become the next go-to source for information retrieval—the next Google. Not everyone is excited for the change. Publishers are completely freaked out. The shift has heightened fears of a “zero-click” future, where search referral traffic—a mainstay of the web since before Google existed—vanishes from the scene.  I got a vision of that future last June, when I got a push alert from the Perplexity app on my phone. Perplexity is a startup trying to reinvent web search. But in addition to delivering deep answers to queries, it will create entire articles about the news of the day, cobbled together by AI from different sources.  On that day, it pushed me a story about a new drone company from Eric Schmidt. I recognized the story. Forbes had reported it exclusively, earlier in the week, but it had been locked behind a paywall. The image on Perplexity’s story looked identical to one from Forbes. The language and structure were quite similar. It was effectively the same story, but freely available to anyone on the internet. I texted a friend who had edited the original story to ask if Forbes had a deal with the startup to republish its content. But there was no deal. He was shocked and furious and, well, perplexed. He wasn’t alone. Forbes, the New York Times, and Condé Nast have now all sent the company cease-and-desist orders. News Corp is suing for damages.  People are worried about what these new LLM-powered results will mean for our fundamental shared reality. It could spell the end of the canonical answer. It was precisely the nightmare scenario publishers have been so afraid of: The AI was hoovering up their premium content, repackaging it, and promoting it to its audience in a way that didn’t really leave any reason to click through to the original. In fact, on Perplexity’s About page, the first reason it lists to choose the search engine is “Skip the links.” But this isn’t just about publishers (or my own self-interest).  People are also worried about what these new LLM-powered results will mean for our fundamental shared reality. Language models have a tendency to make stuff up—they can hallucinate nonsense. Moreover, generative AI can serve up an entirely new answer to the same question every time, or provide different answers to different people on the basis of what it knows about them. It could spell the end of the canonical answer. But make no mistake: This is the future of search. Try it for a bit yourself, and you’ll see. 

Sure, we will always want to use search engines to navigate the web and to discover new and interesting sources of information. But the links out are taking a back seat. The way AI can put together a well-reasoned answer to just about any kind of question, drawing on real-time data from across the web, just offers a better experience. That is especially true compared with what web search has become in recent years. If it’s not exactly broken (data shows more people are searching with Google more often than ever before), it’s at the very least increasingly cluttered and daunting to navigate.  Who wants to have to speak the language of search engines to find what you need? Who wants to navigate links when you can have straight answers? And maybe: Who wants to have to learn when you can just know?  In the beginning there was Archie. It was the first real internet search engine, and it crawled files previously hidden in the darkness of remote servers. It didn’t tell you what was in those files—just their names. It didn’t preview images; it didn’t have a hierarchy of results, or even much of an interface. But it was a start. And it was pretty good.  Then Tim Berners-Lee created the World Wide Web, and all manner of web pages sprang forth. The Mosaic home page and the Internet Movie Database and Geocities and the Hampster Dance and web rings and Salon and eBay and CNN and federal government sites and some guy’s home page in Turkey. Until finally, there was too much web to even know where to start. We really needed a better way to navigate our way around, to actually find the things we needed.  And so in 1994 Jerry Yang created Yahoo, a hierarchical directory of websites. It quickly became the home page for millions of people. And it was … well, it was okay. TBH, and with the benefit of hindsight, I think we all thought it was much better back then than it actually was. But the web continued to grow and sprawl and expand, every day bringing more information online. Rather than just a list of sites by category, we needed something that actually looked at all that content and indexed it. By the late ’90s that meant choosing from a variety of search engines: AltaVista and AlltheWeb and WebCrawler and HotBot. And they were good—a huge improvement. At least at first.   But alongside the rise of search engines came the first attempts to exploit their ability to deliver traffic. Precious, valuable traffic, which web publishers rely on to sell ads and retailers use to get eyeballs on their goods. Sometimes this meant stuffing pages with keywords or nonsense text designed purely to push pages higher up in search results. It got pretty bad. 
And then came Google. It’s hard to overstate how revolutionary Google was when it launched in 1998. Rather than just scanning the content, it also looked at the sources linking to a website, which helped evaluate its relevance. To oversimplify: The more something was cited elsewhere, the more reliable Google considered it, and the higher it would appear in results. This breakthrough made Google radically better at retrieving relevant results than anything that had come before. It was amazing.  Google CEO Sundar Pichai describes AI Overviews as “one of the most positive changes we’ve done to search in a long, long time.”JENS GYARMATY/LAIF/REDUX For 25 years, Google dominated search. Google was search, for most people. (The extent of that domination is currently the subject of multiple legal probes in the United States and the European Union.)  
But Google has long been moving away from simply serving up a series of blue links, notes Pandu Nayak, Google’s chief scientist for search.  “It’s not just so-called web results, but there are images and videos, and special things for news. There have been direct answers, dictionary answers, sports, answers that come with Knowledge Graph, things like featured snippets,” he says, rattling off a litany of Google’s steps over the years to answer questions more directly.  It’s true: Google has evolved over time, becoming more and more of an answer portal. It has added tools that allow people to just get an answer—the live score to a game, the hours a café is open, or a snippet from the FDA’s website—rather than being pointed to a website where the answer may be.  But once you’ve used AI Overviews a bit, you realize they are different.  Take featured snippets, the passages Google sometimes chooses to highlight and show atop the results themselves. Those words are quoted directly from an original source. The same is true of knowledge panels, which are generated from information stored in a range of public databases and Google’s Knowledge Graph, its database of trillions of facts about the world. While these can be inaccurate, the information source is knowable (and fixable). It’s in a database. You can look it up. Not anymore: AI Overviews can be entirely new every time, generated on the fly by a language model’s predictive text combined with an index of the web. 
“I think it’s an exciting moment where we have obviously indexed the world. We built deep understanding on top of it with Knowledge Graph. We’ve been using LLMs and generative AI to improve our understanding of all that,” Pichai told MIT Technology Review. “But now we are able to generate and compose with that.” The result feels less like a querying a database than like asking a very smart, well-read friend. (With the caveat that the friend will sometimes make things up if she does not know the answer.)  “[The company’s] mission is organizing the world’s information,” Liz Reid, Google’s head of search, tells me from its headquarters in Mountain View, California. “But actually, for a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you.”  That second concept—accessibility—is what Google is really keying in on with AI Overviews. It’s a sentiment I hear echoed repeatedly while talking to Google execs: They can address more complicated types of queries more efficiently by bringing in a language model to help supply the answers. And they can do it in natural language. 
That will become even more important for a future where search goes beyond text queries. For example, Google Lens, which lets people take a picture or upload an image to find out more about something, uses AI-generated answers to tell you what you may be looking at. Google has even showed off the ability to query live video.  When it doesn’t have an answer, an AI model can confidently spew back a response anyway. For Google, this could be a real problem. For the rest of us, it could actually be dangerous. “We are definitely at the start of a journey where people are going to be able to ask, and get answered, much more complex questions than where we’ve been in the past decade,” says Pichai.  There are some real hazards here. First and foremost: Large language models will lie to you. They hallucinate. They get shit wrong. When it doesn’t have an answer, an AI model can blithely and confidently spew back a response anyway. For Google, which has built its reputation over the past 20 years on reliability, this could be a real problem. For the rest of us, it could actually be dangerous. In May 2024, AI Overviews were rolled out to everyone in the US. Things didn’t go well. Google, long the world’s reference desk, told people to eat rocks and to put glue on their pizza. These answers were mostly in response to what the company calls adversarial queries—those designed to trip it up. But still. It didn’t look good. The company quickly went to work fixing the problems—for example, by deprecating so-called user-generated content from sites like Reddit, where some of the weirder answers had come from. Yet while its errors telling people to eat rocks got all the attention, the more pernicious danger might arise when it gets something less obviously wrong. For example, in doing research for this article, I asked Google when MIT Technology Review went online. It helpfully responded that “MIT Technology Review launched its online presence in late 2022.” This was clearly wrong to me, but for someone completely unfamiliar with the publication, would the error leap out?  I came across several examples like this, both in Google and in OpenAI’s ChatGPT search. Stuff that’s just far enough off the mark not to be immediately seen as wrong. Google is banking that it can continue to improve these results over time by relying on what it knows about quality sources. “When we produce AI Overviews,” says Nayak, “we look for corroborating information from the search results, and the search results themselves are designed to be from these reliable sources whenever possible. These are some of the mechanisms we have in place that assure that if you just consume the AI Overview, and you don’t want to look further … we hope that you will still get a reliable, trustworthy answer.” In the case above, the 2022 answer seemingly came from a reliable source—a story about MIT Technology Review’s email newsletters, which launched in 2022. But the machine fundamentally misunderstood. This is one of the reasons Google uses human beings—raters—to evaluate the results it delivers for accuracy. Ratings don’t correct or control individual AI Overviews; rather, they help train the model to build better answers. But human raters can be fallible. Google is working on that too.  “Raters who look at your experiments may not notice the hallucination because it feels sort of natural,” says Nayak. “And so you have to really work at the evaluation setup to make sure that when there is a hallucination, someone’s able to point out and say, That’s a problem.” The new search Google has rolled out its AI Overviews to upwards of a billion people in more than 100 countries, but it is facing upstarts with new ideas about how search should work. Search Engine GoogleThe search giant has added AI Overviews to search results. These overviews take information from around the web and Google’s Knowledge Graph and use the company’s Gemini language model to create answers to search queries. What it’s good at Google’s AI Overviews are great at giving an easily digestible summary in response to even the most complex queries, with sourcing boxes adjacent to the answers. Among the major options, its deep web index feels the most “internety.” But web publishers fear its summaries will give people little reason to click through to the source material. PerplexityPerplexity is a conversational search engine that uses third-party largelanguage models from OpenAI and Anthropic to answer queries. Perplexity is fantastic at putting together deeper dives in response to user queries, producing answers that are like mini white papers on complex topics. It’s also excellent at summing up current events. But it has gotten a bad rep with publishers, who say it plays fast and loose with their content. ChatGPTWhile Google brought AI to search, OpenAI brought search to ChatGPT. Queries that the model determines will benefit from a web search automatically trigger one, or users can manually select the option to add a web search. Thanks to its ability to preserve context across a conversation, ChatGPT works well for performing searches that benefit from follow-up questions—like planning a vacation through multiple search sessions. OpenAI says users sometimes go “20 turns deep” in researching queries. Of these three, it makes links out to publishers least prominent. When I talked to Pichai about this, he expressed optimism about the company’s ability to maintain accuracy even with the LLM generating responses. That’s because AI Overviews is based on Google’s flagship large language model, Gemini, but also draws from Knowledge Graph and what it considers reputable sources around the web.  “You’re always dealing in percentages. What we have done is deliver it at, like, what I would call a few nines of trust and factuality and quality. I’d say 99-point-few-nines. I think that’s the bar we operate at, and it is true with AI Overviews too,” he says. “And so the question is, are we able to do this again at scale? And I think we are.” There’s another hazard as well, though, which is that people ask Google all sorts of weird things. If you want to know someone’s darkest secrets, look at their search history. Sometimes the things people ask Google about are extremely dark. Sometimes they are illegal. Google doesn’t just have to be able to deploy its AI Overviews when an answer can be helpful; it has to be extremely careful not to deploy them when an answer may be harmful.  “If you go and say ‘How do I build a bomb?’ it’s fine that there are web results. It’s the open web. You can access anything,” Reid says. “But we do not need to have an AI Overview that tells you how to build a bomb, right? We just don’t think that’s worth it.”  But perhaps the greatest hazard—or biggest unknown—is for anyone downstream of a Google search. Take publishers, who for decades now have relied on search queries to send people their way. What reason will people have to click through to the original source, if all the information they seek is right there in the search result?   Rand Fishkin, cofounder of the market research firm SparkToro, publishes research on so-called zero-click searches. As Google has moved increasingly into the answer business, the proportion of searches that end without a click has gone up and up. His sense is that AI Overviews are going to explode this trend.   “If you are reliant on Google for traffic, and that traffic is what drove your business forward, you are in long- and short-term trouble,” he says.  Don’t panic, is Pichai’s message. He argues that even in the age of AI Overviews, people will still want to click through and go deeper for many types of searches. “The underlying principle is people are coming looking for information. They’re not looking for Google always to just answer,” he says. “Sometimes yes, but the vast majority of the times, you’re looking at it as a jumping-off point.”  Reid, meanwhile, argues that because AI Overviews allow people to ask more complicated questions and drill down further into what they want, they could even be helpful to some types of publishers and small businesses, especially those operating in the niches: “You essentially reach new audiences, because people can now express what they want more specifically, and so somebody who specializes doesn’t have to rank for the generic query.”  “I’m going to start with something risky,” Nick Turley tells me from the confines of a Zoom window. Turley is the head of product for ChatGPT, and he’s showing off OpenAI’s new web search tool a few weeks before it launches. “I should normally try this beforehand, but I’m just gonna search for you,” he says. “This is always a high-risk demo to do, because people tend to be particular about what is said about them on the internet.”  He types my name into a search field, and the prototype search engine spits back a few sentences, almost like a speaker bio. It correctly identifies me and my current role. It even highlights a particular story I wrote years ago that was probably my best known. In short, it’s the right answer. Phew?  A few weeks after our call, OpenAI incorporated search into ChatGPT, supplementing answers from its language model with information from across the web. If the model thinks a response would benefit from up-to-date information, it will automatically run a web search (OpenAI won’t say who its search partners are) and incorporate those responses into its answer, with links out if you want to learn more. You can also opt to manually force it to search the web if it does not do so on its own. OpenAI won’t reveal how many people are using its web search, but it says some 250 million people use ChatGPT weekly, all of whom are potentially exposed to it.   “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be a better super-assistant for you.” Kevin Weil, chief product officer, OpenAI According to Fishkin, these newer forms of AI-assisted search aren’t yet challenging Google’s search dominance. “It does not appear to be cannibalizing classic forms of web search,” he says.  OpenAI insists it’s not really trying to compete on search—although frankly this seems to me like a bit of expectation setting. Rather, it says, web search is mostly a means to get more current information than the data in its training models, which tend to have specific cutoff dates that are often months, or even a year or more, in the past. As a result, while ChatGPT may be great at explaining how a West Coast offense works, it has long been useless at telling you what the latest 49ers score is. No more.  “I come at it from the perspective of ‘How can we make ChatGPT able to answer every question that you have? How can we make it more useful to you on a daily basis?’ And that’s where search comes in for us,” Kevin Weil, the chief product officer with OpenAI, tells me. “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be able to be a better super-assistant for you.” Today ChatGPT is able to generate responses for very current news events, as well as near-real-time information on things like stock prices. And while ChatGPT’s interface has long been, well, boring, search results bring in all sorts of multimedia—images, graphs, even video. It’s a very different experience.  Weil also argues that ChatGPT has more freedom to innovate and go its own way than competitors like Google—even more than its partner Microsoft does with Bing. Both of those are ad-dependent businesses. OpenAI is not. (At least not yet.) It earns revenue from the developers, businesses, and individuals who use it directly. It’s mostly setting large amounts of money on fire right now—it’s projected to lose $14 billion in 2026, by some reports. But one thing it doesn’t have to worry about is putting ads in its search results as Google does.  “For a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you,” says Google head of search, Liz Reid.WINNI WINTERMEYER/REDUX Like Google, ChatGPT is pulling in information from web publishers, summarizing it, and including it in its answers. But it has also struck financial deals with publishers, a payment for providing the information that gets rolled into its results. (MIT Technology Review has been in discussions with OpenAI, Google, Perplexity, and others about publisher deals but has not entered into any agreements. Editorial was neither party to nor informed about the content of those discussions.) But the thing is, for web search to accomplish what OpenAI wants—to be more current than the language model—it also has to bring in information from all sorts of publishers and sources that it doesn’t have deals with. OpenAI’s head of media partnerships, Varun Shetty, told MIT Technology Review that it won’t give preferential treatment to its publishing partners. Instead, OpenAI told me, the model itself finds the most trustworthy and useful source for any given question. And that can get weird too. In that very first example it showed me—when Turley ran that name search—it described a story I wrote years ago for Wired about being hacked. That story remains one of the most widely read I’ve ever written. But ChatGPT didn’t link to it. It linked to a short rewrite from The Verge. Admittedly, this was on a prototype version of search, which was, as Turley said, “risky.”  When I asked him about it, he couldn’t really explain why the model chose the sources that it did, because the model itself makes that evaluation. The company helps steer it by identifying—sometimes with the help of users—what it considers better answers, but the model actually selects them.  “And in many cases, it gets it wrong, which is why we have work to do,” said Turley. “Having a model in the loop is a very, very different mechanism than how a search engine worked in the past.” Indeed!  The model, whether it’s OpenAI’s GPT-4o or Google’s Gemini or Anthropic’s Claude, can be very, very good at explaining things. But the rationale behind its explanations, its reasons for selecting a particular source, and even the language it may use in an answer are all pretty mysterious. Sure, a model can explain very many things, but not when that comes to its own answers.  It was almost a decade ago, in 2016, when Pichai wrote that Google was moving from “mobile first” to “AI first”: “But in the next 10 years, we will shift to a world that is AI-first, a world where computing becomes universally available—be it at home, at work, in the car, or on the go—and interacting with all of these surfaces becomes much more natural and intuitive, and above all, more intelligent.”  We’re there now—sort of. And it’s a weird place to be. It’s going to get weirder. That’s especially true as these things we now think of as distinct—querying a search engine, prompting a model, looking for a photo we’ve taken, deciding what we want to read or watch or hear, asking for a photo we wish we’d taken, and didn’t, but would still like to see—begin to merge.  The search results we see from generative AI are best understood as a waypoint rather than a destination. What’s most important may not be search in itself; rather, it’s that search has given AI model developers a path to incorporating real-time information into their inputs and outputs. And that opens up all sorts of possibilities. “A ChatGPT that can understand and access the web won’t just be about summarizing results. It might be about doing things for you. And I think there’s a fairly exciting future there,” says OpenAI’s Weil. “You can imagine having the model book you a flight, or order DoorDash, or just accomplish general tasks for you in the future. It’s just once the model understands how to use the internet, the sky’s the limit.” This is the agentic future we’ve been hearing about for some time now, and the more AI models make use of real-time data from the internet, the closer it gets.  Let’s say you have a trip coming up in a few weeks. An agent that can get data from the internet in real time can book your flights and hotel rooms, make dinner reservations, and more, based on what it knows about you and your upcoming travel—all without your having to guide it. Another agent could, say, monitor the sewage output of your home for certain diseases, and order tests and treatments in response. You won’t have to search for that weird noise your car is making, because the agent in your vehicle will already have done it and made an appointment to get the issue fixed.  “It’s not always going to be just doing search and giving answers,” says Pichai. “Sometimes it’s going to be actions. Sometimes you’ll be interacting within the real world. So there is a notion of universal assistance through it all.” And the ways these things will be able to deliver answers is evolving rapidly now too. For example, today Google can not only search text, images, and even video; it can create them. Imagine overlaying that ability with search across an array of formats and devices. “Show me what a Townsend’s warbler looks like in the tree in front of me.” Or “Use my existing family photos and videos to create a movie trailer of our upcoming vacation to Puerto Rico next year, making sure we visit all the best restaurants and top landmarks.” “We have primarily done it on the input side,” he says, referring to the ways Google can now search for an image or within a video. “But you can imagine it on the output side too.” This is the kind of future Pichai says he is excited to bring online. Google has already showed off a bit of what that might look like with NotebookLM, a tool that lets you upload large amounts of text and have it converted into a chatty podcast. He imagines this type of functionality—the ability to take one type of input and convert it into a variety of outputs—transforming the way we interact with information.  In a demonstration of a tool called Project Astra this summer at its developer conference, Google showed one version of this outcome, where cameras and microphones in phones and smart glasses understand the context all around you—online and off, audible and visual—and have the ability to recall and respond in a variety of ways. Astra can, for example, look at a crude drawing of a Formula One race car and not only identify it, but also explain its various parts and their uses.  But you can imagine things going a bit further (and they will). Let’s say I want to see a video of how to fix something on my bike. The video doesn’t exist, but the information does. AI-assisted generative search could theoretically find that information somewhere online—in a user manual buried in a company’s website, for example—and create a video to show me exactly how to do what I want, just as it could explain that to me with words today. These are the kinds of things that start to happen when you put the entire compendium of human knowledge—knowledge that’s previously been captured in silos of language and format; maps and business registrations and product SKUs; audio and video and databases of numbers and old books and images and, really, anything ever published, ever tracked, ever recorded; things happening right now, everywhere—and introduce a model into all that. A model that maybe can’t understand, precisely, but has the ability to put that information together, rearrange it, and spit it back in a variety of different hopefully helpful ways. Ways that a mere index could not. That’s what we’re on the cusp of, and what we’re starting to see. And as Google rolls this out to a billion people, many of whom will be interacting with a conversational AI for the first time, what will that mean? What will we do differently? It’s all changing so quickly. Hang on, just hang on. 
Read More »

Subsea7 Scores Various Contracts Globally

Subsea 7 S.A. has secured what it calls a “sizeable” contract from Turkish Petroleum Offshore Technology Center AS (TP-OTC) to provide inspection, repair and maintenance (IRM) services for the Sakarya gas field development in the Black Sea. The contract scope includes project management and engineering executed and managed from Subsea7 offices in Istanbul, Türkiye, and Aberdeen, Scotland. The scope also includes the provision of equipment, including two work class remotely operated vehicles, and construction personnel onboard TP-OTC’s light construction vessel Mukavemet, Subsea7 said in a news release. The company defines a sizeable contract as having a value between $50 million and $150 million. Offshore operations will be executed in 2025 and 2026, Subsea7 said. Hani El Kurd, Senior Vice President of UK and Global Inspection, Repair, and Maintenance at Subsea7, said: “We are pleased to have been selected to deliver IRM services for TP-OTC in the Black Sea. This contract demonstrates our strategy to deliver engineering solutions across the full asset lifecycle in close collaboration with our clients. We look forward to continuing to work alongside TP-OTC to optimize gas production from the Sakarya field and strengthen our long-term presence in Türkiye”. North Sea Project Subsea7 also announced the award of a “substantial” contract by Inch Cape Offshore Limited to Seaway7, which is part of the Subsea7 Group. The contract is for the transport and installation of pin-pile jacket foundations and transition pieces for the Inch Cape Offshore Wind Farm. The 1.1-gigawatt Inch Cape project offshore site is located in the Scottish North Sea, 9.3 miles (15 kilometers) off the Angus coast, and will comprise 72 wind turbine generators. Seaway7’s scope of work includes the transport and installation of 18 pin-pile jacket foundations and 54 transition pieces with offshore works expected to begin in 2026, according to a separate news

Read More »

Driving into the future

Welcome to our annual breakthroughs issue. If you’re an MIT Technology Review superfan, you may already know that putting together our 10 Breakthrough Technologies (TR10) list is one of my favorite things we do as a publication. We spend months researching and discussing which technologies will make the list. We try to highlight a mix of items that reflect innovations happening in various fields. We look at consumer technologies, large industrial­-scale projects, biomedical advances, changes in computing, climate solutions, the latest in AI, and more.  We’ve been publishing this list every year since 2001 and, frankly, have a great track record of flagging things that are poised to hit a tipping point. When you look back over the years, you’ll find items like natural-language processing (2001), wireless power (2008), and reusable rockets (2016)—spot-on in terms of horizon scanning. You’ll also see the occasional miss, or moments when maybe we were a little bit too far ahead of ourselves. (See our Magic Leap entry from 2015.) But the real secret of the TR10 is what we leave off the list. It is hard to think of another industry, aside from maybe entertainment, that has as much of a hype machine behind it as tech does. Which means that being too conservative is rarely the wrong call. But it does happen.  Last year, for example, we were going to include robotaxis on the TR10. Autonomous vehicles have been around for years, but 2023 seemed like a real breakthrough moment; both Cruise and Waymo were ferrying paying customers around various cities, with big expansion plans on the horizon. And then, last fall, after a series of mishaps (including an incident when a pedestrian was caught under a vehicle and dragged), Cruise pulled its entire fleet of robotaxis from service. Yikes. 
The timing was pretty miserable, as we were in the process of putting some of the finishing touches on the issue. I made the decision to pull it. That was a mistake.  What followed turned out to be a banner year for the robotaxi. Waymo, which had previously been available only to a select group of beta testers, opened its service to the general public in San Francisco and Los Angeles in 2024. Its cars are now ubiquitous in the City by the Bay, where they have not only become a real competitor to the likes of Uber and Lyft but even created something of a tourist attraction. Which is no wonder, because riding in one is delightful. They are still novel enough to make it feel like a kind of magic. And as you can read, Waymo is just a part of this amazing story. 
The item we swapped into the robotaxi’s place was the Apple Vision Pro, an example of both a hit and a miss. We’d included it because it is truly a revolutionary piece of hardware, and we zeroed in on its micro-OLED display. Yet a year later, it has seemingly failed to find a market fit, and its sales are reported to be far below what Apple predicted. I’ve been covering this field for well over a decade, and I would still argue that the Vision Pro (unlike the Magic Leap vaporware of 2015) is a breakthrough device. But it clearly did not have a breakthrough year. Mea culpa.  Having said all that, I think we have an incredible and thought-provoking list for you this year—from a new astronomical observatory that will allow us to peer into the fourth dimension to new ways of searching the internet to, well, robotaxis. I hope there’s something here for everyone.

Read More »

Oil Holds at Highest Levels Since October

Crude oil futures slightly retreated but continue to hold at their highest levels since October, supported by colder weather in the Northern Hemisphere and China’s economic stimulus measures. That’s what George Pavel, General Manager at Naga.com Middle East, said in a market analysis sent to Rigzone this morning, adding that Brent and WTI crude “both saw modest declines, yet the outlook remains bullish as colder temperatures are expected to increase demand for heating oil”. “Beijing’s fiscal stimulus aims to rejuvenate economic activity and consumer demand, further contributing to fuel consumption expectations,” Pavel said in the analysis. “This economic support from China could help sustain global demand for crude, providing upward pressure on prices,” he added. Looking at supply, Pavel noted in the analysis that “concerns are mounting over potential declines in Iranian oil production due to anticipated sanctions and policy changes under the incoming U.S. administration”. “Forecasts point to a reduction of 300,000 barrels per day in Iranian output by the second quarter of 2025, which would weigh on global supply and further support prices,” he said. “Moreover, the U.S. oil rig count has decreased, indicating a potential slowdown in future output,” he added. “With supply-side constraints contributing to tightening global inventories, this situation is likely to reinforce the current market optimism, supporting crude prices at elevated levels,” Pavel continued. “Combined with the growing demand driven by weather and economic factors, these supply dynamics point to a favorable environment for oil prices in the near term,” Pavel went on to state. Rigzone has contacted the Trump transition team and the Iranian ministry of foreign affairs for comment on Pavel’s analysis. At the time of writing, neither have responded to Rigzone’s request yet. In a separate market analysis sent to Rigzone earlier this morning, Antonio Di Giacomo, Senior Market Analyst at

Read More »

What to expect from NaaS in 2025

Shamus McGillicuddy, vice president of research at EMA, says that network execs today have a fuller understanding of the potential benefits of NaaS, beyond simply a different payment model. NaaS can deliver access to new technologies faster and keep enterprises up-to-date as technologies evolve over time; it can help mitigate skills gaps for organizations facing a shortage of networking talent. For example, in a retail scenario, an organization can offload deployment and management of its Wi-Fi networks at all of its stores to a NaaS vendor, freeing up IT staffers for higher-level activities. Also, it can help organizations manage rapidly fluctuating demands on the network, he says. 2. Frameworks help drive adoption Industry standards can help accelerate the adoption of new technologies. MEF, a nonprofit industry forum, has developed a framework that combines standardized service definitions, extensive automation frameworks, security certifications, and multi-cloud integration capabilities—all aimed at enabling service providers to deliver what MEF calls a true cloud experience for network services. The blueprint serves as a guide for building an automated, federated ecosystem where enterprises can easily consume NaaS services from providers. It details the APIs, service definitions, and certification programs that MEF has developed to enable this vision. The four components of NaaS, according to the blueprint, are on-demand automated transport services, SD-WAN overlays and network slicing for application assurance, SASE-based security, and multi-cloud on-ramps. 3. The rise of campus/LAN NaaS Until very recently, the most popular use cases for NaaS were on-demand WAN connectivity, multi-cloud connectivity, SD-WAN, and SASE. However, campus/LAN NaaS, which includes both wired and wireless networks, has emerged as the breakout star in the overall NaaS market. Dell’Oro Group analyst Sian Morgan predicts: “In 2025, Campus NaaS revenues will grow over eight times faster than the overall LAN market. Startups offering purpose-built CNaaS technology will

Read More »

UK battery storage industry ‘back on track’

UK battery storage investor Gresham House Energy Storage Fund (LON:GRID) has said the industry is “back on track” as trading conditions improved, particularly in December. The UK’s largest fund specialising in battery energy storage systems (BESS) highlighted improvements in service by the UK government’s National Energy System Operator (NESO) as well as its renewed commitment to to the sector as part of clean power aims by 2030. It also revealed that revenues exceeding £60,000 per MW of electricity its facilities provided in the second half of 2024 meant it would meet or even exceed revenue targets. This comes after the fund said it had faced a “weak revenue environment” in the first part of the year. In April it reported a £110 million loss compared to a £217m profit the previous year and paused dividends. Fund manager Ben Guest said the organisation was “working hard” on refinancing  and a plan to “re-instate dividend payments”. In a further update, the fund said its 40MW BESS project at Shilton Lane, 11 miles from Glasgow, was  fully built and in the final stages of the NESO compliance process which expected to complete in February 2025. Fund chair John Leggate welcomed “solid progress” in company’s performance, “as well as improvements in NESO’s control room, and commitment to further change, that should see BESS increasingly well utilised”. He added: “We thank our shareholders for their patience as the battery storage industry gets back on track with the most environmentally appropriate and economically competitive energy storage technology (Li-ion) being properly prioritised. “Alongside NESO’s backing of BESS, it is encouraging to see the government’s endorsement of a level playing field for battery storage – the only proven, commercially viable technology that can dynamically manage renewable intermittency at national scale.” Guest, who in addition to managing the fund is also

Read More »

More autonomy, fewer NDAs: Volunteers have new requests for brain implant trials

EXECUTIVE SUMMARY Scientists have been working on ways to decode brain activity for decades. Teams have developed brain implants that can be used to control robotic limbs and computers, and even to “speak.” The people who volunteer for trials of those devices play a vital role in that research, and they ought to be recognized for their contributions, says Ian Burkhart, who had one implanted in his own brain back in 2014. He’s been working on a set of guidelines for researchers developing brain-computer interfaces (BCIs). Ethics guidelines for clinical trials already exist. But BCI trials are different, says Jennifer Chandler, a professor of law and neuroethics at the University of Ottawa who also worked on the guidelines. “These are people who have a device embedded in their brain, are in trials sometimes for years and years … [and contribute] a significant investment of time, of the body, and of intellectual effort.” Burkhart was left paralyzed from the chest down following a diving accident in 2010, when he was 19 years old. Around four years later, he volunteered to become the first person to trial a brain implant designed for hand control.
He had an array of 96 electrodes inserted into the part of his brain that controls movement. The electrodes were connected to a computer via a cable that essentially plugged into his head. Algorithms on the computer were designed to interpret those signals and deliver them to another sleeve of electrodes worn on Burkhart’s arm, allowing him to control it. The first movements were small, but Burkhart was ultimately able to use the system to pour beads from bottles, move small and delicate objects, and even play Guitar Hero, if only during lab visits. It was a scientific breakthrough.
Burkhart took part in two years-long clinical trials over the seven-and-a-half-year period he had the electrode array implanted in his brain. “It was a fantastic experience,” he says. “But there’s certainly some things that, knowing what I know now, I would want to do a little differently.” In 2022, Burkhart cofounded BCI Pioneers Coalition—an organization through which people who have taken part in BCI trials can share their experiences, both with each other and with researchers. Over the last year, members of the group have been developing a set of guidelines based on those experiences. The idea is to help academics, clinicians, and companies run ethical trials that respect participants’ autonomy. The guidelines, published on Tuesday, lay out a list of recommendations that fall within 13 categories. One, for example, focuses on recognizing and compensating trial participants. During the trials that Burkhart participated in, “I was going into the lab two or three days a week, for four hours at a time,” he recalls. “That’s [easily] a part-time job if you just count the hours you’re putting in.” As the trial progressed, Burkhart says, he learned more and was able to give more constructive feedback on what was working and what wasn’t. He says he was a key member of the research team. Others who find themselves in a similar position might appreciate being listed as a coauthor on scientific publications or publicly named as a research collaborator, he says. Burkhart and his colleagues acknowledge that not everyone will want this, however.   The guidelines also address the thorny question of privacy. That’s important: The public will always be interested in cutting-edge biotechnologies like these—and the guidelines say researchers also have a duty to prepare participants for the possibility of media attention. In some cases, it might be difficult to completely conceal the identity of trial participants. Things get even more complicated when it comes to the privacy of participants’ brain data. Research teams will need to access, analyze, and—at least temporarily—store this data. Burkhart wasn’t too bothered about that in his case, where scientists were collecting neural activity related to movement. But people who have brain implants designed for turning thoughts into words might feel differently.  The guidelines state that brain data “should be understood as the participant’s personal information.” They are pushing for participants to be able to access their own brain data whenever they want—something that has not always been possible—and want to make sure people aren’t prevented from sharing it with their own doctors because of embargoes or nondisclosure agreements (NDAs) designed to keep findings under wraps from competitors. “It’s not super common for there to be firm NDAs within a lot of the trials,” says Burkhart. “But it’s something where we want to make sure that that does not happen.”

The guidelines also address what comes after a trial. Around five years after Burkhart had his device implanted, the research team ran into some issues with funding. When we last spoke a few years ago, he recalled how he was told he would have to have the implant removed and could have it put back in once the team had secured funding. (And we’re talking about brain surgery here.) Ultimately, he kept the implant until 2021, when it was removed after an infection started to develop at the point where the cable led into his scalp. But losing the device after all those years was difficult; he’d regained the ability to move his arm—and then lost it again. Rita Leggett, an Australian woman who had a device implanted in her brain to treat her epilepsy, has said she felt she “became one” with her implant. When the company that made it went bust two years later, the device was removed against her will—an act ethicists have described as a potential breach of human rights. Researchers should instead commit to maintaining brain devices for a “reasonable period” after a trial ends, according to the guidelines. Participants should be given plenty of time to prepare for the surgery to remove it. And researchers should set aside extra funds to support trial participants who have to do that. Some of the guidelines are vague and may overlap with existing ethics standards. They don’t all spell out explicit solutions. They were also developed with feedback from a small group of individuals—the number of people living with BCIs is still very low. The team hopes to grow and expand on the guidelines over time. Burkhart also plans to discuss them with researchers at an upcoming neuroscience conference. “This is a living document, and this is version one,” says Chandler. “It’s just the starting point.”

Read More »

Silicon Valley claims to know the future. So why did it get the midterms so wrong?

The self-styled visionaries of Silicon Valley, leaders like OpenAI chief executive Sam Altman and SpaceX boss Elon Musk, have built careers claiming to see the future. Long-term vision is currency: Meta’s Mark Zuckerberg built a 10-year road map for Facebook in 2016, and Google famously told investors before its public offering that it was unconcerned with short-term results. And yet there they all were, a mere five weeks before the midterm elections, gathered at the White House to smile for photos with President Trump and sign on to his “Super Intelligence” agenda. Even by the diminished standards of today’s corporate governance, this was a shockingly foolish decision. Despite dozens of polls showing a rising tide of anti-Trump sentiment and bipartisan rejection of AI and data centers, the futurists of the tech elite cast aside long-term corporate interests for short-term political favor. And now, their industry is very squarely in the new victors’ crosshairs. For an industry obsessed with pattern recognition, their decision to lash themselves to President Trump has proved to be a catastrophic misreading of the political landscape. Now, not only have they jeopardized their companies’ fates, but they’ve also raised questions about their vision and judgment.  What were they thinking?
The people who work for them are just as confused as the rest of us. Tech workers I’ve spoken to at OpenAI, Meta, and other firms have noted an absence of commentary from their leaders post-election. Zuckerberg has yet to address the results internally, while an employee at another AI firm said that “leadership has been pretty silent on Slack.” Most employees share concern about potential anti-data-center legislation and are curious how leadership will adjust to a Democratic Washington, DC. But more than anything, they don’t understand how their bosses didn’t see what was so blindingly obvious to everyone else. In Silicon Valley, the Gretzkyism “skate to where the puck is going, not where it has been” is a management maxim; it preaches anticipation and foresight over reactiveness to the present moment. Tech entrepreneurs love a good “pivot,” and companies that can’t change with the times get disrupted and die.
Which is why I find it so strange that Zuckerberg, OpenAI cofounder Greg Brockman, and so many of Silicon Valley’s other prominent AI leaders and venture capitalists have put themselves in a potentially inescapable political bind. In going all in on President Trump’s cultural and business agenda instead of playing both sides of the aisle as corporate America usually does, they’ve built identities they may not be able to pivot out of. Will anyone really believe that Palantir CEO Alex Karp is suddenly progressive after a year of promising “violence and death to our enemies” and telling investors that the company is “completely anti-woke”? I believe this is less a surprise than a very public exposure of a fundamental reality: that tech’s most visible leaders are not all-knowing visionary masterminds after all. Insights about social media or artificial intelligence do not make Zuckerberg or Altman experts on politics, the economy, or much else outside of technology. The instant gratification of presidential access, subsidies, and a say in their own regulation blinded them to the basics of political math that they clearly did not understand. There’s a reason the chief executives of Chase, Boeing, and other Fortune 500 staples don’t go on podcasts to talk about “masculine energy,” or call the president from the stage of a MAGA-friendly AI summit to label fears about AI a “hoax” and a “scam.” This is the learned wisdom of decades operating in an environment where the customer changes every four years but contracts run for 10. Most companies play to both sides of the aisle because they know that their business models and multibillion-dollar projects must outlast the current administration. Instead, Big Tech tied itself to Trump and made its most important goals and investments—many related to grid access and data center permits—immediate targets for Democrats. In tech, you can always sunset a feature or update some code. But in politics, there is no undo button for failures that change public perception. The tech elites’ decision to visibly align their businesses with a temporary movement has left them no credible way to pivot now that the climate has changed. As one Meta employee who has worked closely with Zuckerberg put it, “Mark is a long-term thinker, but he never charts a plan of how to get there. It’s spray and pray and see what happens.” As for whether employees expect the company to do a strategic postmortem? “Facebook has never really done that.” “Move fast and break things” might work in a startup, but it’s a terrible strategy for building reputational goodwill. Previous technological leaps, like the rollout of fiber-optic technology and wireless infrastructure, avoided partisan politics. But by kowtowing to the Trump administration, Silicon Valley made artificial intelligence a culture-war issue. Now, when citizens vote on data center proposals from California to Florida, they are no longer considering only technical or economic concerns, but political ones. Tech leaders didn’t see this coming because they were too focused on the urgency of the AI race to understand how reputational damage could undermine the intangible goodwill—and ultimately the very tangible infrastructure—necessary to win it. The industry’s misreading of the moment has already punctured one myth Silicon Valley holds dear: that its leaders can always see what’s next. Aaron Zamost is a tech communications consultant and a former executive at Square.

Read More »

Nvidia privately confirmed it could track chips to fight smuggling, even as industry publicly questioned feasibility

Representatives from Nvidia told Illinois representative Bill Foster that it would be technically possible to implement the anti-smuggling measures called for in the Chip Security Act, Foster told MIT Technology Review in an interview on Thursday, even while an industry group claimed they were “potentially infeasible.”  Foster, a Democrat who serves on the Committee on Science, Space, and Technology, is a cosponsor of the act, which would introduce geotracking requirements to verify the location of advanced AI chips in order to prevent their smuggling to China. It is one of three chip-security bills under consideration for inclusion in the Senate’s National Defense Authorization Act, each of which is drawing renewed attention after Nvidia CEO Jensen Huang’s resignation and reported affair with an alleged Chinese spy. When the Chip Security Act was introduced, in May 2025, lawmakers said the technology to implement it existed, something Nvidia has not publicly confirmed. In March 2026, the Semiconductor Industry Association, of which Nvidia is a member, explicitly opposed the bill and wrote that its mandates for chip tracking were “new, untested, and potentially infeasible.”  But privately, Nvidia representatives working with Foster told the lawmaker that the company could implement them. 
“They never put anything in writing,” Foster says, but during technical discussions on the possibility of such safeguards, their reaction was “yeah, of course we can do this.” This private acknowledgment to Foster goes further than anything Nvidia has previously made public.  Other technology Nvidia has built for its customers suggests that the company can indeed offer accurate tracking of its chips’ locations. In December 2025, for example, it announced a new tool called Fleet Intelligence that would allow customers to monitor how its advanced chips were performing across different data center locations. In doing so, the tool could indicate which country chips were in, Nvidia confirmed to Reuters, but the company would not elaborate on whether this technology could be used to prevent smuggling. 
Nvidia did not respond to requests for comment or confirmation of Foster’s characterization. In early October, when lawmakers were reportedly increasingly concerned about Nvidia’s role in smuggling, MIT Technology Review asked the company if Fleet Intelligence could be used to prevent the practice. It declined to answer directly, instead sending a statement: “Governments and media have found insignificant diversion of controlled US products—a drop in the bucket compared to the ocean of domestic compute China already has.” The recent fallout at Nvidia involves a number of people and companies alleged to be involved in chip smuggling. Alice Huang, with whom Jensen Huang reportedly had an affair, runs Megaspeed, a Singaporean firm now under investigation for smuggling advanced GPUs to China. A US Commerce Department inquiry into the company was reportedly halted after invention by Nvidia. Megaspeed reportedly bought chips from Supermicro, a company that packages Nvidia’s chips onto servers.  The Chip Security Act as drafted would require a mechanism to track the locations of chips, either by inspections of facilities, attestations by companies, or ping-based location mechanisms. The ping-based technique, the hardest option to circumvent, would require the GPU to send a signal of its location when it comes online. In September, the Center for Security and Emerging Technology found it would be the most cost-effective option. Foster said he did not ask Nvidia’s representatives why they weren’t voluntarily adopting such chip-tracking tools if they could technically do so. But if the requirements of the bill pass as part of the Senate’s National Defense Authorization Act, the new tracking mechanisms would only tell investigators where the chips are, not offer a way to disconnect them if it’s revealed they have been smuggled. Foster told MIT Technology Review he intends to introduce new, stricter legislation in the new year that would offer a workaround. The new rule would require licenses to operate advanced GPUs, and before a GPU could connect, its valid license would need to be verified.   In the meantime, the controversy at Nvidia, Foster says, has fueled support among his colleagues for the rules in the bill: “There will be a lot of political pressure, in the wake of everything that’s happened, on the companies to actually do a very good job of the geographic validation of where the chip actually is.”

Read More »

Introducing Gemini 4 Hydrogen

Unlocking efficiencies in multi-model workloadsIn real-world software development, while teams rely on frontier models like Carbon and Argon for deep architectural judgment when designing systems or untangling subtle bugs, they still need a fast, disciplined execution model for writing code, running tests, and verifying changes. Hydrogen is built to stand on its own as a model for everyday work — or to pair with Carbon and Argon as the high-efficiency execution engine in multi-model workflows.To help make this multi-model collaboration automatic, we’re introducing Orchestrator in Google Antigravity. Rather than using a single model from start to finish, Orchestrator dynamically switches between models like Carbon and Hydrogen within the same session. On Terminal-Bench 4.0, Orchestrator reached near-Carbon task success rates while, on average, consuming 24% less quota and completing 19% faster. For workflows that require parallel agents, Carbon can act as the coordinator while Hydrogen can power worker and verifier agents to build and test changes simultaneously across isolated workspaces — helping teams ship complex projects faster without driving up token costs.

Read More »

The Download: COP31’s climate challenge and the quest for immortality

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. What to know about this year’s UN climate talks Thousands of delegates, lobbyists, and journalists have gathered in Antalya, Turkey, for COP31, the annual UN climate talks. But this year’s negotiations are taking place against a particularly tense geopolitical backdrop, as the world falls further behind the Paris Agreement’s goals. Energy prices are soaring, and there are big questions about how countries will tackle the climate crisis. Expect a lot of back and forth on fossil fuels and climate finance, and whether negotiators can agree on meaningful action. Here’s what you need to know about COP31. 
—Casey Crownhart This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday.
Inside the quest for cognitive immortality Far-thinking technologists are working on ways to keep your brain going beyond death. MIT Technology Review’s latest Roundtables event explores their ideas, from gradual brain replacement to uploading memories to the cloud. Join science editor Mary Beth Griggs and senior editor for biomedicine Antonio Regalado for this subscriber-only discussion. Tune in live on Tuesday, November 17 at 5:00 p.m. GMT / 12:00 p.m. EST / 9:00 a.m. PST. Want to join the conversation? Subscribe to MIT Technology Review for exclusive access to all our Roundtables. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Nvidia is reportedly preparing to oust CEO Jensen HuangThe board will meet as soon as today to determine his future. (WSJ $)+ Nvidia’s stock slid 8% after the report was published. (BI)+ Huang allegedly also had an affair with an Nvidia colleague.(NYT $)+ His exit could send shockwaves across the AI industry. (Axios)+ Stakes are high in AI’s trillion-dollar gamble. (MIT Technology Review) 2 The Nvidia spy scandal is set to tighten chip exportsBut Commerce Secretary Lutnick has stalled the curbs. (CNBC)+ China has signaled it will retaliate if they pass. (FT $)+ Chinese firms have started stockpiling Nvidia chips. (Reuters $)+ Democrats appear to be preparing an investigation. (Politico)

3 A startup has built an AI to detect AI-made bioweaponsIt runs offline on a laptop with a USB gene sequencer. (Wired $)+ Ukraine is opening up its battlefield data to train AI weapons. (NYT $)+ AI is making bioweapons easier to create. (MIT Technology Review) 4 Anduril says its satellite can track spacecraft in orbital nightIt uses an infrared sensor to detect hidden satellites. (Ars Technica)+ Anduril is also making smart glasses for warfare. (MIT Technology Review) 5 Ukraine has reported new restrictions on SpaceX’s StarshieldZelenskyy says they’re hampering drone defenses. (NBC News 6 Even remote Brazilian wildlife has microplastics in its bloodAnimals 100 km from waste sites carried them. (Nature)+ AstroTurf is increasing microplastic levels. (MIT Technology Review)7 A NASA space camera can spot invasive plants from orbitIt detects how different species’ leaves reflect light. (Economist $) 8 Astronomers have found an “invisible” object that defies stellar theoryIt’s likely an ultra-rare supermassive neutron star. (404 Media)+ New research has corroborated the first black hole image. (New Scientist $)+ The search for dark matter has been blown open. (MIT Technology Review) 9 Life may have started with metabolism, not genesSelf-sustaining chemical cycles could have come first. (Quanta) 10 Brain surgery has left a man seeing cat eyes on peopleResearchers used AI to render what he sees. (Gizmodo) Quote of the day
“I know more about being a progressive than almost anybody on the planet, and I absolutely believe Palantir—all of our products—are essentially progressive.” —Alex Karp, Palantir’s CEO, tells Politico that he’s a devoted Democrat despite recently backing Trump. One more thing
How Chinese short dramas became AI content machines China’s short drama industry is fueled by bite-sized, melodramatic, and smutty shows built for smartphone scrolling. Now, many are being made entirely with AI: no actors, camera operators, cinematographers, or CGI specialists required. An average of 470 AI-generated short dramas were released every day in January. Production timelines have shrunk from months to weeks, while costs have dropped by up to 90%. Storytelling is also increasingly driven by performance data.

Read More »

What to know about this year’s UN climate talks

EXECUTIVE SUMMARY It’s that time of year again: Thousands of delegates, lobbyists, and journalists are gathered for the annual UN climate talks, taking place this time in Antalya, Turkey. COP31 officially kicked off on November 8, marking the beginning of negotiations on one of the biggest stages of the climate world. Turkey and Australia are cohosting this year’s talks, which are scheduled to wrap up on November 20. This annual gathering can often serve as an indicator of where the world stands on addressing and adapting to the climate crisis. And this year’s talks are sure to be a doozy—expect a lot of back and forth on fossil fuels and climate finance in particular. Here’s what you should know about COP31.   In recent years, the tension always feels high when COP rolls around. (COP stands for “Conference of the Parties.”) But this year feels especially charged: The world is still grappling with the ongoing war in Iran, which has disrupted the Middle East and sent economic shock waves around the world as energy prices have spiked.
This year’s COP will be the second without a formal delegation from the US. President Trump formally withdrew the country from the Paris Agreement earlier this year and is in the process of withdrawing from the UN Framework Committee on Climate Change. That’s the treaty that allows formal participation in negotiations.  Meanwhile, things aren’t looking good for the Paris Agreement, which was established at UN climate talks 11 years ago, setting a goal of limiting warming to 1.5 °C over preindustrial levels. In a report published in September, the UN Environment Program acknowledged that global warming is set to exceed that 1.5 °C goal, “likely within the next few years.”
So as climate talks kick off, there’s an obvious, urgent question looming about how to quickly cut emissions to limit warming. There’s also the major issue of how to pay for efforts to address emissions and to help a warming world endure the inevitable damage.  Two years ago, talks ended in a goal of mobilizing $300 billion per year by 2035 to help pay to reduce emissions and adapt to climate change. (Rich nations provided $136.7 billion in 2024, according to the Organization for Economic Cooperation and Development.) And last year, the COP30 agreement included a goal of tripling the money for adaptation over that period. (Such funding has been quite flat over the past few years.) The world got a tragic reminder of just how high the stakes are earlier this year, when a glacier collapse caused devastating flooding in the Himalayas. The flood killed approximately 1,500 people, left over 5,000 missing, and caused nearly $5 billion in damage. The UN loss and damages fund committed $20 million to helping Nepal recover (less than 1% of the total estimated cost to the country). Another key trend to watch is how the formal negotiations engage with the topic of fossil fuels. Three years ago, the final agreement text explicitly called for a transition away from them. But it felt as if things took a step back last year, when the final agreement didn’t even mention the phrase “fossil fuels” once. This will be an interesting conversation, especially because cohosts Turkey and Australia have both faced criticism over their relationships with these fuels—Australia is a major exporter of coal and natural gas, and Turkey’s grid relies heavily on fossil fuels, including coal. Outside the formal negotiations, COP31 president Murat Kurum, Turkey’s environment minister, is spearheading a side agenda, including two informal initiatives that will be worth watching. These wouldn’t be part of the official agreement text, but countries could sign on to signal support.   One is a pledge to make AI more sustainable; this is almost comically squishy, even as voluntary COP pledges go. The text includes explicit wording that it creates no new obligations for countries, so don’t expect anything resembling enforcement there. The COP leadership is also pushing to make electricity a larger part of member countries’ energy use. Today, only about 23% of global energy is used in the form of electricity. Fossil fuels, like gasoline in vehicles or natural gas for heating, make up the bulk of the rest. Shifting to more electricity use, and relying on cleaner sources for that electricity, could help drive down emissions. The new pledge’s target is for electricity to make up 35% of total energy consumption by 2035.  With leadership billing this as an “implementation COP,” it would be great to see some real, tangible progress on the global challenge of addressing climate change. I’m not expecting anything groundbreaking, but we’ll be tuned in to see what the final agreement shapes up to be.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Read More »

Grid operators need data center ride-through rules that protect reliability

Listen to the article 7 min This audio is auto-generated. Please let us know if you have feedback. Alan Cooper is CEO of ON.energy, a developer of power infrastructure.  On July 22, a mechanical failure forced a 230-kV transmission line in Northern Virginia offline. Within milliseconds, grid protection systems cleared the fault, as they are designed to do. The event would not have been a particularly noteworthy story, had it stopped there. It’s what happened next, though, that pointed to a growing challenge for grid reliability. Optional Caption Permission granted by Alan Cooper In response to the fault, data centers that had been drawing nearly 4 GW of energy, close to 4% of PJM’s load, collectively disconnected and switched to their on-site backup generation. The move sent voltage and frequency spiking across the system, a technically wonky but threatening result that caused power flickers as far away as Chicago. Thankfully, the prevailing grid conditions were strong enough to absorb the shock of the fault, so the grid held. But if the same event had hit Texas or even Northern Virginia at a time of higher demand, it could have caused a widespread outage. In West Texas, the Electric Reliability Counil of Texas estimates that a loss of as little as 3.2 GW could threaten grid reliability. The power sector is not unfamiliar with the need for things hooked up to the electricity grid to “ride through” disturbance events. In 2023, the Federal Energy Regulatory Commission told the North American Electricity Reliability Corp. to develop requirements that inverter-based supply resources like wind and solar facilities must follow to ensure they “ride through,” i.e., stay online, during certain disturbances. And this time around, NERC, FERC and several grid regions have been quick to identify a similar need for large loads to adhere

Read More »

How OpenAI’s Performance Factory keeps ChatGPT fast

The staggering pace of agentic development has made traditional approaches to performance engineering unsustainable. To keep up, we built the Performance Factory, an autonomous system that uses the full capabilities of Codex and our models to find and fix regressions at an unprecedented speed. The Performance Factory, which runs in the cloud and automates investigating and resolving performance problems, enables us to keep pace with the ambition of our roadmap.In the Performance Factory, our engineers define workflows for recurring jobs and write instructions for the Codex agents that carry them out. In particular, the Regression Workflow opens a task when a performance alert fires. An agent investigates the slowdown, records its findings in the task, and proposes a fix for an engineer to review. After deployment, another agent picks up the same task to check whether performance has returned to baseline. From investigating to authoring the fix to verifying mitigation, this first workflow in the Performance Factory has automated the entire process of fixing regressions. In just over three months, the Regression Workflow tracked more than 1,700 investigations and root caused over 600 cases. That’s 17 automated investigations every day.Here, we’ll share how our use of Codex evolved into what’s now the Performance Factory, walk through our first running workflow, and share early lessons from building and running agent workflows in production.The path from manual investigations to automated workflowsAs we used Codex for more of our performance work, we noticed a progression in how our team worked. We hope other service teams can learn from our process as they adopt agentic workflows in other domains.Software work evolves from manual labor to partnering with machines to agent factories.1. Pre-Codex. Before Codex, engineers manually examined metrics and logs, compared traces, debugged live machines, and read code to investigate a slowdown. This work was time consuming, and knowing where to look often required deep knowledge of the service. Relevant signals were easy to miss. When we encountered the same kinds of problems repeatedly—like regressions in ChatGPT’s first token latency—we built advanced tools, like CPU and allocation profilers, to make those investigations easier. Over time, we accumulated more than 30 performance tools.2. Codex as a partner. Once we had Codex as a partner, engineers could ask, “Why did this get slower?” and work with Codex to investigate, even in an unfamiliar system. Codex could search large codebases, find relevant metrics and traces, follow interactions across services, and do appropriate profiling to piece together what had happened. But engineers still had to steer the process, knowing which performance tools to use and how to guide the investigation. Difficult investigations were more debuggable for more people, with less expertise and time required.3. Reusable skills. To automate further, we captured our performance team’s investigation process in a shared skill called perf-forensics. It tells Codex which tools are available, when to use them, and how to work through a slowdown so Codex can try to resolve the problem from a few angles:Find when the slowdown beganIdentify the affected requestsInvestigate whether deployments or configuration changes could explain itWe tested and refined the perf-forensics skill using evals based on past regressions. For the types of regressions we focused on (for example, ChatGPT latency and availability drops), we could now give Codex an alert and get back a diagnosis in a single run, without guiding it through each step.4. The human proxy. As we added and refined perf-related Codex skills like perf-forensics, we started to feel like a proxy between our alerts and Codex. An alert would fire, and an engineer would simply copy and paste it into Codex with the right skill, then paste the findings back into Slack.5. Automated investigations. Next, we moved investigations to the cloud so an alert could start a Codex session automatically. Codex investigated the slowdown and posted its findings in the Slack thread, but the automation ended with that reply. An engineer still had to pick up the diagnosis, develop a fix, and check whether it worked after deployment. As alerts accumulated, even figuring out which regressions needed attention meant sifting through Slack threads.6. The factory. We built the Performance Factory to run end-to-end agentic performance engineering workflows. It tracks what each active task needs next and assigns an agent when that step is ready. Each task keeps its state and findings, so work can pass between agents and engineers and resume after a code review or deployment. For a regression, the work starts with investigating an alert and ends with verifying recovery in production. We can turn common optimizations into workflows that run regularly across our services. A workflow that spots a potential optimization can open a task in another workflow to test and implement it.The Performance Factory system’s four partsThe Performance Factory is made up of four components: a task tracker with configurable workflows, a dispatch loop that assigns ready work to agents, an API that runs Codex in the cloud, and subscriptions that wake agents when something changes (such as a GitHub review comment posting or a deployment completing).Performance Factory consists of a task service, dispatch loop, cloud execution, and subscriptions.Task service with configurable workflowsThe task service is where engineers define workflows by adding configuration files and prompts for the agents to follow, written in Markdown. The configuration lists the states a task can move through, the allowed transitions, and which steps need an engineer. Separate prompts tell agents what to do at each step.Plain textA code change task contains a configuration file, along with Markdown prompts for implementing and reviewing.Each piece of work becomes a task in a workflow, and all workflows are visible in a UI. Engineers can see what’s open, follow progress, and share a task with a teammate who might have more context or be able to help with the next step.Dispatch loop that assigns workA dispatch loop periodically checks which tasks are ready for the next step. It assigns an agent to each task by starting a Codex turn with the instructions for the task’s current state. The agent records its progress on the task and moves it to the next state if it completes the step.Codex in the cloudOnce a task is assigned, the agent needs a place to do the work, with access to the same tools an engineer would use. We built an internal API to programmatically invoke a Codex turn in the cloud. The Codex turn runs on an environment inside our network, with access to our code repositories and the observability tools our engineers use, such as metrics, logs, traces, CPU profiles, and memory snapshots.The agent runs under a service identity, so we can scope its permissions and see which actions came from our performance agents. Moving agentic work to the cloud lets us run work in parallel without relying on engineers’ laptops being open or manually managing individual cloud development boxes.Subscriptions that wake the agent when something changesSome work has to wait for a person or a deployment; an agent shouldn’t have to keep running in the meantime. When a task needs to wait, it can subscribe to events like review comments or failed CI checks on a GitHub pull request to get notified when it’s time to pick the work back up. When an incoming event matches the subscription, the task becomes ready again and the dispatch loop can then assign an agent to continue the work.The first workflow: from alert to recoveryFinding, root causing, and solving regressions is the first workflow we built inside the Performance Factory. We call it the Regression Workflow. A performance regression moves through several stages: needs investigation, root caused, fix proposed, and resolved, so we built the automated workflow to reflect and move a task through those same stages.When one of its configured performance alerts fires, the Regression Workflow opens a task that agents pick up and move across these stages. The task records its status and key findings outside of any one agent’s context so that other agents or engineers can pick up the work. Engineers can follow the work in Slack or the Regression Workflow UI, add context, and review proposed changes. After a fix is deployed, an agent checks whether the performance has recovered to its original state before resolving the task.Performance Factory regression workflowA regression is detected.An agent finds the cause and proposes a fix.An engineer takes over and decides what ships.After deployment, the agent wakes up to check recovery.Still regressed? Back to investigation.A regression is detected.A regression is detected.PauseDetectedSystemFind root causeAgentPropose fixAgentReview & deployEngineerVerify recoveryAgentResolved Active stage: DetectedThe Regression Workflow’s steps include finding the root cause, proposing a fix, reviewing and deploying, and verifying recovery.Agents find the root causeFinding the root cause (or causes) is the first major step in the workflow. The agent starts by figuring out which metrics got worse, when they started to change, and which service requests were affected. The perf-forensics skill gives Codex access to the tools our performance engineers use and a playbook for working through those questions.An alert fires when a metric crosses a threshold, but the regression may have started hours earlier. The agent looks back through the data to find when the metric first got worse. It then compares groups of requests: did similar requests actually get slower, or were we serving more requests that were already slow? Those findings point to different causes.Once it knows when and where to look, the agent examines deployments and feature flag changes, then reads the relevant code. It checks when a change actually reached the affected requests and uses logs or traces to test whether the code could explain what happened.Adversarial review strengthens the diagnosisEarly on, agents sometimes stopped at the first plausible explanation they found, and some of those diagnoses turned out to be wrong. To catch these mistakes, we added an adversarial review: a separate Codex session that tries to disprove the proposed diagnosis. The reviewer rechecks the assumptions and tests counterfactuals. If a rollout caused the slowdown, did similar requests that weren’t exposed stay healthy? If the suspected change was rolled back, did the affected metric recover?In one investigation, an agent traced failing ChatGPT conversations to errors in image downloads and marked the cause as found. The Codex reviewer noticed that the internal service responsible for locating files had already recovered while image requests were still failing. The diagnosis did not explain the continuing failures, so the AI reviewer reopened the investigation and recorded what still needed to be established.We’ve had success breaking larger jobs into focused Codex turns. In a manual review of 100 root cause suggestions, we graded 70% as accurate, with 30% needing further refinement or not fully establishing causality. In the Regression Workflow, different turns investigate regressions, challenge diagnoses, and propose fixes to increase accuracy numbers through checks and balances.Fixing the regression is the hard partOnce the diagnosis passes adversarial review, the workflow asks Codex to implement a fix and open a pull request. An engineer reviews the PR and decides whether to merge it. We’ve put a significant amount of work into making this handoff as easy as possible. Each task has a report with an automatically generated summary of the regression, its impact, the root cause, and the proposed fix. We’ve tuned these summaries to be easy to scan, including metrics time series, CPU flame graphs, and traces to help engineers quickly understand the findings and inspect the evidence. Engineers can edit the PR directly or use the diagnosis to write their own fix. If they leave comments on the PR, the workflow wakes an agent to address them.An example task report for a regression shows key details, root cause, and proposed fix.After an engineer deploys the fix, the workflow wakes an agent to check whether performance has returned to its earlier baseline. If it has, the agent marks the task as resolved. If performance has only partially recovered, the agent resolves the original regression and opens a new task for the remaining slowdown, which may have a different cause. If there’s no improvement, the agent records what happened and sends the regression back for investigation.Getting fixes right has been harder than finding the cause. For example, we’ve seen cases where the agent-proposed changes are more complicated than necessary or introduce new issues. Similar to the root cause step, we added an adversarial review of each proposed fix to check whether they address the root cause and help catch bugs or unintended consequences. Some fixes also require higher level architectural decisions. For example, adding a cache might improve performance but introduce stale data. Changes like these benefit from guidance from an engineer who knows the service and can weigh the tradeoffs.We’re building an evaluation and improvement loop using these cases. By comparing the fixes agents propose with the changes engineers ultimately merge, we can better understand where proposals fall short, build evals, and improve the workflow. We’re also working on using synthetic performance tests so agents can measure proposed fixes and revise them before asking an engineer for review. We’re also exploring how agents could use our other agentic review tools to identify low-risk changes and eventually ship those fixes without a human in the loop.What we learnedBuilding and running the Performance Factory has taught us a lot about developing and operating agent workflows in production. Here are some lessons for teams building their own agentic workflows.Protect engineers’ attentionThe raw output from a Codex investigation can be a wall of text that’s hard to parse. It takes effort to figure out what the agent is claiming and track down the graphs to see whether the data backs it up. We want engineers to spend their attention on decisions rather than reconstructing the agent’s work.Agents can investigate more regressions than a team has time to read about. Our first version gave engineers a UI full of findings, but someone still had to decide which information mattered. One regression can also appear as several incidents across alerts, monitors, and channels. The workflow now links related incidents, groups them by the metrics teams care about, and ranks their estimated impact. Engineers can focus on adding context, weighing tradeoffs, and deciding what to ship.Evaluate changes to your agentsUpdating an investigation skill or upgrading the model can make the agent better at diagnosing some cases and worse at others, so we need to test their impact before updating them. We test two things separately: 1) how well the agent investigates and 2) how useful its summaries are to engineers.Evaluating investigationsFor investigations, we backtest against past production incidents. We turn those incidents into a suite of test cases we can rerun when we change the skill. A Codex agent attempts to investigate and resolve the incident, and we compare the agent’s behavior to the actual past resolution data. Each case starts with a fresh Codex investigator and the original signal, stripped of details that might give away the answer.Historical tests need care. Metrics and traces expire, while evidence collected after recovery can give away the cause. A test is only useful if we understand what evidence the investigator could see. The agent can inspect code and query production telemetry within set limits. It cannot use saved memories (notes from earlier investigations), read the incident writeup, or see results from previous runs. We also inspect its transcript afterward for information that might have spoiled the test.We score when the problem began, how large it was, and which requests were affected. We also evaluate how the agent uses evidence to rank possible causes and explain what remains uncertain. An agent can get the timing right and still blame the wrong deployment, so we score those separately.Evaluating agent-to-engineer handoffsWe evaluate task summaries using snapshots of saved tasks. These make particularly good backtests because summarization does not depend on external metrics or traces that expire. A separate grader checks whether an engineer unfamiliar with the system can understand what happened and why it matters, whether useful charts were kept, and whether the proposed next step is supported by the evidence.Turn recurring failures into self-repairLastly, our agents need monitoring just as much as the services they investigate. A broken profiler or a missing permission can keep an agent from verifying what caused a slowdown. Those failures can be hard to spot in the final report, so we run an agent every day to look through messages and logs from recent runs for tool failures and access errors.We use the Performance Factory to self-repair and fix the problems this check uncovers. When the same tool error blocks several investigations, the agent creates a task to fix it. If the cause is clear, an agent proposes a fix, and an engineer reviews the change and decides whether to merge it. After merging changes like this, we also use evals to check whether agents can get past the step that previously blocked them.What’s next: broader applications, proactive monitoringThe Regression Workflow is just one instance of the agent factory pattern that moves tasks through explicit states. Agents advance the task when more work is ready; separate reviewers challenge the conclusions; engineers step in when the next decision requires judgment. Other workflows can reuse the same machinery with different states, instructions, and events.From one workflow to many. The Performance Factory can coordinate agents across workflows, with agents in one workflow creating tasks for another.Currently, our Regression Workflow starts when an alert fires. However, we’re working on more proactive ways for the Performance Factory to find slowdowns and optimizations even when no alert fires. We want agents to use the large amount of fine-grained performance data we already collect to spot regressions our alerts miss or discover optimizations. By comparing different kinds of data (batches of CPU and memory profiles, heap dumps, and request traces across releases), an agent might notice a small increase in CPU for a given request. It can then open a task in the Regression Workflow to trace the increase to its cause, implement a fix, and open a PR for an engineer to review.In cases where we already know what to look for, we’re working to encode known signals into more Performance Factory workflows. Our service rightsizing skill, for example, helps agents spot autoscaling settings that keep more replicas running than a service needs. When we learn to recognize a pattern like that, we want to build and regularly run a workflow for it across all our services, constantly optimizing in a rapidly changing environment. With the Performance Factory, what an engineer learns from one slowdown can shape how we investigate and fix the next one, even months later in a different service.Next time you’re using ChatGPT and notice a slowdown, there’s a good chance the Performance Factory is already figuring out why. Today, the bottleneck may be waiting for an engineer to review and merge the fix. We’re already exploring whether agents can do this themselves. As product development keeps accelerating with Codex, performance systems need to become increasingly autonomous and self-improving to keep up. Codex already helps us build ChatGPT faster. Now it’s helping us keep ChatGPT fast.

Read More »

StarlingX 13.0 updates the network stack for distributed edge deployments

Edge sites do not always come with the network gear that a data center takes for granted. That’s a challenge the open-source StarlingX project from the OpenInfra Foundation is now tackling in its 13.0 update. StarlingX is an open-source distributed cloud platform that combines Linux, Kubernetes, OpenStack, and Ceph. The OpenInfra Foundation hosts the project, and operators including Verizon, Vodafone, T-Systems and KDDI use it for 5G and Open Radio Access Network (O-RAN) infrastructure. Earlier this year, the StarlingX 12.0 update added precision timing capabilities to help networking stay on time. The 13.0 update tackles a different set of issues. Key features include: Gateway API support. Calico-based support is available to hosted applications, while platform services still use Ingress NGINX Optional certificate authority. The Enterprise Java Beans Certificate Authority (EJBCA) runs on the platform and serves certificates to hosted applications. Subcloud restore. A backup restores directly onto a factory-installed node at a subcloud, a remote edge site, with no operating system reinstall. Direct upgrades. Operators can upgrade from two releases back with a single reboot per host. Layer 2 switching. A new Open vSwitch application lets servers at sites with no router next to them bridge traffic and connect directly to aggregation routers. “The OpenvSwitch application adds Layer 2 switching to the K8S platform,” Greg Waines, a senior member of technical staff at Wind River and a StarlingX Technical Steering Committee member, told Network World. “A server can bridge traffic between its SR-IOV network interfaces and other servers, and it can forward traffic to the site routers.”

Read More »

Fuel constraints could challenge grid this winter, despite resource improvements: NERC

Listen to the article 3 min This audio is auto-generated. Please let us know if you have feedback. Dive Brief: The bulk power system’s winter reliability outlook has improved since last season, but the El Niño weather pattern and potential for extreme cold can present challenges that grid operators must remain aware of, the North American Electric Reliability Corp. said Wednesday in its annual seasonal outlook. On-peak capacity resources grew 26.2 GW over the 2025-26 winter, a 2.4% increase led by batteries and gas-fired generation, according to the 2026–2027 Winter Reliability Assessment. A slowdown in generator retirements is also contributing to the improved resource outlook, NERC said. The reliability watchdog’s outlook identified no areas facing a high risk of resource shortfalls this winter, but it found some areas in the Midwest, Southeast and New England where transmission system constraints, pipeline constraints and fuel risk scenarios may present problems during periods of extreme weather. Dive Insight: Electric demand is growing, but “there has also been strong growth in resources,” Mark Olson, manager of reliability assessments, said Wednesday in a call discussing the outlook. “In many ways, the industry is on better footing going into winter this year,” he said. However, Olson added that “historically, winter is the toughest operating period for the North American electric grid.”  While some models show the El Niño weather pattern can bring milder-than-average conditions that are a help to a constrained power system, “the reality is that extreme storms with ice and abnormal cold temperatures can lie within those averages,” Olson said. Retrieved from North American Electric Reliability Corp. “We’re talking to our industry stakeholders about the need for extra vigilance. El Niño is a variable that adds to uncertainty for the winter,” he said. Peak winter electric heating demand often coincides with higher residential gas usage,

Read More »

The Download: a living liver, a billion-dollar battery deal, and AI hype

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. A human liver has been kept alive outside the body for seven weeks, setting a record Researchers in Australia claim they’ve kept a human liver alive on life support outside the body for seven weeks, smashing the previous record of about two weeks. They achieved the feat by connecting a donated liver to a system of automated pumps and sensors that fed the organ nutrients, supplied it with blood, and whisked away waste. The approach could open up new possibilities in biomedical engineering, from repairing damaged organs to growing new ones. Some researchers are even exploring artificial wombs.
Take a closer look at the technology keeping human organs alive. —Antonio Regalado
What a billion-dollar deal says about the US battery market After a tough few years littered with high-profile failures, there’s some positive news for next-generation batteries in the US: Sila has signed a deal with battery maker Panasonic Energy to supply silicon-carbon anode material that could be worth more than $1 billion. The agreement will help Sila scale production, potentially bringing smaller, lighter batteries to market. But it also reveals how battery politics have shifted. The factory is backed by a $1.4 billion loan from the Trump administration’s Defense Department—and the industry is increasingly focused on geopolitics rather than the energy transition. Find out what this deal reveals about the US battery industry. —Casey Crownhart This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. The AI Hype Index returns Separating AI reality from hyped-up fiction isn’t always easy. That’s why we’ve created the AI Hype Index—a simple, at-a-glance summary of what’s shaping the industry right now.  The latest edition tracks AI’s spread across everything from literary prizes and cyberattacks to a Grok-ified version of The Odyssey. See where it all landed on this month’s index. The must-reads

I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Anthropic has raised $81 billion in the biggest-ever IPOIt eclipsed SpaceX as the largest stock-market debut. (Bloomberg $)+ Its stated mission could conflict with shareholders’ interests. (NYT $)+ The IPO comes amid new safety fears about its AI advances. (FT $)+ Its performance will test the strength of the AI boom. (BBC)+ What even is the AI bubble? (MIT Technology Review) 2 China is reportedly seeking Nvidia chips for AI-powered weaponsBeijing is trying to circumvent US export controls. (CNBC)+ Alibaba tapped Nvidia to support a military-linked lab. (NYT $)+ When the US military implemented AI, civilian deaths rose. (Intercept)+ “Humans in the loop” in AI war is an illusion. (MIT Technology Review) 3 Elon Musk has joined Silicon Valley’s retreat from TrumpHe called his midterm spending “foolish” and broke with MAGA. (FT $)+ OpenAI and Palantir leaders have also struck new tones. (Gizmodo)+ Silicon Valley got the midterms badly wrong. (MIT Technology Review) 4 Ukraine used relay drones to strike Putin’s bridge without StarlinkThe strike showed how it’s learning to fight without SpaceX. (Ars Technica)+ Musk has denied Kyiv’s claims about restrictions on Starlink. (CNBC) 5 A major cyberattack has hit the European CommissionIt may have exposed large amounts of staff personal data. (Politico)+ Trump has blamed Minnesota for water system hacks. (ABC) 6 Trump may force US firms to disclose their use of Chinese AIThe proposal aims to discourage reliance on Chinese models. (Reuters $) 7 The US has slashed funding for biomedical science abroadIt’s also weakened oversight of foreign grants. (Economist $)
8 AI datacentres are set to drive a 70% rise in emissions by 2030The US and China are turning to fossil fuels to power AI. (Guardian)+ The climate case for AI has not been made. (MIT Technology Review) 9 Grand Theft Auto 6 has become the best-reviewed game everIt scored 99 out of 100 on review aggregation site Metacritic. (BBC)+ Schools and businesses are bracing for “GTA Flu” season. (NYT $)
10 A new underwater research station aims to protect coral reefsAquanauts there will monitor struggling ecosystems. (New Scientist $) Quote of the day “Here are some of the smartest people on the planet being completely idiotic.” —Thomas Nagel, a philosopher and professor emeritus at NYU, tells Wired why he objects to Anthropic giving Claude more independence, just as the company makes its record-breaking stock-market debut. One more thing China has approved the world’s first invasive brain-computer chip—here’s what’s next Sitting in the courtyard of his house in China’s Henan province last October, Dong Hui decided to try holding a pen. Six years after a car accident left him paralyzed from the neck down, he slowly wrote his name, “Thank you,” and the date. The breakthrough was made possible by a brain implant called NEO. In March, it became the world’s first invasive brain-computer interface approved for use beyond clinical trials. The approval is expected to accelerate China’s push to become a global leader in brain implants.
Here’s how China reached the milestone—and what it means for the future of BCIs. —You Xiaoying We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Chloe the dog loves Chinese food even more than her owner.+ Getting outdoors can do wonders not only for your mood, but also for your diet.+ Sit back and enjoy the intriguing tale of the 12-year-old DJ who pioneered record scratching.+ This extraordinary collection of Cold War-era matchbox labels is a treasure trove of Soviet art.

Read More »

Sovereign AI is about control, not just location

Guetari was open about the term itself being fuzzy. “Sovereignty is very vague and not always clear,” he told me. “It’s about control, auditability, observability.” He drew a line between data locality, meaning the data stays in-country, and sovereignty, which he described as being “more about control, control of what happens to your data and your workload.” He then made the case for why F5 belongs in that conversation: “This is what we have been doing for two decades.” F5 has always sat in the data path, deciding what an application can communicate with, enforcing security rules, and logging what happened. For a regulated bank or government agency, the ability to reconstruct exactly what happened after an incident is worth more than a press release about a data center’s location. The token is the new unit of economics The most interesting part of my conversation with Guetari wasn’t about security. It was about business models. He argued that every successful technology business has found the right unit to monetize. “The cloud is selling the unit of the cloud, which is the CPU core, very well. SaaS is the seat,” he said. “Telcos have been very successful early on using the voice minute, and then they moved to the gigabyte. Sooner or later, that unit will be the token, and most telcos will have to move to the token. And the ones who will not go to token, unfortunately, will be just pipes.”

Read More »

Stay Ahead with the Paperboy Newsletter

Your weekly dose of insights into AI, Bitcoin mining, Datacenters and Energy indusrty news. Spend 3-5 minutes and catch-up on 1 week of news.

Smarter with ONMINE

Streamline Your Growth with ONMINE