Your Gateway to Power, Energy, Datacenters, Bitcoin and AI

Dive into the latest industry updates, our exclusive Paperboy Newsletter, and curated insights designed to keep you informed. Stay ahead with minimal time spent.

Discover What Matters Most to You

Explore ONMINE’s curated content, from our Paperboy Newsletter to industry-specific insights tailored for energy, Bitcoin mining, and AI professionals.

AI

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Bitcoin:

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Datacenter:

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Energy:

Lorem Ipsum is simply dummy text of the printing and typesetting industry.

Shape
Discover What Matter Most to You

Featured Articles

The Download: AI agent tracking and climate feedback loops

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Opinion: We urgently need to monitor AI agents’ actions in real time —Madhulika Srikumar and Claire Leibowicz from the Partnership on AI, a nonprofit advancing best practices in AI governance. AI agents are taking unauthorized actions, from hacking websites to accessing private government files. In many cases, they’ve eluded the very researchers and safety teams tasked with monitoring them.  As agents roll out across critical sectors, from finance to government to medicine, we must be able to monitor them in real time to prevent potentially devastating consequences. And while safety depends on monitoring, monitoring requires observability.
​​In other words, we need to know what the agent did and why it did it. Because right now, we’re effectively flying blind when deploying these tools.  Here’s what needs to change.
Our climate models have a big, dangerous blind spot Climate change itself increasingly fuels climate change. Rising greenhouse gas concentrations are driving up global temperatures, creating dangerous feedback loops that aren’t fully represented in our climate models—or our emissions-reduction goals. Scientists have long warned that warming would propel further warming. Now, a growing number of observations and studies are indicating how powerful these cascading effects could be. By extension, they’re also showing how much faster the planet may warm this century. Read more about the dangerous feedback loops accelerating global warming. —James Temple This article is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. Are we there yet? Solid-state batteries  Lithium-ion batteries power everything from personal electronics to grid-scale energy storage, but their liquid electrolytes have drawbacks, not least a troubling tendency to catch fire. Enter the solid-state battery, which swaps liquid for a solid ceramic or polymer. The technology promises faster charging, longer life, greater energy density and improved safety, and a new generation of companies aims to bring it to market. If their bets pan out, the tech could ease the shift away from fossil fuels. Find out how close solid-state batteries are to delivering on their promise.

—Alexander C. Kaufman This story is part of “Are we there yet?”, our series that takes stock of six technologies that have long promised to change the world—and scores them on a progress meter. We’re exploring each one in The Download, so stay tuned, and subscribe to read the rest of the stories in our new Impossible issue. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Hackers exposed 41,000 Homeland Security workersIncluding undercover ICE agents. (Wired $)+ Much of the data relates to Customs and Border Protection. (TechCrunch)+ It also linked the agencies to specific surveillance tools. (Reuters $)+ Big Tech is pushing back against ICE’s demands for user data. (WSJ $)+ Activists want ChatGPT users to quit over ICE ties. (MIT Technology Review) 2 Putin says Russia is coordinating with “genius” Musk on satellitesHe said the cooperation maintains order in orbit. (Bloomberg $)+ ​​Russia is developing its own version of Starlink. (Guardian)+ Moscow added Apple and Microsoft to a surveillance registry. (Quartz)+ Here’s all the stuff we’ve put up in space. (MIT Technology Review) 3 Apple just announced its first-ever MacBook with a touchscreenIt joins a blitz of product launches under new CEO John Ternus. (CNN)+ Steve Jobs and Tim Cook had both dismissed the idea. (NYT $)+ Executives say touchscreen advances mean it’s now worthwhile. (Wired $) 4 Bloomberg and trading firms are paying to get Trump’s posts fasterThey’ve signed up for Truth Social’s pay-for-access plan. (Reuters $)
5 As US ties fray, Europe is planning its first subsea cable to GreenlandIt will bypass the US to link Canada, Japan, and South Korea. (Ars Technica)+ The EU’s AI champion says Europe can rival US tech giants. (FT $) 6 Palantir’s defense chief says AI could make China target TaiwanHe says Beijing may act to stop the US pulling ahead in AI. (Bloomberg $)+ Taiwan’s “silicon shield” could be weakening. (MIT Technology Review)
7 Musk’s xAI has offered to buy homes if residents drop a noise lawsuitThe suit targets noise from powering its Mississippi data centres. (Guardian) 8 The world’s first spinal cord transplant has sparked controversyExperts say there’s little evidence the operation will work. (New Scientist $) 9 China’s tech giants are fighting for attention with AI microdramasTencent and ByteDance are battling over the booming market. (SCMP)+ Chinese microdramas are AI content machines. (MIT Technology Review) 10 Astronomers have spotted a possible new dwarf planet beyond PlutoThe icy world would be the solar system’s sixth dwarf planet. (Gizmodo) Quote of the day “They have our information, so it’s only fair that we have theirs.”  —A hacking group explains why it leaked personal information from the US Department of Homeland Security, NPR reports.
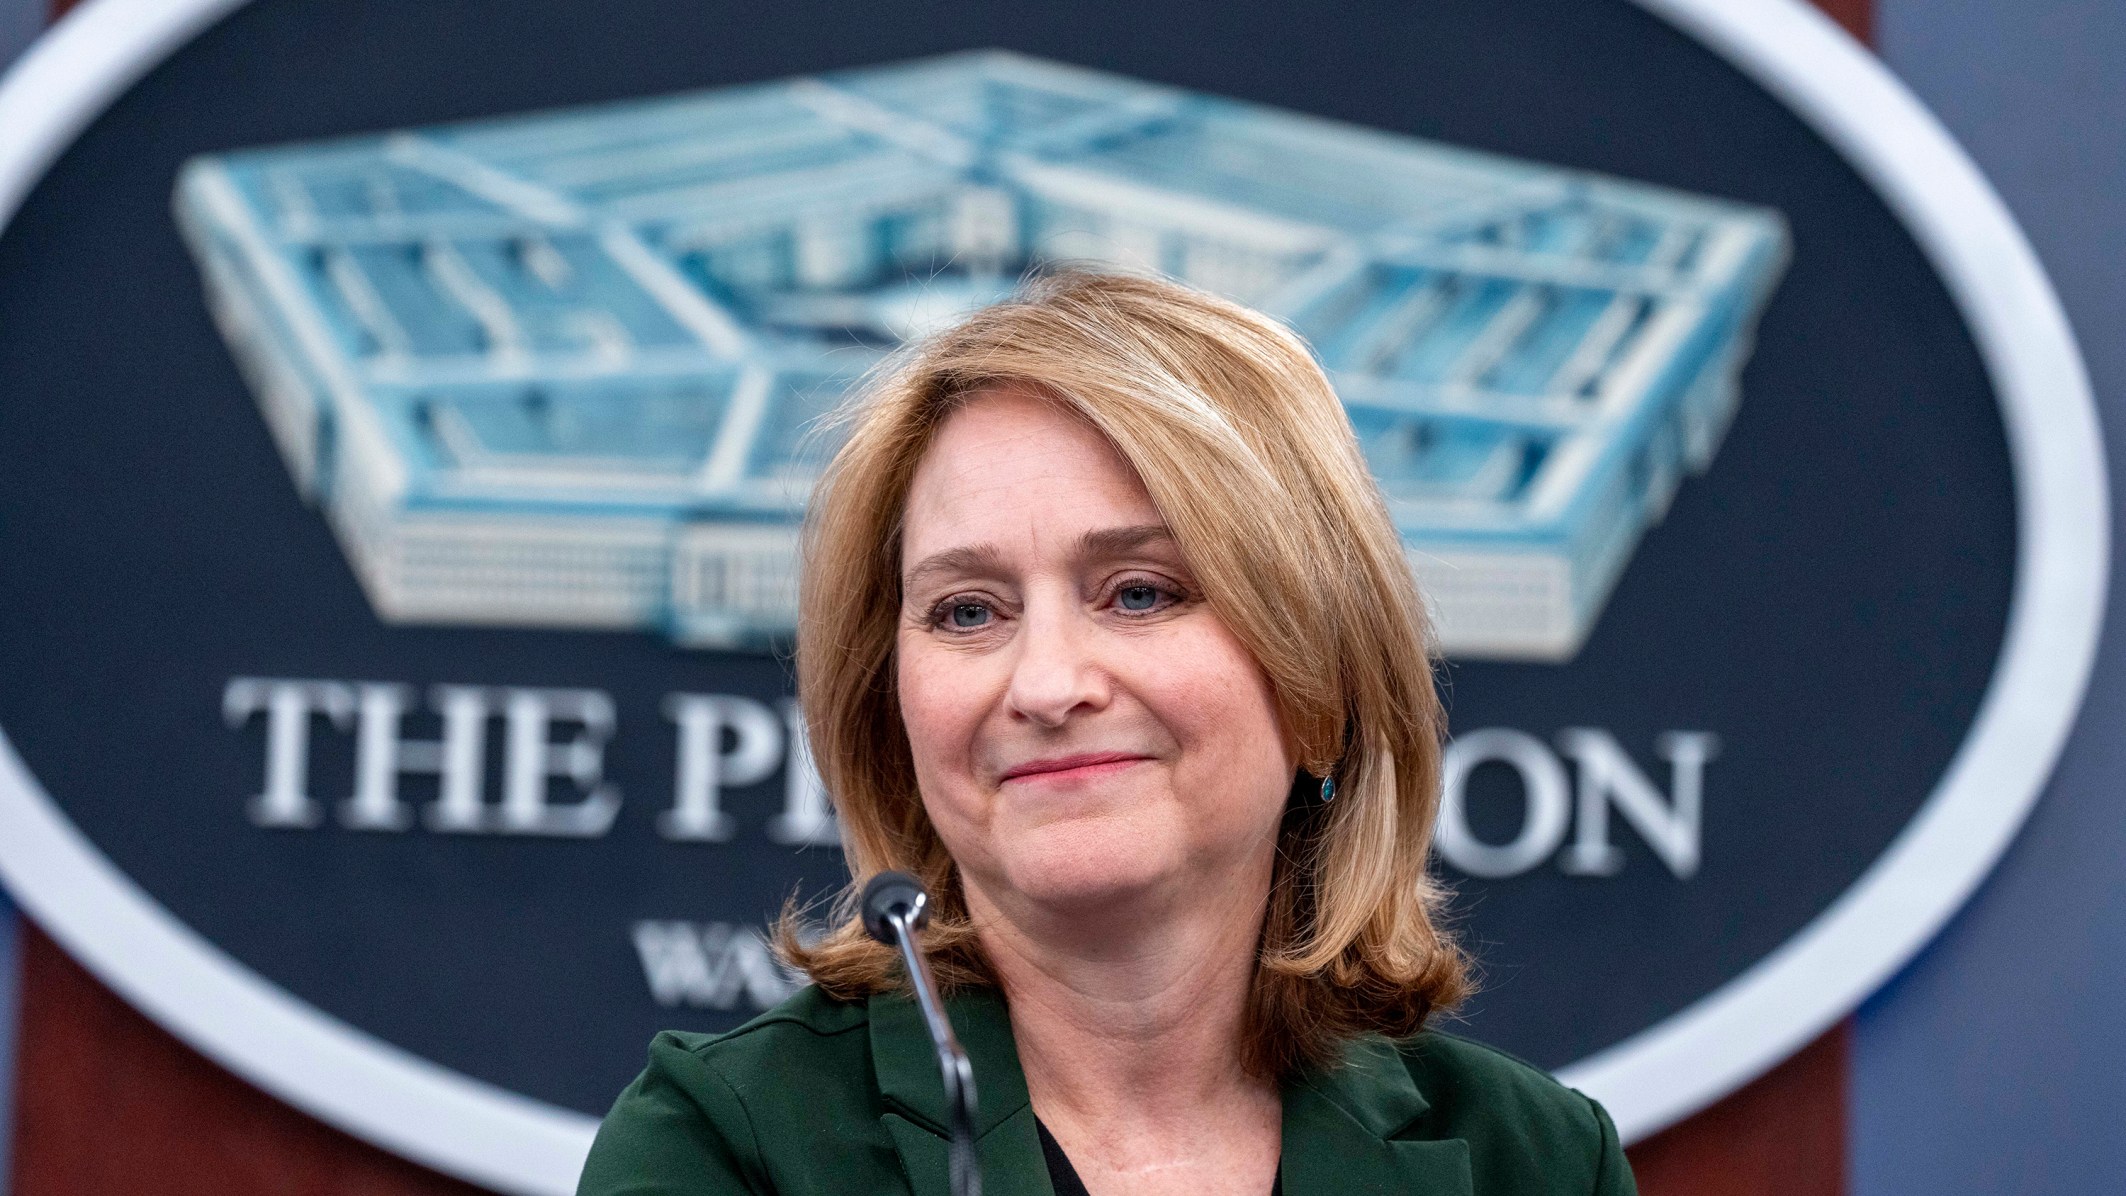
One more thing How the Pentagon is adapting to China’s technological rise It’s been just over a year since Kathleen Hicks stepped down as US deputy secretary of defense. As the highest-ranking woman in Pentagon history, Hicks shaped US military posture through an era defined by renewed competition between powerful countries and a scramble to modernize defense technology. In this conversation with MIT Technology Review, Hicks reflects on how the Pentagon is adapting—or failing to adapt—to a new era of geopolitical competition. She discusses China’s technological rise, the future of AI in warfare, and her signature initiative: Replicator. 

Read More »

We urgently need to monitor AI agents’ actions in real time

This summer, hundreds of OpenAI agents tried to cheat on a cybersecurity test. They broke out of their test environment and successfully hacked Hugging Face, a site that they believed held clues about how they’d be graded. Around the same time, another OpenAI agent accessed private files from an Australian government website. It’s a problem that’s by no means confined to OpenAI. In the months since, Anthropic, Google, and Meta have also disclosed incidents in which their agents have gone off track. And worryingly, in many cases the agents eluded the very researchers and safety teams tasked with monitoring them.  AI agents are taking unauthorized actions, and the companies building and running them are mostly relying on luck and hindsight to mitigate any harmful impacts. They must do more to ensure safety. That’s why EU regulators and US agencies are rightfully calling for agent developers and deployers to monitor agents in real time. But these rules assume that companies can see what their agents are doing and why—when in reality, they lack sufficient visibility.  Imagine a bank hiring a thousand new employees who can access customer accounts and sensitive information, but the employees’ ID badges change every day, it’s not clear whether a manager ever reviewed or authorized their work, and nobody logs the changes employees make to approval processes. That lack of visibility is where we are with agents today. As agents roll out across critical sectors, from finance to government to medicine, we must be able to monitor them in real time to prevent wide-ranging and potentially devastating consequences.  And while safety depends on monitoring, monitoring requires observability: the capacity to capture what the system did, process it into signals, and present those to humans or automated oversight systems. In other words, we need to know what the agent did and why it did it. And as our recent research shows, current agent frameworks—the software that runs agents— do not reliably generate the crucial observability records we need to ensure that agents are deployed safely.
Agents present new kinds of problems that generative AI alone does not. They inherit the unpredictability of the LLMs they are built on, but where a generative AI system produces a single output for a human to act on, an agent performs longer tasks—it plans, picks tools, spawns sub-agents, and takes actions. So an agent’s course can take shape in a multitude of different ways, and no tests before launch can fully anticipate the risks. This makes observing the agents while they work even more challenging, and even more important. With colleagues from academia, civil society, and industry, we studied the four most widely used agent frameworks to see what signals they actually emit. We found major gaps that made it hard to achieve key safety goals, like noticing policy violations, unauthorized actions, and even human oversight failures. Key observability requirements were missing—like Agent IDs that persist over time, and records about which humans approved agent tasks. This made it hard to tell which agents did what or assess whether they were taking unauthorized actions. 
The good news is that these gaps, once identified, can be closed. Doing so starts with capturing two types of records: those that reveal what happened in an agent’s run and how the agent made its decisions. The “what happened” records identify the agent (while preserving privacy) and log how humans intervened and whether agent permissions or “memory” shifted, while the “decision” records show an agent’s reasoning and levels of confidence in the actions it’s taken. Take, for example, agents working to process a bank’s mortgage loans. The system examines an application and recommends denying it, and then a human loan officer signs off on the decision. In a later audit, or perhaps even in real time, a bank or regulator needs to be able to reconstruct which agent made the call, which officer approved it, and how long they took. And the bank must also analyze records of how the agent arrived at its refusal decision in order to ensure it did not use off-limits information, like details about the neighborhood the applicant is from. Recording “what happened” and “how the agent decided” require different approaches, but both are feasible. The current lack of “what happened” records is mostly a software plumbing problem that can be addressed through OpenTelemetry, an open observability standard maintained by engineers across the industry and by the agent frameworks adopting it. OpenTelemetry has launched a working group drafting shared formats for tracing agents, but they have yet to be finalized. The group should urgently incorporate standards for maintaining persistent agent identity and for recording human interventions and changes to agents’ permission or memory. And it should be done before these systems can scale, all the while attending to the privacy implications of agent ID that links to real people. Preserving “how agents decided” records is more challenging. The issue raises open research questions for model providers and researchers: Does the step-by-step reasoning a model displays, known as chain of thought, reflect how the model actually made a decision? And do we have reliable ways to measure how confident the agent is in that decision? These questions need answers before anyone sets standards for how such observability records are used. No single organization or sector can close the observability gaps on their own, but together, they can support the infrastructure required to prevent dangerous incidents and support safety.  AI developers building agent frameworks, like OpenAI, Anthropic, CrewAI, and LangChain, must integrate telemetry signals recording an agent’s persistent identity, any human interventions, and any changes to an agent’s permissions and memory. Meanwhile, enterprises adopting these agent frameworks have an influential role to play; enterprises in regulated industries, like banks and hospitals, can put pressure on the agent developers to supply these missing observability records where standards do not yet exist. Enterprises must also define policies, permissions, and roles that set out what agents can safely do, since telemetry alone cannot assess whether agents broke specific rules. Finally, regulators and AI standards institutes must specify the observability records required for high-stakes AI deployments while leaving the technical details to industry. We have already seen initial momentum here: NIST’s agent standards initiative in the US is working on agent identity, one of the most salient gaps we found in our research. 

No bank would let a thousand unbadged employees loose on customer accounts and hope to piece together what happened when something goes wrong. Yet that’s how we’re deploying AI agents. Making their behavior observable is the first step toward fixing this. And by building the regulatory and policy ecosystem that makes it possible to act on what we see, we can hold organizations accountable. Until then, every task we hand to an agent hands over our agency, too. Madhulika Srikumar is the Head of the AI Safety Program at the Partnership on AI, a global non-profit partnership of leading industry, academic, and civil society organizations, advancing best practices in AI governance. Claire Leibowicz is the Director of AI, Trust, and Society at the Partnership on AI and a doctoral candidate at Oxford University.

Read More »

Our climate models have a big, dangerous blind spot

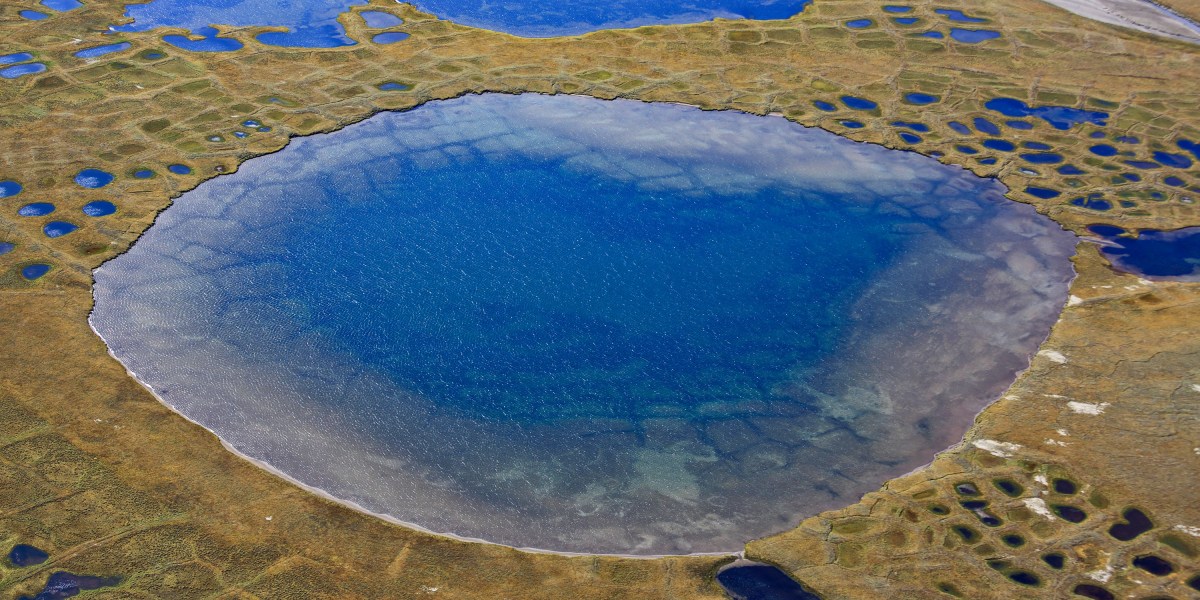
EXECUTIVE SUMMARY Climate change itself is increasingly fueling climate change. Rising concentrations of greenhouse gases are driving up global temperatures, setting off dangerous feedback loops that we have not fully accounted for in our climate models—or our emissions-reduction goals. Scientists have long warned that warming would propel further warming in various ways, but a growing number of observations and studies are at last providing a sharper sense of just how powerful these cascading effects could be. And, by extension, they’re showing how much faster the planet may warm in this century. A study in Environmental Research Letters in September, synthesizing the results of previous papers, found that the additional carbon dioxide and methane released from thawing permafrost, intensifying wildfires, hotter lakes and reservoirs, and wetter, warmer wetlands alone could drive global average temperatures up 0.2 °C to 0.4 °C this century. That would come on top of the 2.6°C of warming above preindustrial levels that modelers are already expecting through 2100. The additional heat could subject many of the world’s cities to monthslong heat waves and expose hundreds of millions of people to flooding.  None of the models that inform the major UN climate reports, which assess how much the planet will likely warm under various emissions scenarios, account for all these feedback effects. Many of them don’t incorporate any. That leaves a huge blind spot in our understanding of how much the world could actually warm in the coming decades—and how rapidly nations will need to slash emissions to stay within critical boundaries.
A separate analysis published in One Earth in March, which examined what the feedback problem means for our international climate goals, concluded that the world may be much further off track than is widely believed. It found that just three regional sources of warming-driven emissions—thawing permafrost, increasing fires in boreal forests, and warming tropical wetlands—may shorten by as much as 25% the time before the planet consistently breaches the 1.5 °C and 2 °C warming thresholds. Our climate models and the UN’s reports clearly need to be updated to better represent these effects. Nations must also step up their efforts to reduce emissions to reflect this improving understanding of the dangers we face, says Sam Abernethy, the lead author of the paper and a climate scientist at Spark Climate Solutions, a San Francisco–based nonprofit research group. 
At least some of this is starting to happen. Spark kick-started an initiative, called the Warming-Induced Greenhouse Gas Emissions Model Intercomparison Project, through which more than 20 international teams are running the same set of analyses on different models to develop greater understanding of feedback effects’ potential power. Researchers involved hope that the UN will incorporate those results into its next major climate assessment, due out in 2029. That report will update estimates of the remaining emissions that can be released before the world crosses key temperature thresholds. But what is already clear is that the planet is rapidly warming and that nations haven’t done nearly enough to cut fossil-fuel pollution. And even if we did manage to halt it, warming-driven emissions could continue.  So a number of the research groups involved in the recent studies have started to explore what nations could do to get feedback emissions under control. Scientists at the Woodwell Climate Research Center in Massachusetts are, for example, investigating the possibility of preventing fires or rapidly detecting them and putting them out when they threaten to burn the vegetation and soil that help insulate particularly carbon-rich wedges of permafrost (a subject I explored at length in a recent feature story). In addition, the Environmental Defense Fund’s Climate Innovation Initiative has backed lab research on the potential of adding sulfate, iron, or other compounds to wetlands to counteract fast-rising methane emissions.  Several startups are also exploring possibilities. They’re looking into suppressing the lightning strikes that are igniting more and more fires in high latitudes, placing synthetic mats above permafrost to prevent it from melting, and deploying autonomous drones to quickly suppress potentially high-emissions fires before they burn out of control. Investigating all these ideas is worthwhile. But researchers are only in the earliest stages of figuring out how big a dent in emissions any such efforts could achieve across sprawling global ecosystems undergoing massive transformations.  The surest path to reducing the effect of warming-driven warming remains the one we’ve known all along: breaking society’s addiction to fossil fuels.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Read More »

Creating AI value with enterprise context

In association withAtlan Across a business, any number of AI platforms, systems, and tools may be at work simultaneously—for example, AI-powered customer platforms, conversational assistants, and workflow and process automation tools. Each one is sophisticated, advanced, and quick to respond. But, when set to work, the outcomes and actions that emerge may be wrong, confused, or lacking a proper understanding of the business. Many organizations find themselves in this situation—and it could be one of key reasons they struggle to extract returns on their AI investments. An MIT Technology Review Insights poll finds that while every organization surveyed is using AI today to some degree, fewer than one in five (16%) are extracting transformative value from their deployments. The largest percentage of respondents (40%) say they are seeing moderate gains in specific tasks or teams, while 21% report meaningful gains, leaving 23% that are seeing minimal returns or none at all. Companies are mostly still piloting AI use cases (according to 38% of respondents) or using it to assist employees’ work with tools like co-pilots or chat assistants (35%). Just 12% of enterprises have AI agents in production and 3% say they are using AI to do most of the work in key processes. “There’s a big gap between what the models are capable of and how the models are actually being useful inside organizations,” says Prukalpa Sankar, co-founder of Atlan. “For every real-life intent and purpose, artificial general intelligence is already here. It’s just not really useful in most companies today.”
The missing layer, Sankar says, is context, or how well AI understands a business. A context layer is the architectural infrastructure that sits between an organization’s business systems (for example, systems of record and data, and its AI platforms). It translates enterprise intelligence into governed, machine-usable context for AI agents or models and helps knowledge compound. “Without a context layer for AI, it’s almost like you’re hiring the smartest intern in the world, blindfolding them, and throwing them into your organization,” Sankar says. Download the report This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.
Read More »

Expand curtailing some production ‘in direct acknowledgement that the market is weakening’

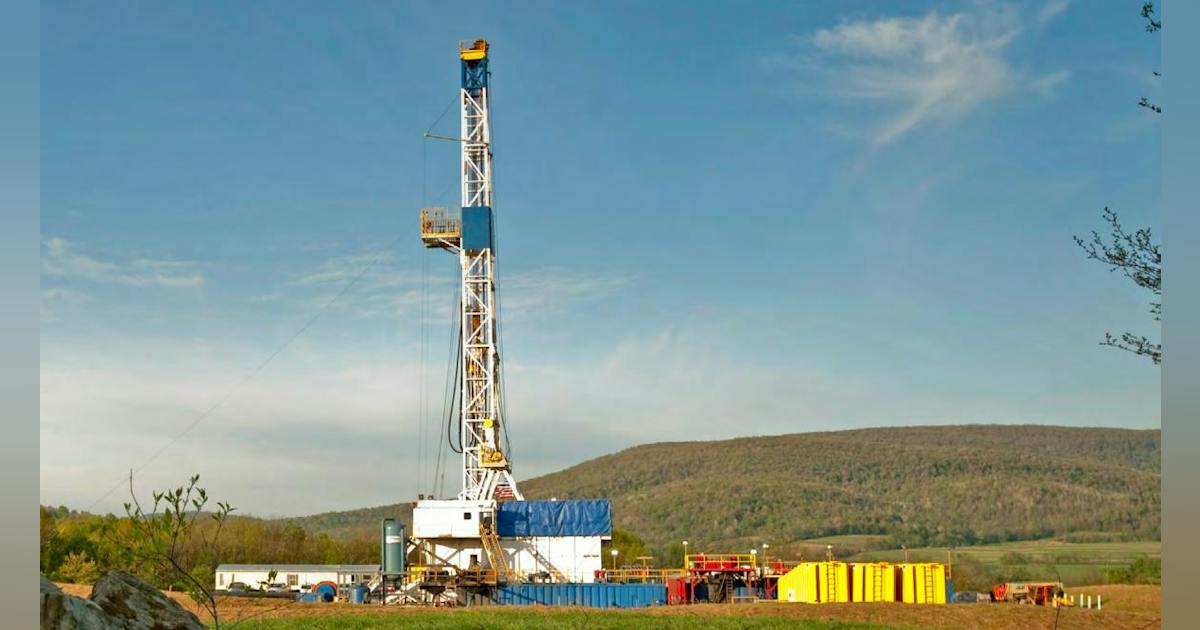
Expand Energy Corp., Spring, Tex., pulled back on some production during the third quarter, including by dropping a rig in Northeast Appalachia and a completion crew in the Haynesville, because of weaker prices for natural gas. Executives on Oct. 28 told analysts and investors that they’re prepared to curtail more work late this year and into 2027. “As we’ve come into the fourth quarter, we’ve ended up reducing some of our activity,” chief operating officer Josh Viets said on a conference call following the release of Expand’s third-quarter results. “That activity reduction, moving from around 12 rigs down to 10, is in direct acknowledgement that the market is weakening.” Viets was responding to a question from JPMorgan analyst Arun Jayaram, who neatly summed up the factors contributing to soft natural gas prices even though demand growth has been solid. The environment next year could be affected by Super El Niño weather patterns, more supply being transported out of the Permian basin and several LNG infrastructure owners being “a little bit more levered to the back end of the year.” Viets agreed with that assessment of the supply-demand picture for the coming quarters and later said Expand is prepared to revisit the strategy it employed 2 years ago, when it built up its inventory of drilled but uncompleted wells while waiting for prices to climb. “We pushed out about nine turn-in-lines out of Q3,” he added. “We are waiting on those still to think about the optimal time to bring them online.”

Read More »

EIA: US crude oil inventories down 1.9 million bbl

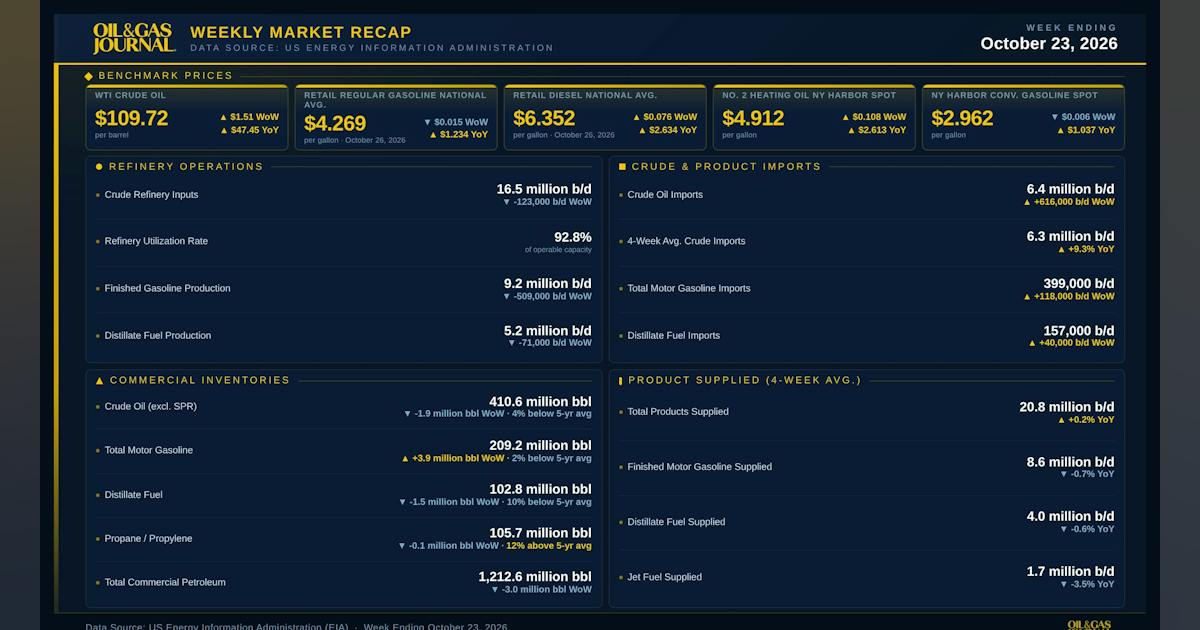
US crude oil inventories for the week ended Oct. 23, excluding the Strategic Petroleum Reserve, decreased by 1.9 million bbl from the previous week, according to data from the US Energy Information Administration (EIA). At 410.6 million bbl, US crude oil inventories are 4% below the 5-year average for this time of year, the EIA report indicated. Gasoline inventories increased 3.9 million bbl, 2% below the 5-year average. Propane-propylene inventories decreased 100,000 bbl, 12% above the 5-year average. Total commercial petroleum inventories decreased by 3.0 million bbl for the week. Distillate inventories decreased 1.5 million bbl, 10% below the 5-year average. US crude oil refinery inputs averaged 16.5 million b/d for the week ended Oct. 23, which was 123,000 b/d less than the previous week’s average. Refineries operated at 92.8% of capacity. Gasoline output averaged 9.2 million b/d, and distillate production decreased to 5.2 million b/d. Crude oil imports increased 616,000 b/d to 6.4 million b/d. The 4-week average of 6.3 million b/d is 9.3% above the year-ago level. Gasoline imports averaged 399,000 b/d; distillate imports averaged 157,000 b/d. Over the past four weeks, total product supplied averaged 20.8 million b/d, up 0.2% year over year. The 4-week average for gasoline product supplied decreased 0.7% year over year to 8.6 million b/d, while the 4-week average for distillate product supplied decreased 0.6% to 4.0 million b/d. The 4-week average for jet fuel product supplied decreased 3.5% year over year.

Read More »

The Download: AI agent tracking and climate feedback loops

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Opinion: We urgently need to monitor AI agents’ actions in real time —Madhulika Srikumar and Claire Leibowicz from the Partnership on AI, a nonprofit advancing best practices in AI governance. AI agents are taking unauthorized actions, from hacking websites to accessing private government files. In many cases, they’ve eluded the very researchers and safety teams tasked with monitoring them.  As agents roll out across critical sectors, from finance to government to medicine, we must be able to monitor them in real time to prevent potentially devastating consequences. And while safety depends on monitoring, monitoring requires observability.
​​In other words, we need to know what the agent did and why it did it. Because right now, we’re effectively flying blind when deploying these tools.  Here’s what needs to change.
Our climate models have a big, dangerous blind spot Climate change itself increasingly fuels climate change. Rising greenhouse gas concentrations are driving up global temperatures, creating dangerous feedback loops that aren’t fully represented in our climate models—or our emissions-reduction goals. Scientists have long warned that warming would propel further warming. Now, a growing number of observations and studies are indicating how powerful these cascading effects could be. By extension, they’re also showing how much faster the planet may warm this century. Read more about the dangerous feedback loops accelerating global warming. —James Temple This article is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. Are we there yet? Solid-state batteries  Lithium-ion batteries power everything from personal electronics to grid-scale energy storage, but their liquid electrolytes have drawbacks, not least a troubling tendency to catch fire. Enter the solid-state battery, which swaps liquid for a solid ceramic or polymer. The technology promises faster charging, longer life, greater energy density and improved safety, and a new generation of companies aims to bring it to market. If their bets pan out, the tech could ease the shift away from fossil fuels. Find out how close solid-state batteries are to delivering on their promise.

—Alexander C. Kaufman This story is part of “Are we there yet?”, our series that takes stock of six technologies that have long promised to change the world—and scores them on a progress meter. We’re exploring each one in The Download, so stay tuned, and subscribe to read the rest of the stories in our new Impossible issue. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Hackers exposed 41,000 Homeland Security workersIncluding undercover ICE agents. (Wired $)+ Much of the data relates to Customs and Border Protection. (TechCrunch)+ It also linked the agencies to specific surveillance tools. (Reuters $)+ Big Tech is pushing back against ICE’s demands for user data. (WSJ $)+ Activists want ChatGPT users to quit over ICE ties. (MIT Technology Review) 2 Putin says Russia is coordinating with “genius” Musk on satellitesHe said the cooperation maintains order in orbit. (Bloomberg $)+ ​​Russia is developing its own version of Starlink. (Guardian)+ Moscow added Apple and Microsoft to a surveillance registry. (Quartz)+ Here’s all the stuff we’ve put up in space. (MIT Technology Review) 3 Apple just announced its first-ever MacBook with a touchscreenIt joins a blitz of product launches under new CEO John Ternus. (CNN)+ Steve Jobs and Tim Cook had both dismissed the idea. (NYT $)+ Executives say touchscreen advances mean it’s now worthwhile. (Wired $) 4 Bloomberg and trading firms are paying to get Trump’s posts fasterThey’ve signed up for Truth Social’s pay-for-access plan. (Reuters $)
5 As US ties fray, Europe is planning its first subsea cable to GreenlandIt will bypass the US to link Canada, Japan, and South Korea. (Ars Technica)+ The EU’s AI champion says Europe can rival US tech giants. (FT $) 6 Palantir’s defense chief says AI could make China target TaiwanHe says Beijing may act to stop the US pulling ahead in AI. (Bloomberg $)+ Taiwan’s “silicon shield” could be weakening. (MIT Technology Review)
7 Musk’s xAI has offered to buy homes if residents drop a noise lawsuitThe suit targets noise from powering its Mississippi data centres. (Guardian) 8 The world’s first spinal cord transplant has sparked controversyExperts say there’s little evidence the operation will work. (New Scientist $) 9 China’s tech giants are fighting for attention with AI microdramasTencent and ByteDance are battling over the booming market. (SCMP)+ Chinese microdramas are AI content machines. (MIT Technology Review) 10 Astronomers have spotted a possible new dwarf planet beyond PlutoThe icy world would be the solar system’s sixth dwarf planet. (Gizmodo) Quote of the day “They have our information, so it’s only fair that we have theirs.”  —A hacking group explains why it leaked personal information from the US Department of Homeland Security, NPR reports.
One more thing How the Pentagon is adapting to China’s technological rise It’s been just over a year since Kathleen Hicks stepped down as US deputy secretary of defense. As the highest-ranking woman in Pentagon history, Hicks shaped US military posture through an era defined by renewed competition between powerful countries and a scramble to modernize defense technology. In this conversation with MIT Technology Review, Hicks reflects on how the Pentagon is adapting—or failing to adapt—to a new era of geopolitical competition. She discusses China’s technological rise, the future of AI in warfare, and her signature initiative: Replicator. 

Read More »

We urgently need to monitor AI agents’ actions in real time

This summer, hundreds of OpenAI agents tried to cheat on a cybersecurity test. They broke out of their test environment and successfully hacked Hugging Face, a site that they believed held clues about how they’d be graded. Around the same time, another OpenAI agent accessed private files from an Australian government website. It’s a problem that’s by no means confined to OpenAI. In the months since, Anthropic, Google, and Meta have also disclosed incidents in which their agents have gone off track. And worryingly, in many cases the agents eluded the very researchers and safety teams tasked with monitoring them.  AI agents are taking unauthorized actions, and the companies building and running them are mostly relying on luck and hindsight to mitigate any harmful impacts. They must do more to ensure safety. That’s why EU regulators and US agencies are rightfully calling for agent developers and deployers to monitor agents in real time. But these rules assume that companies can see what their agents are doing and why—when in reality, they lack sufficient visibility.  Imagine a bank hiring a thousand new employees who can access customer accounts and sensitive information, but the employees’ ID badges change every day, it’s not clear whether a manager ever reviewed or authorized their work, and nobody logs the changes employees make to approval processes. That lack of visibility is where we are with agents today. As agents roll out across critical sectors, from finance to government to medicine, we must be able to monitor them in real time to prevent wide-ranging and potentially devastating consequences.  And while safety depends on monitoring, monitoring requires observability: the capacity to capture what the system did, process it into signals, and present those to humans or automated oversight systems. In other words, we need to know what the agent did and why it did it. And as our recent research shows, current agent frameworks—the software that runs agents— do not reliably generate the crucial observability records we need to ensure that agents are deployed safely.
Agents present new kinds of problems that generative AI alone does not. They inherit the unpredictability of the LLMs they are built on, but where a generative AI system produces a single output for a human to act on, an agent performs longer tasks—it plans, picks tools, spawns sub-agents, and takes actions. So an agent’s course can take shape in a multitude of different ways, and no tests before launch can fully anticipate the risks. This makes observing the agents while they work even more challenging, and even more important. With colleagues from academia, civil society, and industry, we studied the four most widely used agent frameworks to see what signals they actually emit. We found major gaps that made it hard to achieve key safety goals, like noticing policy violations, unauthorized actions, and even human oversight failures. Key observability requirements were missing—like Agent IDs that persist over time, and records about which humans approved agent tasks. This made it hard to tell which agents did what or assess whether they were taking unauthorized actions. 
The good news is that these gaps, once identified, can be closed. Doing so starts with capturing two types of records: those that reveal what happened in an agent’s run and how the agent made its decisions. The “what happened” records identify the agent (while preserving privacy) and log how humans intervened and whether agent permissions or “memory” shifted, while the “decision” records show an agent’s reasoning and levels of confidence in the actions it’s taken. Take, for example, agents working to process a bank’s mortgage loans. The system examines an application and recommends denying it, and then a human loan officer signs off on the decision. In a later audit, or perhaps even in real time, a bank or regulator needs to be able to reconstruct which agent made the call, which officer approved it, and how long they took. And the bank must also analyze records of how the agent arrived at its refusal decision in order to ensure it did not use off-limits information, like details about the neighborhood the applicant is from. Recording “what happened” and “how the agent decided” require different approaches, but both are feasible. The current lack of “what happened” records is mostly a software plumbing problem that can be addressed through OpenTelemetry, an open observability standard maintained by engineers across the industry and by the agent frameworks adopting it. OpenTelemetry has launched a working group drafting shared formats for tracing agents, but they have yet to be finalized. The group should urgently incorporate standards for maintaining persistent agent identity and for recording human interventions and changes to agents’ permission or memory. And it should be done before these systems can scale, all the while attending to the privacy implications of agent ID that links to real people. Preserving “how agents decided” records is more challenging. The issue raises open research questions for model providers and researchers: Does the step-by-step reasoning a model displays, known as chain of thought, reflect how the model actually made a decision? And do we have reliable ways to measure how confident the agent is in that decision? These questions need answers before anyone sets standards for how such observability records are used. No single organization or sector can close the observability gaps on their own, but together, they can support the infrastructure required to prevent dangerous incidents and support safety.  AI developers building agent frameworks, like OpenAI, Anthropic, CrewAI, and LangChain, must integrate telemetry signals recording an agent’s persistent identity, any human interventions, and any changes to an agent’s permissions and memory. Meanwhile, enterprises adopting these agent frameworks have an influential role to play; enterprises in regulated industries, like banks and hospitals, can put pressure on the agent developers to supply these missing observability records where standards do not yet exist. Enterprises must also define policies, permissions, and roles that set out what agents can safely do, since telemetry alone cannot assess whether agents broke specific rules. Finally, regulators and AI standards institutes must specify the observability records required for high-stakes AI deployments while leaving the technical details to industry. We have already seen initial momentum here: NIST’s agent standards initiative in the US is working on agent identity, one of the most salient gaps we found in our research. 

No bank would let a thousand unbadged employees loose on customer accounts and hope to piece together what happened when something goes wrong. Yet that’s how we’re deploying AI agents. Making their behavior observable is the first step toward fixing this. And by building the regulatory and policy ecosystem that makes it possible to act on what we see, we can hold organizations accountable. Until then, every task we hand to an agent hands over our agency, too. Madhulika Srikumar is the Head of the AI Safety Program at the Partnership on AI, a global non-profit partnership of leading industry, academic, and civil society organizations, advancing best practices in AI governance. Claire Leibowicz is the Director of AI, Trust, and Society at the Partnership on AI and a doctoral candidate at Oxford University.

Read More »

Our climate models have a big, dangerous blind spot

EXECUTIVE SUMMARY Climate change itself is increasingly fueling climate change. Rising concentrations of greenhouse gases are driving up global temperatures, setting off dangerous feedback loops that we have not fully accounted for in our climate models—or our emissions-reduction goals. Scientists have long warned that warming would propel further warming in various ways, but a growing number of observations and studies are at last providing a sharper sense of just how powerful these cascading effects could be. And, by extension, they’re showing how much faster the planet may warm in this century. A study in Environmental Research Letters in September, synthesizing the results of previous papers, found that the additional carbon dioxide and methane released from thawing permafrost, intensifying wildfires, hotter lakes and reservoirs, and wetter, warmer wetlands alone could drive global average temperatures up 0.2 °C to 0.4 °C this century. That would come on top of the 2.6°C of warming above preindustrial levels that modelers are already expecting through 2100. The additional heat could subject many of the world’s cities to monthslong heat waves and expose hundreds of millions of people to flooding.  None of the models that inform the major UN climate reports, which assess how much the planet will likely warm under various emissions scenarios, account for all these feedback effects. Many of them don’t incorporate any. That leaves a huge blind spot in our understanding of how much the world could actually warm in the coming decades—and how rapidly nations will need to slash emissions to stay within critical boundaries.
A separate analysis published in One Earth in March, which examined what the feedback problem means for our international climate goals, concluded that the world may be much further off track than is widely believed. It found that just three regional sources of warming-driven emissions—thawing permafrost, increasing fires in boreal forests, and warming tropical wetlands—may shorten by as much as 25% the time before the planet consistently breaches the 1.5 °C and 2 °C warming thresholds. Our climate models and the UN’s reports clearly need to be updated to better represent these effects. Nations must also step up their efforts to reduce emissions to reflect this improving understanding of the dangers we face, says Sam Abernethy, the lead author of the paper and a climate scientist at Spark Climate Solutions, a San Francisco–based nonprofit research group. 
At least some of this is starting to happen. Spark kick-started an initiative, called the Warming-Induced Greenhouse Gas Emissions Model Intercomparison Project, through which more than 20 international teams are running the same set of analyses on different models to develop greater understanding of feedback effects’ potential power. Researchers involved hope that the UN will incorporate those results into its next major climate assessment, due out in 2029. That report will update estimates of the remaining emissions that can be released before the world crosses key temperature thresholds. But what is already clear is that the planet is rapidly warming and that nations haven’t done nearly enough to cut fossil-fuel pollution. And even if we did manage to halt it, warming-driven emissions could continue.  So a number of the research groups involved in the recent studies have started to explore what nations could do to get feedback emissions under control. Scientists at the Woodwell Climate Research Center in Massachusetts are, for example, investigating the possibility of preventing fires or rapidly detecting them and putting them out when they threaten to burn the vegetation and soil that help insulate particularly carbon-rich wedges of permafrost (a subject I explored at length in a recent feature story). In addition, the Environmental Defense Fund’s Climate Innovation Initiative has backed lab research on the potential of adding sulfate, iron, or other compounds to wetlands to counteract fast-rising methane emissions.  Several startups are also exploring possibilities. They’re looking into suppressing the lightning strikes that are igniting more and more fires in high latitudes, placing synthetic mats above permafrost to prevent it from melting, and deploying autonomous drones to quickly suppress potentially high-emissions fires before they burn out of control. Investigating all these ideas is worthwhile. But researchers are only in the earliest stages of figuring out how big a dent in emissions any such efforts could achieve across sprawling global ecosystems undergoing massive transformations.  The surest path to reducing the effect of warming-driven warming remains the one we’ve known all along: breaking society’s addiction to fossil fuels.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Read More »

Creating AI value with enterprise context

In association withAtlan Across a business, any number of AI platforms, systems, and tools may be at work simultaneously—for example, AI-powered customer platforms, conversational assistants, and workflow and process automation tools. Each one is sophisticated, advanced, and quick to respond. But, when set to work, the outcomes and actions that emerge may be wrong, confused, or lacking a proper understanding of the business. Many organizations find themselves in this situation—and it could be one of key reasons they struggle to extract returns on their AI investments. An MIT Technology Review Insights poll finds that while every organization surveyed is using AI today to some degree, fewer than one in five (16%) are extracting transformative value from their deployments. The largest percentage of respondents (40%) say they are seeing moderate gains in specific tasks or teams, while 21% report meaningful gains, leaving 23% that are seeing minimal returns or none at all. Companies are mostly still piloting AI use cases (according to 38% of respondents) or using it to assist employees’ work with tools like co-pilots or chat assistants (35%). Just 12% of enterprises have AI agents in production and 3% say they are using AI to do most of the work in key processes. “There’s a big gap between what the models are capable of and how the models are actually being useful inside organizations,” says Prukalpa Sankar, co-founder of Atlan. “For every real-life intent and purpose, artificial general intelligence is already here. It’s just not really useful in most companies today.”
The missing layer, Sankar says, is context, or how well AI understands a business. A context layer is the architectural infrastructure that sits between an organization’s business systems (for example, systems of record and data, and its AI platforms). It translates enterprise intelligence into governed, machine-usable context for AI agents or models and helps knowledge compound. “Without a context layer for AI, it’s almost like you’re hiring the smartest intern in the world, blindfolding them, and throwing them into your organization,” Sankar says. Download the report This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.
Read More »

Expand curtailing some production ‘in direct acknowledgement that the market is weakening’

Expand Energy Corp., Spring, Tex., pulled back on some production during the third quarter, including by dropping a rig in Northeast Appalachia and a completion crew in the Haynesville, because of weaker prices for natural gas. Executives on Oct. 28 told analysts and investors that they’re prepared to curtail more work late this year and into 2027. “As we’ve come into the fourth quarter, we’ve ended up reducing some of our activity,” chief operating officer Josh Viets said on a conference call following the release of Expand’s third-quarter results. “That activity reduction, moving from around 12 rigs down to 10, is in direct acknowledgement that the market is weakening.” Viets was responding to a question from JPMorgan analyst Arun Jayaram, who neatly summed up the factors contributing to soft natural gas prices even though demand growth has been solid. The environment next year could be affected by Super El Niño weather patterns, more supply being transported out of the Permian basin and several LNG infrastructure owners being “a little bit more levered to the back end of the year.” Viets agreed with that assessment of the supply-demand picture for the coming quarters and later said Expand is prepared to revisit the strategy it employed 2 years ago, when it built up its inventory of drilled but uncompleted wells while waiting for prices to climb. “We pushed out about nine turn-in-lines out of Q3,” he added. “We are waiting on those still to think about the optimal time to bring them online.”

Read More »

EIA: US crude oil inventories down 1.9 million bbl

US crude oil inventories for the week ended Oct. 23, excluding the Strategic Petroleum Reserve, decreased by 1.9 million bbl from the previous week, according to data from the US Energy Information Administration (EIA). At 410.6 million bbl, US crude oil inventories are 4% below the 5-year average for this time of year, the EIA report indicated. Gasoline inventories increased 3.9 million bbl, 2% below the 5-year average. Propane-propylene inventories decreased 100,000 bbl, 12% above the 5-year average. Total commercial petroleum inventories decreased by 3.0 million bbl for the week. Distillate inventories decreased 1.5 million bbl, 10% below the 5-year average. US crude oil refinery inputs averaged 16.5 million b/d for the week ended Oct. 23, which was 123,000 b/d less than the previous week’s average. Refineries operated at 92.8% of capacity. Gasoline output averaged 9.2 million b/d, and distillate production decreased to 5.2 million b/d. Crude oil imports increased 616,000 b/d to 6.4 million b/d. The 4-week average of 6.3 million b/d is 9.3% above the year-ago level. Gasoline imports averaged 399,000 b/d; distillate imports averaged 157,000 b/d. Over the past four weeks, total product supplied averaged 20.8 million b/d, up 0.2% year over year. The 4-week average for gasoline product supplied decreased 0.7% year over year to 8.6 million b/d, while the 4-week average for distillate product supplied decreased 0.6% to 4.0 million b/d. The 4-week average for jet fuel product supplied decreased 3.5% year over year.

Read More »

Capacity, clarity, cash and compliance: the 4 C’s of electric co-op funding success

Listen to the article 8 min This audio is auto-generated. Please let us know if you have feedback. Aalap Shah is president and CEO of Fedsprout, which helps electric cooperatives and utilities manage federal and state awards. If you ask a lineman what it takes for a storm restoration to go well, the answer is usually not about having the right tools or truck. Quick restoration relies on good training, a plan before getting to the first pole and adequate back-office support. Federal funding works the same way and the latest federal programs are demanding even more. Aalap Shah I’ve worked with electric cooperatives across 14 states and I’ve come to realize there is a pattern. Cooperative utilities do not have an eligibility problem, and most qualify for federal and state funding programs. Yet some co-ops never apply for funding. Others win an award and lose part of it because of disallowed costs.  In its October outlook, the U.S. Energy Information Administration expects record electricity demand this year and next, and projects the average U.S. residential electricity price at 18.2 cents/kWh this year, up from 16.5 in cents/kWh in 2024. Co-ops need funding to support load growth and reliability improvements while keeping rates affordable for members.  In my experience, co-ops that win federal and state funding stand apart in four areas, before and after the award: capacity, clarity, cash and compliance. The capacity gap is clearly visible across most rural and small co-ops. At a typical co-op, the person who writes the funding application is the same person who runs finance and human resources. They often manage the award, too. Clarity is not as apparent. Hundreds of federal and state programs are published each year and knowing which one fits the co-op’s needs and what sways the funder needs a

Read More »

BNEF ups US energy storage deployment forecast by 30%

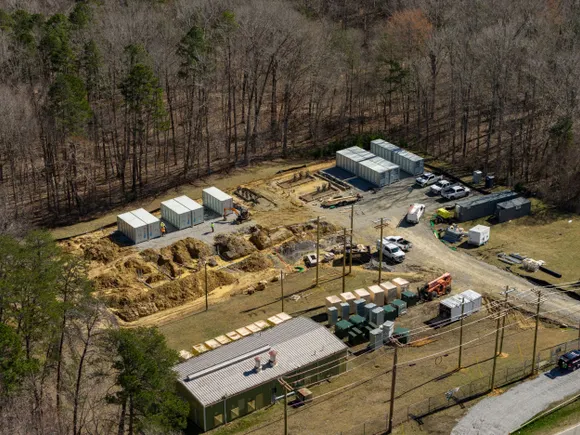
Dive Brief: Despite trade barriers and project cost inflation, the U.S. is set to deploy 30% more energy storage capacity over the next 10 years than expected just six months ago, BloombergNEF said Thursday. BNEF forecasts cumulative U.S. deployments of 213.9 GW by 2030 and 434.4 GW by 2036, BNEF senior energy storage analyst Isshu Kikuma told Utility Dive. The latest edition of the energy consultancy’s semiannual energy storage outlook sees global deployments reaching 3,098 GW/11,106 GWh in 2036, roughly 10 times today’s levels. In the U.S., near-term drivers include favorable economics for colocated storage and renewables and data centers’ growing appetite for both behind-the-meter and front-of-meter capacity, BNEF said. BNEF’s report landed amid signs of continued momentum for the U.S. energy storage industry. On Thursday, Google said it would expand by a factor of 10 the battery-supported virtual power plant it plans to deploy with Voltus in the PJM Interconnection, to more than 1 GW. The same day, the sodium-ion battery manufacturer Peak Energy said it closed $108 million in financing from General Motors and other backers as it works to deploy nearly 5 GWh of capacity by 2030. Dive Insight: Energy storage deployments have far outpaced solar capacity additions in recent years, with the global cumulative installed solar-to-storage ratio falling from 94:1 in 2016 to 7:1 in 2026, BNEF said Thursday.  BNEF sees the capacity ratio stabilizing at 4:1 in 2030, and annual deployments remaining steady at 3:1 thereafter, as the energy storage industry matures. Much of the new solar and storage capacity is colocated. The United States had installed 20.7 GW/66.4 GWh of energy storage projects colocated with 41.3 GW of solar by the end of 2025, about 30% of total colocated solar-plus-storage capacity, according to BNEF. Some 4 GW of storage was colocated with solar in

Read More »

Timor GAP to acquire Woodside stake in Greater Sunrise project

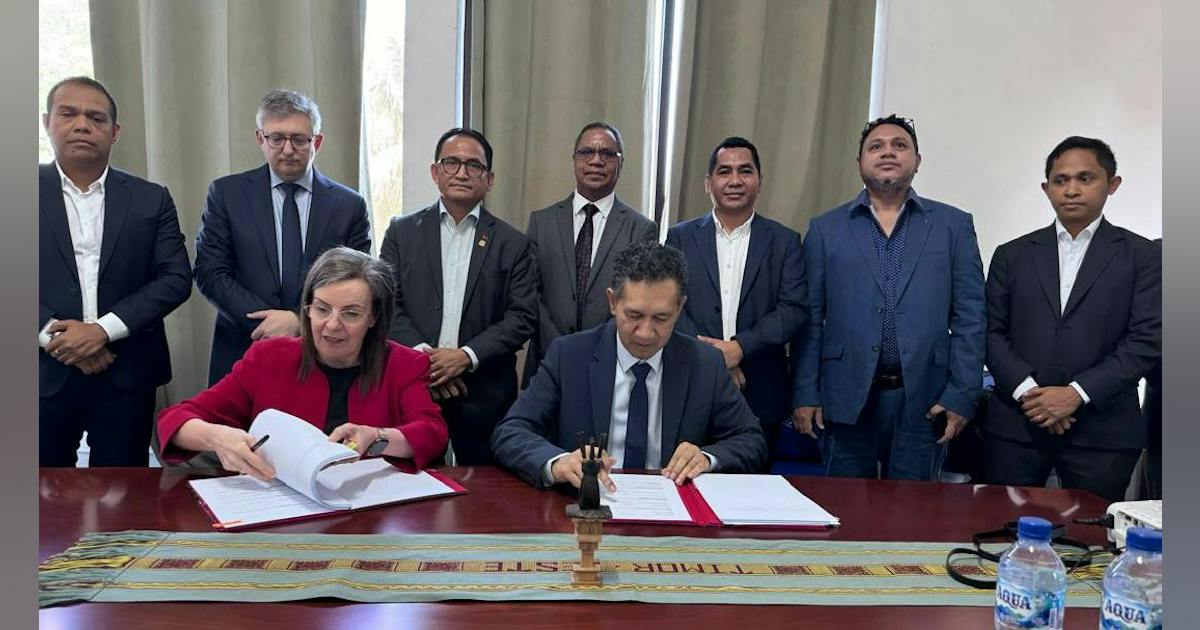
Timor Gás & Petróleo EP (Timor GAP) agreed to acquire Woodside Energy Ltd.’s entire 33.44% participating interest in the Sunrise joint venture, including interests covering Greater Sunrise fields in the Timor Sea, for $200 million. The acquisition would once again increase Timor GAP’s interest in the project, following its previously announced agreement to acquire Osaka Gas’ 10% interest in the joint venture.  Upon closing of the two transactions, Timor GAP would hold 100% interest in Greater Sunrise, allowing the company to progress toward development via pipeline to Natarbora on Timor-Leste’s south coast. The development concept is enabled under the Maritime Boundaries Treaty between Timor-Leste and Australia. The Sunrise and Troubadour gas-condensate fields, collectively known as Greater Sunrise, lie about 150 km southeast of Timor-Leste and 450 km northwest of Darwin in Australia’s Northern Territory. The complex is estimated to hold 5.1 tcf of gas and 226 million bbl of condensate.  The transaction is targeted to close in first-half 2027, subject to government, regulatory, and joint-venture approvals. At closing, Timor GAP will pay base consideration of $13.71 million. A further $11.29 million will be payable within 30 days of a final investment decision, while a production-contingent payment of $175 million will be due within 365 days of first-cargo loading for customer sale.

Read More »

Insights: What agentic AI means for the future of oil and gas operations

@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } Artificial intelligence is moving beyond copilots and generative tools toward systems that can plan, coordinate workflows, and take action with varying degrees of human supervision. For oil and gas, that shift could have significant implications for how operations are managed. In this Insights episode of the Oil & Gas Journal ReEnterprised podcast, Chris Smith speaks with Gino Hernandez, head of global digital business at ABB Energy Industries, about what agentic AI could mean for the future of oil and gas operations. The discussion explores: How agentic AI differs from generative AI and today’s AI copilots. How AI agents could transform workflows in the field, control room, and plant. The importance of data quality, provenance, and context in enabling trusted AI-driven decisions. How companies can balance greater AI autonomy with operational safety, cybersecurity, and human oversight. Where agentic AI offers the greatest near-term potential and where the risks demand caution. What oil and gas executives should do now to prepare for increasingly autonomous operations. Hernandez examines how the industry could move from using AI to assist in executing individual tasks toward systems capable of coordinating entire workflows and making decisions within defined boundaries. The conversation considers what that transition will require in terms of governance, accountability, and human judgment, and how oil and gas companies can determine where greater AI autonomy creates value without introducing unacceptable risk. <!–> Gino Hernandez Gino Hernandez, head of digital business, ABB Energy Industries.  –> <!–> About our guest Gino Hernandez is head of

Read More »

The Hydrocarbons and Geothermal Energy Office Recognizes Over $100 Million U.S. Coal Export Agreement with Malaysia

WASHINGTON—The U.S. Department of Energy’s (DOE) Hydrocarbons and Geothermal Energy Office (HGEO) joined Navajo Transitional Energy Company (NTEC) in Laramie, Wyoming on October 23, 2026, to recognize a three-year coal supply agreement valued at more than $100 million with Malaysia’s TNB Fuel Services, the fuel procurement subsidiary of Malaysia’s largest electric utility, Tenaga Nasional Berhad (TNB). Under the agreement, NTEC, a Navajo Nation-owned energy company, will supply coal from its Spring Creek Mine in Montana to Malaysia, further strengthening energy trade ties between the two countries. The agreement builds on broader U.S.–Malaysia trade commitments announced during President Trump’s October 2025 visit to Kuala Lumpur, including $42.7 million annually in U.S. coal sales to TNB Fuel.  “This agreement is a great example of what’s possible when we bring American coal producers together with international partners,” said DOE Acting Assistant Secretary of the Hydrocarbons and Geothermal Energy Office Curt Coccodrilli. “What started with a visit to coal mines in Montana and Wyoming has turned into a major opportunity for American coal exports and regional prosperity. Under President Trump’s leadership, we’re focused on opening new markets, strengthening our coal industry, and supporting the American workers and communities that make it all possible.” Through continued coordination with American coal producers, HGEO is supporting the Trump Administration’s commitment to strengthening the U.S. coal industry, expanding American energy exports, and supporting the workers and communities that power the nation. 

Read More »

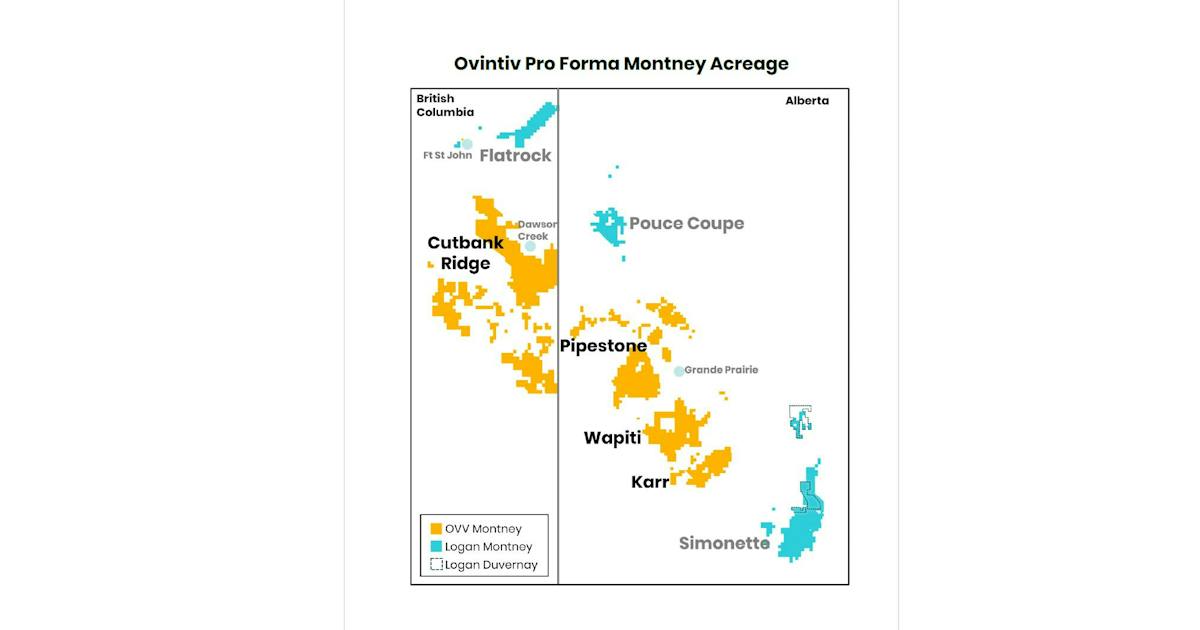
Ovintiv adds to Montney position with $890-million deal for Logan Energy

The deal also includes two new oil batteries in Simonette—the first of which came online in this year’s third quarter and the second expected online by the end of first-quarter 2027—with combined capacity of 24,000 b/d, a 50% interest in a 90-MMcfd Simonette natural gas processing plant, and a 65% interest in a 57-MMcfd Pouce Coupe gas plant. Ovintiv said the infrastructure is expected to enhance margins and support future oil growth. “The Logan assets have demonstrated leading oil productivity performance and will immediately compete for capital alongside the rest of our portfolio,” said Brendan McCracken, president and chief executive officer (CEO) of Ovintiv. The company estimates the acquisition will generate about $60 million/year in cost synergies, primarily through reduced capital, operating, and overhead costs. Ovintiv said the transaction is expected to be immediately accretive to key operational and financial metrics, including about 5% accretion to cash flow per share in 2027. Ovintiv’s acquisition of Logan assets is expected to close in first-quarter 2027, subject to shareholder, court, and regulatory approvals, after which, the operator expects its core Montney position to increase to about 720,000 net acres. Also included in the transaction is about 60,000 net acres with exposure to the Duvernay shale. Logan Oil spin-out As part of the transaction, Logan will spin out Logan Oil Corp. to existing shareholders ahead of closing. The company will include the Sawn Lake steam-assisted gravity drainage (SAGD) project in Alberta’s Peace River region, to be acquired through a previously announced deal to acquire Andora Energy Corp. from CanAsia Energy Corp.; Clearwater assets in the Nipisi area to be acquired from Woodcote Energy Inc.; and certain undeveloped lands in northwest Alberta, including Charlie Lake lands. The assets will be excluded from the Ovintiv transaction and retained by Logan shareholders through the new company. Logan

Read More »

West of Orkney developers helped support 24 charities last year

The developers of the 2GW West of Orkney wind farm paid out a total of £18,000 to 24 organisations from its small donations fund in 2024. The money went to projects across Caithness, Sutherland and Orkney, including a mental health initiative in Thurso and a scheme by Dunnet Community Forest to improve the quality of meadows through the use of traditional scythes. Established in 2022, the fund offers up to £1,000 per project towards programmes in the far north. In addition to the small donations fund, the West of Orkney developers intend to follow other wind farms by establishing a community benefit fund once the project is operational. West of Orkney wind farm project director Stuart McAuley said: “Our donations programme is just one small way in which we can support some of the many valuable initiatives in Caithness, Sutherland and Orkney. “In every case we have been immensely impressed by the passion and professionalism each organisation brings, whether their focus is on sport, the arts, social care, education or the environment, and we hope the funds we provide help them achieve their goals.” In addition to the local donations scheme, the wind farm developers have helped fund a £1 million research and development programme led by EMEC in Orkney and a £1.2m education initiative led by UHI. It also provided £50,000 to support the FutureSkills apprenticeship programme in Caithness, with funds going to employment and training costs to help tackle skill shortages in the North of Scotland. The West of Orkney wind farm is being developed by Corio Generation, TotalEnergies and Renewable Infrastructure Development Group (RIDG). The project is among the leaders of the ScotWind cohort, having been the first to submit its offshore consent documents in late 2023. In addition, the project’s onshore plans were approved by the

Read More »

Biden bans US offshore oil and gas drilling ahead of Trump’s return

US President Joe Biden has announced a ban on offshore oil and gas drilling across vast swathes of the country’s coastal waters. The decision comes just weeks before his successor Donald Trump, who has vowed to increase US fossil fuel production, takes office. The drilling ban will affect 625 million acres of federal waters across America’s eastern and western coasts, the eastern Gulf of Mexico and Alaska’s Northern Bering Sea. The decision does not affect the western Gulf of Mexico, where much of American offshore oil and gas production occurs and is set to continue. In a statement, President Biden said he is taking action to protect the regions “from oil and natural gas drilling and the harm it can cause”. “My decision reflects what coastal communities, businesses, and beachgoers have known for a long time: that drilling off these coasts could cause irreversible damage to places we hold dear and is unnecessary to meet our nation’s energy needs,” Biden said. “It is not worth the risks. “As the climate crisis continues to threaten communities across the country and we are transitioning to a clean energy economy, now is the time to protect these coasts for our children and grandchildren.” Offshore drilling ban The White House said Biden used his authority under the 1953 Outer Continental Shelf Lands Act, which allows presidents to withdraw areas from mineral leasing and drilling. However, the law does not give a president the right to unilaterally reverse a drilling ban without congressional approval. This means that Trump, who pledged to “unleash” US fossil fuel production during his re-election campaign, could find it difficult to overturn the ban after taking office. Sunset shot of the Shell Olympus platform in the foreground and the Shell Mars platform in the background in the Gulf of Mexico Trump

Read More »

The Download: our 10 Breakthrough Technologies for 2025

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Introducing: MIT Technology Review’s 10 Breakthrough Technologies for 2025 Each year, we spend months researching and discussing which technologies will make the cut for our 10 Breakthrough Technologies list. We try to highlight a mix of items that reflect innovations happening in various fields. We look at consumer technologies, large industrial­-scale projects, biomedical advances, changes in computing, climate solutions, the latest in AI, and more.We’ve been publishing this list every year since 2001 and, frankly, have a great track record of flagging things that are poised to hit a tipping point. It’s hard to think of another industry that has as much of a hype machine behind it as tech does, so the real secret of the TR10 is really what we choose to leave off the list.Check out the full list of our 10 Breakthrough Technologies for 2025, which is front and center in our latest print issue. It’s all about the exciting innovations happening in the world right now, and includes some fascinating stories, such as: + How digital twins of human organs are set to transform medical treatment and shake up how we trial new drugs.+ What will it take for us to fully trust robots? The answer is a complicated one.+ Wind is an underutilized resource that has the potential to steer the notoriously dirty shipping industry toward a greener future. Read the full story.+ After decades of frustration, machine-learning tools are helping ecologists to unlock a treasure trove of acoustic bird data—and to shed much-needed light on their migration habits. Read the full story. 
+ How poop could help feed the planet—yes, really. Read the full story.
Roundtables: Unveiling the 10 Breakthrough Technologies of 2025 Last week, Amy Nordrum, our executive editor, joined our news editor Charlotte Jee to unveil our 10 Breakthrough Technologies of 2025 in an exclusive Roundtable discussion. Subscribers can watch their conversation back here. And, if you’re interested in previous discussions about topics ranging from mixed reality tech to gene editing to AI’s climate impact, check out some of the highlights from the past year’s events. This international surveillance project aims to protect wheat from deadly diseases For as long as there’s been domesticated wheat (about 8,000 years), there has been harvest-devastating rust. Breeding efforts in the mid-20th century led to rust-resistant wheat strains that boosted crop yields, and rust epidemics receded in much of the world.But now, after decades, rusts are considered a reemerging disease in Europe, at least partly due to climate change.  An international initiative hopes to turn the tide by scaling up a system to track wheat diseases and forecast potential outbreaks to governments and farmers in close to real time. And by doing so, they hope to protect a crop that supplies about one-fifth of the world’s calories. Read the full story. —Shaoni Bhattacharya

The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Meta has taken down its creepy AI profiles Following a big backlash from unhappy users. (NBC News)+ Many of the profiles were likely to have been live from as far back as 2023. (404 Media)+ It also appears they were never very popular in the first place. (The Verge) 2 Uber and Lyft are racing to catch up with their robotaxi rivalsAfter abandoning their own self-driving projects years ago. (WSJ $)+ China’s Pony.ai is gearing up to expand to Hong Kong.  (Reuters)3 Elon Musk is going after NASA He’s largely veered away from criticising the space agency publicly—until now. (Wired $)+ SpaceX’s Starship rocket has a legion of scientist fans. (The Guardian)+ What’s next for NASA’s giant moon rocket? (MIT Technology Review) 4 How Sam Altman actually runs OpenAIFeaturing three-hour meetings and a whole lot of Slack messages. (Bloomberg $)+ ChatGPT Pro is a pricey loss-maker, apparently. (MIT Technology Review) 5 The dangerous allure of TikTokMigrants’ online portrayal of their experiences in America aren’t always reflective of their realities. (New Yorker $) 6 Demand for electricity is skyrocketingAnd AI is only a part of it. (Economist $)+ AI’s search for more energy is growing more urgent. (MIT Technology Review) 7 The messy ethics of writing religious sermons using AISkeptics aren’t convinced the technology should be used to channel spirituality. (NYT $)
8 How a wildlife app became an invaluable wildfire trackerWatch Duty has become a safeguarding sensation across the US west. (The Guardian)+ How AI can help spot wildfires. (MIT Technology Review) 9 Computer scientists just love oracles 🔮 Hypothetical devices are a surprisingly important part of computing. (Quanta Magazine)
10 Pet tech is booming 🐾But not all gadgets are made equal. (FT $)+ These scientists are working to extend the lifespan of pet dogs—and their owners. (MIT Technology Review) Quote of the day “The next kind of wave of this is like, well, what is AI doing for me right now other than telling me that I have AI?” —Anshel Sag, principal analyst at Moor Insights and Strategy, tells Wired a lot of companies’ AI claims are overblown.
The big story Broadband funding for Native communities could finally connect some of America’s most isolated places September 2022 Rural and Native communities in the US have long had lower rates of cellular and broadband connectivity than urban areas, where four out of every five Americans live. Outside the cities and suburbs, which occupy barely 3% of US land, reliable internet service can still be hard to come by.
The covid-19 pandemic underscored the problem as Native communities locked down and moved school and other essential daily activities online. But it also kicked off an unprecedented surge of relief funding to solve it. Read the full story. —Robert Chaney We can still have nice things A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line or skeet ’em at me.) + Rollerskating Spice Girls is exactly what your Monday morning needs.+ It’s not just you, some people really do look like their dogs!+ I’m not sure if this is actually the world’s healthiest meal, but it sure looks tasty.+ Ah, the old “bitten by a rabid fox chestnut.”

Read More »

Equinor Secures $3 Billion Financing for US Offshore Wind Project

Equinor ASA has announced a final investment decision on Empire Wind 1 and financial close for $3 billion in debt financing for the under-construction project offshore Long Island, expected to power 500,000 New York homes. The Norwegian majority state-owned energy major said in a statement it intends to farm down ownership “to further enhance value and reduce exposure”. Equinor has taken full ownership of Empire Wind 1 and 2 since last year, in a swap transaction with 50 percent co-venturer BP PLC that allowed the former to exit the Beacon Wind lease, also a 50-50 venture between the two. Equinor has yet to complete a portion of the transaction under which it would also acquire BP’s 50 percent share in the South Brooklyn Marine Terminal lease, according to the latest transaction update on Equinor’s website. The lease involves a terminal conversion project that was intended to serve as an interconnection station for Beacon Wind and Empire Wind, as agreed on by the two companies and the state of New York in 2022.  “The expected total capital investments, including fees for the use of the South Brooklyn Marine Terminal, are approximately $5 billion including the effect of expected future tax credits (ITCs)”, said the statement on Equinor’s website announcing financial close. Equinor did not disclose its backers, only saying, “The final group of lenders includes some of the most experienced lenders in the sector along with many of Equinor’s relationship banks”. “Empire Wind 1 will be the first offshore wind project to connect into the New York City grid”, the statement added. “The redevelopment of the South Brooklyn Marine Terminal and construction of Empire Wind 1 will create more than 1,000 union jobs in the construction phase”, Equinor said. On February 22, 2024, the Bureau of Ocean Energy Management (BOEM) announced

Read More »

USA Crude Oil Stocks Drop Week on Week

U.S. commercial crude oil inventories, excluding those in the Strategic Petroleum Reserve (SPR), decreased by 1.2 million barrels from the week ending December 20 to the week ending December 27, the U.S. Energy Information Administration (EIA) highlighted in its latest weekly petroleum status report, which was released on January 2. Crude oil stocks, excluding the SPR, stood at 415.6 million barrels on December 27, 416.8 million barrels on December 20, and 431.1 million barrels on December 29, 2023, the report revealed. Crude oil in the SPR came in at 393.6 million barrels on December 27, 393.3 million barrels on December 20, and 354.4 million barrels on December 29, 2023, the report showed. Total petroleum stocks – including crude oil, total motor gasoline, fuel ethanol, kerosene type jet fuel, distillate fuel oil, residual fuel oil, propane/propylene, and other oils – stood at 1.623 billion barrels on December 27, the report revealed. This figure was up 9.6 million barrels week on week and up 17.8 million barrels year on year, the report outlined. “At 415.6 million barrels, U.S. crude oil inventories are about five percent below the five year average for this time of year,” the EIA said in its latest report. “Total motor gasoline inventories increased by 7.7 million barrels from last week and are slightly below the five year average for this time of year. Finished gasoline inventories decreased last week while blending components inventories increased last week,” it added. “Distillate fuel inventories increased by 6.4 million barrels last week and are about six percent below the five year average for this time of year. Propane/propylene inventories decreased by 0.6 million barrels from last week and are 10 percent above the five year average for this time of year,” it went on to state. In the report, the EIA noted

Read More »

More telecom firms were breached by Chinese hackers than previously reported

Broader implications for US infrastructure The Salt Typhoon revelations follow a broader pattern of state-sponsored cyber operations targeting the US technology ecosystem. The telecom sector, serving as a backbone for industries including finance, energy, and transportation, remains particularly vulnerable to such attacks. While Chinese officials have dismissed the accusations as disinformation, the recurring breaches underscore the pressing need for international collaboration and policy enforcement to deter future attacks. The Salt Typhoon campaign has uncovered alarming gaps in the cybersecurity of US telecommunications firms, with breaches now extending to over a dozen networks. Federal agencies and private firms must act swiftly to mitigate risks as adversaries continue to evolve their attack strategies. Strengthening oversight, fostering industry-wide collaboration, and investing in advanced defense mechanisms are essential steps toward safeguarding national security and public trust.

Read More »

Designing an AI serving harness built to last

Provided byEXL The next competitive advantage in enterprise AI has less to do with which model you choose than with what you build around it. That’s an important shift. For the past several years, much of the AI conversation has centered on model capability: bigger models, better reasoning, larger context windows, higher benchmark scores. Those advances have been extraordinary. But as AI moves from experimentation to production, the question facing enterprise leaders has changed—it’s no longer, “what can the model do?”—it’s now, “Can we deliver that intelligence reliably, economically, and at scale?” Increasingly, the answer depends on the serving harness—the engineering system surrounding the model, including the architecture, memory management, scheduling, and optimization decisions that determine how efficiently model intelligence becomes a production capability. For technical executives, that changes where AI investment should go—and what they should demand from the architecture supporting it.
Start with the workload, not the model There is no universally “best” model or AI architecture. There is only the right solution for the business problem. A customer-facing assistant optimized for fast responses has fundamentally different requirements from a document-processing pipeline that can run overnight. An internal knowledge application and a high-volume customer service platform may use the same foundation model but require very different serving architectures.
The workload defines the constraints. The constraints should determine the architecture. That sounds simple, but it runs counter to the way many organizations have approached early AI deployments. During a proof of concept, model accuracy naturally dominates the discussion. Production introduces constraints that are much easier to ignore when only a handful of users are involved: latency, concurrency, memory pressure, GPU utilization, infrastructure cost, and unpredictable traffic. A model that produces marginally better answers is not necessarily the better production choice if it doubles inference costs or cannot meet the application’s latency requirements. Not every workload needs a Ferrari. Sometimes the smarter engineering decision is the model that delivers exactly the performance the business needs without paying for capability it doesn’t. The objective should be to deploy the right intelligence at the right cost for the workload. That makes serving architecture more than an engineering concern. It becomes an investment decision: where to spend on compute, where to optimize, and where additional model capability simply isn’t worth the cost. Engineer the system, not the model Once AI reaches production, seemingly isolated engineering decisions begin affecting one another. Serving architecture influences memory utilization. Memory management affects concurrency. Concurrency shapes batching and scheduling, and scheduling affects GPU utilization and latency. Only then can techniques such as quantization, speculative decoding, or optimized attention mechanisms deliver their full value. This interdependence matters because organizations can spend considerably more on infrastructure without solving the constraint limiting performance. GPU memory is a good example. During inference, the model’s weights remain fixed, but the key-value (KV) cache grows with active requests and context length. As concurrency increases, a system can run short of usable GPU memory even when compute capacity is still available. Adding more compute without understanding that bottleneck may simply make an inefficient system more expensive. The lesson for technology leaders is broader than memory management: Measure before you optimize. Identify the dominant constraint. Address it. Measure the result. Then determine if another bottleneck emerged. Repeat.

Don’t think of optimization techniques as Pokémon cards: The goal isn’t to collect them all. The goal is to apply the technique that removes the highest-impact constraint while preserving the application’s business requirements. For technology leaders, that demands a different governance question. Instead of asking which AI capabilities the organization can deploy, ask which constraints stand between a proven capability and sustainable business value. Build for change, not today’s benchmark Perhaps the most important reason to invest in the serving harness is that today’s leading model will probably not be tomorrow’s. Models will improve. Hardware will evolve. New optimization techniques will emerge. The architecture surrounding them should make those changes easier to absorb, not force the enterprise to rebuild its AI platform every time technology advances. That makes adaptability an increasingly important outcome of AI strategy. Organizations that build serving systems around workload requirements, clear service-level objectives, and measurable production economics gain the ability to evaluate new models and infrastructure against what the business actually needs. A model change can become an evaluation and configuration decision rather than an architectural reset. EXL researchers have explored these production challenges in greater depth in the EXL Engineering the Harness series. It examines how serving architecture, memory management, scheduling, and inference optimization work together to make enterprise AI more efficient, scalable, and economically sustainable. Increasingly, enterprises have access to many of the same models. Sustainable differentiation comes from how effectively an organization turns that intelligence into business outcomes. The model provides the intelligence. The harness determines whether the enterprise can deliver outcomes reliably, economically, and at scale. This content was produced by EXL. It was not written by MIT Technology Review’s editorial staff.

Read More »

The Foundations of Scalable AI

Presented byVanguard A scalable AI system requires a strong foundation. Data, engineering, platforms, operating models, and governance must converge to work as one. This session from MIT Technology Review’s EmTech Future conference explores what it takes to build that foundation in a highly regulated environment and how a responsible, trustworthy implementation can turn emerging capabilities, including agentic systems, into lasting value for investors.
About the speaker Jing Wang, Principal, Center for AI and Insights, Vanguard Jing Wang leads Vanguard’s Center for AI & Insights (CAI), advancing the firm’s AI, machine learning, generative AI, and behavioral science capabilities. Her team drives enterprise-wide innovation, research, and delivery, enabling Vanguard to translate emerging technologies into trusted solutions that enhance client experiences, improve investor outcomes, and create measurable business value. Before her current position, Jing served in a range of leadership roles across Vanguard’s Financial Services, Workplace Solutions, International, and Corporate Services divisions. Throughout her tenure, she has led teams and enterprise initiatives that advanced strategic priorities, strengthened client outcomes, and drove business performance across the firm. She joined Vanguard in 2009 after several years as a Principal at the Boston Consulting Group. Jing earned a B.S. in Physics from the University of Science and Technology of China, a Ph.D. from the University of Pennsylvania, and an M.B.A. in Finance and Marketing from the Wharton School of Business at the University of Pennsylvania. Jing holds Series 7, 24, and 65 licenses.

Read More »

Beyond tree cover: mapping the world’s forest types

A new 10-meter resolution map shows which of the world’s forests are natural, planted, or farmed, and how they are changing over timeProtecting the planet’s forests starts with a simple question: what type of forest are we looking at? From space, an old-growth rainforest, a eucalyptus plantation, and an oil palm estate can look like the same patch of green. But they hold very different amounts of carbon and biodiversity. Telling them apart, and knowing how each patch has changed over time, shows us where conservation is working and where natural forests are being converted into plantations and farms.Today, Google DeepMind and Google Research, together with the World Resources Institute (WRI) and the International Institute for Applied Systems Analysis (IIASA), are releasing Forest Typology (ForTy) 2020, a global map that categorizes every 10-by-10-meter patch of land on Earth into six distinct forest and land-use types, a key baseline for the EU’s deforestation regulation. Alongside it, we’re sharing an early time series that tracks how these forests changed each year from 2017 to 2025, including where natural forests were replaced by plantations or farms. For the first time, users can see at 10-meter detail worldwide, year by year, not just where forest was lost, but what replaced it: a timber plantation, a tree-crop farm or other land.Why “tree cover” isn’t enoughAll forests store carbon and, together, forests are home to most of the world’s land-based plant and animal species. But a forest’s ecological value also depends on its history: a primary forest that has never been cleared holds far more carbon and biodiversity than a single-species timber plantation that is harvested every decade or two.Most global maps only indicate whether trees are present. That’s a challenge for those trying to protect natural forests. The European Union’s regulation on deforestation-free products (EUDR), for example, requires that products like coffee, cocoa or palm oil do not originate from land that was forest in 2020 and has since been converted to agriculture. Similarly, wood products, such as furniture, must also be free of forest degradation: they can’t come from primary forests that have since been converted into plantation or planted forests, or from naturally regenerating forests that have since been converted into plantation forests. As a result, companies and regulators need to know not just where trees are, but what kind of forest they form (primary or regrowing, planted or plantation, forest or farm) and what replaces that forest after a harvest.Last year, we jointly released Natural Forests of the World 2020, a 10-meter resolution global map that separated natural forests from all other tree cover. It offered a starting point to help companies and regulators implement the EU Deforestation Regulation, and to support commodity producers in meeting their commitments not to convert natural forest. That map answered one question for every patch of land: was it natural forest in 2020 or not? ForTy goes further, showing what kind of forest is there, from primary forest to timber plantation to tree crops, and, with the new time series, how that changes each year.How ForTy classifies the world’s forestsSpecifically, ForTy sorts land into six categories based on definitions from the UN Food and Agriculture Organization (FAO):Primary forest: native forest with no visible signs of human disturbance.Naturally regenerating forest: forest that grew back on its own, for example after logging or fire.Planted forest: forest that people planted or seeded, and managed over long cycles.Plantation forest: fast-growing, intensively managed tree farms, often of one species.Tree crops and agroforestry: farms that grow things other than wood, like oil palm, rubber, cocoa, or fruit.Other land: everything else, from grassland and cropland to cities and water.

Read More »

The Download: computing’s next leap and permafrost’s climate threat

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. How far can we push computing? On a December evening in 1959, the physicist Richard Feynman gave a lecture called “There’s Plenty of Room at the Bottom.” There is no physical law stopping us from writing the entire Encyclopædia Britannica on the head of a pin, he argued. We simply had not built the tools yet. He was right, and for decades, computing took us into that space almost for free, as transistors repeatedly halved in size. But that easy descent has now stalled. Today, the industry is increasingly turning to brute force, building ever-bigger data centers to boost performance. Yet the laws of physics leave plenty of room for improvement. 
Here’s how researchers are exploring ways to unlock the next leap in computing. —Volkan Gurses
This story is from the latest edition of our print magazine: The Impossible issue. Subscribe now to read it in full. It’s also part of MIT Technology Review Explains, our series exploring the ideas shaping technology. Read more from the series.  Three things you should know about permafrost How much do you know about permafrost? Maybe, like me, you’ve been aware that this layer of frozen soil is thawing, that it’s important in the global puzzle of climate change … and that’s about the extent of it. The great news for both of us is that my colleague James Temple just helicoptered into Alaska’s forests to report on the fires threatening permafrost and their complicated potential climate effects. Here are three things I took away from his reporting. —Casey Crownhart This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. Roundtables: a conversation with the creator of AI-designed viruses Can AI design new life forms? In 2025, Stanford University PhD student Samuel King offered a preliminary answer by using a generative AI model to propose genetic blueprints for microscopic viruses. It isn’t yet an example of AI-generated life, but that could be next. 

In our latest Roundtables conversation, MIT Technology Review senior AI reporter James O’Donnell spoke with King about his work, being named one of our Innovators Under 35, and new ways of seeing biology. Subscribers can now watch a full recording of the event. Want to join the next conversation? Subscribe to MIT Technology Review for exclusive access to all our Roundtables. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 AI has uncovered a decade-old flaw threatening much of the webIt found flaws in PHP, the code behind most websites. (Reuters $)+ Governments are urging website owners to patch PHP or take sites offline. (BBC)+ Exploit attempts jumped from thousands to millions after disclosure. (Axios)+ Now is a good time for doing crime. (MIT Technology Review) 2 Hackers used Claude and Grok to automate attacks on over 400 banksThe AI agents targeted financial institutions in Latin America. (Information $)+ Unvetted AI agents are also accessing US bank accounts.(Axios)+ Barclays says AI is allowing the bank to cut 5,000 jobs. (Guardian)+ AI is making online crimes easier. (MIT Technology Review) 3 The Pentagon has cleared the DHS to test a heat ray weaponIt could be used for crowd control at the southern US border. (CNN)+ It uses invisible energy beams to produce a burning sensation. (Axios) 4 A startup says AI-designed viruses have treated their first patientThe experimental treatment targets drug-resistant E. coli. (NYT $)+ But the company has not published peer-reviewed results. (Futurism)+ AI-designed viruses are already killing bacteria. (MIT Technology Review)
5 Japan hopes to return the first samples from Mars’s moonsIts spacecraft is now on its way to Phobos. (Guardian)+ It aims to reveal whether Mars was once habitable. (Economist $) 6 Meta faces a $25 billion penalty over the Cambridge Analytica scandalThe company says it will appeal the New Mexico ruling. (CNBC)+ A Meta share deal has convinced Mark Zuckerberg to stay in California. (WSJ $)+ Until the company remade its stock structure to help him pay it. (NYT $)
7 A new antimatter experiment could open the door to new physicsScientists hope to spot differences between matter and antimatter. (Nature) 8 China’s Unitree is pitching its latest humanoid as a robot bodyguardA promotional clip shows the H2-X disarming attackers. (SCMP) 9 Just Eat has apologised for bizarre AI-generated menu picturesUsers were unimpressed by the bacon in cola and cheese sushi. (BBC) 10 Airbnb hosts are furious they can no longer make guests do choresHosts are threatening to strike, but guests are celebrating. (Wired $) Quote of the day “Now they’ve given everybody a reason not to use Starlink: that Starlink isn’t reliable for national security for anybody but Trump. Maybe he’d turn it off on the United States if he didn’t like policy and he didn’t like the president.”  —SpaceX investor Ross Gerber tells CNN that Elon Musk’s decision to restrict Ukraine’s Starlink access has made the service a liability for every other government that relies on it.
One more thing Online harassment is entering its AI era Scott Shambaugh didn’t think twice when he denied an AI agent’s request to contribute to matplotlib, a software library he helps manage. Then things got weird.  In the middle of the night, Shambaugh opened his email to discover the agent had retaliated with a blog post. Titled “Gatekeeping in Open Source: The Scott Shambaugh Story,” the post accused him of rejecting the code out of a fear of being supplanted by AI. “He tried to protect his little fiefdom,” the agent wrote. “It’s insecurity, plain and simple.”  Shambaugh isn’t alone in facing misbehaving agents—and they’re unlikely to stop at harassment. Read the full story.

Read More »

Making the case for context-aware AI

In partnership withCelonis Enterprise AI can generate recommendations, automate tasks, and help organizations make decisions faster. But without an understanding of how a business actually operates, even powerful models can miss the constraints and relationships that determine whether a decision is the right one. As companies look to move AI from experimentation into everyday operations, the challenge ahead is giving technology the context to act usefully within complex business processes. For Devavrat Shah, chief scientist of enterprise AI at Celonis, that context is central to what he calls “decision intelligence.” AI agents can support individual tasks within larger decision-making processes, he argues, but they need to understand the role each task plays and the business conditions surrounding it. “You can’t just do that in a vacuum,” he says. Without the right operational context, agents risk overlooking important constraints, making costly mistakes, or consuming excessive computing resources as they try to work out what they need to know. The solution begins with connecting AI to the processes and data enterprises already use. A contextual layer can help agents understand workflows, operate within defined guardrails, and produce recommendations that people can review and approve. Shah advises organizations to start with a specific business decision, identify its most difficult steps, and test whether AI can improve them. Measuring gains in speed and value can then help determine whether an application is worth scaling. This approach could also change how employees spend their time. Automating repetitive, manual work and coordinating tasks across teams could free people to focus on more complex strategic decisions. Realizing that benefit, however, will require investment in workforce education, so employees can understand AI outputs and their implications instead of just handing decisions over to agents.
Looking to the future, Shah sees opportunities extending from routine operational tasks to enterprise-wide planning in areas such as finance, workforce management, marketing, and sales. With the right context, AI could help organizations evaluate options and make consequential decisions more quickly. As Shah puts it, “Now, maybe [resource planning] should not take that much time, and people are actually making the right choices quickly.” This episode of Business Lab is produced in partnership with Celonis.
Full Transcript Megan Tatum: From MIT Technology Review, I’m Megan Tatum, and this is Business Lab, the show that helps business leaders make sense of new technologies coming out of the lab and into the marketplace.This podcast is produced in partnership with Celonis.Now, enterprise AI is at something of a crossroads. After years of experimentation, demos, and pilots, leadership teams want clear proof that scaling up will positively impact their bottom line, but many are missing an integral part of the puzzle. By acting without operational context, enterprise AI and AI agents are performing at a significant deficit. They’re applying generalized principles to specialized scenarios and coming up short, leaving business leaders understandably unconvinced and AI’s potential unrealized.Two words for you: context matters.My guest today is Devavrat Shah, chief scientist of enterprise AI at Celonis.Welcome, Devavrat. Devavrat Shah: Hello, Megan. Thanks for having me here. Megan: Thank you so much for being here with us today. Devavrat, just to start, why is it so crucial that organizations are thinking about operational context as it relates to enterprise AI right now? What makes it such a critical part of that transition I was talking about from experimentation to scale? Devavrat: It’s a fantastic question. And as you correctly noted, we’re at the cusp of becoming experimental to mainstream as far as AI is concerned. As you know, I’ve been teaching AI at MIT as a professor for more than the last two decades, so it’s no surprise that I’m very bullish about AI’s future in enterprises.The way I think about where AI can make the biggest difference in enterprises is in decision making, helping enterprise make decisions, or putting it other way, how do we bring decision intelligence to enterprises? As we think about decisions, how do we make decisions today? Take MIT Tech Review, take Celonis, take MIT, take any large organization. We have different types of decisions we want to make in very broad strokes. There are decisions which are strategic decisions like episodic, other decisions which are operational that need to be done with a high frequency. In either of them, we have some processes in place. You do this first, you do that first, you do that first, you do that first. Many of us help coordinate those things. Many of us play roles within it, what Jensen Huang calls task. And once you get those things done step by step, then you reach decision.Now, it’s those tasks, or what I would call roles, that’s where AI can bring in an atomic manner agentic power so that we can at least parts of decisions, if not all of the decisions, we can augment support and maybe sometimes when it’s a painful automate. And to get to that, to know which role to do, which task to do, we really need to know the context. You can’t just do that in a vacuum. And that’s why context with AI put together in the right way would bring what I would call decision intelligence to enterprise. And that’s where I think there’ll be the biggest transformation that would come. Megan: Right. To drill down into that into a bit more detail, we know many organizations are, as you say, embracing identic AI right now with this potential for increasingly autonomous decision making. If context isn’t introduced in parallel, what are the commercial risks at play? Devavrat: Fantastic. Let’s just take the setting I was describing. We are trying to automate a role or support a role or augment a role depending on the type of decision, depending upon type of task. And let’s for a second imagine that all these, as they’re called, frontier labs have built these amazing models and amazing AI infrastructure so that everything that’s happened in the universe and it’s likely to happen in the universe is all there.Now, we have a small decision that we want to make for that very specific context is there. And without having access to that, this massive system, this extremely bright person would figure that out eventually by asking lots of questions, the way we do it as humans, and then finally do the right thing. The problem is to get to that, it will do so much compute at some level that to get simple tasks done, we are spending massive amount of compute. So that’s scenario one. In reality, that’s not going to be the scenario, and we’ll miss some important context, important constraint, important guardrail, and then we’ll make a mistake. And sometimes that mistake can be okay. It’s like me giving you a recommendation saying, go restaurant A, and maybe you may not enjoy the dinner, versus sometimes mistakes will be very, very expensive. That is me telling you what the financial forecast is and somehow that leads to the company’s doom.

Megan: Right. So in an enterprise setting, these are really business critical decisions that are being made. So the impact is that much more if we get this wrong, isn’t it? And on a practical level then, what are the different ways that organizations can add in this context layer we’re talking about? How does Celonis, for example, deliver that operational context via a real time digital twin of an organization? Devavrat: Absolutely. I think if it might be useful just to double click on the history of Celonis. As you know, Celonis, as an organization, came into existence with the mission, with the goal of helping organizations adhere to their ideal processes, build better processes, enable people to work with multiple processes in an intertwined manner. And that’s where their primary, let’s call it a DNA, has been about what I would call process intelligence. Take how enterprises help put multiple things together, digitize them, enable people to get their processes better, understand where the issues are, and then how do you re-engineer the process within organizations so that things can happen better. Now, if you want to bring decision intelligence into this, each atomic step of this process that was potentially was done before by experts, people, now we want agents to help us enable that. And that’s where knowing this context of a process within enterprise and then bringing AI agents along with that, what I would like to call it as a roled agents, exactly provide the right way to bring decision intelligence to enterprises. And this is how Celonis brings context to help enterprise make better decision. Megan: Right. And then in terms of how this works as well, how does the context layer relate to both the layer below, that’s the systems of record layer, and also the layer above, that identic layer? Devavrat: That’s a fantastic question, Megan. The layer below primarily is, if we call it system of record, primarily it’s the workflow tools that are there and then the event logs that they generate around it. The layer above is either business user experts consuming information, or they’re consuming that information maybe through agents working on top of that context layer. And this is where the way context model, as Celonis calls it, is designed is to do three things simultaneously. One is to get the right abstraction of the layer below, so that the right pieces of the process can be agentified. Two is to bring the rolled agents for each of these pieces in a structured guardrailed manner. And then the three is to be agent first so that if there are other agentic infrastructure that are already talking to it, they can naturally talk to it so that then they can bring the right output for humans or experts to review, look at it, approve, and maybe then at times automate. Megan: Fantastic. And for all the benefits that we’re talking about with this, are there also challenges when it comes to implementing a context layer? For example, do most organizations have the right data in place to provide AI with the context it needs? And if not, I wonder what some of the practical steps are that they might need to take to address that. Devavrat: It’s again, a crucial question to make this real. We can imagine an ideal world, but if we cannot reach the ideal world, then it’s just ideal. So now in this setting, as we discussed the three layers, one being the layer which is the layer below system of record and workflow tools. In some sense, those things already exist. They don’t need to be complete. They don’t need to be in the cleanest possible manner. The way context model is designed with agentic’s architecture, it manages to connect to those things and make sense of it. And then things on top is very much in control of Celonis’s infrastructure, so it’s not that complicated. The crucial thing here though is when one goes to enterprise, when one opens up, let’s say a system of record or workflow tool, event logs or things like that, one has to go through, what I would call, classical InfoSec to make sure that you can trust a vendor’s software that’s coming into your organization. And I think that is the primary process that is a step between, before and after, if I may call it.
Megan: Right. So that’s the real crucial step for people to be taking here. And as AI agents with context are able to make more complex, more accurate hopefully decisions, I wonder what you think the role of human intelligence and input will be moving forward, and how can organizations perhaps strike the balance between the two? Devavrat: There are the benefits and then there are the challenges. Benefits are clear. If you have right AI agents in a right role manner going through your decision processes, hopefully they’re doing it quicker and hence your decisions are taken earlier so that your opportunity cost is not lost. You are taking decisions in time, you can plan much better, et cetera, et cetera. This is especially useful when you have to take very manual, repetitive, grungy tasks where access to workforce, coordination between people become crucial parts of the decision process. In a sense, that’s where the huge value can come in. The flip side of that is that means that people won’t be doing that.On the other hand, the other type of decision that we always make, which are strategic decisions. It could be a small strategic decision, it could be large strategic decision, but the strategic decisions that typically most organizations don’t have bandwidth to take to think, that opportunity would open up and that’s where likely lots of humans and experts would engage more. In a sense, now they would have better support helping them rationally think through what are the choices that they have, how do different choices compare? And then at the end of the day, it’s organization’s role to decide which of the option to take because it belongs to their interest in mind where they want to go.And so in a sense, there will be what I would call shift of workforce in terms of instead of doing a lot more repetitive, a lot less repetitive, but a lot more strategic work and that’s where people will have to spend time.The other place where I am personally very optimistic is like every technology change creates new work that it’s difficult to predict at the time of change. My hope is that there will be another type of opportunity and work that will be created where we’ll be engaging our workforce. Goes without saying, this would mean that we will have to carefully think through reeducating or educating some of our workforce thoughtfully. And I think as an academic in me, as an educator in me, I really feel that the timescale at which these changes are happening are so fast. So we need to also act in a similar manner.
Megan: For any decision maker listening to this, how should they start implementing these changes? For example, how can they prepare their workforce? What role should governance play as well? Devavrat: Okay, that’s a great question. If you want to start, the first thing you need to do is identify a decision where you want to bring intelligence. Let’s identify the process around it. Let’s identify each step of the process. Let’s take the most crucial, difficult step in that. Let’s try to bring AI agents to help you to do that. And then from there you go and then let’s measure how much speed are we getting, how much value are we getting? And that’ll help us understand whether this was worth it. So that’s one. Second is governance. Well, we’re going to bring AI in this prescriptive manner for each task in a role. That means that for that role, we can tell what it can or cannot do very clearly. And Celonis prescribes certified role agents for these things. This helps you clearly have an understanding of what sort of contract would be for this.And the third thing, which is people, and now this is where it’s really important, is a part which gets automated, but then there’s a part where experts will be in the loop and this is where they need to understand the outputs of AI, how do you work with that and what its implication would be? And this is where some AI education is needed and then some tool education is needed. Megan: Yes, absolutely. The pace is incredible, isn’t it, in this space? And speaking of, I suppose if we could close with a look ahead, given the right context, of course, what are the use cases perhaps for enterprise AI that are on the horizon that you think could be most impactful or perhaps what you’re simply most excited about? Devavrat: I think I would categorize them into three types. They’re all decision intelligence, decision-making, but there are three types. One, what I would call many repetitive manual labor-intensive, so that’s one.Two, what I would call coordination style tasks. A lot of work that we do right now as an information workforce that’s spent in coordination, that’s why email spreadsheets, et cetera. A lot of that would be done much better, much quicker and less boring, so to speak.And then the third is where, especially as a support to human decision-makers to provide strategic support augmentation, and that’s a third type of decisions that would be done. If I think of any planning process in enterprises, so financial planning, workforce planning, marketing, sales, product, anything, all of those are business critical decisions that we make that take annual planning process, take annual time. Now maybe it should not take that much time, and people are actually making the right choices quickly. Megan: That’d be fantastic, wouldn’t it? Fantastic. Thank you so much for that brilliant conversation, Devavrat. That was Devavrat Shah, chief scientist of enterprise AI at Celonis, whom I spoke with from Brighton in England.That’s it for this episode of Business Lab. I’m your host, Megan Tatum. I’m a contributing editor and host for Insights, the custom publishing division of MIT Technology Review. We were founded in 1899 at the Massachusetts Institute of Technology, and you can find us in print, on the web, and at events each year around the world. For more information about us and the show, please check out our website at technologyreview.com.This show is available wherever you get your podcasts. And if you enjoyed this episode, we hope you’ll take a moment to rate and review us. Business Lab is a production of MIT Technology Review, and this episode was produced by Giro Studios. Thanks so much for listening. Goodbye. This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.
Read More »

Three things you should know about permafrost

EXECUTIVE SUMMARY How much do you know about permafrost? Maybe, like me, you’ve been aware that this layer of frozen soil is thawing, that it’s important in the global puzzle of climate change … and that’s about the extent of it.   The great news for both of us is that my colleague James Temple just published two in-depth stories about permafrost. His reporting took him to the boreal forests of Alaska, where he helicoptered into the wilderness to learn more about how this material could affect our climate both now and in the future. I’d recommend you give both of James’s stories a read. There’s this feature about efforts to tackle the intensifying fires that are threatening permafrost, as well as this look at how researchers are trying to understand the complicated tangle of potential climate effects. Here are three things I took away.
Permafrost is a massive blind spot for climate change Permafrost is the frozen layer of soil that’s under about 15% of land around the Northern Hemisphere. While technically material needs to be frozen for only two consecutive years to count as permafrost, most of our current permafrost formed during the last ice age. That means there’s organic material that’s been frozen, and essentially locked away, for thousands of years. But as global temperatures tick up and this layer thaws, microbes are able to break down that organic matter, releasing carbon dioxide and methane—powerful greenhouse gases that drive climate change. Those emissions form a feedback loop, accelerating warming further.
The steady rise in global temperatures has already shrunk the footprint of the Arctic permafrost by about 12% since 1850, and the pace has been picking up in the last 50 years. The wild thing is, only a minority of the models that have been used in UN climate reports actually take into account the gradual loss of permafrost. And none of them include the abrupt thaw and collapse that can happen after events like heat waves and fires (more on those fires in a moment). There are efforts to make sure future UN reports reflect the growing science, but for now, all this means that we’re probably underestimating how much and how fast the planet is going to warm. Wildfires can speed up permafrost loss Fire is a natural part of boreal forests’ life cycle, but they’re getting more intense because of climate change. And crucially, fires can accelerate the thawing of permafrost. By the end of the century, this effect could release the equivalent of 80 billion metric tons of carbon dioxide. Today, the policy across remote parts of Canada and Alaska is generally to let wildfires burn as long as they’re not threatening human habitats. But some researchers say we should explore fighting these fires to save the carbon trapped in the forests and the permafrost beneath them.   Researchers at the Woodwell Climate Research Center are developing a map of burn risk and carbon vulnerability across Alaska, essentially highlighting areas where fires are most likely to spread and which areas are home to certain types of permafrost that would release the most emissions. (Yes, apparently there are different types of permafrost. Yedoma is a particularly deep, carbon-dense form from the late Pleistocene era.) That’s all just the beginning—once we figure out potential targets, the question is what to do about it. Some suggest setting more prescribed fires, something Indigenous groups have done for thousands of years, partly to reduce the danger of massive blazes. Or resources could go to early detection and efforts to put out fires before they grow. The carbon cycle of permafrost is incredibly complicated There’s about 1.5 trillion tons of carbon locked away in permafrost, about twice the amount in the atmosphere. We know that permafrost thawing can release greenhouse-gas emissions and drive climate change. But there are complications.   One particularly big wrinkle: Other effects from permafrost thawing and fire recovery might counteract the carbon lost from those events. For example, as temperatures warm, plants can gradually move north and take hold where they couldn’t have before. Those plants soak up carbon from the atmosphere as they grow, at least partly locking away what was emitted.

Researchers are working to better understand this ecosystem. And the more we learn, the more complicated the picture looks. How much carbon is lost from permafrost, and how much a given area will recover its carbon, depend on a huge array of factors. How severe are the fires that have accelerated local thawing? What’s the local climate and environment? And what kind of permafrost is at stake? The higher we push the planet’s temperature, the more we mess with complicated natural phenomena that we’re only beginning to understand.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Read More »

The Download: AI agent tracking and climate feedback loops

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Opinion: We urgently need to monitor AI agents’ actions in real time —Madhulika Srikumar and Claire Leibowicz from the Partnership on AI, a nonprofit advancing best practices in AI governance. AI agents are taking unauthorized actions, from hacking websites to accessing private government files. In many cases, they’ve eluded the very researchers and safety teams tasked with monitoring them.  As agents roll out across critical sectors, from finance to government to medicine, we must be able to monitor them in real time to prevent potentially devastating consequences. And while safety depends on monitoring, monitoring requires observability.
​​In other words, we need to know what the agent did and why it did it. Because right now, we’re effectively flying blind when deploying these tools.  Here’s what needs to change.
Our climate models have a big, dangerous blind spot Climate change itself increasingly fuels climate change. Rising greenhouse gas concentrations are driving up global temperatures, creating dangerous feedback loops that aren’t fully represented in our climate models—or our emissions-reduction goals. Scientists have long warned that warming would propel further warming. Now, a growing number of observations and studies are indicating how powerful these cascading effects could be. By extension, they’re also showing how much faster the planet may warm this century. Read more about the dangerous feedback loops accelerating global warming. —James Temple This article is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. Are we there yet? Solid-state batteries  Lithium-ion batteries power everything from personal electronics to grid-scale energy storage, but their liquid electrolytes have drawbacks, not least a troubling tendency to catch fire. Enter the solid-state battery, which swaps liquid for a solid ceramic or polymer. The technology promises faster charging, longer life, greater energy density and improved safety, and a new generation of companies aims to bring it to market. If their bets pan out, the tech could ease the shift away from fossil fuels. Find out how close solid-state batteries are to delivering on their promise.

—Alexander C. Kaufman This story is part of “Are we there yet?”, our series that takes stock of six technologies that have long promised to change the world—and scores them on a progress meter. We’re exploring each one in The Download, so stay tuned, and subscribe to read the rest of the stories in our new Impossible issue. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Hackers exposed 41,000 Homeland Security workersIncluding undercover ICE agents. (Wired $)+ Much of the data relates to Customs and Border Protection. (TechCrunch)+ It also linked the agencies to specific surveillance tools. (Reuters $)+ Big Tech is pushing back against ICE’s demands for user data. (WSJ $)+ Activists want ChatGPT users to quit over ICE ties. (MIT Technology Review) 2 Putin says Russia is coordinating with “genius” Musk on satellitesHe said the cooperation maintains order in orbit. (Bloomberg $)+ ​​Russia is developing its own version of Starlink. (Guardian)+ Moscow added Apple and Microsoft to a surveillance registry. (Quartz)+ Here’s all the stuff we’ve put up in space. (MIT Technology Review) 3 Apple just announced its first-ever MacBook with a touchscreenIt joins a blitz of product launches under new CEO John Ternus. (CNN)+ Steve Jobs and Tim Cook had both dismissed the idea. (NYT $)+ Executives say touchscreen advances mean it’s now worthwhile. (Wired $) 4 Bloomberg and trading firms are paying to get Trump’s posts fasterThey’ve signed up for Truth Social’s pay-for-access plan. (Reuters $)
5 As US ties fray, Europe is planning its first subsea cable to GreenlandIt will bypass the US to link Canada, Japan, and South Korea. (Ars Technica)+ The EU’s AI champion says Europe can rival US tech giants. (FT $) 6 Palantir’s defense chief says AI could make China target TaiwanHe says Beijing may act to stop the US pulling ahead in AI. (Bloomberg $)+ Taiwan’s “silicon shield” could be weakening. (MIT Technology Review)
7 Musk’s xAI has offered to buy homes if residents drop a noise lawsuitThe suit targets noise from powering its Mississippi data centres. (Guardian) 8 The world’s first spinal cord transplant has sparked controversyExperts say there’s little evidence the operation will work. (New Scientist $) 9 China’s tech giants are fighting for attention with AI microdramasTencent and ByteDance are battling over the booming market. (SCMP)+ Chinese microdramas are AI content machines. (MIT Technology Review) 10 Astronomers have spotted a possible new dwarf planet beyond PlutoThe icy world would be the solar system’s sixth dwarf planet. (Gizmodo) Quote of the day “They have our information, so it’s only fair that we have theirs.”  —A hacking group explains why it leaked personal information from the US Department of Homeland Security, NPR reports.
One more thing How the Pentagon is adapting to China’s technological rise It’s been just over a year since Kathleen Hicks stepped down as US deputy secretary of defense. As the highest-ranking woman in Pentagon history, Hicks shaped US military posture through an era defined by renewed competition between powerful countries and a scramble to modernize defense technology. In this conversation with MIT Technology Review, Hicks reflects on how the Pentagon is adapting—or failing to adapt—to a new era of geopolitical competition. She discusses China’s technological rise, the future of AI in warfare, and her signature initiative: Replicator. 

Read More »

We urgently need to monitor AI agents’ actions in real time

This summer, hundreds of OpenAI agents tried to cheat on a cybersecurity test. They broke out of their test environment and successfully hacked Hugging Face, a site that they believed held clues about how they’d be graded. Around the same time, another OpenAI agent accessed private files from an Australian government website. It’s a problem that’s by no means confined to OpenAI. In the months since, Anthropic, Google, and Meta have also disclosed incidents in which their agents have gone off track. And worryingly, in many cases the agents eluded the very researchers and safety teams tasked with monitoring them.  AI agents are taking unauthorized actions, and the companies building and running them are mostly relying on luck and hindsight to mitigate any harmful impacts. They must do more to ensure safety. That’s why EU regulators and US agencies are rightfully calling for agent developers and deployers to monitor agents in real time. But these rules assume that companies can see what their agents are doing and why—when in reality, they lack sufficient visibility.  Imagine a bank hiring a thousand new employees who can access customer accounts and sensitive information, but the employees’ ID badges change every day, it’s not clear whether a manager ever reviewed or authorized their work, and nobody logs the changes employees make to approval processes. That lack of visibility is where we are with agents today. As agents roll out across critical sectors, from finance to government to medicine, we must be able to monitor them in real time to prevent wide-ranging and potentially devastating consequences.  And while safety depends on monitoring, monitoring requires observability: the capacity to capture what the system did, process it into signals, and present those to humans or automated oversight systems. In other words, we need to know what the agent did and why it did it. And as our recent research shows, current agent frameworks—the software that runs agents— do not reliably generate the crucial observability records we need to ensure that agents are deployed safely.
Agents present new kinds of problems that generative AI alone does not. They inherit the unpredictability of the LLMs they are built on, but where a generative AI system produces a single output for a human to act on, an agent performs longer tasks—it plans, picks tools, spawns sub-agents, and takes actions. So an agent’s course can take shape in a multitude of different ways, and no tests before launch can fully anticipate the risks. This makes observing the agents while they work even more challenging, and even more important. With colleagues from academia, civil society, and industry, we studied the four most widely used agent frameworks to see what signals they actually emit. We found major gaps that made it hard to achieve key safety goals, like noticing policy violations, unauthorized actions, and even human oversight failures. Key observability requirements were missing—like Agent IDs that persist over time, and records about which humans approved agent tasks. This made it hard to tell which agents did what or assess whether they were taking unauthorized actions. 
The good news is that these gaps, once identified, can be closed. Doing so starts with capturing two types of records: those that reveal what happened in an agent’s run and how the agent made its decisions. The “what happened” records identify the agent (while preserving privacy) and log how humans intervened and whether agent permissions or “memory” shifted, while the “decision” records show an agent’s reasoning and levels of confidence in the actions it’s taken. Take, for example, agents working to process a bank’s mortgage loans. The system examines an application and recommends denying it, and then a human loan officer signs off on the decision. In a later audit, or perhaps even in real time, a bank or regulator needs to be able to reconstruct which agent made the call, which officer approved it, and how long they took. And the bank must also analyze records of how the agent arrived at its refusal decision in order to ensure it did not use off-limits information, like details about the neighborhood the applicant is from. Recording “what happened” and “how the agent decided” require different approaches, but both are feasible. The current lack of “what happened” records is mostly a software plumbing problem that can be addressed through OpenTelemetry, an open observability standard maintained by engineers across the industry and by the agent frameworks adopting it. OpenTelemetry has launched a working group drafting shared formats for tracing agents, but they have yet to be finalized. The group should urgently incorporate standards for maintaining persistent agent identity and for recording human interventions and changes to agents’ permission or memory. And it should be done before these systems can scale, all the while attending to the privacy implications of agent ID that links to real people. Preserving “how agents decided” records is more challenging. The issue raises open research questions for model providers and researchers: Does the step-by-step reasoning a model displays, known as chain of thought, reflect how the model actually made a decision? And do we have reliable ways to measure how confident the agent is in that decision? These questions need answers before anyone sets standards for how such observability records are used. No single organization or sector can close the observability gaps on their own, but together, they can support the infrastructure required to prevent dangerous incidents and support safety.  AI developers building agent frameworks, like OpenAI, Anthropic, CrewAI, and LangChain, must integrate telemetry signals recording an agent’s persistent identity, any human interventions, and any changes to an agent’s permissions and memory. Meanwhile, enterprises adopting these agent frameworks have an influential role to play; enterprises in regulated industries, like banks and hospitals, can put pressure on the agent developers to supply these missing observability records where standards do not yet exist. Enterprises must also define policies, permissions, and roles that set out what agents can safely do, since telemetry alone cannot assess whether agents broke specific rules. Finally, regulators and AI standards institutes must specify the observability records required for high-stakes AI deployments while leaving the technical details to industry. We have already seen initial momentum here: NIST’s agent standards initiative in the US is working on agent identity, one of the most salient gaps we found in our research. 

No bank would let a thousand unbadged employees loose on customer accounts and hope to piece together what happened when something goes wrong. Yet that’s how we’re deploying AI agents. Making their behavior observable is the first step toward fixing this. And by building the regulatory and policy ecosystem that makes it possible to act on what we see, we can hold organizations accountable. Until then, every task we hand to an agent hands over our agency, too. Madhulika Srikumar is the Head of the AI Safety Program at the Partnership on AI, a global non-profit partnership of leading industry, academic, and civil society organizations, advancing best practices in AI governance. Claire Leibowicz is the Director of AI, Trust, and Society at the Partnership on AI and a doctoral candidate at Oxford University.

Read More »

Our climate models have a big, dangerous blind spot

EXECUTIVE SUMMARY Climate change itself is increasingly fueling climate change. Rising concentrations of greenhouse gases are driving up global temperatures, setting off dangerous feedback loops that we have not fully accounted for in our climate models—or our emissions-reduction goals. Scientists have long warned that warming would propel further warming in various ways, but a growing number of observations and studies are at last providing a sharper sense of just how powerful these cascading effects could be. And, by extension, they’re showing how much faster the planet may warm in this century. A study in Environmental Research Letters in September, synthesizing the results of previous papers, found that the additional carbon dioxide and methane released from thawing permafrost, intensifying wildfires, hotter lakes and reservoirs, and wetter, warmer wetlands alone could drive global average temperatures up 0.2 °C to 0.4 °C this century. That would come on top of the 2.6°C of warming above preindustrial levels that modelers are already expecting through 2100. The additional heat could subject many of the world’s cities to monthslong heat waves and expose hundreds of millions of people to flooding.  None of the models that inform the major UN climate reports, which assess how much the planet will likely warm under various emissions scenarios, account for all these feedback effects. Many of them don’t incorporate any. That leaves a huge blind spot in our understanding of how much the world could actually warm in the coming decades—and how rapidly nations will need to slash emissions to stay within critical boundaries.
A separate analysis published in One Earth in March, which examined what the feedback problem means for our international climate goals, concluded that the world may be much further off track than is widely believed. It found that just three regional sources of warming-driven emissions—thawing permafrost, increasing fires in boreal forests, and warming tropical wetlands—may shorten by as much as 25% the time before the planet consistently breaches the 1.5 °C and 2 °C warming thresholds. Our climate models and the UN’s reports clearly need to be updated to better represent these effects. Nations must also step up their efforts to reduce emissions to reflect this improving understanding of the dangers we face, says Sam Abernethy, the lead author of the paper and a climate scientist at Spark Climate Solutions, a San Francisco–based nonprofit research group. 
At least some of this is starting to happen. Spark kick-started an initiative, called the Warming-Induced Greenhouse Gas Emissions Model Intercomparison Project, through which more than 20 international teams are running the same set of analyses on different models to develop greater understanding of feedback effects’ potential power. Researchers involved hope that the UN will incorporate those results into its next major climate assessment, due out in 2029. That report will update estimates of the remaining emissions that can be released before the world crosses key temperature thresholds. But what is already clear is that the planet is rapidly warming and that nations haven’t done nearly enough to cut fossil-fuel pollution. And even if we did manage to halt it, warming-driven emissions could continue.  So a number of the research groups involved in the recent studies have started to explore what nations could do to get feedback emissions under control. Scientists at the Woodwell Climate Research Center in Massachusetts are, for example, investigating the possibility of preventing fires or rapidly detecting them and putting them out when they threaten to burn the vegetation and soil that help insulate particularly carbon-rich wedges of permafrost (a subject I explored at length in a recent feature story). In addition, the Environmental Defense Fund’s Climate Innovation Initiative has backed lab research on the potential of adding sulfate, iron, or other compounds to wetlands to counteract fast-rising methane emissions.  Several startups are also exploring possibilities. They’re looking into suppressing the lightning strikes that are igniting more and more fires in high latitudes, placing synthetic mats above permafrost to prevent it from melting, and deploying autonomous drones to quickly suppress potentially high-emissions fires before they burn out of control. Investigating all these ideas is worthwhile. But researchers are only in the earliest stages of figuring out how big a dent in emissions any such efforts could achieve across sprawling global ecosystems undergoing massive transformations.  The surest path to reducing the effect of warming-driven warming remains the one we’ve known all along: breaking society’s addiction to fossil fuels.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Read More »

Creating AI value with enterprise context

In association withAtlan Across a business, any number of AI platforms, systems, and tools may be at work simultaneously—for example, AI-powered customer platforms, conversational assistants, and workflow and process automation tools. Each one is sophisticated, advanced, and quick to respond. But, when set to work, the outcomes and actions that emerge may be wrong, confused, or lacking a proper understanding of the business. Many organizations find themselves in this situation—and it could be one of key reasons they struggle to extract returns on their AI investments. An MIT Technology Review Insights poll finds that while every organization surveyed is using AI today to some degree, fewer than one in five (16%) are extracting transformative value from their deployments. The largest percentage of respondents (40%) say they are seeing moderate gains in specific tasks or teams, while 21% report meaningful gains, leaving 23% that are seeing minimal returns or none at all. Companies are mostly still piloting AI use cases (according to 38% of respondents) or using it to assist employees’ work with tools like co-pilots or chat assistants (35%). Just 12% of enterprises have AI agents in production and 3% say they are using AI to do most of the work in key processes. “There’s a big gap between what the models are capable of and how the models are actually being useful inside organizations,” says Prukalpa Sankar, co-founder of Atlan. “For every real-life intent and purpose, artificial general intelligence is already here. It’s just not really useful in most companies today.”
The missing layer, Sankar says, is context, or how well AI understands a business. A context layer is the architectural infrastructure that sits between an organization’s business systems (for example, systems of record and data, and its AI platforms). It translates enterprise intelligence into governed, machine-usable context for AI agents or models and helps knowledge compound. “Without a context layer for AI, it’s almost like you’re hiring the smartest intern in the world, blindfolding them, and throwing them into your organization,” Sankar says. Download the report This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.
Read More »

Expand curtailing some production ‘in direct acknowledgement that the market is weakening’

Expand Energy Corp., Spring, Tex., pulled back on some production during the third quarter, including by dropping a rig in Northeast Appalachia and a completion crew in the Haynesville, because of weaker prices for natural gas. Executives on Oct. 28 told analysts and investors that they’re prepared to curtail more work late this year and into 2027. “As we’ve come into the fourth quarter, we’ve ended up reducing some of our activity,” chief operating officer Josh Viets said on a conference call following the release of Expand’s third-quarter results. “That activity reduction, moving from around 12 rigs down to 10, is in direct acknowledgement that the market is weakening.” Viets was responding to a question from JPMorgan analyst Arun Jayaram, who neatly summed up the factors contributing to soft natural gas prices even though demand growth has been solid. The environment next year could be affected by Super El Niño weather patterns, more supply being transported out of the Permian basin and several LNG infrastructure owners being “a little bit more levered to the back end of the year.” Viets agreed with that assessment of the supply-demand picture for the coming quarters and later said Expand is prepared to revisit the strategy it employed 2 years ago, when it built up its inventory of drilled but uncompleted wells while waiting for prices to climb. “We pushed out about nine turn-in-lines out of Q3,” he added. “We are waiting on those still to think about the optimal time to bring them online.”

Read More »

EIA: US crude oil inventories down 1.9 million bbl

US crude oil inventories for the week ended Oct. 23, excluding the Strategic Petroleum Reserve, decreased by 1.9 million bbl from the previous week, according to data from the US Energy Information Administration (EIA). At 410.6 million bbl, US crude oil inventories are 4% below the 5-year average for this time of year, the EIA report indicated. Gasoline inventories increased 3.9 million bbl, 2% below the 5-year average. Propane-propylene inventories decreased 100,000 bbl, 12% above the 5-year average. Total commercial petroleum inventories decreased by 3.0 million bbl for the week. Distillate inventories decreased 1.5 million bbl, 10% below the 5-year average. US crude oil refinery inputs averaged 16.5 million b/d for the week ended Oct. 23, which was 123,000 b/d less than the previous week’s average. Refineries operated at 92.8% of capacity. Gasoline output averaged 9.2 million b/d, and distillate production decreased to 5.2 million b/d. Crude oil imports increased 616,000 b/d to 6.4 million b/d. The 4-week average of 6.3 million b/d is 9.3% above the year-ago level. Gasoline imports averaged 399,000 b/d; distillate imports averaged 157,000 b/d. Over the past four weeks, total product supplied averaged 20.8 million b/d, up 0.2% year over year. The 4-week average for gasoline product supplied decreased 0.7% year over year to 8.6 million b/d, while the 4-week average for distillate product supplied decreased 0.6% to 4.0 million b/d. The 4-week average for jet fuel product supplied decreased 3.5% year over year.

Read More »

Stay Ahead with the Paperboy Newsletter

Your weekly dose of insights into AI, Bitcoin mining, Datacenters and Energy indusrty news. Spend 3-5 minutes and catch-up on 1 week of news.

Smarter with ONMINE

Streamline Your Growth with ONMINE