Stay Ahead, Stay ONMINE

OpenAI returns to open source roots with new models gpt-oss-120b and gpt-oss-20b 

OpenAI is getting back to its roots as an open source AI company with today’s announcement and release of two new, open source, frontier large language models (LLMs): gpt-oss-120b and gpt-oss-20b.The former is a 120-billion parameter model as the name would suggest, capable of running on a single Nvidia H100 graphics processing unit (GPU) and the latter is only 20 billion, small enough to run locally on a consumer laptop or desktop PC. Both are text-only language models, which means unlike the multimodal AI that we’ve had for nearly two years that allows users to upload files and images and have the AI analyze them, users will be confined to only inputting text messages to the models and receiving text back out. However, they can still of course write code and provide math problems and numerics, and in terms of their performance on tasks, they rank above some of OpenAI’s paid models and much of the competition globally.

OpenAI is getting back to its roots as an open source AI company with today’s announcement and release of two new, open source, frontier large language models (LLMs): gpt-oss-120b and gpt-oss-20b.

The former is a 120-billion parameter model as the name would suggest, capable of running on a single Nvidia H100 graphics processing unit (GPU) and the latter is only 20 billion, small enough to run locally on a consumer laptop or desktop PC.

Both are text-only language models, which means unlike the multimodal AI that we’ve had for nearly two years that allows users to upload files and images and have the AI analyze them, users will be confined to only inputting text messages to the models and receiving text back out.

However, they can still of course write code and provide math problems and numerics, and in terms of their performance on tasks, they rank above some of OpenAI’s paid models and much of the competition globally.


The AI Impact Series Returns to San Francisco – August 5

The next phase of AI is here – are you ready? Join leaders from Block, GSK, and SAP for an exclusive look at how autonomous agents are reshaping enterprise workflows – from real-time decision-making to end-to-end automation.

Secure your spot now – space is limited: https://bit.ly/3GuuPLF


They can also be connected to external tools including web search to perform research on behalf of the user. More on this below.

Most importantly: they’re free, they’re available for enterprises and indie developers to download the code and use right now, modifying according to their needs, and can be run locally without a web connection, ensuring maximum privacy, unlike the other top OpenAI models and those from leading U.S.-based rivals Google and Anthropic.

The models can be downloaded today with full weights (the settings guiding its behavior) on the AI code sharing community Hugging Face and GitHub.

High benchmark scores

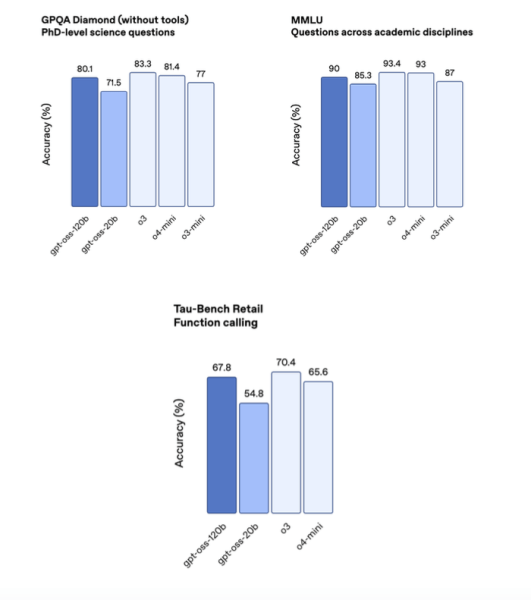
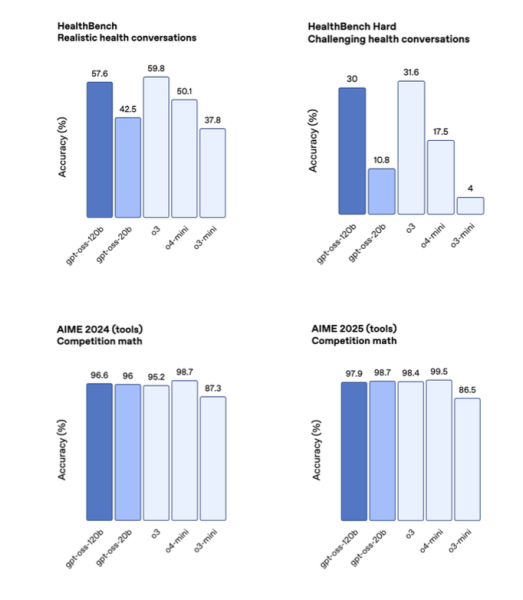
According to OpenAI, gpt-oss-120b matches or exceeds its proprietary o4-mini model on reasoning and tool-use benchmarks, including competition mathematics (AIME 2024 & 2025), general problem solving (MMLU and HLE), agentic evaluations (TauBench), and health-specific evaluations (HealthBench). The smaller gpt-oss-20b model is comparable to o3-mini and even surpasses it in some benchmarks.
The models are multilingual and perform well across a variety of non-English languages, though OpenAI declined to specify which and how many.

While these capabilities are available out of the box, OpenAI notes that localized fine-tuning — such as an ongoing collaboration with the Swedish government to produce a version fine-tuned on the country’s language —can still meaningfully enhance performance for specific regional or linguistic contexts.

A hugely advantageous license for enterprises and privacy-minded users

But the biggest feature is the licensing terms for both: Apache 2.0, the same as the wave of Chinese open source models that have been released over the last several weeks, and a more enterprise-friendly license than Meta’s trickier and more nuanced open-ish Llama license, which requires that users who operate a service with more than 700 million monthly active users obtain a paid license to keep using the company’s family of LLMs.

By contrast, OpenAI’s new gpt-oss series of models offer no such restrictions. In keeping with Chinese competitors and counterparts, any consumer, developer, independent entrepreneur or enterprise large and small is empowered by the Apache 2.0 license to be able to download the new gpt-oss models at will, fine-tune and alter them to fit their specific needs, and use them to generate revenue or operate paid services, all without paying OpenAI a dime (or anything!).

This also means enterprises can use a powerful, near topline OpenAI model on their own hardware totally privately and securely, without sending any data up to the cloud, on web servers, or anywhere else. For highly regulated industries like finance, healthcare, and legal services, not to mention organizations in military, intelligence, and government, this may be a requirement.

Before today, anyone using ChatGPT or its application programming interface (API) — the service that acts like a switching board and allows third-party software developers to connect their own apps and services to these OpenAI’s proprietary/paid models like GPT-4o and o3 — was sending data up to OpenAI servers that could technically be subpoenaed by government agencies and accessed without a user’s knowledge. That’s still the case for anyone using ChatGPT or the API going forward, as OpenAI co-founder and Sam Altman recently warned.

And while running the new gpt-oss models locally on a user’s own hardware disconnected from the web would allow for maximum privacy, as soon as the user decides to connect it to external web search or other web enabled tools, some of the same privacy risks and issues would then arise — through any third-party web services the user or developer was relying on when hooking the models up to said tools.

The last OpenAI open source language model was released more than six years ago

“This is the first time we’re releasing an open-weight language model in a long time… We view this as complementary to our other products,” said OpenAI co-founder and president Greg Brockman on an embargoed press video call with VentureBeat and other journalists last night.

The last time OpenAI released a fully open source language model was GPT-2 in 2019, more than six years ago, and three years before the release of ChatGPT.

This fact has sparked the ire of — and resulted in several lawsuits from — former OpenAI co-founder and backer turned rival Elon Musk, who, along with many other critics, have spent the last several years accusing OpenAI of betraying its mission and founding principles and namesake by eschewing open source AI releases in favor of paid proprietary models available only to customers of OpenAI’s API or paying ChatGPT subscribers (though there is a free tier for the latter).

OpenAI co-founder CEO Sam Altman did express regret about being on the “wrong side of history” but not releasing more open source AI sooner in a Reddit AMA (ask me anything) QA with users in February of this year, and Altman committed to releasing a new open source model back in March, but ultimately the company delayed its release from a planned July date until now.

Now OpenAI is tacking back toward open source, and the question is, why?

Why would OpenAI release a set of free open source models that it makes no money from?

To paraphrase Jesse Plemons’ character’s memorable line from the film Game Night: “How can that be profitable for OpenAI?”
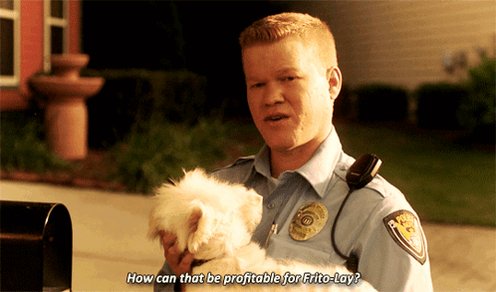
After all, business to OpenAI’s paid offerings appears to be booming.

Revenue has skyrocketed alongside the rapid expansion of its ChatGPT user base, now at 700 million weekly active users. As of August 2025, OpenAI reported $13 billion in annual recurring revenue, up from $10 billion in June. That growth is driven by a sharp rise in paying business customers — now 5 million, up from 3 million just two months earlier — and surging daily engagement, with over 3 billion user messages sent every day.

The financial momentum follows an $8.3 billion funding round that valued OpenAI at $300 billion and provides the foundation for the company’s aggressive infrastructure expansion and global ambitions.

Compare that to closed/proprietary rival AI startup Anthropic’s reported $5 billion in total annual recurring revenue, but interestingly, Anthropic is said to be getting more money from its API, $3.1 billion in revenue compared to OpenAI’s $2.9 billion, according to The Information.

So, given how well the paid AI business is already doing, the business strategy behind these open source offerings is less clear — especially since the new OpenAI gpt-oss models will almost certainly cut into some (perhaps a lot of) usage of OpenAI’s paid models. Why go back to offering open source LLMs now when so much money is flowing into paid and none will, by virtue of its very intent, go directly toward open source models?

Put simply: because open source competitors, beginning with the release of the impressively efficient DeepSeek R1 by the Chinese AI division of the same name in January 2025, are offering near parity on performance benchmarks to paid proprietary models, for free, with fewer (basically zero) implementation restrictions for enterprises and end users. And increasingly, enterprises are adopting these open source models in production.

As OpenAI executives and team members revealed to VentureBeat and many other journalists on an embargoed video call last night about the new models that when it comes to OpenAI’s API, the majority of customers are using a mix of paid OpenAI models and open source models from other providers. (I asked, but OpenAI declined to specify what percentage or total number of API customers are using open source models and which ones).

At least, until now. OpenAI clearly hopes these new gpt-oss offerings will get more of these users to switch away from competing open source offerings and back into OpenAI’s ecosystem, even if OpenAI doesn’t see any direct revenue or data from that usage.

On a grander scale, it seems OpenAI wants to be a full-service, full-stack, one-stop shop AI offering for all of an enterprise, indie developer’s, or regular consumer’s machine intelligence needs — from a clean chatbot interface to an API to build services and apps atop of to agent frameworks for building AI agents through said API to an image generation model (gpt-4o native image generation), video model (Sora), audio transcription model (gpt-4o-transcribe), and now, open source offerings as well. Can a music generation and “world model” be far behind?

OpenAI seeks to span the AI market, propriety and open source alike, even if the latter is worth nothing in terms of actual, direct dollars and cents.

Training and architecture

Feedback from developers directly influenced gpt-oss’s design. OpenAI says the top request was for a permissive license, which led to the adoption of Apache 2.0 for both models. Both models use a Mixture-of-Experts (MoE) architecture with a Transformer backbone.

The larger gpt-oss-120b activates 5.1 billion parameters per token (out of 117 billion total), and gpt-oss-20b activates 3.6 billion (out of 21 billion total).

Both support 128,000 token context length (about 300-400 pages of a novel’s worth of text a user can upload at once), and employ locally banded sparse attention and use Rotary Positional Embeddings for encoding.

The tokenizer — the program that converts words and chunks of words into the numerical tokens that the LLMs can understand, dubbed “o200k_harmony“ — is also being open-sourced.

Developers can select among low, medium, or high reasoning effort settings based on latency and performance needs. While these models can reason across complex agentic tasks, OpenAI emphasizes they were not trained with direct supervision of CoT outputs, to preserve the observability of reasoning behavior—an approach OpenAI considers important for safety monitoring.

Another common request from OpenAI’s developer community was for strong support for function calling, particularly for agentic workloads, which OpenAI believes gpt-oss now delivers.

The models are engineered for chain-of-thought reasoning, tool use, and few-shot function calling, and are compatible with OpenAI’s Responses API introduced back in March, which allows developers to augment their apps by connecting an OpenAI LLM of their choice to three powerful built-in tools — web search, file search, and computer use — within a single API call.

But for the new gpt-oss models, tool use capabilities — including web search and code execution — are not tied to OpenAI infrastructure. OpenAI provides the schemas and examples used during training, such as a basic browser implementation using the Exa API and a Python interpreter that operates in a Docker container.

It is up to individual inference providers or developers to define how tools are implemented. Providers like vLLM, for instance, allow users to configure their own MCP (Model-Controller-Proxy) server to specify the browser backend.

While these models can reason across complex agentic tasks, OpenAI emphasizes they were not trained with direct supervision of CoT outputs, to preserve the observability of reasoning behavior—an approach OpenAI considers important for safety monitoring.

Safety evaluations and measures

OpenAI conducted safety training using its Preparedness Framework, a document that outlines the procedural commitments, risk‑assessment criteria, capability categories, thresholds, evaluations, and governance mechanisms OpenAI uses to monitor, evaluate, and mitigate frontier AI risks.

These included filtering chemical, biological, radiological, and nuclear threat (CBRN) related data out during pretraining, and applying advanced post-training safety methods such as deliberative alignment and an instruction hierarchy to enforce refusal behavior on harmful prompts.

To test worst-case misuse potential, OpenAI adversarially fine-tuned gpt-oss-120b on sensitive biology and cybersecurity data using its internal RL training stack. These malicious fine-tuning (MFT) scenarios—one of the most sophisticated evaluations of this kind to date—included enabling browsing and disabling refusal behavior, simulating real-world attack potential.

The resulting models were benchmarked against both open and proprietary LLMs, including DeepSeek R1-0528, Qwen 3 Thinking, Kimi K2, and OpenAI’s o3. Despite enhanced access to tools and targeted training, OpenAI found that even the fine-tuned gpt-oss models remained below the “High” capability threshold for frontier risk domains such as biorisk and cybersecurity. These conclusions were reviewed by three independent expert groups, whose recommendations were incorporated into the final methodology.

In parallel, OpenAI partnered with SecureBio to run external evaluations on biology-focused benchmarks like Human Pathogen Capabilities Test (HPCT), Molecular Biology Capabilities Test (MBCT), and others. Results showed that gpt-oss’s fine-tuned models performed close to OpenAI’s o3 model, which is not classified as frontier-high under OpenAI’s safety definitions.

According to OpenAI, these findings contributed directly to the decision to release gpt-oss openly. The release is also intended to support safety research, especially around monitoring and controlling open-weight models in complex domains.

Availability and ecosystem support

The gpt-oss models are now available on Hugging Face, with pre-built support through major deployment platforms including Azure, AWS, Databricks, Cloudflare, Vercel, Together AI, OpenRouter, and others. Hardware partners include NVIDIA, AMD, and Cerebras, and Microsoft is making GPU-optimized builds available on Windows via ONNX Runtime.

OpenAI has also announced a $500,000 Red Teaming Challenge hosted on Kaggle, inviting researchers and developers to probe the limits of gpt-oss and identify novel misuse pathways. A public report and an open-source evaluation dataset will follow, aiming to accelerate open model safety research across the AI community.

Early adopters such as AI Sweden, Orange, and Snowflake have collaborated with OpenAI to explore deployments ranging from localized fine-tuning to secure on-premise use cases. OpenAI characterizes the launch as an invitation for developers, enterprises, and governments to run state-of-the-art language models on their own terms.

While OpenAI has not committed to a fixed cadence for future open-weight releases, it signals that gpt-oss represents a strategic expansion of its approach — balancing openness with aligned safety methodologies to shape how large models are shared and governed in the years ahead.

The big question: with so much competition in open source AI, will OpenAI’s own efforts pay off?

OpenAI re-enters the open source model market in the most competitive moment yet.

At the top of public AI benchmarking leaderboards, U.S. frontier models remain proprietary — OpenAI (GPT-4o/o3), Google (Gemini), and Anthropic (Claude).

But they now compete directly with a surge of open-weights contenders. From China: DeepSeek-R1 (open source, MIT) and DeepSeek-V3 (open-weights under a DeepSeek Model License that permits commercial use); Alibaba’s Qwen 3 (open-weights, Apache-2.0); MoonshotAI’s Kimi K2 (open-weights; public repo and model cards); and Z.ai’s GLM-4.5 (also Apache 2.0 licensed).

Europe’s Mistral (Mixtral/Mistral, open-weights, Apache-2.0) anchors the EU push; the UAE’s Falcon 2/3 publish open-weights under TII’s Apache-based license. In the U.S. open-weights camp, Meta’s Llama 3.1 ships under a community (source-available) license, Google’s Gemma under Gemma terms (open weights with use restrictions), and Microsoft’s Phi-3.5 under MIT.

Developer pull mirrors that split. On Hugging Face, Qwen2.5-7B-Instruct (open-weights, Apache-2.0) sits near the top by “downloads last month,” while DeepSeek-R1 (MIT) and DeepSeek-V3 (model-licensed open weights) also post heavy traction. Open-weights stalwarts Mistral-7B / Mixtral (Apache-2.0), Llama-3.1-8B/70B (Meta community license), Gemma-2 (Gemma terms), Phi-3.5 (MIT), GLM-4.5 (open-weights), and Falcon-2-11B (TII Falcon License 2.0) round out the most-pulled families —underscoring that the open ecosystem spans the U.S., Europe, the Middle East, and China. Hugging Face signals adoption, not market share, but they show where builders are experimenting and deploying today. 

Consumer usage remains concentrated in proprietary apps even as weights open up. ChatGPT still drives the largest engagement globally (about 2.5 billion prompts/day, proprietary service), while in China the leading assistants — ByteDance’s Doubao, DeepSeek’s app, Moonshot’s Kimi, and Baidu’s ERNIE Bot — are delivered as proprietary products, even as several base models (GLM-4.5, ERNIE 4.5 variants) now ship as open-weights.

But now that a range of powerful open source models are available to businesses and consumers — all nearing one another in terms of performance — and can be downloaded on consumer hardware, the big question facing OpenAI is: who will pay for intelligence at all? Will the convenience of the web-based chatbot interface, multimodal capabilities, and more powerful performance be enough to keep the dollars flowing? Or has machine intelligence already become, in the words of Atlman himself, “too cheap to meter”? And if so, how to build a successful business atop it, especially with OpenAI and other AI firms’ sky-high valuations and expenditures.

One clue: OpenAI is already said to be offering in-house engineers to help its enterprise customers customize and deploy fine-tuned models, similar to Palantir’s “forward deployed” software engineers (SWEs), essentially charging for experts to come in, set up the models correctly, and train employees how to use them for best results.

Perhaps the world will migrate toward a majority of AI usage going to open source models, or a sizeable minority, with OpenAI and other AI model providers offering experts to help install said models into enterprises. Is that enough of a service to build a multi-billion dollar business upon? Or will enough people continue paying $20, $200 or more each month to have access to even more powerful proprietary models?

I don’t envy the folks at OpenAI figuring out all the business calculations — despite what I assume to be hefty compensation as a result, at least for now. But for end users and enterprises, the release of the gpt-oss series is undoubtedly compelling.
Shape
Shape
Stay Ahead

Explore More Insights

Stay ahead with more perspectives on cutting-edge power, infrastructure, energy,  bitcoin and AI solutions. Explore these articles to uncover strategies and insights shaping the future of industries.

Shape

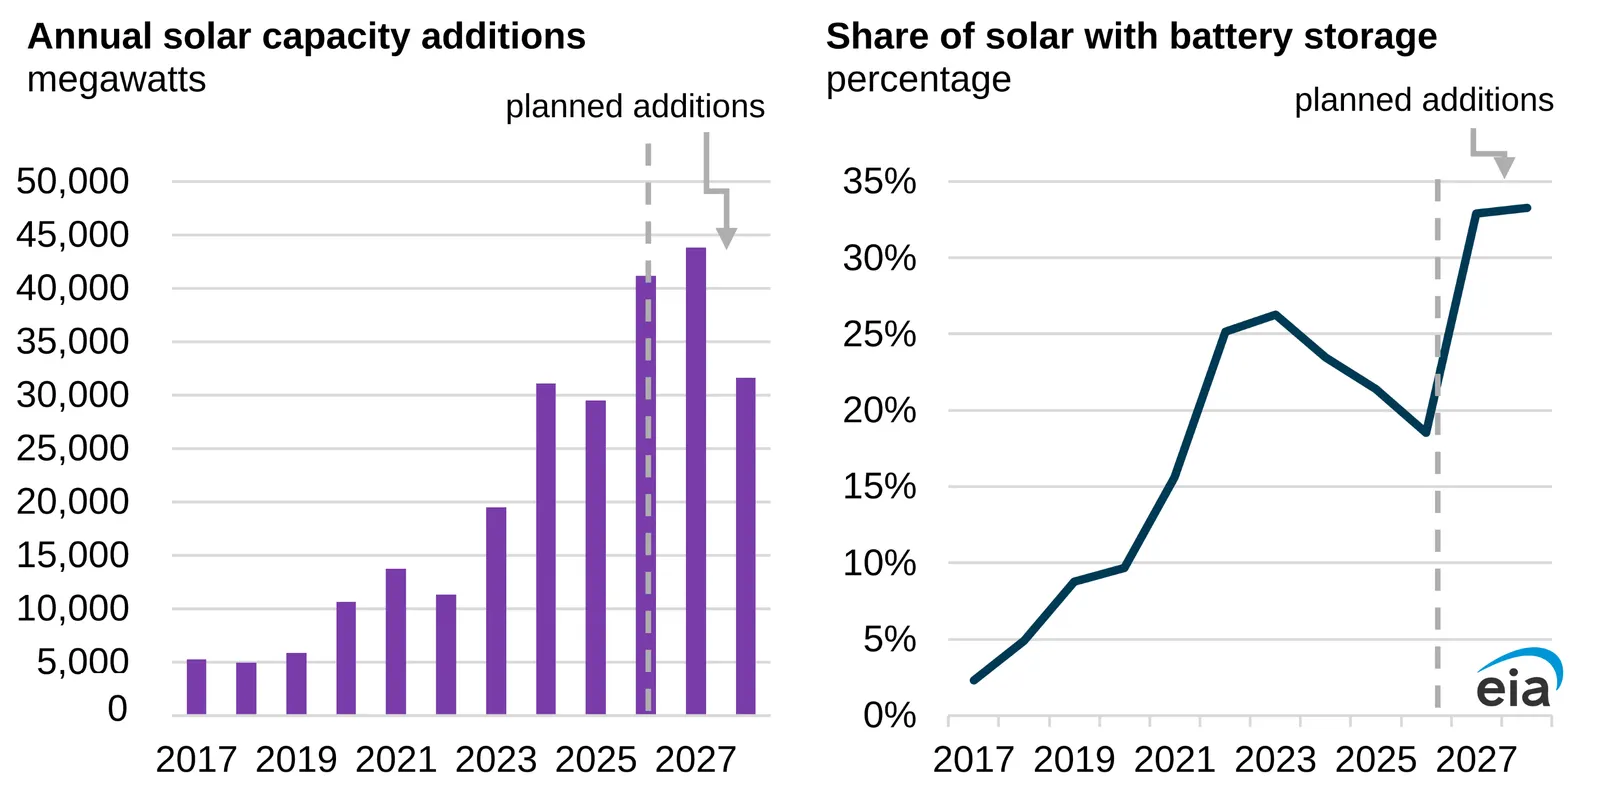
Co-located solar, storage jumps to 16% of all installations, up from 2% in 2017: EIA

Listen to the article 3 min This audio is auto-generated. Please let us know if you have feedback. The share of new solar projects deployed with co-located battery storage this year is 16% — or about 41 GW — as of September, and may reach 19% by year’s end, said an Oct. 30 report from the U.S. Energy Information Administration. It is likely to pass 30% in the next two years, the agency estimated. The trend has increased significantly over the last decade, as only around 2% of projects, or 5 GW, of new solar capacity was co-located with storage in 2017. In 2023, co-location jumped to 25% of projects, then fell over 2024 and 2025, according to EIA’s data — but is projected to pass 30% over the next two years, based on planned additions. “When operators co-locate battery storage with solar, they can direct solar electricity output to the grid or to the battery, depending on the wholesale prices,” EIA’s report said. “Wholesale prices in regions with large solar participation tend to fall when solar contributions are high and rise as they decrease.” “Plants with both solar and battery storage can manage the combined output of their generating resources to maximize their value in a changing wholesale price environment,” EIA added. Courtesy of U.S. Energy Information Administration An Oct. 22 report from the Solar Energy Industries Association found that from 2021 to 2026, “solar generation increased 421% in Texas and 90% in California, while battery storage capacity grew more than 26-fold in Texas and nearly sevenfold in California.” When comparing the same June to August period, SEIA found that “CAISO used 2.5% more power than the same time in 2021 with an average wholesale electricity price 40% lower after accounting for inflation. ERCOT used 30.1% more power than the

Read More »

Data centers don’t need special treatment to get power faster

Listen to the article 7 min This audio is auto-generated. Please let us know if you have feedback. Seyed Madaeni is CEO and co-founder of Verse, an energy software company specializing in battery dispatch optimization for data centers. Even the best-funded project can’t operate without electricity, and the grid often can’t deliver hundreds of new megawatts as quickly as AI developers need them. Access to power has become a competitive advantage, and companies are searching for ways to get it faster. Seyed Madaeni Today, developers see two obvious options. They can wait years for traditional grid upgrades, or they can build private power plants onsite. The first can move too slowly. The second brings fuel-supply, equipment, permitting and community challenges of its own. A third path to data center interconnection is taking shape. Across the country, utilities and grid operators are creating clearer ways for large loads that can reduce the risks they bring to the system. Depending on the market, a data center might guarantee a minimum payment, agree to reduce its grid demand when the system is strained, provide better operating data or contract for new generation and storage. These policies differ, but they share one idea: If a data center wants faster or more certain access to power, it should give the grid greater certainty in return. That is a better approach than advancing projects mainly because they promise jobs or investment. Projects that make their demand more predictable, controllable and financially secure should have a clearer path to service. Ohio is asking data centers to pay for what they reserve Utilities often need to invest in substations, transmission equipment and other infrastructure years before a data center reaches full operation. They are building against forecasts that can change, and their queues may include projects that never get

Read More »

APA to beef up exploration spending in 2027

@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } Executives at APA Corp., Houston, plan to bump the company’s 2027 capital spending to $2.5 billion from an expected $2.1 billion and will dedicate the majority of that increase to exploration work and the development of the GranMorgu project in which it is a 40% partner. Speaking to analysts and investors after APA reported third-quarter profits of $698 million on revenues of more than $2.8 billion, chief executice officer John Christmann said the allocation of $250 million to exploration and another $250 million to developing GranMorgu will return APA to its targeted range of having 10-15% of annual upstream capital go to such work. The plans comprise: Two exploration wells in Suriname’s GranMorgu offshore development with TotalEnergies, which also owns 40% of that project and is the operator. Christmann said the wells will look to extend GranMorgu’s production plateau “or even support a second development.” A winter program in Alaska that includes an exploration well and an appraisal test of the company’s Sockeye discovery. The spudding of APA’s well in the OFF-6 block of which it owns 60%, with Eni holding the remainder. Tracey Henderson, APA’s executive vice-president of exploration, said the block reminds her team of conditions offshore Namibia and that its work with Eni will essentially be a “petroleum systems test.” Addressing the potential of GranMorgu—which APA and TotalEnergies teams have estimated has nearly 760 million bbl of reserves—and the goal of starting production in mid-2028, Christmann said 4 wells are being planned over the

Read More »

Energy Department Announces Fall 2026 SBIR/STTR Phase I Topics, Unlocking $200 Million for American Innovation

WASHINGTON—The U.S. Department of Energy (DOE) today announced the Fall 2026 Small Business Innovation Research (SBIR) and Small Business Technology Transfer (STTR) Phase I Topics, unlocking more than $200 million in federal funding to support American small businesses developing innovative technologies that strengthen U.S. energy and national security. The Phase I topics span grid innovation, nuclear detonation detection, cybersecurity, and other areas with strong commercial potential.  The Fall 2026 release marks a significant milestone for DOE’s restructured SBIR and STTR programs, now managed by DOE’s Office of Technology Commercialization (OTC). Through DOE’s Partnership Intermediary, ConnectWerx, the programs are streamlining management and delivery, reducing application burdens, and expanding access to funding opportunities for American small businesses.    The restructuring advances the Trump Administration’s priorities to strengthen American energy and national security, support U.S. small businesses, and accelerate the commercialization of technologies critical to maintaining U.S. technological leadership. By prioritizing projects with strong technical and commercial potential, DOE is helping move American innovation from the laboratory to the marketplace.  “Under President Trump’s leadership, we’ve fundamentally redesigned the SBIR/STTR programs from the ground up to make them more accessible, more dynamic, and much more productive,” said Anthony Pugliese, DOE Chief Commercialization Officer and Director of the Office of Technology Commercialization. “These changes will help us attract more American entrepreneurs and startups, maximize the impact of every federal dollar, and ultimately turn promising innovations into real-world solutions that strengthen American competitiveness.”  Phase I now serves as the entry point to the full SBIR/STTR funding pathway. Companies begin by submitting a pitch for a Phase I award to demonstrate the technical feasibility of their proposed innovations, with opportunities to secure follow-on funding in subsequent phases. Go/no-go decisions between phases assess technical progress and commercial potential before advancing to the next stage, ensuring federal resources are focused

Read More »

QatarEnergy continues Maydan Mahzam field redevelopment

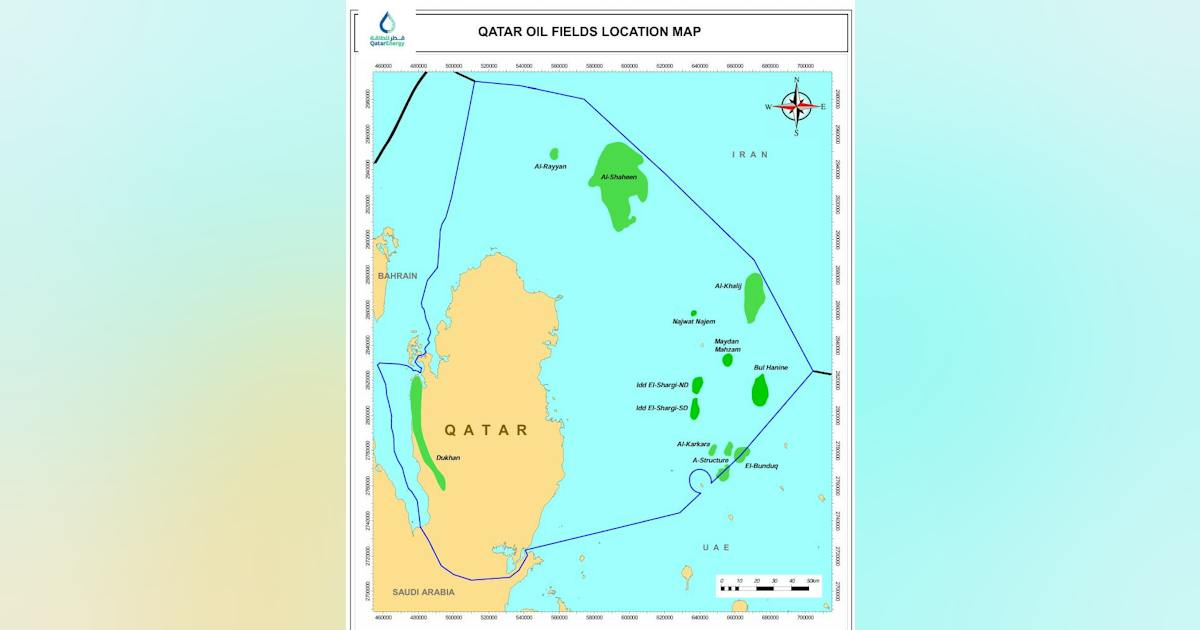
@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } QatarEnergy contractor PTSC Mechanical and Construction Ltd. Co. (PTSC M&C) has let a letter of award (LOA) to Aker Solutions for design work related to the redevelopment of Maydan Mahzam oil field offshore Qatar. The field lies, which started production in November 1965, lies about 100 km northeast of the Qatari coastline and 28 km southeast of Halul Island in water depths of about 40 m. QatarEnergy has been redeveloping the field to extend its operational life.  Aker Solutions will provide detailed design services for several offshore installations under PTSC M&C’s project scope, including three major topsides, four jackets, and brownfield tie-in. The work will be executed by Aker Solutions’ engineering teams in Kuala Lumpur, Malaysia, and Mumbai, India.

Read More »

US sanctions network supporting Iranian oil shipments

The US Department of the Treasury imposed new sanctions on Nov. 4 against an India-based maritime network accused of facilitating Iranian oil shipments through fraudulent vessel registrations and certifications, as Washington continued efforts to restrict Tehran’s petroleum revenues. The sanctions target Suniel Kumar Sharma, his wife Jaspreet Preeti Shahid, two other Indian nationals, and nine associated entities. According to the  Treasury, the network established unauthorized ship registries and maritime classification services that enabled sanctioned tankers transporting Iranian petroleum to operate under false flags. Treasury said some of the vessels supported by the network operated on behalf of Iran’s military and its proxies. Among the designated companies are India-based Oceaniek Technologies India and Singapore-based Eswatini Maritime Affairs and International Ship Registry Pte. Ltd. Treasury said the network provided false vessel registrations to several sanctioned tankers, including LATTAFA, BINARY STAR, and VERA. The action, taken under Executive Order 13902 as part of the administration’s Operation Economic Outcast campaign, also included a new Office of Foreign Assets Control (OFAC) advisory warning maritime operators about sanctions risks associated with falsely flagged vessels. The designations block assets of the sanctioned parties held in the US or under the control of US persons and generally prohibit US persons from conducting transactions involving their property. The measures could further complicate transportation and compliance arrangements for Iranian oil shipments, although their immediate impact on export volumes remains uncertain.

Read More »

DCF Global: Britain’s New Bargain With the AI Data Center Industry

The Global Perspective: A New Bargain for the AI Economy? Britain’s new Data Centre Covenant may ultimately prove important well beyond the United Kingdom. Governments across the world are attempting to reconcile the economic promise of AI infrastructure with the extraordinary physical requirements of building it. Electricity networks must accommodate loads measured in hundreds of megawatts. Utilities must plan transmission and generation investments years in advance. Communities are being asked to host facilities whose construction costs can run into billions, but whose permanent employment footprints may be relatively modest. At the same time, national governments increasingly view domestic computing capacity as a strategic asset. Britain is attempting to connect those issues within a single policy framework. Its approach differs in important respects from the fragmented regulatory environment in the United States, where utility commissions, state governments, local authorities, and regional grid operators exercise separate—and sometimes competing—powers over development. Nevertheless, the underlying questions are increasingly similar. In DCF’s October examination of Virginia’s changing data center policies, the industry’s largest established market was confronting new expectations concerning infrastructure costs, utility commitments, community impacts, and the conditions under which large facilities should receive development approval. Britain’s Covenant addresses comparable pressures through a more coordinated national initiative. It effectively proposes that preferential treatment for strategically important data center development should be accompanied by demonstrable public value. That is a meaningful evolution in the relationship between government and the industry. For years, data center investment announcements have emphasized capital expenditure, construction employment, technological leadership, and economic development. Those considerations remain important. But Britain’s emerging framework asks a more demanding set of questions: Can the project obtain real electricity capacity? Will it pay its fair share of infrastructure costs? Does it contribute to domestic capability? What obligations does it have to its host community? And can

Read More »

Don’t mention the data center: OpenAI calls them ‘compute campuses’ instead

Data centers’ increasing power consumption is straining the grid, with AI servers accounting for an ever larger share of that consumption, with further increases forecast. These demands are leading to a growing number of protests against the development of data centers, which could lead to construction delays. OpenAI claims that its Grid Protectors Program will meet some of those issues head-on by taking into account future capacity needs and working to make power flexibility a key element in data center, sorry, compute campus, design. The company said that the approach would differ, region by region. It has yet to finalize all the details of the scheme, but it hopes to head off some of the protests. It remains to be seen whether it has this effect. Google recently took the opposite approach to the peak consumption problem, proposing to pay people to turn off their appliances at times of high demand so that it can continue to power its data centers.

Read More »

Agentic AI boom expected to reshape CPU market

These activities include planning tasks, scheduling subtasks, calling external tools, managing interactions between multiple agents and evaluating results. Agents also rely on conventional computing resources to execute Python code, search databases, crawl websites and process information, according to TrendForce. As a result, the CPU is enjoying a new lease on life and becoming a more significant component of AI infrastructure rather than simply serving as a supporting processor for GPUs, according to TrendForce. TrendForce notes that traditional AI data centers have typically deployed approximately one CPU for every four to eight GPUs, reflecting the industry’s emphasis on accelerating computationally intensive AI workloads.

Read More »

DCF Poll: Does the Data Center Industry Need a Political Reset?

Matt Vincent is Editor in Chief of Data Center Frontier, where he leads editorial strategy and coverage focused on the infrastructure powering cloud computing, artificial intelligence, and the digital economy. A veteran B2B technology journalist with more than two decades of experience, Vincent specializes in the intersection of data centers, power, cooling, and emerging AI-era infrastructure. Since assuming the EIC role in 2023, he has helped guide Data Center Frontier’s coverage of the industry’s transition into the gigawatt-scale AI era, with a focus on hyperscale development, behind-the-meter power strategies, liquid cooling architectures, and the evolving energy demands of high-density compute, while working closely with the Digital Infrastructure Group at Endeavor Business Media to expand the brand’s analytical and multimedia footprint. Vincent also hosts The Data Center Frontier Show podcast, where he interviews industry leaders across hyperscale, colocation, utilities, and the data center supply chain to examine the technologies and business models reshaping digital infrastructure. Since its inception he serves as Head of Content for the Data Center Frontier Trends Summit. Before becoming Editor in Chief, he served in multiple senior editorial roles across Endeavor Business Media’s digital infrastructure portfolio, with coverage spanning data centers and hyperscale infrastructure, structured cabling and networking, telecom and datacom, IP physical security, and wireless and Pro AV markets. He began his career in 2005 within PennWell’s Advanced Technology Division and later held senior editorial positions supporting brands such as Cabling Installation & Maintenance, Lightwave Online, Broadband Technology Report, and Smart Buildings Technology. Vincent is a frequent moderator, interviewer, and keynote speaker at industry events including the HPC Forum, where he delivers forward-looking analysis on how AI and high-performance computing are reshaping digital infrastructure. He graduated with honors from Indiana University Bloomington with a B.A. in English Literature and Creative Writing and lives in southern New Hampshire with

Read More »

Arista posts record growth as AI networking supercycle accelerates

One of the core answers to that threat is the company’s Autonomous Virtual Assistant (AVA), which lets administrators ask it questions about network conditions and receive explanations, recommendations, and assistance diagnosing problems. “AVA is incredibly powerful. It seamlessly navigates networking and security infrastructure from campus to WAN, to data center, to cloud, continuously monitoring and troubleshooting, isolating root causes without manual labor-intensive tasks,” said Ken Duda, Arista co-founder, president, CTO & director. “The bad news, of course, is the massive challenge AI poses for us and our customers by discovering and exploiting security vulnerabilities. This threat landscape demands secure and robust networking. Over the past few months, we’ve been collaborating with Anthropic, Google, OpenAI, and many others to integrate new AI-enabled security capabilities from frontier models into our existing software security pipeline,” Duda said.

Read More »

AEP, Google Advance $4 Billion Fuel-Cell Project to Power Cheyenne Data Centers

A Power Commitment That Began Two Years Earlier Although Google’s participation was publicly identified in October 2026, the procurement strategy underlying the Cheyenne project dates to November 2024, when Bloom Energy announced an agreement with AEP covering up to 1 gigawatt of solid oxide fuel-cell equipment. As Data Center Frontier reported at the time, the agreement included an initial commitment to purchase 100 MW, with options for an additional 900 MW. The arrangement was intended to help AEP serve large commercial and industrial customers facing growing electricity requirements without waiting for the completion of conventional grid infrastructure upgrades. The relationship advanced in January 2026, when AEP disclosed in a regulatory filing that an unregulated subsidiary had committed approximately $2.65 billion to purchase a substantial portion of the fuel-cell capacity covered by its earlier option. The company also reported a 20-year agreement to sell the planned facility’s entire electricity output to an unidentified investment-grade customer, now confirmed as Google. The equipment purchase formed part of the project’s development history, rather than representing a separate $2.65 billion investment in addition to the $4 billion project announced in October. The scale of the investment is significant, but so is the transaction structure. Rather than requiring Google to own and operate the generation equipment directly, the arrangement places development and ownership responsibilities with an established energy company while providing the hyperscaler long-term access to the facility’s electricity output. For AEP, it also represents an opportunity to deploy capital in support of large-load customers beyond its traditional regulated utility territory. At approximately $4 billion for 702 MW, the project represents roughly $5.7 million per megawatt of planned generating capacity. That figure offers a measure of the investment’s capital intensity, although it is not directly comparable with the construction cost of a conventional gas-fired power plant

Read More »

Microsoft will invest $80B in AI data centers in fiscal 2025

And Microsoft isn’t the only one that is ramping up its investments into AI-enabled data centers. Rival cloud service providers are all investing in either upgrading or opening new data centers to capture a larger chunk of business from developers and users of large language models (LLMs).  In a report published in October 2024, Bloomberg Intelligence estimated that demand for generative AI would push Microsoft, AWS, Google, Oracle, Meta, and Apple would between them devote $200 billion to capex in 2025, up from $110 billion in 2023. Microsoft is one of the biggest spenders, followed closely by Google and AWS, Bloomberg Intelligence said. Its estimate of Microsoft’s capital spending on AI, at $62.4 billion for calendar 2025, is lower than Smith’s claim that the company will invest $80 billion in the fiscal year to June 30, 2025. Both figures, though, are way higher than Microsoft’s 2020 capital expenditure of “just” $17.6 billion. The majority of the increased spending is tied to cloud services and the expansion of AI infrastructure needed to provide compute capacity for OpenAI workloads. Separately, last October Amazon CEO Andy Jassy said his company planned total capex spend of $75 billion in 2024 and even more in 2025, with much of it going to AWS, its cloud computing division.

Read More »

John Deere unveils more autonomous farm machines to address skill labor shortage

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More Self-driving tractors might be the path to self-driving cars. John Deere has revealed a new line of autonomous machines and tech across agriculture, construction and commercial landscaping. The Moline, Illinois-based John Deere has been in business for 187 years, yet it’s been a regular as a non-tech company showing off technology at the big tech trade show in Las Vegas and is back at CES 2025 with more autonomous tractors and other vehicles. This is not something we usually cover, but John Deere has a lot of data that is interesting in the big picture of tech. The message from the company is that there aren’t enough skilled farm laborers to do the work that its customers need. It’s been a challenge for most of the last two decades, said Jahmy Hindman, CTO at John Deere, in a briefing. Much of the tech will come this fall and after that. He noted that the average farmer in the U.S. is over 58 and works 12 to 18 hours a day to grow food for us. And he said the American Farm Bureau Federation estimates there are roughly 2.4 million farm jobs that need to be filled annually; and the agricultural work force continues to shrink. (This is my hint to the anti-immigration crowd). John Deere’s autonomous 9RX Tractor. Farmers can oversee it using an app. While each of these industries experiences their own set of challenges, a commonality across all is skilled labor availability. In construction, about 80% percent of contractors struggle to find skilled labor. And in commercial landscaping, 86% of landscaping business owners can’t find labor to fill open positions, he said. “They have to figure out how to do

Read More »

2025 playbook for enterprise AI success, from agents to evals

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More 2025 is poised to be a pivotal year for enterprise AI. The past year has seen rapid innovation, and this year will see the same. This has made it more critical than ever to revisit your AI strategy to stay competitive and create value for your customers. From scaling AI agents to optimizing costs, here are the five critical areas enterprises should prioritize for their AI strategy this year. 1. Agents: the next generation of automation AI agents are no longer theoretical. In 2025, they’re indispensable tools for enterprises looking to streamline operations and enhance customer interactions. Unlike traditional software, agents powered by large language models (LLMs) can make nuanced decisions, navigate complex multi-step tasks, and integrate seamlessly with tools and APIs. At the start of 2024, agents were not ready for prime time, making frustrating mistakes like hallucinating URLs. They started getting better as frontier large language models themselves improved. “Let me put it this way,” said Sam Witteveen, cofounder of Red Dragon, a company that develops agents for companies, and that recently reviewed the 48 agents it built last year. “Interestingly, the ones that we built at the start of the year, a lot of those worked way better at the end of the year just because the models got better.” Witteveen shared this in the video podcast we filmed to discuss these five big trends in detail. Models are getting better and hallucinating less, and they’re also being trained to do agentic tasks. Another feature that the model providers are researching is a way to use the LLM as a judge, and as models get cheaper (something we’ll cover below), companies can use three or more models to

Read More »

OpenAI’s red teaming innovations define new essentials for security leaders in the AI era

Join our daily and weekly newsletters for the latest updates and exclusive content on industry-leading AI coverage. Learn More OpenAI has taken a more aggressive approach to red teaming than its AI competitors, demonstrating its security teams’ advanced capabilities in two areas: multi-step reinforcement and external red teaming. OpenAI recently released two papers that set a new competitive standard for improving the quality, reliability and safety of AI models in these two techniques and more. The first paper, “OpenAI’s Approach to External Red Teaming for AI Models and Systems,” reports that specialized teams outside the company have proven effective in uncovering vulnerabilities that might otherwise have made it into a released model because in-house testing techniques may have missed them. In the second paper, “Diverse and Effective Red Teaming with Auto-Generated Rewards and Multi-Step Reinforcement Learning,” OpenAI introduces an automated framework that relies on iterative reinforcement learning to generate a broad spectrum of novel, wide-ranging attacks. Going all-in on red teaming pays practical, competitive dividends It’s encouraging to see competitive intensity in red teaming growing among AI companies. When Anthropic released its AI red team guidelines in June of last year, it joined AI providers including Google, Microsoft, Nvidia, OpenAI, and even the U.S.’s National Institute of Standards and Technology (NIST), which all had released red teaming frameworks. Investing heavily in red teaming yields tangible benefits for security leaders in any organization. OpenAI’s paper on external red teaming provides a detailed analysis of how the company strives to create specialized external teams that include cybersecurity and subject matter experts. The goal is to see if knowledgeable external teams can defeat models’ security perimeters and find gaps in their security, biases and controls that prompt-based testing couldn’t find. What makes OpenAI’s recent papers noteworthy is how well they define using human-in-the-middle

Read More »