NVIDIA Opens More of the AI Factory Architecture
NVIDIA’s Ian Buck closed the opening keynote program with an extensive presentation covering Vera Rubin systems, open rack designs, networking, power delivery and AI factory software.
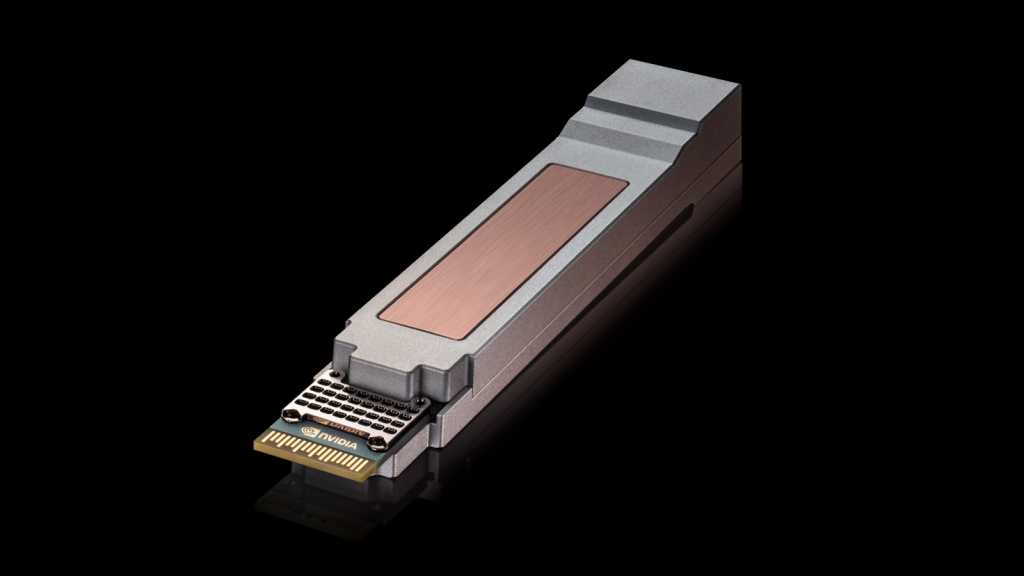
The company announced additional contributions to OCP based on its third-generation MGX 1.2 reference architecture.
The specification includes high-density liquid-cooled computing systems, improved cooling connections, standardized power interfaces and modular mechanical designs.
Buck emphasized that these developments are as much about manufacturing and serviceability as they are about computational performance.
He described how NVIDIA reduced the assembly time for a compute tray from approximately 90 minutes in the Grace Blackwell generation to roughly one minute for Vera Rubin through simplified mechanical construction and more automated assembly.
At the scale of thousands of racks, those manufacturing improvements can materially influence deployment schedules.
NVIDIA also previewed its next-generation Vera Rubin Ultra architecture, designed to interconnect 576 GPUs using an advanced NVLink fabric with co-packaged optics.
Open Data Center and Grid Resilience Specifications
For data center developers and operators, however, NVIDIA’s most consequential OCP contributions may lie outside the computing rack.
NVIDIA, AMD, Google and Meta have published an Open Data Center Specification, currently at version 0.7, intended to establish common design principles for AI factory facilities.
The specification addresses power architecture, cooling infrastructure and physical layout, helping equipment suppliers and developers coordinate around shared infrastructure requirements.
That shared facilities work unfolds alongside vendor-specific programs such as NVIDIA’s DSX Ready, which establishes qualification requirements for battery energy storage and liquid cooling equipment supporting its AI factory designs.
NVIDIA also joined Google, Meta and Microsoft in publishing an OCP Grid Resilience Specification addressing the behavior of large AI installations during grid disturbances.
The specification establishes expectations for facilities to remain connected, respond automatically to disturbances and recover toward normal operating load rapidly.
These initiatives reflect the growing importance of treating the AI factory as an integrated electrical and computational system.
Buck made the broader objective explicit:
“AI factories need to be part of the grid, not just consumers but contributors.”
He described a future in which computing workloads could respond dynamically to electrical-system conditions, shifting or reducing demand when necessary rather than behaving exclusively as inflexible loads.
NVIDIA also highlighted Visionbay’s planned K-1 AI factory architecture, which incorporates 800-volt DC power distribution and supporting power and thermal technologies from Vertiv.
Higher-voltage distribution promises reductions in copper requirements and conversion stages while supporting increasingly dense computing installations.
According to Buck, 800VDC approaches can reduce copper requirements by approximately 45% relative to certain conventional alternatives.
The significance extends beyond individual racks. As AI deployments approach hundreds of megawatts and eventually gigawatt scale, electrical distribution becomes a central constraint on facility design, deployment speed and operating efficiency.
Managing Power as a Computing Resource
NVIDIA also introduced another important dimension of AI factory optimization: using software to extract greater computing productivity from existing electrical infrastructure.
Buck discussed DSX MaxLPS, an approach to dynamic power management that allocates electrical capacity according to actual workload requirements rather than assuming every processor will continuously operate at its maximum rated draw.
The premise is straightforward. A data center may have a fixed utility allocation, but its computing equipment does not necessarily consume that full allocation at every moment.
That difference creates opportunities to accommodate additional workloads or computing systems, provided power use can be managed within electrical limits.
In a previously published joint evaluation with Nscale at its Iceland facility, NVIDIA demonstrated an increase from 140 to 192 managed GPUs within the same provisioned 264.4-kilowatt power budget.
The test produced approximately 49% higher aggregate inference throughput under the evaluated workload configuration.
Although the results are specific to the test environment and should not be assumed to apply uniformly across deployments, they point toward an important emerging strategy.
AI factory operators may be able to increase the productivity of constrained electrical capacity through coordinated workload scheduling, dynamic power management and more granular infrastructure controls.
That introduces another dimension to the industry’s familiar pursuit of improved power usage effectiveness.
The objective is not merely to reduce the energy consumed by supporting infrastructure. It is to increase useful computing output within the electrical capacity already available.
Optical Networking and an Open Transport Ecosystem
NVIDIA also detailed advances in its Spectrum-X networking architecture, including co-packaged optics and multiplane Ethernet switching.
The company said its new Spectrum-X Photonics Multiplane switches will improve energy efficiency and fault response while reducing the complexity of large AI fabrics.
Buck highlighted hardware-assisted fault detection capable of identifying network problems in approximately 2.6 milliseconds.
NVIDIA also announced expanded networking collaboration with Meta, including Spectrum-6 technology for the hyperscaler’s new liquid-cooled IceCube switching platform.
Separately, NVIDIA and Google announced work to support Google’s Falcon transport technology on future NVIDIA ConnectX-10 SuperNICs and BlueField DPUs.
These developments reinforce the expanding importance of common networking interfaces, even as major suppliers compete through different silicon, switching architectures and software implementations.
The industry’s increasingly complex AI networks cannot afford to be constrained by completely isolated hardware ecosystems.
The New Infrastructure Equation
The opening keynotes at OCP 2026 demonstrated how thoroughly AI is changing the engineering assumptions behind data center development.
The shift toward agentic workloads is creating new demand for CPU infrastructure alongside accelerating investment in GPUs and purpose-built silicon.
Gigawatt-scale projects are changing expectations for construction schedules, cooling, network architecture and operational reliability.
And electrical infrastructure, once largely treated as a supporting requirement, is becoming inseparable from computing-system design and software orchestration.
Yet the most revealing feature of the summit may be the degree to which competing technology companies are acknowledging a shared engineering problem.
AMD, NVIDIA, Arm, Broadcom, Meta and the broader OCP community continue to compete vigorously in processors, networking technology, software and integrated systems.
At the same time, the physical and operational complexity of AI infrastructure increasingly demands common interfaces, reusable designs and collaborative specifications.
That tension—between proprietary computing advantage and the need for open infrastructure—now sits at the center of the AI factory buildout.
For data center developers, operators and the suppliers supporting them, the implications extend far beyond the next generation of server hardware.
As AI computing expands from individual racks into geographically distributed, power-intensive infrastructure, the industry’s ability to deploy and operate capacity increasingly depends on how effectively the entire system is engineered together.
The next frontier of open computing is no longer confined to the server rack. It extends from the silicon to the utility grid.