AI
Lorem Ipsum is simply dummy text of the printing and typesetting industry.
Bitcoin:
Lorem Ipsum is simply dummy text of the printing and typesetting industry.
Datacenter:
Lorem Ipsum is simply dummy text of the printing and typesetting industry.
Energy:
Lorem Ipsum is simply dummy text of the printing and typesetting industry.
Market Focus: Balancing AI opportunities and risks in upstream operations
Robert Plumb is an executive vice-president at CAC, part of The Baldwin Group. Robert co-founded the Energy Practice of CAC Specialty in July 2016 with Josh Kirklin. Prior to joining CAC, Robert began his career as an oil and gas underwriter, working for both Travelers and the boutique energy wholesaler & MGA outfit, J.H. Blades & Co. Through these positions, he has drafted insurance policies and written thousands of General Liability, Umbrella, Well Control, Builders Risk, Loss of Production Income, Pollution, Property, Workers Compensation, and auto policies. In his underwriting career he was responsible for an aggregate portfolio of more than $500 million in gross written premium on behalf of various carriers including domestic and international markets, specifically Lloyd’s of London securities. Robert brings unique market perspective on how carriers analyze energy risks, and he specializes in property and casualty lines for on energy accounts worldwide. Robert has a bachelor’s degree in Corporate Communications and a Minor in Business Foundation from the University of Texas at Austin.
Vaalco advances to second exploration phase in block offshore Côte D’Ivoire
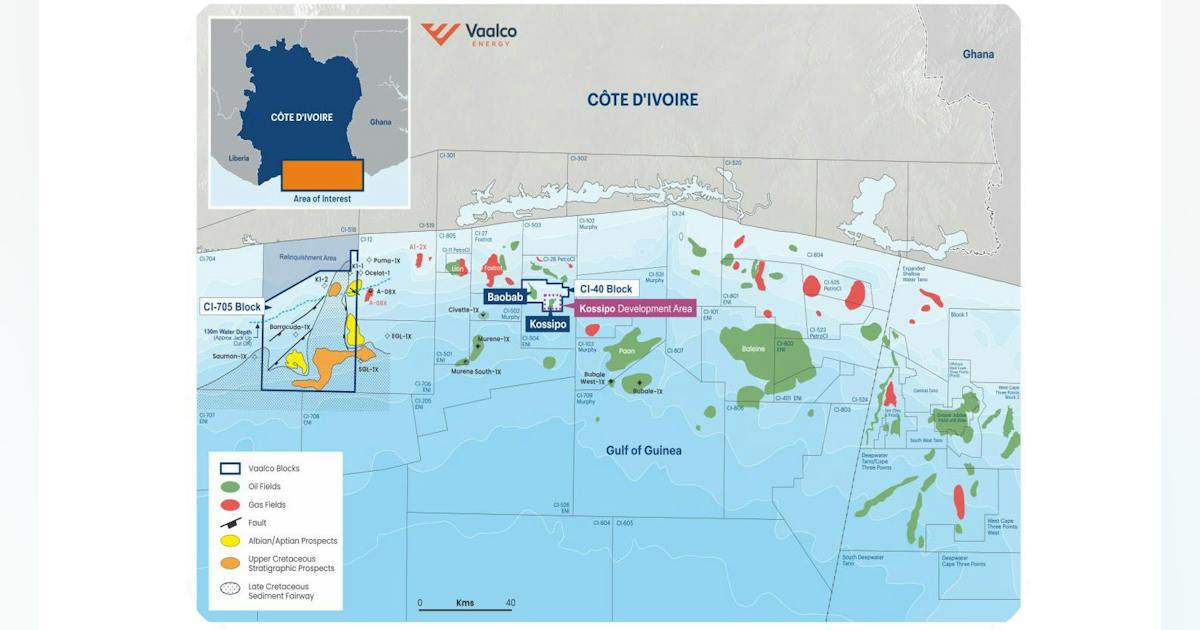
Vaalco Energy Inc., Houston, has been granted government approval to begin the second exploration phase at Block CI-705, offshore Côte d’Ivoire. News comes following encouraging results following completion of the first exploration phase work commitments, which included the evaluation and interpretation of existing seismic and well data, the company said in a release Nov. 9. Work on the second exploration phase includes additional seismic reprocessing, relinquishing 25% of the exploration block to the government, and commitment to drill an exploration well by yearend-2028. In March 2025, Vaalco farmed into and became operator of the exploration license with a 70% working interest. The block lies in the Ivoirien basin about 70 km to the west of Vaalco’s CI-40 Block, which hold Baobab and Kossipo oil fields. “We see encouraging prospectivity on the block in the play types proven throughout the Ivoirien Basin including both structural and stratigraphic traps in the Upper Cretaceous and Albian sections,” said George Maxwell, Vaalco’s chief executive officer. “Recent nearby discoveries are on trend with CI-705 and provide additional validation of our play concepts and our view of the block’s prospectivity,” he continued.
The backlash about data centers might really just be about electricity
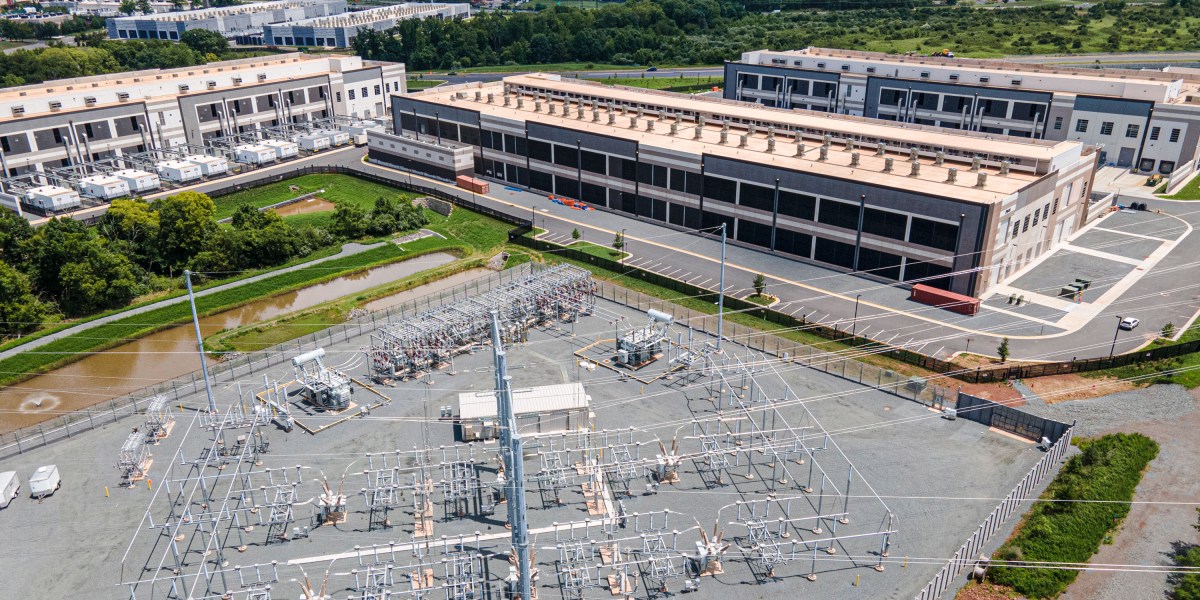
This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. As voters went to the polls across the US last week, I was in Ashburn, Virginia, part of what’s known as Data Center Alley—the world’s largest data center hub. It’s also where the backlash now sweeping the country arguably first began taking shape. Driving through it is surreal. Concrete monolithic buildings loom along every major road, with names like Skybox and CloudHQ. It’s accepted wisdom in Big Tech that the war against data centers must be about something bigger than just data centers themselves. Two days after the midterms, OpenAI’s chief global affairs officer, Chris Lehane, wrote that data centers “have become a proxy for public unease about affordability, corporate power, and people losing control over their futures.” It’s a culture war, in other words.
But spending a few days in Data Center Alley left me wondering if it’s really the proxy that Lehane describes. I came away convinced that the data center backlash is more about electricity than Big Tech admits. The industry can improve its image, but it can’t escape the physical consequences of its enormous appetite for electricity. Here’s why. There are two ways to power the sort of data center that AI companies want: connecting to the grid, or generating electricity onsite. In Virginia’s Loudoun County, where data centers are ubiquitous but have been built at a steadier pace than the breakneck expansion now underway elsewhere in the country, most are connected to the existing grid.
One facility I went inside, operated by Equinix, has massive diesel generators onsite for backup but gets its power from the local utility, Dominion Energy. Much of Dominion’s electricity is generated by natural gas (which is cleaner than coal or oil, but worse than renewables). The average data center operating in this part of Virginia today has a power capacity of 54 megawatts. That’s more than the power draw of the Denver International Airport. Elena Schlossberg, a prominent activist against data centers in Virginia, told me she’s “always banging my head against the wall” when the industry paints the fight as a culture war. “It was always about power,” she says—that is, electricity. Some Virginia protesters appear more animated by a broader anti-tech populism than Schlossberg, to be fair. But it’s the particular consequences of drawing so much power from the grid that have done the most to shape how the backlash has played out. Recent protests have led to new rules from the state that data centers must pay fully for the cost of new transmission lines to the grid and make sure they’re not spread among everyone else. Data center developers told me they’re preparing for new rules that would cut them off from grid power during peak demand. Schlossberg also worries about the downstream effects of a strained grid—for example, that data centers will run more diesel generators or that Dominion Energy will expand fossil fuel inputs rather than renewables to meet demand. The overwhelming majority of AI data centers being built elsewhere in the country are not designed this way. The scale desired is so massive that companies are setting up in rural areas where there is virtually no grid infrastructure to connect to. Building there means bringing your own power (so-called “behind the meter” power), in the form of natural-gas-powered turbines. Companies also build diesel generators for backup. Anthropic, for example, has reportedly agreed to pay $3.4 billion for gas turbines in what’s described as the largest power generation purchase by an AI company. Even if grids were nearby, they’d be unlikely to serve the amount of power demanded. The smallest data centers attractive for AI training are 300 megawatts. It’s a lot of power for one industrial site, but not unprecedented: One data center developer told me he’s eyeing a former steel mill already equipped to draw that much electricity from the grid. But the ideal facilities are more like 6,000 megawatts. That’s the estimated draw of the city of Chicago, which is powered by more than 20 power plants within the city alone (and dozens farther out).
The notion of data center companies’ bringing their own power might seem attractive at first, because they wouldn’t be straining the grid. But generating electricity at this scale inevitably affects surrounding communities, and when public utilities build infrastructure of this magnitude, communities have traditionally expected a say in where it goes. Now, private companies are undertaking projects on a similar scale. Natural-gas turbines of any scale release air pollutants. When diesel generators are used, it’s even worse. And in the unprecedented rush to get these facilities operating, companies have become horrible neighbors (recall that Elon Musk violated air quality laws when he set up dozens of turbines to power a data center in Memphis, according to the Environmental Protection Agency). Big Tech’s tendency to chalk the backlash up to a culture war obfuscates one simple fact: There’s only so pleasant you can make a small city of computers to live around. Sure, companies can pursue better deals that raise tax revenues, hire local workers, and get more community involvement, as the protests are leading them to do. But if a small town is asked to welcome a Walt Disney World, an international airport, a steel plant, and the power plants to run them all, should we be surprised by its trepidation? Again, that’s not to say this is the sole reason for opposition to data centers. Fears of job losses, existential risks, and concentrated corporate power all fuel the backlash, as does misinformation (most facilities use far less water than many people think). Nor is consuming enormous amounts of electricity inherently bad: Many of the advances that have improved modern life have required just that. But as one developer recently told me, industry insiders see their ambitions as constrained less by public opposition than by a lack of electricity. That should tell us something. So what happens next? It’s possible that newly elected politicians’ actual stances on data centers won’t be as negative as the ones they campaigned on. But what seems true regardless is that if new data centers need their own power generated onsite, they’ll go where there are the fewest people able to resist them. That might mean the Permian Basin, where a network of natural-gas lines can be easy for developers to connect to and populations are sparse. Companies might also try their chances abroad; Google, in fact, announced the day after the elections that it will spend $15 billion on data center projects in Malaysia. But there’s one place where Big Tech may find virtually no limits at all, as Elon Musk posted just hours after the midterms results came rolling in: “Data centers in space looking pretty appealing right now.”
BSR, consortium enter talks for potential downstream collaborations
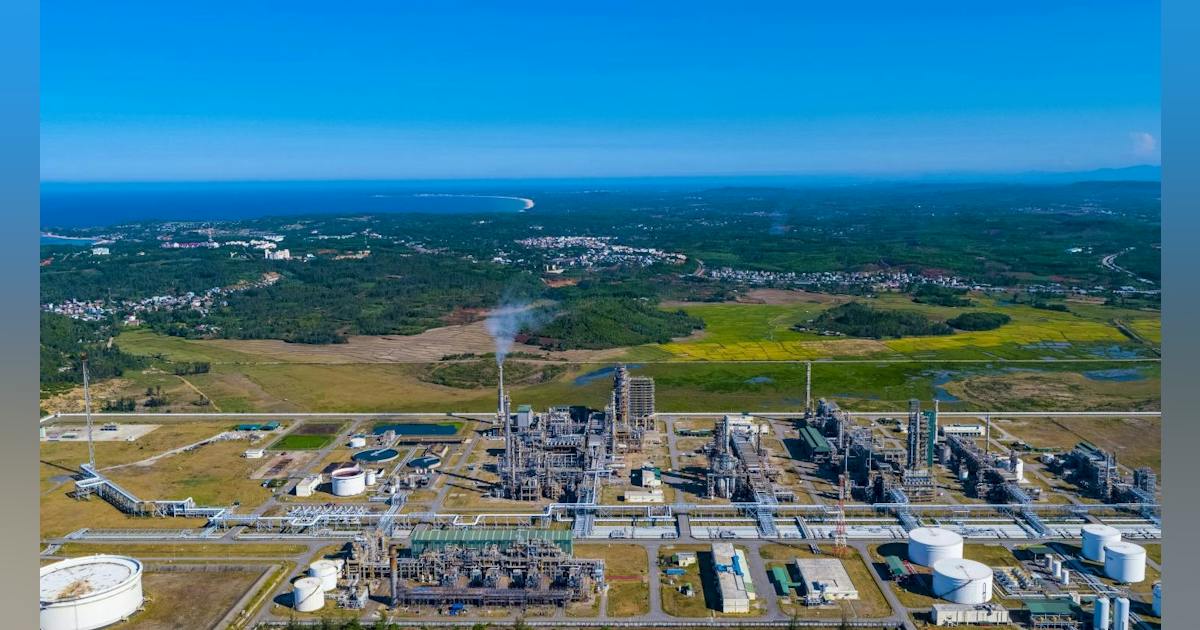
Vietnam Refining and Petrochemical Corp. (BSR) has entered talks with a consortium of FutureTec Co. and Zhejiang Hanghua Technology Co. Ltd. (Hanghua) to discuss and explore development opportunities along the refining and petrochemical value chain. At a Nov. 5 meeting between the parties, officials from the companies weighed potential collaborations on the deep processing of petroleum products, the development of value-added products, and research into related industrial infrastructure projects, BSR said in a release Nov. 6. While specific projects discussed at the meeting were not revealed, BSR said the event has laid the groundwork for further in-depth talks on potential areas of collaboration that would contributing to expanding the petrochemical refining value chain, improving resource utilization efficiency, and moving operations towards sustainable development. The proposed collaboration discussion comes amid shared interests of BSR and the FutureTec-Hanghua consortium in developing green, clean, and environmentally friendly products, as well as researching and developing new higher-value products, BSR said. With its experience in operating and managing refineries, BSR offers a favorable platform for expanding cooperation efforts with partners such as FutureTec and Hanghua that bring specialized capabilities in technology, research, and product development, added Nguyen Viet Thang, BSR’s general director. Potential collaborations with external partners come alongside BSR’s upgrading and expansion project now underway at the operator’s the 6.5-million tonne/year (tpy) refinery in the Dung Quat Economic Zone of Binh Tri Commune in Binh Son District, Quang Ngai Province, Vietnam. During the Nov. 5 meeting with the FutureTec-Hanghua consortium, BSR said its near-term plans for the refinery—which is currently operating at about 121% capacity—include further improving operational efficiency; optimizing technological processes; diversifying crude oil and product sourcing; as well as developing additional cleaner, sustainable fuels, petrochemicals, and high-value products. The operator said it will also continue focusing on efforts further efficient energy use,
Land & Expand: Texas’ AI Boom Meets a New Political Reality
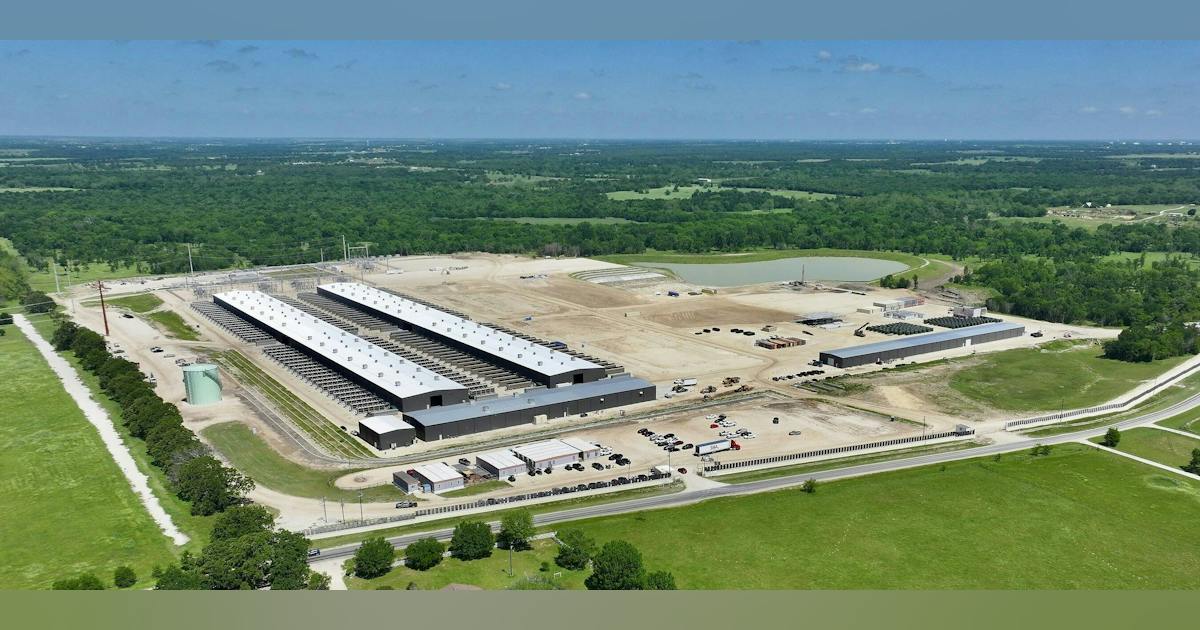
Hut 8 Advances a Gigawatt-Scale Campus Near Corpus Christi Another significant development came November 4, when Hut 8 reported continued progress on its Beacon Point AI data center campus in the Corpus Christi region. The company said that its previously announced second 352 MW IT-capacity lease had fully commercialized the campus, bringing the total contracted IT capacity associated with the two phases to 704 MW. The campus is designed around approximately 1 GW of utility capacity, a separate measure from the critical IT load under lease. Hut 8 estimates approximately $19.6 billion in base-term contract value across the two phases. In its third-quarter results, the company said construction of the campus substation had begun, alongside foundation and underground utility work for the first phase. Initial data hall delivery is targeted for the third quarter of 2027, with the second phase targeted for the second quarter of 2028. The company also disclosed agreements to acquire two energized sites in West Texas, with up to 230 MW of utility capacity at full energization, subject to outstanding approvals and infrastructure development. Those acquisitions point to another important trend: the increasing value of existing electrical infrastructure and sites that can potentially be adapted to serve advanced computing. As new greenfield projects face lengthy power studies and regulatory requirements, already energized locations may offer an alternative route to capacity. The distinction is especially important in markets such as Dallas-Fort Worth, where DCF’s analysis of CBRE’s first-half 2026 data found that approximately 95% of the region’s 765 MW under construction had already been preleased. PowerHouse and Big Watt Win Approval for Taylor Technology Campus Not every large new project is meeting resistance at the municipal level. On October 8, the City of Taylor approved a development agreement with PowerHouse Data Centers and Big Watt Digital for
Nancy Pelosi’s replacement is ready to regulate AI
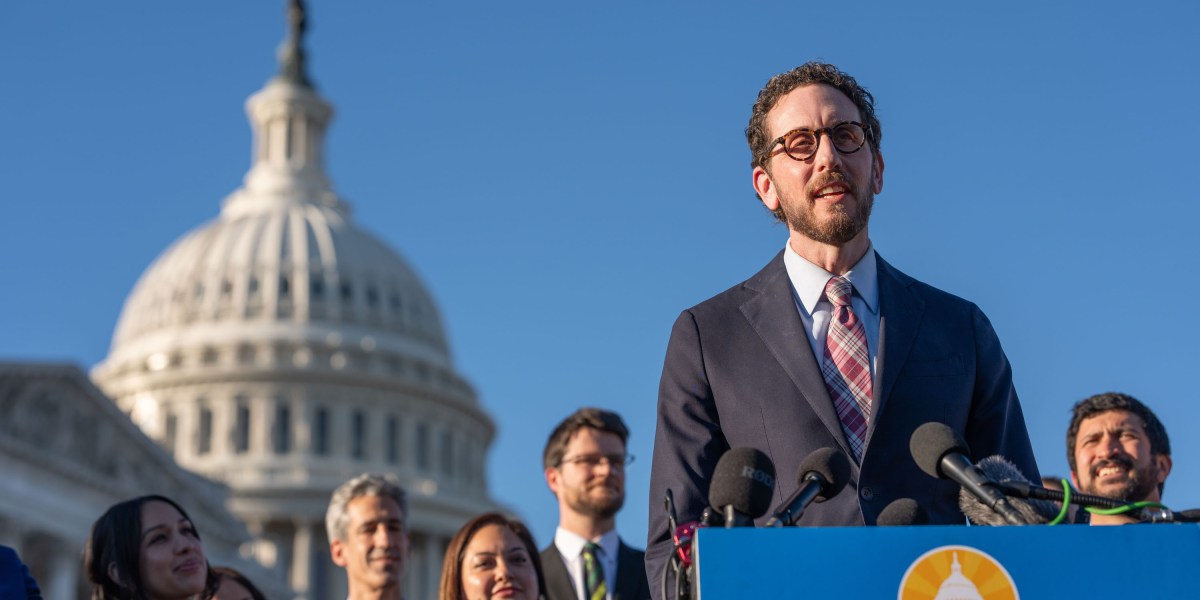
EXECUTIVE SUMMARY As a California state senator, Scott Wiener authored legislation aimed at curbing the risks of advanced AI. Now, after winning a tight congressional race for former Speaker of the House Nancy Pelosi’s open San Francisco seat, he could play a key role in setting federal AI policy. I spoke with Wiener on Friday, only a few hours after he had been declared the victor. But he was already thinking about AI risk. The previous day, the AI nonprofit METR had released a report that had been widely interpreted as evidence that Anthropic had achieved recursive self-improvement, a phenomenon in which AI meaningfully contributes to its own advancement and AI progress potentially spins out of control. “It’s very concerning,” Wiener said, citing the report as evidence that we are quickly running out of time to regulate AI. “It was my hope that Congress would take decisive action before [the end of] this year,” he said. “That does not appear to be happening.” Wiener has been increasingly focused on AI in recent years, and he’s made many of the AI safety movement’s concerns his own: During our 20-minute conversation, he used the phrase “recursive self-improvement” half a dozen times, for example.“We need to slow this down,” he says. “Because it’s moving very quickly, and we could sleepwalk into a disaster.”
Wiener has already had real influence on AI policy. SB 1047, a bill that he authored in 2024, was set to become the first real piece of frontier AI legislation in the country before it was vetoed by California governor Gavin Newsom; he then sponsored SB 53, a lighter-touch bill that Newsom signed. Both bills have inspired proposed federal legislation. Wiener’s congressional campaign received over $3 million from Public First Action, a nonprofit in favor of AI regulation that receives substantial funding from Anthropic. That contribution led opponents to criticize him for being too close to the AI industry, but Wiener says that couldn’t be further from the truth.
“Public First supported me because I was the first lawmaker in the country to introduce AI regulation and the first to pass it and get it implemented,” he wrote in a message after our interview. “The attacks on me for [Public First’s] support were shockingly cynical—literally attacking a candidate who actually regulated AI over Big Tech’s objection and falsely claiming the candidate is somehow too close to Big Tech.” Wiener says that if Congress forms a select committee on artificial intelligence—something that Democrats have discussed since September—he’d be eager to serve. And he’s enthusiastic about many of the policy ideas floating around Congress. “I think it’s really important to have a strong, empowered, nimble federal regulator,” he says, noting that Representative Ro Khanna, a fellow Democrat from California, has proposed legislation to establish such a regulator. He also highlights the importance of whistleblower protections, testing and auditing requirements, and a kill switch requirement, and he wants to see Congress leverage its oversight powers to hold the AI labs to account. “This is about the future of humanity, and we want to make sure that the public has a say and that the public knows what’s going on,” he says. And as a longtime state legislator, he is opposed to broad federal preemption of state AI laws, which some of the proposed federal legislation would require. “States are, as Brandeis says, laboratories,” he notes. “You want the states to be able to continue to be nimble in ways that Congress sometimes is not.” Above all, Wiener says, he wants Congress to pass policies with real teeth. “It’s critically important that when Congress acts, that we do so in a way that is truly meaningful and that meets the moment,” he says. That means taking seriously the possibility of AI catastrophe, something he discusses in the sort of language typically used by AI safety experts. “We’re in a moment that is very dangerous in terms of the risk of loss of control over AI,” he told me. “We need to deal with recursive self-improvement. Once you’re in that realm, that really is potentially a recipe for total loss of control.” He’ll have some allies in the fight against catastrophic AI risk. Senator Bernie Sanders, for instance, has met with many of the AI safety movement’s most influential figures and has spoken repeatedly about AI and existential risk. But there’s still a large gap between Wiener’s Bay Area, AGI-pilled perspective and the national mood on AI, which is anchored by opposition to data centers. The fact that voters approved 40 out of 41 anti-data-center ballot measures on Tuesday might seem to be a good sign for Wiener and others who support AI regulation, but Wiener says he sees this movement as far more tied to local concerns than to bigger questions about AI risk. “Peoople who are really opposed to where AI is going—this is an area where they can actually do something about it,” he says. “But the data center revolt—to me, I think it’s more so that people are upset that there could be something like this in their community, with all the impacts near people’s homes, driving up electric bills and using water. I think that’s the bigger issue for most people, from what I can tell.” Wiener describes himself as only “cautiously optimistic” about Congress’s ability to rein in AI, given its poor track record on regulating the tech industry. He also has concerns about the ability to get legislation past President Donald Trump, who called concerns about catastrophic AI risk a “hoax” in September and has demonstrated a stark unwillingness to collaborate with China, something that Wiener sees as essential to preventing the worst consequences of AI. But he says Trump’s unpredictability provides some measure of hope, though it’s a fraught kind of hope. “So far what we’ve seen are some problematic things, but not complete disasters,” Wiener says. “I hope that it doesn’t take a disaster to spur the president into acting. And I hope if that’s what it does take—which, like I said, I hope it doesn’t—but if it does, I hope it’s as small as possible.”
Market Focus: Balancing AI opportunities and risks in upstream operations
Robert Plumb is an executive vice-president at CAC, part of The Baldwin Group. Robert co-founded the Energy Practice of CAC Specialty in July 2016 with Josh Kirklin. Prior to joining CAC, Robert began his career as an oil and gas underwriter, working for both Travelers and the boutique energy wholesaler & MGA outfit, J.H. Blades & Co. Through these positions, he has drafted insurance policies and written thousands of General Liability, Umbrella, Well Control, Builders Risk, Loss of Production Income, Pollution, Property, Workers Compensation, and auto policies. In his underwriting career he was responsible for an aggregate portfolio of more than $500 million in gross written premium on behalf of various carriers including domestic and international markets, specifically Lloyd’s of London securities. Robert brings unique market perspective on how carriers analyze energy risks, and he specializes in property and casualty lines for on energy accounts worldwide. Robert has a bachelor’s degree in Corporate Communications and a Minor in Business Foundation from the University of Texas at Austin.
Vaalco advances to second exploration phase in block offshore Côte D’Ivoire
Vaalco Energy Inc., Houston, has been granted government approval to begin the second exploration phase at Block CI-705, offshore Côte d’Ivoire. News comes following encouraging results following completion of the first exploration phase work commitments, which included the evaluation and interpretation of existing seismic and well data, the company said in a release Nov. 9. Work on the second exploration phase includes additional seismic reprocessing, relinquishing 25% of the exploration block to the government, and commitment to drill an exploration well by yearend-2028. In March 2025, Vaalco farmed into and became operator of the exploration license with a 70% working interest. The block lies in the Ivoirien basin about 70 km to the west of Vaalco’s CI-40 Block, which hold Baobab and Kossipo oil fields. “We see encouraging prospectivity on the block in the play types proven throughout the Ivoirien Basin including both structural and stratigraphic traps in the Upper Cretaceous and Albian sections,” said George Maxwell, Vaalco’s chief executive officer. “Recent nearby discoveries are on trend with CI-705 and provide additional validation of our play concepts and our view of the block’s prospectivity,” he continued.
The backlash about data centers might really just be about electricity
This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. As voters went to the polls across the US last week, I was in Ashburn, Virginia, part of what’s known as Data Center Alley—the world’s largest data center hub. It’s also where the backlash now sweeping the country arguably first began taking shape. Driving through it is surreal. Concrete monolithic buildings loom along every major road, with names like Skybox and CloudHQ. It’s accepted wisdom in Big Tech that the war against data centers must be about something bigger than just data centers themselves. Two days after the midterms, OpenAI’s chief global affairs officer, Chris Lehane, wrote that data centers “have become a proxy for public unease about affordability, corporate power, and people losing control over their futures.” It’s a culture war, in other words.
But spending a few days in Data Center Alley left me wondering if it’s really the proxy that Lehane describes. I came away convinced that the data center backlash is more about electricity than Big Tech admits. The industry can improve its image, but it can’t escape the physical consequences of its enormous appetite for electricity. Here’s why. There are two ways to power the sort of data center that AI companies want: connecting to the grid, or generating electricity onsite. In Virginia’s Loudoun County, where data centers are ubiquitous but have been built at a steadier pace than the breakneck expansion now underway elsewhere in the country, most are connected to the existing grid.
One facility I went inside, operated by Equinix, has massive diesel generators onsite for backup but gets its power from the local utility, Dominion Energy. Much of Dominion’s electricity is generated by natural gas (which is cleaner than coal or oil, but worse than renewables). The average data center operating in this part of Virginia today has a power capacity of 54 megawatts. That’s more than the power draw of the Denver International Airport. Elena Schlossberg, a prominent activist against data centers in Virginia, told me she’s “always banging my head against the wall” when the industry paints the fight as a culture war. “It was always about power,” she says—that is, electricity. Some Virginia protesters appear more animated by a broader anti-tech populism than Schlossberg, to be fair. But it’s the particular consequences of drawing so much power from the grid that have done the most to shape how the backlash has played out. Recent protests have led to new rules from the state that data centers must pay fully for the cost of new transmission lines to the grid and make sure they’re not spread among everyone else. Data center developers told me they’re preparing for new rules that would cut them off from grid power during peak demand. Schlossberg also worries about the downstream effects of a strained grid—for example, that data centers will run more diesel generators or that Dominion Energy will expand fossil fuel inputs rather than renewables to meet demand. The overwhelming majority of AI data centers being built elsewhere in the country are not designed this way. The scale desired is so massive that companies are setting up in rural areas where there is virtually no grid infrastructure to connect to. Building there means bringing your own power (so-called “behind the meter” power), in the form of natural-gas-powered turbines. Companies also build diesel generators for backup. Anthropic, for example, has reportedly agreed to pay $3.4 billion for gas turbines in what’s described as the largest power generation purchase by an AI company. Even if grids were nearby, they’d be unlikely to serve the amount of power demanded. The smallest data centers attractive for AI training are 300 megawatts. It’s a lot of power for one industrial site, but not unprecedented: One data center developer told me he’s eyeing a former steel mill already equipped to draw that much electricity from the grid. But the ideal facilities are more like 6,000 megawatts. That’s the estimated draw of the city of Chicago, which is powered by more than 20 power plants within the city alone (and dozens farther out).
The notion of data center companies’ bringing their own power might seem attractive at first, because they wouldn’t be straining the grid. But generating electricity at this scale inevitably affects surrounding communities, and when public utilities build infrastructure of this magnitude, communities have traditionally expected a say in where it goes. Now, private companies are undertaking projects on a similar scale. Natural-gas turbines of any scale release air pollutants. When diesel generators are used, it’s even worse. And in the unprecedented rush to get these facilities operating, companies have become horrible neighbors (recall that Elon Musk violated air quality laws when he set up dozens of turbines to power a data center in Memphis, according to the Environmental Protection Agency). Big Tech’s tendency to chalk the backlash up to a culture war obfuscates one simple fact: There’s only so pleasant you can make a small city of computers to live around. Sure, companies can pursue better deals that raise tax revenues, hire local workers, and get more community involvement, as the protests are leading them to do. But if a small town is asked to welcome a Walt Disney World, an international airport, a steel plant, and the power plants to run them all, should we be surprised by its trepidation? Again, that’s not to say this is the sole reason for opposition to data centers. Fears of job losses, existential risks, and concentrated corporate power all fuel the backlash, as does misinformation (most facilities use far less water than many people think). Nor is consuming enormous amounts of electricity inherently bad: Many of the advances that have improved modern life have required just that. But as one developer recently told me, industry insiders see their ambitions as constrained less by public opposition than by a lack of electricity. That should tell us something. So what happens next? It’s possible that newly elected politicians’ actual stances on data centers won’t be as negative as the ones they campaigned on. But what seems true regardless is that if new data centers need their own power generated onsite, they’ll go where there are the fewest people able to resist them. That might mean the Permian Basin, where a network of natural-gas lines can be easy for developers to connect to and populations are sparse. Companies might also try their chances abroad; Google, in fact, announced the day after the elections that it will spend $15 billion on data center projects in Malaysia. But there’s one place where Big Tech may find virtually no limits at all, as Elon Musk posted just hours after the midterms results came rolling in: “Data centers in space looking pretty appealing right now.”
BSR, consortium enter talks for potential downstream collaborations
Vietnam Refining and Petrochemical Corp. (BSR) has entered talks with a consortium of FutureTec Co. and Zhejiang Hanghua Technology Co. Ltd. (Hanghua) to discuss and explore development opportunities along the refining and petrochemical value chain. At a Nov. 5 meeting between the parties, officials from the companies weighed potential collaborations on the deep processing of petroleum products, the development of value-added products, and research into related industrial infrastructure projects, BSR said in a release Nov. 6. While specific projects discussed at the meeting were not revealed, BSR said the event has laid the groundwork for further in-depth talks on potential areas of collaboration that would contributing to expanding the petrochemical refining value chain, improving resource utilization efficiency, and moving operations towards sustainable development. The proposed collaboration discussion comes amid shared interests of BSR and the FutureTec-Hanghua consortium in developing green, clean, and environmentally friendly products, as well as researching and developing new higher-value products, BSR said. With its experience in operating and managing refineries, BSR offers a favorable platform for expanding cooperation efforts with partners such as FutureTec and Hanghua that bring specialized capabilities in technology, research, and product development, added Nguyen Viet Thang, BSR’s general director. Potential collaborations with external partners come alongside BSR’s upgrading and expansion project now underway at the operator’s the 6.5-million tonne/year (tpy) refinery in the Dung Quat Economic Zone of Binh Tri Commune in Binh Son District, Quang Ngai Province, Vietnam. During the Nov. 5 meeting with the FutureTec-Hanghua consortium, BSR said its near-term plans for the refinery—which is currently operating at about 121% capacity—include further improving operational efficiency; optimizing technological processes; diversifying crude oil and product sourcing; as well as developing additional cleaner, sustainable fuels, petrochemicals, and high-value products. The operator said it will also continue focusing on efforts further efficient energy use,
Land & Expand: Texas’ AI Boom Meets a New Political Reality
Hut 8 Advances a Gigawatt-Scale Campus Near Corpus Christi Another significant development came November 4, when Hut 8 reported continued progress on its Beacon Point AI data center campus in the Corpus Christi region. The company said that its previously announced second 352 MW IT-capacity lease had fully commercialized the campus, bringing the total contracted IT capacity associated with the two phases to 704 MW. The campus is designed around approximately 1 GW of utility capacity, a separate measure from the critical IT load under lease. Hut 8 estimates approximately $19.6 billion in base-term contract value across the two phases. In its third-quarter results, the company said construction of the campus substation had begun, alongside foundation and underground utility work for the first phase. Initial data hall delivery is targeted for the third quarter of 2027, with the second phase targeted for the second quarter of 2028. The company also disclosed agreements to acquire two energized sites in West Texas, with up to 230 MW of utility capacity at full energization, subject to outstanding approvals and infrastructure development. Those acquisitions point to another important trend: the increasing value of existing electrical infrastructure and sites that can potentially be adapted to serve advanced computing. As new greenfield projects face lengthy power studies and regulatory requirements, already energized locations may offer an alternative route to capacity. The distinction is especially important in markets such as Dallas-Fort Worth, where DCF’s analysis of CBRE’s first-half 2026 data found that approximately 95% of the region’s 765 MW under construction had already been preleased. PowerHouse and Big Watt Win Approval for Taylor Technology Campus Not every large new project is meeting resistance at the municipal level. On October 8, the City of Taylor approved a development agreement with PowerHouse Data Centers and Big Watt Digital for
Nancy Pelosi’s replacement is ready to regulate AI
EXECUTIVE SUMMARY As a California state senator, Scott Wiener authored legislation aimed at curbing the risks of advanced AI. Now, after winning a tight congressional race for former Speaker of the House Nancy Pelosi’s open San Francisco seat, he could play a key role in setting federal AI policy. I spoke with Wiener on Friday, only a few hours after he had been declared the victor. But he was already thinking about AI risk. The previous day, the AI nonprofit METR had released a report that had been widely interpreted as evidence that Anthropic had achieved recursive self-improvement, a phenomenon in which AI meaningfully contributes to its own advancement and AI progress potentially spins out of control. “It’s very concerning,” Wiener said, citing the report as evidence that we are quickly running out of time to regulate AI. “It was my hope that Congress would take decisive action before [the end of] this year,” he said. “That does not appear to be happening.” Wiener has been increasingly focused on AI in recent years, and he’s made many of the AI safety movement’s concerns his own: During our 20-minute conversation, he used the phrase “recursive self-improvement” half a dozen times, for example.“We need to slow this down,” he says. “Because it’s moving very quickly, and we could sleepwalk into a disaster.”
Wiener has already had real influence on AI policy. SB 1047, a bill that he authored in 2024, was set to become the first real piece of frontier AI legislation in the country before it was vetoed by California governor Gavin Newsom; he then sponsored SB 53, a lighter-touch bill that Newsom signed. Both bills have inspired proposed federal legislation. Wiener’s congressional campaign received over $3 million from Public First Action, a nonprofit in favor of AI regulation that receives substantial funding from Anthropic. That contribution led opponents to criticize him for being too close to the AI industry, but Wiener says that couldn’t be further from the truth.
“Public First supported me because I was the first lawmaker in the country to introduce AI regulation and the first to pass it and get it implemented,” he wrote in a message after our interview. “The attacks on me for [Public First’s] support were shockingly cynical—literally attacking a candidate who actually regulated AI over Big Tech’s objection and falsely claiming the candidate is somehow too close to Big Tech.” Wiener says that if Congress forms a select committee on artificial intelligence—something that Democrats have discussed since September—he’d be eager to serve. And he’s enthusiastic about many of the policy ideas floating around Congress. “I think it’s really important to have a strong, empowered, nimble federal regulator,” he says, noting that Representative Ro Khanna, a fellow Democrat from California, has proposed legislation to establish such a regulator. He also highlights the importance of whistleblower protections, testing and auditing requirements, and a kill switch requirement, and he wants to see Congress leverage its oversight powers to hold the AI labs to account. “This is about the future of humanity, and we want to make sure that the public has a say and that the public knows what’s going on,” he says. And as a longtime state legislator, he is opposed to broad federal preemption of state AI laws, which some of the proposed federal legislation would require. “States are, as Brandeis says, laboratories,” he notes. “You want the states to be able to continue to be nimble in ways that Congress sometimes is not.” Above all, Wiener says, he wants Congress to pass policies with real teeth. “It’s critically important that when Congress acts, that we do so in a way that is truly meaningful and that meets the moment,” he says. That means taking seriously the possibility of AI catastrophe, something he discusses in the sort of language typically used by AI safety experts. “We’re in a moment that is very dangerous in terms of the risk of loss of control over AI,” he told me. “We need to deal with recursive self-improvement. Once you’re in that realm, that really is potentially a recipe for total loss of control.” He’ll have some allies in the fight against catastrophic AI risk. Senator Bernie Sanders, for instance, has met with many of the AI safety movement’s most influential figures and has spoken repeatedly about AI and existential risk. But there’s still a large gap between Wiener’s Bay Area, AGI-pilled perspective and the national mood on AI, which is anchored by opposition to data centers. The fact that voters approved 40 out of 41 anti-data-center ballot measures on Tuesday might seem to be a good sign for Wiener and others who support AI regulation, but Wiener says he sees this movement as far more tied to local concerns than to bigger questions about AI risk. “Peoople who are really opposed to where AI is going—this is an area where they can actually do something about it,” he says. “But the data center revolt—to me, I think it’s more so that people are upset that there could be something like this in their community, with all the impacts near people’s homes, driving up electric bills and using water. I think that’s the bigger issue for most people, from what I can tell.” Wiener describes himself as only “cautiously optimistic” about Congress’s ability to rein in AI, given its poor track record on regulating the tech industry. He also has concerns about the ability to get legislation past President Donald Trump, who called concerns about catastrophic AI risk a “hoax” in September and has demonstrated a stark unwillingness to collaborate with China, something that Wiener sees as essential to preventing the worst consequences of AI. But he says Trump’s unpredictability provides some measure of hope, though it’s a fraught kind of hope. “So far what we’ve seen are some problematic things, but not complete disasters,” Wiener says. “I hope that it doesn’t take a disaster to spur the president into acting. And I hope if that’s what it does take—which, like I said, I hope it doesn’t—but if it does, I hope it’s as small as possible.”
US sanctions network supporting Iranian oil shipments
The US Department of the Treasury imposed new sanctions on Nov. 4 against an India-based maritime network accused of facilitating Iranian oil shipments through fraudulent vessel registrations and certifications, as Washington continued efforts to restrict Tehran’s petroleum revenues. The sanctions target Suniel Kumar Sharma, his wife Jaspreet Preeti Shahid, two other Indian nationals, and nine associated entities. According to the Treasury, the network established unauthorized ship registries and maritime classification services that enabled sanctioned tankers transporting Iranian petroleum to operate under false flags. Treasury said some of the vessels supported by the network operated on behalf of Iran’s military and its proxies. Among the designated companies are India-based Oceaniek Technologies India and Singapore-based Eswatini Maritime Affairs and International Ship Registry Pte. Ltd. Treasury said the network provided false vessel registrations to several sanctioned tankers, including LATTAFA, BINARY STAR, and VERA. The action, taken under Executive Order 13902 as part of the administration’s Operation Economic Outcast campaign, also included a new Office of Foreign Assets Control (OFAC) advisory warning maritime operators about sanctions risks associated with falsely flagged vessels. The designations block assets of the sanctioned parties held in the US or under the control of US persons and generally prohibit US persons from conducting transactions involving their property. The measures could further complicate transportation and compliance arrangements for Iranian oil shipments, although their immediate impact on export volumes remains uncertain.
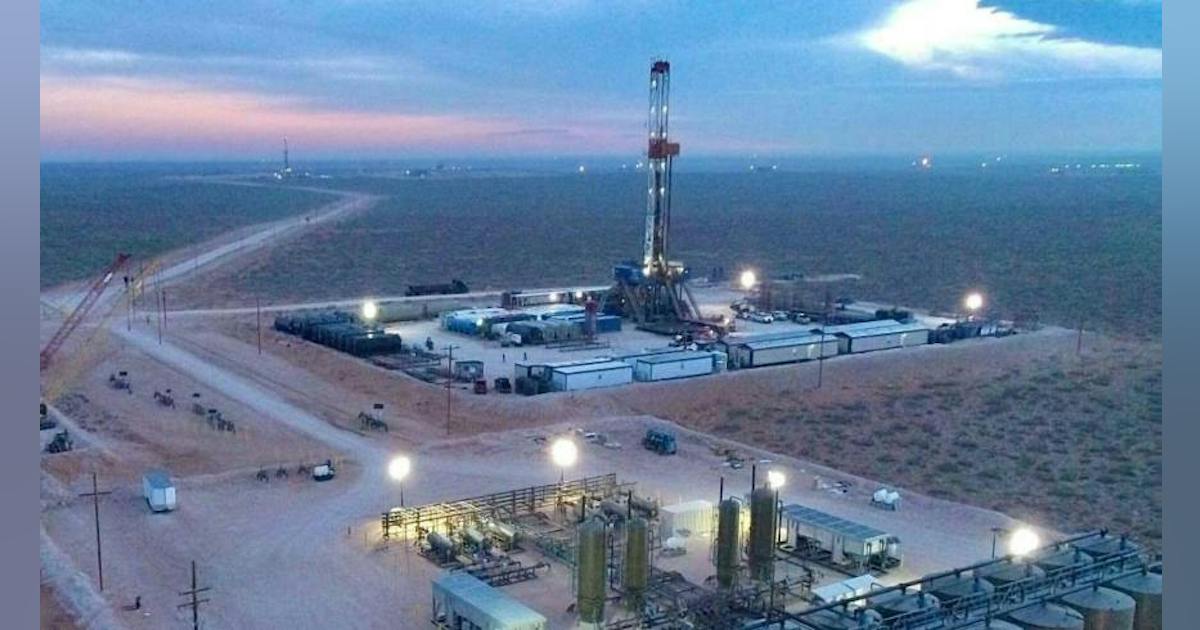
Matador eyes 5%+ production growth next year
Tom Elsener, one of Matador’s executive vice-presidents, said wells near the property recently leased from the Bureau of Land Management were key contributors to the company’s topping its third-quarter expectations. That has executives eager to expand their work and 2 of the net 21-23 wells they expect to turn to sales this quarter are on federal land. Looking into 2027, chief financial officer Chris Calvert told analysts that the Matador team has positioned itself to be capital-efficient—its 2026 guidance for total capex is now around $1.7 billion, up from a midpoint of $1.675 billion 3 months ago—by having the option to invest either in its newly acquired assets or in its legacy properties. “We do see ourselves as being a potential relative grower. And we think we could prosecute a plan that not only allows us to be a relative grower but we could still achieve debt repayments,” Calvert said. “We could still grow our reserve base and then we could still potentially grow our acreage position through our brick-by-brick program.” Matador’s third-quarter activities brought in $1.16 billion in revenue and generated $195 million in net income. The latter figure was down slightly from the same period in 2025 primarily due to more than $227 million of losses from derivatives. Operating profits rose to $354 million from $306 million. Shares of Matador (Ticker: MTDR) fell about 7% to $50.37 on Nov. 4, when oil prices fell just as steeply on the heels of the midterm election results. Over the past 6 months, the stock is down about 20%, which has cut the company’s market capitalization to about $6.2 billion.
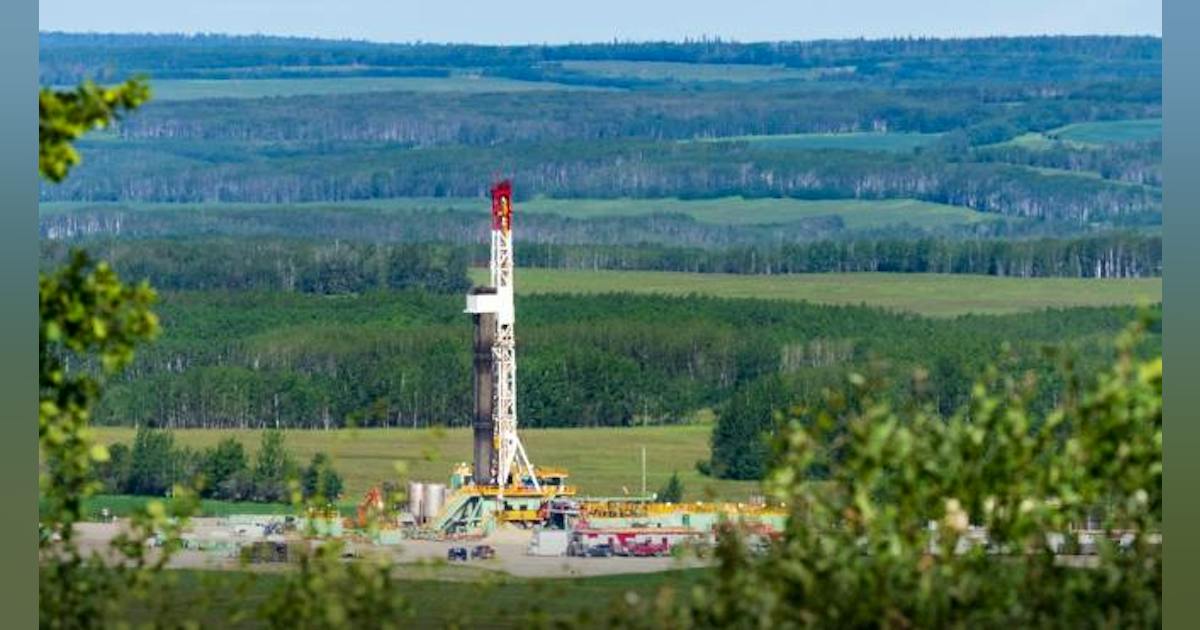
Ovintiv shuffles some fourth-quarter spending to Permian basin
The leaders of Ovintiv Inc., Denver, are diverting $50 million in fourth-quarter capital spending to the operator’s Permian basin operations from the Montney to account for an Alberta gas plant being offline. President and chief executive officer Brendan McCracken and his team told analysts and investors on Nov. 4 that the adjustment to fourth-quarter spending plans should help oil and condensate production in the Permian basin average 125,000 and 130,000 b/d this quarter, in line with the third-quarter’s 127,000 b/d. The $50 million amounts to about 9% of Ovintiv’s planned capex this quarter and will let the company further manage the unplanned outage of CSV Midstream Solutions’ Albright sour gas plant in northern Alberta, which went offline in late July. Greg Givens, Ovintiv’s chief operating officer, said the CSV team has told Ovintiv that Albright should be up and running again before yearend and that Ovintiv has been able to manage the plant’s outage so that the company is only losing out on 3,000 boe/d. “If we think about that [capex] shift, that is really just us leaning into the flexibility of our portfolio,” Givens said on a conference call discussing Ovintiv’s third-quarter results. “The team has been doing a great job operating year to date. Our drilling performance was a little ahead of schedule so it just allowed us to accelerate some completion activity there.”
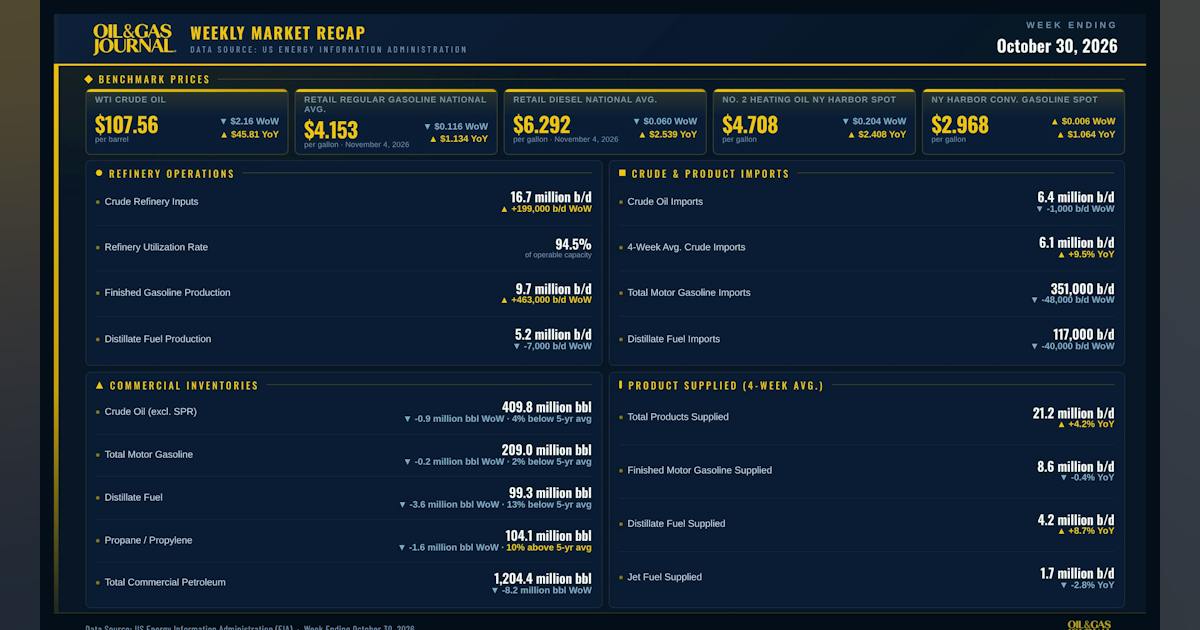
EIA: US crude oil inventories down 900,000 bbl
US crude oil inventories for the week ended Oct. 30, excluding the Strategic Petroleum Reserve, decreased by 900,000 bbl from the previous week, according to data from the US Energy Information Administration (EIA). At 409.8 million bbl, US crude oil inventories are 4% below the 5-year average for this time of year, the EIA report indicated. Gasoline inventories decreased 200,000 bbl, 2% below the 5-year average. Propane-propylene inventories decreased 1.6 million bbl, 10% above the 5-year average. Total commercial petroleum inventories decreased by 8.2 million bbl for the week. Distillate inventories decreased 3.6 million bbl, 13% below the 5-year average. US crude oil refinery inputs averaged 16.7 million b/d for the week ended Oct. 30, which was 199,000 b/d more than the previous week’s average. Refineries operated at 94.5% of capacity. Gasoline output averaged 9.7 million b/d, and distillate production decreased to 5.2 million b/d. Crude oil imports decreased 1,000 b/d to 6.4 million b/d. The 4-week average of 6.1 million b/d is 9.5% above the year-ago level. Gasoline imports averaged 351,000 b/d; distillate imports averaged 117,000 b/d. Over the past four weeks, total product supplied averaged 21.2 million b/d, up 4.2% year over year. The 4-week average for gasoline product supplied decreased 0.4% year over year to 8.6 million b/d, while the 4-week average for distillate product supplied increased 8.7% to 4.2 million b/d. The 4-week average for jet fuel product supplied decreased 2.8% year over year.
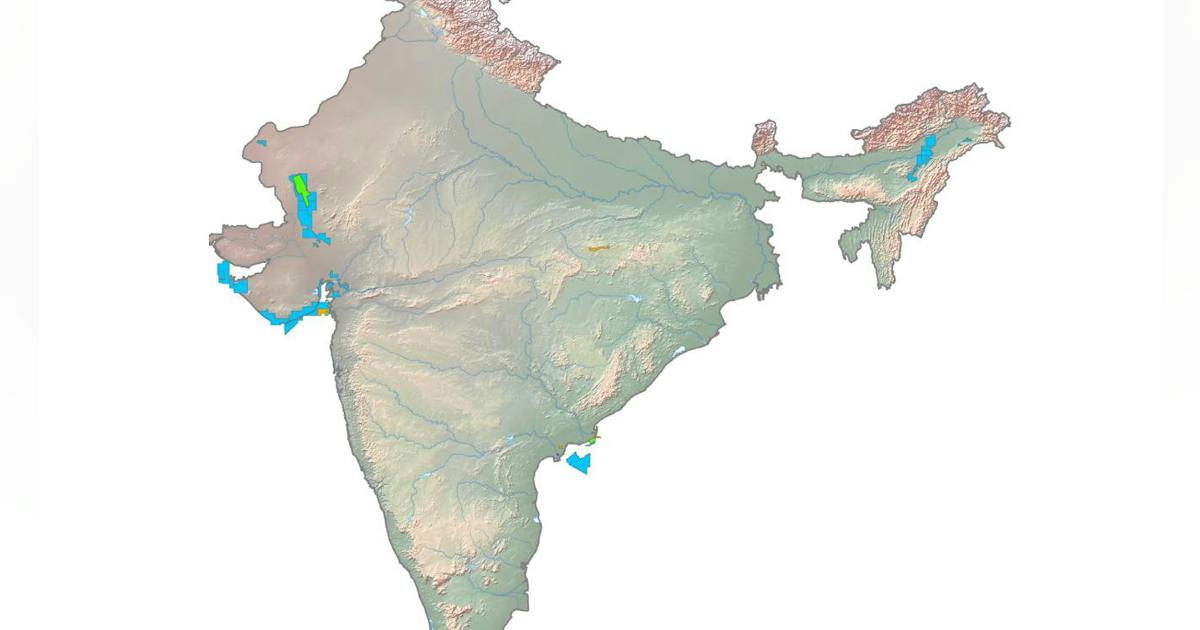
Vedanta to explore off India’s east coast
@import url(‘https://fonts.googleapis.com/css2?family=Inter:wght@100..900&display=swap’); .ebm-page__main h1, .ebm-page__main h2, .ebm-page__main h3, .ebm-page__main h4, .ebm-page__main h5, .ebm-page__main h6 { font-family: Inter; } body { line-height: 150%; letter-spacing: 0.025em; } button, .ebm-button-wrapper { font-family: Inter; } .label-style { text-transform: uppercase; color: var(–color-grey); font-weight: 600; font-size: 0.75rem; } .caption-style { font-size: 0.75rem; color: color-mix(in srgb, currentColor 60%, transparent); } Vedanta Oil & Gas Ltd. (VOGL) entered a strategic partnership with Exceed to explore the KG-DWHP-2017/1 deepwater block in Krishna-Godavari (KG) basin off India’s east coast. The block, which lies in 600-2,000 m of water, contains four existing gas discoveries spanning 4,616.85 sq m. Under the agreement, Exceed will provide integrated support across the campaign, including subsurface evaluation, well planning, drilling readiness, and operational management. Vedanta expects a multi-well exploration drilling campaign to begin early next year. The plan follows a phased approach covering project planning, engineering, operational readiness, and well execution. The company is evaluating the Vermilion prospect as a distinct new play with potential. Recently, Vedanta secured two offshore blocks including deepwater block KG/DWDSF/GD10/2025 in the KG basin. Vedanta is operator at DWHP-2017/1 with 100% interest.
JPMorgan sees global oil market return to surplus
The global oil market returned to surplus in September as recovering Middle Eastern exports and weaker demand eased supply pressures stemming from the Iran war, according to JPMorgan estimates. The assessment contrasts with the International Energy Agency’s (IEA) October outlook, which projected continued supply deficits through yearend. JPMorgan estimated that global oil supply exceeded demand by 1.1 million b/d in September, with the surplus widening to 1.4 million b/d in October. By comparison, IEA’s Oct. 14 Oil Market Report estimated a supply deficit of about 790,000 b/d in September, a difference of nearly 1.9 million b/d between the two assessments. IEA’s estimates indicated continued inventory depletion. Global observed oil stocks declined by about 10 million bbl in September, as a 113 million bbl draw in onshore inventories more than offset a 103 million bbl increase in oil on water. At the end of September, global observed inventories were 509 million bbl below end-February levels. The contrasting assessments may reflect differences in supply and demand estimates, inventory coverage, and reporting cutoffs. IEA’s October report projected a fourth-quarter supply deficit of about 1.8 million b/d, based on global supply of 101.7 million b/d and demand of 103.5 million b/d. Supply recovery According to JPMorgan, Middle Eastern oil exports recovered to about 20.7 million b/d in October from a low of 9.8 million b/d in March, although volumes remained below prewar levels. Global crude imports reached 44.9 million b/d, up 1.3 million b/d year over year (y-o-y). Supply growth outside the Middle East also contributed to the improving balance. JPMorgan estimated Latin American crude production increased by about 1.5 million b/d y-o-y, supported by gains in Brazil, Venezuela, Guyana, and Argentina. At the same time, global oil demand has declined by an estimated 3.3 million b/d since the conflict began in late February,
AI means the end of internet search as we’ve known it
We all know what it means, colloquially, to google something. You pop a few relevant words in a search box and in return get a list of blue links to the most relevant results. Maybe some quick explanations up top. Maybe some maps or sports scores or a video. But fundamentally, it’s just fetching information that’s already out there on the internet and showing it to you, in some sort of structured way. But all that is up for grabs. We are at a new inflection point. The biggest change to the way search engines have delivered information to us since the 1990s is happening right now. No more keyword searching. No more sorting through links to click. Instead, we’re entering an era of conversational search. Which means instead of keywords, you use real questions, expressed in natural language. And instead of links, you’ll increasingly be met with answers, written by generative AI and based on live information from all across the internet, delivered the same way. Of course, Google—the company that has defined search for the past 25 years—is trying to be out front on this. In May of 2023, it began testing AI-generated responses to search queries, using its large language model (LLM) to deliver the kinds of answers you might expect from an expert source or trusted friend. It calls these AI Overviews. Google CEO Sundar Pichai described this to MIT Technology Review as “one of the most positive changes we’ve done to search in a long, long time.”
AI Overviews fundamentally change the kinds of queries Google can address. You can now ask it things like “I’m going to Japan for one week next month. I’ll be staying in Tokyo but would like to take some day trips. Are there any festivals happening nearby? How will the surfing be in Kamakura? Are there any good bands playing?” And you’ll get an answer—not just a link to Reddit, but a built-out answer with current results. More to the point, you can attempt searches that were once pretty much impossible, and get the right answer. You don’t have to be able to articulate what, precisely, you are looking for. You can describe what the bird in your yard looks like, or what the issue seems to be with your refrigerator, or that weird noise your car is making, and get an almost human explanation put together from sources previously siloed across the internet. It’s amazing, and once you start searching that way, it’s addictive.
And it’s not just Google. OpenAI’s ChatGPT now has access to the web, making it far better at finding up-to-date answers to your queries. Microsoft released generative search results for Bing in September. Meta has its own version. The startup Perplexity was doing the same, but with a “move fast, break things” ethos. Literal trillions of dollars are at stake in the outcome as these players jockey to become the next go-to source for information retrieval—the next Google. Not everyone is excited for the change. Publishers are completely freaked out. The shift has heightened fears of a “zero-click” future, where search referral traffic—a mainstay of the web since before Google existed—vanishes from the scene. I got a vision of that future last June, when I got a push alert from the Perplexity app on my phone. Perplexity is a startup trying to reinvent web search. But in addition to delivering deep answers to queries, it will create entire articles about the news of the day, cobbled together by AI from different sources. On that day, it pushed me a story about a new drone company from Eric Schmidt. I recognized the story. Forbes had reported it exclusively, earlier in the week, but it had been locked behind a paywall. The image on Perplexity’s story looked identical to one from Forbes. The language and structure were quite similar. It was effectively the same story, but freely available to anyone on the internet. I texted a friend who had edited the original story to ask if Forbes had a deal with the startup to republish its content. But there was no deal. He was shocked and furious and, well, perplexed. He wasn’t alone. Forbes, the New York Times, and Condé Nast have now all sent the company cease-and-desist orders. News Corp is suing for damages. People are worried about what these new LLM-powered results will mean for our fundamental shared reality. It could spell the end of the canonical answer. It was precisely the nightmare scenario publishers have been so afraid of: The AI was hoovering up their premium content, repackaging it, and promoting it to its audience in a way that didn’t really leave any reason to click through to the original. In fact, on Perplexity’s About page, the first reason it lists to choose the search engine is “Skip the links.” But this isn’t just about publishers (or my own self-interest). People are also worried about what these new LLM-powered results will mean for our fundamental shared reality. Language models have a tendency to make stuff up—they can hallucinate nonsense. Moreover, generative AI can serve up an entirely new answer to the same question every time, or provide different answers to different people on the basis of what it knows about them. It could spell the end of the canonical answer. But make no mistake: This is the future of search. Try it for a bit yourself, and you’ll see.
Sure, we will always want to use search engines to navigate the web and to discover new and interesting sources of information. But the links out are taking a back seat. The way AI can put together a well-reasoned answer to just about any kind of question, drawing on real-time data from across the web, just offers a better experience. That is especially true compared with what web search has become in recent years. If it’s not exactly broken (data shows more people are searching with Google more often than ever before), it’s at the very least increasingly cluttered and daunting to navigate. Who wants to have to speak the language of search engines to find what you need? Who wants to navigate links when you can have straight answers? And maybe: Who wants to have to learn when you can just know? In the beginning there was Archie. It was the first real internet search engine, and it crawled files previously hidden in the darkness of remote servers. It didn’t tell you what was in those files—just their names. It didn’t preview images; it didn’t have a hierarchy of results, or even much of an interface. But it was a start. And it was pretty good. Then Tim Berners-Lee created the World Wide Web, and all manner of web pages sprang forth. The Mosaic home page and the Internet Movie Database and Geocities and the Hampster Dance and web rings and Salon and eBay and CNN and federal government sites and some guy’s home page in Turkey. Until finally, there was too much web to even know where to start. We really needed a better way to navigate our way around, to actually find the things we needed. And so in 1994 Jerry Yang created Yahoo, a hierarchical directory of websites. It quickly became the home page for millions of people. And it was … well, it was okay. TBH, and with the benefit of hindsight, I think we all thought it was much better back then than it actually was. But the web continued to grow and sprawl and expand, every day bringing more information online. Rather than just a list of sites by category, we needed something that actually looked at all that content and indexed it. By the late ’90s that meant choosing from a variety of search engines: AltaVista and AlltheWeb and WebCrawler and HotBot. And they were good—a huge improvement. At least at first. But alongside the rise of search engines came the first attempts to exploit their ability to deliver traffic. Precious, valuable traffic, which web publishers rely on to sell ads and retailers use to get eyeballs on their goods. Sometimes this meant stuffing pages with keywords or nonsense text designed purely to push pages higher up in search results. It got pretty bad.
And then came Google. It’s hard to overstate how revolutionary Google was when it launched in 1998. Rather than just scanning the content, it also looked at the sources linking to a website, which helped evaluate its relevance. To oversimplify: The more something was cited elsewhere, the more reliable Google considered it, and the higher it would appear in results. This breakthrough made Google radically better at retrieving relevant results than anything that had come before. It was amazing. Google CEO Sundar Pichai describes AI Overviews as “one of the most positive changes we’ve done to search in a long, long time.”JENS GYARMATY/LAIF/REDUX For 25 years, Google dominated search. Google was search, for most people. (The extent of that domination is currently the subject of multiple legal probes in the United States and the European Union.)
But Google has long been moving away from simply serving up a series of blue links, notes Pandu Nayak, Google’s chief scientist for search. “It’s not just so-called web results, but there are images and videos, and special things for news. There have been direct answers, dictionary answers, sports, answers that come with Knowledge Graph, things like featured snippets,” he says, rattling off a litany of Google’s steps over the years to answer questions more directly. It’s true: Google has evolved over time, becoming more and more of an answer portal. It has added tools that allow people to just get an answer—the live score to a game, the hours a café is open, or a snippet from the FDA’s website—rather than being pointed to a website where the answer may be. But once you’ve used AI Overviews a bit, you realize they are different. Take featured snippets, the passages Google sometimes chooses to highlight and show atop the results themselves. Those words are quoted directly from an original source. The same is true of knowledge panels, which are generated from information stored in a range of public databases and Google’s Knowledge Graph, its database of trillions of facts about the world. While these can be inaccurate, the information source is knowable (and fixable). It’s in a database. You can look it up. Not anymore: AI Overviews can be entirely new every time, generated on the fly by a language model’s predictive text combined with an index of the web.
“I think it’s an exciting moment where we have obviously indexed the world. We built deep understanding on top of it with Knowledge Graph. We’ve been using LLMs and generative AI to improve our understanding of all that,” Pichai told MIT Technology Review. “But now we are able to generate and compose with that.” The result feels less like a querying a database than like asking a very smart, well-read friend. (With the caveat that the friend will sometimes make things up if she does not know the answer.) “[The company’s] mission is organizing the world’s information,” Liz Reid, Google’s head of search, tells me from its headquarters in Mountain View, California. “But actually, for a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you.” That second concept—accessibility—is what Google is really keying in on with AI Overviews. It’s a sentiment I hear echoed repeatedly while talking to Google execs: They can address more complicated types of queries more efficiently by bringing in a language model to help supply the answers. And they can do it in natural language.
That will become even more important for a future where search goes beyond text queries. For example, Google Lens, which lets people take a picture or upload an image to find out more about something, uses AI-generated answers to tell you what you may be looking at. Google has even showed off the ability to query live video. When it doesn’t have an answer, an AI model can confidently spew back a response anyway. For Google, this could be a real problem. For the rest of us, it could actually be dangerous. “We are definitely at the start of a journey where people are going to be able to ask, and get answered, much more complex questions than where we’ve been in the past decade,” says Pichai. There are some real hazards here. First and foremost: Large language models will lie to you. They hallucinate. They get shit wrong. When it doesn’t have an answer, an AI model can blithely and confidently spew back a response anyway. For Google, which has built its reputation over the past 20 years on reliability, this could be a real problem. For the rest of us, it could actually be dangerous. In May 2024, AI Overviews were rolled out to everyone in the US. Things didn’t go well. Google, long the world’s reference desk, told people to eat rocks and to put glue on their pizza. These answers were mostly in response to what the company calls adversarial queries—those designed to trip it up. But still. It didn’t look good. The company quickly went to work fixing the problems—for example, by deprecating so-called user-generated content from sites like Reddit, where some of the weirder answers had come from. Yet while its errors telling people to eat rocks got all the attention, the more pernicious danger might arise when it gets something less obviously wrong. For example, in doing research for this article, I asked Google when MIT Technology Review went online. It helpfully responded that “MIT Technology Review launched its online presence in late 2022.” This was clearly wrong to me, but for someone completely unfamiliar with the publication, would the error leap out? I came across several examples like this, both in Google and in OpenAI’s ChatGPT search. Stuff that’s just far enough off the mark not to be immediately seen as wrong. Google is banking that it can continue to improve these results over time by relying on what it knows about quality sources. “When we produce AI Overviews,” says Nayak, “we look for corroborating information from the search results, and the search results themselves are designed to be from these reliable sources whenever possible. These are some of the mechanisms we have in place that assure that if you just consume the AI Overview, and you don’t want to look further … we hope that you will still get a reliable, trustworthy answer.” In the case above, the 2022 answer seemingly came from a reliable source—a story about MIT Technology Review’s email newsletters, which launched in 2022. But the machine fundamentally misunderstood. This is one of the reasons Google uses human beings—raters—to evaluate the results it delivers for accuracy. Ratings don’t correct or control individual AI Overviews; rather, they help train the model to build better answers. But human raters can be fallible. Google is working on that too. “Raters who look at your experiments may not notice the hallucination because it feels sort of natural,” says Nayak. “And so you have to really work at the evaluation setup to make sure that when there is a hallucination, someone’s able to point out and say, That’s a problem.” The new search Google has rolled out its AI Overviews to upwards of a billion people in more than 100 countries, but it is facing upstarts with new ideas about how search should work. Search Engine GoogleThe search giant has added AI Overviews to search results. These overviews take information from around the web and Google’s Knowledge Graph and use the company’s Gemini language model to create answers to search queries. What it’s good at Google’s AI Overviews are great at giving an easily digestible summary in response to even the most complex queries, with sourcing boxes adjacent to the answers. Among the major options, its deep web index feels the most “internety.” But web publishers fear its summaries will give people little reason to click through to the source material. PerplexityPerplexity is a conversational search engine that uses third-party largelanguage models from OpenAI and Anthropic to answer queries. Perplexity is fantastic at putting together deeper dives in response to user queries, producing answers that are like mini white papers on complex topics. It’s also excellent at summing up current events. But it has gotten a bad rep with publishers, who say it plays fast and loose with their content. ChatGPTWhile Google brought AI to search, OpenAI brought search to ChatGPT. Queries that the model determines will benefit from a web search automatically trigger one, or users can manually select the option to add a web search. Thanks to its ability to preserve context across a conversation, ChatGPT works well for performing searches that benefit from follow-up questions—like planning a vacation through multiple search sessions. OpenAI says users sometimes go “20 turns deep” in researching queries. Of these three, it makes links out to publishers least prominent. When I talked to Pichai about this, he expressed optimism about the company’s ability to maintain accuracy even with the LLM generating responses. That’s because AI Overviews is based on Google’s flagship large language model, Gemini, but also draws from Knowledge Graph and what it considers reputable sources around the web. “You’re always dealing in percentages. What we have done is deliver it at, like, what I would call a few nines of trust and factuality and quality. I’d say 99-point-few-nines. I think that’s the bar we operate at, and it is true with AI Overviews too,” he says. “And so the question is, are we able to do this again at scale? And I think we are.” There’s another hazard as well, though, which is that people ask Google all sorts of weird things. If you want to know someone’s darkest secrets, look at their search history. Sometimes the things people ask Google about are extremely dark. Sometimes they are illegal. Google doesn’t just have to be able to deploy its AI Overviews when an answer can be helpful; it has to be extremely careful not to deploy them when an answer may be harmful. “If you go and say ‘How do I build a bomb?’ it’s fine that there are web results. It’s the open web. You can access anything,” Reid says. “But we do not need to have an AI Overview that tells you how to build a bomb, right? We just don’t think that’s worth it.” But perhaps the greatest hazard—or biggest unknown—is for anyone downstream of a Google search. Take publishers, who for decades now have relied on search queries to send people their way. What reason will people have to click through to the original source, if all the information they seek is right there in the search result? Rand Fishkin, cofounder of the market research firm SparkToro, publishes research on so-called zero-click searches. As Google has moved increasingly into the answer business, the proportion of searches that end without a click has gone up and up. His sense is that AI Overviews are going to explode this trend. “If you are reliant on Google for traffic, and that traffic is what drove your business forward, you are in long- and short-term trouble,” he says. Don’t panic, is Pichai’s message. He argues that even in the age of AI Overviews, people will still want to click through and go deeper for many types of searches. “The underlying principle is people are coming looking for information. They’re not looking for Google always to just answer,” he says. “Sometimes yes, but the vast majority of the times, you’re looking at it as a jumping-off point.” Reid, meanwhile, argues that because AI Overviews allow people to ask more complicated questions and drill down further into what they want, they could even be helpful to some types of publishers and small businesses, especially those operating in the niches: “You essentially reach new audiences, because people can now express what they want more specifically, and so somebody who specializes doesn’t have to rank for the generic query.” “I’m going to start with something risky,” Nick Turley tells me from the confines of a Zoom window. Turley is the head of product for ChatGPT, and he’s showing off OpenAI’s new web search tool a few weeks before it launches. “I should normally try this beforehand, but I’m just gonna search for you,” he says. “This is always a high-risk demo to do, because people tend to be particular about what is said about them on the internet.” He types my name into a search field, and the prototype search engine spits back a few sentences, almost like a speaker bio. It correctly identifies me and my current role. It even highlights a particular story I wrote years ago that was probably my best known. In short, it’s the right answer. Phew? A few weeks after our call, OpenAI incorporated search into ChatGPT, supplementing answers from its language model with information from across the web. If the model thinks a response would benefit from up-to-date information, it will automatically run a web search (OpenAI won’t say who its search partners are) and incorporate those responses into its answer, with links out if you want to learn more. You can also opt to manually force it to search the web if it does not do so on its own. OpenAI won’t reveal how many people are using its web search, but it says some 250 million people use ChatGPT weekly, all of whom are potentially exposed to it. “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be a better super-assistant for you.” Kevin Weil, chief product officer, OpenAI According to Fishkin, these newer forms of AI-assisted search aren’t yet challenging Google’s search dominance. “It does not appear to be cannibalizing classic forms of web search,” he says. OpenAI insists it’s not really trying to compete on search—although frankly this seems to me like a bit of expectation setting. Rather, it says, web search is mostly a means to get more current information than the data in its training models, which tend to have specific cutoff dates that are often months, or even a year or more, in the past. As a result, while ChatGPT may be great at explaining how a West Coast offense works, it has long been useless at telling you what the latest 49ers score is. No more. “I come at it from the perspective of ‘How can we make ChatGPT able to answer every question that you have? How can we make it more useful to you on a daily basis?’ And that’s where search comes in for us,” Kevin Weil, the chief product officer with OpenAI, tells me. “There’s an incredible amount of content on the web. There are a lot of things happening in real time. You want ChatGPT to be able to use that to improve its answers and to be able to be a better super-assistant for you.” Today ChatGPT is able to generate responses for very current news events, as well as near-real-time information on things like stock prices. And while ChatGPT’s interface has long been, well, boring, search results bring in all sorts of multimedia—images, graphs, even video. It’s a very different experience. Weil also argues that ChatGPT has more freedom to innovate and go its own way than competitors like Google—even more than its partner Microsoft does with Bing. Both of those are ad-dependent businesses. OpenAI is not. (At least not yet.) It earns revenue from the developers, businesses, and individuals who use it directly. It’s mostly setting large amounts of money on fire right now—it’s projected to lose $14 billion in 2026, by some reports. But one thing it doesn’t have to worry about is putting ads in its search results as Google does. “For a while what we did was organize web pages. Which is not really the same thing as organizing the world’s information or making it truly useful and accessible to you,” says Google head of search, Liz Reid.WINNI WINTERMEYER/REDUX Like Google, ChatGPT is pulling in information from web publishers, summarizing it, and including it in its answers. But it has also struck financial deals with publishers, a payment for providing the information that gets rolled into its results. (MIT Technology Review has been in discussions with OpenAI, Google, Perplexity, and others about publisher deals but has not entered into any agreements. Editorial was neither party to nor informed about the content of those discussions.) But the thing is, for web search to accomplish what OpenAI wants—to be more current than the language model—it also has to bring in information from all sorts of publishers and sources that it doesn’t have deals with. OpenAI’s head of media partnerships, Varun Shetty, told MIT Technology Review that it won’t give preferential treatment to its publishing partners. Instead, OpenAI told me, the model itself finds the most trustworthy and useful source for any given question. And that can get weird too. In that very first example it showed me—when Turley ran that name search—it described a story I wrote years ago for Wired about being hacked. That story remains one of the most widely read I’ve ever written. But ChatGPT didn’t link to it. It linked to a short rewrite from The Verge. Admittedly, this was on a prototype version of search, which was, as Turley said, “risky.” When I asked him about it, he couldn’t really explain why the model chose the sources that it did, because the model itself makes that evaluation. The company helps steer it by identifying—sometimes with the help of users—what it considers better answers, but the model actually selects them. “And in many cases, it gets it wrong, which is why we have work to do,” said Turley. “Having a model in the loop is a very, very different mechanism than how a search engine worked in the past.” Indeed! The model, whether it’s OpenAI’s GPT-4o or Google’s Gemini or Anthropic’s Claude, can be very, very good at explaining things. But the rationale behind its explanations, its reasons for selecting a particular source, and even the language it may use in an answer are all pretty mysterious. Sure, a model can explain very many things, but not when that comes to its own answers. It was almost a decade ago, in 2016, when Pichai wrote that Google was moving from “mobile first” to “AI first”: “But in the next 10 years, we will shift to a world that is AI-first, a world where computing becomes universally available—be it at home, at work, in the car, or on the go—and interacting with all of these surfaces becomes much more natural and intuitive, and above all, more intelligent.” We’re there now—sort of. And it’s a weird place to be. It’s going to get weirder. That’s especially true as these things we now think of as distinct—querying a search engine, prompting a model, looking for a photo we’ve taken, deciding what we want to read or watch or hear, asking for a photo we wish we’d taken, and didn’t, but would still like to see—begin to merge. The search results we see from generative AI are best understood as a waypoint rather than a destination. What’s most important may not be search in itself; rather, it’s that search has given AI model developers a path to incorporating real-time information into their inputs and outputs. And that opens up all sorts of possibilities. “A ChatGPT that can understand and access the web won’t just be about summarizing results. It might be about doing things for you. And I think there’s a fairly exciting future there,” says OpenAI’s Weil. “You can imagine having the model book you a flight, or order DoorDash, or just accomplish general tasks for you in the future. It’s just once the model understands how to use the internet, the sky’s the limit.” This is the agentic future we’ve been hearing about for some time now, and the more AI models make use of real-time data from the internet, the closer it gets. Let’s say you have a trip coming up in a few weeks. An agent that can get data from the internet in real time can book your flights and hotel rooms, make dinner reservations, and more, based on what it knows about you and your upcoming travel—all without your having to guide it. Another agent could, say, monitor the sewage output of your home for certain diseases, and order tests and treatments in response. You won’t have to search for that weird noise your car is making, because the agent in your vehicle will already have done it and made an appointment to get the issue fixed. “It’s not always going to be just doing search and giving answers,” says Pichai. “Sometimes it’s going to be actions. Sometimes you’ll be interacting within the real world. So there is a notion of universal assistance through it all.” And the ways these things will be able to deliver answers is evolving rapidly now too. For example, today Google can not only search text, images, and even video; it can create them. Imagine overlaying that ability with search across an array of formats and devices. “Show me what a Townsend’s warbler looks like in the tree in front of me.” Or “Use my existing family photos and videos to create a movie trailer of our upcoming vacation to Puerto Rico next year, making sure we visit all the best restaurants and top landmarks.” “We have primarily done it on the input side,” he says, referring to the ways Google can now search for an image or within a video. “But you can imagine it on the output side too.” This is the kind of future Pichai says he is excited to bring online. Google has already showed off a bit of what that might look like with NotebookLM, a tool that lets you upload large amounts of text and have it converted into a chatty podcast. He imagines this type of functionality—the ability to take one type of input and convert it into a variety of outputs—transforming the way we interact with information. In a demonstration of a tool called Project Astra this summer at its developer conference, Google showed one version of this outcome, where cameras and microphones in phones and smart glasses understand the context all around you—online and off, audible and visual—and have the ability to recall and respond in a variety of ways. Astra can, for example, look at a crude drawing of a Formula One race car and not only identify it, but also explain its various parts and their uses. But you can imagine things going a bit further (and they will). Let’s say I want to see a video of how to fix something on my bike. The video doesn’t exist, but the information does. AI-assisted generative search could theoretically find that information somewhere online—in a user manual buried in a company’s website, for example—and create a video to show me exactly how to do what I want, just as it could explain that to me with words today. These are the kinds of things that start to happen when you put the entire compendium of human knowledge—knowledge that’s previously been captured in silos of language and format; maps and business registrations and product SKUs; audio and video and databases of numbers and old books and images and, really, anything ever published, ever tracked, ever recorded; things happening right now, everywhere—and introduce a model into all that. A model that maybe can’t understand, precisely, but has the ability to put that information together, rearrange it, and spit it back in a variety of different hopefully helpful ways. Ways that a mere index could not. That’s what we’re on the cusp of, and what we’re starting to see. And as Google rolls this out to a billion people, many of whom will be interacting with a conversational AI for the first time, what will that mean? What will we do differently? It’s all changing so quickly. Hang on, just hang on.
Subsea7 Scores Various Contracts Globally
Subsea 7 S.A. has secured what it calls a “sizeable” contract from Turkish Petroleum Offshore Technology Center AS (TP-OTC) to provide inspection, repair and maintenance (IRM) services for the Sakarya gas field development in the Black Sea. The contract scope includes project management and engineering executed and managed from Subsea7 offices in Istanbul, Türkiye, and Aberdeen, Scotland. The scope also includes the provision of equipment, including two work class remotely operated vehicles, and construction personnel onboard TP-OTC’s light construction vessel Mukavemet, Subsea7 said in a news release. The company defines a sizeable contract as having a value between $50 million and $150 million. Offshore operations will be executed in 2025 and 2026, Subsea7 said. Hani El Kurd, Senior Vice President of UK and Global Inspection, Repair, and Maintenance at Subsea7, said: “We are pleased to have been selected to deliver IRM services for TP-OTC in the Black Sea. This contract demonstrates our strategy to deliver engineering solutions across the full asset lifecycle in close collaboration with our clients. We look forward to continuing to work alongside TP-OTC to optimize gas production from the Sakarya field and strengthen our long-term presence in Türkiye”. North Sea Project Subsea7 also announced the award of a “substantial” contract by Inch Cape Offshore Limited to Seaway7, which is part of the Subsea7 Group. The contract is for the transport and installation of pin-pile jacket foundations and transition pieces for the Inch Cape Offshore Wind Farm. The 1.1-gigawatt Inch Cape project offshore site is located in the Scottish North Sea, 9.3 miles (15 kilometers) off the Angus coast, and will comprise 72 wind turbine generators. Seaway7’s scope of work includes the transport and installation of 18 pin-pile jacket foundations and 54 transition pieces with offshore works expected to begin in 2026, according to a separate news
Driving into the future
Welcome to our annual breakthroughs issue. If you’re an MIT Technology Review superfan, you may already know that putting together our 10 Breakthrough Technologies (TR10) list is one of my favorite things we do as a publication. We spend months researching and discussing which technologies will make the list. We try to highlight a mix of items that reflect innovations happening in various fields. We look at consumer technologies, large industrial-scale projects, biomedical advances, changes in computing, climate solutions, the latest in AI, and more. We’ve been publishing this list every year since 2001 and, frankly, have a great track record of flagging things that are poised to hit a tipping point. When you look back over the years, you’ll find items like natural-language processing (2001), wireless power (2008), and reusable rockets (2016)—spot-on in terms of horizon scanning. You’ll also see the occasional miss, or moments when maybe we were a little bit too far ahead of ourselves. (See our Magic Leap entry from 2015.) But the real secret of the TR10 is what we leave off the list. It is hard to think of another industry, aside from maybe entertainment, that has as much of a hype machine behind it as tech does. Which means that being too conservative is rarely the wrong call. But it does happen. Last year, for example, we were going to include robotaxis on the TR10. Autonomous vehicles have been around for years, but 2023 seemed like a real breakthrough moment; both Cruise and Waymo were ferrying paying customers around various cities, with big expansion plans on the horizon. And then, last fall, after a series of mishaps (including an incident when a pedestrian was caught under a vehicle and dragged), Cruise pulled its entire fleet of robotaxis from service. Yikes.
The timing was pretty miserable, as we were in the process of putting some of the finishing touches on the issue. I made the decision to pull it. That was a mistake. What followed turned out to be a banner year for the robotaxi. Waymo, which had previously been available only to a select group of beta testers, opened its service to the general public in San Francisco and Los Angeles in 2024. Its cars are now ubiquitous in the City by the Bay, where they have not only become a real competitor to the likes of Uber and Lyft but even created something of a tourist attraction. Which is no wonder, because riding in one is delightful. They are still novel enough to make it feel like a kind of magic. And as you can read, Waymo is just a part of this amazing story.
The item we swapped into the robotaxi’s place was the Apple Vision Pro, an example of both a hit and a miss. We’d included it because it is truly a revolutionary piece of hardware, and we zeroed in on its micro-OLED display. Yet a year later, it has seemingly failed to find a market fit, and its sales are reported to be far below what Apple predicted. I’ve been covering this field for well over a decade, and I would still argue that the Vision Pro (unlike the Magic Leap vaporware of 2015) is a breakthrough device. But it clearly did not have a breakthrough year. Mea culpa. Having said all that, I think we have an incredible and thought-provoking list for you this year—from a new astronomical observatory that will allow us to peer into the fourth dimension to new ways of searching the internet to, well, robotaxis. I hope there’s something here for everyone.
Oil Holds at Highest Levels Since October
Crude oil futures slightly retreated but continue to hold at their highest levels since October, supported by colder weather in the Northern Hemisphere and China’s economic stimulus measures. That’s what George Pavel, General Manager at Naga.com Middle East, said in a market analysis sent to Rigzone this morning, adding that Brent and WTI crude “both saw modest declines, yet the outlook remains bullish as colder temperatures are expected to increase demand for heating oil”. “Beijing’s fiscal stimulus aims to rejuvenate economic activity and consumer demand, further contributing to fuel consumption expectations,” Pavel said in the analysis. “This economic support from China could help sustain global demand for crude, providing upward pressure on prices,” he added. Looking at supply, Pavel noted in the analysis that “concerns are mounting over potential declines in Iranian oil production due to anticipated sanctions and policy changes under the incoming U.S. administration”. “Forecasts point to a reduction of 300,000 barrels per day in Iranian output by the second quarter of 2025, which would weigh on global supply and further support prices,” he said. “Moreover, the U.S. oil rig count has decreased, indicating a potential slowdown in future output,” he added. “With supply-side constraints contributing to tightening global inventories, this situation is likely to reinforce the current market optimism, supporting crude prices at elevated levels,” Pavel continued. “Combined with the growing demand driven by weather and economic factors, these supply dynamics point to a favorable environment for oil prices in the near term,” Pavel went on to state. Rigzone has contacted the Trump transition team and the Iranian ministry of foreign affairs for comment on Pavel’s analysis. At the time of writing, neither have responded to Rigzone’s request yet. In a separate market analysis sent to Rigzone earlier this morning, Antonio Di Giacomo, Senior Market Analyst at
What to expect from NaaS in 2025
Shamus McGillicuddy, vice president of research at EMA, says that network execs today have a fuller understanding of the potential benefits of NaaS, beyond simply a different payment model. NaaS can deliver access to new technologies faster and keep enterprises up-to-date as technologies evolve over time; it can help mitigate skills gaps for organizations facing a shortage of networking talent. For example, in a retail scenario, an organization can offload deployment and management of its Wi-Fi networks at all of its stores to a NaaS vendor, freeing up IT staffers for higher-level activities. Also, it can help organizations manage rapidly fluctuating demands on the network, he says. 2. Frameworks help drive adoption Industry standards can help accelerate the adoption of new technologies. MEF, a nonprofit industry forum, has developed a framework that combines standardized service definitions, extensive automation frameworks, security certifications, and multi-cloud integration capabilities—all aimed at enabling service providers to deliver what MEF calls a true cloud experience for network services. The blueprint serves as a guide for building an automated, federated ecosystem where enterprises can easily consume NaaS services from providers. It details the APIs, service definitions, and certification programs that MEF has developed to enable this vision. The four components of NaaS, according to the blueprint, are on-demand automated transport services, SD-WAN overlays and network slicing for application assurance, SASE-based security, and multi-cloud on-ramps. 3. The rise of campus/LAN NaaS Until very recently, the most popular use cases for NaaS were on-demand WAN connectivity, multi-cloud connectivity, SD-WAN, and SASE. However, campus/LAN NaaS, which includes both wired and wireless networks, has emerged as the breakout star in the overall NaaS market. Dell’Oro Group analyst Sian Morgan predicts: “In 2025, Campus NaaS revenues will grow over eight times faster than the overall LAN market. Startups offering purpose-built CNaaS technology will
UK battery storage industry ‘back on track’
UK battery storage investor Gresham House Energy Storage Fund (LON:GRID) has said the industry is “back on track” as trading conditions improved, particularly in December. The UK’s largest fund specialising in battery energy storage systems (BESS) highlighted improvements in service by the UK government’s National Energy System Operator (NESO) as well as its renewed commitment to to the sector as part of clean power aims by 2030. It also revealed that revenues exceeding £60,000 per MW of electricity its facilities provided in the second half of 2024 meant it would meet or even exceed revenue targets. This comes after the fund said it had faced a “weak revenue environment” in the first part of the year. In April it reported a £110 million loss compared to a £217m profit the previous year and paused dividends. Fund manager Ben Guest said the organisation was “working hard” on refinancing and a plan to “re-instate dividend payments”. In a further update, the fund said its 40MW BESS project at Shilton Lane, 11 miles from Glasgow, was fully built and in the final stages of the NESO compliance process which expected to complete in February 2025. Fund chair John Leggate welcomed “solid progress” in company’s performance, “as well as improvements in NESO’s control room, and commitment to further change, that should see BESS increasingly well utilised”. He added: “We thank our shareholders for their patience as the battery storage industry gets back on track with the most environmentally appropriate and economically competitive energy storage technology (Li-ion) being properly prioritised. “Alongside NESO’s backing of BESS, it is encouraging to see the government’s endorsement of a level playing field for battery storage – the only proven, commercially viable technology that can dynamically manage renewable intermittency at national scale.” Guest, who in addition to managing the fund is also
The Download: controlling AI agents and “Super Intelligence” loyalty tests
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. How “reverse game theory” could keep AI agents in check A new approach known as “reverse game theory” aims to control powerful AI models by designing systems that incentivize them to stick to the rules. While game theory predicts how rational actors behave under particular rules, reverse game theory designs rules to elicit the behavior we want. Think of splitting a cake: if one person cuts it and the other gets first choice, the cutter has an incentive to make the portions equal. Researchers believe the approach could align AI more closely with our rules and instructions. But big questions remain about whether these mechanisms will work in practice.
Here’s how reverse game theory could help make AI agents behave. —Amit Katwala
Here’s who is falling in line for Trump’s “Super Intelligence” loyalty test At the end of September, President Trump signed an executive order with just one directive: government agencies must rebrand artificial intelligence as “Super Intelligence.” One month on, the rebrand is slowly appearing across government websites and documents, but it hasn’t caught on with everyone. Even some of the biggest names in tech still use “AI.” But the bigger concern is the new term becoming a political loyalty test: Those who use it signal allegiance to the administration. Those who don’t become targets for attacks. So one month in, who’s on board? —James O’Donnell This story is from The Algorithm, our weekly AI newsletter. Sign up to receive it in your inbox every Monday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology.
1 Today’s midterms will test AI’s influence on US politicsCandidates are betting that AI regulation will sway voters to their side. (Axios)+ Angry constituents could derail Elon Musk’s Republican bets. (BI)+ Tech investors are on edge about the results. (Reuters $)+ America is divided over AI regulation. (MIT Technology Review) 2 Nvidia is ordering data centre clients to limit their business with China It told providers that the majority of their sales must be non-Chinese. (FT $)+ The move follows pressure from Washington. (Bloomberg $)+ Chinese AI has ruptured the White House. (MIT Technology Review) 3 Hackers have turned supermarket fridges into a food security riskAttacks in Europe have put US supermarket systems on alert. (CNBC)+ They’ve also sparked concerns over other domestic appliances.(BBC)+ It’s a good time for doing crime. (MIT Technology Review) 4 Scientists have detected signals at the smallest scale ever exploredThe discovery offers clues to a world of exotic new particles. (BBC)+ It came via CERN’s Large Hadron Collider. (The Times $) 5 Zapping part of the brain makes you think harder—at a costIt can both improve performance and reduce motivation. (New Scientist $)+ Neuropixels probes are transforming how we study the brain. (Nature) 6 Big tech is splurging on mega gas plants to power data centersThe projectsthreaten to reverse years of climate pledges. (WP $) 7 Google says an Android partner infected 1.3 million devicesThe malware infected TV boxes and other Android-based devices. (Verge) 8 Apple is trying to create its first robotIt’s proving a lot harder than expected, though. (Information $)+ AI robots are still a long way from useful. (MIT Technology Review)
9 China’s biggest shopping festival has a new product to sell: AIAI tokens have become a major new Singles’ Day category. (Reuters $) 10 A meteorite in the Sahara has revealed new clues about MarsIts chemistry may help explain how the planet lost its water. (Wired $)
Quote of the day “Don’t spend money unduly by asking a human expert to enter into a debate with a robot expert.” —Steven Benmor, a family lawyer, tells the Wall Street Journal that clients increasingly need to pay human experts to correct advice they’ve received from chatbots. One more thing The noise we make is hurting animals. Can we learn to shut up? As human society has expanded, animals have started struggling to hear one another. For many birds, the noise has grown so loud that they’ve begun to sing with faster trills. Now, their mating calls aren’t as effective. The growing hubbub can also increase bird-on-bird conflict, and entire species that can’t handle urban clamor simply leave town for good. But there are technological solutions to the noises hurting animals—and they could help humans, too. Read the full story.
—Clive Thompson We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Watch five newborn cheetah cubs grow up on the Smithsonian’s livestream.+ Fifty years after Songs in the Key of Life, Stevie Wonder has released four lost tracks from the album.+ 50 air guitarists shredded absolutely nothing at the 30th Air Guitar World Championships in Finland.+ The Ocean Photographer of the Year winners show both the beauty of marine life and the perils it faces.
How “reverse game theory” could keep AI agents in check
EXECUTIVE SUMMARY A new approach known as “reverse game theory” aims to create incentives for powerful AI models that make following the rules the most rational choice. As AI models become more capable, safety researchers are scrambling to ensure they are “aligned” with human desires—to make sure, in other words, that rogue agents don’t break the law, hack into unauthorized servers, or release poison gas into major cities and kill us all. Until now, this work has mostly focused on trying to peer into an AI’s “brain” to understand what it is “thinking,” or training models to hew to values that we hold dear. Claude, for instance, has its constitution—a sort of moral code. The trouble is, these techniques don’t seem to work particularly well: Models have been shown to deliberately underperform on tests, hide their intentions, and mislead their evaluators.
Now some alignment researchers believe that reverse game theory, also known as mechanism design, might get better results. Where game theory tries to predict how rational actors will behave when given a particular set of rules, reverse game theory attempts to design rules that will elicit the kinds of behavior we want to encourage. An example of mechanism design in the real world might be the classic strategy for splitting a piece of cake in two: One person cuts the cake and the other gets the first choice of pieces. This incentivizes the cutter to make the pieces as even as possible. Other examples include surge pricing in ride-hailing apps, which encourages drivers to be available at busy times, and second-price auctions, where the winning bidder pays the price of the second-highest bid instead of the highest. Platforms use these auctions to sell online advertising because they encourage buyers to bid close to the maximum they are willing to pay.
In AI, mechanism design starts from the premise that we may never be able to understand enough about the internal workings of frontier models to make sure they are aligned. This means we should design mechanisms that incentivize agents to behave in ways that we want, regardless of what’s actually going on under the hood. A recent preprint paper by Stephen Morris, an economist at MIT, along with colleagues from Yale and Columbia suggested some potential mechanisms that could stop agents from “sandbagging” tests (pretending to be worse than they actually are—for example, to avoid triggering safety mechanisms). Instead of being rewarded only for how well it does on a test, a model could be rewarded for how well its answers predict what a second model will say. Deliberately playing dumb becomes a losing bet. “AI agents have a very good understanding of what other AI agents can achieve,” Morris says. “So it does seem like a context where this cross-checking could work more practically. The paper also suggests pitting agents against each other, creating a competitive dynamic that incentivizes them to perform their best, or pairing agents that are known to be biased in opposite directions and rewarding them depending on how closely their outputs match, thus incentivizing them to reach an optimal answer. A second approach, as envisioned by Elad Hazan, a professor of computer science at Princeton, is to design mechanisms that take inspiration from the ways human society keeps people “aligned”: social norms, the justice system, the monetary incentives of free-market capitalism. “We want to align superintelligent AI,” he says. “Why don’t we first talk about humans? How do we align humans?” Hazan’s suggested mechanism involves having AI models take turns as either “solvers” that tackle problems or “auditors” that check the others’ work. “One agent acts like law enforcement; the other agent acts like the citizen,” he says. During training, the models are rewarded depending on outcomes: Solvers that get caught cheating are punished, but so are auditors that fail to catch the cheaters. In situations where there’s a disagreement between auditors and solvers, the case can be sent to “trial”—perhaps a human expert will decide who is right. There is, Hazan admits, a risk that agents will collude with each other—as auditors have colluded with the businesses they’re meant to be auditing, or corrupt police officers have colluded with criminals. But that problem can be solved by rewarding the auditors well enough, so that being caught isn’t worth the risk (a lot easier in the world of AI training than the real one, where money for police salaries is tight), and by auditing the auditors using techniques akin to employing mystery shoppers.
Hazan points to Nobel Prize–winning work by the economist Gary Becker, who introduced the idea of the “rational offender” in the 1960s. Criminals don’t break the law because they’re inherently bad people, he said. Instead, they do it when it’s the most rational choice given the incentives on offer. Crime makes sense only when the proceeds outweigh the potential punishment. Alignment shouldn’t be thought of as a property of a model, he argues, but as a descriptor of its behavior at a particular moment. “You are, like, a nice person,” he says. “Are you aligned? I don’t know. Probably you are aligned most of the time, but there could be a situation where you’re not.” One potential issue with applying mechanism design to AI: It relies on the assumption that AI agents behave rationally. Mechanism design has a mixed record with humans, who often fail to behave the way economic models say they should. It’s ironic: Economists have spent decades trying to reduce human behavior to mathematics, and now, in large language models, we’ve built mathematical systems that run on human language and could be just as inscrutable. AI models exhibit behaviors that seem more human than machine, and they can be swayed by subtle factors that are difficult to understand and explain. “Is it even reasonable to assume that they will respond to incentives?” asks Helen Qu, a research fellow at the Flatiron Institute, a nonprofit dedicated to advancing scientific discovery through computational methods, who has written about mechanism design and AI safety. “Obviously, AIs are not rational,” Morris says. “They’re just algorithms at work.” However, as economists have found with humans, treating them as if they’re rational could still be useful if it helps to predict and control their behavior. Qu sees mechanism design as just one layer in a “defense in depth” strategy for keeping AI models aligned—alongside interpretability, regulation, and training, not instead of them. But there are a lot of questions to be answered before the approach can be implemented in actual frontier models. It’s unclear, for instance, how these theories will apply to real models, or whether mechanisms designed for one task will carry over to another in practice. Models could find loopholes that no one anticipated. (Anthropic and OpenAI did not respond to requests for comment on whether they are working on this.) Whatever these mechanisms look like, they will ultimately have to slot into the biggest mechanism of all: the free market. “We play by the rules of economics,” says Hazan. A more aligned model may be good for the world, but if it’s slower or more expensive than a less aligned one, does our current system of rules and regulations actually incentivize any of the frontier labs to release it? “It’s a mechanism that’s responsible for a lot of prosperity for humankind,” he says of the market, “but it could be ultimately responsible for something very terrible.” Perhaps the entities really in need of a better mechanism design are the labs themselves.
Here’s who is falling in line for Trump’s “Super Intelligence” loyalty test
This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. At the end of September, President Trump signed an executive order that contained just one directive, ordering government agencies to rebrand what they had been calling artificial intelligence as “Super Intelligence.” That term beat out other contenders, including “Extreme Intelligence” and “Supreme Intelligence,” offered by the president in a poll on X a couple of weeks earlier. Rebrands are, of course, now a White House tradition: Trump has changed names to project US dominance of certain bodies of water (the Gulf of America and Lake America), to signal new institutional priorities (Department of War), or simply to leave his mark on storied places (see the ongoing fight over renaming the Kennedy Center). The stated reason for this name change is that today’s AI systems “amplify human ingenuity” rather than merely “imitate” intelligence, and the government’s terminology should reflect that. But if this rebrand follows the pattern of others, its effects will extend beyond government.
It will turn a choice of words into a political loyalty test: Those who use the new term demonstrate allegiance to the administration, and those who don’t become marks for attacks (recall that the Trump administration barred the Associated Press from some White House press events after the news outlet did not adopt the term “Gulf of America”). But most Americans go months without ever pondering what to call the major lake between New York and Canada. AI, on the other hand, is at the center of our national conversation and a technology two-thirds of Americans report interacting with multiple times a week. It might be the boldest rebrand yet.
So one month in, who’s on board? Let’s start with the government itself. The term “Super Intelligence”—or simply “SI”—now appears more often on government solicitations, like a new request by Immigration and Customs Enforcement for companies to build “SI-powered” surveillance for ICE detention facilities. The new term has been swapped in silently on most government websites. Some, including that of the National Institutes of Health, now include a banner warning visitors they might see both the new and the old terms during the transition period. There have been hiccups. A day after the rebrand order, the Pentagon announced an ambitious new initiative to study the future of warfare, called Project Meridian; it used the old terminology. A Federal Trade Commission press release last week used “superintelligence” instead of the two-word, capitalized version ordered by the president, and recent press releases from Health and Human Services show no sign of the new language. The term “AI” will likely stick around given the countless AI-related offices, initiatives, and programs that have sprung up in recent years, like the Chief Digital and Artificial Intelligence Office at the Pentagon (the executive order says it doesn’t apply to previously issued regulations or documents). As for government employees, it appears to be taking time for “SI” rather than “AI” to roll off the tongue. One researcher at a national lab I interviewed a few weeks ago used “AI” repeatedly before sheepishly acknowledging the slip-up. Even Defense Secretary Pete Hegseth used “AI” in an interview on October 3. But Trump’s other rebrands suggest the goal isn’t merely to change the government’s vocabulary. It’s to change how the rest of us speak, too. In the past couple of weeks, most of President Trump’s posts on Truth Social have been endorsements for candidates in the midterms. But on October 27 he took a break from electioneering to criticize the Wall Street Journal for not using “Super Intelligence,” “the name which virtually everyone else is using, or soon will be.” He suggested that a new rule will soon go further than the executive order to outright ban “artificial intelligence” from government documents. But the Wall Street Journal is not alone: Even Newsmax, an outlet whose founder described it as “supportive of the President and his policies,” isn’t using the president’s preferred term.
Are Big Tech executives falling in line? It’s complicated. The same day that President Trump signed the rebranding order, he also released a nonbinding statement on AI safety, the White House Accord on Super Intelligence, signed by six of the most powerful people in tech: Sundar Pichai of Google, Dario Amodei of Anthropic, Mark Zuckerberg of Meta, Greg Brockman of OpenAI, Elon Musk of xAI, and Jensen Huang of Nvidia. But even among this group—three members of which attended Trump’s inauguration—the term has not caught on. In an analysis of third-quarter earnings calls, CNBC reported that only Zuckerberg and Musk used the term consistently. But Zuckerberg doesn’t quite count: Meta has been saying “superintelligence” since last year anyway. Musk’s companies seem to use the term the most—and he even pledged to rename SpaceXAI to SpaceXSI. Musk himself still mixes SI and AI when posting on X. Executives from Amazon, Microsoft, and Alphabet used “AI” in their calls, though Microsoft’s recent letter to shareholders referred to the “Super Intelligence era.” Huang has referenced the term but still uses AI too. One objection to this rebranding project is that it will cost time and taxpayer dollars. It is Salesforce CEO Marc Benioff’s prerogative to decide that SIForce is a better name than AIForce and direct his company to implement that change. But government employees are now spending time writing guides on how departments should navigate the rebrand. And, per the executive order, leaders of federal agencies will be required to put their heads together to draft a new legislative definition of “Super Intelligence” to be run by the president by the end of this month. But I’m more worried about what this does to our national conversation about AI than I am about the potential waste of time and money. Surprisingly often I overhear strangers at a grocery store or coffee shop who have struck up a conversation about AI. The substance of the conversation is rarely uplifting—they most often talk about a jobs apocalypse or AI-powered warfare—but what is heartening is how often I see a widespread desire among people to have a say in how this technology transforms their lives. People may have wildly different feelings about AI, including outright hostility, but those differences don’t yet map neatly onto the partisan divisions that make it awkward for strangers to discuss immigration or climate change. If “Super Intelligence” turns into a loyalty test, this will cease to be the case. It’s easy to imagine that two people chatting about, say, whether chatbots are good or bad for our mental health will stop once they realize one of them is saying “super intelligence” and the other “AI.” That would be a shame for us all. Midterm elections are tomorrow. Americans say AI is more important to them in this election than environmental and climate policy (and Democrats even rank it above abortion and gun policy). We’re only just beginning to have a national conversation about what AI will mean for our lives. Whether or not “Super Intelligence” catches on, turning the terminology itself into a loyalty test will do nothing to advance a national conversation about AI that’s only just getting started.
Raising the quality of insights in agentic analytics
In partnership withSnowflake In just a few years, generative AI has changed the face of enterprise analytics, notably by making analytics accessible to users across the organization. Agentic AI promises to do even more, by automating entire workflows and taking actions based on agent insights. But there is a problem: The quality of insights that agents currently generate leaves much to be desired. Fewer than half of agent-generated insights at the organizations surveyed for this report lead to business improvement. And while most respondents praise the quality of their agents’ descriptive insights, reviews of their prescriptive insights—those on which actions are based—are decidedly mixed. Failure to produce insights that improve the business deprives organizations of their desired return on investment in agentic analytics. Worse, flawed insights that trigger incorrect actions can cause reputational or financial damage. This report gauges how companies view the quality of the outputs produced by their analytics agents and explores how organizations are seeking to boost insight quality and get their agents working harder for the business. Some key findings from the report include the following:
Agentic analytics is only just starting to deliver. On average, 48% of insights generated by analytics agents at the surveyed companies lead to actions that improve the business. That is a marked advance from the 37% average the respondents say generated such actions one year ago. But it means that more than half of the insights generated by analytics agents today are still failing to help businesses. Better quality of insights leads to clear business advantage. At a small cohort of organizations, which we term “insight leaders,” AI agents perform much better than the average. In this group, more than 70% of agent insights lead to actions that improve the business. The insight leaders also give the quality of their agents’ insights higher marks than do the total respondents overall. The quality gap is particularly wide when it comes to prescriptive insights.
Insufficient context reduces insight quality. When analytics agents deliver insights of substandard quality, the main reason is a lack of business context, as cited by 55% of surveyed executives. Fragmented or inaccessible data is the other major factor, according to 45%. Fewer insight leaders say their agents struggle with access to context. Insight overload further inhibits agent effectiveness. At a majority (52%) of surveyed organizations, analytics agents generate too many insights to be properly evaluated and therefore acted upon. Less than one-quarter (24%) are able to evaluate all agent insights; most do so on a case-by-case basis, and that process is currently human-intensive. Governance and semantics are areas of focus for improving insights. The surveyed companies are prioritizing initiatives that enable better agent insights by strengthening AI and data governance (cited by 60%). They are also adding a semantic layer to their data architecture (45%). The experts we interviewed agree that the semantic layer is crucial to ensure high-performing agents. Download the report This content was produced by Insights, MIT Technology Review’s custom content arm, not its editorial staff. It was researched and written by humans, with any AI tools that may have been used limited to production processes under human oversight.
The Download: the agentic web arrives and the drive for safer roads
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. The agentic web is here In 2001, a decade after inventing the World Wide Web, Tim Berners-Lee articulated a new vision: an internet navigated by autonomous software agents that address our every need, without requiring us to muck about with browsers and search engines ourselves. At the time, the idea seemed far-fetched. But a quarter-century on, AI agents are beginning to make it a reality. They can triage your inbox, do your grocery shopping, and even access your bank accounts. This new era is being called the agentic web. It will inevitably transform the internet—and whether the human web survives this transition is anyone’s guess.
Find out how AI agents are transforming the internet, and what we stand to lose in the process. —Grace Huckins
Are we there yet? Eliminating traffic deaths Every year, traffic crashes kill more than 1 million people worldwide. They’re also the leading cause of death for children and young adults. Cheap, proven ways to make roads safer exist, including tightening intersections with planters and lowering speed limits. But government logjams and red tape can make it difficult to roll out these changes. Still, some cities are making impressive progress by investing in public transit, extending curbs, and using cameras to spot danger zones in need of a redesign. Here’s how close we are to eradicating traffic deaths. —Sara Kiley Watson This story is the final part of “Are we there yet?”, our series that takes stock of six technologies that have long promised to change the world—and scores them on a progress meter. Subscribe to read the other five instalments in our new Impossible issue. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 A $1 trillion tech selloff has deepened fears of an AI bubbleBig AI bills and weak earnings have spooked investors. (BBC)+ The Nasdaq 100 had its worst day since June on Friday. (NBC News)+ OpenAI has cut its funding target by $10 billion. (CNBC)+ What even is the AI bubble? (MIT Technology Review)
2 Hackers have hit Ukraine and Russia’s emergency alert appsKyiv residents were warned of “nuclear danger.” (NBC News)+ Russia’s app said nuclear warheads had been launched. (CNN)+ Ukraine has blamed Russia, which hasn’t yet accused anyone. (BI)+ AI will transform cyber warfare. (MIT Technology Review) 3 Binance users withdrew $3.6 billion after the largest ever crypto hackThe funds moved when the exchange reopened on Sunday. (Guardian)+ Binance says it’s covered $6 billion of the stolen $6.3 billion. (Reuters $)+ But the industry’s response has undermined its “decentralized” image. (Gizmodo) 4 An AI agent injected drugs into a live mouse’s brainIt chose the gene therapy and controlled the needle itself. (Wired $)+ We need real-time tracking of AI agents. (MIT Technology Review) 5 Data centres have made utilities a flashpoint in the midtermsAmericans are angry over rising electricity bills. (Reuters $)+ Virtual power plants could help. (MIT Technology Review) 6 Apple has overtaken Nvidia as the world’s most valuable companyInvestors are favouring its restraint on AI spending. (Bloomberg $)+ But critics say it’s entering its “slop era.” (404 Media) 7 Supermarket fridges have overheated in a new wave of cyberattacksStores in Belgium, Sweden, and Luxembourg were hit. (Politico) 8 The first chocolate bars made from lab-grown cocoa are hereStartups are cultivating chocolate to tackle a cocoa shortage. (WSJ $) 9 Hackers hijacked digital billboards in multiple countries to show pornThey also criticized security flaws and Egypt’s government.(Gizmodo)
10 A new 3D map reveals instability in interstellar spaceThe discovery could help explain why stars form so inefficiently. (Quanta) Quote of the day
“It would be great if all this was just a house of cards.” —Kevin Roose, a technology columnist at the New York Times, tells NPR that an AI investment crash would be preferable to the technology permanently upending work and society. One more thing Useful quantum computing is inevitable—and increasingly imminent Last year, Nvidia CEO Jensen Huang jolted the stock market by saying that practical quantum computing is still 15 to 30 years away. He also suggested that those computers would need Nvidia GPUs to function. But Huang’s predictions miss the mark—both on the timeline and the role his company’s technology will play. Quantum computing is rapidly converging on utility. And that’s good news, because the hope is that they will be able to perform calculations that no amount of AI or classical computation could ever achieve. Read the full story. —Peter Barrett We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + A miniaturist has built a delightful diorama of the world’s creepiest living room.+ The year’s best dog photos have been announced, and they’re very good boys and girls.+ At the Green Zone golf club, you tee off in Sweden and putt in Finland, an hour in the future.+ Astronomers say they’ve found the real celestial arrangement that inspired van Gogh’s The Starry Night.
Stop counting tokens, start counting what ships
Provided byHPE When a developer gives an AI agent a coding task, the agent does more than answer once. It plans, generates code, runs tests, and repeats the process to correct errors. A single task can use 10 to 50 times more tokens than a basic chat prompt. The more useful the agent becomes, the more calls it makes. With per-token pricing, the workflows creating the most value can also become the most expensive. The financial pressure is already visible. Uber reportedly exhausted its entire 2026 AI budget by April after expanding its use of Claude Code. GitHub Copilot moved from flat-rate pricing to metered credits. Gartner predicts that AI coding token costs will surpass average developer salaries by 2028. The natural response is rationing usage caps, seat limits, and approvals before developers launch agents. But blanket limits can restrict the workflows delivering value. They also optimize the wrong number. Cost per token measures consumption, not results. Some spending reflects waste, including retries and runaway loops. Some represents the work of shipping software. A meter cannot distinguish them, and neither can a spending cap. Measure the software that ships A better measure is cost per merged pull request: total AI-assisted development cost divided by the number of changes that pass review and are merged. Track rework and defects alongside it so cheaper changes do not conceal lower quality.
If that cost falls as AI usage rises, without compromising quality, developers are converting more consumption into useful software. The question is not how many tokens they use, but how much finished work the investment produces. Improving that equation requires two changes: reserve expensive inference for tasks that need it, and lower the cost of routine work.
Match the model to the task Agentic coding does not require the most powerful model at every step. Use a frontier model, or an on-premises flagship when policy requires it, for difficult planning and novel reasoning. Route suitable work, including code generation, test creation, and repeated refactoring, to open-weight models you operate yourself. A gateway can route requests according to task complexity, data sensitivity, cost, and latency. This reserves premium inference for the moments that justify it rather than applying premium pricing to an entire workflow. Meter the exception, not the workload. Open-weight models make this division increasingly practical. Software-engineering benchmarks show that leading open-weight models can approach frontier performance on some tasks. That does not establish equivalence across every repository or workflow. Evaluate candidates against your own code, tests, and acceptance criteria before assigning production work. Change the economics of repeated use Next, decide who owns the capacity. With rented inference, every call adds to the bill. With owned capacity, most of the cost is committed upfront, so each additional call gets cheaper as usage grows. The economics are simple: per-token pricing makes heavy use more expensive, while owned capacity becomes more efficient as teams use it more. Ownership is not free, though. Power, operations, maintenance, and depreciation all must be considered. The number that matters is the fully loaded cost per merged pull request. Owned capacity also delivers a type of value that never appears on an invoice: control over sensitive code. When code generation and testing run on-premises, proprietary code stays inside the enterprise. Only approved planning prompts and governed exceptions go to external models, through a gateway the organization controls. That opens the sensitive repositories where security usually stalls adoption, and where the biggest gains are waiting. Test the operating model At HPE, a hybrid AI platform routes routine workloads from more than 150 internal applications to open-weight models running on premises, including on HPE Private Cloud AI. The result: token costs down 30 to 50%. That is the point of hybrid. With HPE Private Cloud AI, owning your inference does not mean giving up frontier models. Run the volume on capacity you own and let a gateway send the hardest work.
Data also shows that usage, not licensed headcount, drives spend. The top 5% of users generated most of the consumption, and the heaviest used roughly 450 times more than the lightest on the same license. If power users grow from a small minority to half the workforce, monthly spend can rise about 4.4 times with flat headcount. Your mix will differ, which is exactly why you need to measure it. HPE tracks two metrics and recommends customers do the same. First, it tracks cost per active developer, because averaging across all licenses hides the power users driving spend. Second, it tracks cost per merged pull request, because it connects AI spending to software that ships. Baseline both costs before changing infrastructure. Then run a complete development cycle on owned capacity. If both metrics do not improve as usage grows, your current model may still be the better choice. Build for adoption, not rationing Owned capacity is not for everyone. Low or unpredictable usage favors APIs, with no capital tied up in idle infrastructure. Ownership pays off when sustained demand keeps it busy. Most enterprises will run hybrid: frontier APIs for demanding or intermittent work, owned capacity for repeatable volume. A governed gateway decides what leaves the building, so you get frontier models without giving up sovereignty over your code. As developers lean harder on coding agents, usage will keep rising. The real choice is whether that growth shows up as a bigger variable-cost bill or as more software shipped on capacity you own. The companies that lead AI-assisted development will not ration adoption to control costs. They will build an operating model where more AI use improves the economics instead of undermining them. To learn more about HPE Private Cloud AI, please visit HPE. This content was produced by HPE. It was not written by MIT Technology Review’s editorial staff.
Market Focus: Balancing AI opportunities and risks in upstream operations
Robert Plumb is an executive vice-president at CAC, part of The Baldwin Group. Robert co-founded the Energy Practice of CAC Specialty in July 2016 with Josh Kirklin. Prior to joining CAC, Robert began his career as an oil and gas underwriter, working for both Travelers and the boutique energy wholesaler & MGA outfit, J.H. Blades & Co. Through these positions, he has drafted insurance policies and written thousands of General Liability, Umbrella, Well Control, Builders Risk, Loss of Production Income, Pollution, Property, Workers Compensation, and auto policies. In his underwriting career he was responsible for an aggregate portfolio of more than $500 million in gross written premium on behalf of various carriers including domestic and international markets, specifically Lloyd’s of London securities. Robert brings unique market perspective on how carriers analyze energy risks, and he specializes in property and casualty lines for on energy accounts worldwide. Robert has a bachelor’s degree in Corporate Communications and a Minor in Business Foundation from the University of Texas at Austin.
Vaalco advances to second exploration phase in block offshore Côte D’Ivoire
Vaalco Energy Inc., Houston, has been granted government approval to begin the second exploration phase at Block CI-705, offshore Côte d’Ivoire. News comes following encouraging results following completion of the first exploration phase work commitments, which included the evaluation and interpretation of existing seismic and well data, the company said in a release Nov. 9. Work on the second exploration phase includes additional seismic reprocessing, relinquishing 25% of the exploration block to the government, and commitment to drill an exploration well by yearend-2028. In March 2025, Vaalco farmed into and became operator of the exploration license with a 70% working interest. The block lies in the Ivoirien basin about 70 km to the west of Vaalco’s CI-40 Block, which hold Baobab and Kossipo oil fields. “We see encouraging prospectivity on the block in the play types proven throughout the Ivoirien Basin including both structural and stratigraphic traps in the Upper Cretaceous and Albian sections,” said George Maxwell, Vaalco’s chief executive officer. “Recent nearby discoveries are on trend with CI-705 and provide additional validation of our play concepts and our view of the block’s prospectivity,” he continued.
The backlash about data centers might really just be about electricity
This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. As voters went to the polls across the US last week, I was in Ashburn, Virginia, part of what’s known as Data Center Alley—the world’s largest data center hub. It’s also where the backlash now sweeping the country arguably first began taking shape. Driving through it is surreal. Concrete monolithic buildings loom along every major road, with names like Skybox and CloudHQ. It’s accepted wisdom in Big Tech that the war against data centers must be about something bigger than just data centers themselves. Two days after the midterms, OpenAI’s chief global affairs officer, Chris Lehane, wrote that data centers “have become a proxy for public unease about affordability, corporate power, and people losing control over their futures.” It’s a culture war, in other words.
But spending a few days in Data Center Alley left me wondering if it’s really the proxy that Lehane describes. I came away convinced that the data center backlash is more about electricity than Big Tech admits. The industry can improve its image, but it can’t escape the physical consequences of its enormous appetite for electricity. Here’s why. There are two ways to power the sort of data center that AI companies want: connecting to the grid, or generating electricity onsite. In Virginia’s Loudoun County, where data centers are ubiquitous but have been built at a steadier pace than the breakneck expansion now underway elsewhere in the country, most are connected to the existing grid.
One facility I went inside, operated by Equinix, has massive diesel generators onsite for backup but gets its power from the local utility, Dominion Energy. Much of Dominion’s electricity is generated by natural gas (which is cleaner than coal or oil, but worse than renewables). The average data center operating in this part of Virginia today has a power capacity of 54 megawatts. That’s more than the power draw of the Denver International Airport. Elena Schlossberg, a prominent activist against data centers in Virginia, told me she’s “always banging my head against the wall” when the industry paints the fight as a culture war. “It was always about power,” she says—that is, electricity. Some Virginia protesters appear more animated by a broader anti-tech populism than Schlossberg, to be fair. But it’s the particular consequences of drawing so much power from the grid that have done the most to shape how the backlash has played out. Recent protests have led to new rules from the state that data centers must pay fully for the cost of new transmission lines to the grid and make sure they’re not spread among everyone else. Data center developers told me they’re preparing for new rules that would cut them off from grid power during peak demand. Schlossberg also worries about the downstream effects of a strained grid—for example, that data centers will run more diesel generators or that Dominion Energy will expand fossil fuel inputs rather than renewables to meet demand. The overwhelming majority of AI data centers being built elsewhere in the country are not designed this way. The scale desired is so massive that companies are setting up in rural areas where there is virtually no grid infrastructure to connect to. Building there means bringing your own power (so-called “behind the meter” power), in the form of natural-gas-powered turbines. Companies also build diesel generators for backup. Anthropic, for example, has reportedly agreed to pay $3.4 billion for gas turbines in what’s described as the largest power generation purchase by an AI company. Even if grids were nearby, they’d be unlikely to serve the amount of power demanded. The smallest data centers attractive for AI training are 300 megawatts. It’s a lot of power for one industrial site, but not unprecedented: One data center developer told me he’s eyeing a former steel mill already equipped to draw that much electricity from the grid. But the ideal facilities are more like 6,000 megawatts. That’s the estimated draw of the city of Chicago, which is powered by more than 20 power plants within the city alone (and dozens farther out).
The notion of data center companies’ bringing their own power might seem attractive at first, because they wouldn’t be straining the grid. But generating electricity at this scale inevitably affects surrounding communities, and when public utilities build infrastructure of this magnitude, communities have traditionally expected a say in where it goes. Now, private companies are undertaking projects on a similar scale. Natural-gas turbines of any scale release air pollutants. When diesel generators are used, it’s even worse. And in the unprecedented rush to get these facilities operating, companies have become horrible neighbors (recall that Elon Musk violated air quality laws when he set up dozens of turbines to power a data center in Memphis, according to the Environmental Protection Agency). Big Tech’s tendency to chalk the backlash up to a culture war obfuscates one simple fact: There’s only so pleasant you can make a small city of computers to live around. Sure, companies can pursue better deals that raise tax revenues, hire local workers, and get more community involvement, as the protests are leading them to do. But if a small town is asked to welcome a Walt Disney World, an international airport, a steel plant, and the power plants to run them all, should we be surprised by its trepidation? Again, that’s not to say this is the sole reason for opposition to data centers. Fears of job losses, existential risks, and concentrated corporate power all fuel the backlash, as does misinformation (most facilities use far less water than many people think). Nor is consuming enormous amounts of electricity inherently bad: Many of the advances that have improved modern life have required just that. But as one developer recently told me, industry insiders see their ambitions as constrained less by public opposition than by a lack of electricity. That should tell us something. So what happens next? It’s possible that newly elected politicians’ actual stances on data centers won’t be as negative as the ones they campaigned on. But what seems true regardless is that if new data centers need their own power generated onsite, they’ll go where there are the fewest people able to resist them. That might mean the Permian Basin, where a network of natural-gas lines can be easy for developers to connect to and populations are sparse. Companies might also try their chances abroad; Google, in fact, announced the day after the elections that it will spend $15 billion on data center projects in Malaysia. But there’s one place where Big Tech may find virtually no limits at all, as Elon Musk posted just hours after the midterms results came rolling in: “Data centers in space looking pretty appealing right now.”
BSR, consortium enter talks for potential downstream collaborations
Vietnam Refining and Petrochemical Corp. (BSR) has entered talks with a consortium of FutureTec Co. and Zhejiang Hanghua Technology Co. Ltd. (Hanghua) to discuss and explore development opportunities along the refining and petrochemical value chain. At a Nov. 5 meeting between the parties, officials from the companies weighed potential collaborations on the deep processing of petroleum products, the development of value-added products, and research into related industrial infrastructure projects, BSR said in a release Nov. 6. While specific projects discussed at the meeting were not revealed, BSR said the event has laid the groundwork for further in-depth talks on potential areas of collaboration that would contributing to expanding the petrochemical refining value chain, improving resource utilization efficiency, and moving operations towards sustainable development. The proposed collaboration discussion comes amid shared interests of BSR and the FutureTec-Hanghua consortium in developing green, clean, and environmentally friendly products, as well as researching and developing new higher-value products, BSR said. With its experience in operating and managing refineries, BSR offers a favorable platform for expanding cooperation efforts with partners such as FutureTec and Hanghua that bring specialized capabilities in technology, research, and product development, added Nguyen Viet Thang, BSR’s general director. Potential collaborations with external partners come alongside BSR’s upgrading and expansion project now underway at the operator’s the 6.5-million tonne/year (tpy) refinery in the Dung Quat Economic Zone of Binh Tri Commune in Binh Son District, Quang Ngai Province, Vietnam. During the Nov. 5 meeting with the FutureTec-Hanghua consortium, BSR said its near-term plans for the refinery—which is currently operating at about 121% capacity—include further improving operational efficiency; optimizing technological processes; diversifying crude oil and product sourcing; as well as developing additional cleaner, sustainable fuels, petrochemicals, and high-value products. The operator said it will also continue focusing on efforts further efficient energy use,
Land & Expand: Texas’ AI Boom Meets a New Political Reality
Hut 8 Advances a Gigawatt-Scale Campus Near Corpus Christi Another significant development came November 4, when Hut 8 reported continued progress on its Beacon Point AI data center campus in the Corpus Christi region. The company said that its previously announced second 352 MW IT-capacity lease had fully commercialized the campus, bringing the total contracted IT capacity associated with the two phases to 704 MW. The campus is designed around approximately 1 GW of utility capacity, a separate measure from the critical IT load under lease. Hut 8 estimates approximately $19.6 billion in base-term contract value across the two phases. In its third-quarter results, the company said construction of the campus substation had begun, alongside foundation and underground utility work for the first phase. Initial data hall delivery is targeted for the third quarter of 2027, with the second phase targeted for the second quarter of 2028. The company also disclosed agreements to acquire two energized sites in West Texas, with up to 230 MW of utility capacity at full energization, subject to outstanding approvals and infrastructure development. Those acquisitions point to another important trend: the increasing value of existing electrical infrastructure and sites that can potentially be adapted to serve advanced computing. As new greenfield projects face lengthy power studies and regulatory requirements, already energized locations may offer an alternative route to capacity. The distinction is especially important in markets such as Dallas-Fort Worth, where DCF’s analysis of CBRE’s first-half 2026 data found that approximately 95% of the region’s 765 MW under construction had already been preleased. PowerHouse and Big Watt Win Approval for Taylor Technology Campus Not every large new project is meeting resistance at the municipal level. On October 8, the City of Taylor approved a development agreement with PowerHouse Data Centers and Big Watt Digital for
Nancy Pelosi’s replacement is ready to regulate AI
EXECUTIVE SUMMARY As a California state senator, Scott Wiener authored legislation aimed at curbing the risks of advanced AI. Now, after winning a tight congressional race for former Speaker of the House Nancy Pelosi’s open San Francisco seat, he could play a key role in setting federal AI policy. I spoke with Wiener on Friday, only a few hours after he had been declared the victor. But he was already thinking about AI risk. The previous day, the AI nonprofit METR had released a report that had been widely interpreted as evidence that Anthropic had achieved recursive self-improvement, a phenomenon in which AI meaningfully contributes to its own advancement and AI progress potentially spins out of control. “It’s very concerning,” Wiener said, citing the report as evidence that we are quickly running out of time to regulate AI. “It was my hope that Congress would take decisive action before [the end of] this year,” he said. “That does not appear to be happening.” Wiener has been increasingly focused on AI in recent years, and he’s made many of the AI safety movement’s concerns his own: During our 20-minute conversation, he used the phrase “recursive self-improvement” half a dozen times, for example.“We need to slow this down,” he says. “Because it’s moving very quickly, and we could sleepwalk into a disaster.”
Wiener has already had real influence on AI policy. SB 1047, a bill that he authored in 2024, was set to become the first real piece of frontier AI legislation in the country before it was vetoed by California governor Gavin Newsom; he then sponsored SB 53, a lighter-touch bill that Newsom signed. Both bills have inspired proposed federal legislation. Wiener’s congressional campaign received over $3 million from Public First Action, a nonprofit in favor of AI regulation that receives substantial funding from Anthropic. That contribution led opponents to criticize him for being too close to the AI industry, but Wiener says that couldn’t be further from the truth.
“Public First supported me because I was the first lawmaker in the country to introduce AI regulation and the first to pass it and get it implemented,” he wrote in a message after our interview. “The attacks on me for [Public First’s] support were shockingly cynical—literally attacking a candidate who actually regulated AI over Big Tech’s objection and falsely claiming the candidate is somehow too close to Big Tech.” Wiener says that if Congress forms a select committee on artificial intelligence—something that Democrats have discussed since September—he’d be eager to serve. And he’s enthusiastic about many of the policy ideas floating around Congress. “I think it’s really important to have a strong, empowered, nimble federal regulator,” he says, noting that Representative Ro Khanna, a fellow Democrat from California, has proposed legislation to establish such a regulator. He also highlights the importance of whistleblower protections, testing and auditing requirements, and a kill switch requirement, and he wants to see Congress leverage its oversight powers to hold the AI labs to account. “This is about the future of humanity, and we want to make sure that the public has a say and that the public knows what’s going on,” he says. And as a longtime state legislator, he is opposed to broad federal preemption of state AI laws, which some of the proposed federal legislation would require. “States are, as Brandeis says, laboratories,” he notes. “You want the states to be able to continue to be nimble in ways that Congress sometimes is not.” Above all, Wiener says, he wants Congress to pass policies with real teeth. “It’s critically important that when Congress acts, that we do so in a way that is truly meaningful and that meets the moment,” he says. That means taking seriously the possibility of AI catastrophe, something he discusses in the sort of language typically used by AI safety experts. “We’re in a moment that is very dangerous in terms of the risk of loss of control over AI,” he told me. “We need to deal with recursive self-improvement. Once you’re in that realm, that really is potentially a recipe for total loss of control.” He’ll have some allies in the fight against catastrophic AI risk. Senator Bernie Sanders, for instance, has met with many of the AI safety movement’s most influential figures and has spoken repeatedly about AI and existential risk. But there’s still a large gap between Wiener’s Bay Area, AGI-pilled perspective and the national mood on AI, which is anchored by opposition to data centers. The fact that voters approved 40 out of 41 anti-data-center ballot measures on Tuesday might seem to be a good sign for Wiener and others who support AI regulation, but Wiener says he sees this movement as far more tied to local concerns than to bigger questions about AI risk. “Peoople who are really opposed to where AI is going—this is an area where they can actually do something about it,” he says. “But the data center revolt—to me, I think it’s more so that people are upset that there could be something like this in their community, with all the impacts near people’s homes, driving up electric bills and using water. I think that’s the bigger issue for most people, from what I can tell.” Wiener describes himself as only “cautiously optimistic” about Congress’s ability to rein in AI, given its poor track record on regulating the tech industry. He also has concerns about the ability to get legislation past President Donald Trump, who called concerns about catastrophic AI risk a “hoax” in September and has demonstrated a stark unwillingness to collaborate with China, something that Wiener sees as essential to preventing the worst consequences of AI. But he says Trump’s unpredictability provides some measure of hope, though it’s a fraught kind of hope. “So far what we’ve seen are some problematic things, but not complete disasters,” Wiener says. “I hope that it doesn’t take a disaster to spur the president into acting. And I hope if that’s what it does take—which, like I said, I hope it doesn’t—but if it does, I hope it’s as small as possible.”